# 🧠 lossless-code
**DAG-based Lossless Context Management for Claude Code and Codex.**
*Every message preserved forever. Summaries cascade, never delete. Full recall across sessions. Works with any LLM.*
[](https://opensource.org/licenses/MIT)
[](https://github.com/GodsBoy/lossless-code/stargazers)
[](https://github.com/GodsBoy/lossless-code/network/members)
[](https://github.com/GodsBoy/lossless-code/issues)
[](https://github.com/GodsBoy/lossless-code/commits/main)
[](https://www.python.org/)
[](https://www.sqlite.org/)
[](https://docs.anthropic.com/en/docs/claude-code)
[](https://developers.openai.com/codex/hooks)
[](https://modelcontextprotocol.io/)
[](https://github.com/GodsBoy/lossless-code/pulls)

[Getting Started](#install) · [MCP Server](#mcp-server) · [Commands](#commands) · [Dream](#lossless-dream) · [Terminal UI](#terminal-ui-lcc-tui) · [How It Works](#how-it-works) · [Configuration](#configuration) · [Contributing](#contributing)
---
> Claude Code forgets. claude-mem remembers fragments. MemPalace compresses until you can't trace back. lossless-code remembers everything.
## What's new in v1.2
The v1.2 release delivers three composing layers on top of the v1.1 vault and dream cycle:
- **Compaction-aware reference bundle.** SessionStart now emits a token-budgeted reference bundle (default 1000 tokens, configurable via `bundleTokenBudget`) instead of a 2-5K token text dump. The agent pulls depth on demand via `lcc_expand`, `lcc_grep`, and `lcc_context`. Recovery-protocol line ships first so the agent knows the protocol before any content arrives.
- **Codex start continuity.** `lcc codex doctor`, Codex `SessionStart` hook config, and `lcc codex start` bring the same bounded bundle to Codex. The bundle leads with current task state, labels partial recall, and keeps MCP expansion as the dependable base.
- **Behavior contracts.** Typed retractable rules (`prefer` / `forbid` / `verify-before`) the agent commits to follow next session. The dream cycle proposes them as `Pending`; you approve via the TUI Contracts tab (key `5`, then `a` to approve, `r` to reject or retract, `s` to supersede). Append-only retraction trail preserved for audit; supersede atomicity wraps INSERT and UPDATE in `BEGIN IMMEDIATE`.
- **OpenTelemetry-shaped span substrate.** New `parent_message_id`, `span_kind`, `tool_call_id`, `attributes` columns on the `messages` table. `lcc_expand` accepts `span_id` and walks the parent chain, returning a structured-error JSON shape for `span_not_found` / `expand_too_large` / `vault_corrupt` so agents know how to fall back.
### Reverting to pre-v1.2 behavior
The legacy 2-5K full-text injection from v1.1 has been removed in v1.2. To run Claude Code without lossless-code's SessionStart injection, set `"bundleEnabled": false` in `~/.lossless-code/config.json`. The dream cycle, MCP tools, and TUI continue to work; only the SessionStart bundle is suppressed (graceful degradation).
## Try it in 60 seconds
```
/plugin marketplace add GodsBoy/lossless-code
/plugin install lossless-code
```
That's it. Start a new session and search your history:
> lcc_grep "database migration"
## The Problem
Claude Code forgets everything between sessions. Memory tools like ClawMem, context-memory, and claude-mem use flat retrieval: keyword search over snippets, no structure, no hierarchy, no way to trace a summary back to its source conversation.
When a project spans weeks and hundreds of sessions, flat search fails. You get fragments without lineage.
## What Makes lossless-code Different
lossless-code uses **DAG-based lossless preservation**, the same approach pioneered by [lossless-claw](https://github.com/Martian-Engineering/lossless-claw) for [OpenClaw](https://github.com/openclaw/openclaw):
- **Nothing is ever deleted.** Every message stays in `vault.db` forever.
- **Summaries form a directed acyclic graph.** Messages cascade to depth-0 summaries, which roll up to depth-1, depth-2, and beyond.
- **Full drill-down.** `lcc_expand` traces any summary back to the exact messages that created it.
- **Automatic.** Claude Code hooks capture every turn and trigger summarisation transparently. Zero manual effort.
- **Codex start continuity.** Codex can use MCP recall, `SessionStart` bundle injection, doctor checks, launcher fallback, and project opt-in latest-tail task state.
- **Cross-session recall.** Start a new session and your full project history is immediately searchable.
- **Lossless Dream.** Extracts recurring patterns (corrections, preferences, conventions) from vault history and injects them into future sessions — like Auto-Dream but without forgetting.
```
┌──────────────────┐
│ Claude Code │
│ Session │
└────────┬─────────┘
│
┌────────────────────────┼────────────────────────┐
│ │ │ │
┌─────▼─────┐ ┌──────▼──────┐ ┌──────▼──────┐ ┌────▼─────┐
│ Hooks │ │ Skills │ │ CLI │ │ MCP │
│ (write) │ │ (shell) │ │ Tools │ │ Server │
│ │ │ │ │ │ │ (stdio) │
│ SessionStart│ │ lcc_grep │ │ lcc_status │ │ │
│ Stop │ │ lcc_expand │ │ │ │ 7 tools │
│ PreCompact │ │ lcc_context │ │ │ │ read + │
│ PostCompact│ │ lcc_sessions│ │ │ │ contracts│
│ UserPrompt │ │ lcc_handoff │ │ │ │ │
│ │ │ lcc_contracts│ │ │ │ │
└─────┬──────┘ └──────┬──────┘ └──────┬──────┘ └────┬─────┘
│ │ │ │
└──────────────────┼────────────────┼──────────────┘
│ │
┌────────▼────────────────▼──┐
│ vault.db │
│ (SQLite) │
│ │
│ messages summaries │
│ summary_sources sessions │
│ FTS5 indexes │
└──────────────────────────────┘
```
## Comparison
| | lossless-code | MemPalace | ClawMem | context-memory | claude-mem |
|---|---|---|---|---|---|
| **Storage** | SQLite with FTS5 | SQLite | SQLite + vector DB | Markdown files | SQLite + Chroma |
| **Structure** | DAG (summaries cascade) | Palace (Wings/Rooms/Halls) | Flat RAG retrieval | Flat retrieval | Flat retrieval |
| **Drill-down** | Full (summary -> source messages) | None (30x lossy compression) | None | None | None |
| **Auto-capture** | Hooks (zero manual effort) | Mining command required | Hooks + watcher | Manual | Hooks + worker |
| **Cross-session** | Yes (vault persists) | Yes | Yes | Yes | Yes |
| **Summarisation** | Cascading DAG (depth-N) | AAAK compression (lossy) | Single-level | None | Single-level |
| **Search** | Hybrid (FTS5 + vector) | Semantic + palace navigation | Hybrid (BM25 + vector + reranker) | Keyword | Hybrid (BM25 + vector) |
| **Multi-provider** | Any (auto-detect + openaiBaseUrl) | Any (all major LLMs) | Bun + llama.cpp | None | Bun |
| **MCP tools** | 7 | 19 | 28 | 0 | 10+ |
| **Background services** | None | None | watcher + embed timer + GPU | None | Worker on port 37777 |
| **Runtime** | Python (stdlib) | Python | Bun + llama.cpp (optional) | None | Bun |
| **Models required** | None (extractive fallback) | None (AAAK is non-LLM) | 2GB+ GGUF (embed + reranker) | None | Chroma embeddings |
| **Idle cost** | Zero | Zero | CPU/RAM for services | Zero | Worker process |
## Why lossless-code Costs Less
Memory tools that inject context on every prompt are silently expensive. Here's why lossless-code's design saves tokens:
### 1. On-demand recall, not automatic injection
ClawMem injects relevant memory into **90% of prompts automatically** (their stated design). claude-mem injects a context index on every SessionStart. Both approaches front-load tokens whether or not the agent needs that context.
lossless-code injects **nothing by default**. Context surfaces only when the agent explicitly calls an MCP tool or the PreCompact hook fires. Most coding turns (writing code, running tests, reading files) don't need historical context at all. You pay for recall only when recall matters.
### 2. Fewer MCP tool definitions = fewer tokens per turn
Every MCP tool registered in `~/.claude.json` has its schema injected into **every single API call** as available tools. Claude Code's own docs warn: *"Prefer CLI tools when available... they don't add persistent tool definitions."*
- ClawMem: **28 MCP tools** (query, intent_search, find_causal_links, timeline, similar, etc.)
- claude-mem: **10+ search endpoints** via worker service
- lossless-code: **7 MCP tools** (grep, expand, context, sessions, handoff, status, contracts)
Over a 200-turn session, that difference in tool schema overhead compounds significantly.
### 3. No background embedding costs
ClawMem runs a watcher service (re-indexes on file changes) and an embed timer (daily embedding sweep across all collections). These require GGUF models (~2GB minimum) and consume CPU/GPU continuously. claude-mem runs a persistent worker service on port 37777.
lossless-code has **zero background processes**. Hooks fire only during Claude Code events. The vault is pure SQLite with FTS5 (built into SQLite, no external models). Nothing runs between sessions.
### 4. DAG summarisation reduces compaction waste
When Claude Code hits its context limit, it compacts: summarising earlier context to make room. With flat memory systems, compaction loses fidelity and the agent may re-explore territory it forgot, costing more tokens ("debugging in circles").
lossless-code's DAG captures the full conversation **before** compaction happens (PreCompact hook). After compaction, the PostCompact hook re-injects only the top-level summaries. The agent can drill down via `lcc_expand` if it needs detail, but the DAG ensures nothing is truly lost. This means:
- Fewer repeated explorations after compaction
- One long session is cheaper than multiple short sessions covering the same ground
- Context survives compaction without paying to re-read everything
### 5. How lossless-code Compares to MemPalace on Cost
[MemPalace](https://github.com/milla-jovovich/mempalace) achieves ~$0.70/yr by compressing context into an AAAK dialect (~170 tokens loaded per session). This is impressive for token efficiency, but the compression is lossy — you cannot drill back to the original conversation that produced a fact.
lossless-code takes a different approach: **nothing is compressed away.** Every message stays verbatim in `vault.db`. Context is loaded on-demand, not on every prompt. With a cheap model:
| Approach | Per-session cost | Annual (5 sessions/day) |
|----------|-----------------|------------------------|
| MemPalace wake-up (~170 tokens) | ~$0.0004 | ~$0.70/yr |
| lossless-code (on-demand, 0-1 recalls/session) | ~$0.001 | ~$1.80/yr |
| lossless-code + gpt-4.1-nano summaries | ~$0.01 | ~$18/yr |
| LLM summary injection every prompt | ~$0.03 | ~$55/yr |
lossless-code costs slightly more per session but preserves full fidelity with drill-down to original messages. For users who value the ability to trace any summary back to its source conversation, the trade-off is clear.
### 6. No runtime dependencies
| Dependency | lossless-code | ClawMem | claude-mem |
|---|---|---|---|
| Python 3.10+ | Yes (usually pre-installed) | No | No |
| Bun | No | **Required** | **Required** |
| llama.cpp / GGUF models | No | Optional (2GB+) | No |
| Chroma / vector DB | No | No | **Required** |
| systemd services | No | Recommended | No |
| `mcp` Python SDK | Yes (pip install) | No (TypeScript) | No |
Fewer dependencies means less to maintain, fewer failure modes, and lower resource consumption.
## Install
### Option A: Claude Code Plugin (recommended)
```
/plugin marketplace add GodsBoy/lossless-code
/plugin install lossless-code
```
Hooks, MCP server, skill, and `lcc_*` shell commands are activated automatically. No manual setup needed.
### Option B: Standalone Install
```bash
git clone https://github.com/GodsBoy/lossless-code.git
cd lossless-code
bash install.sh
```
The installer:
1. Creates `~/.lossless-code/` with `vault.db` and scripts
2. Configures Claude Code hooks in `~/.claude/settings.json`
3. Installs the skill to `~/.claude/skills/lossless-code/`
4. Adds CLI tools to PATH
Idempotent: safe to run again to upgrade.
### Requirements
- Python 3.10+
- SQLite 3.35+ (for FTS5)
- Claude Code CLI
Optional: `anthropic` Python package for AI-powered summarisation (falls back to extractive summaries without it).
## MCP Server
lossless-code includes an MCP (Model Context Protocol) server so Claude Code can access the vault as **native tools** without shelling out to CLI commands.
### Setup
If you installed via the Claude Code plugin (Option A), the MCP server is registered automatically through the plugin's `.mcp.json`. Nothing else to do.
If you installed standalone via `install.sh` (Option B), the installer:
1. Copies the MCP server to `~/.lossless-code/mcp/server.py`
2. Installs the `mcp` Python SDK
3. Registers the server in `~/.claude.json` as a user-scope MCP — **unless the plugin is also installed**, in which case the script skips (or removes) the user-scope entry so the plugin registration is the single source of truth. This avoids the "Server defined in multiple scopes with different endpoints" warning from `claude /doctor`.
After installation, every new Claude Code session auto-discovers 7 MCP tools:
| Tool | Description |
|------|-------------|
| `lcc_grep` | Full-text search across messages and summaries |
| `lcc_expand` | Expand a summary, file, or span chain back to source messages (v1.2: span_id mode for OTel-shaped span walks) |
| `lcc_context` | Return the v1.2 SessionStart reference bundle (task state + contracts + handoff + decisions + fingerprints) |
| `lcc_sessions` | List sessions with metadata |
| `lcc_handoff` | Generate session handoff documents |
| `lcc_status` | Vault statistics (sessions, messages, DAG depth, DB size) plus v1.2 contract/decision counts and bundle state |
| `lcc_contracts` | List, show, approve, reject, retract, or supersede behavior contracts (v1.2) |
### Manual Registration
If you need to register the MCP server manually:
```json
// ~/.claude.json
{
"mcpServers": {
"lossless-code": {
"command": "python3",
"args": ["~/.lossless-code/mcp/server.py"]
}
}
}
```
### Codex MCP Registration
Codex can use the same MCP server for pull-on-demand recall. Preview the registration command:
```bash
lcc codex install-mcp
```
Run it when you are ready to write Codex MCP config:
```bash
lcc codex install-mcp --write
```
Check readiness at any time:
```bash
lcc codex doctor
```
### Architecture
```
Claude Code ──stdio──▶ MCP Server ─▶ vault.db
(server.py)
7 tools
```
The MCP server is **read-mostly**. Six of seven tools are read-only (grep, expand, context, sessions, handoff, status). The seventh, `lcc_contracts`, mutates the `contracts` table for approve/reject/retract/supersede actions; the `list` and `show` actions remain read-only. All other writes (messages, summaries, sessions) still happen through hooks (SessionStart, Stop, UserPromptSubmit, PreCompact, PostCompact). The MCP server imports the `db` package (`scripts/db/`) directly for SQLite access.
## Commands
### `lcc_grep `
Full-text search across all messages and summaries.
```bash
lcc_grep "database migration"
lcc_grep "auth refactor"
```
### `lcc_expand `
Expand a summary node back to its source messages. v1.2 also accepts a span id (walks the `parent_message_id` chain) and a file path (lists summaries that mention it).
```bash
lcc_expand sum_abc123def456 # by summary id
lcc_expand sum_abc123def456 --full # no per-line truncation; total cap still applies
lcc_expand --span-id 4271 # v1.2: walk the parent chain from a message id
lcc_expand --file path/to/file.py # list recent summaries that touched this file
```
### `lcc_context`
Print the v1.2 SessionStart reference bundle for the current working directory. The bundle starts with current task state when available, then contracts, handoff, decisions, and file fingerprints, with each line carrying its own Expand instruction. Takes no arguments; the bundle shape is the same content the start hooks inject.
```bash
lcc_context
```
### `lcc codex`
Codex setup, diagnostics, and launcher helpers.
```bash
lcc codex doctor # check Codex CLI, registered SessionStart hook, MCP, vault, and bundle preview
lcc codex install-hooks # dry-run project hooks.json for SessionStart
lcc codex install-hooks --write # write project .codex/hooks.json
lcc codex install-hooks --scope user # dry-run ~/.codex/hooks.json
lcc codex install-mcp # print codex mcp add command
lcc codex tail-import # inspect project opt-in state
lcc codex tail-import --enable # allow latest local tail task-state import for this project
lcc codex tail-import --disable # remove this project from tail import
lcc codex start --print-context "task" # print launcher fallback prompt
lcc codex start "task" # launch Codex with Lossless-Code context
```
The hook path is preferred once Codex has reviewed and trusted the hook. The launcher is a bridge for environments where hook setup or hook timing is not ready yet.
Tail import is project opt-in. When enabled for a project, the SessionStart hook reads only the latest matching local session tail, extracts compact task state, and stores that task-state record in `imported_task_state`. It does not store raw turns or full transcripts. `lcc codex doctor` reports whether tail import is disabled, enabled, or enabled but unable to inspect local sessions.
### `lcc_sessions`
List recorded sessions with timestamps and handoff status.
```bash
lcc_sessions
lcc_sessions --limit 5
```
### `lcc_handoff`
Show or generate a session handoff.
```bash
lcc_handoff
lcc_handoff --generate --session "$CLAUDE_SESSION_ID"
```
### `lcc_status`
Show vault statistics: message count, summary count, DAG depth, dream stats, and FTS index health. v1.2 adds contract counts by status, decision count, bundle state and budget, and the last dream cycle's mode (LLM, regex fallback, or failure).
```bash
lcc_status
```
### `lcc_contracts` (v1.2)
List, show, approve, reject, retract, or supersede behavior contracts. Same six actions on both the CLI and the MCP tool.
```bash
lcc contracts list # default: list Pending
lcc contracts list --status Active
lcc contracts show --id con_abc123
lcc contracts approve --id con_abc123
lcc contracts reject --id con_abc123
lcc contracts retract --id con_abc123 --reason "no longer applies"
lcc contracts supersede --id con_abc123 --body "new replacement rule"
```
The TUI Contracts tab (key `5`) is the recommended approval surface for Pending candidates, since it shows the full body before you press `a` to approve.
### `lcc_dream`
Run the dream cycle — extract patterns from vault history and consolidate the DAG.
```bash
lcc_dream --run # Dream for current working directory
lcc_dream --run --project /path # Dream for a specific project
lcc_dream --run --global # Cross-project dream
```
See [Lossless Dream](#lossless-dream) for details.
## Terminal UI (lcc-tui)
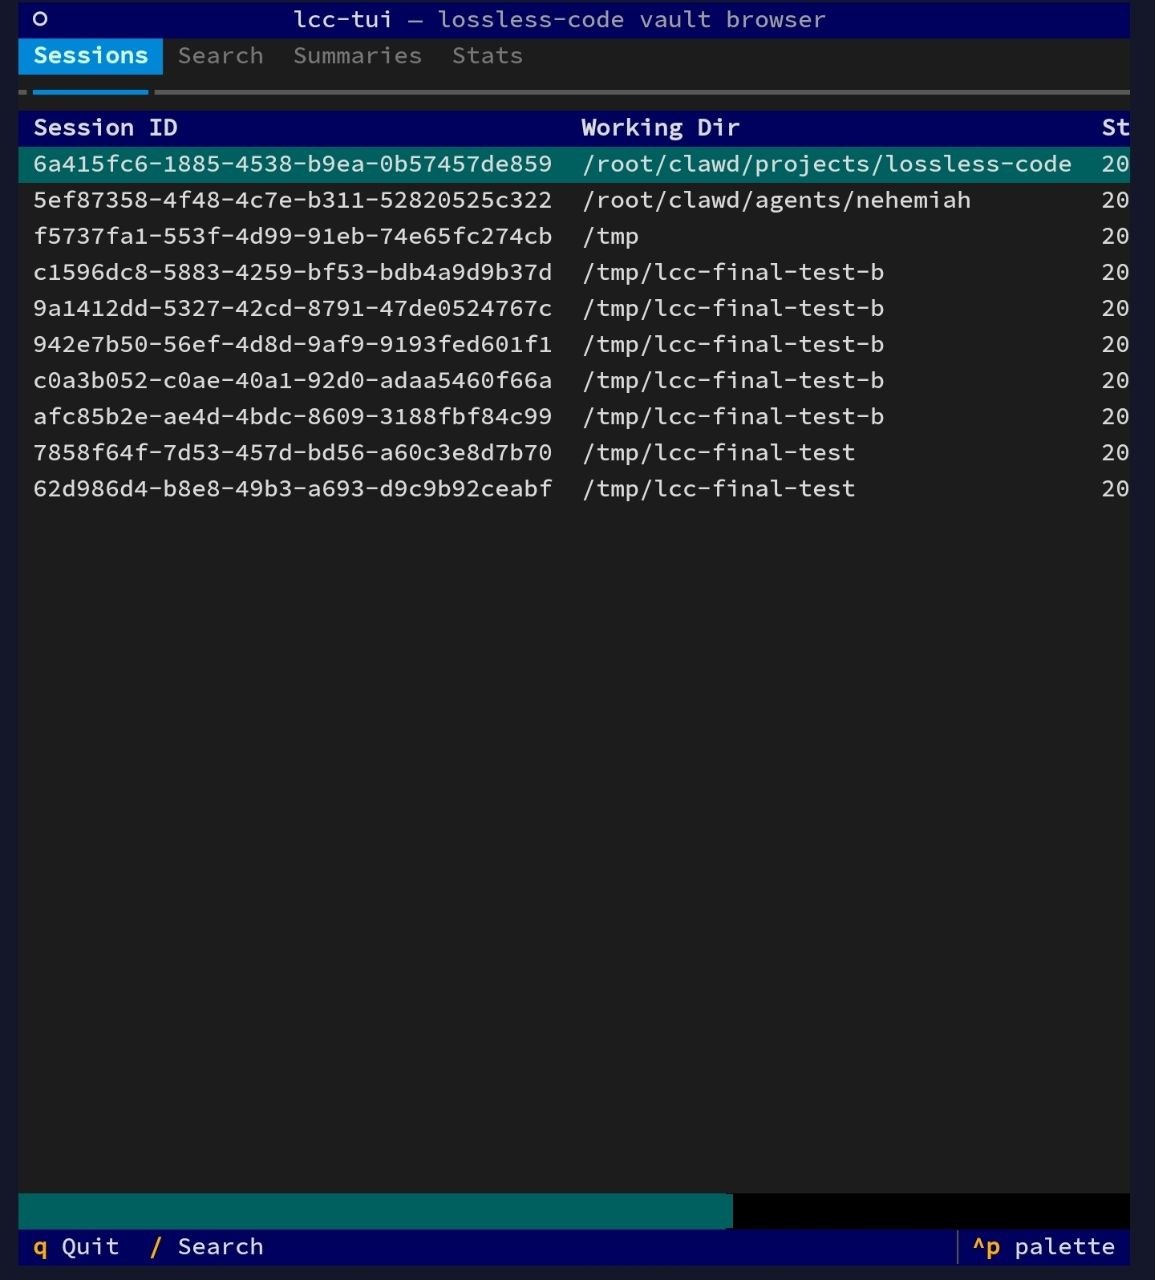
`lcc-tui` is a terminal-based browser for your vault. Built with [Textual](https://github.com/Textualize/textual).
```bash
lcc-tui
```
### Views
| Tab | Key | Description |
|-----|-----|-------------|
| Sessions | `1` | Browse all sessions; select to view messages |
| Search | `2` | Full-text search across messages and summaries |
| Summaries | `3` | Browse DAG summaries by depth; select to expand |
| Stats | `4` | Dashboard: sessions, messages, summaries, vault size |
| Contracts | `5` | v1.2: approve / reject / retract / supersede behavior contracts |
### Navigation
- `1` to `5`: switch tabs
- `/`: open search modal from any view
- `Enter`: drill into selected session or summary
- `Esc`: go back
- `q`: quit
### Contracts tab keys (v1.2)
- `a`: approve the selected Pending contract (flips to Active, rides in every SessionStart bundle)
- `r`: reject (Pending) or retract (Active) the selected contract; retraction prompts for a required reason
- `s`: supersede the selected Active contract via a TextArea pre-filled with the old body
- `t`: cycle the filter between Pending / Active / Retracted
- `Enter`: open the contract detail modal with the full body before approving
Full reference: [docs/tui.md](docs/tui.md)
## How It Works
### Hooks (Automatic)
| Hook | Event | Purpose |
|------|-------|---------|
| `session_start.sh` | SessionStart | Register session, inject handoff + summaries |
| `stop.sh` | Stop | Persist each turn to vault.db; trigger auto-dream if conditions met |
| `user_prompt_submit.sh` | UserPromptSubmit | Surface relevant context for the prompt (BM25-ranked) |
| `pre_compact.sh` | PreCompact | Run DAG summarisation before compaction |
| `post_compact.sh` | PostCompact | Record compaction, re-inject top summaries |
| `pre_tool_use.sh` | PreToolUse | Inject file-context fingerprint before `Read`/`Edit`/`Write` tools (opt-in, see [fingerprint file context](#fingerprint-file-context)) |
| `post_tool_use.sh` | PostToolUse | Record which file a tool call touched, so fingerprints can surface later |
### DAG Summarisation
1. Collect unsummarised messages, chunk into groups of ~20
2. Summarise each chunk (via Claude API or extractive fallback)
3. Hard-cap summary text to prevent vault bloat (leaf: 7,200 tokens max, condensed: 6,000 tokens max)
4. Write summary nodes to `summaries` table (depth=0)
5. Link to sources in `summary_sources`
6. Mark source messages as summarised
7. If depth-N exceeds threshold: cascade to depth-N+1 (max depth: 5)
8. Repeat until under threshold or max depth reached
### Lossless Dream
Dream is the intelligence layer on top of the DAG. It analyzes vault history to extract recurring patterns and consolidate redundant summaries — all without deleting anything.
**Three-phase cycle:**
1. **Pattern extraction** — Queries messages and summaries since the last dream, chunks them, and sends each chunk to the LLM. Extracts patterns in 5 categories: corrections, preferences, anti-patterns, conventions, decisions. Falls back to keyword heuristics when no LLM API is available.
2. **DAG consolidation** — Finds summaries with overlapping sources (>50% shared), merges them into tighter nodes via LLM, marks originals as `consolidated=1`. Nothing is deleted.
3. **Report generation** — Writes a timestamped report and updates the dream log for idempotent reruns.
**Auto-trigger:** Dream runs automatically from the `stop.sh` hook when configurable conditions are met (default: 5+ sessions or 24+ hours since last dream). Runs as a background process with file-based locking to prevent concurrent races.
**Context injection:** On SessionStart, per-project and global dream patterns are injected alongside existing handoff and summaries, within a configurable token budget (default 2000 tokens).
### Prompt-Aware Context Eviction
When context injection exceeds `contextTokenBudget`, lossless-code uses **budget-aware per-item packing** instead of hard truncation:
1. **Reserve** — Handoff text and dream patterns are always included (reserved budget)
2. **Rank** — When a user prompt is present, candidate summaries are ranked by FTS5 BM25 relevance. Without a prompt (session start), summaries are ranked by DAG depth
3. **Pack** — Summaries are greedily packed by rank until the budget is exhausted. Each summary is either fully included or fully excluded — never truncated mid-content
4. **Fallback** — If the query produces no FTS5 matches (or is blank), selection falls back to depth-based ordering
This ensures the most relevant summaries survive budget pressure, rather than being silently dropped by position.
**Lineage:** Every pattern in `patterns.md` includes source reference IDs. Use `lcc_expand` to trace any pattern back to the original conversation.
```bash
# Run dream manually
lcc dream --run
# Dream for a specific project
lcc dream --run --project /path/to/project
# Cross-project dream
lcc dream --run --global
```
### Semantic Search (v1.1.0+)
Hybrid FTS5 + vector search, activated optionally. Default is FTS5-only — install nothing and the plugin behaves exactly as before.
**Enable semantic search:**
```bash
# Install the optional embedding dependency
pip install fastembed
# Turn it on in ~/.lossless-code/config.json
{"embeddingEnabled": true}
# Index your existing vault (one-time backfill)
lcc reindex --embeddings
```
**How it works:** New messages are embedded in the background after each session (same non-blocking pattern as dream auto-trigger). Queries combine FTS5 keyword results with vector cosine similarity using Reciprocal Rank Fusion (k=60). When hybrid search is active, `lcc grep` shows a `[hybrid]` tag on results.
**Provider tiers:**
- `fastembed` (default local): ONNX-based, no PyTorch, ~200 MB install. Default model: `BAAI/bge-small-en-v1.5`
- `openai` / `anthropic`: API-based, higher quality. Set `embeddingProvider` in config and export the API key
- Fallback: pure-Python numpy cosine similarity (no extra install, works for smaller vaults)
- Always: FTS5-only if no provider installed
**Config keys** (all optional, flat in `~/.lossless-code/config.json`):
| Key | Default | Description |
|-----|---------|-------------|
| `embeddingEnabled` | `false` | Master switch |
| `embeddingProvider` | `"local"` | `"local"`, `"openai"`, `"anthropic"` |
| `embeddingModel` | `"BAAI/bge-small-en-v1.5"` | Model name passed to provider |
| `ftsWeight` | `1.0` | RRF weight for FTS5 results |
| `vectorWeight` | `1.0` | RRF weight for vector results |
**Switching models:** Change `embeddingModel` and run `lcc reindex --embeddings --force` to re-embed with the new model.
**Check status:**
```bash
lcc status # shows "Vector search: active (fastembed, BAAI/bge-small-en-v1.5)"
# "Embeddings: 4,231 / 4,400 messages indexed (169 pending)"
```
### Fingerprint file context
When an agent is about to read or edit a file, lossless-code can surface a compact fingerprint of what the vault already knows about that path — prior summaries, last touched date, polarity (created/edited/discussed/mixed), and topic snippets — injected as `additionalContext` via the PreToolUse hook. An agent that already has recall is less likely to repeat past mistakes on the same file.
**Default off.** Flip the flag in `~/.lossless-code/config.json`:
```json
{"fileContextEnabled": true}
```
While off, the PreToolUse and PostToolUse hooks return immediately and the feature adds zero latency.
**How it works:**
1. PostToolUse records which file each `Read | Edit | Write | MultiEdit | NotebookEdit` call touched (stored on `messages.file_path`)
2. DAG summarisation tags summaries with a `kind` — `created | edited | discussed | mixed` — based on the tool calls in the chunk
3. PreToolUse walks `summary_sources` upward from the target file to ancestor summaries via a recursive CTE, renders a ~200-token fingerprint line, and caches it under `~/.lossless-code/cache/file_fingerprints.json` (60s TTL, file-locked reads/writes, single-flight guard)
4. Cold path opens `vault.db` read-only so the hook never blocks the writer
5. `lcc_expand --file ` (CLI) and `{"file": "..."}` (MCP) drill from a file path to the full recent summaries
**Check status:**
```bash
lcc status # shows "Fingerprint: 342 tagged messages across 57 files (12 cached)"
# (only displayed when fileContextEnabled is on)
```
### Storage
```
~/.lossless-code/
vault.db # SQLite: all messages, summaries, DAG, sessions, dream_log
config.json # Settings (summary model, thresholds, dream config)
scripts/ # Python modules and CLI tools
hooks/ # Shell scripts called by Claude Code hooks
cache/ # JSON cache for file-context fingerprints (when enabled)
dream/ # Dream output
reports/ # Timestamped dream reports
projects/ # Per-project pattern files (keyed by working dir hash)
global/ # Cross-project pattern files
dream.log # Dream cycle log (for debugging background execution)
```
## Configuration
`~/.lossless-code/config.json`:
```json
{
"summaryModel": "claude-haiku-4-5-20251001",
"summaryProvider": null,
"anthropicBaseUrl": null,
"openaiBaseUrl": null,
"chunkSize": 20,
"depthThreshold": 10,
"incrementalMaxDepth": 5,
"leafTargetTokens": 2400,
"condensedTargetTokens": 2000,
"summaryMaxOverageFactor": 3,
"workingDirFilter": null,
"autoDream": true,
"dreamAfterSessions": 5,
"dreamAfterHours": 24,
"dreamModel": "claude-haiku-4-5-20251001",
"handoffModel": null,
"dreamTokenBudget": 2000,
"dreamBatchSize": 100,
"contextTokenBudget": 8000,
"ignoreSessionPatterns": [],
"statelessSessionPatterns": [],
"circuitBreakerEnabled": true,
"circuitBreakerThreshold": 5,
"circuitBreakerCooldownMs": 1800000,
"dynamicChunkSize": { "enabled": true, "max": 50 },
"bundleEnabled": true,
"bundleTokenBudget": 1000,
"taskStateEnabled": true,
"taskStateTokenBudget": 200,
"codexTailImportProjectRoots": [],
"codexTailImportMaxFiles": 200,
"codexTailImportMaxTailLines": 120,
"codexTailImportMaxTailBytes": 120000,
"codexTailImportTimeoutMs": 1500,
"codexTailImportCodexHome": null,
"contractsModel": null,
"contractsPerCycleLimit": 5,
"decisionsPerCycleLimit": 10
}
```
| Key | Default | Description |
|-----|---------|-------------|
| `summaryModel` | `claude-haiku-4-5-20251001` | Model for compactions |
| `summaryProvider` | `null` | LLM provider: `null` (auto-detect), `anthropic`, `openai`, or `local` |
| `anthropicBaseUrl` | `null` | Custom Anthropic-compatible API endpoint (overrides `ANTHROPIC_BASE_URL` env) |
| `openaiBaseUrl` | `null` | Custom OpenAI-compatible endpoint (Ollama, Groq, Together AI, LM Studio, etc.) |
| `chunkSize` | `20` | Messages per compaction chunk (floor for dynamic chunk sizing) |
| `depthThreshold` | `10` | Max nodes at any depth before cascading |
| `incrementalMaxDepth` | `5` | Max cascade depth (prevents unbounded summary chains) |
| `leafTargetTokens` | `2400` | Target token count for depth-0 (leaf) summaries |
| `condensedTargetTokens` | `2000` | Target token count for depth-1+ (condensed) summaries |
| `summaryMaxOverageFactor` | `3` | Hard cap multiplier: summaries exceeding target × factor are truncated |
| `workingDirFilter` | `null` | Only capture messages from this directory |
| `autoDream` | `true` | Enable automatic dream trigger from stop hook |
| `dreamAfterSessions` | `5` | Sessions since last dream before auto-trigger |
| `dreamAfterHours` | `24` | Hours since last dream before auto-trigger |
| `dreamModel` | `claude-haiku-4-5-20251001` | Model for dream pattern extraction |
| `handoffModel` | `null` | Model for handoff generation (falls back to `summaryModel`) |
| `dreamTokenBudget` | `2000` | Max tokens for dream pattern injection on SessionStart |
| `dreamBatchSize` | `100` | Summaries loaded per batch during dream cycle (prevents OOM) |
| `contextTokenBudget` | `8000` | Max tokens for context injection (summaries + handoff + dreams). When a query is present, summaries are ranked by FTS5 BM25 relevance and packed greedily within this budget. Without a query, summaries are selected by DAG depth. Individual summaries are never truncated mid-content. |
| `fileContextEnabled` | `false` | Master switch for the [fingerprint file context](#fingerprint-file-context) feature. When off, the PreToolUse/PostToolUse hooks return immediately and no file paths are recorded. |
**v1.2 reference bundle and behavior contracts:**
| Key | Default | Description |
|-----|---------|-------------|
| `bundleEnabled` | `true` | v1.2 sole rollback flag. When `false`, SessionStart emits no additionalContext (the dream cycle, MCP tools, contracts queue, and TUI all keep working). Use this to A/B compare against a no-injection baseline or to disable injection on a CI runner. |
| `bundleTokenBudget` | `1000` | Total token budget for the SessionStart reference bundle. Header + recovery line cost is subtracted first; the remainder is divided across task state, contracts, handoff, decisions, and fingerprints. Lower values drop later slots first; the recovery line and header are last to lose space. |
| `taskStateEnabled` | `true` | Include the current-task-state slot at the front of the reference bundle. When task state is sparse, the bundle says so explicitly instead of pretending recall is complete. |
| `taskStateTokenBudget` | `200` | Token budget for the task-state slot. This slot is packed before contracts, handoff, decisions, and fingerprints. |
| `codexTailImportProjectRoots` | `[]` | Explicit project roots allowed to import latest local session tail task state. Empty means disabled. Use `lcc codex tail-import --enable` instead of editing this list by hand. |
| `codexTailImportMaxFiles` | `200` | Maximum local session files to inspect while looking for the latest matching project session. |
| `codexTailImportMaxTailLines` | `120` | Maximum JSONL lines read from the selected local session tail. |
| `codexTailImportMaxTailBytes` | `120000` | Maximum bytes read from the selected local session tail. |
| `codexTailImportTimeoutMs` | `1500` | Startup budget for project tail import before the hook falls back to the normal bundle path. |
| `codexTailImportCodexHome` | `null` | Optional override for the local Codex home used by tests or nonstandard installs. `null` uses `~/.codex`. |
| `contractsModel` | `null` | Model used by the dream cycle's Phase 1.5 contract extractor. When `null`, falls back to `dreamModel`. Set this to a smaller model if dream cycles are over budget on contracts/decisions extraction. |
| `contractsPerCycleLimit` | `5` | Maximum new Pending contracts the dream cycle proposes per run. Hard cap to keep the TUI approval queue tractable; further candidates are deferred to the next cycle. |
| `decisionsPerCycleLimit` | `10` | Maximum new decision-typed summaries the dream cycle records per run. Decisions ride in the SessionStart bundle's decisions slot once recorded. |
**Session filtering:**
| Key | Default | Description |
|-----|---------|-------------|
| `ignoreSessionPatterns` | `[]` | Glob patterns (Python `fnmatch`-style). Sessions matching these are completely ignored — no storage, no summarization. Example: `["cron:*", "agent:*:subagent:*"]` |
| `statelessSessionPatterns` | `[]` | Glob patterns. Sessions matching these store messages normally but skip dream/summarization passes. Useful for subagent sessions you want searchable but not summarized. |
**Summarization reliability (circuit breaker):**
| Key | Default | Description |
|-----|---------|-------------|
| `circuitBreakerEnabled` | `true` | Stop attempting LLM calls after consecutive failures |
| `circuitBreakerThreshold` | `5` | Number of consecutive failures before the breaker trips |
| `circuitBreakerCooldownMs` | `1800000` | 30 min: time before the breaker auto-resets and retries |
State is persisted in `~/.lossless-code/circuit_breaker.json` so the breaker survives across hook invocations.
**Dynamic chunk sizing:**
| Key | Default | Description |
|-----|---------|-------------|
| `dynamicChunkSize.enabled` | `true` | Scale chunk size up in busy sessions |
| `dynamicChunkSize.max` | `50` | Maximum chunk size; `chunkSize` is always the floor |
In sessions with many unsummarized messages, the chunk size grows up to `max`, producing fewer but larger summarization passes. Hard-capped at 500 regardless of config.
**Environment variable overrides:** Set `LOSSLESS_SUMMARY_PROVIDER`, `LOSSLESS_SUMMARY_MODEL`, or `LOSSLESS_DREAM_MODEL` to override config.json values. Useful for hooks and CI environments.
## Compaction Configuration
lossless-code **auto-detects your LLM provider** from environment. No configuration needed for most setups — if you have Claude Code installed, it just works.
### Auto-Detection (default)
When `summaryProvider` is `null` (the default), lossless-code checks in priority order:
1. `claude` CLI on PATH -> uses Claude CLI (works with Max/Pro subscriptions, $0)
2. `ANTHROPIC_API_KEY` -> uses Anthropic API directly
3. `OPENAI_API_KEY` -> uses OpenAI
4. `openaiBaseUrl` set -> uses OpenAI-compatible endpoint (Ollama, etc.)
5. Nothing found -> uses extractive fallback (no API needed, lower quality)
### Supported Providers
**Claude CLI (Claude Max/Pro subscription — $0)**
If you have [Claude Code](https://docs.anthropic.com/en/docs/claude-code) installed and authenticated, lossless-code uses it automatically. No API key needed — your existing subscription covers all LLM calls.
This is the highest-priority auto-detection option. If `claude` is on your PATH, it will be used unless you explicitly set `summaryProvider` to something else.
```json
{ "summaryProvider": "claude-cli", "summaryModel": "claude-haiku-4-5-20251001" }
```
Model examples: any model your subscription supports (`claude-haiku-4-5-20251001`, `claude-sonnet-4-20250514`)
> **Note:** Each LLM call spawns a `claude --print` subprocess, which adds ~2-5s overhead per call compared to direct API access. For most users this is invisible (summarisation runs in hooks), but heavy users may prefer a direct API key for faster throughput.
>
> Subprocesses run with `cwd=~/.lossless-code/.cli-cwd` so their per-CWD session files land in their own project bucket and don't pollute your interactive `claude --resume` list. To verify: `python3 scripts/check_summariser_pollution.py` (exit 0 = clean, 1 = polluting files listed).
**Anthropic**
Set `ANTHROPIC_API_KEY` in your environment. Get a key from [console.anthropic.com](https://console.anthropic.com).
> **Tip:** If you have a Claude Max/Pro subscription and don't want to manage a separate API key, use the Claude CLI provider above instead.
```json
{ "summaryProvider": "anthropic", "summaryModel": "claude-haiku-4-5-20251001" }
```
Model examples: `claude-haiku-4-5-20251001`, `claude-sonnet-4-20250514`
**OpenAI**
Set `OPENAI_API_KEY` in your environment.
```json
{ "summaryProvider": "openai", "summaryModel": "gpt-4.1-mini" }
```
Model examples: `gpt-4.1-mini`, `gpt-4.1-nano`, `gpt-4o-mini`
**Ollama (local, free)**
Run models locally with [Ollama](https://ollama.com). No API key needed.
```json
{
"summaryProvider": "openai",
"openaiBaseUrl": "http://localhost:11434/v1",
"summaryModel": "llama3"
}
```
Model examples: `llama3`, `mistral`, `phi3`, `gemma2`
**Groq / Together AI / Fireworks**
Any OpenAI-compatible provider works via `openaiBaseUrl`:
```json
{
"summaryProvider": "openai",
"openaiBaseUrl": "https://api.groq.com/openai/v1",
"summaryModel": "llama-3.1-8b-instant"
}
```
```bash
export OPENAI_API_KEY="your-groq-api-key"
```
**LM Studio**
```json
{
"summaryProvider": "openai",
"openaiBaseUrl": "http://localhost:1234/v1",
"summaryModel": "local-model"
}
```
**Custom Anthropic-compatible endpoints**
Any provider that exposes an Anthropic Messages API endpoint works (e.g. MiniMax, Cloudflare AI Gateway, custom proxies). Set `anthropicBaseUrl` in config (or `ANTHROPIC_BASE_URL` env var) and provide the provider's API key via `ANTHROPIC_API_KEY`.
```json
{
"summaryProvider": "anthropic",
"summaryModel": "MiniMax-M2.7",
"anthropicBaseUrl": "https://api.minimax.io/anthropic"
}
```
```bash
export ANTHROPIC_API_KEY="your-minimax-api-key"
```
Reasoning models that return `ThinkingBlock` responses are handled automatically.
Model examples: `MiniMax-M2.7`, `MiniMax-M2.7-highspeed`
**Local (extractive fallback)**
When no LLM provider is available, lossless-code uses TF-IDF sentence scoring to produce extractive summaries from your conversation history. No API keys, no cost, works everywhere. Quality is lower than LLM summaries but the vault stays fully functional.
```json
{ "summaryProvider": "local" }
```
### Cost Comparison
| Model | Input cost (per 1M tokens) |
|-------|---------------------------|
| Claude CLI (Max/Pro subscription) | $0 (included) |
| Ollama / local models | $0 |
| Extractive fallback (no API) | $0 |
| `gpt-4.1-nano` | ~$0.10 |
| `gpt-4o-mini` | ~$0.15 |
| `MiniMax-M2.7` | ~$0.30 |
| `gpt-4.1-mini` | ~$0.40 |
| `claude-haiku-4-5-20251001` (API) | ~$0.80 |
| `claude-sonnet-4-20250514` (API) | ~$3.00 |
### Estimated Monthly Costs
| Usage | Claude CLI (Max/Pro) | Ollama (free) | gpt-4.1-nano | gpt-4.1-mini | claude-haiku (API) |
|-------|---------------------|--------------|-------------|-------------|-------------------|
| Light (1-2 sessions/day) | $0 | $0 | $0.20-0.60 | $1-3 | $2-6 |
| Moderate (3-5 sessions/day) | $0 | $0 | $0.60-1.50 | $3-7 | $6-14 |
| Heavy (10+ sessions/day) | $0 | $0 | $1.50-3.00 | $7-15 | $14-30 |
Compactions are triggered automatically before context compaction (PreCompact hook) and at session end (Stop hook). The extractive fallback runs automatically when no API key is configured: no hard dependency on any LLM provider.
## CLI Usage
The `lcc` CLI provides direct access to vault operations.
```bash
# Run compaction manually
lcc summarise --run
# Run compaction for a specific session
lcc summarise --run --session
# Check vault status
lcc status
# Search all messages and summaries
lcc grep "auth refactor"
# Show handoff from last session
lcc handoff
# Generate and save a handoff for current session
lcc handoff --generate --session "$CLAUDE_SESSION_ID"
# List recent sessions
lcc sessions
# Expand a summary node
lcc expand sum_abc123def456
# Run dream cycle
lcc dream --run
# Dream for a specific project directory
lcc dream --run --project /path/to/project
```
## Schema
```sql
sessions -- session_id, working_dir, started_at, last_active, handoff_text
messages -- id, session_id, turn_id, role, content, tool_name, working_dir, timestamp, summarised
summaries -- id, session_id, content, depth, token_count, created_at, consolidated
summary_sources -- summary_id, source_type, source_id
dream_log -- id, project_hash, scope, dreamed_at, patterns_found, consolidations, sessions_analyzed, report_path
messages_fts -- FTS5 index on messages.content
summaries_fts -- FTS5 index on summaries.content
```
## Uninstall
```bash
rm -rf ~/.lossless-code
# Remove hooks from ~/.claude/settings.json manually
# Remove skill: rm -rf ~/.claude/skills/lossless-code
```
## Prior Art and Acknowledgements
lossless-code is a Claude Code adaptation of the **Lossless Context Management (LCM)** architecture created by [Jeff Lehman](https://github.com/jalehman) and the [Martian Engineering](https://github.com/Martian-Engineering) team. Their [lossless-claw](https://github.com/Martian-Engineering/lossless-claw) plugin for [OpenClaw](https://github.com/openclaw/openclaw) proved that DAG-based context preservation eliminates the information loss problem in long-running AI sessions. lossless-code brings that same architecture to Claude Code.
Additional references:
- [ClawMem](https://github.com/yoloshii/clawmem) by yoloshii (hooks architecture patterns)
- [Voltropy LCM paper](https://papers.voltropy.com/LCM) (theoretical foundation)
## Contributing
Contributions are welcome! Please:
1. Fork the repository
2. Create a feature branch (`git checkout -b feat/your-feature`)
3. Write tests for new functionality
4. Ensure tests pass
5. Open a pull request
## Roadmap
lossless-code currently supports **Claude Code** natively. The hook and plugin ecosystem across coding agents is converging fast, and we're tracking compatibility:
| Agent | Hook Support | MCP | Status | Notes |
|-------|-------------|-----|--------|-------|
| **Claude Code** | 20+ lifecycle events | ✅ | ✅ Supported | Full plugin with hooks, MCP, skills |
| **Copilot CLI** | Claude Code format | ✅ | 🟢 Next | Reads `hooks.json` natively; lowest adaptation effort |
| **Codex CLI** | SessionStart, Stop, UserPromptSubmit | ✅ | 🟢 Start continuity | `SessionStart` bundle, doctor checks, MCP setup, launcher fallback, and project opt-in latest-tail task state. Prompt capture and full transcript import remain planned |
| **Gemini CLI** | BeforeTool, AfterTool, lifecycle | ✅ | 🟡 Planned | Different event names; needs thin adapter layer |
| **OpenCode** | session.compacting + plugin hooks | ✅ | 🔵 Researching | Plugin architecture differs; compacting hook maps to PreCompact |
Current Codex support focuses on safe start-of-thread continuity: MCP pull-on-demand recall, a bounded `SessionStart` bundle, readiness checks, launcher fallback, and opt-in latest-tail task state. Roadmap items from the compatibility planning remain prompt capture, stop/transcript import, richer project review tools, and adapter work for other hook-capable CLIs.
> **MCP works everywhere today.** Any agent that supports MCP servers can already use `lcc_grep`, `lcc_expand`, `lcc_context`, `lcc_sessions`, `lcc_handoff`, and `lcc_status` for manual recall. The roadmap above tracks *automatic* capture via hooks.
Contributions welcome for any of the planned integrations.
## Star History
## Contributors
[](https://github.com/GodsBoy)
## Licence
MIT
---
**If lossless-code helps your workflow, consider giving it a ⭐**
[Report Bug](https://github.com/GodsBoy/lossless-code/issues/new?labels=bug) · [Request Feature](https://github.com/GodsBoy/lossless-code/issues/new?labels=enhancement)