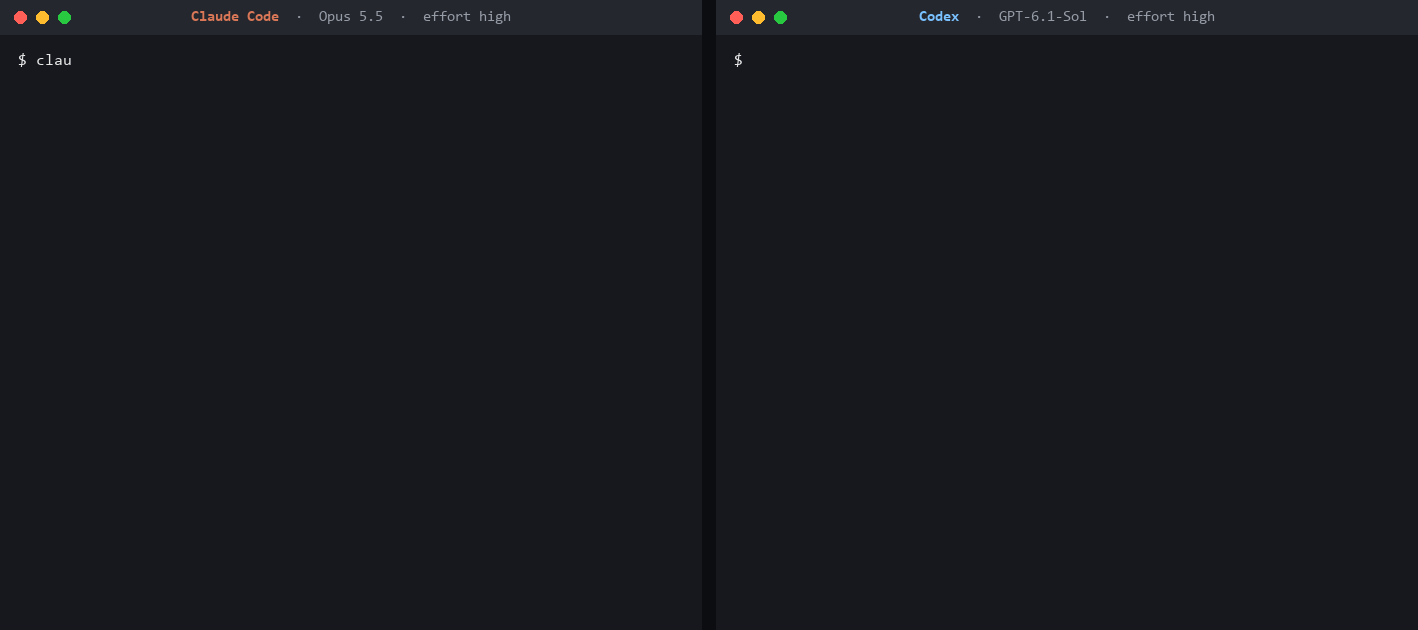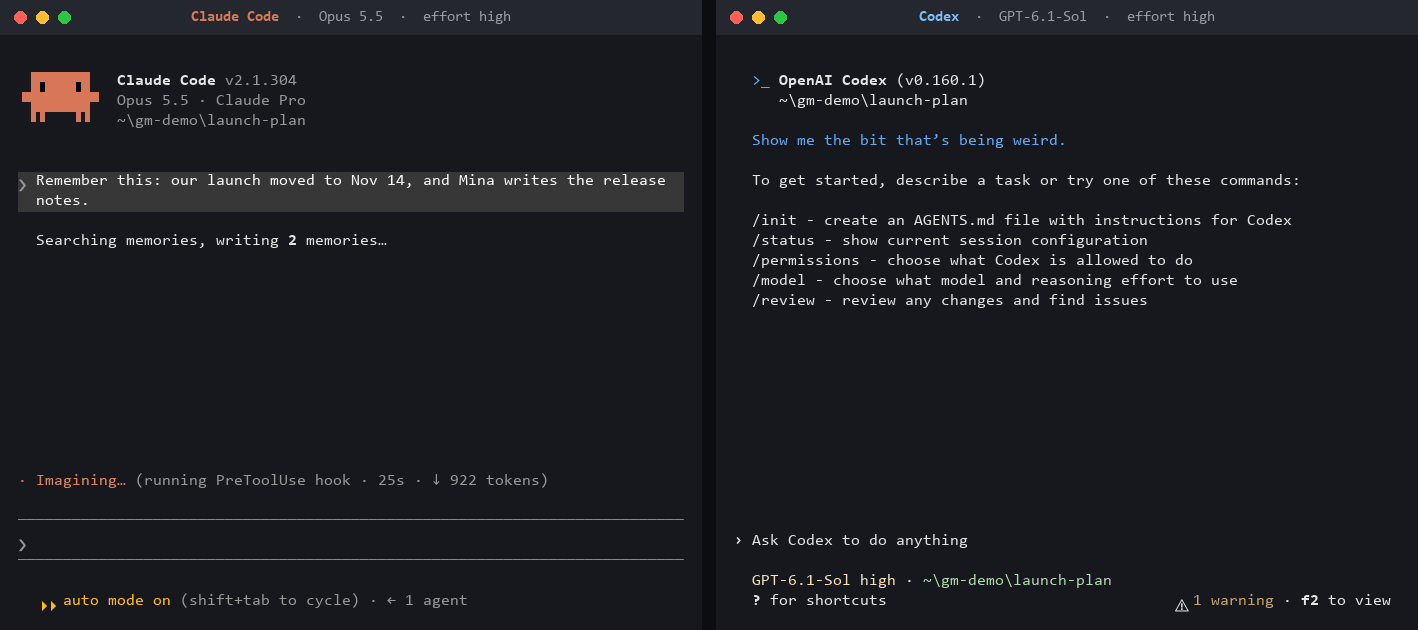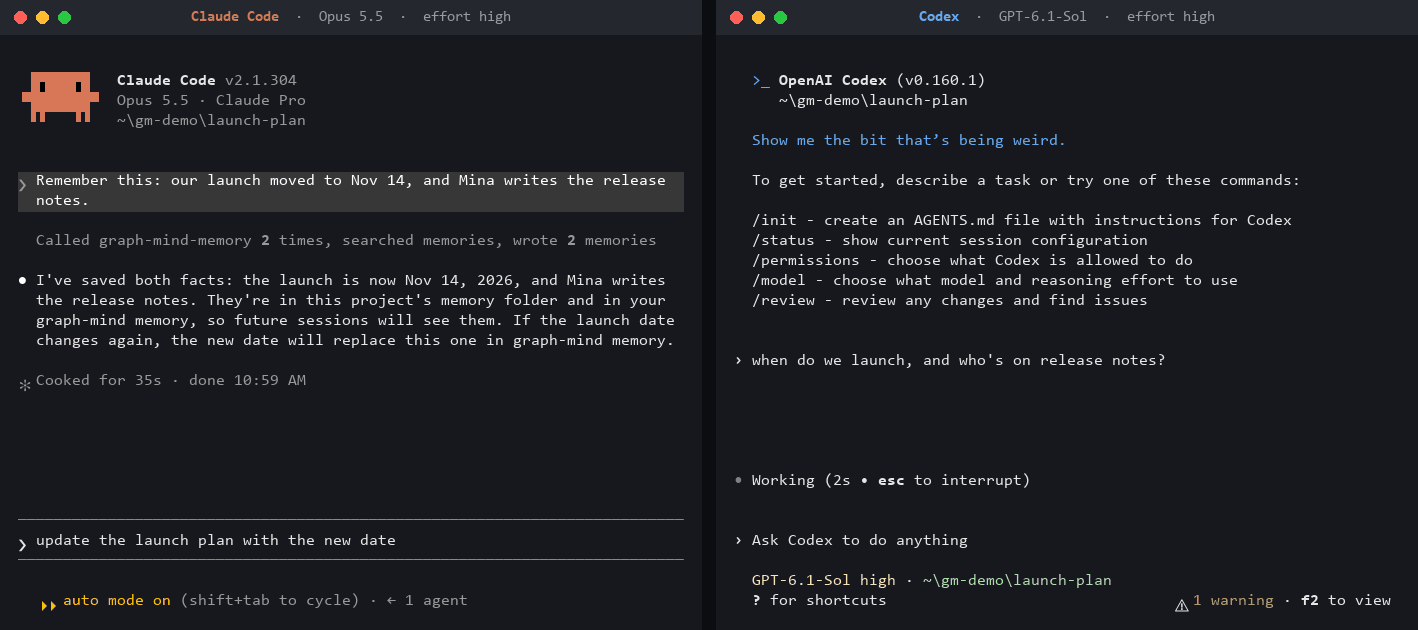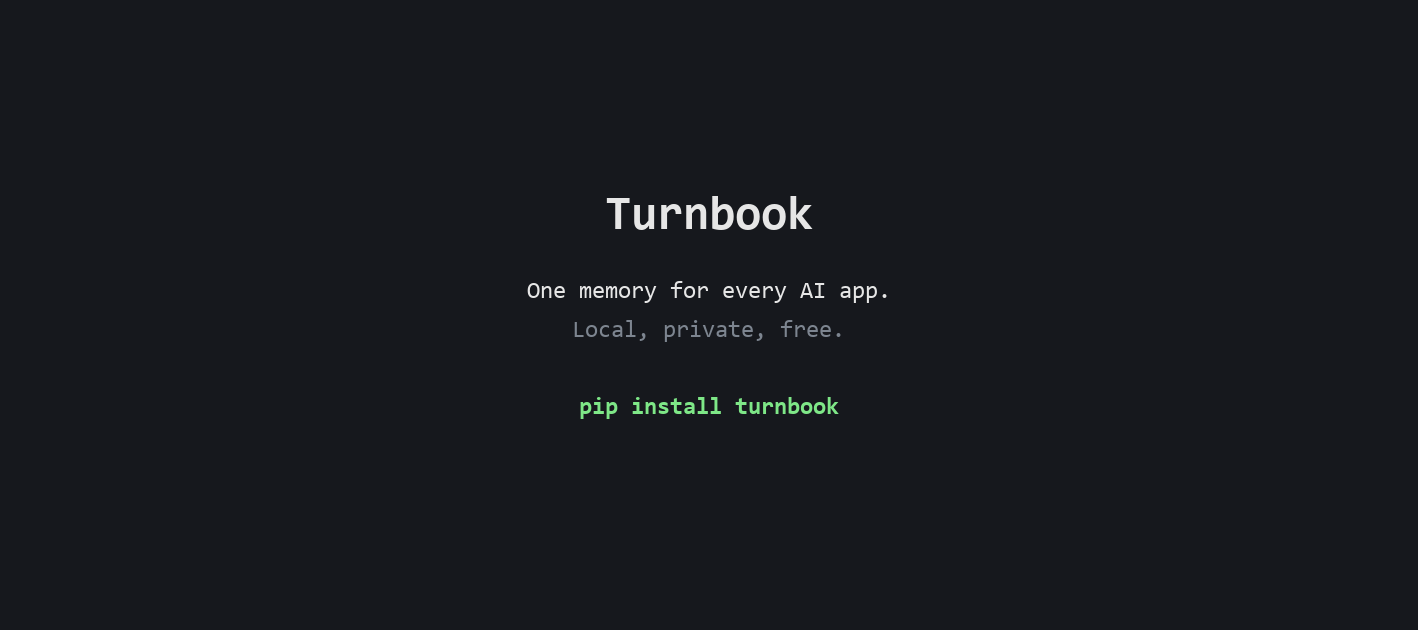
Turnbook # Turnbook ### Your AI forgets everything when the session ends. This one remembers, and it never calls an LLM to do it. **88.8% on LongMemEval. Zero model tokens spent saving memory. Runs on your own PC.** [![][license-shield]][license-link] [![][python-shield]][python-link] [![][platform-shield]][platform-link] [![][longmemeval-shield]][benchmarks-link] [![][ci-shield]][ci-link] [![][pypi-shield]][pypi-link] [![goyohan0611-png/turnbook MCP server](https://glama.ai/mcp/servers/goyohan0611-png/turnbook/badges/score.svg)](https://glama.ai/mcp/servers/goyohan0611-png/turnbook) [![Listed on mcpservers.org](https://mcpservers.org/badge.svg)](https://mcpservers.org/servers/goyohan0611-png/turnbook) [![Mentioned in Awesome MCP Servers](https://awesome.re/mentioned-badge.svg)](https://github.com/punkpeye/awesome-mcp-servers#knowledge--memory) *Decide something with one agent on Monday. Ask another on Wednesday. It knows.* **English** · [한국어](README.ko.md) Recorded live: Claude Code saves a decision to Turnbook, and Codex, a different app, recalls it Recorded live on one PC: Claude Code (Opus 5.5, effort high) and Codex (GPT-6.1-Sol, effort high) sharing one Turnbook memory. Model thinking time is fast-forwarded.

## Install Windows: download [Turnbook-Setup.cmd](https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/Turnbook-Setup.cmd) and double-click it, or in PowerShell: ```powershell irm https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.ps1 | iex ``` macOS / Linux: ```bash curl -LsSf https://raw.githubusercontent.com/goyohan0611-png/turnbook/main/scripts/install.sh | sh ``` No Python needed; nothing else to set up. Restart your AI apps afterwards. Already have Python? `pip install turnbook && turnbook-install`. More: [docs/install.md](docs/install.md).
Connecting an MCP client by hand After `pip install turnbook`: ```json { "mcpServers": { "turnbook": { "command": "python", "args": ["-m", "graph_mind.mcp_server"] } } } ``` Claude Code: `claude mcp add turnbook -- python -m graph_mind.mcp_server`. This gives the tools only; `turnbook-install` also saves every conversation automatically.
## Try it Work as usual for a while, then open a new session, another app, or another model and ask: - *"Where did we leave off yesterday?"* - *"Which database did we pick for the billing service, and why?"* - *"What did you change in the auth middleware last week?"* - *"What's my dog's name?"* (any fact you mentioned once, in passing) Nothing to tag or save by hand: every turn is already stored, and the agent pulls back the few that answer the question. ## What it does - **One shared brain for every agent in your terminal.** Whichever coding agent or model you run, they all read and write the same memory. Switch agents or models; the memory stays. - **Made for orchestration.** When an orchestrator runs several agents at once, they all write to the same memory as they work, so what one agent decided is there for the next. Every memory keeps which app and session it came from. - **Remembers conversations word for word**, on your own PC. Saving is a database write: no model call, no tokens. When a question depends on the past, the agent gets back the few thousand tokens that answer it. Korean and English. - **One memory across your PCs.** Run `turnbook folder share`, then `turnbook folder ` on the other PC (the AI tells you the command; it never moves your memory by itself, so a web page cannot either). Office network or [Tailscale](https://tailscale.com), over TLS, every line encrypted before it leaves a PC. - **Hand a memory to someone else as a file.** `turnbook export FILE` writes all of it; `--project FOLDER` writes only the conversations held in that folder. They run `turnbook import FILE`. - **Yours.** No account, no cloud of its own, no telemetry. Secrets are masked before anything is stored, and *"delete the password I typed earlier"* deletes it everywhere. [docs/privacy.md](docs/privacy.md) - **Teams, if you want them.** Share a project's decisions and progress with teammates' AIs, never your personal memory; files stay in Slack and GitHub. [docs/teams.md](docs/teams.md) ## Works with The installer finds these and connects them; run it again after installing a new one. | app | conversations saved | how | |---|---|---| | Claude Code | every turn | reads its transcripts | | Codex CLI | every turn | reads its transcripts | | Cursor | every turn | reads its transcripts | | Copilot CLI | every turn | reads its transcripts | | Claude Desktop (Cowork) | every turn | reads its session files | | Gemini CLI | every turn | hooks; also adds relevant memory before each answer | | OpenCode | every turn | plugin; also adds relevant memory before each answer, for any model | | Claude Desktop chat, Windsurf, VS Code Copilot, Cline, LM Studio | what the model saves | MCP tools | Any other MCP client works through the tools: see the hand-written config above. ## How it works ```mermaid flowchart LR A["Claude Code · Codex · Cursor
Gemini CLI · OpenCode · ..."] -- "transcripts, hooks, plugin" --> C["capture service
(runs in the background)"] C -- "verbatim turns,
secrets masked" --> S[("your memory
on this PC")] S --> I["local search
words + meaning + time"] A -- "a question that needs the past" --> I I -- "the few turns that answer it
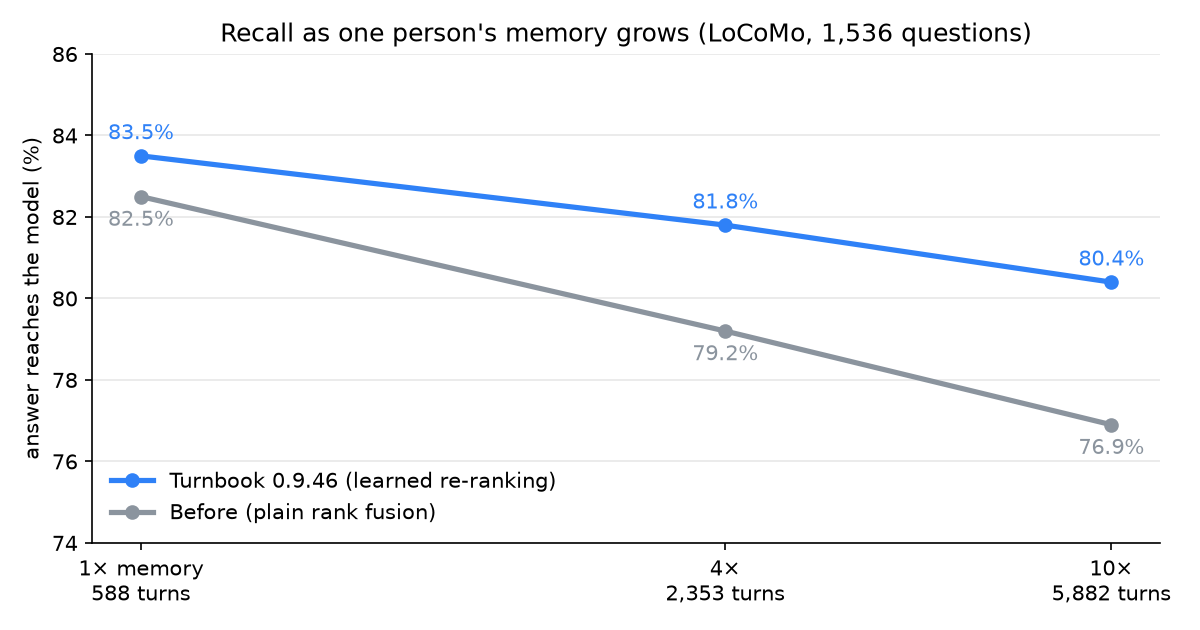
(~3k tokens)" --> A ``` - **Saving costs nothing.** Turns are stored as they were said. No model summarises or extracts anything at write time, so nothing is lost or invented on the way in, and no tokens are spent. - **Search runs on your PC.** Word search, a multilingual embedding model (mpnet, int8; ONNX, no GPU) and when things were said are combined; the agent gets a short packet with the source turns, not a dump of history. - **The model you already use does the thinking.** Turnbook hands it evidence; it answers. When models get better, the answers get better without changing the memory. ## Does it work? [LongMemEval](https://github.com/xiaowu0162/LongMemEval) is the public benchmark for long-term chat memory: 500 questions over about 50 past sessions each. Every system below got the same answer model (gpt-5-mini), the same prompt and the official gpt-4o judge; only the memory differs. | | accuracy | model tokens spent **saving** memory | text the answer model reads | |---|---|---|---| | **Turnbook** | **88.8%** (all 500) | **0** | **3.4k tokens** | | agentmemory | 80.4% (same 499) | — | ~16.5k tokens | | MemPalace 3.10.0 | 57.5% (40 questions) | 0 | — | | Mem0 2.2.1 (open source) | 52.5% (40 questions) | ~640,000 per question | — | On agentmemory's 499 Turnbook scored 89.0%; on the 40, 85.0%. Retrieval alone, on agentmemory's own measure (an answer session among the first 5 retrieved): Turnbook 98.5%, agentmemory 95.2%. These runs used the embedding model of 0.9.9 and before; on a 100-question sample the current one finds the answer session as often or more (among the first 5: 99.0% against 97.9%). ### As the memory grows Recall gets harder as memory piles up: more past conversations look like the one you mean. Since 0.9.46 Turnbook orders what it finds with a small learned score instead of a fixed blend. On LoCoMo (1,536 questions), with each person's memory grown to 10× by storing other conversations beside it, the share of questions whose answer reaches the model fell 5.6 points before (82.5% → 76.9%) and 3.1 points now (83.5% → 80.4%). Each conversation was scored with weights learned on the other nine; the added conversations are other people's, likely easier to tell apart than one person's own history. On LongMemEval the same change took the answer reaching the model from 97.5% to 98.3%.

Recall at 1x, 4x and 10x memory: 83.5 to 80.4 percent with learned re-ranking, 82.5 to 76.9 percent before

Every question, answer and verdict is in [`research/runs/`](research/runs); method, failures and how to rerun it: [docs/benchmarks.md](docs/benchmarks.md). ## FAQ **Will it slow my PC down?** The background service uses about 2% of one CPU core when nothing new is coming in and about 650 MB of memory, most of it the search model. A memory search takes about 20 ms (41 ms at the 95th percentile on a GitHub runner); the first one after an app starts, about 1.3 s. After an update that changes the search model, it reads the memory again once, at half pace (about an hour for 11,000 pieces). **What does it cost?** Nothing. No API key and no model calls of its own; your AI app reads a packet of about 3k tokens when a question needs the past. **Does anything leave my PC?** No, unless you share the memory with your own other PCs or a team. No telemetry. Secrets (API keys, passwords, card numbers...) are masked before storing. **How is this different from CLAUDE.md or an app's built-in memory?** Those keep notes a model wrote, one app at a time. Turnbook keeps every turn as it was said and shares it across every app and model on the PC. **Korean?** Yes: Korean and English conversations, and questions in either language. A Korean question about something said only in English is found most of the time, not always. **How do I remove it?** `turnbook-uninstall` disconnects every app and stops the service; the memory stays in `~/.graph-mind` unless you add `--purge`. > [!NOTE] > **Beta.** Used daily on Windows. macOS and Linux pass every test in CI but have not seen daily > use yet. ## More [MCP tools](docs/install.md#mcp-tools) · [See your memory in 3D](docs/privacy.md#seeing-your-memory) (`turnbook-view`) · [Changelog](CHANGELOG.md) · [Security](SECURITY.md) · Development: `pip install -r requirements.txt`, then `python -m unittest discover -s tests` Contributions are welcome. License: [Apache-2.0](LICENSE). [license-shield]: https://img.shields.io/badge/license-Apache--2.0-4dc9f6?style=flat-square [license-link]: LICENSE [python-shield]: https://img.shields.io/badge/python-3.10+-7dd8f8?style=flat-square&logo=python&logoColor=white [python-link]: https://www.python.org/ [platform-shield]: https://img.shields.io/badge/platform-Windows%20%7C%20macOS%20%7C%20Linux-b0e8ff?style=flat-square [platform-link]: docs/benchmarks.md#known-limits [longmemeval-shield]: https://img.shields.io/badge/LongMemEval-88.8%25-2ea44f?style=flat-square [benchmarks-link]: docs/benchmarks.md [ci-shield]: https://img.shields.io/github/actions/workflow/status/goyohan0611-png/turnbook/tests.yml?style=flat-square&label=tests [ci-link]: https://github.com/goyohan0611-png/turnbook/actions/workflows/tests.yml [pypi-shield]: https://img.shields.io/pypi/v/turnbook?style=flat-square&label=pypi&cacheSeconds=3600 [pypi-link]: https://pypi.org/project/turnbook/