Patent Pending | MIT License | Patent Details
# Comfy Cozy
**The production-grade local counterpart to Comfy Cloud MCP — your GPU, your models, reversible, provable.**
**Talk to ComfyUI like a colleague. It talks back.**
- **Local execution** — renders on *your* GPU, against *your* models, on *your* disk
- **Surgical, validated edits** — small reversible changes, never rewrites; every edit is one `undo` away
- **Zero-LLM recipes** — "dreamier", "sharper", "faster" apply as instant, deterministic macros
- **Provenance** — `workflow.lock` pins model SHA-256s + pack commits; drift warns at validate
- **6 swappable LLM brains** — Claude, GPT-4o, Gemini, Ollama, NVIDIA Nemotron, or any OpenAI-compatible endpoint
> **TL;DR** *(each line stands alone — take what you need)*
> - **Plain-English co-pilot for ComfyUI.** You describe the change; the agent does it.
> - **134 MCP tools · 6 LLM providers** — Claude, GPT-4o, Gemini, Ollama, NVIDIA Nemotron, or *any* OpenAI-compatible endpoint (`custom`). Swap with one env var or mid-session — your pick sticks across restarts, and it won't switch you to a model that can't run the tools.
> - **Zero-LLM recipes.** "Dreamier", "sharper", "faster" — common intents apply as instant, deterministic parameter macros. No API call, no wait, fully undoable.
> - **Keyless run reports.** Every render leaves a structured report — env fingerprint, per-node timings, and an *explained* finding for every anomaly. `agent diagnose --last`. No API key in that path, ever.
> - **Everything is undoable.** Reversible delta layers (LIVRPS), full undo stack, nothing destructive without your say-so.
> - **It learns you.** ~30 runs in, it starts biasing toward what actually worked for *your* renders. Crash-safe, append-only.
> - **Fast edit loop.** Validate → fix → re-validate without re-fetching the node registry — cached, instant. Downloads resume from the dead byte.
> - **Built for the VFX floor.** Linear EXR into the vision loop · `workflow.lock` provenance sidecars · multi-worker endpoint pooling with failover.
> - **Ships three ways:** inside Claude Code/Desktop (MCP) · standalone CLI · native ComfyUI sidebar.
**Jump to what you need:**
| You want to... | Go to |
|---|---|
| Get running in 2 minutes | [Get Running](#get-running) |
| Compare with the cloud twin | [Where it sits](#where-it-sits) |
| See what talking to it looks like | [See It In Action](#see-it-in-action) |
| Put it inside ComfyUI | [Connect the Sidebar](#connect-the-sidebar-to-comfyui) |
| Pick / swap your LLM | [Pick Your LLM](#pick-your-llm) |
| Instant parameter macros | [Zero-LLM Recipes](#zero-llm-recipes-instant-artist-speak) |
| Know why a render was slow/broken | [Run Reports](#run-reports-why-was-that-slow--keyless) |
| Let it run overnight | [Autonomous Mode](#autonomous-mode) |
| Understand the machinery | [How It Works](#how-it-works) · Architecture Deep Dive (expandable, below) |
> **Maturity legend** — Unless flagged otherwise, a feature is **on by default**. **Opt-in** = one extra install or env flag, always called out inline (e.g. the USD stage layer via `pip install -e ".[dev,stage]"`, the Agent Bridge node pack, or the BGE embedder).
### Install
```bash
pip install comfy-cozy # the package
uvx comfy-cozy mcp # or zero-install, straight to the MCP server
```
### 60 seconds to Claude Code
1. **Install** — `pip install comfy-cozy` (above).
2. **Register the MCP server** — add this to your Claude Code / Claude Desktop MCP config:
```json
{
"mcpServers": {
"comfy-cozy": {
"command": "comfy-cozy",
"args": ["mcp"]
}
}
}
```
3. **Start ComfyUI** (if it isn't already running).
4. **Talk to it** — *"load my portrait workflow and make it dreamier."* Claude drives all 133 tools from there.
### The local twin, in one picture
```mermaid
flowchart LR
Client["Claude Code /
any MCP client"] --> Cozy["comfy-cozy MCP server
133 tools · validate-first gate · undo"]
Cozy --> GPU["ComfyUI on YOUR GPU
your models · your disk"]
Client -.->|"the cloud twin"| Cloud["Comfy Cloud MCP"]
Cloud -.-> CGPU["cloud GPUs"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Client,Cloud,CGPU orange
class Cozy,GPU yellow
```
### Where it sits
*No swipes — all three solve real problems. This is about where your pixels get made.*
| | Comfy Cloud MCP | **Comfy-Cozy** | raw comfy-cli |
|---|---|---|---|
| **Execution locus** | cloud GPUs | **your local GPU** | your local GPU |
| **Custom workflow edits** | runs your saved workflows (converted for cloud) | **surgical, validated edits — 133 tools** | manual JSON / CLI flags |
| **Undo / reversibility** | — | **full undo stack + reversible delta layers** | — |
| **Provenance (`workflow.lock`)** | — | **model SHA-256s + pack commits, drift warnings** | — |
| **Works offline** | no — cloud service (OAuth / API key) | **yes** | yes |
| **Cost model** | cloud compute | **free — your hardware, MIT** | free — your hardware |
*— = not part of that tool's documented surface. Cloud MCP's outputs come back via download; Comfy-Cozy's never leave your disk.*
---
## You describe. It does. You never touch JSON.
- Say what you want in plain English — it loads workflows, swaps models, tweaks parameters, installs missing nodes, runs generations, analyzes outputs.
- **Edits don't wait for permission.** It makes the change, tells you what it did. Everything is undoable.
- **One exception, always:** installing node packs or downloading models. That pulls code onto your machine, so it asks first. Every time.
- It **learns your style.** Session 100 knows what session 1 didn't.
```mermaid
graph LR
You([You]) -->|"make it dreamier"| Agent[Comfy Cozy]
Agent -->|loads, patches, runs| ComfyUI[ComfyUI]
ComfyUI -->|image| Agent
Agent -->|"Done. Lowered CFG to 5,
switched to DPM++ 2M Karras.
Here's your render."| You
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class You,ComfyUI orange
class Agent yellow
```
> **Session 1** is a capable tool.
> **Session 100** is a capable tool that knows your style.
---
## Demo
**Demo 1 — overview**
[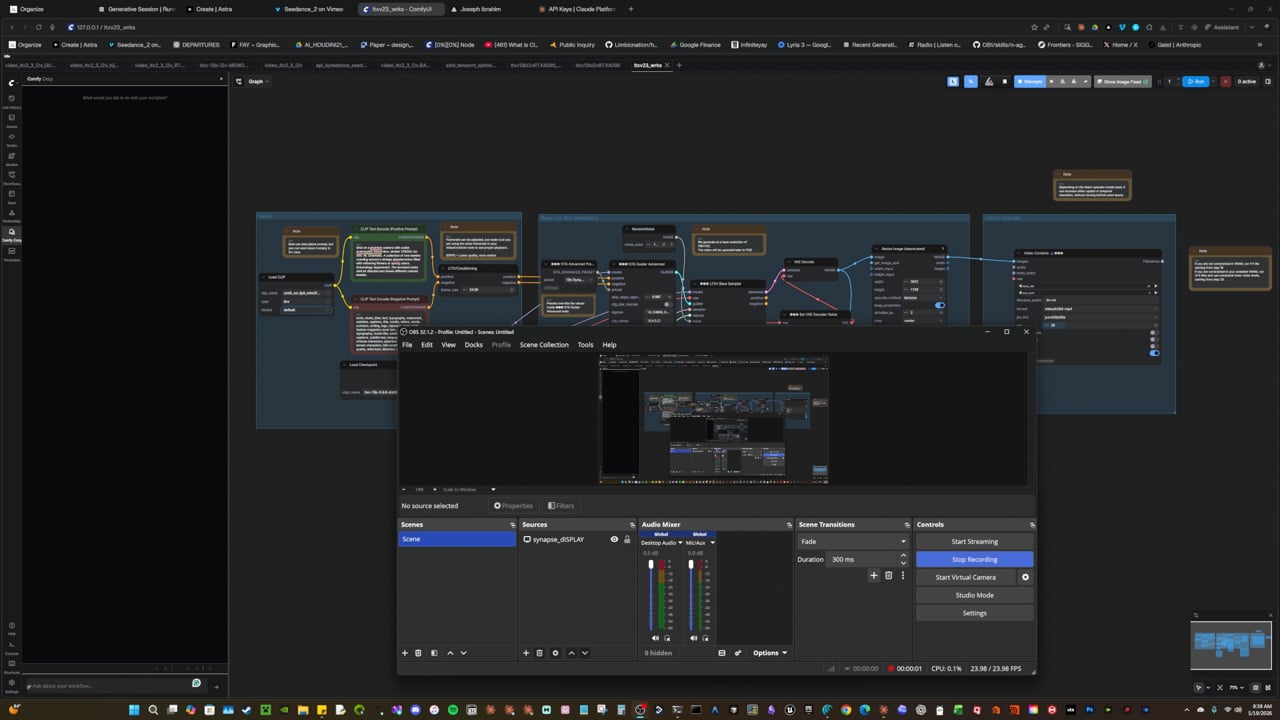](https://vimeo.com/1193607778)
**Demo 2 — walkthrough**
[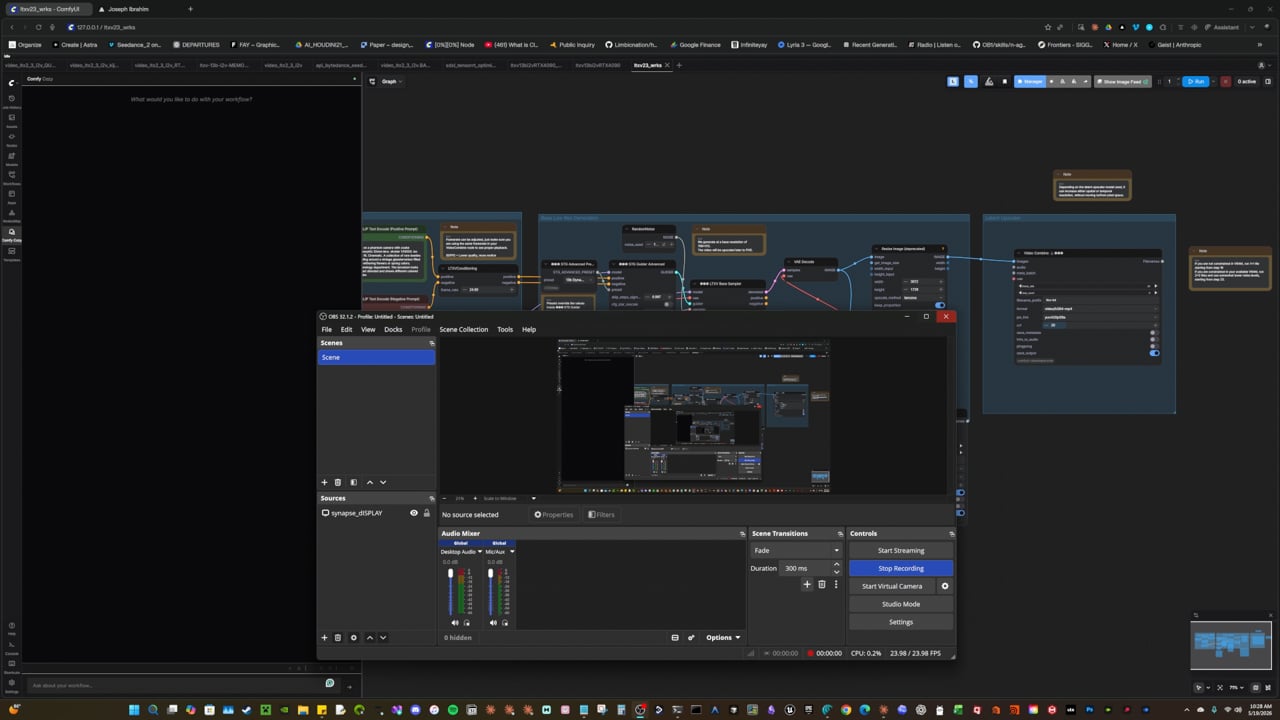](https://vimeo.com/1193622319)
## See It In Action
| You say | What happens |
|---------|-------------|
| *"Load my portrait workflow and make it dreamier"* | Loads the file, applies the **dreamier recipe** — CFG down, sampler switched — instantly, no LLM round-trip, full undo |
| *"I want to use Flux"* | Searches CivitAI + HuggingFace, downloads the model on your go-ahead, wires it into your workflow |
| *"Repair this workflow"* | Finds missing nodes, shows you the packs it needs, installs them once you approve, fixes connections, migrates deprecated nodes |
| *"Run this with 30 steps"* | Patches the workflow, validates it, queues it to ComfyUI, shows progress |
| *"Analyze this output"* | Uses Vision AI to diagnose issues and suggest parameter changes |
| *"What model should I use for anime?"* | Searches CivitAI + HuggingFace + your local models, recommends the best fit |
| *"Optimize this for speed"* | Profiles GPU usage, checks TensorRT eligibility, applies optimizations |
| *"Repair and run this"* | Finds missing nodes, asks once to install the packs, validates, executes |
---
---
## Get Running
```mermaid
flowchart LR
A["Install"] -->|30 sec| B["Paste key"]
B -->|done| C(["comfy-cozy run"])
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class C orange
class A,B yellow
```
**Three prerequisites, three copy-paste steps. Under 2 minutes start to finish.**
| | What you need | Where to get it | Time |
|---|------|-----------------|------|
| 1 | **Python 3.11+** | [python.org/downloads](https://python.org/downloads) | already have it? skip |
| 2 | **ComfyUI running** | [github.com/comfyanonymous/ComfyUI](https://github.com/comfyanonymous/ComfyUI) | already have it? skip |
| 3 | **One LLM backend** | API key (Anthropic / OpenAI / Google / [NVIDIA](https://build.nvidia.com)) OR [Ollama](https://ollama.com) (free, local, no key) | 1 min to grab a key |
**Already have all three? Copy-paste these three blocks. That's it.**
### 1. Install
```bash
pip install comfy-cozy
```
*(Prefer working from source? The dev path:)*
```bash
git clone https://github.com/JosephOIbrahim/Comfy-Cozy.git
cd Comfy-Cozy
pip install -e .
```
One command. No build step. No Docker. No conda. Just pip.
Want the test suite too? (optional, click to expand)
```bash
pip install -e ".[dev]" # + 4,680+ passing tests
pip install -e ".[dev,stage]" # + USD stage subsystem (~200MB, most users skip)
```
### 2. API key
**Installed from PyPI / a wheel?** Create `~/.comfy-cozy/.env`.
**Running from a checkout?**
```bash
cp .env.example .env
```
Either way, open `.env` in any text editor and paste your key on the first line:
```bash
ANTHROPIC_API_KEY=sk-ant-your-key-here
```
> The agent looks for `.env` in `~/.comfy-cozy/` first, then the checkout root. Your current directory is deliberately not searched.
Using OpenAI, Gemini, or Ollama instead? (click to expand)
Pick one block, paste into `.env`:
```bash
# --- OpenAI ---
LLM_PROVIDER=openai
OPENAI_API_KEY=sk-your-key-here
# first time only: pip install openai
# --- Gemini ---
LLM_PROVIDER=gemini
GEMINI_API_KEY=your-key-here
# first time only: pip install google-genai
# --- Ollama (fully local, free, no key) ---
LLM_PROVIDER=ollama
AGENT_MODEL=llama3.1
# first time only: ollama pull llama3.1
```
ComfyUI installed somewhere non-default? (click to expand)
Add one more line to `.env`:
```
COMFYUI_DATABASE=C:/path/to/your/ComfyUI
```
### 3. Go
```bash
comfy-cozy run
```
Type what you want. Type `quit` when you're done.
> `cozy` is the short alias for the same command. The old `agent` entry point still works but is **deprecated** — it prints a migration notice.
---
## Connect the Sidebar to ComfyUI
The agent also lives **inside ComfyUI** as a native sidebar panel. To enable it, create two symlinks from ComfyUI's `custom_nodes/` folder to Comfy-Cozy:
**Windows (run as Administrator):**
```cmd
cd C:\path\to\ComfyUI\custom_nodes
mklink /D comfy-cozy-panel C:\path\to\Comfy-Cozy\panel
mklink /D comfy-cozy-ui C:\path\to\Comfy-Cozy\ui
```
**Linux / macOS:**
```bash
cd /path/to/ComfyUI/custom_nodes
ln -s /path/to/Comfy-Cozy/panel comfy-cozy-panel
ln -s /path/to/Comfy-Cozy/ui comfy-cozy-ui
```
Restart ComfyUI. The Comfy Cozy chat panel appears in the **left sidebar**.
```mermaid
graph LR
CN["ComfyUI/custom_nodes/"] --> P["comfy-cozy-panel/ (symlink)"]
CN --> U["comfy-cozy-ui/ (symlink)"]
P -->|"canvas sync (headless)"| Panel["panel/__init__.py"]
U -->|"sidebar + chat"| UI["ui/__init__.py"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class CN,U orange
class P,sync,Panel,UI yellow
```
**Both symlinks are required:**
- **`comfy-cozy-panel`** -- Canvas sync bridge (runs headlessly -- keeps the agent in sync with your live graph)
- **`comfy-cozy-ui`** -- The visible sidebar: chat window, quick actions, status
---
## Optional: the Agent Bridge node pack (live canvas + render timing)
Want the agent to **load workflows straight onto your canvas**, **see the edits you make by hand**, and **tell you exactly which node ate your render time**? Install the one extra node pack. It's optional -- everything else works without it -- but it unlocks three things ComfyUI's stock API can't give the agent.
```mermaid
graph LR
Agent[Comfy Cozy] -->|"push_workflow_to_canvas"| Gate{"Origin + Bearer
gate"}
Gate -->|"POST /agent/push_workflow"| Canvas["Your ComfyUI canvas
(every open tab reloads)"]
Canvas -->|"you hand-edit a node"| Gate
Gate -->|"POST /agent/canvas_changed"| Buf["canvas buffer"]
Buf -->|"get_canvas_state"| Agent
Render["Your render finishes"] -->|"per-node timing"| Prof["GET /agent/exec_profile/{id}"]
Prof -->|"get_execution_profile"| Agent
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Canvas,Render orange
class Agent,Gate,Buf,Prof yellow
```
> The mutating bridge routes are **Origin-gated** (a browser fetch can't attach a custom header, so same-origin *is* the auth layer) and Bearer-gated for non-browser callers when `MCP_AUTH_TOKEN` is set — so a cross-origin page can't hijack your canvas.
**What you get:**
- *"Load my portrait workflow onto the canvas"* -- it appears in your browser, no file juggling
- *"What did I just change?"* -- the agent reads your hand edits back off the canvas
- *"Why was that render slow?"* -- real per-node timing, so optimization stops being guesswork
**Install (one symlink, then restart):**
**Windows (run as Administrator):**
```cmd
cd C:\path\to\ComfyUI\custom_nodes
mklink /D comfy_agent_bridge C:\path\to\Comfy-Cozy\node_pack\comfy_agent_bridge
```
**Linux / macOS:**
```bash
cd /path/to/ComfyUI/custom_nodes
ln -s /path/to/Comfy-Cozy/node_pack/comfy_agent_bridge comfy_agent_bridge
```
Restart ComfyUI. You'll see `comfy_agent_bridge: routes registered` in the log -- that's it. If a bridge feature ever returns a "node pack not installed" message, it means ComfyUI needs a restart to pick the pack up.
> **Under the hood:** these three routes are covered by a live contract test suite (`tests/integration/test_bridge_routes_integration.py`) that boots against a real ComfyUI and asserts each route answers correctly -- so "installed but silently broken" can't slip through. Run it with `python -m pytest tests/integration/test_bridge_routes_integration.py -v` while ComfyUI is running.
---
## Pick Your LLM
Comfy Cozy is **provider-agnostic** — six engines, one abstraction. Same 133 tools, same streaming, same vision analysis; swap one env var, or swap models mid-session. Your last pick is remembered across restarts, a swap won't hand you a model that can't call tools, and `list_models_available` shows which engines are configured (and, with `probe=true`, which actually answer).
**Pick one row. Everything else on this page works the same either way.**
| Provider | Best when | Needs a key? |
|---|---|---|
| **Anthropic** *(default)* | you want the best results out of the box | yes |
| **Ollama** | you want everything local and free | **no** |
| **OpenAI** | you already pay for GPT-4o | yes |
| **Google Gemini** | you already have a Google key | yes |
| **NVIDIA Nemotron** | you want free credits + reasoning models | yes |
| **Custom** | you self-host vLLM / LM Studio / LiteLLM | usually no |
Setup for each is one collapsed block below — **Anthropic is open by default.**
### Anthropic (default)
```bash
# .env
ANTHROPIC_API_KEY=sk-ant-your-key-here
# Optional overrides (defaults shown):
# AGENT_MODEL=claude-opus-4-7 -- main loop
# FAST_MODEL=claude-haiku-4-5-20251001 -- low-stakes triage
# VISION_MODEL=claude-opus-4-7 -- analyze/compare images
# THINKING_BUDGET=4000 -- agent reasoning budget (tokens)
# VISION_THINKING_BUDGET=2000 -- vision reasoning budget
# Run
comfy-cozy run
```
Ships as the default with **Opus 4.7 + extended thinking + three-tier prompt caching**.
The agent runs on Opus 4.7 with a 4K reasoning budget; vision analysis (`analyze_image`,
`compare_outputs`, `suggest_improvements`) runs the same model with its own budget. Set
`FAST_MODEL` if you want to route triage / classification tools to Haiku 4.5.
OpenAI — GPT-4o / GPT-4o-mini
### OpenAI
```bash
# Install the SDK (one time)
pip install openai
# .env
LLM_PROVIDER=openai
OPENAI_API_KEY=sk-your-key-here
AGENT_MODEL=gpt-4o # or gpt-4o-mini for faster/cheaper
# Run
comfy-cozy run
```
Full tool-use support with streaming. Works with any OpenAI-compatible endpoint.
Google Gemini — 2.5 Flash / Pro
### Google Gemini
```bash
# Install the SDK (one time)
pip install google-genai
# .env
LLM_PROVIDER=gemini
GEMINI_API_KEY=your-key-here
AGENT_MODEL=gemini-2.5-flash # or gemini-2.5-pro
# Run
comfy-cozy run
```
Function declarations mapped automatically. Supports Gemini's thinking mode.
Ollama — fully local, free, no API key
### Ollama (fully local, no API key)
```bash
# Install Ollama: https://ollama.com
# Pull a model
ollama pull llama3.1
# .env
LLM_PROVIDER=ollama
AGENT_MODEL=llama3.1 # or any model you've pulled
# Run (no API key needed)
comfy-cozy run
```
Uses Ollama's OpenAI-compatible endpoint at `localhost:11434`. Override with `OLLAMA_BASE_URL` if running remotely. **No data leaves your machine.**
NVIDIA Nemotron — NIM cloud / OpenRouter / self-hosted
### NVIDIA Nemotron (NIM cloud / OpenRouter / self-hosted)
```bash
# Install the SDK (one time)
pip install openai
# .env
LLM_PROVIDER=nvidia
NVIDIA_BASE_URL=https://integrate.api.nvidia.com/v1 # or OpenRouter / self-hosted vLLM
NVIDIA_API_KEY=nvapi-your-key-here
AGENT_MODEL=nvidia/nemotron-3-super-120b-a12b # super (default) / ultra / nano
# Run
comfy-cozy run --model nemotron
```
Endpoint-agnostic, OpenAI-compatible provider for NVIDIA's **Nemotron-3** reasoning models — grab a key + free credits at [build.nvidia.com](https://build.nvidia.com). The same provider serves NVIDIA NIM cloud, OpenRouter, and a self-hosted vLLM/SGLang endpoint; the model id picks the backend. Nemotron streams `` reasoning, which the provider strips from both the visible output **and** the replayed history by default (reasoning is off unless you set `NVIDIA_EMIT_REASONING=true`). Vision stays on a multimodal provider (`VISION_PROVIDER`, default `anthropic`), so swapping the loop to a text-only Nemotron never breaks `analyze_image`.
Custom — any OpenAI-compatible endpoint you host
### Custom (bring-your-own OpenAI-compatible endpoint)
```bash
# Install the SDK (one time)
pip install openai
# .env
LLM_PROVIDER=custom
CUSTOM_BASE_URL=http://localhost:8000/v1 # your vLLM / SGLang / LM Studio / LiteLLM / OpenRouter endpoint
CUSTOM_API_KEY= # optional -- many local servers need none
CUSTOM_MODEL=my-local-model # the model id your endpoint serves
# Run (LLM_PROVIDER=custom is already set above)
comfy-cozy run
```
Point it at **anything that speaks the OpenAI chat-completions API** -- a self-hosted vLLM/SGLang server, LM Studio, LiteLLM, OpenRouter, or your own gateway. It's a plain passthrough (no Nemotron `` handling), so a local endpoint isn't mislabeled `nvidia` anymore. Vision stays on `VISION_PROVIDER`, so `analyze_image` keeps working.
### Swap models on the fly
Beyond the `LLM_PROVIDER` env var, switch the reasoning model per launch or mid-conversation — no restart, and it reaches the live loop immediately:
```bash
comfy-cozy run --model nemotron # alias -> nvidia/nemotron-3-super-120b-a12b
comfy-cozy run --model claude # back to the default
comfy-cozy run --provider openai --model gpt-4o
comfy-cozy run --model custom # your custom OpenAI-compatible endpoint (needs CUSTOM_MODEL)
```
In conversation, the `swap_model` and `list_models_available` tools do the same thing. Three things happen for free:
- **Your pick sticks.** The last swap is remembered across restarts (`~/.comfy-cozy/model_selection.json`); an explicit `--model` always wins.
- **No broken loops.** A swap is atomic (rolls back on a bad key) and refuses a model that can't call tools — *before* anything changes, not mid-chat.
- **You can see what's live.** `list_models_available` lists each engine's capabilities and a health `status` column: which engines are configured, and — with `probe=true` — which actually answer, and how fast.
The whole swap in one picture — the gate, the rollback, the memory, and the health check:
```mermaid
graph TD
Req["swap_model · --model · LLM_PROVIDER"] --> Resolve["resolve alias
claude · nemotron · custom · …"]
Resolve --> Gate{"can it
tool-call?"}
Gate -->|no| Refuse["refuse — nothing changes
(no half-swap)"]
Gate -->|yes| Swap["atomic swap
snapshot → reassign → clear cache"]
Swap --> Probe{"live probe
key / endpoint ok?"}
Probe -->|fails| Rollback["roll back to
the previous model"]
Probe -->|ok| Persist["remember it
~/.comfy-cozy/model_selection.json"]
Persist --> Live["now running the new engine"]
Live --> Health["list_models_available
status: configured + reachable"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Refuse,Rollback orange
class Req,Resolve,Gate,Swap,Probe,Persist,Live,Health yellow
```
### Architecture
All six providers share the same abstraction layer (`agent/llm/`):
```mermaid
graph LR
Agent[Agent Loop
133 tools] --> LLM{LLM_PROVIDER}
LLM -->|anthropic| A["Claude
Streaming + Cache"]
LLM -->|openai| B["GPT-4o
Tool Calls"]
LLM -->|gemini| C["Gemini
Function Decl."]
LLM -->|ollama| D["Ollama
Local + Private"]
LLM -->|nvidia| E["Nemotron
NIM / OpenRouter"]
LLM -->|custom| F["Custom
Any OpenAI-compatible"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class B,D,F orange
class Agent,A,C,E,LLM yellow
```
Common types (`TextBlock`, `ToolUseBlock`, `LLMResponse`), unified error hierarchy, provider-specific format conversion handled internally. Switch providers with one env var -- no code changes. All 6 providers have dedicated test suites (230+ tests) plus a parameterized conformance suite that verifies protocol compliance across providers. Every `stream()` and `create()` call is instrumented with `llm_call_total` and `llm_call_duration_seconds` metrics (per-provider labels).
### Reasoning + caching (Opus 4.7)
The Anthropic path uses two Opus-4.7-specific features the other providers ignore:
1. **Extended thinking.** Every agent turn ships `thinking={"type": "enabled",
"budget_tokens": THINKING_BUDGET}`. The streamed `ThinkingBlock`s include a
cryptographic `signature`; we capture it and replay it on the next turn so
tool-use loops stay valid (without the signature, Anthropic 400s the next
request).
2. **Three-tier system prompt.** `system_prompt.build_system_prompt_blocks()`
returns a list of cache blocks instead of one big string. Two blocks are
marked `cache_control: ephemeral`; the third (volatile session context) is
deliberately not cached. Combined with the last-tool cache pin, three of
Anthropic's four cache breakpoints stay hot across a session.
```mermaid
flowchart TB
classDef stable fill:#d99458,stroke:#1a1a1a,color:#1a1a1a,stroke-width:1.2px
classDef volatile fill:#d9c958,stroke:#d99458,color:#1a1a1a,stroke-width:1.2px
subgraph SYS[" system prompt blocks "]
b1["Block 1 · stable prefix
identity · paths · RULES
+ comfyui_core.md
cache_control: ephemeral"]
b2["Block 2 · topical knowledge
3d / flux / controlnet / video / ...
cache_control: ephemeral"]
b3["Block 3 · session tail
notes · recommendations
last-output context
uncached"]
end
subgraph TOOLS[" tools[] "]
t1[tool 1]
t2[tool 2]
tN[... 100+ tools]
tL["last tool
cache_control: ephemeral"]
end
subgraph LOOP[" agent turn loop "]
m1[messages · user input]
think["ThinkingBlock
thinking text
+ signature ✓"]
tu[ToolUseBlock]
tr[ToolResultBlock]
api[(claude-opus-4-7
thinking enabled)]
end
b1 --> api
b2 --> api
b3 --> api
t1 --> api
t2 --> api
tN --> api
tL --> api
m1 --> api
api --> think --> tu --> tr --> m1
class b1,b2,tL stable
class b3,t1,t2,tN,m1,think,tu,tr,api volatile
```
**Tone key.** Blue = blocks pinned in the prompt cache (the stable prefix, the
topical knowledge, and the last-tool breakpoint). Amber = the per-turn volatile
tail: session context, the message log, and the streaming agent loop itself.
Signature-bearing `ThinkingBlock`s are replayed verbatim on each turn so the
API accepts the next request.
---
## Three Ways to Use It
*Same 133 tools, three front ends — MCP inside Claude, standalone CLI, or the one-click launcher. Pick one.*
### A. Inside Claude Code / Claude Desktop (recommended)
The agent runs as an MCP server -- Claude can use all 133 tools directly.
Add this to your Claude Code or Claude Desktop MCP config:
```json
{
"mcpServers": {
"comfy-cozy": {
"command": "comfy-cozy",
"args": ["mcp"]
}
}
}
```
Now talk to Claude about your ComfyUI workflows. It has full access. (`uvx comfy-cozy mcp` works too, once the PyPI listing is live — no install step at all.)
### B. Standalone CLI
```bash
comfy-cozy run # Start a conversation
comfy-cozy run --session my-project # Auto-saves so you can pick up later
comfy-cozy run --verbose # See what's happening under the hood
```
### C. One-click launcher (ComfyUI + agent together)
If you use the **ComfyUI CLI launcher** (`ComfyUI CLI.lnk`), Comfy Cozy is the default mode:
```
[ 1 ] STABLE Balanced. Works with everything.
[ 2 ] DETERMINISTIC Same prompt = same pixels.
[ 3 ] FAST Sage attention + async offload.
[ 4 ] COMFY COZY * Talk to your workflow. (auto-selects in 10s)
```
Select **4** (or wait 10 seconds) -- ComfyUI starts in a background window, then the agent launches ready to talk.
### Handy CLI Commands (no API key needed)
```bash
comfy-cozy inspect # See your installed models and nodes
comfy-cozy parse workflow.json # Analyze a workflow file
comfy-cozy sessions # List your saved sessions
comfy-cozy diagnose --last # Why was that render slow/broken?
comfy-cozy diagnose --last --json | jq '.findings' # Same, for scripts/CI
```
---
## What the Agent Knows About Your Models
The agent ships with built-in knowledge about how each model family actually behaves. It won't use SD 1.5 settings on a Flux workflow.
| Model | Resolution | CFG | Notes |
|-------|-----------|-----|-------|
| **SD 1.5** | 512x512 | 7-12 | Huge LoRA ecosystem. Negative prompts matter. |
| **SDXL** | 1024x1024 | 5-9 | Better anatomy. Tag-based prompts work best. |
| **Flux** | 512-1024 | ~1.0 (guidance) | No negative prompts. Needs FluxGuidance node + T5 encoder. |
| **SD3** | 1024x1024 | 5-7 | Triple text encoder (CLIP-G, CLIP-L, T5). |
| **LTX-2** (video) | 768x512 | ~25 | 121 steps. Frame count must be (N*8)+1. |
| **WAN 2.x** (video) | 832x480 | 1-3.5 | Dual-noise architecture. 4-20 steps. |
**The agent will never mix model families** -- no SD 1.5 LoRAs on SDXL checkpoints, no Flux ControlNets on SD3.
### Artist-Speak Translation
| You say | What the agent adjusts |
|---------|----------------------|
| *"dreamier"* or *"softer"* | Lower CFG (5-7), more steps, DPM++ 2M Karras |
| *"sharper"* or *"crisper"* | Higher CFG (8-12), Euler or DPM++ SDE |
| *"more photorealistic"* | CFG 7-10, realistic checkpoint, negative: "cartoon, anime" |
| *"more stylized"* | Lower CFG (4-6), artistic checkpoint or LoRA |
| *"faster"* | Fewer steps (15-20), LCM/Lightning/Turbo, smaller resolution |
| *"higher quality"* | More steps (30-50), hires fix, upscaler |
| *"more variation"* | Higher denoise, different seed, lower CFG |
| *"less variation"* | Lower denoise, same seed, higher CFG |
### Zero-LLM Recipes (instant artist-speak)
The table above isn't just documentation — the most common intents ship as **recipes**: pre-built, deterministic parameter macros that apply *without any LLM call*.
- **Instant.** "Dreamier" lands in milliseconds, not seconds. No API round-trip, no tokens.
- **Deterministic.** The same recipe always makes the same change. No model mood.
- **Safe.** Every recipe step dispatches through the same safety gate as everything else, and every change is one `undo` away.
- **14+ built-in** — intent macros (dreamier, sharper, faster, ...) plus build recipes for common workflow assemblies.
```
You: "make it dreamier"
Agent: applied recipe 'dreamier' — CFG 8.0 → 6.0, sampler → DPM++ 2M Karras. Undo anytime.
```
Two tools drive it: `list_recipes` (see what's available) and `apply_recipe` (fire one). The LLM stays in the loop for everything a recipe *can't* express — recipes just make the common path free.
---
## Run Reports ("why was that slow?" — keyless)
Recipes made common **edits** instant and deterministic.
Run reports do the same for common **diagnoses**.
**Every render leaves a report on disk.** Automatically. No setup, no key.
```bash
comfy-cozy diagnose --last
```
```
env 59a135a4 · 127.0.0.1:8188 · 2026-07-12T20:31:06Z
run error · 3.4s · workflow aaaaaaaa · baseline 4 clean runs
triggers: execution_error, oom
CRITICAL vram_pressure — the workflow's VRAM demand exceeded the device.
fix: reduce resolution or batch size, enable offload, or tile the VAE decode.
```
**What's in a report** *(each line stands alone)*:
- **Environment fingerprint** — one hash for *os · python · torch · CUDA · driver · ComfyUI*. A torch upgrade = a new fingerprint. No more "what changed?"
- **Per-node timings** — which node ate the render (needs the [Agent Bridge](#optional-the-agent-bridge-node-pack-live-canvas--render-timing); degrades gracefully without it).
- **An explained finding for every anomaly.** The contract *refuses* silence — a fired trigger with zero findings is a structurally **invalid** document, rejected by the schema itself.
- **Self-building baseline.** Your first clean runs quietly become "normal" for that workflow on that machine. A run 25% past its own median gets flagged. *A fresh machine's first sessions produce clean, empty-trigger reports and quietly build your baseline — the tool bootstraps its own normal.*
**Three ways in:**
| Path | Command | For |
|---|---|---|
| Terminal | `comfy-cozy diagnose --last` | you, after a weird render |
| Scripts / CI | `diagnose --last --json \| jq` · `--strict` exits 1 on critical | render-farm gates |
| Agent | `diagnose` MCP tool | the co-pilot, before it optimizes |
**Zero LLM involvement.** The whole path is deterministic code — run it on a box with no API key, pipe it to `jq`, gate a pipeline on it. Findings *point*; the agent's repair tools *act*.
---
## How It Works
*The four-phase loop every request runs through — UNDERSTAND → DISCOVER → PILOT → VERIFY — plus the safety rails around installs and execution.*
```mermaid
graph TB
subgraph Browser ["ComfyUI Browser"]
Sidebar["Comfy Cozy Sidebar
Native left panel -- Chat -- Quick Actions"]
end
subgraph Backend ["Agent Backend (Python)"]
Routes["49 REST Routes
+ WebSocket"]
Tools["133 Tools
workflow -- models -- recipes -- vision -- session -- provision"]
Cache["object_info cache
TTL + invalidate
re-validate ~1 ms"]
Engine["IAIEngine
ComfyUIAdapter -- EndpointPool
pooled client -- per-host breakers -- job affinity"]
Cog["Cognitive Engine
LIVRPS delta stack -- CWM -- experience"]
end
subgraph ComfyUI ["ComfyUI (1..N workers)"]
API["/prompt -- /history -- /ws"]
Canvas["Live Canvas"]
end
subgraph Disk ["Persistence"]
EXP[("experience.jsonl
append-only, fsync'd
cross-session learning")]
Sessions[("sessions/ in a checkout
~/.comfy-cozy when installed
workflow state")]
Lock[("workflow.lock
model SHA-256s -- pack commits
drift warnings at validate")]
end
Sidebar <-->|"WebSocket + REST"| Routes
Sidebar <-->|"canvas sync"| Canvas
Routes --> Tools
Tools --> Cog
Tools -->|introspection| Cache
Cache -->|"class-scoped GETs"| API
Tools -->|execution path| Engine
Engine -->|httpx + websockets| API
Cog --> EXP
Tools --> Sessions
Tools -->|save_workflow| Lock
style Browser fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Backend fill:#d9c958,color:#1a1a1a,stroke:#d99458
style ComfyUI fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Disk fill:#d9c958,color:#1a1a1a,stroke:#d99458
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Engine orange
class Sidebar,Routes,Tools,Cache,Cog,API,Canvas,EXP,Sessions,Lock yellow
```
```mermaid
graph LR
You([You]) --> Agent[133 Tools]
Agent --> Understand[UNDERSTAND
What do you have?]
Understand --> Discover[DISCOVER
What do you need?]
Discover --> Pilot[PILOT
Make the changes]
Pilot --> Verify[VERIFY
Did it work?]
Verify -->|learn| Agent
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class You,Verify orange
class Understand,Discover,Pilot,Agent yellow
```
**Four phases, always in order:**
1. **UNDERSTAND** -- Reads your workflow, scans your models, checks what's installed
2. **DISCOVER** -- Searches CivitAI, HuggingFace, ComfyUI Manager (31k+ nodes)
3. **PILOT** -- Makes changes through safe, reversible delta layers (never edits your original)
4. **VERIFY** -- Runs the workflow, checks the output, records what worked
When validation finds errors, the agent **auto-repairs**. Workflow fixes flow without stopping; installing missing packs pauses exactly once for your go-ahead:
```mermaid
flowchart TD
Run(["You: 'run this'"]) --> Validate["validate_before_execute
+ workflow.lock drift warnings"]
Validate --> Check{"Errors?"}
Check -->|No| Execute["execute_workflow"]
Check -->|"Missing nodes"| Repair["repair_workflow
identifies the packs"]
Check -->|"Missing inputs"| SetInput["set_input
fill required fields"]
Check -->|"Wrong model name"| Discover["discover
find correct model"]
Repair --> Confirm{"Pack list shown —
you approve?"}
Confirm -->|"yes → confirm=true"| Install["install packs"]
Confirm -->|no| Report
Install --> Revalidate["re-validate
cached schemas — ~1 ms"]
SetInput --> Revalidate
Discover --> SetInput
Revalidate --> Check2{"Still errors?"}
Check2 -->|No| Execute
Check2 -->|Yes| Report["Report unfixable
issue + ask"]
Execute --> Done(["Done — image ready"])
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Run,Execute,Done,Report orange
class Validate,Repair,Confirm,Install,SetInput,Discover,Check,Revalidate,Check2 yellow
```
**The rules of the road, in five lines:**
- **Doer, not describer.** Say "wire the model" — it wires the model. Say "run it" — it validates, fixes, executes.
- **Edits never stop to ask.** Every change is undoable; asking would just be friction.
- **Fetching code/files always asks.** `repair_workflow`, `install_node_pack`, `download_model` show you the list and wait for your `confirm=true`. No exceptions.
- **Run-after-edit requires a fresh validation.** Once you've changed the session workflow, the gate denies execution until `validate_before_execute` passes. (Running an explicit file path is exempt.)
- **The seams are tested.** A cross-module seam test runs the real discovery producer against the real repair consumer, so they can never silently drift apart.
### Event Triggers
Register callbacks (or webhooks) that fire automatically when ComfyUI events happen. Built into the execution pipeline -- no polling.
```mermaid
flowchart LR
WS["ComfyUI
WebSocket"] -->|event| Parse["ExecutionEvent
.from_ws_message()"]
Parse --> Dispatch["TriggerRegistry
.dispatch()"]
Dispatch --> CB1["on_complete
→ auto-evaluate"]
Dispatch --> CB2["on_error
→ log to session"]
Dispatch --> CB3["on_progress
→ custom callback"]
Dispatch --> WH["Webhook
→ POST JSON to URL"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class WS,CB1,CB3,WH orange
class Parse,Dispatch,CB2,from_ws_message,dispatch yellow
```
```python
from cognitive.transport.triggers import on_execution_complete, register_webhook
# Python callback
on_execution_complete(lambda event: print(f"Done in {event.elapsed:.1f}s"))
# External webhook (POSTs JSON on every execution_complete + execution_error)
register_webhook("https://your-server.com/hook", ["execution_complete", "execution_error"])
```
---
## Autonomous Mode
Write a creative intent. Hit go. No workflow file needed, no parameters to tune -- the agent composes a workflow, runs it on ComfyUI, scores the result, and learns from it automatically.
```mermaid
flowchart TD
You(["Creative Intent
'cinematic portrait, golden hour'"]) --> INTENT["INTENT
Parse + validate"]
INTENT --> COMPOSE["COMPOSE
Load template
Blend with experience"]
COMPOSE --> PROVISION{"PROVISION CHECK
Models on disk?"}
PROVISION -->|"missing"| WARN["Warning logged
(continues)"]
PROVISION -->|"all present"| PREDICT
WARN --> PREDICT["PREDICT
CWM estimates quality
(SNR-adaptive alpha)"]
PREDICT --> GATE{"GATE
Arbiter:
proceed?"}
GATE -->|Yes| CB{"CIRCUIT BREAKER
ComfyUI healthy?"}
GATE -->|Interrupt| STOP(["Interrupted
+ reason"])
CB -->|Open| FAIL(["Failed: infra down"])
CB -->|Closed| EXECUTE["EXECUTE
Post to ComfyUI
Monitor WebSocket"]
EXECUTE --> EVALUATE["EVALUATE
Vision AI or rule-based
(auto-wired)"]
EVALUATE --> LEARN["LEARN
Record to accumulator
Recalibrate CWM"]
LEARN --> DONE(["Complete
Experience recorded"])
EVALUATE -->|"score < threshold
retries remaining"| CB
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class You,CB,EXECUTE,DONE orange
class GATE,EVALUATE,LEARN,STOP,FAIL,PROVISION,INTENT,COMPOSE,WARN,PREDICT yellow
```
**Use from Python:**
```python
from cognitive.pipeline import create_default_pipeline, PipelineConfig
pipeline = create_default_pipeline() # fresh accumulator, CWM, arbiter
result = pipeline.run(PipelineConfig(
intent="cinematic portrait, golden hour",
model_family="SD1.5", # optional -- agent detects from intent
))
print(result.success, result.quality.overall, result.stage.value)
if result.warnings:
print("warnings:", result.warnings) # e.g. template family fallback
```
- **No executor required.** The pipeline calls ComfyUI directly via the real `execute_workflow` implementation.
- **Vision evaluator auto-wires.** Set `brain_available=True` and the pipeline auto-imports VisionAgent for multi-axis quality scoring (technical, aesthetic, prompt adherence). Falls back to rule-based scoring when vision is unavailable.
- **Auto-retry on low quality.** If score < threshold, adjusts parameters (steps +10, CFG nudged toward 7), and re-executes. Up to 3 attempts. Circuit breaker prevents retrying against a dead ComfyUI.
- **Provision check.** Before execution, scans for referenced models (`ckpt_name`, `lora_name`, `vae_name`). Missing models generate warnings without halting.
- **Template library.** 8 workflows: txt2img (SD 1.5 / SDXL), img2img, LoRA, multi-pass compositing (depth + normals + beauty), ControlNet depth, LTX-2 video, WAN 2.x video. Hardcoded SD 1.5 fallback if no template matches.
- **Adaptive learning.** CWM alpha blending responds to signal quality -- low variance in experience = more trust, high variance = more prior. Recalibrator adjusts confidence thresholds after every 10 predictions.
- **Experience persists across sessions -- crash-safe.** Every run saved atomically (write-to-tmp then `os.replace()`). After 30+ runs, the agent starts using your personal history to bias parameter selection.
- **Pipeline failures are graceful.** Circuit breaker, CWM exceptions, and template mismatches all produce clean `PipelineStage.FAILED` with `result.warnings`.
```mermaid
graph LR
subgraph Session1 ["Session 1"]
I1["Intent"] --> C1["Compose"] --> E1["Execute"] --> S1["Score"]
end
subgraph Session2 ["Session 2+"]
I2["Intent"] --> C2["Compose
(+prior runs)"] --> E2["Execute"] --> S2["Score"]
end
S1 -->|"atomic save"| JSONL[("experience.jsonl
crash-safe")]
JSONL -->|"load on startup"| C2
S2 -->|"atomic save -- cumulative"| JSONL
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class C2 orange
class JSONL,Session1,I1,C1,E1,S1,Session2,I2,E2,S2 yellow
```
### Cozy Constitution + MoE Chain
The pipeline above runs as one shot per intent. For long-running, self-healing autonomy across many experiments, **Cozy** adds two things on top: a constitutional MoE specialist team and a bounded-failure ladder. Doctrine lives in `.claude/COZY_CONSTITUTION.md`. Specialists are in `.claude/agents/cozy-*.md`. Code in `agent/stage/constitution.py` (commandments + classifier), `agent/stage/moe_profiles.py` (specialists + chain), and `agent/harness/cozy_loop.py` (the runner).
**MoE chain** -- Article II of the constitution mandates that every state-mutating chain ends in **Scribe**. Each specialist owns one concern and produces one typed handoff artifact. The chain dispatcher (`agent/stage/moe_dispatcher.py`) routes by `TASK_CHAINS`; the default chain shown below is the full build-execute-judge-persist sequence.
```mermaid
flowchart LR
Intent(["Intent
'cinematic portrait'"]) --> Scout
Scout["Scout
recon: nodes,
models, interfaces"] -->|recon_report| Architect
Architect["Architect
plan: params,
graph structure"] -->|design_spec| Provisioner
Provisioner["Provisioner
fetch missing
models / packs"] -->|provision_manifest| Forge
Forge["Forge
validated
RFC6902 patches"] -->|build_artifact| Crucible
Crucible["Crucible
execute + verify
(comfy_execute)"] -->|execution_result| Vision
Vision["Vision
judge quality
(analyze_image)"] -->|quality_report| Scribe
Scribe["Scribe
save_session +
record_experience"] -->|persistence_receipt| Done(["Stage flushed"])
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Intent,Scout,Architect,Provisioner,Forge,Crucible,Vision,Scribe,Done yellow
```
**Self-healing ladder** -- Article III mandates that every error gets classified once by `self_healing_ladder()` and routed to one of three policies. **TERMINAL is the only path that halts**; everything else burns iteration budget and continues. This is what makes a 24-hour autonomous run survivable: ComfyUI hiccups, missing assets, and rate-limit blips never stop the loop.
```mermaid
flowchart TD
Try["execute_fn(change_context)"] -->|success| Ratchet[Ratchet decides keep/reject]
Try -->|exception| Class["self_healing_ladder
classify(error)"]
Class -->|"TRANSIENT
timeout, 5xx,
ConnectionError"| Backoff["Exponential backoff
1s → 2s → 4s
(max 3 retries)"]
Backoff --> Try
Class -->|"RECOVERABLE
FileNotFoundError,
validation"| Repair{repair_fn
provided?}
Repair -->|yes, returns ctx| Try
Repair -->|no / returns None| Counter["Signature counter +1
(>3 same sig →
promote to TERMINAL)"]
Class -->|"TERMINAL
AnchorViolation,
disk-full,
repeated-recoverable"| Halt["Final checkpoint
+ BLOCKER.md
+ Halt"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Try,execute_fn,Ratchet,Class,classify,Backoff,Repair,Counter,Halt yellow
```
Run it: `comfy-cozy autonomous --execute-mode real --workflow path/to/wf.json --hours 24`. Per-iteration checkpoint to `STAGE_DEFAULT_PATH` (atomic via `.tmp` + `os.replace`). On TERMINAL halt, `BLOCKER.md` is written with the full classification trail. See `CLAUDE.md` "Cozy Autonomous Harness" for the full CLI surface.
---
## Comfy Cozy Sidebar (Native ComfyUI Integration)
A typography-forward chat panel in ComfyUI's native left sidebar. No floating buttons, no separate windows. Uses ComfyUI's own CSS variables -- adapts to any theme automatically.
```mermaid
graph TB
subgraph ComfyUI_App ["ComfyUI"]
subgraph Sidebar ["Left Sidebar"]
Tab["Comfy Cozy Tab
registerSidebarTab()"]
Chat["Chat Window
WebSocket -- streaming -- rich text"]
QA["Quick Actions
Run -- Validate -- Repair -- Optimize -- Undo"]
end
Canvas["Canvas"]
end
subgraph Bridge ["Bidirectional Canvas Bridge"]
C2A["Canvas --> Agent
Auto-sync on change"]
A2C["Agent --> Canvas
Push mutations + highlights"]
end
Tab --> Chat
Tab --> QA
Sidebar <--> Bridge
Bridge <--> Canvas
style ComfyUI_App fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Sidebar fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Bridge fill:#d9c958,color:#1a1a1a,stroke:#d99458
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Tab,registerSidebarTab,Chat,QA,Canvas,C2A,A2C yellow
```
**What you get:**
- **Native sidebar tab** -- `app.extensionManager.registerSidebarTab()`, sits alongside ComfyUI's built-in panels
- **Design system v3** -- Inter + JetBrains Mono, ComfyUI CSS variables, Pentagram-inspired: hairline borders, generous whitespace, 2px radii, zero ornamentation
- **Chat** -- Auto-growing textarea, streaming responses, rich text (code blocks, bold, inline code), collapsible tool results
- **Node pills** -- Clickable inline node references, color-coded by slot type. Click = select + center on canvas.
- **Quick actions** -- Context-aware chips: Run, Validate, Repair, Optimize, Undo
- **Canvas bridge** -- Agent changes sync to canvas live with node highlighting; canvas re-syncs after each execution
- **Self-healing** -- Missing node warnings with one-click repair, deprecated node migration
**51 panel routes** expose the full tool surface: discovery, provisioning, repair, sessions, execution. (Write-back v1 added `/get-workflow-api-with-touched` and `/ack-push` to the existing 49.)
Every request passes through a three-layer security chain:
```mermaid
flowchart TD
REST([REST Request]) --> Guard["_guard(request, category)"]
WS([WebSocket /ws]) --> Guard
Guard --> Auth{check_auth}
Auth -->|"no token configured"| Rate{check_rate_limit}
Auth -->|"bearer matches"| Rate
Auth -->|"missing / wrong"| R401(["401 Unauthorized"])
Rate -->|"tokens available"| Size{check_size}
Rate -->|"bucket empty"| R429(["429 -- Retry-After: 1s"])
Size -->|"Content-Length OK"| Handler(["Route handler"])
Size -->|"> 10 MB"| R413(["413 Too Large"])
Size -->|"chunked -- no length"| R411(["411 Length Required"])
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class R401,R413,Handler orange
class R429,R411,Guard,REST,_guard,WS,Auth,Rate,Size yellow
```
### Write-back v1 -- touched-set push to the live canvas
The canvas bridge is **bidirectional**. The canvas → agent direction has worked since launch (the panel POSTs the live graph to the agent on every change). The agent → canvas direction shipped Tier 1 only -- widget edits -- and **silently dropped every link the agent emitted** (`panel/web/js/superduperPanel.js:89-92, :106` pre-v1). Write-back v1 closes that gap with a touched-set delta-merge.
```mermaid
flowchart LR
Event["comfy-cozy:workflow-changed
(agent mutated cache)"] --> Debounce["debounce(100ms)
coalesce burst events"]
Debounce --> Run["runPushAgentToCanvas
(_pushOrchestrator.js)"]
Run --> Clear["clearDeltaFailures
(L-7 lifecycle)"]
Clear --> Fetch["GET /comfy-cozy/
get-workflow-api-with-touched
→ {workflow, touched}"]
Fetch --> Pause["withObserverPause
(L-6 try/finally
+ refcount)"]
Pause --> Apply["applyTouchedSet
iterate touched ONLY"]
Apply --> Kind{"entry.kind"}
Kind -->|widget| W["widget.value = new_value"]
Kind -->|link| L["fromNode.connect /
toNode.disconnectInput"]
Kind -->|"Tier-3 / stale /
missing / malformed"| S["addDeltaFailure
(P3 surface)"]
W --> Dirty["app.canvas.setDirty"]
L --> Dirty
S --> Dirty
Dirty --> Restore["observer restored
(finally)"]
Restore --> Ack["POST /comfy-cozy/ack-push
(rotates server snapshot)"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class W,L,Dirty,Restore,Ack orange
class Event,Debounce,Run,Clear,Fetch,Pause,Apply,Kind,S yellow
```
**F-1 mitigation -- touched-set diff.** The push iterates a server-computed *touched-set* (the diff between the agent's current cache and the last successfully-pushed snapshot) instead of the full workflow. Untouched canvas slots are never read or written -- director hand-edits on neighbour nodes survive every push, by construction.
```mermaid
flowchart LR
Load["/load-workflow-data
(canvas-sync POST)"] -->|"record_last_pushed"| Snap[("snapshot:
last-pushed workflow
panel/server/touched.py")]
Agent["agent mutation
(connect_nodes / set_input)"] -->|"updates"| Cache[("server cache:
current_workflow")]
Cache --> Diff["compute_touched
= diff(cache, snapshot)"]
Snap --> Diff
Diff --> Touched["touched = [
{node_id, input_name,
kind, old, new}
]
= what the AGENT changed"]
Director["director hand-edits
node 5 cfg = 8.0"] -.->|"never iterated
by frontend push"| Survives["node 5 survives
(P2 / F-1 closed)"]
Touched -->|"push touched only"| Survives
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Survives orange
class Load,Snap,Agent,Cache,Diff,Touched,Director yellow
```
**P3 surface -- no silent drops.** Every emitted delta is either applied or routed to the panel's status bar as a "**N delta(s) not applied**" warning with a Details modal listing each entry. Six categories surface:
| Type | Trigger | Action |
|---|---|---|
| `tier3_add` | server workflow has a node the canvas doesn't | surface only -- Tier 3 deferred per SPEC |
| `tier3_delete` | canvas has a node the server doesn't | surface only |
| `stale_node_ref` | touched references a node not on canvas (and not in workflow) | surface only |
| `missing_slot` | node found, but input / widget name doesn't match | surface only |
| `malformed` | unparseable node id, unknown kind, or non-conforming shape | surface only |
| `link_rejected` | LiteGraph's `connect` / `disconnectInput` returned `false` | surface only |
**Echo + concurrency.** `withObserverPause` is module-level refcounted, so the push pauses `app.graph.onAfterChange` **exactly once** even under nested / overlapping invocations and restores in `finally` -- no echo back into the agent (P4), no observer leak (F-4), no concurrent-push race (F-5).
**Verifier stack.** 111 tests guard the contract -- **24 pytest cases** for the server-side touched-set module + **87 Vitest cases** across seven JS test files (unit, property, integration, stress, pipeline orchestrator, surface accumulator, stubs). See `harness/SHIP_REPORT.md` for predicate-by-predicate evidence and `harness/CAPSULE.md` for the F-1..F-8 verification status table.
```bash
npm install --include=dev # one-time -- pulls Vitest
npm test # 87 Vitest cases (~250ms)
python -m pytest tests/test_touched.py -v # 24 pytest cases
```
---
## One-Click Model Provisioning
The agent handles the entire pipeline from "I want Flux" to a wired workflow:
```mermaid
flowchart LR
Search["Search
CivitAI + HF + Registry"] --> Confirm["Your go-ahead
(what + where shown)"]
Confirm --> Download["Download
to correct folder"]
Download --> Verify["Verify
family + compat"]
Verify --> Wire["Auto-Wire
find loader -- set input"]
Wire --> Ready["Ready to
Queue"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Verify,Ready orange
class Search,Confirm,Download,Wire yellow
```
**`provision_model`** -- one tool call that discovers, downloads, verifies compatibility, finds the right loader node in your workflow, and wires the model in. Downloads escalate through the safety gate: the agent shows you what it's about to fetch and waits for your confirmation before anything hits disk.
---
## NVIDIA NIM Containers (preflight → run → warm state)
Running Flux through NVIDIA's NIM microservice nodes instead of a raw checkpoint? Three tools manage the lifecycle -- built around one hard-won fact: a cold NIM container pull can sit silent for many minutes and still be perfectly healthy.
```mermaid
flowchart LR
Pre["nim_preflight
pack? VRAM? warm?
ComfyUI alive?"] --> Run["nim_run
queue install → load → generate"]
Run --> Warm["WARMUP
cold pull ≤ 15 min
silence ≠ failure"]
Warm --> Cook["COOKING
separate inference deadline"]
Cook --> Done(["Images +
warm state recorded"])
Done -.->|"nim_state reads it
next session"| Pre
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Done orange
class Pre,Run,Warm,Cook yellow
```
- **`nim_preflight`** -- read-only readiness probe: NIM node pack present, free VRAM, warm state, ComfyUI alive. Run it first; it never changes anything.
- **`nim_run`** -- queues the NIM workflow (its install → load → generate nodes) on the live execution engine and watches it with two separate deadlines: a warm-up budget (15 min cold, 3 min if the container image is already pulled) so the silent pull doesn't read as a failure, then a fresh inference budget once cooking starts.
- **`nim_state`** -- reads the newest warm-state record for a model on this host (valid for 24 h), so the agent knows whether your next run pays the cold-pull tax or starts hot.
The safety gate classifies these like everything else: `nim_preflight` and `nim_state` are read-only; `nim_run` is execution-class, same as `execute_workflow`.
---
Architecture Deep Dive — internals for engineers; artists can skip this (click to expand)
### Seven Structural Subsystems
The agent is built on seven architectural subsystems. Each one degrades independently -- if one breaks, the rest keep working.
```mermaid
graph TB
subgraph Foundation ["Foundation Layer"]
DAG["Workflow Intelligence DAG
6 pure computation nodes"]
OBS["Time-Sampled State
Monotonic step index"]
CAP["Capability Registry
133 tools indexed"]
end
subgraph Safety ["Safety Layer"]
GATE["Pre-Dispatch Gate
5 checks, default-deny"]
BRIDGE["Mutation Bridge
LIVRPS composition + audit"]
end
subgraph Integration ["Integration Layer"]
ADAPT["Inter-Module Adapters
Pure-function translators"]
DEGRADE["Degradation Manager
Per-subsystem fallbacks"]
end
Foundation --> Safety --> Integration
style Foundation fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Safety fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Integration fill:#d9c958,color:#1a1a1a,stroke:#d99458
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class DAG,OBS,CAP,GATE,BRIDGE,ADAPT,DEGRADE yellow
```
### Workflow Intelligence DAG
Before any workflow runs, a DAG of pure functions analyzes it:
```mermaid
graph LR
C[Complexity
TRIVIAL to EXTREME] --> M[Model Requirements
VRAM, family, LoRAs]
M --> O[Optimization
TensorRT, batching]
O --> R[Risk
SAFE to BLOCKED]
R --> RD[Readiness
go / no-go]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class R,RD orange
class C,M,O yellow
```
### Pre-Dispatch Safety Gate
Every tool call passes through a default-deny gate. Read-only tools bypass it (zero overhead). Destructive tools are always locked. The gate auto-detects loaded workflows AND USD stages: if either kind of workspace state exists for the current connection, mutation tools are allowed without explicit session context. Stage tools (`stage_write`, `stage_add_delta`) are recognized separately from workflow tools — a USD stage can exist independently of any loaded workflow.
The gate runs on live state, not defaults. The real ComfyUI circuit-breaker state feeds the system-health check, and a per-session action history (the last 50 dispatched calls) feeds the constitution checks. Every one of the 133 dispatched tools carries an **explicit** risk classification — a completeness test (`tests/test_gate_completeness.py`) pins the registry so a new tool can't ship unclassified. And the gate **fails closed**: if the gate package itself can't import, every tool is denied until it can (it used to degrade silently, which meant ungated dispatch). One more consent rule rides on the same checks: after any workflow mutation, `execute_workflow` / `execute_with_progress` on the session workflow are denied until a `validate_before_execute` passes — validate, then run, enforced by the gate itself. (Executing an explicit file path is exempt; the session flag says nothing about an external file.)
```mermaid
flowchart LR
Tool([Tool Call]) --> Gate{"Gate
imports?"}
Gate -->|"No — fail closed"| Closed["Denied:
gate unavailable"]
Gate -->|Yes| Type{"Stage
tool?"}
Type -->|No| WF{"Workflow
loaded?"}
Type -->|Yes| ST{"Stage
exists?"}
WF -->|Yes| Risk{Risk Level?}
WF -->|No| Deny["Denied:
no active session"]
ST -->|Yes| Risk
ST -->|No| Deny
Risk -->|"Read-only"| Pass[Pass through]
Risk -->|"Mutation / Execute"| Checks["5 safety checks
live breaker + history"]
Risk -->|"Install / Download"| Escalate["Needs your
confirmation"]
Risk -->|"Uninstall / Delete"| Block[Blocked]
Checks --> OK{All pass?}
OK -->|Yes| Go[Execute]
OK -->|No| Stop[Denied + reason]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Pass,Go,Stop,Block,Deny,Closed orange
class Escalate,Tool,Gate,Type,WF,ST,Risk,Checks,OK yellow
```
### Per-Connection Session Isolation (all 4 transports)
Every sidebar conversation, every panel chat, every MCP client connection, and every `comfy-cozy run --session foo` invocation gets its own isolated `WorkflowSession` + `CognitiveWorkflowStage`. State never leaks across tabs, clients, or named sessions. Isolation is propagated via a single `_conn_session` `ContextVar` set at every entry point — and by the per-session dicts inside the four stage modules (`provision`, `foresight`, `compositor`, `hyperagent`).
```mermaid
flowchart LR
SB["Sidebar tabs
conv.id"] --> H1["_spawn_with_session
(shared helper)"]
PNL["Panel chats
conv.id"] --> H1
MCP["MCP clients
conn_xxxxxxxx"] --> H2["mcp_server._handler
sets _conn_session"]
CLI["comfy-cozy run --session foo
(CLI)"] --> H3["cli.run
+ _save_and_exit"]
H1 --> CV[("_conn_ctx
ContextVar")]
H2 --> CV
H3 --> CV
CV --> WP["workflow_patch._get_state()"]
CV --> ST["stage_tools._get_stage()"]
CV --> FT["foresight_tools._get_*()"]
CV --> PV["provision_tools._get_provisioner()"]
CV --> CT["compositor_tools._scenes[sid]"]
CV --> HY["hyperagent_tools._meta_agents[sid]"]
WP --> WS[("Per-session
WorkflowSession + Stage")]
ST --> WS
FT --> WS
PV --> WS
CT --> WS
HY --> WS
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class WS orange
class CV,WP,ST,FT,PV,CT,HY,SB,H1,PNL,MCP,H2,CLI,H3,_get_state,_get_stage,_get_provisioner,_scenes,_meta_agents yellow
```
The same connection id is also installed as the per-thread correlation ID via `set_correlation_id`, so every log entry from a single conversation is greppable end-to-end. Parallel tool calls inside a single turn inherit the contextvar via `contextvars.copy_context()` per `ThreadPoolExecutor.submit()`. And `_save_and_exit()` (called on normal exit, atexit, or SIGTERM) self-sets the contextvar before saving so the user's named session never gets corrupted with empty default workflow state.
### LIVRPS -- How Conflicts Get Resolved
All workflow changes are non-destructive layers. When two opinions conflict:
| Priority | Layer | Example |
|----------|-------|---------|
| 6 (strongest) | **Safety** | "CFG above 30 is degenerate" -- always wins |
| 5 | **Local** (your edit) | "Set CFG to 9" |
| 4 | **Inherits** (experience) | "CFG 7.5 worked better last time" |
| 3 | **VariantSets** | Creative profile presets |
| 2 | **References** | Learned recipes |
| 1 (weakest) | **Payloads** | Default template values |
Your edit beats experience. Safety beats everything. Every conflict is deterministic, transparent, and reversible.
This is an intentional inversion of USD's native LIVRPS (where Specializes is weakest). Safety is promoted to strongest for safety-critical override -- the architectural decision documented in the patent application.
### Cognitive State Engine (Phase 0.5 -- live in production)
LIVRPS is no longer a table on a slide. Since Phase 0.5 the engine is a real top-level package (`cognitive/`) installed alongside `agent/`, and `agent/tools/workflow_patch.py` imports it directly at module load -- no try/except, no silent fallback. Every PILOT mutation is recorded as a delta layer with SHA-256 tamper detection, then resolved on demand. The engine is session-scoped via the `_conn_session` ContextVar described above, so each sidebar tab and MCP connection mutates its own delta stack.
```mermaid
graph LR
User([Tool Call
via MCP]) --> WP["agent/tools/
workflow_patch.py"]
WP -->|"_get_state() reads
_conn_session ContextVar"| CGE["CognitiveGraphEngine
(per-session)"]
CGE --> Stack["Delta Stack
P -- R -- V -- I -- L -- S"]
Stack -->|"sort weakest to strongest
apply, preserve link arrays"| Resolved["Resolved WorkflowGraph"]
Resolved -->|"to_api_json()"| Comfy["ComfyUI /prompt"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class User,Resolved,Comfy orange
class WP,CGE,Stack,_get_state,to_api_json yellow
```
The `cognitive/` package is layered by phase -- the core engine (Phase 1) is fully tested at 54/54 adversarial cases. Phase 6 is complete: the autonomous pipeline is fully wired with real executor, template loading, rule-based evaluator, and experience persistence.
```mermaid
graph TB
Cognitive["cognitive/
(installed top-level package)"]
Cognitive --> Core["core/
graph -- delta -- models
54/54 tests passing"]
Cognitive --> Exp["experience/
chunk -- signature -- accumulator"]
Cognitive --> Pred["prediction/
cwm -- arbiter -- counterfactual"]
Cognitive --> Trans["transport/
schema_cache -- events -- interrupt"]
Cognitive --> Pipe["pipeline/
autonomous -- create_default_pipeline
Phase 6 complete"]
Cognitive --> CogTools["tools/
analyze -- compose -- execute
(cycle 9 deleted 5 dead modules)"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Core,Trans,Pipe orange
class Cognitive,Exp,Pred,CogTools yellow
```
Each delta layer carries its `creation_hash` (SHA-256 of `opinion + sorted-JSON mutations`). `verify_stack_integrity()` walks the stack and flags any layer whose `layer_hash` no longer matches its `creation_hash` -- making post-hoc tampering detectable. Link arrays (`["node_id", output_index]`) are preserved through every parse/mutate/serialize round-trip, which is the #1 failure mode in ComfyUI agents.
### LLM Provider Hardening
The agent supports six LLM providers (Anthropic, OpenAI, Gemini, Ollama, NVIDIA, and a bring-your-own `custom` OpenAI-compatible endpoint). Cycles 7+18+20 closed six real bugs in the streaming, retry, and multi-turn paths, and the Opus 4.7 upgrade (commit `c61c65f`) refined the multi-turn `ThinkingBlock` policy on Anthropic. After this work, every provider correctly: extracts streaming token usage, doesn't duplicate text on retry, doesn't fire callbacks with empty content, doesn't leak reasoning into user-visible text, and handles `ThinkingBlock` correctly on multi-turn replay — Anthropic re-sends signature-bearing thinking blocks (required by the API when extended thinking runs alongside tool use), while the others drop them (those APIs don't model replayable thinking).
```mermaid
graph TB
Stream["_stream_with_retry
(agent/main.py)"] --> Track["content_emitted = [False]
per attempt — closure-captured"]
Track --> Wrap["_wrap_safe + tracking
on_text / on_thinking"]
Wrap --> Provider{Which provider?}
Provider -->|Anthropic| A["✓ thinking blocks preserved
in _to_response (with signature)
✓ empty deltas filtered
✓ signature-bearing ThinkingBlock
replayed verbatim in convert_messages
(c61c65f — supersedes cycle 20)"]
Provider -->|OpenAI| O["✓ stream_options=
{include_usage: true}
✓ ThinkingBlock skipped
in convert_messages (cycle 20)"]
Provider -->|Gemini| G["✓ thinking / text branches
mutually exclusive (if/elif)
✓ ThinkingBlock skipped
(was sending repr as text)"]
Provider -->|Ollama| OL["✓ stream_options=
{include_usage: true}
✓ ThinkingBlock pre-filtered
from content list (cycle 20)"]
Track -->|content emitted + transient error| NoRetry["RAISE — don't retry
(would duplicate text in UI)"]
Track -->|no content + transient error| Retry["Retry with backoff
RateLimit / Connection / 5xx"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class A,O,G,OL,NoRetry,Retry orange
class Stream,Track,Wrap,Provider,_to_response,convert_messages,exclusive,list yellow
```
**Cycle 20 — ThinkingBlock multi-turn bug.** When Claude 3.7+ or Claude 4 returns a `ThinkingBlock` in its response, the agent stores it in message history. On the next turn, `convert_messages` must translate that block back to the provider's native format. Before cycle 20, all 4 providers mishandled it: Anthropic sent the raw Python dataclass to the API (400 error), OpenAI silently dropped it, Gemini converted `str(ThinkingBlock(...))` to user-visible text, and Ollama sent raw objects. Fix: all providers now skip ThinkingBlock in convert_messages (the API requires a signature field we don't capture; thinking content is already delivered via the streaming `on_thinking` callback).
**Opus 4.7 evolution (c61c65f → 3261318).** The cycle-20 fix above strips `ThinkingBlock` across the board. The Opus 4.7 upgrade refined Anthropic's branch: extended-thinking responses now include a cryptographic `signature` on each thinking block, and the API requires the signature on the next turn whenever a `tool_use` block follows. `agent/llm/_anthropic.py:convert_messages` now replays signature-bearing blocks verbatim; signature-less blocks (legacy paths, manually-constructed test fixtures) are dropped — and `3261318` made that drop loud: a WARNING-level log now names the dropped content, the API constraint, and the next-turn 400 risk. The same commit extracted a `_build_thinking_kwarg` helper and made the clamp formula raise `ValueError` early when `thinking_budget > 0` and `max_tokens <= 1024` (the prior clamp produced `budget_tokens == max_tokens`, which the API rejects). OpenAI, Gemini, and Ollama retain the cycle-20 behavior; their APIs don't model replayable thinking, so the strip remains correct.
```mermaid
graph LR
LLM["LLM Response
[TextBlock, ThinkingBlock]"] --> Store["main.py:293
messages.append(content)"]
Store --> NextTurn["Next turn
convert_messages()"]
NextTurn -->|"Anthropic, signature ✓"| Replay["ThinkingBlock
→ replay verbatim"]
NextTurn -->|"Anthropic, no signature"| WarnDrop["ThinkingBlock
→ drop + log.warning"]
NextTurn -->|"OpenAI / Gemini / Ollama"| Skip["ThinkingBlock
→ skip (continue)"]
NextTurn --> Keep["TextBlock / ToolUseBlock
→ convert to native format"]
Replay --> Safe
WarnDrop --> Safe
Skip --> Safe["API receives only
valid native blocks"]
Keep --> Safe
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Replay,WarnDrop,Skip,Keep,Safe orange
class LLM,Store,append,NextTurn,convert_messages,skip yellow
```
The retry tracker pattern is the key insight: an `on_text("Hello ")` followed by a transient `LLMRateLimitError` USED TO retry from scratch, calling `on_text("Hello ")` again, then `on_text("world!")` — the user saw `"Hello Hello world!"` in the UI. After cycle 7, any error fired AFTER content was emitted raises immediately instead of retrying. Tested across all 4 providers via `tests/test_main.py::TestStreamRetryDuplication` + provider-specific regression tests.
### Vision Cost Controls
Vision analysis is the agent's most expensive habit, so the spend path is tightened at three points:
- **One client, reused.** Per-call timeouts derive from the cached Anthropic client via `with_options` (microseconds) instead of constructing a fresh client per vision call — the old path burned ~0.3 s and leaked a file descriptor every time.
- **Downscale before upload.** Images are resized so the longest side is ≤ 1568 px before encoding (the Vision API resizes anything bigger server-side anyway — full resolution only burned bandwidth and tokens). Your original file on disk is never touched, and a post-downscale 5 MB encoded-payload guard catches images the API would reject.
- **Prompt-aware caching.** `analyze_image_cached` keys on the image bytes *and* the prompt. Same image + same question answers instantly from cache; a *different* question about the same image re-analyzes — it no longer serves the stale previous answer.
### Execution Engine Adapter
The agent's **execution path** (POST `/prompt`, POST `/interrupt`, GET `/history`, WS `/ws`) routes through an abstraction layer that mirrors `agent/llm/` discipline exactly. `agent/engine/` defines an `IAIEngine` ABC with four keyword-only methods — `queue_prompt`, `interrupt`, `get_history`, `subscribe_ws` — and ships a `ComfyUIAdapter(IAIEngine)` that owns every direct HTTP/WS call to a running ComfyUI instance. `agent/tools/comfy_execute.py` delegates through `get_engine()`; the call sites it owned before (queue, poll, websocket monitoring, execution status) now translate engine exceptions back to their established string/tuple return shapes, so caller behavior is byte-for-byte identical and the existing test suite passes unchanged.
```mermaid
graph LR
Tool["agent/tools/comfy_execute.py
queue / poll / ws / status"] --> Get["get_engine()
thread-safe cache
env var AI_ENGINE"]
Get --> IFace{IAIEngine}
IFace -->|comfyui| Adapter["ComfyUIAdapter
httpx + websockets
circuit breaker"]
Adapter -->|POST| P["/prompt"]
Adapter -->|POST| I["/interrupt"]
Adapter -->|GET| H["/history"]
Adapter -.->|WS| W["/ws"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Adapter,P,I,H,W orange
class Tool,Get,IFace yellow
```
The split is deliberate: **execution operations** live behind `IAIEngine` because they're the path that a future backend (a remote queue, a hosted ComfyUI fleet, a mock for tests) would re-implement. **Introspection endpoints** (`/object_info`, `/system_stats`, `/queue` status, `/userdata`) stay as direct `httpx` calls in their existing tool modules — they're discovery-only and not part of the execution surface. Engine errors form a hierarchy that parallels the LLM error hierarchy: `EngineError` base + `EngineConnectionError`, `EngineTimeoutError`, `EngineValidationError` (carries `node_errors`), `EngineServerError` (carries `status_code`), `EngineUnavailableError` (circuit-breaker open). The `subscribe_ws` context manager yields `EngineEvent(type, data, raw)` objects plus a `__timeout__` sentinel event that lets the caller re-check its deadline without losing the connection.
### Graceful Degradation
Every subsystem has an independent kill switch. Set any of these to `0` in your `.env` to disable:
`BRAIN_ENABLED` `DAG_ENABLED` `GATE_ENABLED` `OBSERVATION_ENABLED`
All default to ON. The agent works fine with any combination disabled -- features gracefully disappear.
One deliberate exception: turning the gate off with `GATE_ENABLED=0` is your call, but if the gate is ON and *breaks* (an import failure), tool dispatch is denied rather than quietly running unguarded. Safety fails closed; everything else fails soft.
### Experience Loop
Every generation is an experiment. The agent tracks what worked:
- **Sessions 1-30**: Uses built-in knowledge only
- **Sessions 30-100**: Blends knowledge with what it's learned from your renders
- **Sessions 100+**: Primarily driven by your personal history
### Semantic Knowledge Retrieval
The agent ships with 12 knowledge files (1,300+ lines) covering ControlNet preprocessor selection and strength scheduling (174 lines), Flux guidance and T5 encoder tuning (172 lines), multi-pass compositing for Nuke/AE/Fusion (119 lines), video workflows, 3D pipelines, and more. Retrieval is hybrid: keyword triggers fire first (fast path), then TF-IDF semantic search fills gaps when keywords miss. Pure Python, zero external dependencies -- no vector DB required.
```mermaid
flowchart LR
Context["Workflow context
+ session notes"] --> KW{"Keyword
triggers"}
KW -->|"≥ 2 files"| Done["Load knowledge"]
KW -->|"< 2 files"| TFIDF["TF-IDF
cosine similarity"]
TFIDF --> Merge["Union results"]
Merge --> Done
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Done orange
class KW,TFIDF,Context,Merge yellow
```
### BGE Embedder (in-process semantic vectors)
`agent/embedder.py` exposes a single function — `embed(payload: str) -> list[float]` — that returns 384-dimension L2-normalized vectors from `BAAI/bge-small-en-v1.5`. The model is lazy-loaded on first call (≈130 MB cache at `~/.cache/huggingface/hub/`) and reused thereafter; encoding latency on CPU is a few ms per short string after warm-up. Opt-in: `pip install -e ".[embed]"` pulls the encoder (`sentence-transformers` + torch); `requirements.txt` pins the CPU-only torch wheel (`--extra-index-url https://download.pytorch.org/whl/cpu`) if you want to skip CUDA.
```mermaid
flowchart LR
Text["outcome text
(workflow params + result)"] --> Embed["embed(payload)
lazy SentenceTransformer
thread-safe cache"]
Embed --> Vec["384-dim
L2-normalized list[float]"]
Vec --> Cos["cosine similarity
(= dot product)"]
Cos --> Neighbors["nearest-neighbor
outcome retrieval"]
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Embed,Vec,Cos orange
class Text,Neighbors yellow
```
The acceptance test (`tests/embedder/test_minilm_clustering.py`) verifies the contract on a 50-outcome × 5-theme corpus: within-theme cosine averages stay above 0.4, between-theme below 0.3, separation above 0.15. A parallel control using deterministic hash-based "synthetic" vectors (the shape of a placeholder stub) deliberately does **not** cluster — the test asserts `|within − between| < 0.05` and that both averages sit near zero. This is the contract that distinguishes a real embedder from a placeholder before an in-process retrieval path consumes it. **`record_outcome` and the existing JSONL pipeline are not modified by this step** — the embedder is wired in as a future-ready dependency, opt-in, not switched on yet.
### Tool Inventory
**133 tools reachable via the central dispatcher** (`agent/tools/__init__.py:handle()`). The dispatcher routes through TWO maps:
- `_HANDLERS` (106 entries) — tools registered via module-level `TOOLS:` lists. Loaded eagerly at import time for the intelligence + stage layers.
- `_BRAIN_TOOL_NAMES` (27 entries) — tools registered via `BrainAgent` SDK subclasses (`__init_subclass__` auto-registration in `agent/brain/_sdk.py`). Loaded lazily on first call when `BRAIN_ENABLED=true` to break import cycles.
Sum: 106 + 27 = 133. Verify the live count with:
```python
from agent.tools import _HANDLERS, _BRAIN_TOOL_NAMES, _ensure_brain
_ensure_brain() # forces lazy brain registration
print(len(_HANDLERS) + len(_BRAIN_TOOL_NAMES))
```
| Layer | Count | Dispatch | Highlights |
|-------|-------|----------|------------|
| **Intelligence** (`agent/tools/`) | 84 | TOOLS list → `_HANDLERS` | Workflow parsing, model search (CivitAI + HF + 31k nodes), delta patching, graph surgery, canvas bridge, UI→API parsing, execution profiling, auto-wire, provisioning, execution, NIM lifecycle, model swap, **zero-LLM recipes** |
| **Stage** (`agent/stage/`) | 22 | TOOLS list → `_HANDLERS` | USD cognitive state, LIVRPS composition, predictive experiments, scene composition |
| **Brain** (`agent/brain/`) | 27 | BrainAgent SDK → `_BRAIN_TOOL_NAMES` | Vision analysis, goal planning, pattern memory, GPU optimization, artistic intent capture, iteration tracking |
| **Total** | **133** | | |
### Workflow Lifecycle
```mermaid
flowchart LR
Load[Load] --> Validate[Validate]
Validate --> Errors{"Errors?"}
Errors -->|"Missing nodes"| Repair["Auto-Repair
installs wait for your OK"]
Errors -->|"Missing inputs"| Fix[Auto-Fix
set_input]
Errors -->|None| Analyze[DAG
Analysis]
Repair --> Validate
Fix --> Validate
Analyze --> Gate[Safety
Gate]
Gate --> Patch[Patch via
Delta Layer]
Patch --> Run[Run on
ComfyUI]
Run --> Check[Check
Output]
Check --> Learn[Record
Experience]
Patch -->|Undo| Validate
Check -->|Iterate| Patch
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class Gate,Run,Check orange
class Load,Repair,Fix,Analyze,Learn,Validate,Errors,Patch yellow
```
### Project Structure
```
agent/
llm/ Multi-provider LLM abstraction (Anthropic, OpenAI, Gemini, Ollama, NVIDIA, Custom)
recipes/ Zero-LLM recipe layer -- 14+ deterministic intent/build macros
engine/ Execution-engine abstraction (IAIEngine + ComfyUIAdapter)
Wraps POST /prompt, POST /interrupt, GET /history, WS /ws
so the agent's execution path is backend-pluggable
embedder.py BGE (bge-small-en-v1.5) -- 384-dim L2-normalized vectors
Lazy-loaded, thread-safe, opt-in via the [embed] extra
tools/ 84 tools -- workflow ops, model search, provisioning, auto-wire, recipes,
graph surgery, canvas bridge, UI->API parser, execution profiling
workflow_patch.py wraps the cognitive engine for non-destructive PILOT
comfy_execute.py routes execution traffic through agent/engine/
nim_lifecycle.py NVIDIA NIM preflight / run / warm-state wrapper
brain/ 27 tools -- vision, planning, memory, optimization
adapters/ Pure-function translators between brain modules
stage/ 22 tools -- USD state, prediction, composition (USD optional via [stage])
dag/ Workflow intelligence (6 computation nodes)
gate/ Pre-dispatch safety (5-check pipeline)
metrics.py Observability (Counter, Histogram, Gauge -- pure stdlib, thread-safe)
degradation.py Fault isolation manager
config.py Environment + 4 kill switches + LLM provider selection
mcp_server.py MCP server (primary interface)
cognitive/ LIVRPS state engine -- installed as top-level package (Phase 0.5)
core/ CognitiveGraphEngine, DeltaLayer, WorkflowGraph (link-preserving)
experience/ ExperienceChunk, GenerationContextSignature, Accumulator
prediction/ CognitiveWorldModel, SimulationArbiter, CounterfactualGenerator
transport/ SchemaCache, ExecutionEvent, interrupt, system_stats, TriggerRegistry
pipeline/ Autonomous end-to-end orchestration
tools/ Phase 3 macro-tools (analyze, mutate, query, compose, ...)
ui/
__init__.py WEB_DIRECTORY + route registration
web/js/sidebar.js Native left sidebar -- chat, quick actions, progress
web/css/ Design system v3 -- ComfyUI-native CSS variables, theme-reactive
server/routes.py WebSocket + REST endpoints for sidebar chat
panel/
__init__.py WEB_DIRECTORY + route registration + sys.path injection
server/routes.py 51 REST routes -- full tool surface (+ write-back v1 endpoints)
server/touched.py Per-session "last pushed" snapshot + compute_touched (F-1)
server/chat.py WebSocket chat handler -- clears touched session on disconnect
web/js/ Bidirectional canvas bridge (no visible UI -- sidebar is primary)
_deltaFailures.js L-7 surface-report accumulator
_pushApplyTouched.js L-3/L-4/L-5/L-8 apply pipeline (widget + link + surface)
_pushControl.js L-6 debounce + withObserverPause (module-level refcount)
_pushOrchestrator.js Composed push: clear → fetch → pause → apply → ack
superduperPanel.js Headless canvas↔agent bridge entry point
agentClient.js HTTP client incl. getWorkflowApiWithTouched / ackPush
graphMode.js GRAPH-mode panel + delta-failure status bar + modal
tests/ 4,680+ pytest + 87 Vitest, all mocked, ~8min + ~250ms
panel/ Vitest suite for write-back v1 (sample, deltaFailures,
pushApplyTouched, pushControl, pushOrchestrator,
integration, stress + LiteGraph stubs)
integration/ Skips cleanly when ComfyUI not running
test_bridge_routes_integration.py -- live agent<->node-pack seam
```
### Production Hardening
| Domain | What it means |
|--------|-------------|
| **Safety** | 5-check default-deny gate that **fails closed** if the gate itself can't import. Risk levels 0-4; every dispatched tool explicitly classified (a completeness test pins the registry against drift). Installs/downloads escalate for your confirmation. Session-workflow execution requires a passing validation since the last change. Destructive ops never auto-execute. |
| **Fault Isolation** | Each subsystem fails independently. Circuit breakers prevent cascading failures. `brain` (threshold=3, timeout=30s) and `comfyui_http` (threshold=5, timeout=60s) registered; `BRAIN_ENABLED=0` kill switch fully enforced in tool registry. Session isolation: each `comfy-cozy mcp` process gets a unique `conn_XXXXXXXX` namespace; ContextVar set in executor thread before dispatch. Parallel tool dispatch routes through `agent.tools.handle` live module reference -- monkey-patch visible to all ThreadPoolExecutor workers. |
| **Determinism** | Pure computation DAG. Deterministic JSON. Ordinal state enums. Same input = same output. |
| **Audit Trail** | Every mutation logged: who changed what, when, and what got overridden. |
| **Security** | Bearer token auth on all routes including WebSocket — **constant-time `hmac.compare_digest`** comparison (no timing-attack leakage). **WebSocket Origin allowlist** on sidebar + panel (rejects cross-origin connects from `evil.com`; same-origin LAN browsers pass). Path traversal blocked. **`download_model` symlink-bypass guard**: resolves the full target path (parent + filename) and re-checks against `MODELS_DIR` so a planted symlink in a `Custom_Nodes` subdirectory can't escape. SSRF prevented on initial URL and every redirect hop (RFC 1918 + loopback + link-local + CGNAT rejected via DNS resolution). MCP tool errors return `isError=True` per protocol. Gate exceptions deny by default (no silent allow). 10 MB + chunked-transfer size guards. Max 20 concurrent WebSocket connections. Atomic file writes with `flush()`+`os.fsync()` before rename (session.py + workflow_patch.py). Thread-safe token bucket rate limiter. **Handler exception guard**: stream callbacks wrapped with `_wrap_safe` so a misbehaving custom renderer can't crash the agent loop. **Config sanitization**: `COMFYUI_HOST` stripped of whitespace and trailing slashes to prevent malformed URLs. |
| **Observability** | Thread-safe metrics module (`agent/metrics.py`): Counter, Histogram, Gauge. Tool call latency (p50/p99), error rates, LLM call timing, circuit breaker transitions, session counts. JSON + Prometheus text export. Health endpoint includes metrics summary. Zero external dependencies. |
| **Bounded Resources** | Intent history (100), iteration steps (200), demo checkpoints (100). No unbounded growth. |
```mermaid
graph TB
subgraph Sec ["Security"]
A1["Auth -- Bearer token
(REST + WebSocket)"]
A2["Rate limit -- Token bucket
per category"]
A3["Size guard -- 10 MB limit
+ chunked-transfer block"]
A4["WS cap -- 20 connections max"]
end
subgraph Atom ["Persistence"]
B1["_save_lock
threading.Lock"]
B2["Write to .jsonl.tmp"]
B3["os.replace()
atomic swap"]
B1 --> B2 --> B3
end
subgraph Resil ["Resilience"]
C1["CWM exception
--> PipelineStage.FAILED"]
C2["Template mismatch
--> result.warnings"]
C3["Save failure
--> non-fatal log"]
end
subgraph Obs ["Observability"]
D1["Counter / Histogram / Gauge
thread-safe, pure stdlib"]
D2["tool_call_total
tool_call_duration_seconds"]
D3["get_metrics() -- JSON
get_metrics_prometheus() -- text"]
D1 --> D2 --> D3
end
style Sec fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Atom fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Resil fill:#d9c958,color:#1a1a1a,stroke:#d99458
style Obs fill:#d9c958,color:#1a1a1a,stroke:#d99458
classDef orange fill:#d99458,color:#1a1a1a,stroke:#1a1a1a
classDef yellow fill:#d9c958,color:#1a1a1a,stroke:#1a1a1a
class A1,A2,A3,A4,B1,B2,B3,replace,C1,C2,C3,D1,D2,D3,get_metrics,get_metrics_prometheus yellow
```
---
## Configuration
All settings live in your `.env` file — `~/.comfy-cozy/.env` for an installed package, the repo root for a checkout (searched in that order; the current directory is deliberately excluded):
| Setting | Default | What it does |
|---------|---------|-------------|
| `ANTHROPIC_API_KEY` | *(required for Anthropic)* | Your Claude API key |
| `OPENAI_API_KEY` | | Your OpenAI API key |
| `GEMINI_API_KEY` | | Your Google Gemini API key |
| `LLM_PROVIDER` | `anthropic` | Which LLM to use: `anthropic`, `openai`, `gemini`, `ollama`, `nvidia`, `custom` |
| `AGENT_MODEL` | *(auto per provider)* | Override the model name |
| `FAST_MODEL` | *(auto per provider)* | Model for short triage / classification (Haiku 4.5 default on Anthropic) |
| `VISION_MODEL` | *(same as `AGENT_MODEL`)* | Model for vision tools (`analyze_image`, `compare_outputs`) |
| `THINKING_BUDGET` | `4000` | Extended-thinking budget per agent turn (Anthropic Claude 4.x+ only; `0` disables; requires `max_tokens > 1024` or the call raises `ValueError`) |
| `VISION_THINKING_BUDGET` | `2000` | Extended-thinking budget for vision-tool calls (`0` disables) |
| `OLLAMA_BASE_URL` | `http://localhost:11434/v1` | Ollama server URL |
| `CUSTOM_BASE_URL` | `http://localhost:8000/v1` | Endpoint for the `custom` provider (vLLM / LM Studio / LiteLLM / OpenRouter / …) |
| `CUSTOM_API_KEY` | | Key for the `custom` endpoint (optional -- many local servers need none) |
| `CUSTOM_MODEL` | | Model id your `custom` endpoint serves |
| `MODEL_SELECTION_PATH` | `~/.comfy-cozy/model_selection.json` | Where your last model pick is remembered across restarts |
| `COMFY_COZY_HOME` | `~/.comfy-cozy` | Where an installed package keeps its state (`.env`, sessions, logs); checkouts keep repo-root `sessions/` and `logs/` |
| `COMFYUI_HOST` | `127.0.0.1` | Where ComfyUI runs |
| `COMFYUI_PORT` | `8188` | ComfyUI port |
| `COMFYUI_DATABASE` | `~/ComfyUI` | Your ComfyUI folder (models, nodes, workflows) |
---
## Testing
No ComfyUI needed -- everything is mocked:
```bash
python -m pytest tests/ -v # 4,680+ passing tests, ~8min
# Skip tests that require a real ComfyUI server or API keys
python -m pytest tests/ -v -m "not integration"
```
The `[dev]` install runs the full test suite -- no ComfyUI server or API keys required, everything is mocked. The `test_provisioner.py` tests require `usd-core` (install with `pip install -e ".[stage]"` to resolve them).
### JavaScript / panel write-back v1
The bidirectional canvas bridge runs its own Vitest suite under `tests/panel/`:
```bash
npm install --include=dev # one-time -- pulls Vitest
npm test # 87 Vitest cases, ~250ms
```
The suite covers: surface-report accumulator, push-apply pipeline (widget + link), push control (`debounce` + `withObserverPause` + concurrent-pause refcount), push orchestrator (vi.fn() stubs), integration (SPEC P1-P4 oracle), and stress (100-entry batch, 50-event burst, 50-node Tier-3, slow ack, rapid sequence). See `harness/SHIP_REPORT.md` for write-back v1 details and `harness/CAPSULE.md` for the F-1..F-8 verification status table.
---
## Sponsor This Project
Comfy Cozy is production software. 4,740+ tests (all mocked, runnable in minutes) cover the 133 MCP tools that drive the workflow lifecycle end-to-end. CI runs the full advertised matrix — Python 3.10–3.13 on Ubuntu and Windows — with the USD stage layer actually installed and tested, not skipped. Six LLM providers — Anthropic, OpenAI, Gemini, Ollama, NVIDIA Nemotron, and any OpenAI-compatible endpoint (`custom`) — sit behind a single abstraction with parity across all six. The [CHANGELOG](CHANGELOG.md) tracks active hardening and new work.
If Comfy Cozy saves you time inside ComfyUI, sponsorship is the most direct way to keep it moving.
**Sponsorship funds:**
- Continued development of the MCP agent layer
- Priority response on sponsor-filed issues
- New intelligence-layer tools — vision evaluators, provisioning, planning
A separate Pro tier with additional offerings is planned. Details when it's ready, not before.
[**Become a sponsor →**](https://github.com/sponsors/JosephOIbrahim) · [Acknowledgments](SPONSORS.md)
---
## License & Patents
**Patent Pending** | [MIT](LICENSE)
Aspects of this architecture -- including deterministic state-evolution, LIVRPS non-destructive composition, predictive experiment pipelines, and the cognitive experience loop -- are the subject of pending US provisional patent applications filed by Joseph O. Ibrahim.
This project shares structural patterns with [Harlo](https://github.com/JosephOIbrahim/Harlo), a USD-native cognitive architecture for persistent AI memory. See Harlo's [PATENTS.md](https://github.com/JosephOIbrahim/Harlo/blob/main/PATENTS.md) for patent details and grant terms.
For questions about patent licensing, commercial licensing, or enterprise arrangements:
**Joseph O. Ibrahim** -- jomar.ibrahim@gmail.com