



A post modern data stack — built for the AI era.
One data model, served over MCP and REST to AI agents, applications, and BI tools.
Created and maintained by Credible, the company behind the AI Analytics Engine.
AI agents: read AGENTS.md first (raw: https://raw.githubusercontent.com/malloydata/publisher/main/AGENTS.md).
It covers starting the server, connecting over MCP, the bundled skills, and the package format. Fetch the raw file, not a summary of this page.
To learn the skills with nothing installed, read https://unpkg.com/@malloy-publisher/skills@latest/skills/malloy-getting-started/SKILL.md. With a shell, npx -y @malloy-publisher/skills@latest install copies them all into this project.
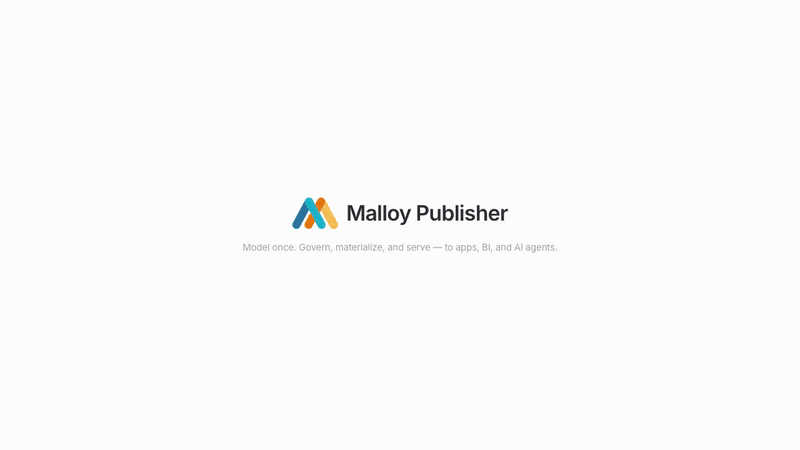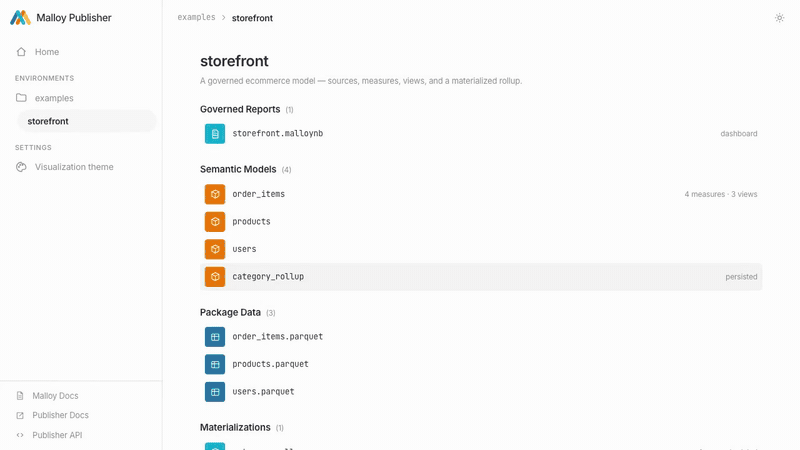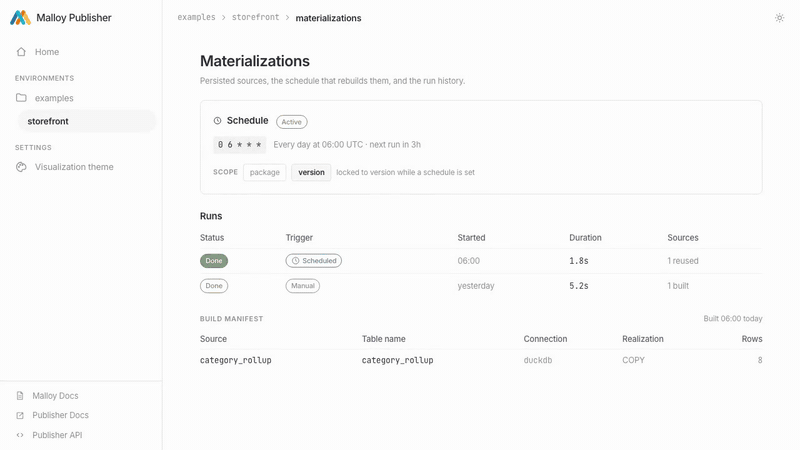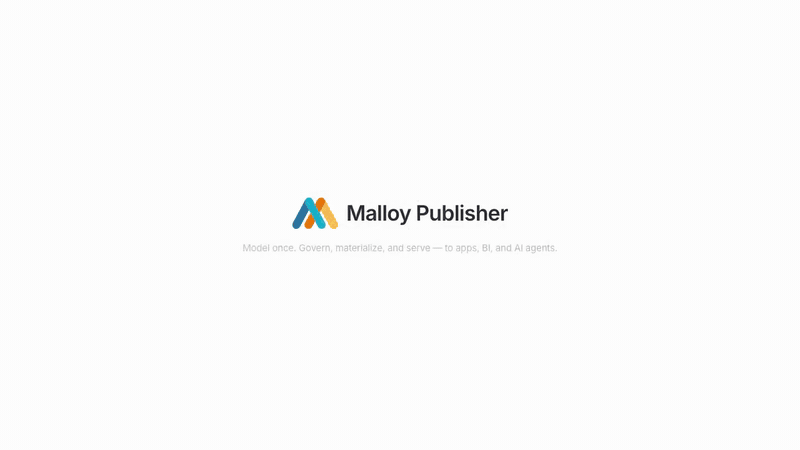
A 60-second walkthrough — model in your IDE with the Malloy skills, serve with Publisher, build a data app, materialize on a schedule, and analyze. Watch the video for playback controls.
Modeling, a query engine, materialization, access control, and an API — the pieces you used to assemble from five projects — ship as one server, built assuming the first builder or consumer is an agent. Write down what your data means, in [Malloy](https://malloydata.dev): the sources, the joins, the measures, who may see what. The open-source Malloy [skills](skills/) ship alongside, so an agent can do the writing — build the model, then the reports and data apps on top of it. Publisher serves that model to every surface — over MCP to Claude, Cursor, Codex, or an agent you build; over REST to applications and BI tools. Agents compose queries against the model instead of writing SQL from scratch, so there is no wrong join, no invented column, no fan-out that double-counts but looks plausible — and the same question returns the same numbers tomorrow. - **Model** — an agent builds the model with the bundled open-source [skills](skills/), from a warehouse or a file, and validates each edit without a restart. - **Analyze** — Claude, Cursor, Codex, or an agent you build asks over MCP; unattended agents and applications use REST. Queries are Malloy, legible enough to review at a glance, and run against the model, never your raw tables. - **Surface** — reports declared in Malloy, read top to bottom or laid out as a grid and built by dragging tiles if you like, and no-build HTML data apps, all shipped inside the package, plus the Console for browsing it all. - **Govern** — givens, `#(authorize)` and `#(access_filter)` decide who may query and who sees what; discovery curation decides what is even visible. - **Optimize** — one `#@ persist` annotation materializes an expensive source into a table and `#@ preaggregate` rolls it up, rebuilt on demand or on a schedule. - **Run anywhere** — DuckDB built in for CSV, Parquet, JSON, and Excel; BigQuery, Snowflake, Postgres, Databricks, MotherDuck, and more by connection; `npx`, Docker, or Compose, in minutes. ## Requirements Node.js 20 or newer (the server refuses to start on anything older and says so). Building from a clone also needs [Bun](https://bun.sh/) 1.3.13+. The Docker image carries its own runtime and needs neither. ## Quick start ### Run the examples ```bash npx @malloy-publisher/server@latest --port 4000 ``` Open **http://localhost:4000**. Three example packages are bundled — [`storefront`](examples/storefront) (a complete ecommerce model), [`governed-analytics`](examples/governed-analytics) (access control), and [`html-data-app`](examples/html-data-app) (a no-build dashboard) — all DuckDB-backed, no credentials required. The first run fetches them from GitHub. ## Start from your own data ### Create a package ```bash mkdir my-data && cd my-data npm create @malloy-publisher/malloy-package@latest sales npm start ``` This writes a package to `./sales` — plus, in the current directory, a small workspace: start and reset scripts, an MCP config, agent instructions, and the Malloy skills as files your agent can read. `npm start` serves the package in watch mode, so edits take effect as you save. Keep the `@latest`: without it npm may reuse a cached, older version. The finer points of `npm create` — caching, workspace layout, the bare `npx` form — are in [docs/scaffolding.md](docs/scaffolding.md). Agents: [AGENTS.md](AGENTS.md) sections 1 and 2 have the same steps plus the pitfalls around `@latest`, the `--` before `--data`, and reconnecting the MCP client after the server starts. ### Bring local data files ```bash npm create @malloy-publisher/malloy-package@latest sales -- --data ./orders.csv ``` CSV, Parquet, JSON, newline-delimited JSON, or Excel `.xlsx` — DuckDB reads all of them in place. The `--` is required, and the path is relative to where you run the command. A seeded package starts small: a row count and an overview, which is the moment to point an agent at it. ### Connect a database A package is just Malloy, so it is not limited to local files. Add a [connection](docs/connections.md) — BigQuery, Snowflake, Postgres, Databricks, MotherDuck, and more — and point the model at it; the same workspace serves a warehouse. Have the warehouse but no model yet? Ask the agent what is in it: `search_database_schema` ranks a connection's tables against a plain-English description and hands back the `source:` line for each. Ranking needs no API key; the optional embedding-backed mode is in [docs/configuration.md](docs/configuration.md#semantic-ranking-for-search_database_schema). ## Point your agent at it ### Connect Claude Code Keep the server from [Quick start](#quick-start) running — or `npm start` from [Create a package](#create-a-package). On startup it wrote a `.mcp.json` into the directory you ran it in, pointing at the MCP port it bound. Open a second terminal, **in that same directory**, and start the agent: ```bash claude ``` Say yes when the agent asks to trust the folder, use the server it found, and approve the first tool call — the trust prompt is asked once per directory, and only interactively, so a headless run can't clear it. Then ask, in plain English: > _"Use Malloy to explore the storefront sales data and chart revenue by category."_ The agent discovers what exists (`get_context`), grounds itself in real source, view, and field names, runs the query (`execute_query`), and answers from your model — no schema spelunking, no hallucinated columns. If the agent reports no Malloy tools, register the server for yourself instead of relying on that file: ```bash claude mcp add --transport http malloy http://127.0.0.1:4040/mcp -s user ``` The server skips writing the file in some directories (a git working tree, your home directory, one that already has a `.mcp.json`) and says so in its startup log. When it is written, why it can go stale, and how to turn it off: [docs/configuration.md](docs/configuration.md#the-mcpjson-the-server-writes). ### Other clients, and unattended agents Cursor, VS Code, Codex, and Claude Desktop take the same endpoint — `http://localhost:4040/mcp`, or whatever `--mcp_port` / `MCP_PORT` you set — through their own config; see [docs/ai-agents.md](docs/ai-agents.md). An agent working unattended that started the server itself uses the same loop over REST: ```bash curl -s -X POST \ http://localhost:4000/api/v0/environments/examples/packages/storefront/models/storefront.malloy/query \ -H 'content-type: application/json' \ -d '{"query":"run: order_items -> by_category","compactJson":true}' | jq -r .result ``` The running server serves its full OpenAPI spec at `http://localhost:4000/api-doc.yaml`. > **Security.** The server — MCP and REST alike — is stateless and unauthenticated, and it can read any > data your models connect to. Bind it to loopback (`--host 127.0.0.1`) for local use, and put an > authenticating gateway in front before exposing it more widely. ## What you can do ### Model - **Build the model with an agent.** The bundled open-source [skills](skills/) carry the whole loop — discover what a database holds, define sources and measures, model as you go, review, document, publish. A LookML review skill covers coming from Looker. - **Start from a warehouse.** `search_database_schema` ranks a connection's tables against a plain-English description and returns the `source:` line for each. - **Validate without a restart.** `compile_model` checks an edit without running it; `reload_package` recompiles a package from disk. Watch mode does the same for a human editing in an IDE. ### Analyze - **Ask in plain English.** An agent grounds itself with `get_context`, runs `execute_query`, and answers from the model, never from raw tables. Analysis skills teach it the pitfalls and how to write up a finding — [docs/ai-agents.md](docs/ai-agents.md). - **Write it up as a report.** A report is a `.malloy` file with an `## artifact` tag, anywhere in a package; it mixes prose and queries and runs on the same governed endpoints. Pick a layout: `linear` for a story read top to bottom, `grid` for a view scanned at a glance — [docs/choosing-a-surface.md](docs/choosing-a-surface.md). - **Explore, no code.** Build and drill into queries visually with [Malloy Explorer](docs/explorer.md); every action generates valid Malloy, so metrics stay correct across joins. ### Surface - **Reports declared in Malloy.** A tagged `.malloy` file _is_ the report: filterable, clickable, laid out as a grid or top to bottom, no code and no build step. Build it by dragging tiles around in the Console if you want the classic dashboard feel, or write the tags by hand — same file either way, and it reviews like any other source file — [docs/reports.md](docs/reports.md). - **No-build HTML data apps.** Ship HTML, CSS, and JavaScript inside a package and Publisher hosts it against the model — [docs/html-data-apps.md](docs/html-data-apps.md). - **The Publisher Console.** Browse packages, models, and every artifact in the built-in web UI, with your own [colors, fonts, and dark mode](docs/theming.md) — [docs/console.md](docs/console.md). - **Your own applications.** The REST API serves any language, and the running server publishes its OpenAPI spec. From Python, the standard library is enough: [AGENTS.md section 7](AGENTS.md#7-working-unattended-the-rest-api) has a copyable example. A generated client lives in [`packages/python-client`](packages/python-client), but it is not published to PyPI. ### Govern - **Decide who sees what.** [Givens](docs/givens.md) declare runtime parameters and drive filter widgets; [row-level access](docs/row-level-access.md) and [`#(access_filter)`](docs/authorize.md) gate which rows a caller gets and whether they may query a source at all. - **Decide what is visible.** Curate what is [discoverable and queryable](docs/discovery-and-access.md) separately, so an agent sees only the sources you meant it to. - **Know the boundary.** [docs/security-posture.md](docs/security-posture.md) lists what Publisher defends against and what it leaves to the gateway in front of it. ### Optimize - **Materialize.** One `#@ persist` annotation turns an expensive source into a table, rebuilt on demand, from the `malloy-pub` CLI, or on a cron with the opt-in scheduler — [docs/materialization.md](docs/materialization.md). - **Pre-aggregate.** `#@ preaggregate` rolls a measure up to a coarse grain so covered queries read a small table instead of the fact table — [docs/preaggregation.md](docs/preaggregation.md). - **Store it where you like.** Persist into a [DuckLake](docs/ducklake.md) storage tier, attach a DuckLake catalog read-only, and run offline or air-gapped — [docs/persist-storage-tutorial.md](docs/persist-storage-tutorial.md). - **Attribute every query.** [Query metadata](docs/query-metadata.md) tags each statement with a team, a workload, a request id, so the warehouse's own reporting can say who asked. ### Run anywhere - **Any data.** DuckDB is built in for CSV, Parquet, JSON, and Excel; connect BigQuery, Snowflake, Postgres, MySQL, SQL Server, Trino, Databricks, MotherDuck, and DuckLake — [docs/connections.md](docs/connections.md). - **Any host.** `npx`, Docker, or Docker Compose, in minutes — [docs/deployment.md](docs/deployment.md). - **Alongside dbt.** Where Malloy and dbt fit together, and the plan to close the gaps — [docs/dbt-roadmap.md](docs/dbt-roadmap.md). ## Examples The fastest way to see all of the above is the [`examples/`](examples/) directory. Three are packages Publisher serves out of the box, and a fourth shows the SDK: - **[storefront](examples/storefront)** — the flagship ecommerce model: sources, joins, reports in both layouts, and givens-driven filters. It is the package Quick start serves, and the one the SDK example reads from. - **[governed-analytics](examples/governed-analytics)** — the whole governance story in one small package: givens, row-level access, and `#(access_filter)` source gates. - **[html-data-app](examples/html-data-app)** — a no-build SaaS subscriptions dashboard served from a package's `public/` directory, driven by `Publisher.query()`. - **[data-app](examples/data-app)** — a standalone Vite + React app on [`@malloy-publisher/sdk`](packages/sdk), embedding live results in your own UI. Not a served package. ## Documentation The [`docs/`](docs/) folder is the reference hub; start at its [index](docs/README.md). Beyond the guides linked above: [architecture](docs/architecture.md) for how the pieces fit together, [api-overview](docs/api-overview.md) for the REST and MCP surface, [packages](docs/packages.md) for the package format (`publisher.json`, models, data), and the [Docker runtime deep-dive](packages/server/README.docker.md) for image layout, environment, and tuning. The complete user guide also lives at **[docs.malloydata.dev](https://docs.malloydata.dev/documentation/user_guides/publishing/publishing)**. ## Publisher and Credible Publisher is created and maintained by [Credible](https://www.credibledata.com), the company behind the **AI Analytics Engine**. The two fit together like this: - **Publisher is the open-source analytics engine.** It serves Malloy models over REST and MCP, and everything an agent needs from the language and the server — the modeling and analysis skills, the MCP tools — ships here in the open. Run it on a laptop, in Docker, or wherever you like. - **Credible is the hosted, governed engine built around it.** You write down what your data means once, in Malloy; the engine owns the how — it materializes and indexes the model in storage it brings along, enforces access at one gateway on every query, compresses each model into a concept index so an agent gets just the slice a question needs, and serves every surface — agents over MCP, dashboards and workspaces, the data apps and APIs in your product — from one model. Run Publisher yourself, or let Credible run it: the model is the same Malloy either way, and moving between them is a publish, not a rewrite. Where the open-source engine ends and the hosted one begins: [credibledata.com/malloy](https://www.credibledata.com/malloy) · [Inside the AI Analytics Engine](https://www.credibledata.com/blog/posts/inside-the-ai-analytics-engine). ## Contributing Build and hack on Publisher from a clone with [docs/development.md](docs/development.md); contribution process and sign-off are in [CONTRIBUTING.md](CONTRIBUTING.md). ## Community - Join the [Malloy Slack](https://join.slack.com/t/malloy-community/shared_invite/zt-1kgfwgi5g-CrsdaRqs81QY67QW0~t_uw) - Report issues on [GitHub](https://github.com/malloydata/publisher/issues) - Report a security vulnerability privately — see [SECURITY.md](SECURITY.md) for the reporting form and what's in scope