# tokio-prompt-orchestrator
**Run many LLM agents at once without blowing your rate limit or your bill: 24 Claude Code agents ran on one RTX 4070, and deduplication cut API use to 26% of expected.**
**Why this over the alternatives:** A plain request queue sends every duplicated context to the API. This collapses duplicates into one call, with backpressure and circuit breakers built in.
**Guarantee:** if it doesn't do what this README says, [open an issue](https://github.com/Mattbusel/tokio-prompt-orchestrator/issues) and I'll fix it.
English | [简体中文](README.zh-CN.md) | [日本語](README.ja.md) | [한국어](README.ko.md)
**A Rust LLM request orchestrator: it sits between your app and an AI model (Anthropic, OpenAI, llama.cpp, vLLM), so the same prompt asked twice costs one model call, and when the provider goes down your requests fail fast with a clear reason instead of piling up.**
For developers who call an LLM API from an app, an agent or a script and want it to stay fast and predictable under load and during outages. Use it as a ready-made server (`orchestrator`) or as a Rust library.
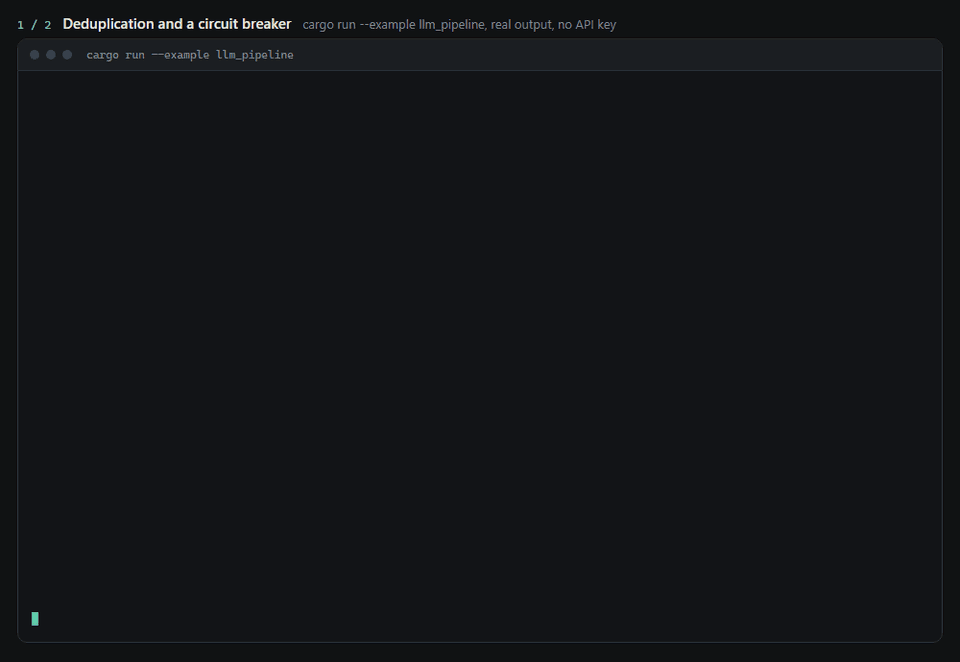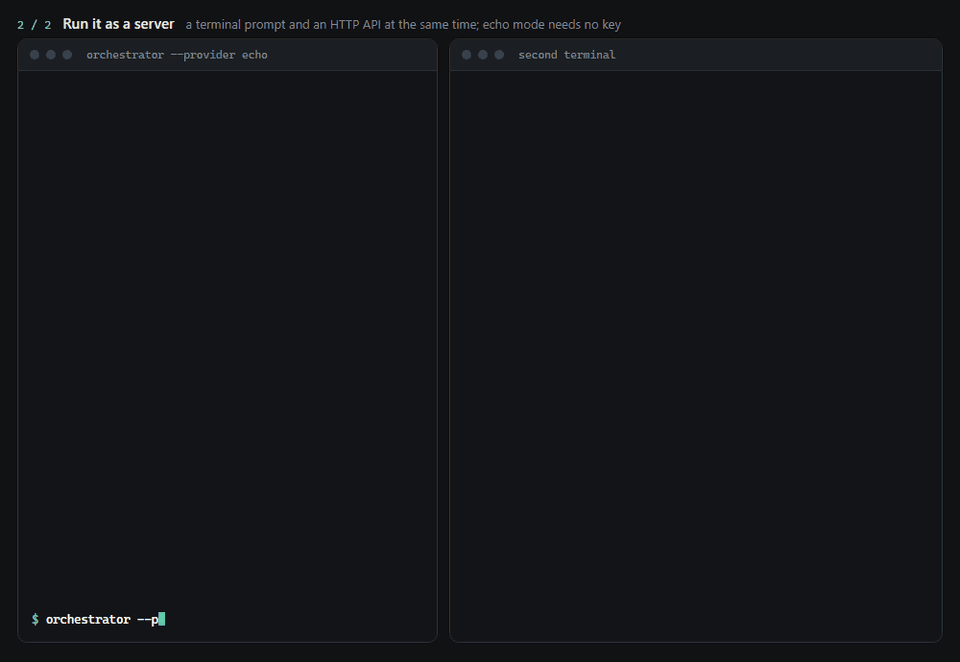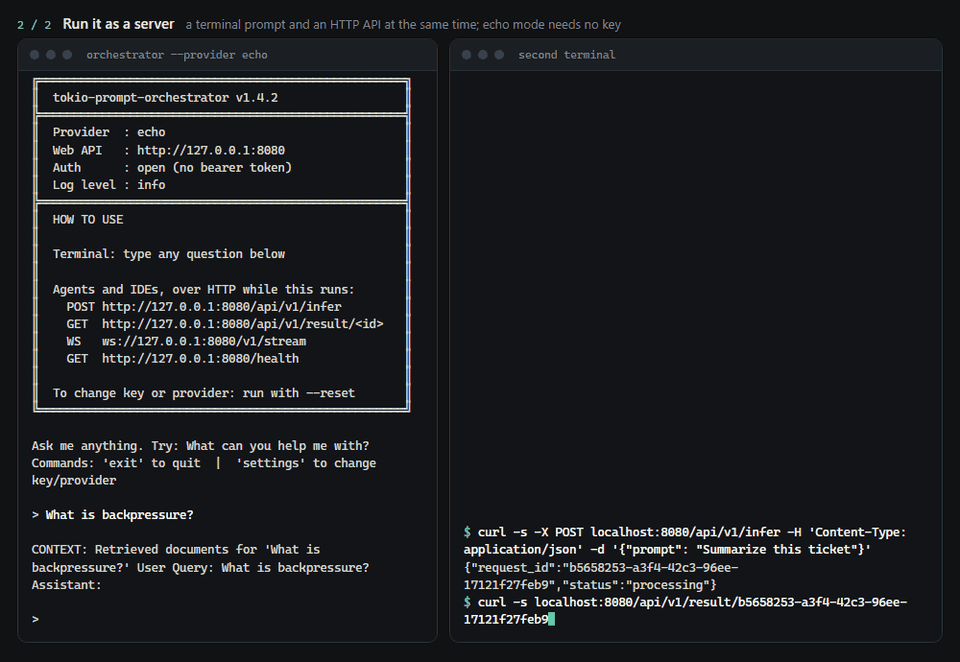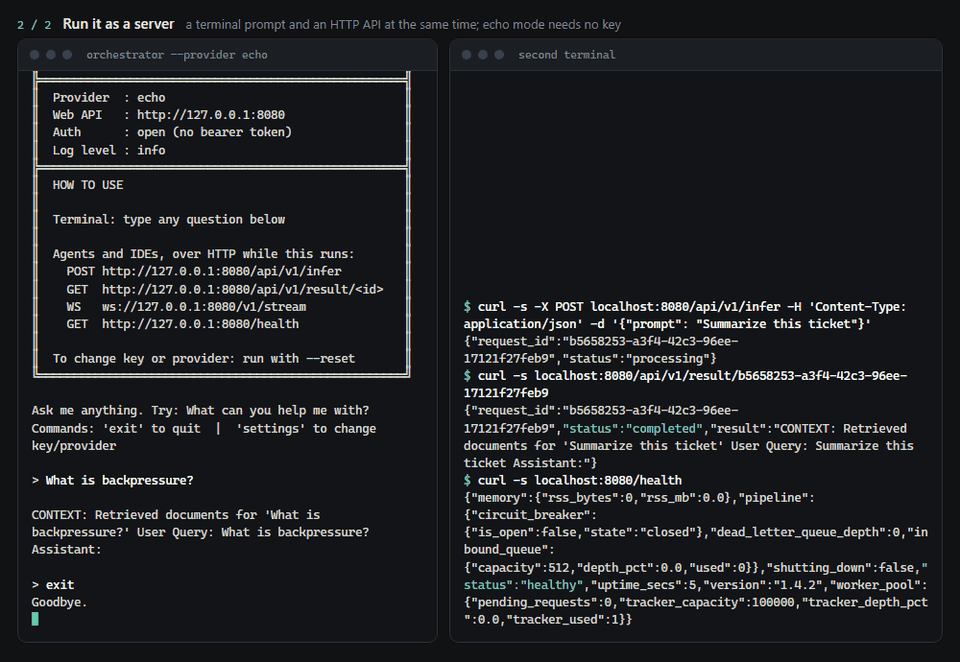
A real recording, sped up only where it was waiting. The site replays the same run step by step.
## See the numbers before you install
- [LLM proxy benchmark: 200 duplicate calls became 1](https://tensorust.com/articles/llm-proxy-benchmark/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) measures this crate's deduplication on real traffic, including the one bug it found.
- [LLM semantic cache: stop paying twice for the same answer](https://tensorust.com/articles/llm-semantic-cache-duplicate-prompts/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) covers when a cache in front of the pipeline pays off.
- [Exponential backoff with jitter: 64 of 100 LLM calls failed](https://tensorust.com/articles/exponential-backoff-jitter/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) shows why the retry stage works the way it does.
- Price your own workload first with the free [LLM API cost calculator](https://tensorust.com/tools/llm-api-cost/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) and [token counter](https://tensorust.com/tools/token-counter/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator).
## Install
**Linux** (x86_64, Ubuntu 20.04+ / Debian 11+). One line, no dependencies, installs to `~/.local/bin`:
```sh
mkdir -p ~/.local/bin && curl -fsSL https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases/permalink/latest/downloads/orchestrator-linux-x86_64.tar.gz | tar xz --strip-components=1 -C ~/.local/bin --wildcards '*/orchestrator'
```
| Other systems | |
|---|---|
| **Windows** | [Download orchestrator-windows-x86_64.exe](https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases/permalink/latest/downloads/orchestrator-windows-x86_64.exe) and run it. (Unsigned, so SmartScreen may ask: *More info*, then *Run anyway*.) |
| **macOS, or from source** | `cargo install --locked tokio-prompt-orchestrator --features web-api,tantivy` (add `fastembed` for `--semantic-dedup`) |
Every method installs the same `orchestrator` command. Every release, with SHA-256 checksums: [Releases](https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases).
## Drop-in OpenAI proxy
Any app that already uses an OpenAI client gets deduplication, the circuit breaker, timeouts, a spend cap and the dead-letter queue with no code change: start `orchestrator` and point the client's base URL at it.
```sh
export OPENAI_BASE_URL=http://127.0.0.1:8080/v1
```
With `orchestrator --provider echo` running (echo mode answers with your prompt, no key needed), the official Python client (`pip install openai`), unchanged:
```python
from openai import OpenAI
client = OpenAI() # reads OPENAI_BASE_URL and OPENAI_API_KEY
reply = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Summarize this ticket"}],
)
print(reply.choices[0].message.content, reply.usage.total_tokens)
for chunk in client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Now stream it"}],
stream=True,
):
if chunk.choices:
print(chunk.choices[0].delta.content or "", end="")
print()
```
```text
Summarize this ticket 10
Now stream it
```
The same question again from `curl` is answered from the dedup window, without a model call:
```bash
curl -s -i localhost:8080/v1/chat/completions -H 'Content-Type: application/json' \
-d '{"model": "gpt-4o-mini", "messages": [{"role": "user", "content": "Summarize this ticket"}]}'
```
```text
x-orchestrator-dedup: cached
{"choices":[{"finish_reason":"stop","index":0,"logprobs":null,"message":{"content":"Summarize this ticket","refusal":null,"role":"assistant"}}],"created":1790804186,"id":"chatcmpl-4d5284a811bd4c0f90bee01018103e1a","model":"echo","object":"chat.completion","system_fingerprint":null,"usage":{"completion_tokens":5,"prompt_tokens":5,"total_tokens":10}}
```
The orchestrator answers with the provider and model it was started with (`--provider openai --model gpt-4o-mini`, say), whatever `model` the request names. Errors come back in OpenAI's format: 503 while the breaker is open (with `x-should-retry: false`, so the SDK does not retry it), 429 at the spend cap. Details, auth and limits: [docs/REFERENCE.md](docs/REFERENCE.md#openai-compatible-api).
For OpenAI models the token counts in `usage` (and so the spend cap) come from the model's own tokenizer, so they match your OpenAI bill. Other models get an estimate of about 4 characters per token, which is what you see from `echo` above.
## Drop-in Anthropic proxy
The same for Anthropic clients: point the base URL at the orchestrator and `POST /v1/messages` gets the same deduplication, circuit breaker and spend cap. The official Python SDK, unchanged, against `orchestrator --provider echo`:
```python
import anthropic
client = anthropic.Anthropic(base_url="http://127.0.0.1:8080", api_key="local")
msg = client.messages.create(
model="claude-sonnet-4-6",
max_tokens=200,
messages=[{"role": "user", "content": "Summarize this ticket"}],
)
print(msg.content[0].text, msg.stop_reason)
with client.messages.stream(model="claude-sonnet-4-6", max_tokens=200,
messages=[{"role": "user", "content": "Now stream it"}]) as s:
print("".join(s.text_stream))
```
```text
Summarize this ticket end_turn
Now stream it
```
Text conversations, system prompts and streaming are supported; image and tool blocks are rejected with a clear `invalid_request_error`. The key goes in `x-api-key` (as the Anthropic SDKs send it) or `Authorization: Bearer`.
## Server flags
The flags that change how `orchestrator` treats your provider (`orchestrator --help` lists them all):
| Flag | Default | What it does |
|---|---|---|
| `--concurrency ` | 16 | Model calls sent upstream at the same time. 20 different prompts at once with a 1.5 s provider take about 1.5 s at the default; with `--concurrency 1` they queue and take about 30 s. Identical prompts in flight still share one call whatever the setting. |
| `--timeout ` | 30 (60 for `anthropic`) | Longest one upstream call may take. A call that runs past it is answered `504 upstream_timeout` and counts as a failure for the circuit breaker, so a provider that accepts connections and never answers opens the breaker instead of holding every caller. |
| `--retries ` | 0 | Retry a call that failed with a 429, a 5xx or a network error, with backoff. |
| `--max-spend ` | none | Spend cap: the API answers 429 once it is reached. |
| `--semantic-dedup [0.5-1.0]` | off | Also reuse answers to reworded questions (needs `fastembed`). |
| `--docs ` | off | Answer from your own Markdown and text files (needs `tantivy`). |
When the breaker is open, refused requests come back as `503 circuit_open` with `x-should-retry: false` and a `Retry-After` set to when the breaker will try the provider again. The OpenAI and Anthropic SDKs read `x-should-retry`, so they fail at once instead of retrying a request that cannot succeed yet.
## Answer from your own documents
`orchestrator --docs ./my-docs` indexes the Markdown and text files in a folder ([tantivy](https://crates.io/crates/tantivy) BM25 search with English stemming, in memory) and sends the best passages, with their file names, in front of each question. Real run with `--provider echo`, which shows exactly what the model receives:
```text
Answering from 2 passages in ./demo-docs
> How long do refunds take?
Use the following excerpts to answer. If they do not contain the answer, say so. [1] (policies/refunds.md) # Refunds Refunds are issued to the original card within 14 days of us receiving the return. Gift cards cannot be refunded. Question: How long do refunds take?
```
If search fails or takes longer than 2 seconds, the prompt is sent without context; a request is never dropped because of retrieval. In Rust: `spawn_pipeline_with(worker, PipelineOptions::with_retriever(Arc::new(TantivyRetriever::index_dir("./docs")?)))`, or implement the `Retriever` trait over your own search (a vector database, Elasticsearch, Postgres).
## Semantic dedup: same question, different words
Exact dedup only catches identical prompts. With an embedder, the OpenAI and Anthropic endpoints also answer a reworded question from the cache (`x-orchestrator-dedup: semantic`, with the similarity in `x-orchestrator-similarity`). `orchestrator --semantic-dedup` uses a local model ([fastembed](https://crates.io/crates/fastembed), BGE-small, no API key, 128 MB downloaded once to your cache directory); in Rust, `Deduplicator::with_embedder` takes it or an OpenAI/genai embedder.
Embeddings alone are not safe for this. Measured with BGE-small, "Convert 10 miles to kilometers" and "Convert 10 kilometers to miles" score 0.99, higher than any real paraphrase we tried. So a match must also have the same numbers and its shared words in the same order. On our test pairs (`tests/semantic_dedup_tests.rs`), at the default threshold of 0.93:
| Pair | Similarity | Answer reused |
|---|---|---|
| "What is the capital of France?" / "Which city is the capital of France?" | 0.959 | yes |
| "How many ounces are in a pound?" / "How many oz in one lb?" | 0.931 | yes |
| "How do I reverse a list in Python?" / "What's the way to reverse a Python list?" | 0.985 | no (word order; costs one call) |
| "Convert 10 miles to kilometers" / "Convert 10 kilometers to miles" | 0.992 | no |
| "Is 17 a prime number?" / "Is 21 a prime number?" | 0.845 | no |
It errs toward a second model call, never toward someone else's answer. Check the hits on your own traffic before lowering the threshold.
## How it works
Each stage is its own Tokio task. A full channel never grows memory: the request is shed to the dead-letter queue with the reason, and the HTTP API answers `429` with `Retry-After`. Everything in the drawing is read from [`src/stages.rs`](src/stages.rs); more in [docs/ARCHITECTURE.md](docs/ARCHITECTURE.md).
**Retries for brief hiccups.** Providers sometimes fail for a second: a 429, a 503, a dropped connection. Start with `orchestrator --retries 2` (or set `retry_attempts` in a pipeline config) and such a call is tried again after a short, randomised wait that doubles each time, before it counts as a failure. A provider's `Retry-After` is respected, a bad API key is never retried, and all the tries of one request count once for the circuit breaker. It is off by default, so the breaker demo above behaves exactly as shown.
**Built on proven crates.** The parts that are easy to get subtly wrong come from widely used open-source libraries rather than code written here: [backon](https://crates.io/crates/backon) for retry timing, [moka](https://crates.io/crates/moka) for the dedup cache (it has a size limit, so a flood of different prompts cannot grow memory without bound), [tiktoken-rs](https://crates.io/crates/tiktoken-rs) for OpenAI token counts, and [prometheus](https://crates.io/crates/prometheus) for `/metrics`.
## Examples
**1. Twelve requests, three model calls, then an outage.** `cargo run --example llm_pipeline` (no key needed), real output from today, trimmed:
```text
1) 12 requests: 4 users x 3 questions
req-01 alice The capital of France is Paris.
req-02 alice Backpressure means a slow consumer makes fast producers wait instead of letting queues grow without bound.
...
req-12 dave Bounded channels fill / the sender waits its turn now / memory stays calm
-> 12 answers in 0.9s, 3 model calls (9 saved by dedup)
2) Provider outage: 8 new requests while every call fails
DLQ req-13 inference_failure:inference failed: 503 Service Unavailable (simulated outage)
...
DLQ req-17 inference_failure:inference failed: 503 Service Unavailable (simulated outage)
DLQ req-18 circuit open, failed fast (provider not called)
DLQ req-19 circuit open, failed fast (provider not called)
DLQ req-20 circuit open, failed fast (provider not called)
-> breaker is Open; it lets one probe through after 60s to test recovery
```
Set `PROVIDER=anthropic ANTHROPIC_API_KEY=...` or `PROVIDER=openai OPENAI_API_KEY=...` to make the same 3 calls against a real model. The source, [`examples/llm_pipeline.rs`](examples/llm_pipeline.rs), is a good template for your own backend.
**2. Any tool can use it over HTTP.** With `orchestrator --provider echo` running (echo mode answers with the prompt exactly as the model would receive it):
```bash
curl -s -X POST localhost:8080/api/v1/infer -H 'Content-Type: application/json' -d '{"prompt": "Summarize this ticket"}'
```
```json
{"request_id":"d6a70800-99ef-4f2b-9b27-63b02af7d972","status":"processing"}
```
```bash
curl -s localhost:8080/api/v1/result/d6a70800-99ef-4f2b-9b27-63b02af7d972
```
```json
{"request_id":"d6a70800-99ef-4f2b-9b27-63b02af7d972","status":"completed","result":"Summarize this ticket"}
```
```bash
curl -s localhost:8080/health
```
```json
{"memory":{"rss_bytes":0,"rss_mb":0.0},"pipeline":{"circuit_breaker":{"is_open":false,"state":"closed"},"dead_letter_queue_depth":0,"inbound_queue":{"capacity":512,"depth_pct":0.0,"used":0}},"shutting_down":false,"status":"healthy","uptime_secs":2,"version":"2.0.0","worker_pool":{"pending_requests":0,"tracker_capacity":100000,"tracker_depth_pct":0.0,"tracker_used":1}}
```
**3. In your own Rust code.** [`examples/quickstart.rs`](examples/quickstart.rs), `cargo run --example quickstart`:
```rust,no_run
use std::{collections::HashMap, sync::Arc};
use tokio_prompt_orchestrator::{spawn_pipeline, EchoWorker, ModelWorker, PromptRequest, SessionId};
#[tokio::main]
async fn main() -> Result<(), Box> {
// Swap EchoWorker for AnthropicWorker, OpenAiWorker, LlamaCppWorker, VllmWorker,
// or a worker over the client you already use (next section).
let worker: Arc = Arc::new(EchoWorker::new());
let handles = spawn_pipeline(worker);
let mut output = handles.take_output_rx().await.ok_or("output already taken")?;
handles.input_tx.send(PromptRequest {
session: SessionId::new("demo"),
request_id: "req-1".into(),
input: "Hello, pipeline!".into(),
meta: HashMap::new(),
deadline: None,
}).await?;
let answer = output.recv().await.ok_or("pipeline closed")?;
println!("{}", answer.text);
for dropped in handles.dlq.drain() { println!("dropped {}: {}", dropped.request_id, dropped.reason); }
Ok(())
}
```
```text
Hello, pipeline!
```
Needs `tokio-prompt-orchestrator = "2"` and `tokio = { version = "1", features = ["rt-multi-thread", "macros"] }` in `Cargo.toml`.
## Already using async-openai, genai, rig or tower?
Keep your client. Each of these is a cargo feature that turns it into a worker, so deduplication, the circuit breaker, retries, timeouts and the dead-letter queue sit in front of the code you already have.
| You use | Add | Then |
|---|---|---|
| [async-openai](https://crates.io/crates/async-openai) | `features = ["async-openai"]` | `AsyncOpenAiWorker::new(client, "gpt-4o-mini")`: OpenAI, Azure, or any OpenAI-compatible server (Ollama, vLLM, llama.cpp, LM Studio) |
| [genai](https://crates.io/crates/genai) | `features = ["genai"]` | `GenaiWorker::new(genai::Client::default(), "claude-sonnet-4-6")`: OpenAI, Anthropic, Gemini, Ollama, Groq, DeepSeek, xAI and more, picked by model name |
| [rig](https://crates.io/crates/rig-core) | `features = ["rig"]` | `RigWorker::new(OpenAI::from_env()?.completion("gpt-5.2"))`: any rig completion model; rig-core 0.43 or 0.44 (needs Rust 1.95+) |
| [tower](https://crates.io/crates/tower) | `features = ["tower"]` | `ServiceWorker::new(svc)` runs any `Service` (with your tower layers) as a worker; `WorkerService::new(worker)` goes the other way |
```rust,ignore
use std::sync::Arc;
use async_openai::{config::OpenAIConfig, Client};
use tokio_prompt_orchestrator::{integrations::AsyncOpenAiWorker, spawn_pipeline};
// The client you already have, here pointed at a local Ollama.
let client = Client::with_config(
OpenAIConfig::new().with_api_base("http://localhost:11434/v1").with_api_key("ollama"),
);
let handles = spawn_pipeline(Arc::new(AsyncOpenAiWorker::new(client, "llama3.2")));
```
All four are tested end to end against a mock OpenAI server ([`tests/integrations_tests.rs`](tests/integrations_tests.rs)): replies, streaming, and that a rejected key is never retried while a 429 backs off.
### Feature flags
With no features the library is the pipeline, the workers and the resilience parts: 167 crates in the dependency tree. Everything else is opt-in.
| Feature | Adds |
|---|---|
| `web-api` | HTTP server: REST, SSE, WebSocket and the OpenAI-compatible `/v1/chat/completions` |
| `otel` | OpenTelemetry span export over OTLP/HTTP when `OTEL_EXPORTER_OTLP_ENDPOINT` is set |
| `tiktoken` | Exact OpenAI token counts (on with `web-api`) |
| `metrics-server`, `caching`, `rate-limiting` | `/metrics` endpoint, Redis result cache, token-bucket limiter |
| `full` | All of the above plus `cli` and `hot-reload` |
| `async-openai`, `genai`, `rig`, `tower` | The integrations above |
| `tantivy` | `TantivyRetriever` and `--docs`: answers grounded in a folder of documents (Rust 1.90+) |
| `fastembed` | `FastEmbedder` and `--semantic-dedup`: local embeddings for semantic dedup (Rust 1.88+; on Windows it needs the dynamic C runtime, so not with `+crt-static`) |
| `tui`, `mcp`, `dashboard` | Terminal dashboard, MCP server for Claude Desktop and Claude Code, web dashboard |
| `distributed` | Cross-node dedup over Redis, NATS work queues, leader election |
| `hot-reload`, `cli`, `schema`, `core-pinning` | Config file watcher, the `replay` binary, JSON Schema export, CPU pinning |
| `self-tune`, `self-modify`, `intelligence`, `evolution`, `self-improving` | Experimental self-tuning tiers |
## Use it in 3 steps
1. **Start it.** `orchestrator --provider echo` needs no key. You get a `>` prompt in the terminal and a web address, `http://127.0.0.1:8080`.
2. **Send it prompts** from the terminal, or from any app with `POST /api/v1/infer` and `GET /api/v1/result/` (example 2 above).
3. **Point it at a real model.** `orchestrator --reset` asks for a provider and key once and saves them, or pass them directly: `ANTHROPIC_API_KEY=sk-ant-... orchestrator --provider anthropic --model claude-sonnet-4-6`.
`orchestrator --help` lists every flag. If something goes wrong, see [Troubleshooting](docs/GUIDE.md#troubleshooting).
## Documentation
| Read this | For |
|---|---|
| [docs/GUIDE.md](docs/GUIDE.md) | Running the server, the HTTP API, the terminal dashboard, Claude Desktop and Claude Code (MCP), deployment, tuning, troubleshooting, all examples |
| [docs/REFERENCE.md](docs/REFERENCE.md) | Architecture, resilience building blocks, benchmarks, configuration file, environment variables, feature flags, API table, known issues |
| [docs/MODULES.md](docs/MODULES.md) | Every optional module: plugins, sessions, templates, A/B tests, semantic dedup, cache, rate limiter, cron, DLQ replay and more |
| [docs/ARCHITECTURE.md](docs/ARCHITECTURE.md), [docs/configuration.md](docs/configuration.md) | Pipeline design, every config field with its default |
| [WEB_API.md](WEB_API.md), [BENCHMARKS.md](BENCHMARKS.md), [CHANGELOG.md](CHANGELOG.md) | HTTP endpoints, benchmark runs, release notes |
| [docs.rs](https://docs.rs/tokio-prompt-orchestrator) | Full Rust API |
Contributions welcome: see [CONTRIBUTING.md](CONTRIBUTING.md). MIT licensed, see [LICENSE](LICENSE).
Source, issues and stars: [GitHub](https://github.com/Mattbusel/tokio-prompt-orchestrator). Mirror and release downloads: [GitLab](https://gitlab.com/mattbusel/tokio-prompt-orchestrator). More open-source Rust from the same author: [tensorust.com/open-source](https://tensorust.com/open-source/).
## Hire the author
**Need this kind of engineering on your product?** I take on a small number of client builds: LLM features, iOS apps and performance work, fixed price. [Services and pricing](https://tensorust.com/) · [Email](mailto:mattbusel@gmail.com) · [LinkedIn](https://www.linkedin.com/in/matthewbusel/)


 A real recording, sped up only where it was waiting. The site replays the same run step by step.
## See the numbers before you install
- [LLM proxy benchmark: 200 duplicate calls became 1](https://tensorust.com/articles/llm-proxy-benchmark/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) measures this crate's deduplication on real traffic, including the one bug it found.
- [LLM semantic cache: stop paying twice for the same answer](https://tensorust.com/articles/llm-semantic-cache-duplicate-prompts/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) covers when a cache in front of the pipeline pays off.
- [Exponential backoff with jitter: 64 of 100 LLM calls failed](https://tensorust.com/articles/exponential-backoff-jitter/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) shows why the retry stage works the way it does.
- Price your own workload first with the free [LLM API cost calculator](https://tensorust.com/tools/llm-api-cost/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator) and [token counter](https://tensorust.com/tools/token-counter/?utm_source=github&utm_medium=readme&utm_campaign=tokio-prompt-orchestrator).
## Install
**Linux** (x86_64, Ubuntu 20.04+ / Debian 11+). One line, no dependencies, installs to `~/.local/bin`:
```sh
mkdir -p ~/.local/bin && curl -fsSL https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases/permalink/latest/downloads/orchestrator-linux-x86_64.tar.gz | tar xz --strip-components=1 -C ~/.local/bin --wildcards '*/orchestrator'
```
| Other systems | |
|---|---|
| **Windows** | [Download orchestrator-windows-x86_64.exe](https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases/permalink/latest/downloads/orchestrator-windows-x86_64.exe) and run it. (Unsigned, so SmartScreen may ask: *More info*, then *Run anyway*.) |
| **macOS, or from source** | `cargo install --locked tokio-prompt-orchestrator --features web-api,tantivy` (add `fastembed` for `--semantic-dedup`) |
Every method installs the same `orchestrator` command. Every release, with SHA-256 checksums: [Releases](https://gitlab.com/mattbusel/tokio-prompt-orchestrator/-/releases).
## Drop-in OpenAI proxy
Any app that already uses an OpenAI client gets deduplication, the circuit breaker, timeouts, a spend cap and the dead-letter queue with no code change: start `orchestrator` and point the client's base URL at it.
```sh
export OPENAI_BASE_URL=http://127.0.0.1:8080/v1
```
With `orchestrator --provider echo` running (echo mode answers with your prompt, no key needed), the official Python client (`pip install openai`), unchanged:
```python
from openai import OpenAI
client = OpenAI() # reads OPENAI_BASE_URL and OPENAI_API_KEY
reply = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Summarize this ticket"}],
)
print(reply.choices[0].message.content, reply.usage.total_tokens)
for chunk in client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Now stream it"}],
stream=True,
):
if chunk.choices:
print(chunk.choices[0].delta.content or "", end="")
print()
```
```text
Summarize this ticket 10
Now stream it
```
The same question again from `curl` is answered from the dedup window, without a model call:
```bash
curl -s -i localhost:8080/v1/chat/completions -H 'Content-Type: application/json' \
-d '{"model": "gpt-4o-mini", "messages": [{"role": "user", "content": "Summarize this ticket"}]}'
```
```text
x-orchestrator-dedup: cached
{"choices":[{"finish_reason":"stop","index":0,"logprobs":null,"message":{"content":"Summarize this ticket","refusal":null,"role":"assistant"}}],"created":1790804186,"id":"chatcmpl-4d5284a811bd4c0f90bee01018103e1a","model":"echo","object":"chat.completion","system_fingerprint":null,"usage":{"completion_tokens":5,"prompt_tokens":5,"total_tokens":10}}
```
The orchestrator answers with the provider and model it was started with (`--provider openai --model gpt-4o-mini`, say), whatever `model` the request names. Errors come back in OpenAI's format: 503 while the breaker is open (with `x-should-retry: false`, so the SDK does not retry it), 429 at the spend cap. Details, auth and limits: [docs/REFERENCE.md](docs/REFERENCE.md#openai-compatible-api).
For OpenAI models the token counts in `usage` (and so the spend cap) come from the model's own tokenizer, so they match your OpenAI bill. Other models get an estimate of about 4 characters per token, which is what you see from `echo` above.
## Drop-in Anthropic proxy
The same for Anthropic clients: point the base URL at the orchestrator and `POST /v1/messages` gets the same deduplication, circuit breaker and spend cap. The official Python SDK, unchanged, against `orchestrator --provider echo`:
```python
import anthropic
client = anthropic.Anthropic(base_url="http://127.0.0.1:8080", api_key="local")
msg = client.messages.create(
model="claude-sonnet-4-6",
max_tokens=200,
messages=[{"role": "user", "content": "Summarize this ticket"}],
)
print(msg.content[0].text, msg.stop_reason)
with client.messages.stream(model="claude-sonnet-4-6", max_tokens=200,
messages=[{"role": "user", "content": "Now stream it"}]) as s:
print("".join(s.text_stream))
```
```text
Summarize this ticket end_turn
Now stream it
```
Text conversations, system prompts and streaming are supported; image and tool blocks are rejected with a clear `invalid_request_error`. The key goes in `x-api-key` (as the Anthropic SDKs send it) or `Authorization: Bearer`.
## Server flags
The flags that change how `orchestrator` treats your provider (`orchestrator --help` lists them all):
| Flag | Default | What it does |
|---|---|---|
| `--concurrency
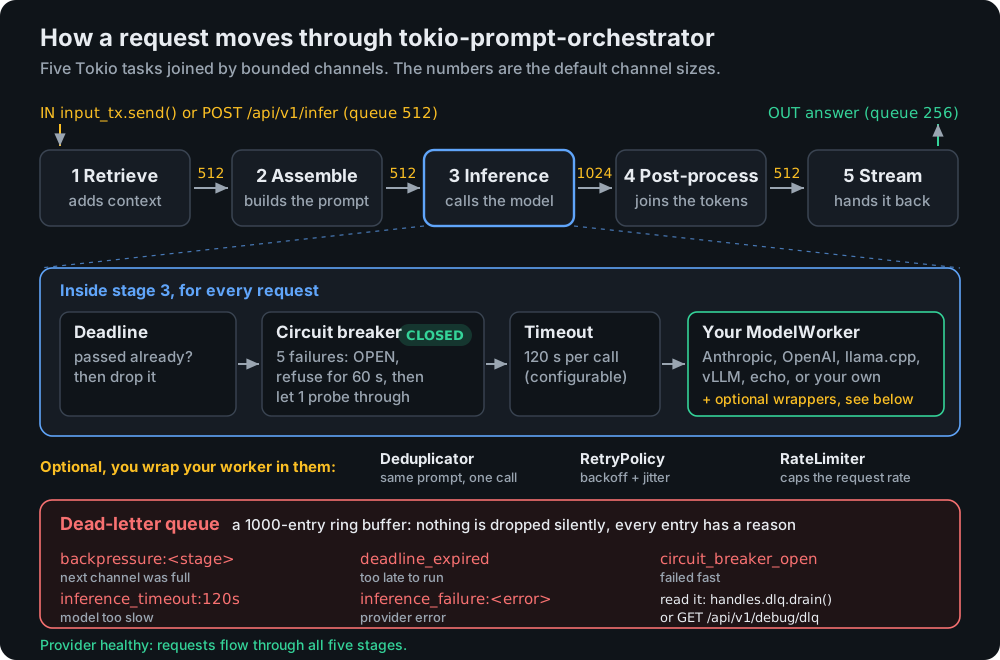 Each stage is its own Tokio task. A full channel never grows memory: the request is shed to the dead-letter queue with the reason, and the HTTP API answers `429` with `Retry-After`. Everything in the drawing is read from [`src/stages.rs`](src/stages.rs); more in [docs/ARCHITECTURE.md](docs/ARCHITECTURE.md).
**Retries for brief hiccups.** Providers sometimes fail for a second: a 429, a 503, a dropped connection. Start with `orchestrator --retries 2` (or set `retry_attempts` in a pipeline config) and such a call is tried again after a short, randomised wait that doubles each time, before it counts as a failure. A provider's `Retry-After` is respected, a bad API key is never retried, and all the tries of one request count once for the circuit breaker. It is off by default, so the breaker demo above behaves exactly as shown.
**Built on proven crates.** The parts that are easy to get subtly wrong come from widely used open-source libraries rather than code written here: [backon](https://crates.io/crates/backon) for retry timing, [moka](https://crates.io/crates/moka) for the dedup cache (it has a size limit, so a flood of different prompts cannot grow memory without bound), [tiktoken-rs](https://crates.io/crates/tiktoken-rs) for OpenAI token counts, and [prometheus](https://crates.io/crates/prometheus) for `/metrics`.
## Examples
**1. Twelve requests, three model calls, then an outage.** `cargo run --example llm_pipeline` (no key needed), real output from today, trimmed:
```text
1) 12 requests: 4 users x 3 questions
req-01 alice The capital of France is Paris.
req-02 alice Backpressure means a slow consumer makes fast producers wait instead of letting queues grow without bound.
...
req-12 dave Bounded channels fill / the sender waits its turn now / memory stays calm
-> 12 answers in 0.9s, 3 model calls (9 saved by dedup)
2) Provider outage: 8 new requests while every call fails
DLQ req-13 inference_failure:inference failed: 503 Service Unavailable (simulated outage)
...
DLQ req-17 inference_failure:inference failed: 503 Service Unavailable (simulated outage)
DLQ req-18 circuit open, failed fast (provider not called)
DLQ req-19 circuit open, failed fast (provider not called)
DLQ req-20 circuit open, failed fast (provider not called)
-> breaker is Open; it lets one probe through after 60s to test recovery
```
