Maxwell-V1.0-Flash

Homepage Chat
Hugging Face License

📄 Technical Report  |   💬 GitHub

## 1. Introduction We present **Maxwell-V1.0-Flash**, a high-performance Mixture-of-Experts (MoE) language model with **35B total parameters and 3B active parameters per token**, supporting a context window of up to **256K tokens**. Maxwell combines learned block-sparse attention, fine-grained expert routing, and manifold-constrained hyper-connections for efficient long-context inference. It is pre-trained on approximately 26T multilingual tokens with the Muon optimizer and multi-token prediction, followed by two-stage supervised fine-tuning, specialized reinforcement learning, and multi-teacher on-policy distillation. Together, these choices deliver strong reasoning, agentic search, and broad general capabilities.
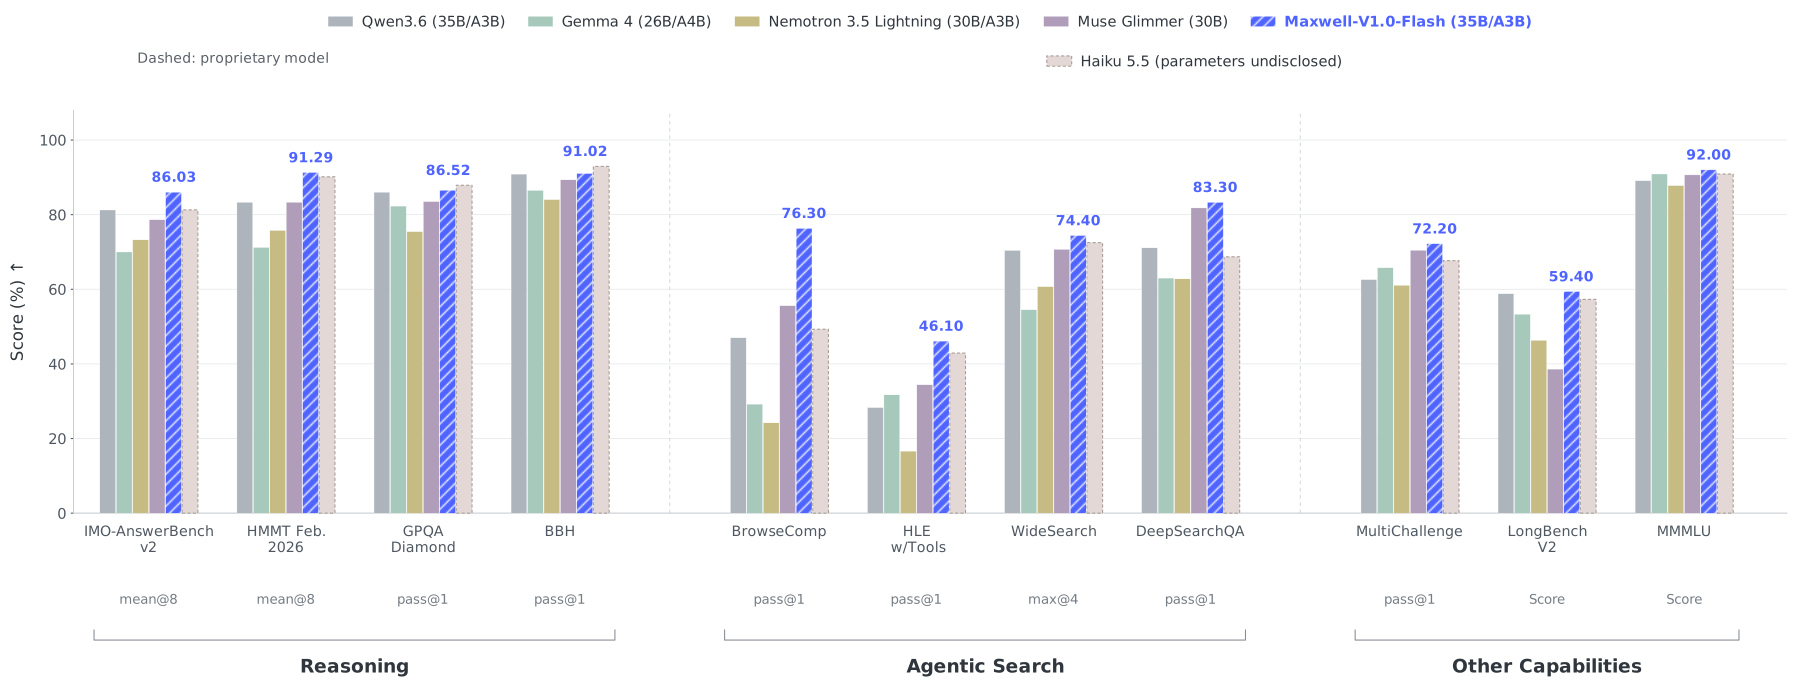
Selected Maxwell-V1.0-Flash benchmark results across reasoning, agentic search, and other capabilities
## 2. Model Summary Maxwell-V1.0-Flash uses a 45-layer decoder-only Transformer backbone. Its feed-forward stack begins with 3 dense layers followed by 42 MoE layers, while block-sparse attention and manifold-constrained hyper-connections support selective context access and information flow across residual streams.
Overall architecture of Maxwell-V1.0-Flash
#### Maxwell Block Sparse Attention Maxwell Block Sparse Attention (MBSA) combines fixed prefix and local coverage with learned remote block selection. Each KV group attends to up to 32 blocks, capping support at 4,096 tokens while retaining full-history KV. MBSA delivers a 6.7x kernel speedup over dense GQA at 256K under matched shapes. #### Manifold-Constrained Hyper-Connections Four residual streams use learned input-dependent aggregation and constrained mixing with 20 Sinkhorn-Knopp iterations. This expands information flow across the network without adding extra attention or feed-forward evaluations. #### Fine-Grained Mixture of Experts The first 3 decoder layers use dense feed-forward networks, followed by 42 MoE layers. Each MoE layer contains 256 routed experts, activates 12 per token, and includes 2 always-active shared experts, with a dynamic selection bias for auxiliary-loss-free load balancing. #### Pre-training and Long Context Maxwell-V1.0-Flash is pre-trained on approximately 26T multilingual tokens using the Muon optimizer and an auxiliary multi-token prediction objective. Context length is progressively extended from 4K to 256K, with block-sparse attention introduced during mid-training after indexer warm-up. #### Post-training Two-stage supervised fine-tuning establishes general, reasoning, and agentic capabilities. Independent reinforcement-learning branches then specialize these capabilities, and multi-teacher on-policy distillation consolidates them into a single model. ## 3. Model Links | Model Name | Description | Hugging Face | |:---|:------------------------------------------|:---:| | Maxwell-V1-Flash | 35B-total / 3B-active MoE model | [🤗 Hugging Face](https://huggingface.co/maxwell-model/Maxwell-V1-Flash) | The model repository above contains the official Maxwell-V1.0-Flash release used by the examples in this repository. ## 4. Evaluation Results **Base model.** Maxwell-V1.0-Flash (Base) is compared with two Qwen base models of comparable scale under a unified internal evaluation framework. All scores are percentages; the best score in each row is shown in bold. GSM8K is evaluated using pass@8. | Category | Benchmark | Qwen3.0-w30a3-base | Qwen3.5-w35a3-base | Maxwell-V1.0-Flash (Base) | |:---|:---|:---:|:---:|:---:| | Math | GSM8K (pass@8) | 97.95 | **98.41** | 97.19 | | | MATH-500 | 59.00 | 57.50 | **71.40** | | | MinervaMath (MATH) | 62.14 | 58.62 | **74.56** | | | MathQA | 60.40 | 63.69 | **66.10** | | Code | HumanEval | 70.73 | 67.68 | **78.05** | | | MBPP | **73.93** | 61.09 | 65.37 | | | HumanEval+ | 63.41 | 56.10 | **71.95** | | | MBPP+ | **75.40** | 70.90 | 75.13 | | STEM | MMLU | 80.98 | **82.85** | 79.85 | | | MMLU-Redux | **78.17** | **78.17** | 74.90 | | | MMLU-Pro | 61.64 | 64.68 | **65.25** | | | ARC-Easy | 80.01 | 82.15 | **86.78** | | | ARC-Challenge | 57.59 | 62.12 | **65.78** | | | BBH | 28.08 | 52.17 | **57.01** | | | GPQA-main | 40.62 | **54.69** | 52.68 | | | GPQA-diamond | 42.42 | **54.04** | 51.52 | | Multilingual | MMLU (SEA) | 73.89 | **77.37** | 75.06 | | | XCOPA (SEA) | 79.63 | 78.93 | **79.80** | | | OpenBookQA (SEA) | 43.20 | 41.30 | **43.30** | | | ARC-Challenge (SEA) | 51.83 | 54.67 | **58.13** | | | MGSM | **85.20** | 84.13 | 83.87 | | Knowledge | HellaSwag | 81.38 | **83.64** | 79.84 | | | PIQA | 81.12 | **82.54** | **82.54** | | | WinoGrande | **77.74** | 74.11 | 72.30 | | | TriviaQA | 66.66 | 71.01 | **75.02** | | | RACE | **86.89** | 81.15 | 84.88 | | | OpenBookQA | **90.00** | 88.60 | 89.60 | | Chinese | CMMLU | **87.41** | 86.17 | 79.41 | | | C-Eval | **88.78** | 86.33 | 77.41 | **Base model, long context.** Scores are on a 0–100 scale. All results use block-sparse attention in every layer. | Benchmark | Context length | Qwen3.5-w35a3-base | Maxwell-V1.0-Flash (Base) | |:---|:---:|:---:|:---:| | RULER | 8K | 91.98 | **94.80** | | | 16K | 91.44 | **94.72** | | | 32K | 90.91 | **94.63** | | | 64K | 89.65 | **93.77** | | | 128K | 88.39 | **94.57** | | | 256K | 85.75 | **93.35** | | HELMET | 8K | 56.62 | **62.61** | | | 16K | 54.93 | **61.43** | | | 32K | 56.87 | **60.28** | | | 64K | 54.61 | **58.74** | | | 128K | 52.35 | **56.55** | **Post-trained model.** Maxwell-V1.0-Flash is compared with four models of comparable scale: Qwen3.6-35B-A3B, Gemma-4-26B-A4B-it, Nemotron-3.5-Lightning, and Muse-Glimmer-30B. All scores are percentages; the highest score for each metric is shown in bold. Multilingual results cover only market languages. Model names wrap across lines to keep the complete comparison compact.
Benchmark (Metric) Qwen3.6
35B-A3B
Gemma-4
26B-A4B-it
Nemotron-3.5
Lightning
Muse
Glimmer-30B
Maxwell
V1.0-Flash
General
Instruction following
AdvancedIF (Score) 72.50 76.10 65.60 73.80 71.30
IFBench (Score) 59.60 79.10 70.80 83.20 64.80
IFEval (Score) 93.80 94.00 91.50 96.80 93.00
Instruction-following average (Average) 75.30 83.07 75.97 84.60 76.37
Multi-turn
MultiChallenge (pass@1) 62.59 65.76 61.07 70.45 72.20
MT-Bench-101 (Score) 94.20 93.90 94.50 88.20 93.30
MT-RAG (Average) 65.03 70.54 67.00 72.70 65.74
LongMemEval (Score) 79.52 85.89 83.44 94.48 86.18
Multi-turn average (Average) 75.34 79.02 76.50 81.46 79.36
Long context
AA-LCR (mean@5) 71.70 65.70 60.30 79.60 75.60
LongBench V2 (Score) 58.80 53.30 46.30 38.60 59.40
RULER (Score) 97.08 94.74 96.75 94.84 95.81
Long-context average (Average) 75.86 71.25 67.78 71.01 76.94
Multilingual
MLogiQA (Score) 77.8 77.8 71.3 80.0 81.5
CEval (Score) 88.3 83.7 76.2 85.4 91.0
MMMLU (Score) 89.1 90.9 87.8 90.7 92.0
INCLUDE (Score) 84.7 85.8 71.5 79.4 84.7
Belebele (Score) 93.8 94.8 91.8 94.3 92.8
Global-PIQA (Score) 91.7 93.9 90.9 92.4 92.3
MGSM (Score) 90.3 91.1 91.5 93.2 93.0
Multilingual average (Average) 88.0 88.3 83.0 87.9 89.6
Role playing
CoSER (pass@1) 47.79 56.19 43.78 60.32 53.54
RoleBench (pass@1) 89.21 84.05 81.10 73.40 89.92
Role-playing average (Average) 68.50 70.12 62.44 66.86 71.73
Reasoning
Mathematics
AIME 2025 (pass@8) 93.33 93.33 96.67 100.00 100.00
AIME 2025 (mean@8) 90.00 85.83 87.92 92.08 96.25
AIME 2026 (pass@8) 96.67 96.67 96.67 96.67 96.67
AIME 2026 (mean@8) 91.25 87.50 87.08 94.17 95.00
HMMT February 2025 (pass@8) 100.00 100.00 96.67 96.67 100.00
HMMT February 2025 (mean@8) 89.58 82.50 85.83 91.25 96.25
HMMT November 2025 (pass@8) 93.33 96.67 93.33 93.33 100.00
HMMT November 2025 (mean@8) 88.75 80.83 86.67 87.92 90.83
HMMT February 2026 (pass@8) 93.94 87.88 90.91 93.94 100.00
HMMT February 2026 (mean@8) 83.33 71.21 75.76 83.33 91.29
IMO-AnswerBench (pass@8) 92.25 88.50 88.00 91.75 95.50
IMO-AnswerBench (mean@8) 81.25 70.00 73.25 78.62 86.03
Mathematical average (pass@8) 94.92 93.84 93.71 95.39 98.70
Mathematical average (mean@8) 87.36 79.65 82.75 87.90 92.61
Science
GPQA-Diamond (pass@1) 86.00 82.30 75.44 83.50 86.52
MMLU-Pro (Accuracy) 85.20 82.60 81.94 83.16 85.46
MMLU-Redux (Accuracy) 93.30 93.10 91.91 90.72 93.59
Scientific average (Average) 88.17 86.00 83.10 85.79 88.52
HLE (128K context) (Score) 21.40 20.60 11.40 21.83 24.79
Logic
BBH (pass@1) 90.87 86.50 84.03 89.33 91.02
BBEH (pass@1) 48.05 55.18 25.86 64.69 52.51
KOR-Bench (pass@1) 74.48 77.36 72.32 80.08 77.20
Logical macro average (Macro average) 71.13 73.01 60.74 78.03 73.58
Code
LiveCodeBench v6 (pass@1) 85.32 85.96 78.30 76.80 85.66
LiveCodeBench v6 (pass@8) 92.32 92.89 87.90 85.70 93.74
Agent
Terminal
Terminal-Bench (mean@5) 47.42 38.43 23.10 48.50 58.65
SWE
SWE-Bench-Verified (Claude Code) (pass@1) 63.40 39.20 42.60 47.60 65.40
Tool use
MCP-Mark (mean@8) 36.70 14.50 14.47 27.56 37.30
Tau3-Bench (pass@1) 64.00 58.60 58.63 63.20 67.37
Search
BrowseComp (pass@1) 47.00 29.20 24.20 55.60 76.30 / 82.20*
HLE w/Tools (pass@1) 28.30 31.70 16.60 34.40 46.10 / 55.10*
WideSearch (max@4) 70.40 54.50 60.70 70.70 74.40 / 75.80*
DeepSearchQA (pass@1) 71.10 63.00 62.80 81.80 83.30 / 89.50*
Bamboogle (mean@8) 90.90 91.30 90.60 86.00 92.10
WebWalkerQA-300 (mean@8) 62.80 54.50 55.40 56.00 70.50
2WikiMultihopQA-300 (mean@8) 87.75 89.20 86.20 89.40 89.80
MuSiQue-300 (mean@8) 49.25 49.30 42.40 46.00 63.00
HotpotQA-300 (mean@8) 80.80 79.50 73.20 80.50 84.70
PopQA-300 (mean@8) 68.29 64.70 58.90 68.80 70.10
\* Maxwell with context management enabled. Post-training evaluations mostly use temperature 0.6, top-p 0.95, top-k 20, and a 32K-token context. AA-LCR, mathematical benchmarks, and HLE use 128K; scientific benchmarks use 80K; LiveCodeBench v6 uses 64K; multilingual evaluation uses a maximum generation length of 16K tokens. SWE-Bench Verified is evaluated with the Claude Code harness (version 2.1.212) in a network-isolated environment, with a 256K-token context window, at most 240 interaction turns, and a four-hour wall-clock limit per task. Terminal-Bench 2.1 is evaluated in the Harbor framework with the Terminus-2 harness, using a two-hour timeout per task, a 256K-token context window, 32K max tokens, temperature 1.0, top-p 0.95, top-k 20, and interleaved thinking. The scientific average excludes HLE. ## 5. Deployment Requires NVIDIA driver >= 580 (CUDA 13.0). On older drivers, add `-e VLLM_ENABLE_CUDA_COMPATIBILITY=1` to `docker run`. ### Download the Model Download the weights to a local directory first with the Hugging Face CLI (install it with `pip install -U huggingface_hub` if `hf` is not available): ```bash export MODEL_DIR=$PWD/Maxwell-V1-Flash hf download maxwell-model/Maxwell-V1-Flash --local-dir "$MODEL_DIR" ``` ### Serve on B300 A single GPU is enough: ```bash docker run --rm --init \ --name vllm-maxwell \ --gpus all \ --shm-size 8g \ --network host \ -v "$MODEL_DIR":/models/Maxwell-V1-Flash:ro \ --entrypoint vllm \ maxwellmodel/vllm-openai:v0.30.0 \ serve /models/Maxwell-V1-Flash \ --trust-remote-code \ --block-size 128 \ --served-model-name Maxwell-V1.0-Flash \ --port 8000 \ --tensor-parallel-size 1 \ --reasoning-parser qwen3 \ --enable-auto-tool-choice \ --tool-call-parser qwen3_coder ``` ### Serve on H100 Requires at least two GPUs. Use the same command with `--tensor-parallel-size 2`. > [!TIP] > You can also try Maxwell-V1.0-Flash at > [https://maxwell-llm.ai/playground](https://maxwell-llm.ai/playground). ## 6. Model Usage Maxwell-V1.0-Flash uses the bundled chat template for system, user, assistant, and tool messages, with thinking enabled by default. For multi-turn conversations and tool calls, pass the complete assistant message back into `messages`, including `reasoning_content` and `tool_calls` when present. OpenAI-compatible tool definitions are accepted through the `tools` field. ```python import openai def chat_completion( client: openai.OpenAI, model_name: str, ) -> str: messages = [ { "role": "user", "content": ( "Why is it harder to keep a room cool when the door is open " "on a hot day? Explain in 3-4 simple sentences." ), }, ] response = client.chat.completions.create( model=model_name, messages=messages, stream=False, max_tokens=4096, temperature=0.6, top_p=0.95, extra_body={ "top_k": 20, "chat_template_kwargs": { "enable_thinking": True, }, }, ) return response.choices[0].message.content ``` For full guides and examples, see the Maxwell-V1.0-Flash Quickstart. ## 7. License Maxwell-V1.0-Flash is released under the **Apache License 2.0**. See [LICENSE](./LICENSE) for details. ## 8. Contact Us If you have any questions or suggestions, feel free to reach out to our R&D and product teams via email: contact@maxwell-llm.ai ---
Maxwell-V1.0-Flash is developed by the Maxwell team.