# ForkMind 🧠
### Local-first LLM branching, debugging & context offloading
**Treat your AI conversation history like a Git repository — capture every call, branch from any turn, and diff outcomes side by side. All on your machine.**
[](https://www.npmjs.com/package/forkmind)
[](./LICENSE)
[](https://github.com/medhovarsh/forkmind/actions/workflows/ci.yml)
[](https://nodejs.org)
[](https://registry.modelcontextprotocol.io)
[](https://medhovarsh.github.io/forkmind/)
[**Try in 10s**](#try-it-in-10-seconds) · [Features](#features) · [Install](#install) · [Quick start](#quick-start-free-no-api-key) · [MCP](#mcp--let-agents-query-their-own-history) · [Capsules](#context-capsules--offload-context-as-an-encrypted-dag)
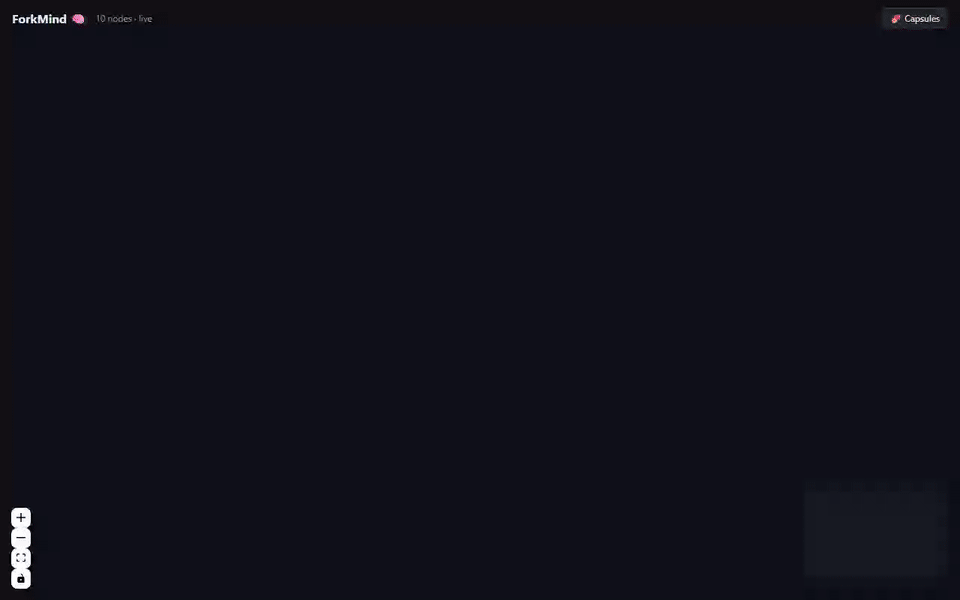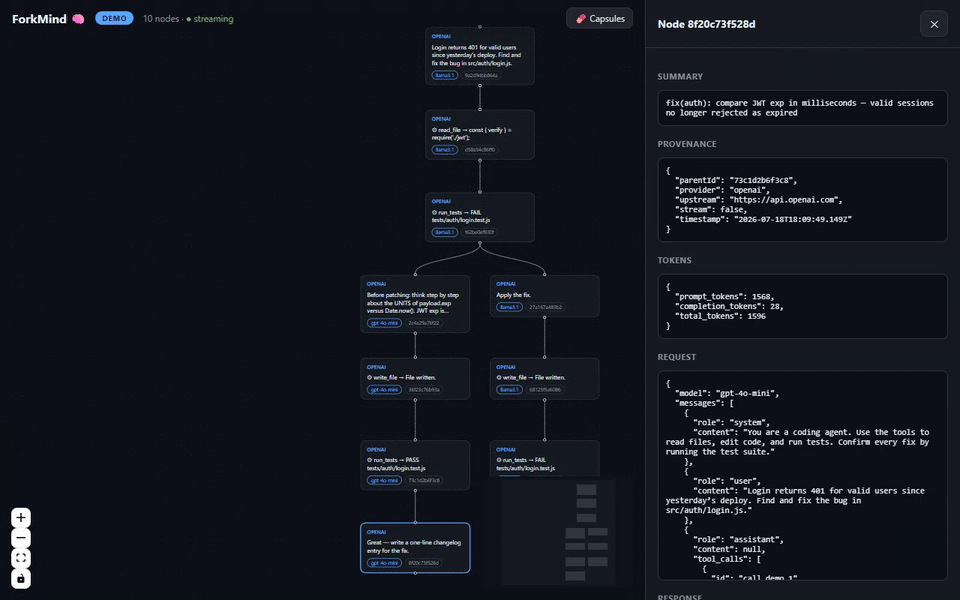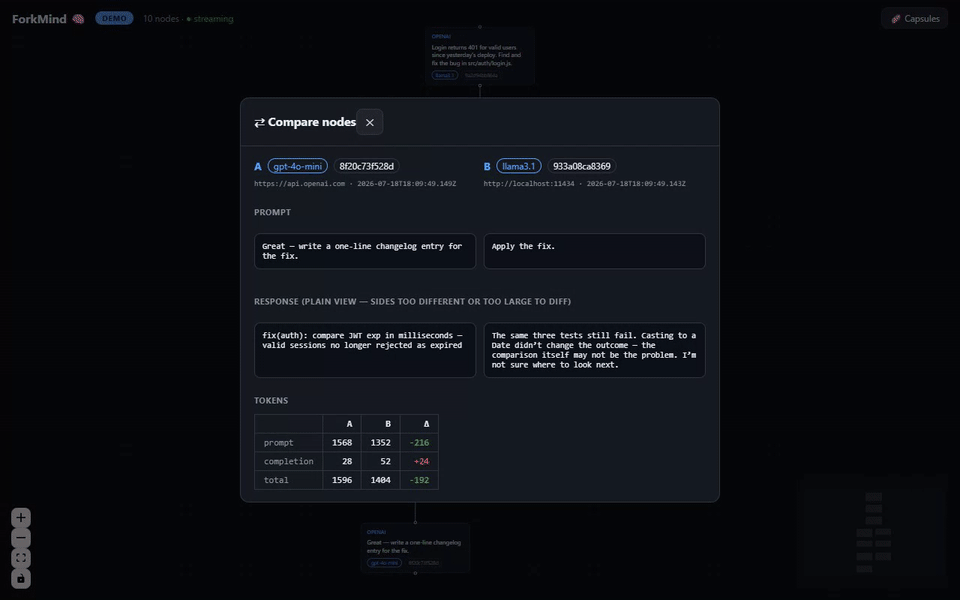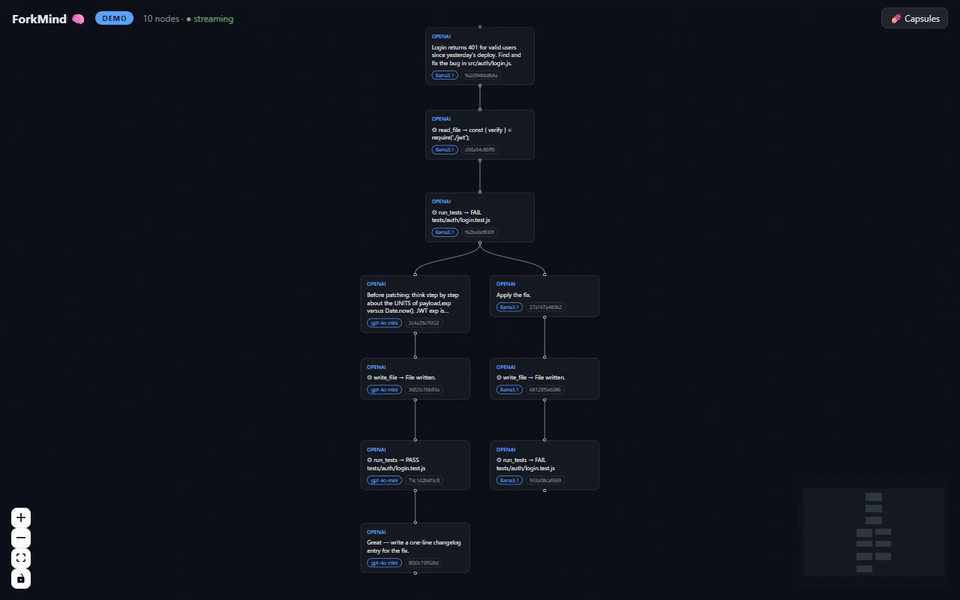
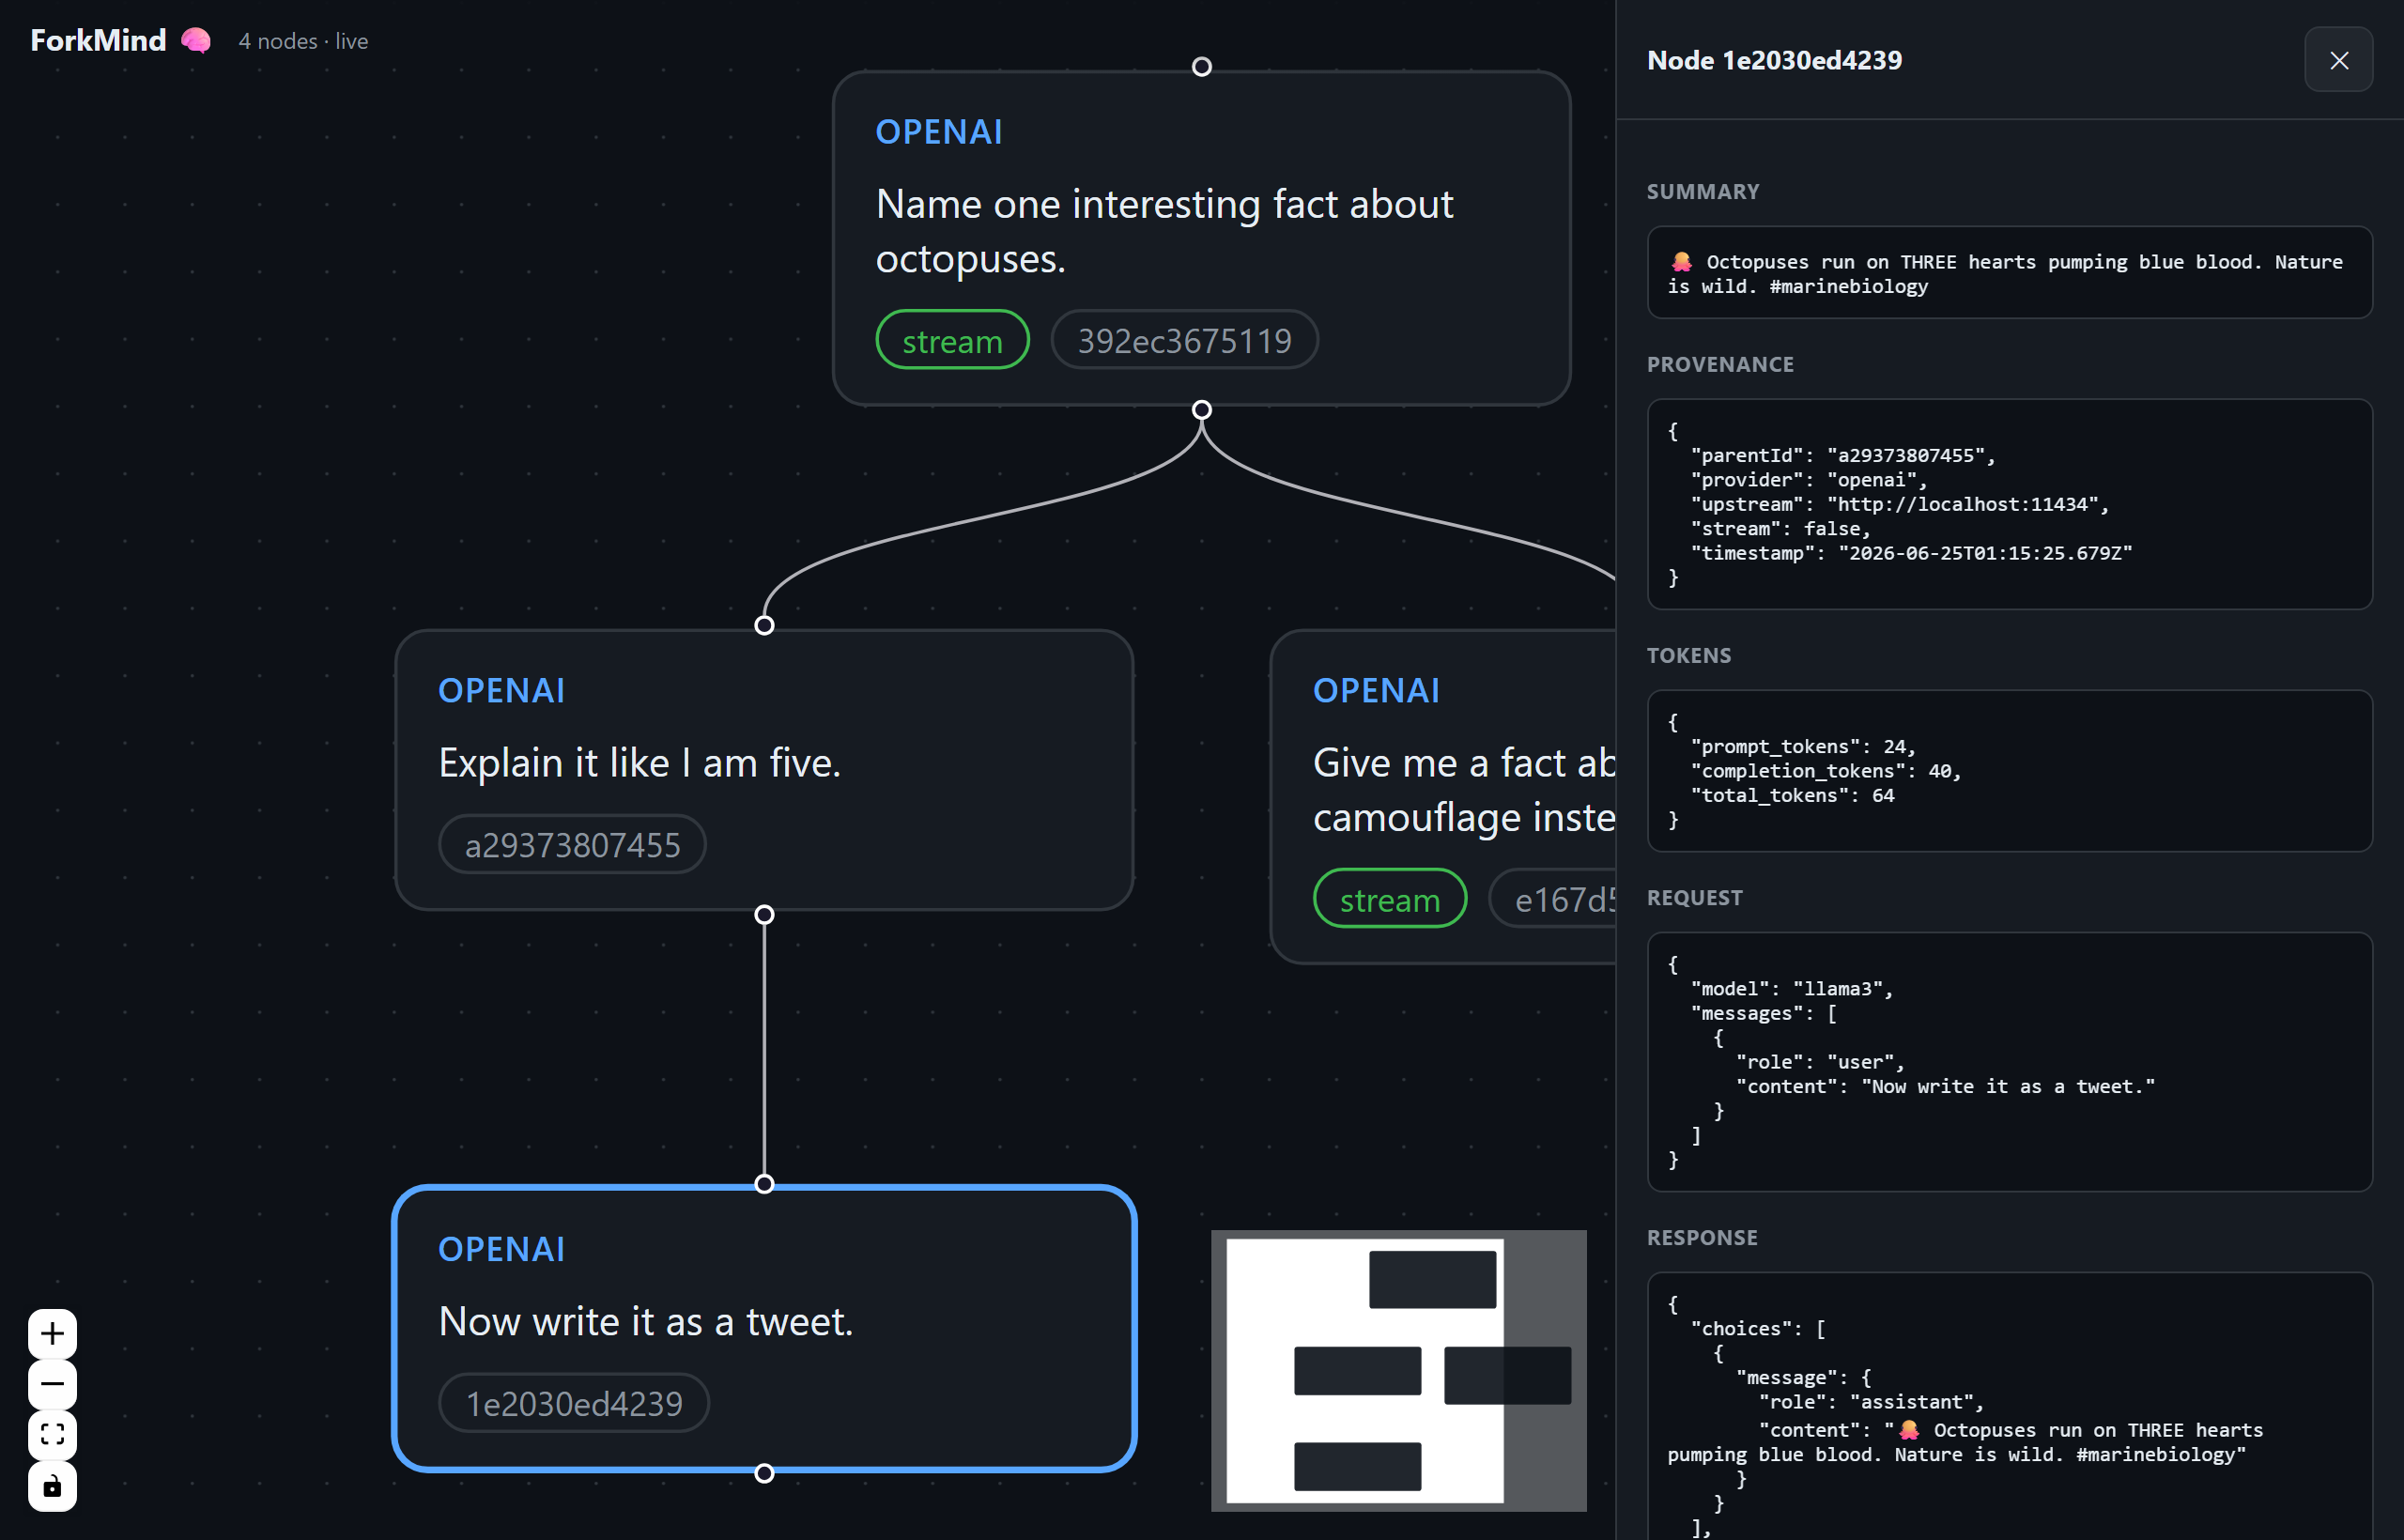
> **What you're seeing:** the conversation DAG with a fork off the debug turn,
> the node inspector (request/response, tokens, provenance), and the **⇄ Compare**
> view diffing two branches with per-token deltas. The green **● streaming**
> badge shows live capture — nodes appear as they're recorded.
ForkMind captures every LLM call into a local `.forkmind/` directory, visualizes
the conversation as a Directed Acyclic Graph (DAG), and lets you **branch**,
**diff**, and **replay** from any point in the history. Works with **any
OpenAI-compatible API**, defaulting to **free, open-source models** via
[Ollama](https://ollama.com) — also Anthropic, Groq, OpenRouter, Together,
vLLM, and LM Studio.
Static screenshot
---
## Why
Debugging agentic / tool-calling flows means re-running the same prompt with
tiny tweaks over and over, then scrolling through terminal logs to see what
changed. ForkMind records each run as a node in a conversation tree, so instead
of re-reading logs you **see** the whole history, **branch** from any turn, and
**compare** outcomes visually.
Everything is plain JSON on disk. No database, no account, no telemetry —
nothing leaves your machine except the LLM call you were already making.
---
## Features
- **Capture** — every LLM call is recorded to a plain JSON node under
`.forkmind/`. Works from any language via an OpenAI-compatible proxy;
streaming responses are reconstructed (text **and** fragmented tool-call args).
- **DAG dashboard** — a React Flow canvas draws the whole conversation as a
tree: every turn, tool call, model, and token count, with the node inspector
one click away.
- **Live capture stream** — nodes pulse into the DAG the instant they're
recorded (Server-Sent Events), so you can watch an agent think in real time.
- **Branch** — fork any historical turn: edit the prompt or swap the model and
re-run, linked to the original as a visible branch.
- **⇄ Compare** — pick any two nodes for a side-by-side, word-level diff of
prompts and responses, plus a token-usage table with per-field deltas. "Git
diff for LLM outputs."
- **⏪ Time-travel replay** — re-run a whole chain from an edited node; the
regenerated turns land as a sibling branch while your original user turns and
tool results re-apply in order.
- **MCP server** — agents query their own `.forkmind/` history mid-task (recall
what they tried, trace how they got somewhere, self-correct).
- **Regression testing** — pin a known-good output as a baseline, re-run it
after prompt/model changes, and catch drift with free offline checks
(contains / regex / similarity), tool-call assertions, or an opt-in LLM judge
graded against your own rubric. CI-ready.
- **Trajectory regression** — pin a whole multi-turn agent *path* from the
captured graph and replay it, so a prompt change that reroutes an agent
mid-run gets caught even when the final answer still reads fine.
- **Context capsules** — offload context into encrypted, immutable DAG capsules;
restore in full or per segment; replicate (RAID), export/import, crypto-shred.
- **`forkmind demo`** — one command opens the dashboard on a pre-seeded sample
DAG, zero setup and zero API key.
---
## Try it in 10 seconds
```bash
npx forkmind demo
```
No API key, no setup: the dashboard opens with a pre-seeded conversation DAG —
a coding-agent debug session that forks into a failed fix and a winning fix,
plus an archived context capsule. Everything lives in a throwaway temp
directory; your project is never touched. If a local
[Ollama](https://ollama.com) is running, **Fork from here** works live against
your local model.
Once you're in, try:
- **⇄ Compare** any two nodes for a side-by-side, word-level diff of prompts,
responses, and token usage — "git diff for LLM outputs".
- **⏪ Replay from here** to re-run a whole chain from an edited node; the
regenerated turns land as a sibling branch.
- **Live capture** — nodes pulse into the DAG the instant they're recorded, so
you can watch an agent think in real time.
## Install
```bash
# Run without installing (published on npm)
npx forkmind init
npx forkmind start
# …or install the CLI globally
npm install -g forkmind
forkmind start
```
No npm registry needed either — ForkMind runs straight from the git link, and
the dashboard builds automatically on install:
```bash
# Run without installing, from GitHub
npx github:medhovarsh/forkmind init
npx github:medhovarsh/forkmind start
# …or clone to hack on it
git clone https://github.com/medhovarsh/forkmind
cd forkmind && npm install
```
### Install as a Claude Code plugin
ForkMind ships a Claude Code plugin (skill + `/forkmind` command) so Claude knows
when and how to drive it — same install flow as any marketplace plugin:
```text
/plugin marketplace add Medhovarsh/forkmind
/plugin install forkmind
```
The plugin bundles:
- **`forkmind` skill** — Claude reaches for ForkMind whenever you ask it to debug
a prompt, compare models, branch from a past turn, or regression-test a call.
- **`/forkmind` command** — start / branch / test / mcp on demand.
- **`forkmind-debugger` agent** — runs model/prompt comparisons in an isolated
context and returns a compact verdict instead of dumping transcripts.
- **MCP server, auto-wired** — agents query their own `.forkmind/` history
(recall attempts, trace lineage, self-correct) with zero manual config.
The CLI is still what runs the proxy + dashboard; the plugin is the glue that
teaches Claude to use it.
## Quick start (free, no API key)
```bash
# 1. Install a free local model
# (install Ollama from https://ollama.com first)
ollama pull llama3
# 2. Init + start ForkMind
npx github:medhovarsh/forkmind init # create .forkmind/ in your project
npx github:medhovarsh/forkmind start # proxy on http://localhost:4500 + dashboard
# 3. Point your code at the proxy (see SDK below), make some calls
# 4. Open the dashboard
open http://localhost:4500
```
### Drop-in SDK (auto-builds the tree)
```bash
npm i openai # the wrapper extends the official SDK
```
```js
const { ForkMindOpenAI } = require('forkmind');
const client = new ForkMindOpenAI({
apiKey: 'ollama', // ignored by Ollama; required by SDK
upstream: 'http://localhost:11434', // free local open-source models
});
// Each call is recorded; sequential calls auto-chain into a conversation tree.
const res = await client.chat.completions.create({
model: 'llama3',
messages: [{ role: 'user', content: 'Explain backpropagation simply.' }],
});
```
Run the full example:
```bash
node examples/chain.js
```
### Any language — point your client at the proxy
The SDK wrapper is convenience, not a requirement. ForkMind's proxy speaks the
**OpenAI-compatible wire protocol**, so capture works from *any* language: set
your client's base URL to `http://localhost:4500/v1` and you're recorded. Chain
turns into a tree by passing back the `x-forkmind-node-id` from the previous
response as the next request's `x-forkmind-parent` header (the JS wrapper just
automates this).
```python
# Python — official openai client, zero ForkMind code
from openai import OpenAI
client = OpenAI(base_url="http://localhost:4500/v1", api_key="ollama")
res = client.chat.completions.create(
model="llama3",
messages=[{"role": "user", "content": "Explain backpropagation simply."}],
extra_headers={"x-forkmind-upstream": "http://localhost:11434"},
)
# read res via .with_raw_response to grab x-forkmind-node-id and chain the next call
```
```bash
# curl — anything that can POST JSON
curl http://localhost:4500/v1/chat/completions \
-H 'content-type: application/json' \
-H 'x-forkmind-upstream: http://localhost:11434' \
-d '{"model":"llama3","messages":[{"role":"user","content":"hi"}]}' -i
# response header `x-forkmind-node-id: ` → pass as `x-forkmind-parent` next call
```
Go, Ruby, Rust, Java — same deal: base URL + the two headers. The dashboard,
branching, MCP, and regression testing all work regardless of source language.
---
## Framework integrations
ForkMind ships thin adapters for the two biggest JS LLM ecosystems. Both route
through the same proxy, so capture, branching, the dashboard, MCP, and
regression all work unchanged — no model-class swap, no callbacks.
### LangChain.js
```bash
npm i @langchain/openai @langchain/core
```
```js
const { ChatOpenAI } = require('@langchain/openai');
const { forkmind } = require('forkmind/langchain');
const fm = forkmind({ upstream: 'http://localhost:11434' }); // free local Ollama
const model = new ChatOpenAI({
apiKey: 'ollama',
model: 'llama3',
configuration: fm.configuration, // baseURL → proxy + chaining fetch
});
await model.invoke('Explain backpropagation simply.');
// sequential calls on `fm` auto-chain; fm.setParent(id) to branch from a node.
```
### Vercel AI SDK
```bash
npm i ai @ai-sdk/openai
```
```js
const { generateText } = require('ai');
const { forkmindOpenAI } = require('forkmind/vercel');
const openai = forkmindOpenAI({ upstream: 'http://localhost:11434' });
const { text } = await generateText({
model: openai('llama3'),
prompt: 'Explain backpropagation simply.',
});
// openai.setParent(id) / openai.resetParent() control the branch point.
```
Both honor `FORKMIND_PROXY` (proxy base URL) and take an explicit `baseURL` /
`upstream` per instance.
---
## Using other free / open providers
ForkMind is provider-agnostic — it forwards your auth headers verbatim and lets
you set the upstream per client. Anything OpenAI-compatible just works:
| Provider | `upstream` | `apiKey` |
| --------------------- | ----------------------------------- | -------------------- |
| **Ollama** (local) | `http://localhost:11434` | any string |
| **LM Studio** (local) | `http://localhost:1234` | any string |
| **Groq** (free tier) | `https://api.groq.com/openai` | `gsk_...` |
| **OpenRouter** | `https://openrouter.ai/api` | `sk-or-...` |
| **Together** | `https://api.together.xyz` | your key |
| **OpenAI** | `https://api.openai.com` (default) | `sk-...` |
```js
new ForkMindOpenAI({ apiKey: process.env.GROQ_API_KEY,
upstream: 'https://api.groq.com/openai' });
```
You can also override per request with the `x-forkmind-upstream` header if you
call the proxy directly instead of via the SDK.
### Anthropic (Claude)
```bash
npm i @anthropic-ai/sdk
```
```js
const { ForkMindAnthropic } = require('forkmind');
const client = new ForkMindAnthropic({ apiKey: process.env.ANTHROPIC_API_KEY });
await client.messages.create({ model: 'claude-3-5-sonnet-latest', max_tokens: 512,
messages: [{ role: 'user', content: 'hi' }] });
```
---
## How it works
```
your app ──▶ ForkMindOpenAI (baseURL = localhost:4500/v1)
│ injects x-forkmind-parent
▼
ForkMind proxy (Express, :4500)
│ forwards verbatim (your key, your upstream)
▼
provider (Ollama / Groq / OpenAI / ...)
│ response
▼
proxy reconstructs + saveNode() ──▶ .forkmind/nodes/.json
│ returns x-forkmind-node-id
▼
wrapper chains it as the next call's parent
```
- **Deterministic node IDs.** `sha256(request + parentId)` → first 12 hex chars.
Same prompt under the same parent collapses to one node. The ID doesn't depend
on the response, so it can be returned as a header even before a streamed body
finishes.
- **Streaming.** Bytes pass through to your app untouched (real SSE); the proxy
tees them, reconstructs the full message (text **and** fragmented tool-call
arguments), and saves the node on stream end.
- **Branching.** Each node records its provider + upstream, so "Fork from here"
in the dashboard replays the edited request to the same host, linked to the
historical parent.
- **Compare.** Any two nodes diff side by side — word-level prompt/response
changes and a token table with signed deltas — computed client-side from the
captured JSON (`dashboard/src/lib/diff.js`).
- **Replay.** `POST /api/replay` walks a captured lineage from an edited node to
a chosen leaf, regenerating each assistant turn against the modified history
while original user turns and tool results re-apply verbatim. The new chain is
saved as a sibling branch.
- **Live stream.** `saveNode` emits on an in-process bus; `GET /api/stream`
relays each new node to the dashboard over SSE, so the canvas updates without
polling.
---
## MCP — let agents query their own history
ForkMind ships an [MCP](https://modelcontextprotocol.io) server so an AI agent
can read its own `.forkmind/` history mid-task and self-correct — recall what it
already tried, see how it reached a state, or search past attempts.
```bash
forkmind mcp # stdio MCP server (or: forkmind-mcp)
```
One-line install via [Smithery](https://smithery.ai) (configured in
[`smithery.yaml`](./smithery.yaml)) — run it from your project root so it sees
your `.forkmind/`:
```bash
npx -y @smithery/cli install forkmind --client claude
```
…or register it manually with any MCP client (Claude Desktop / Claude Code /
Cursor / Cline):
```jsonc
{
"mcpServers": {
"forkmind": {
"command": "npx",
"args": ["-y", "github:medhovarsh/forkmind", "mcp"]
}
}
}
```
Tools exposed:
| Tool | Purpose |
| ------------------- | -------------------------------------------------------- |
| `forkmind_recent` | Newest captured turns (compact) |
| `forkmind_get_node` | Full request + response for one node |
| `forkmind_lineage` | Root→node path — the exact context that produced a state |
| `forkmind_children` | Sibling branches forking from a node |
| `forkmind_search` | Substring search across all requests/responses |
| `forkmind_stats` | Tree totals: nodes, roots, leaves, providers |
| `forkmind_context_save` | Offload context into an encrypted DAG capsule |
| `forkmind_context_list` | List saved capsules (title, digest, size, age) |
| `forkmind_context_digest` | Digest + segment map — cheap pre-restore probe |
| `forkmind_context_restore` | Full or per-segment restore, integrity-verified |
| `forkmind_context_forget` | Irreversible crypto-shred (requires id echo) |
| `forkmind_context_replicas`| Replica (RAID) health, optional sync |
| `forkmind_context_stats` | Aggregate stats: count, bytes, estimated tokens |
| `forkmind_context_export` | Portable passphrase-encrypted bundle |
| `forkmind_context_import` | Import + re-verify a bundle, re-wrap locally |
The server reads the `.forkmind/` in its working directory — point the client's
`cwd` at your project.
## Context capsules — offload context as an encrypted DAG
Most context managers treat a full window as a cache-eviction problem: truncate
and lose it. ForkMind **capsules** invert that — *persist first, verify, then
compact*. A capsule is an immutable, content-addressed DAG of context segments,
AES-256-GCM encrypted on disk, restorable in full or one segment at a time.
```bash
# Save (items JSON from a file or stdin), get back a 12-char handle
echo '{"title":"auth debug","items":[{"role":"user","content":"..."}]}' \
| forkmind context save --digest "oauth loop root-caused; fix in token.js"
forkmind context list # all capsules, newest first
forkmind context show 9f3ac21b7e04 # decrypt + verify + print
forkmind context verify 9f3ac21b7e04 # DAG integrity: parents, acyclicity, hashes
forkmind context forget 9f3ac21b7e04 --confirm 9f3ac21b7e04 # crypto-shred
```
Same engine over HTTP (`POST/GET/DELETE :4500/api/context…`) and via five MCP
tools, so agents can archive their own context mid-task and pull it back later.
The Claude Code plugin ships a **`forkmind-archivist`** skill + subagent that
teaches Claude the offload contract: **save → verify on disk → only then drop
it from the window**.
Guarantees:
- **Immutable & acyclic by construction** — segment ids are hashes over
content + parents (Git-style); a cycle would require a hash to contain itself.
- **No plaintext at rest** — per-capsule keys, wrapped by a master key stored
*outside* `.forkmind/` (`~/.forkmind-keys/`); an accidentally committed
`.forkmind/` leaks only ciphertext and structure.
- **Digests are opt-in** — the agent writes a ≤5-line retrieval summary, or
omits it entirely for private capsules.
- **Forgetting is real** — delete destroys the key first (crypto-shredding),
then tombstones the id so identical content can never resurrect it.
- **The model is never touched** — capsules operate on what the client sends;
provider, weights, and KV cache are out of scope by design.
### RAID — Redundant Array of Independent DAGs
Mirror capsules to any number of extra filesystem targets (second disk, synced
folder, network mount). Replicas hold **ciphertext + manifests only — keys are
never replicated**. If the primary copy is lost or bit-rots, restore self-heals
from the first replica that passes verification; healed copies get no trust
shortcut (full integrity check still runs).
```bash
forkmind context replicas add D:\backup\forkmind # add target + sync
forkmind context replicas list # coverage per target
forkmind context replicas sync # catch up offline targets,
# propagate tombstones
```
Forgetting reaches every copy: reachable replicas are shredded immediately;
a replica that was offline gets its stale ciphertext removed on the next
`sync` (tombstone propagation) — and it was unreadable anyway, since the
capsule key died at forget time. Tombstones also make heal refuse to
resurrect anything forgotten.
### Portable export/import
Move a capsule to another machine or project — a laptop that doesn't share
this project's `~/.forkmind-keys/` master key, a teammate, cold storage:
```bash
forkmind context export 9f3ac21b7e04 --passphrase "correct horse battery staple" --out capsule.json
# ... move capsule.json anywhere ...
forkmind context import capsule.json --passphrase "correct horse battery staple"
```
The bundle carries its own scrypt-derived key material (N=32768, deliberately
slow to resist offline brute force of a weak passphrase) — it never depends
on the source machine's master key, and the passphrase is never written into
the bundle itself. On import, every segment is independently re-verified
(recomputed id, recomputed hash, resolved parents, acyclic DFS) before
anything touches disk — the bundle is never trusted blindly, only proven.
Import is idempotent and honors tombstones, same as a fresh save.
### Archive straight from the capture DAG
The two halves connect: any conversation the proxy captured can be archived
into a capsule in one move — no manual JSON assembly — and restored later as
a provider-ready `messages[]` array, ready to splice into the next request:
```bash
# archive the whole lineage ending at a captured turn
forkmind context save --from-node a1b2c3d4e5f6 --digest "auth debug, resolved"
# restore as chat messages (or GET /api/context/:id/messages)
forkmind context show 9f3ac21b7e04 --messages
```
Same via MCP: `forkmind_context_save { fromNodeId }` and
`forkmind_context_restore { asMessages: true }` — an agent can archive its own
captured history mid-task and splice it back whenever needed. Capsules keep
`sourceNodeIds` links back into the turn DAG.
### Token savings
`forkmind context save` and `forkmind context stats` report an estimated
token count freed from your context window (`~4 bytes/token`, the standard
rough heuristic) — a concrete number for how much a capsule actually saved.
## Regression testing — pin good outputs, catch degradation
Tweaking a system prompt or swapping a model can silently degrade results.
ForkMind lets you pin a known-good captured node as a **baseline**, then re-run
its exact request later and check the new output for drift.
```bash
# 1. Pin a good node (grab its id from the dashboard or forkmind_recent)
forkmind regression pin a1b2c3d4e5f6 \
--name octopus-fact \
--contains "hearts" \
--regex "blue|copper" \
--min-similarity 0.5
# 2. List / remove cases
forkmind regression list
forkmind regression remove octopus-fact
# 3. Re-run after changing prompts/models (exit code 1 if any case fails — CI-ready)
forkmind regression run # keyless local (Ollama)
forkmind regression run --key $GROQ_API_KEY --upstream https://api.groq.com/openai
```
### Mechanical checks — free, offline, deterministic
- **`contains`** — substrings that must appear
- **`not-contains`** — substrings that must NOT appear
- **`regex`** — patterns that must match
- **`min-similarity`** — Jaccard word-overlap vs the baseline (drift guard;
defaults to `0.3` so a wildly different answer fails even without explicit
assertions). LLM output is non-deterministic, so prefer assertions over exact
match.
None of these read meaning. They answer *"does this text still look like that
text"*, not *"is this answer still correct"*. `contains` and `regex` are precise
proxies — if a required fact disappears, they catch it every time. Similarity is
a deliberately cheap alarm: it flags that something changed, and it will cry wolf
on a rewrite that's perfectly correct.
### Tool-call checks — what the agent DID, not what it said
Text checks ask whether the answer still reads right. For an agent, that's the
wrong question. A wrong sentence is annoying; a wrong tool call writes to
somebody's system. These assert on the calls themselves — structured data, so
they're free, offline, and exact:
```bash
forkmind regression pin a1b2c3d4e5f6 \
--name refund-flow \
--tool 'create_ticket:{"priority":"high"}' \ # must call it, with these args
--not-tool issue_refund \ # must never call this
--tools-exact # and must call nothing else
```
- **`--tool name`** / **`--tool 'name:{json}'`** — the call must appear.
Arguments match as a **subset**, so you pin the fields that matter and ignore
the rest.
- **`--not-tool name`** — the destructive-action guard. The check that matters
most when a prompt tweak makes an agent bolder than it should be.
- **`--tools-exact`** — fail on any *extra* call, not just a missing one. With
no `--tool` at all, this asserts the agent acted on nothing.
Works identically on OpenAI `tool_calls` and Anthropic `tool_use` blocks; both
normalize to `{ name, args }`. A model that emits malformed argument JSON is
reported with the raw text under `args._raw` rather than silently dropped, so
the assertion fails loudly instead of the call disappearing.
The failure mode this exists for: **the text can be word-for-word identical
while the action is wrong.** Every text check passes, similarity scores 1.0, and
the agent charged the wrong account. Only the tool check catches it.
### LLM judge — opt-in, costs an API call, reads meaning
For the cases where wording is free to change but the *content* must not, pin a
rubric and let a model grade the replay against it:
```bash
forkmind regression pin a1b2c3d4e5f6 \
--name refund-policy \
--judge "The answer must state the 30-day window and must not promise an exception." \
--judge-threshold 0.8 \
--judge-model gpt-4o # optional: grade with a stronger model than the case uses
forkmind regression run --judge-key $OPENAI_API_KEY
forkmind regression run --no-judge # mechanical checks only — free, offline, no API calls
```
The judge sees the rubric, the approved baseline, and the candidate, and is told
explicitly **not** to penalize rewording — only content that is wrong, missing,
or contradictory. It returns a `0-1` score; the case fails below
`--judge-threshold` (default `0.7`).
Three properties worth knowing before you trust it:
- **It fails closed.** A judge that errors, times out, or returns unparseable
output marks the check **failed**, never skipped. A gate that silently passes
when its grader is broken is worse than no gate.
- **A skip is visible.** `--no-judge` still records the check, flagged as
skipped in the report, so a suite can't quietly stop enforcing its rubric.
- **It is not proof.** The judge is non-deterministic and only as good as the
rubric you wrote. It is a stronger signal than word overlap — not a
correctness guarantee.
Cases are JSON in `.forkmind/regressions/` — commit them to share baselines and
gate prompt changes in CI.
## Trajectory regression — pin the path, not the turn
Everything above tests **one turn**. For an agent that's the wrong unit. Agents
fail in the *middle* of a run — they skip the lookup, they write before they
confirm, a prompt tweak reroutes them entirely — and then produce a final
sentence that reads completely fine. A last-message assertion sees nothing.
Because ForkMind captures real traffic as a parent-linked DAG, a whole path is
already sitting there. Freeze it:
```bash
# Pin the path ending at this node (walks up to the root)
forkmind trajectory pin f4e5d6c7b8a9 \
--name refund-run \
--sequence exact \ # same actions, same order
--not-tool issue_refund \ # never, anywhere in the run
--tool-order verify_identity,charge_card
forkmind trajectory list
forkmind trajectory run # exit 1 on any failure — CI-ready
```
What gets checked across the whole run:
- **`--sequence exact`** — the flattened action sequence must match the baseline
step for step. **`subsequence`** allows extra actions as long as the baseline
ones still appear in order. **`none`** leaves the route free.
- **`--not-tool`** — a forbidden action anywhere in the trajectory.
- **`--tool-order before,after`** — ordering constraints. *Searched before it
wrote. Verified before it charged.*
- **`--judge`** — optional rubric on the **final** answer, same judge as above.
- **`--from `** — start the path at an ancestor instead of the root, so
you can pin just the interesting tail of a long run.
**Text is deliberately unconstrained.** Reworded output passes. Only the route
is pinned — because that's the part that touches other people's systems.
### The limitation, stated plainly
Replaying a path **re-applies the original recorded tool results**. Tools are not
executed live. That's deliberate — it holds the environment fixed so the only
variable is the model's decisions — but it has a hard consequence: the moment the
agent takes a *different* action, the recorded result waiting for it answers a
question it never asked. Everything after that point would be fiction.
So the run **stops at the first divergence** and reports exactly where:
```
✗ FAIL refund-run (2/3 steps)
path: verify_identity → issue_refund
↳ failed divergence: step 2/3: expected [charge_card], got [issue_refund]
— replay stopped (recorded tool results no longer apply)
```
That failure is the whole point of the feature: the final message would have
read fine.
Trajectories are JSON in `.forkmind/trajectories/` — commit them alongside your
single-turn cases.
## Zero cost & local
- **No paid API required** — defaults to free local models via Ollama.
- **No database** — every turn is a plain JSON file under `.forkmind/`.
- **No account, no telemetry** — nothing leaves your machine except the LLM call
you were already making (relayed verbatim to the provider you choose).
## `.forkmind/` layout
```
.forkmind/
├── nodes/
│ ├── a1b2c3d4e5f6.json # one node per turn
│ └── ...
├── contexts/ # encrypted context capsules
│ └── 9f3ac21b7e04/
│ ├── manifest.json # public: DAG shape, hashes, opt-in digest
│ └── seg-.enc # AES-256-GCM ciphertext per segment
├── tombstones.json # forgotten capsule ids (never resurrected)
└── manifest.json # version + root node ids
```
Node schema:
```jsonc
{
"id": "a1b2c3d4e5f6",
"parentId": null, // null = root
"timestamp": "2026-01-01T00:00:00.000Z",
"request": { /* the exact request body */ },
"response": { /* full or stream-reconstructed response */ },
"meta": { "provider": "openai", "upstream": "http://localhost:11434", "stream": true },
"children": ["..."] // child node ids
}
```
---
## CLI
| Command | Does |
| ------------------ | -------------------------------------------------------- |
| `forkmind demo` | Zero-setup showcase: sample DAG + dashboard in a temp dir |
| `forkmind init` | Create `.forkmind/` in the current directory |
| `forkmind start` | Start the proxy (`:4500`) + serve the dashboard if built |
| `forkmind mcp` | Start the stdio MCP server for agents |
| `forkmind regression pin/list/remove/run` | Pin baselines and re-run to catch drift |
| `forkmind trajectory pin/list/remove/run` | Pin multi-turn agent paths and catch rerouting |
| `forkmind context save/list/show/verify/forget` | Encrypted context capsules (see above) |
Env vars: `FORKMIND_PORT`, `FORKMIND_HOST` (default `127.0.0.1` — loopback
only; set `0.0.0.0` to expose on the LAN at your own risk),
`FORKMIND_OPENAI_UPSTREAM`, `FORKMIND_ANTHROPIC_UPSTREAM`, `FORKMIND_PROXY`
(SDK target base URL), `FORKMIND_KEY_DIR` (capsule master-key location,
default `~/.forkmind-keys`).
---
## Development
```bash
npm install # installs proxy + dashboard (npm workspaces)
npm test # jest: hashing, storage, stream reconstruction, API
npm run dashboard:dev # vite dev server on :5173, proxies API to :4500
npm run dashboard:build
npm run lint
```
### Releasing to npm
Publishing is tag-driven via `.github/workflows/release.yml` (needs an
`NPM_TOKEN` repo secret with publish rights):
```bash
npm version patch # bumps package.json + tags
git push --follow-tags # tag push → CI lints, tests, builds dashboard, publishes
```
`prepack` rebuilds `dashboard/dist` so the tarball always ships the UI.
See [CONTRIBUTING.md](./CONTRIBUTING.md).
---
## Roadmap
- [x] CLI + deterministic storage engine
- [x] Provider-agnostic proxy (OpenAI-compatible + Anthropic) with streaming
- [x] Drop-in SDK wrappers with auto-chaining
- [x] React Flow dashboard + branch execution
- [x] MCP integration — let agents query their own `.forkmind/` history
- [x] Automated regression: pin "good" branches, re-run on prompt edits
- [x] Context capsules — offload context as an encrypted, immutable DAG;
restore in full or per segment; crypto-shred to forget
- [x] RAID — Redundant Array of Independent DAGs: replicate capsules across
filesystem targets with self-healing restore and tombstone propagation
- [x] Capsule export/import — portable, passphrase-encrypted bundles to move
context between machines and projects, independently re-verified on import
- [x] Dashboard capsule panel — browse capsules, inspect the DAG segment map,
and run integrity verification from the UI (read-only by design)
- [x] `forkmind demo` — zero-setup sample DAG + dashboard, no API key
- [x] Branch diff view — side-by-side node compare with word-level highlighting
and per-token deltas
- [x] Time-travel replay — re-run a whole chain from an edited node as a
sibling branch
- [x] Live capture stream — SSE push so nodes appear in the DAG in real time
## License
[MIT](./LICENSE)