# EvoCUA: Evolving Computer Use Agent
**π₯ #1 Open-Source Model on OSWorld | A General-Purpose Multimodal Model Excelling at Computer Use**
[](https://huggingface.co/meituan/EvoCUA-32B-20260105)
[](https://huggingface.co/meituan/EvoCUA-8B-20260105)
[](https://os-world.github.io/)
[](./LICENSE)
[English](./README.md) | [δΈζ](./README_CN.md)

**π₯ #1 Open-Source Model on OSWorld Leaderboard (Jan 2026)**
---
## π’ Updates
- **2026.03.31**: EvoCUA-32B achieves **56.48%** on WindowsAgentArena (WAA), surpassing the base model Qwen3-VL-32B-Thinking (42.9%) by ~13.6 points and UI-TARS-2 (50.6%) by ~6 points β demonstrating strong zero-shot cross-OS generalization π
- **2026.03.31**: Independent safety study by Yoshua Bengio & Dawn Song's teams ([arXiv:2602.08235](https://arxiv.org/abs/2602.08235)) shows **EvoCUA-32B has the lowest unintended-behavior rate (35.0%)** among all tested CUAs β the safest agent! π
- **2026.01.23**: EvoCUA ranked **#1** on [Hugging Face Daily Papers](https://huggingface.co/papers/2601.15876) π
- **2026.01.22**: Released [EvoCUA Technical Report](./tech_report.pdf) π
- **2026.01.13**: Released [EvoCUA-8B-20260105](https://huggingface.co/meituan/EvoCUA-8B-20260105) β achieves **46.1%** on OSWorld, **competitive with 72B-level models using fewer parameters!**
- **2026.01.05**: Released [EvoCUA-32B-20260105](https://huggingface.co/meituan/EvoCUA-32B-20260105) with **56.7%** on OSWorld, achieving **#1** among open-source models π₯
---
## π Highlights
- π₯ **#1 Open-Source Model on OSWorld**: Achieves **56.7%** task completion rate, **#1 among all open-source models**
- π **Significant Improvements**: +11.7% over OpenCUA-72B (45.0%β56.7%), +15.1% over Qwen3-VL thinking (41.6%β56.7%), with fewer parameters and half the steps
- π₯οΈ **End-to-End Multi-Turn Automation**: Operates Chrome, Excel, PowerPoint, VSCode and more through screenshots and natural language instructions
- π§ **Novel Training Method**: Our data synthesis and training approach consistently improves Computer Use capability across multiple open-source VLMs without degrading general performance
---
## π Performance Comparison
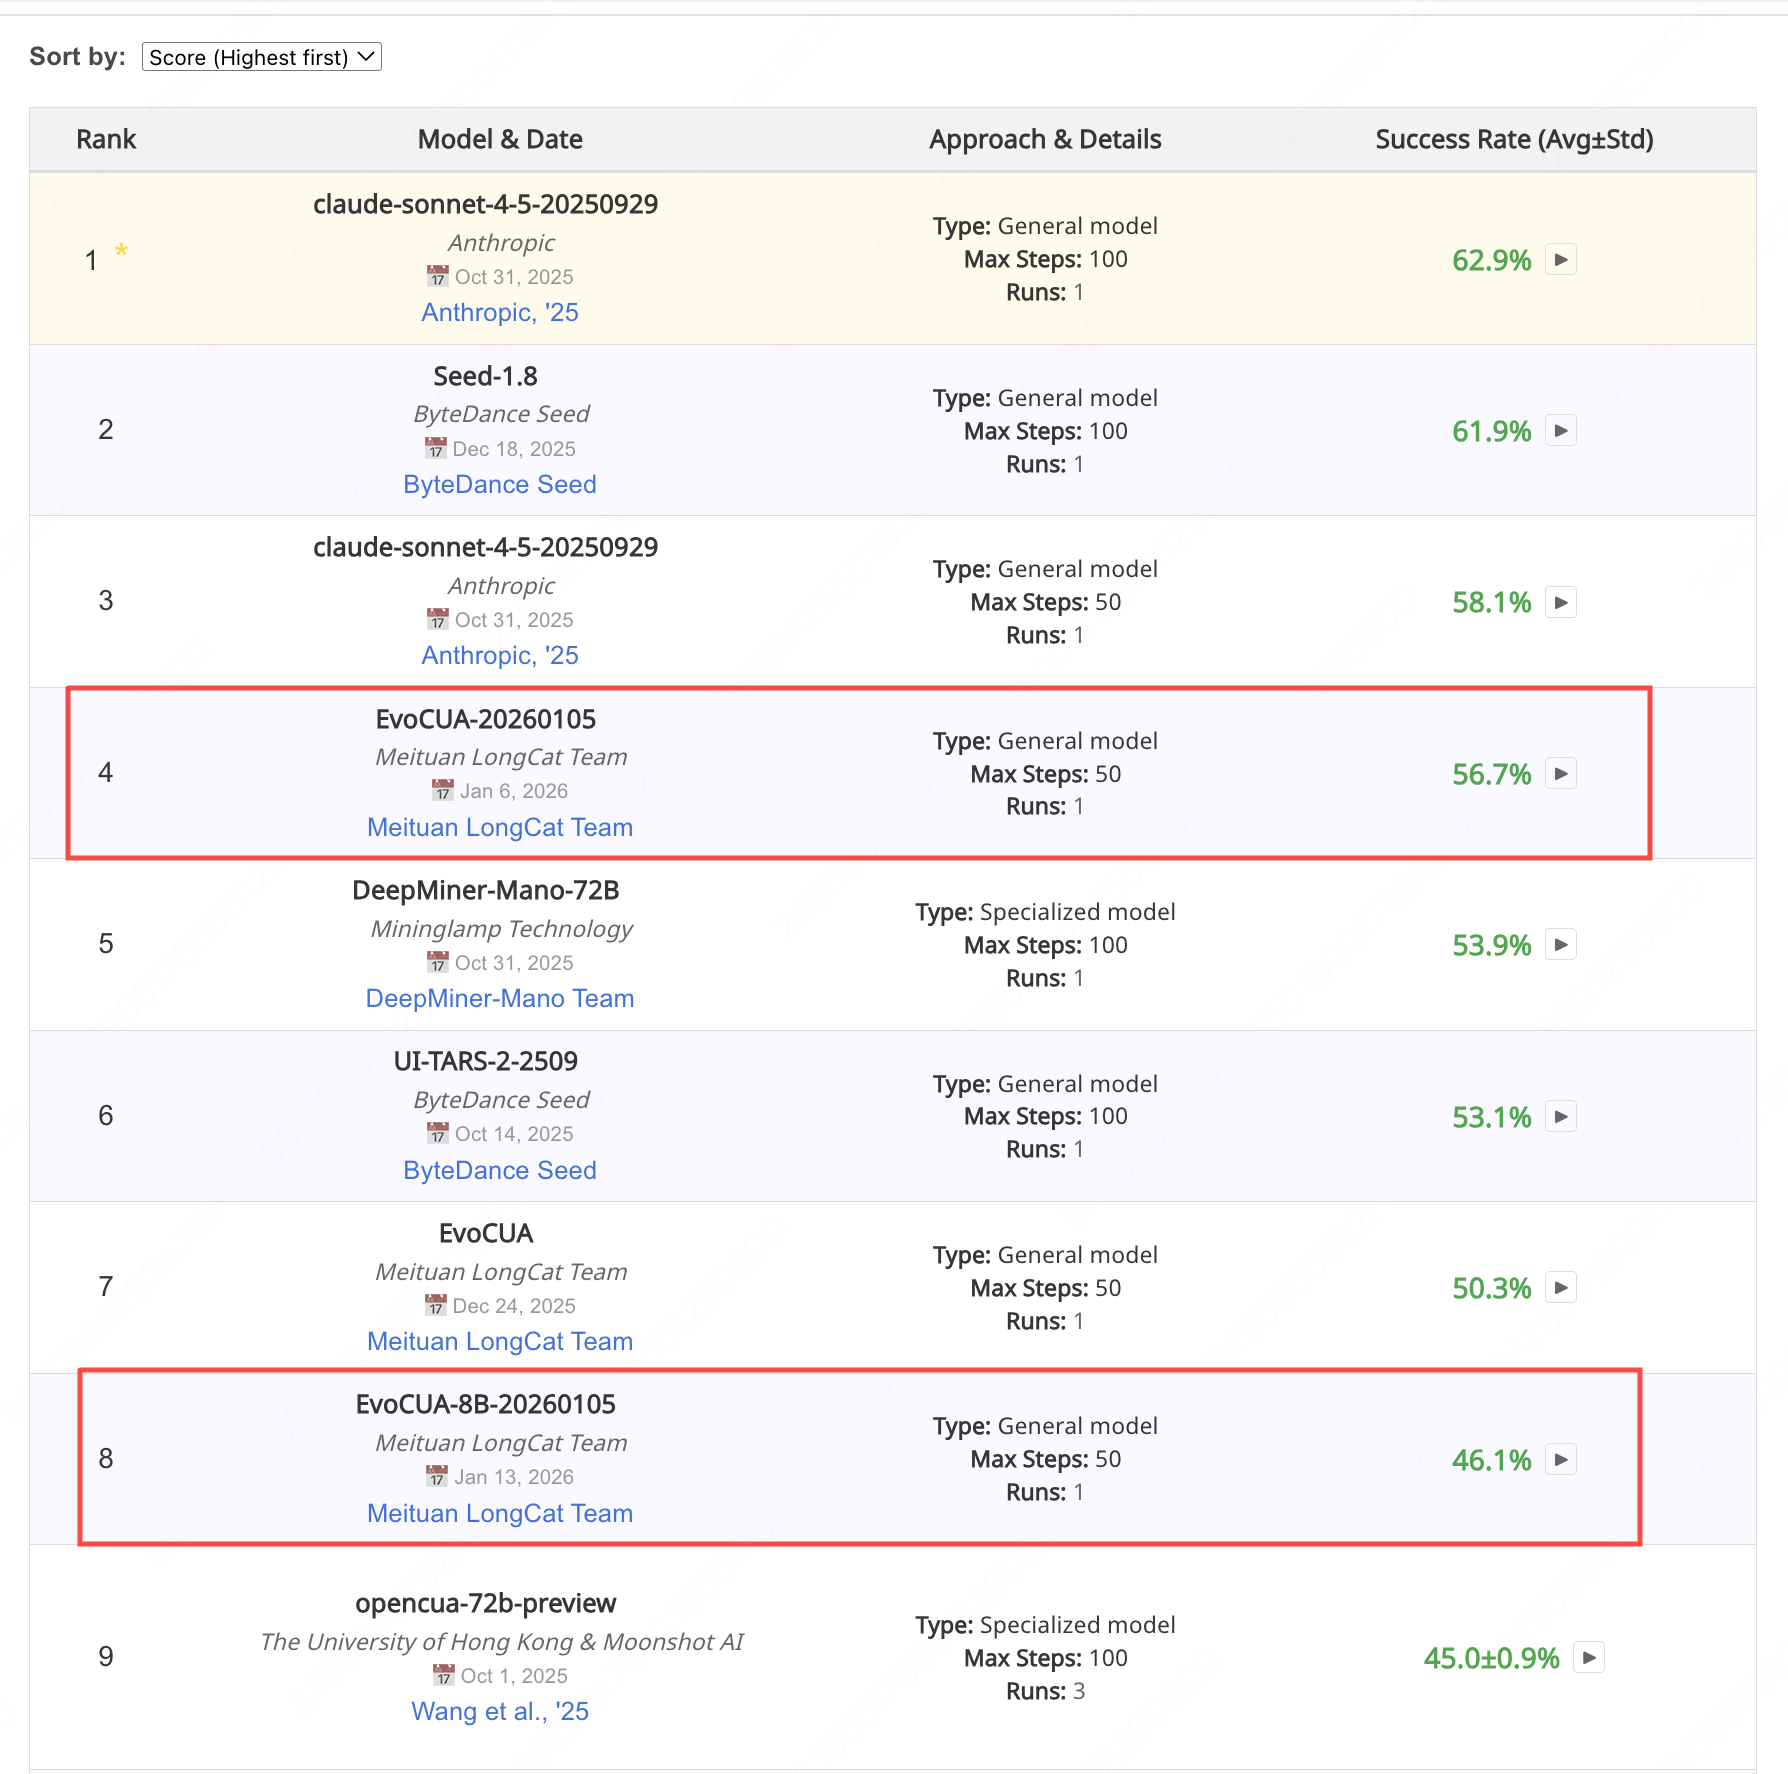
| Rank | Model | Open/Closed | Type | Max Steps | Score |
|------|-------|-------------|------|-----------|-------|
| 1 | Claude-sonnet-4-5 | π Closed | General | 100 | 62.9% |
| 2 | Seed-1.8 | π Closed | General | 100 | 61.9% |
| 3 | Claude-sonnet-4-5 | π Closed | General | 50 | 58.1% |
| **4** | **EvoCUA-20260105 (Ours)** | **π’ Open** | **General** | **50** | **56.7% π₯** |
| 5 | DeepMiner-Mano-72B | π Closed | Specialized | 100 | 53.9% |
| 6 | UI-TARS-2-2509 | π Closed | General | 100 | 53.1% |
| 7 | EvoCUA (Previous Version) | π Closed | General | 50 | 50.3% |
| **8** | **EvoCUA-8B-20260105 (Ours)** | **π’ Open** | **General** | **50** | **46.1%** |
| 9 | OpenCUA-72B | π’ Open | Specialized | 100 | 45.0% |
| ... | ... | ... | ... | ... | ... |
| 13 | Qwen3-VL-Flash | π Closed | General | 100 | 41.6% |
> EvoCUA is **#1 among all open-source models**, achieving competitive results with only **50 steps**. Human-level performance remains significantly higher, indicating substantial room for improvement.
### Zero-shot Cross-OS Control (WindowsAgentArena)
We evaluated EvoCUA on [WindowsAgentArena (WAA)](https://microsoft.github.io/WindowsAgentArena/) to test generalization from the Linux-based training environment to a wholly different OS platform. As shown below, EvoCUA-32B reaches **56.48%**, surpassing the base model Qwen3-VL-32B-Thinking (42.9%) by ~13.6 points and the leading frontier GUI agent UI-TARS-2 (50.6%) by nearly **6 points**.
| Model | WAA |
|-------|-----|
| Qwen3-VL-32B-Instruct | 30.9% [1] |
| Qwen3-VL-32B-Thinking (Base) | 42.9% [1] |
| UI-TARS-2 | 50.6% [2] |
| **EvoCUA-32B (Ours)** | **56.48%** |
> [1] Bai et al., *Qwen3-VL Technical Report* (arXiv:2511.21631, 2025).
> [2] Wang et al., *UI-TARS-2 Technical Report* (arXiv:2509.02544, 2025).
### Safety β Robustness to Unintended Behaviors
A recent study by [Jones et al. (2026)](https://arxiv.org/abs/2602.08235) from Yoshua Bengio and Dawn Song's teams systematically evaluated the safety of leading CUAs. They transferred 117 human-verified perturbations (benign but tricky instructions) to multiple target agents, executing each instruction 3 times and reporting the percentage that elicits unintended behavior in β₯ 1 run. **EvoCUA-32B achieves the lowest overall rate (35.0%)**, demonstrating the strongest robustness among all tested CUAs.