# Fara1.5 – A family of frontier computer use agent models
[](https://aka.ms/fara1.5)
[](https://arxiv.org/abs/2606.20785)
[](https://aka.ms/fara1.5-4B-foundry)
[](https://aka.ms/fara1.5-9B-foundry)
[](https://aka.ms/fara1.5-27B-foundry)
[](https://aka.ms/fara1.5-hf)
[](https://huggingface.co/datasets/microsoft/WebTailBench)
[](https://huggingface.co/datasets/microsoft/CUAVerifierBench)
---
## Updates
* **2026-07-22** — **Fara1.5 released!** A family of native computer use
agents at three scales (Fara1.5-4B, Fara1.5-9B, Fara1.5-27B) built on
Qwen3.5 and trained on data from the **FaraGen1.5** pipeline. **All three models have weights available on [Hugging Face](https://aka.ms/fara1.5-hf) and can be hosted through Microsoft Foundry ([Fara1.5-4B](https://aka.ms/fara1.5-4B-foundry), [Fara1.5-9B](https://aka.ms/fara1.5-9B-foundry), [Fara1.5-27B](https://aka.ms/fara1.5-27B-foundry))**.
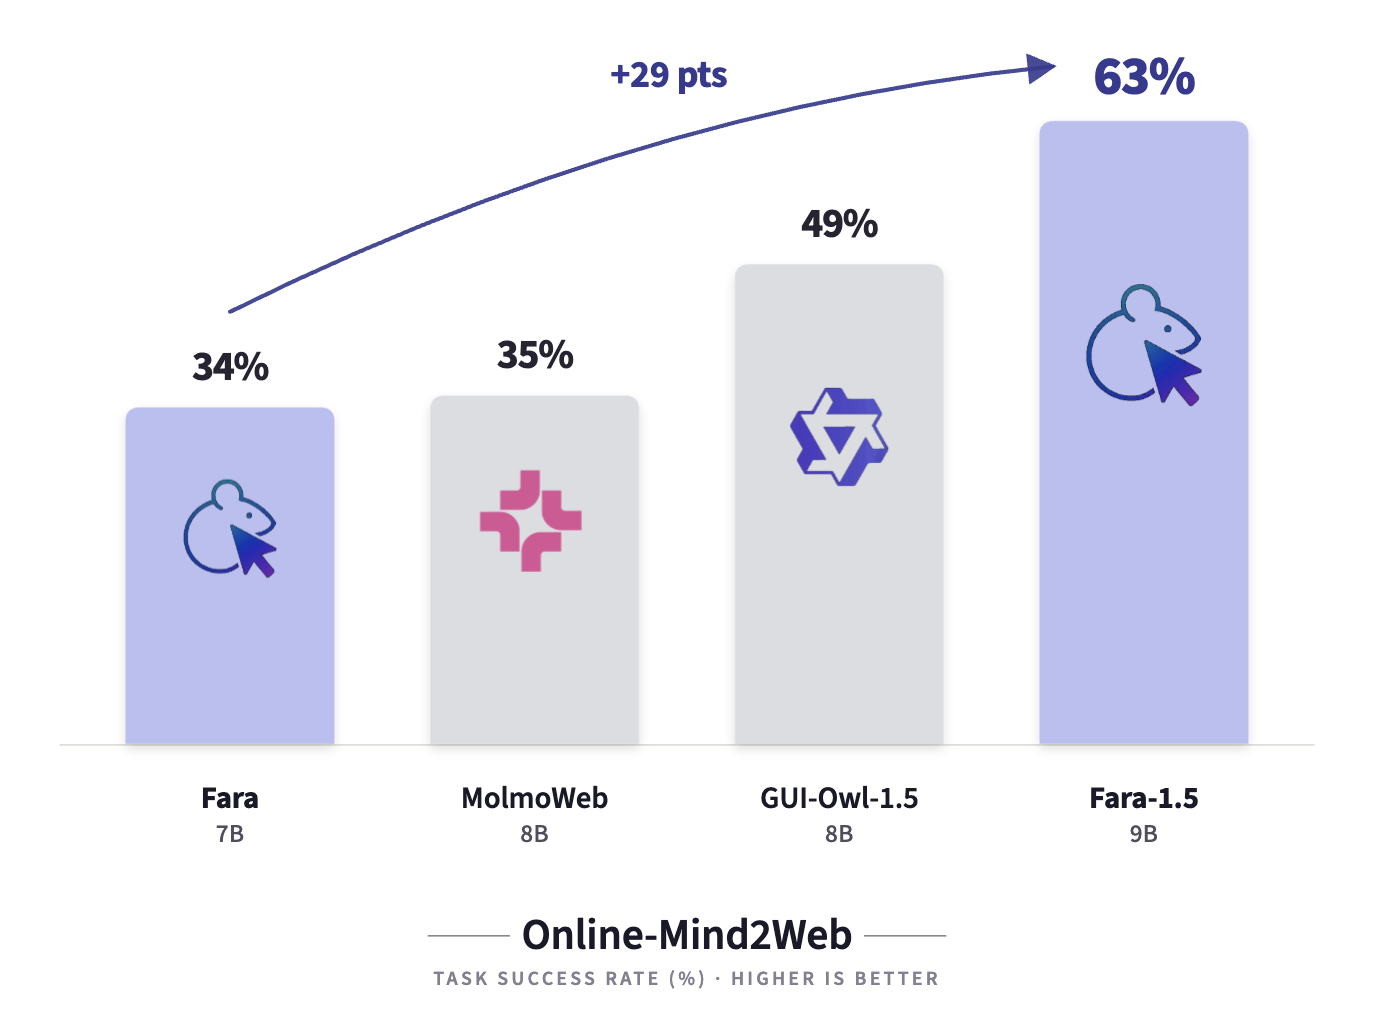
Fara1.5-9B
reaches 63.4% on Online-Mind2Web and 86.6% on WebVoyager, a new state of
the art for its size class; Fara1.5-27B achieves 72.3% on Online-Mind2Web,
outperforming much larger proprietary systems. Read the
[paper](https://arxiv.org/abs/2606.20785) and the
[blog post](https://www.microsoft.com/en-us/research/articles/fara1-5-computer-use-agent/).
* **2026-05-12** — **WebTailBench** is now a first-class benchmark in this
repo: the loader auto-downloads tasks and rubrics from
[`microsoft/WebTailBench`](https://huggingface.co/datasets/microsoft/WebTailBench)
(use the refreshed `test_v2` split; a V1↔V2 diff is hosted
[here](https://microsoft.github.io/fara/docs/webtailbench_v1_v2_diff.html)),
the **Universal Verifier** (`MMRubricAgent`) is the official judge, and the
reproducibility CLI lives in `webeval/scripts/webtailbench.py` (stand-alone
re-scoring via `webeval/scripts/verify_trajectories.py`).
* **2026-04-19** — Released **[CUAVerifierBench](https://huggingface.co/datasets/microsoft/CUAVerifierBench)**,
a human-annotated benchmark for evaluating CUA verifiers (i.e. judges that
score agent trajectories). Two splits — `fara7b_om2w_browserbase` (106
Fara-7B Online-Mind2Web/Browserbase trajectories, ~2 reviewers each) and
`internal` (154 trajectories from a heldout aurora-v2 task suite) —
with per-judge UV-blind / UV-informed labels, Universal Verifier
outputs, and legacy verifier outputs side-by-side. The build script
that produced the dataset lives alongside the data on Hugging Face.
---
## Overview
**Fara1.5** is a family of native Computer Use Agents (CUAs) at three scales — **Fara1.5-4B**, **Fara1.5-9B**, and **Fara1.5-27B** — built on Qwen3.5 and trained with supervised finetuning on data from **FaraGen1.5**, our scalable data pipeline of environments, solvers, and verifiers. Each model sets a new state of the art for its size class on browser-use benchmarks, and Fara1.5-27B outperforms much larger proprietary systems such as OpenAI Operator and Gemini 2.5 Computer Use on Online-Mind2Web.
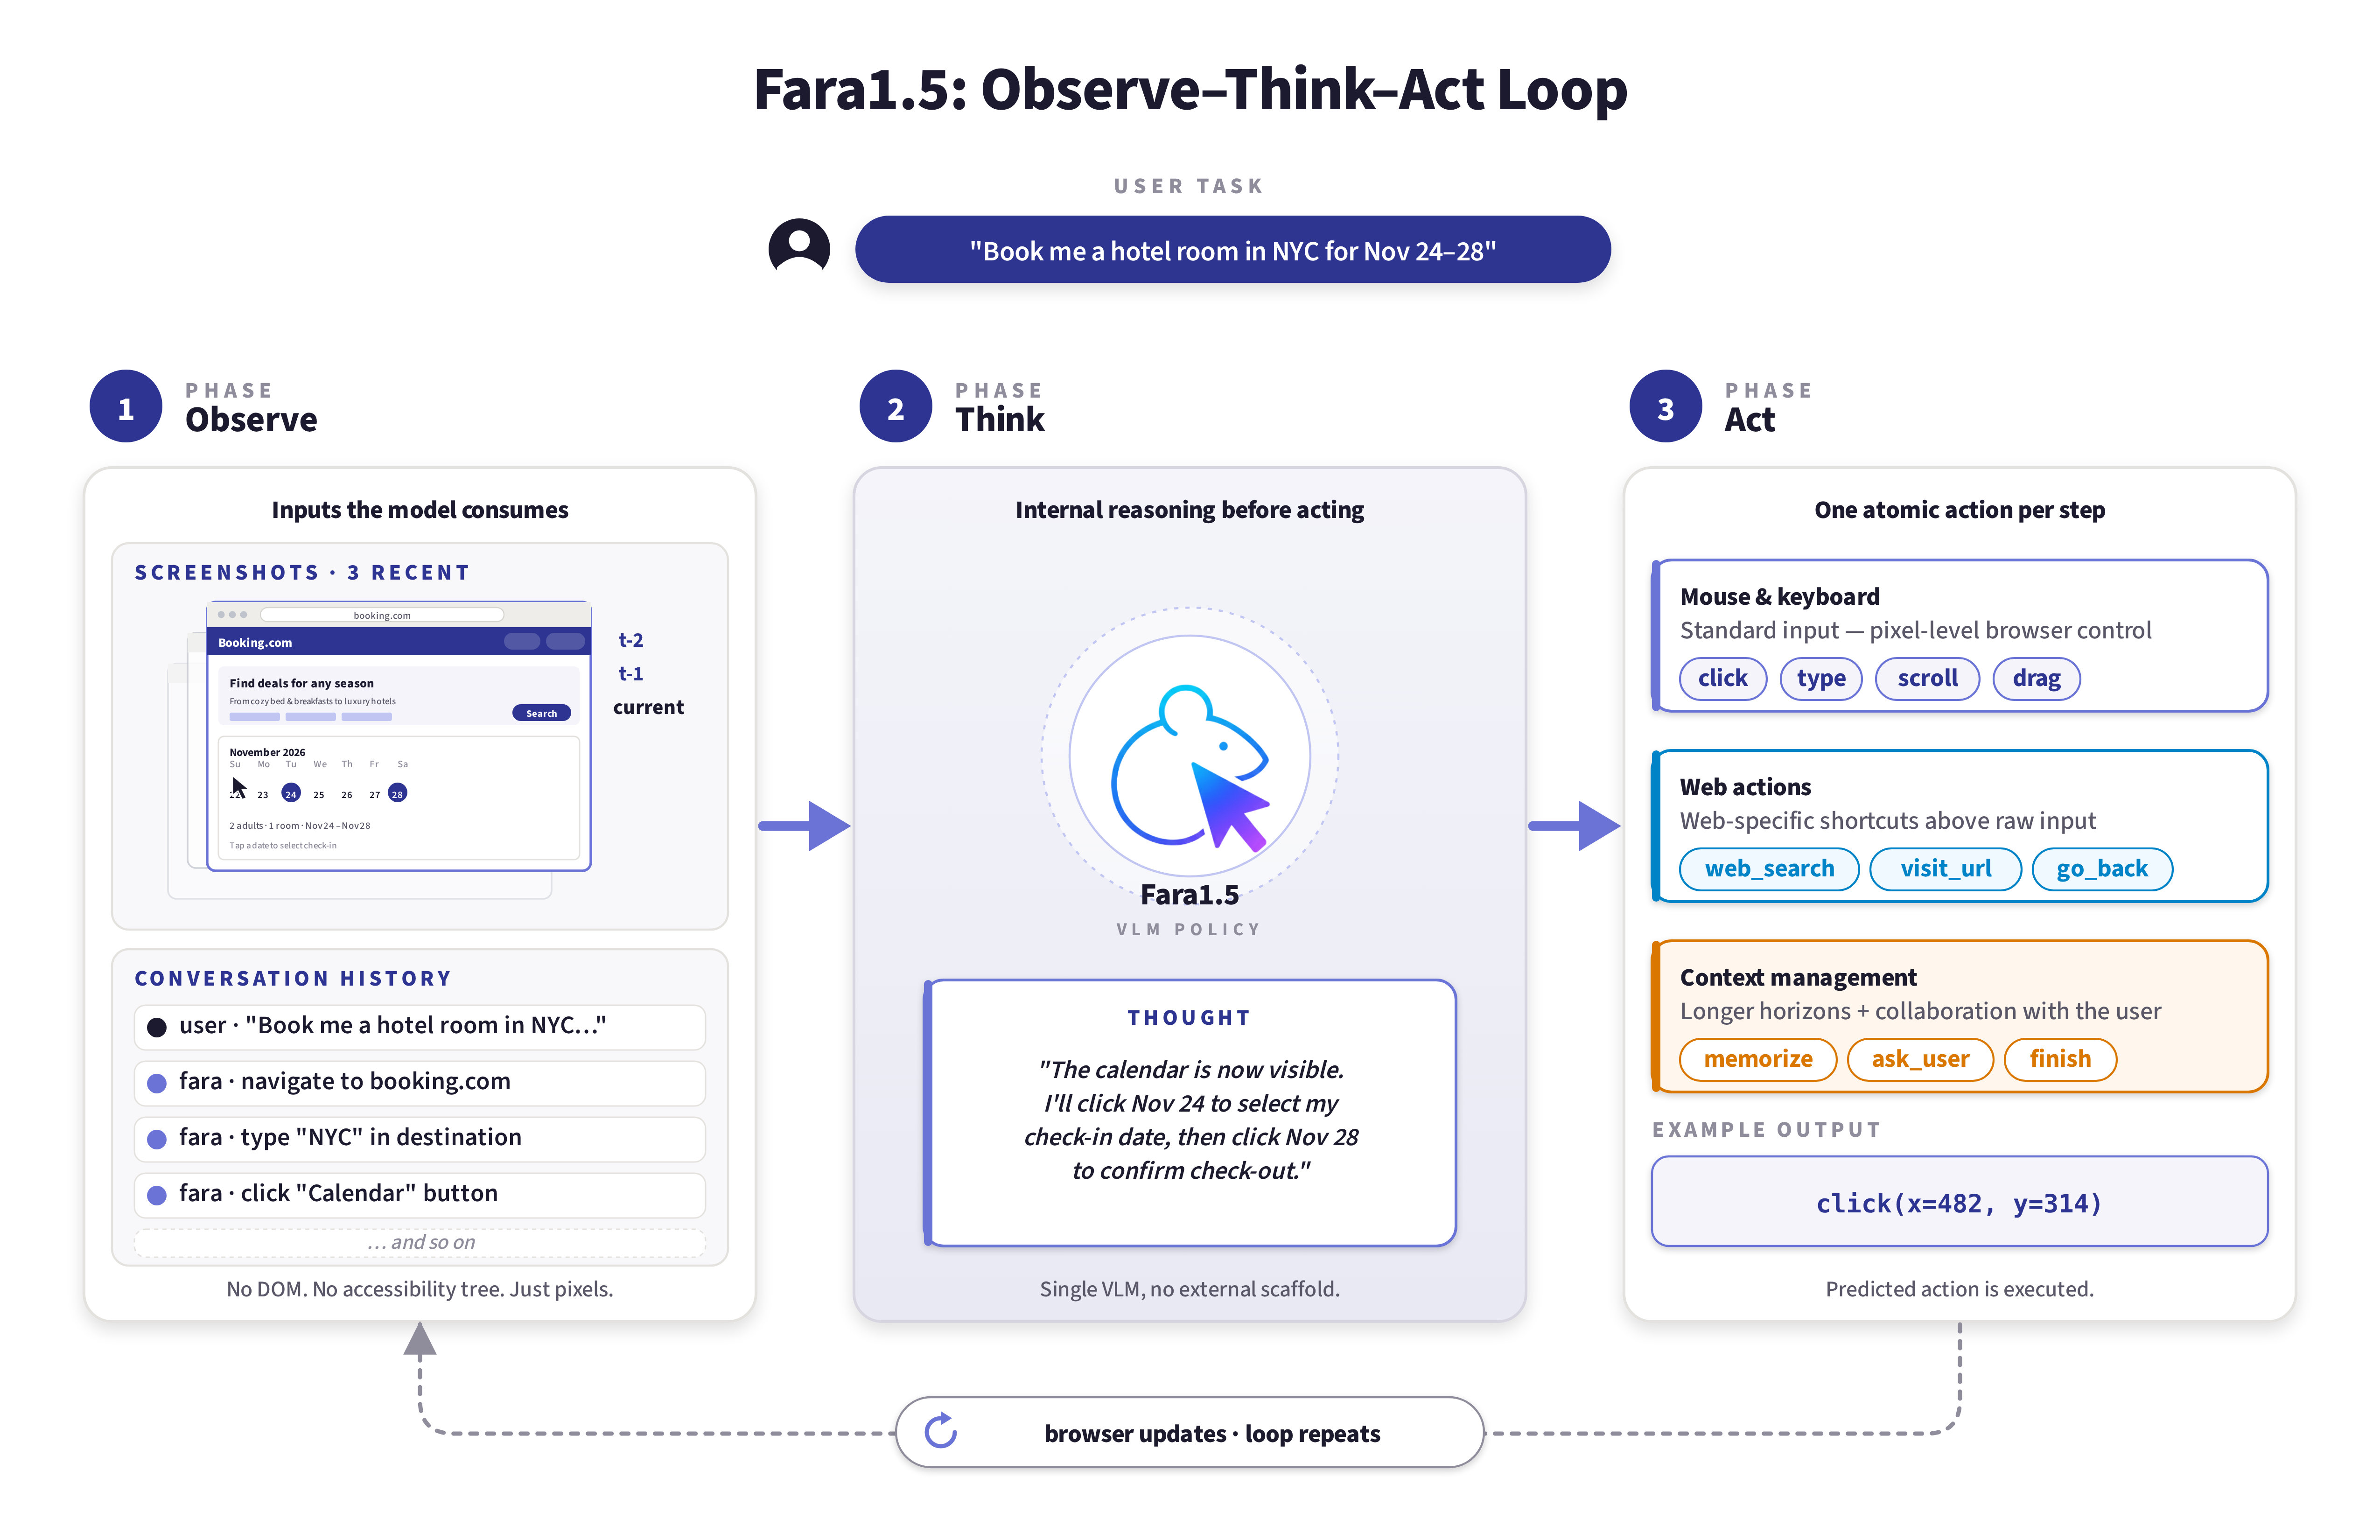
Fara1.5 models operate through an observe-think-act loop: given a screenshot of the browser and the conversation history, the model reasons about the state of the task and outputs an action — mouse and keyboard inputs on directly predicted coordinates, web searches, or context management operations — with no accessibility trees or separate parsing models.