---
date:
created: 2025-05-14
tags:
- Machine Learning
- Binary Classification
- Python
- Data Science
- Hackathon
description: >
National-level hackathon finalist machine learning pipeline analyzing 900,000+ real-world GST records with XGBoost, LightGBM, and SHAP explainability.
---
# GSTN Predictive Binary Classification
## Architecture & ML Pipeline Flow
```mermaid
graph TD
A["900,000+ Anonymized GST Records"] --> B["Data Integrity Validation (SHA256)"]
B --> C["Pre-processing & Imputation (Median / Winsorization)"]
C --> D["Class Imbalance Remediation (RUS + scale_pos_weight)"]
D --> E["Stratified 5-Fold Nested Cross-Validation"]
E --> F["Ensemble Modeling (XGBoost + LightGBM)"]
F --> G["Threshold Tuning for F1 Optimization"]
G --> H["SHAP Feature Interpretability Analysis"]
H --> I["Competition-Compliant Model Artifact"]
```
## Executive Overview
Developed for the **Goods and Services Tax Network (GSTN) AI/ML Hackathon** organized by the Government of India, this project engineered a high-throughput, interpretable binary classification pipeline for GST financial tax analytics.
The challenge required building an accurate predictive model $F_\theta(X) \to Y_{\text{pred}}$ over 900,000 real-world records characterized by severe class imbalance (91% majority / 9% minority) and extreme feature skewness, while adhering to strict zero-data-leakage compliance protocols.
## Technical Challenges & Architectural Solutions
### 1. Severe Class Imbalance (91% / 9%)
- **Challenge:** Standard loss functions biased predictions toward the majority class, causing unacceptably low minority recall.
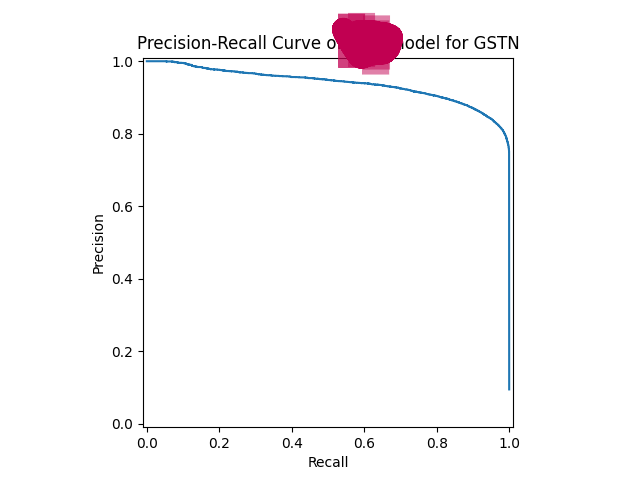
- **Solution:** Evaluated Random Under-Sampling (RUS), SMOTE, and tuned gradient boosted `scale_pos_weight` parameters to systematically optimize the Precision-Recall trade-off, maximizing both F1 and Matthews Correlation Coefficient (MCC).
### 2. Extreme Missingness & Heavy-Tailed Skewness
- **Challenge:** Multiple tax feature columns exhibited >50% missing values and extreme financial outliers.
- **Solution:** Applied strict feature pruning thresholds, robust median imputation, and two-sided Winsorization to normalize distribution tails without sacrificing variance.
### 3. Data Leakage & Generalization Safeguards
- **Challenge:** Risk of subtle data leakage across feature engineering and hyperparameter search.
- **Solution:** Enforced strict nested cross-validation and pipeline encapsulation (scikit-learn `Pipeline`) ensuring preprocessing transformations were fitted exclusively on training splits.
## Performance & Evaluation Metrics
| Evaluation Metric | Cross-Validation Score | Test Partition Score | Objective |
|:---|:---|:---|:---|
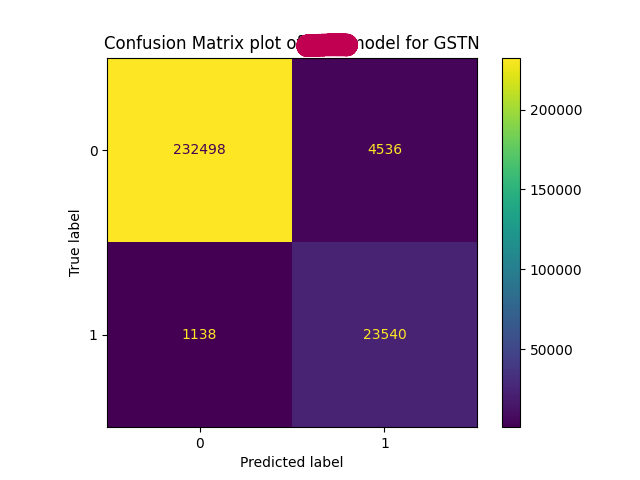
| **Accuracy** | 97.6% | **~97.8%** | Global classification correctness |
| **F1 Score** | 0.884 | **~0.891** | Harmonic mean of precision and recall |
| **MCC (Matthews Correlation)** | 0.875 | **~0.880** | Balanced quality metric for imbalanced classes |
| **ROC-AUC** | 0.988 | **~0.990** | Separability threshold performance |
## Diagnostic Visualizations
Precision-Recall Curve
Confusion Matrix
## Verified Accreditation
## Source Repository
- [GitHub Repository — mrxsierra/gstn_dsp_pbc](https://github.com/mrxsierra/gstn_dsp_pbc): Complete reproduction scripts, cross-validation benches, and documentation.
