 [](https://www.npmjs.com/package/@munhq/distil)
[](https://registry.modelcontextprotocol.io/v0/servers?search=distil)
[](https://smithery.ai/servers/munhq/distil)
[](LICENSE)
[](cursor://anysphere.cursor-deeplink/mcp/install?name=distil&config=eyJjb21tYW5kIjoibnB4IiwiYXJncyI6WyIteSIsIkBtdW5ocS9kaXN0aWwiXX0=)
[](vscode:mcp/install?%7B%22name%22%3A%22distil%22%2C%22command%22%3A%22npx%22%2C%22args%22%3A%5B%22-y%22%2C%22%40munhq%2Fdistil%22%5D%7D)
```
claude mcp add distil -- npx -y @munhq/distil
```
No account, no API key, nothing to configure. The package is a small wrapper that
fetches the binary for your platform and verifies it against the published
checksums; `install.sh` and a prebuilt binary remain for anyone without Node.
---
## Cache writes are 2% of your tokens and 28% of your bill
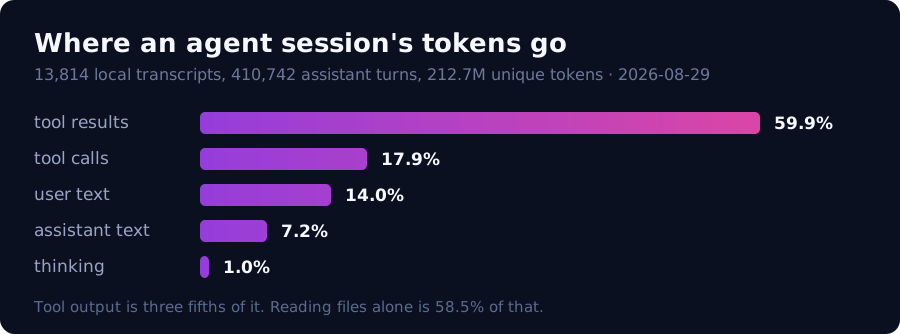
That is not a claim, it is a measurement: 13,814 real agent sessions, 410,742
assistant turns, re-run on 2026-08-29. Every unique token in them was billed
**550 times**, because a request resends the whole history.
Which means the obvious move — compress the history — is usually the wrong one.
Editing history invalidates the cached prefix from the edit onwards and converts
reads at 0.1x into writes at 1.25x or 2.0x. **You cannot compress your way out of
context cost. You can only decline to admit tokens.**
 Every tool in this space publishes a savings percentage measured on its own
fixtures. What none publishes is the denominator: what share of a real session
it is allowed to touch, and what that share costs once prompt-cache pricing is
applied. `distil` measures both on transcripts an agent actually wrote.
**What is prior art, and what is not.** The cache arithmetic below is not a
discovery. Anthropic's [context editing
docs](https://platform.claude.com/docs/en/build-with-claude/context-editing)
state that clearing tool results invalidates the cached prefix, and ship
`clear_at_least` so a clear only fires when it is large enough to pay for that.
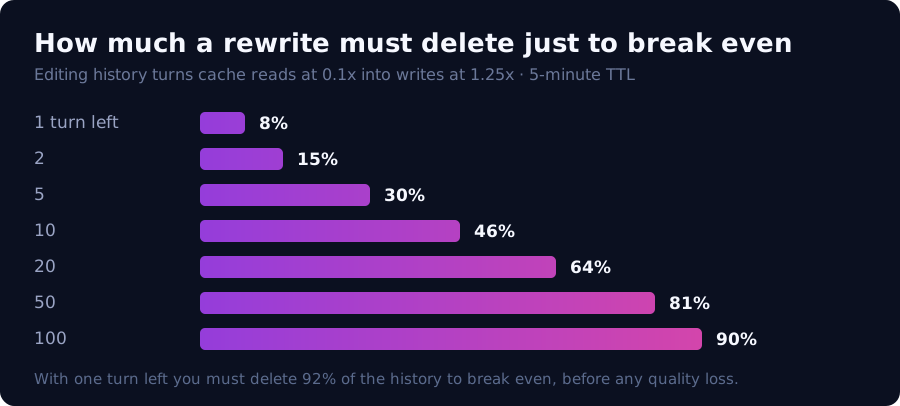
The break-even rule is published too: on a 5-minute cache, cleared tokens times
requests-before-the-next-clear must exceed 11.5 times the tokens you keep. The
table in this README reproduces that rule exactly — it was derived
independently, which is a check on the arithmetic, not a contribution.
The gap is empirical. Every source says to calibrate against your own workload,
and none ships a way to do it or publishes what the values turn out to be. That
is what this crate is for: measuring the numbers you need in order to choose
`clear_at_least`, or to decide not to clear at all.
## The full measurement
Measured 2026-08-29 over 13,814 local Claude Code transcripts — 410,742
assistant turns, 212.7M tokens of unique text. Reproduce it on your own corpus
with `distil-bench ~/.claude/projects`; a corpus grows, so the date matters
more than the decimals.
| | tokens | share |
|---|---|---|
| tool results | 127,371,430 | 59.9% |
| tool calls | 38,065,121 | 17.9% |
| user text | 29,818,536 | 14.0% |
| assistant text | 15,402,077 | 7.2% |
| thinking | 2,076,716 | 1.0% |
Those 212.7M unique tokens were billed as **116.9 billion input tokens** — every
token paid for 550 times, because a request resends the whole history.
Price that at real cache multipliers (read 0.1x, write 1.25x for the 5-minute
TTL and 2.0x for the 1-hour):
| | share of tokens | share of **cost** |
|---|---|---|
| cache read | 97.9% | 71.8% |
| cache writes | **2.0%** | **27.6%** |
**Cache writes are 2% of the tokens and 28% of the bill.** Editing history
invalidates the cached prefix from the edit onwards, converting reads at 0.1x
into writes at 1.25x or 2.0x. So a rewrite must shrink what it invalidates below:
| turns remaining | 5m TTL | 1h TTL |
|---|---|---|
| 1 | 8.0% | 5.0% |
| 10 | 46.5% | 34.5% |
| 20 | 63.5% | 51.3% |
| 100 | 89.7% | 84.0% |
That table is the published break-even rule in another form: at every row,
`cleared x turns / kept` equals 11.5 for the 5-minute tier. Use it to pick a
`clear_at_least` value, and use `distil-bench` to find the turn count and tail
size to put into it — those are workload properties, and they are the part
nobody publishes.
Per unit of history, at 10 remaining turns: keeping it costs 1.00, compressing
it costs 2.15, and never admitting it costs 0. **You cannot compress your way
out of context cost. You can only decline to admit tokens.**
## What that means for using this crate
Layers that do not touch history are on the right side of that arithmetic:
`CacheAlignLayer` (orders content so the stable prefix stays cacheable) and
`ScratchpadLayer` (keeps working state outside the window).
Layers that rewrite history — `MaskingLayer`, `SummarizationLayer`,
`CompactionLayer` — cost more than they save in the common case. Reach for them
at one boundary only: **context overflow**, where the alternative is a failed
request and cache price stops being the comparison. `BudgetLayer` exists for
exactly that moment.
`RegistryLayer` and `CodeModeLayer` predate Anthropic's Tool Search Tool and
Programmatic Tool Calling, which do the same jobs natively and better. Prefer
the native features.
For clearing old tool results, prefer the provider's `clear_tool_uses` context
editing over `MaskingLayer`: it runs server-side, it takes `clear_at_least`, and
it is one API parameter against a dependency. Reach for a layer here only when
you need behaviour the API does not offer.
## Measuring
```bash
cargo build --features bench --release
# Where tokens are, what they cost, and the break-even table
./target/release/distil-bench ~/.claude/projects --json baseline.json
# Sessions that called a given tool, against those that did not
./target/release/distil-bench ~/.claude/projects --split-by-tool mcp__codeindex__
# Export real traffic so other compressors run on the same input
./target/release/distil-bench ~/.claude/projects --export-sessions ./sessions --min-turns 40
```
See [`bench/README.md`](bench/README.md) for the external-tool comparison, the
fairness rules, and the two harness mistakes that produced wrong numbers first.
## Retention
A saving is only a saving if the model can still answer what the original
context could answer.
```bash
# No LLM judge: file paths checked against ground truth from the transcript
python bench/artifact_retention.py ./sessions 12
# LLM-graded probes (recall / artifact / continuation / decision)
cargo build --features probe --release
./target/release/distil-probe --probes 6 --model qwen2.5:3b
```
The probe taxonomy is [Factory.ai's](https://factory.ai/news/evaluating-compression);
their write-up defines it and ships no harness. The judge is a `Completer`,
never a `Summarizer` — a summarizer may impose summarization framing, which
rewrites both the probe format and the grading instruction.
## Using it as a library
```rust
use distil::{CacheAlignLayer, Ctx, EstimateCounter, Pipeline};
let pipeline = Pipeline::builder()
.counter(EstimateCounter)
.layer(CacheAlignLayer::generic())
.build();
let mut ctx = Ctx::new(messages, tools, turn);
let result = pipeline.optimize(&mut ctx);
println!("{result}");
```
This example is kept compilable as
[`examples/readme_quickstart.rs`](examples/readme_quickstart.rs) — run it with
`cargo run --example readme_quickstart`.
Every layer implements `Layer` and reports `tokens_before`, `tokens_after` and a
detail line, so each one can be measured on its own.
## Features
| feature | what it adds |
|---|---|
| `corpus` | transcript loader (no extra dependencies) |
| `bench` | `distil-bench`, needs `tiktoken` |
| `probe` | `distil-probe`, needs `proxy` for the HTTP judge |
| `tiktoken` | accurate BPE counts instead of the chars/3.5 estimate |
| `proxy` | `distil-proxy` HTTP server |
| `mcp` | `distil-mcp` MCP server |
| `metrics` | Prometheus `/metrics` |
## Install
```
./install.sh # binaries, the skill, and the MCP server
/plugin marketplace add munhq/distil
/plugin install distil # Claude Code: skill and server in one step
```
`install.sh` installs both binaries, drops the skill into every Claude home it
finds, and registers the MCP server at user scope. When the plugin is already
installed it installs the binary only, since the plugin declares the server and
ships the skill itself.
The plugin launches the server with `npx -y @munhq/distil`, so it needs Node.
It cannot use a plugin-relative path: Claude Code expands `${CLAUDE_PLUGIN_ROOT}`
and nothing else does, so a plugin declaring one hands every other client a
literal path that does not exist. `install.sh` and the prebuilt binaries remain
for anyone without Node.
### Platform support
| platform | binaries | scripts |
|---|---|---|
| Linux x86_64 / arm64 | released, tested | yes |
| macOS x86_64 / arm64 | released, built in CI | yes |
| Windows x86_64 / arm64 | released, built in CI | needs a shell: Git Bash, MSYS2 or WSL |
The release publishes six targets and `plugin/test_platform.sh` holds both the
installer and the plugin launcher to that matrix, so an asset name and the name
asked for cannot drift apart. `install.sh` and the launcher are bash scripts, so
on Windows they need a shell — `cmd` and PowerShell cannot run them. Linux
binaries are static musl builds, so they do not need a matching glibc.
## Caveats
The corpus is one developer's machine. The **ratios** are the finding; the
absolute totals are personal. Counts use `cl100k_base`, which approximates
Claude's tokenizer within a few percent. The break-even model assumes a single
cache breakpoint, so a rewrite confined to the tail costs less than the table
shows — that refines it, it does not reverse it.
## Contributing
Build and test instructions, the rules a benchmark change has to follow, and what
a pull request needs before review: [`CONTRIBUTING.md`](CONTRIBUTING.md).
Report a vulnerability privately — [`SECURITY.md`](SECURITY.md).
## License
MIT. See [LICENSE](LICENSE).