
 : Reinforcement Fine-Tuning for Improved Remote Sensing Reasoning
Overview
Earth Observation (EO) tasks introduce unique challenges, spanning referred object detection, image/region captioning, change detection, grounding, and temporal analysis, that demand task-aware reasoning. We propose a novel post-training framework that incorporates task-aware rewards to enable effective adaptation of reasoning-based RL models to diverse EO tasks. This training strategy enhances reasoning capabilities for remote-sensing images, stabilizes optimization, and improves robustness. Extensive experiments across multiple EO benchmarks show consistent performance gains over state-of-the-art generic and specialized vision–language models
---
## Install
1. Clone this repository and navigate to GeoVLM-R1-Toolkit folder
```bash
git clone https://github.com/mustansarfiaz/GeoVLM-R1-Toolkit.git
cd GeoVLM-R1-Toolkit
```
2. Install Package
```Shell
conda create -n GeoVLM-R1-Toolkit python=3.10 -y
conda activate GeoVLM-R1-Toolkit
pip install --upgrade pip # enable PEP 660 support
pip install -e .
```
3. Install additional packages for training cases
```
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu121
pip install -r requirements.txt
pip install qwen-vl-utils
pip install ninja
pip install flash-attn --no-build-isolation
pip install modelscope, math_verify, openai, json_repair
pip install --upgrade typing_extensions
pip install openai
pip install json_repair
pip install trl==0.17.0
pip install transformers==4.49.0
pip install math_verify
pip install Babel
```
---
## 🏆 Contributions
- **GeoVLM-R1: A specialized VLM for high-resolution remote sensing image Reasoning.** We propose GeoVLM-R1, a reinforcement learning framework that encourages VLM to enhance its reasoning capabilities with flexibility, scalability, and ease of experimentation in mind for diverse EO tasks.
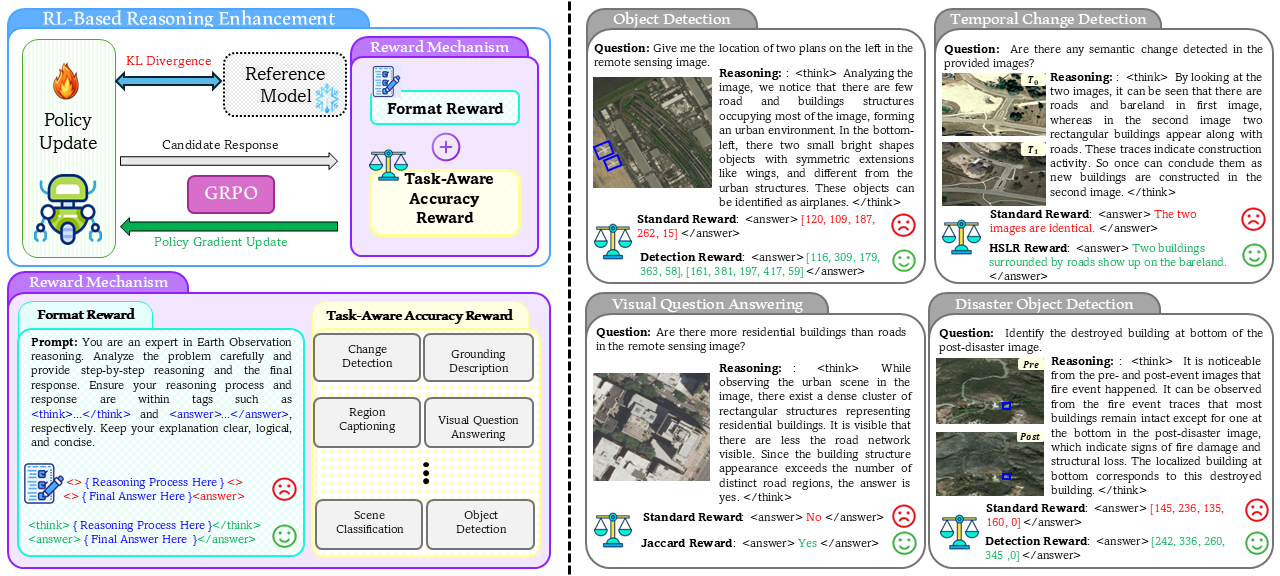
- **Reward Mechanism.** We have a sophisticated reward mechanism, enabling effective RL in EO reasoning contexts. To generate structurally coherent and semantically accurate reasoning outputs, we introduce format and task-aware accuracy rewards to better guide reasoning optimization.
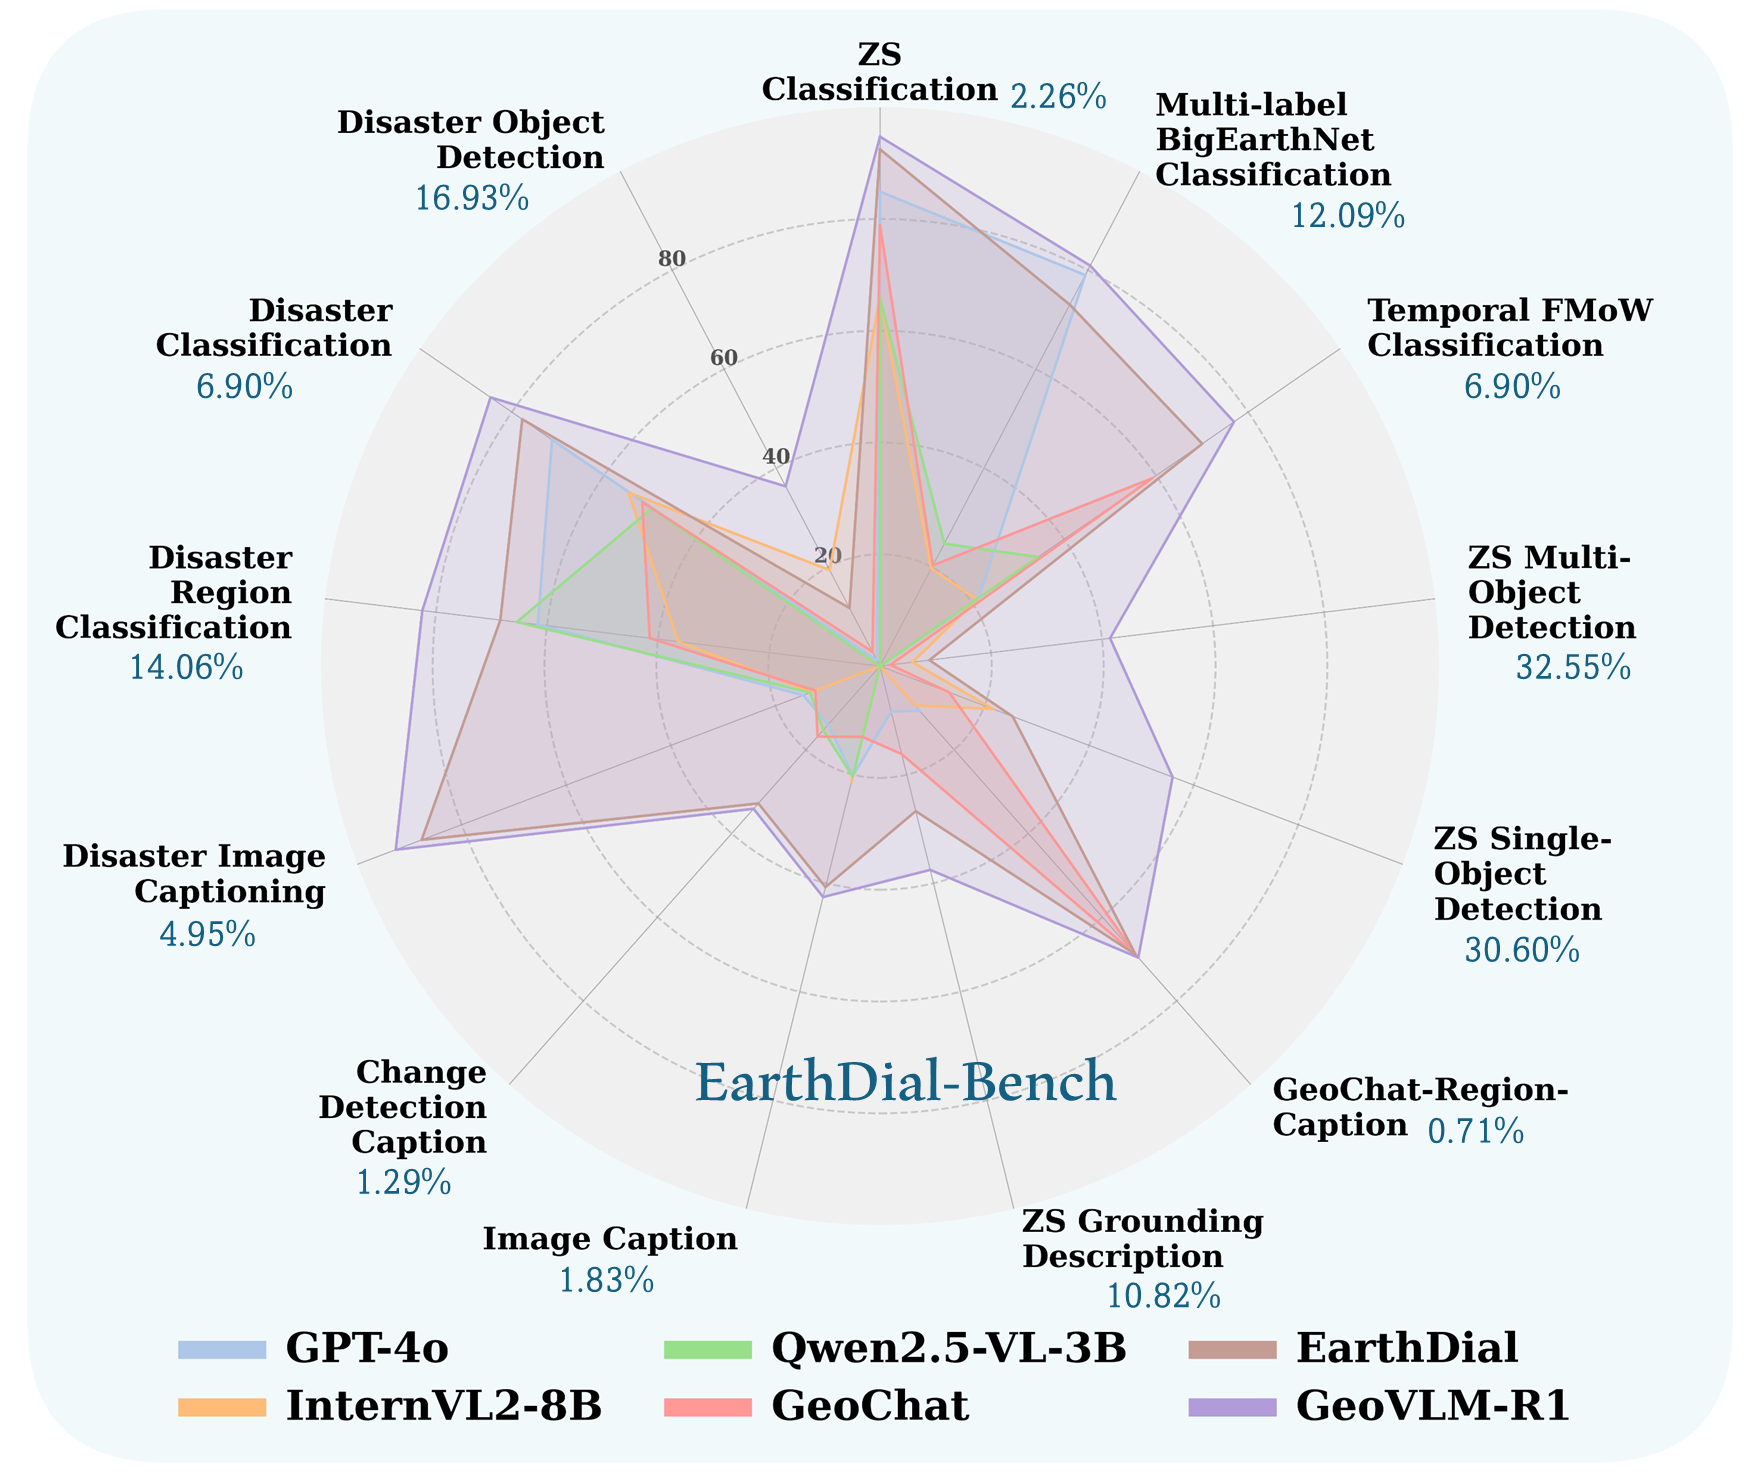
- **Evaluation Benchmark.** Our experimental results demonstrate the effectiveness of GeoVLM-R1 on multiple challenging EO tasks. Experimental results on 28 downstream benchmarks show that our method performs well compared to existing VLMs and achieves better performance, demonstrating its merits.
---
## 👁️💬 GeoVLM-R1: RL Training Paradigm
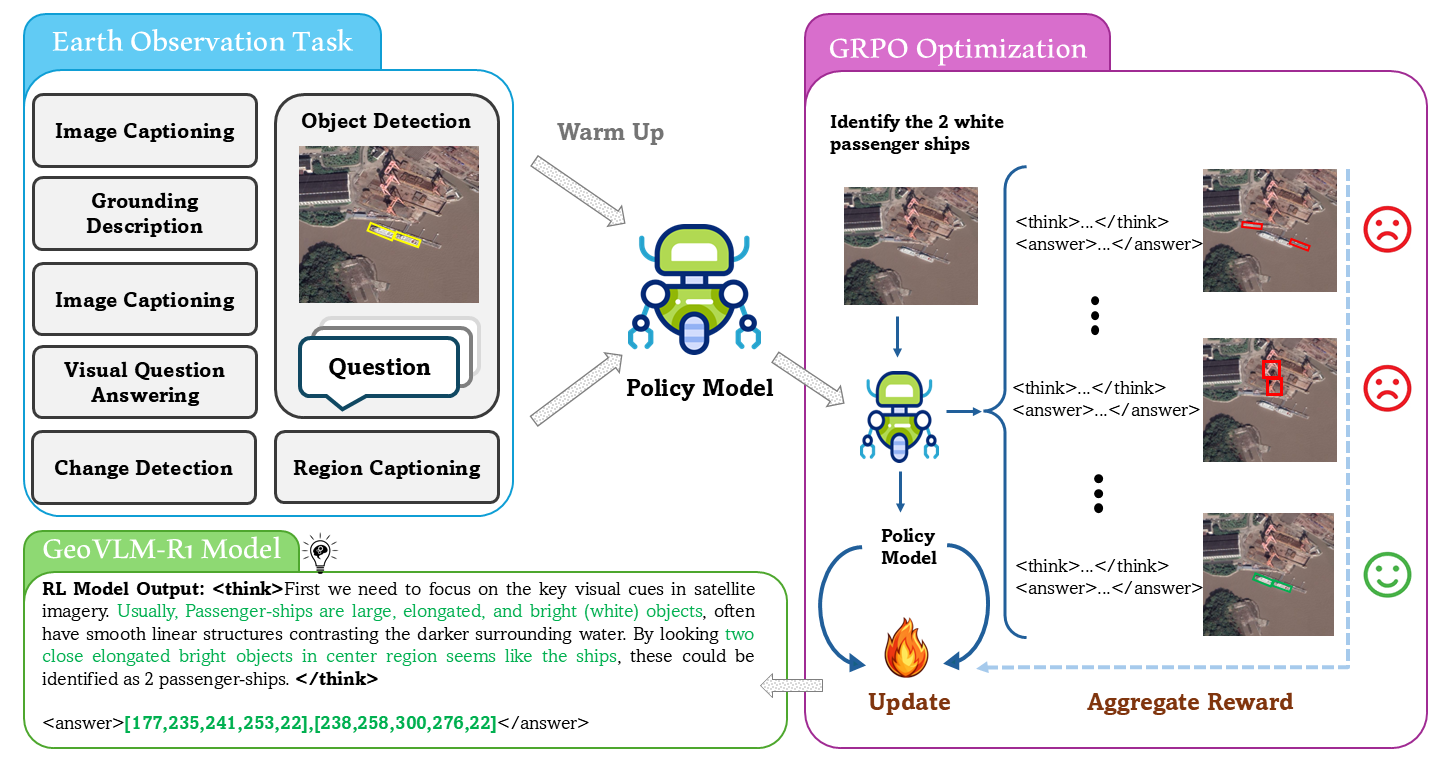
Illustration of the overall proposed training paradigm for GeoVLM-R1. The model is first initialized via supervised fine-tuning using diverse earth observation tasks. It is then successively optimized using GRPO-based reinforcement learning (RL) for each task. The GeoVLM-R1 processes queries and outputs a structured format that comprises an interpretable reasoning trace (
| Model | Referred Object Detection Task | Region-Captioning Task | Grounding Task | ||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| GeoChat-Instruct | NWPU VHR-10 (Zero-Shot) | GeoChat-Instruct | NWPU VHR-10 (Zero-Shot) | NWPU VHR-10 (Zero-Shot) | |||||||||||||||||
| Small | Med. | Large | Single | Mult. | Small | Med. | Large | Single | Mult. | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | @0.5 | @0.25 | Rouge1 | Rouge-L | Meteor | |
| GPT-4o | - | - | - | - | - | - | - | - | - | - | 9.41 | 7.6 | 8.02 | 17.68 | 11.81 | 9.63 | 0.7 | 6.1 | 14.72 | 10.82 | 9.41 |
| InternVL2-4B | 6.3 | 24.37 | 37.38 | 24.96 | 11.72 | 7.1 | 12.68 | 25.48 | 22.96 | 8.1 | - | - | - | - | - | - | 10.6 | 29.87 | 30.67 | 29.09 | 21.92 |
| InternVL2-8B | 7.20 | 23.76 | 31.99 | 25.77 | 9.30 | 4.26 | 11.85 | 20.72 | 21.66 | 5.86 | 10.58 | 9.06 | 8.5 | 11.88 | 9.63 | 7.7 | - | - | - | - | - |
| GeoChat | 2.9 | 13.6 | 21.7 | 16 | 4.3 | 2.5 | 3.2 | 14.7 | 13.23 | 1.9 | 72.77 | 72.74 | 61.9 | 62.02 | 62.02 | 53.31 | 2.2 | 15.27 | 21.46 | 20.74 | 21.38 |
| EarthDial | 11.43 | 31.76 | 39.07 | 34.29 | 13.41 | 11.66 | 14.21 | 23.12 | 25.37 | 8.9 | 73.38 | 73.34 | 62.72 | 72.14 | 72.14 | 60.01 | 17.07 | 41.00 | 27.05 | 26.35 | 23.12 |
| GeoVLM-R1 | 36.02 | 54.72 | 55.03 | 57.1 | 35.04 | 34.44 | 48.76 | 64.91 | 55.97 | 41.45 | 75.92 | 75.9 | 66.43 | 72.10 | 72.10 | 55.49 | 38.74 | 61.45 | 31.31 | 30.08 | 26.10 |
| Model | CD Dubai-CC | CD LEVIR-MCI | CD MUDS | CD SYSU (ZS) | IC NWPU-Captions | IC RSCID-Captions | IC RSITMD-Captions (ZS) | ||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | Rouge1 | Rouge-L | Meteor | |
| GPT-4o | 8.81 | 7.45 | 18.68 | 10.33 | 8.4 | 22.05 | 14.18 | 11.02 | 20.92 | 16.48 | 12.32 | 17.49 | 19.43 | 14.86 | 28.16 | 20.53 | 15.59 | 26.03 | 18.31 | 14.22 | 24.83 |
| InternVL2-4B | 7.31 | 6.38 | 21.12 | 8.88 | 7.43 | 22.14 | 10.25 | 7.90 | 17.73 | 13.27 | 9.98 | 14.36 | - | - | - | - | - | - | - | - | - |
| InternVL2-8B | - | - | - | - | - | - | - | - | - | - | - | - | 20.69 | 15.64 | 30.18 | 21.59 | 16.13 | 28.17 | 18.91 | 14.65 | 26.02 |
| Qwen2.5-VL-3B | 14.41 | 13.62 | 27.59 | 12.27 | 10.11 | 26.11 | 12.13 | 9.30 | 18.22 | 13.61 | 10.34 | 16.06 | 18.82 | 14.72 | 26.79 | 21.37 | 16.42 | 26.53 | 18.79 | 15.02 | 25.05 |
| GeoChat | 14.21 | 14.19 | 28.91 | 17.15 | 35.42 | 12.35 | 12.28 | 12.23 | 15.98 | 13.45 | 12.02 | 13.96 | 14.86 | 12.54 | 15.21 | 13.48 | 11.59 | 12.39 | 13.41 | 11.50 | 12.33 |
| EarthDial | 31.94 | 30.66 | 55.83 | 33.78 | 30.47 | 74.80 | 28.16 | 24.03 | 33.56 | 18.03 | 17.42 | 14.98 | 45.84 | 39.96 | 80.61 | 33.77 | 27.61 | 56.18 | 26.74 | 21.72 | 34.06 |
| GeoVLM-R1 | 36.60 | 34.15 | 61.22 | 37.85 | 34.02 | 73.56 | 34.07 | 27.65 | 45.94 | 19.64 | 18.46 | 15.45 | 46.94 | 40.96 | 82.00 | 34.64 | 28.63 | 56.54 | 30.62 | 25.39 | 39.07 |
| Model | Image Captioning | Region Classification | Image Classification | Object Detection | Referred Object Detection | |||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Rouge1 | Rouge-L | Meteor | Test Set-1 | Test Set-2 | Test Set-1 | Test Set-2 | Test Set-3 | mAP@0.5 | mAP@0.25 | mAP@0.5 | mAP@0.25 | |
| GPT-4o | 14.21 | 10.35 | 19.52 | 51.68 | 71.62 | 67.95 | 75.45 | 70.41 | 0.2 | 2.15 | - | - |
| InternVL2-8B | 13.89 | 10.37 | 14.92 | 14.39 | 58.33 | 51.44 | 61.52 | 51.12 | 0.6 | 1.07 | - | 0.7 |
| Qwen2.5-VL-3B | 11.98 | 8.12 | 19.94 | 71.19 | 59.69 | 51.44 | 56.16 | 41.26 | - | - | - | - |
| GeoChat | 14.18 | 10.67 | 12.20 | 25.30 | 57.65 | 53.32 | 52.19 | 49.51 | 1.15 | 7.2 | 0.2 | 3.09 |
| EarthDial | 87.26 | 87.26 | 88.53 | 53.70 | 83.09 | 96.37 | 82.85 | 54.01 | 7.6 | 21.11 | 5.1 | 13.09 |
| GeoVLM-R1 | 92.26 | 92.26 | 93.37 | 81.36 | 83.55 | 98.93 | 86.39 | 68.60 | 38.15 | 48.13 | 24.52 | 34.52 |
| Model | RSVQA-LRBEN | Model | RSVQA-HRBEN (zero-shot) | |||||
|---|---|---|---|---|---|---|---|---|
| Presence | Comp | R/U | Avg. | Presence | Comp | Avg. | ||
| MiniGPTv2 | 55.16 | 55.22 | 39.00 | 54.96 | MiniGPTv2 | 40.79 | 50.91 | 46.46 |
| Qwen2-VL | 38.57 | 67.59 | 61.00 | 55.35 | Qwen2-VL | 66.44 | 60.41 | 63.06 |
| InternVL2-8B | 58.54 | 72.28 | 71.00 | 66.51 | InternVL2-8B | 67.35 | 76.91 | 72.70 |
| Qwen2.5-VL-3B | 59.59 | 75.04 | 63.00 | 68.40 | Qwen2.5-VL-3B | 59.89 | 72.26 | 66.81 |
| GeoChat | 91.09 | 90.33 | 94.00 | 90.70 | GeoChat | 58.45 | 83.19 | 72.30 |
| LHRS-Bot | 88.51 | 90.00 | 89.07 | 89.19 | EarthGPT | 62.77 | 79.53 | 72.06 |
| TeoChat | 91.70 | 92.70 | 94.00 | 92.29 | TeoChat | 67.50 | 81.10 | 75.04 |
| EarthDial | 92.58 | 92.75 | 94.00 | 92.70 | EarthDial | 58.89 | 83.11 | 72.45 |
| GeoVLM-R1 | 91.81 | 93.20 | 96 | 92.66 | GeoVLM-R1 | 66.38 | 82.26 | 75.27 |
 ](https://ibm.com/)
[
 ](https://insait.ai/)
[
 ](https://ethz.ch/en.html)
[
 ](https://mbzuai.ac.ae)
[
 ](https://liu.se/en)
[
 ](https://www.anu.edu.au/)