
[](https://github.com/NBibikov/cogvault/blob/main/LICENSE) [](https://www.python.org) [](https://modelcontextprotocol.io) [](https://pypi.org/project/cogvault/) [](https://registry.modelcontextprotocol.io/?search=cogvault) [](https://glama.ai/mcp/servers/NBibikov/cogvault) **[Get started](#get-started-in-30-seconds)** · **[Why](#why)** · **[Compared](#compared-to)** · **[How it works](#how-it-works)** · **[Benchmark](#benchmark)** · **[Install](#install)** · **[Quickstart](#quickstart)** · **[MCP](#as-an-mcp-server-claude-code-cursor-any-mcp-client)** · **[Fleets](#multi-tenant-fleets)**
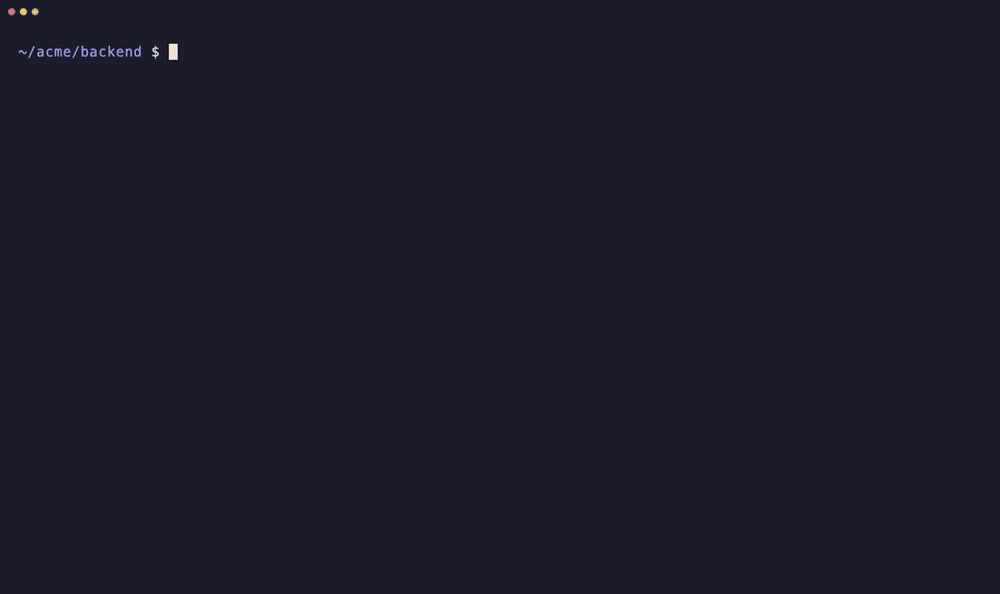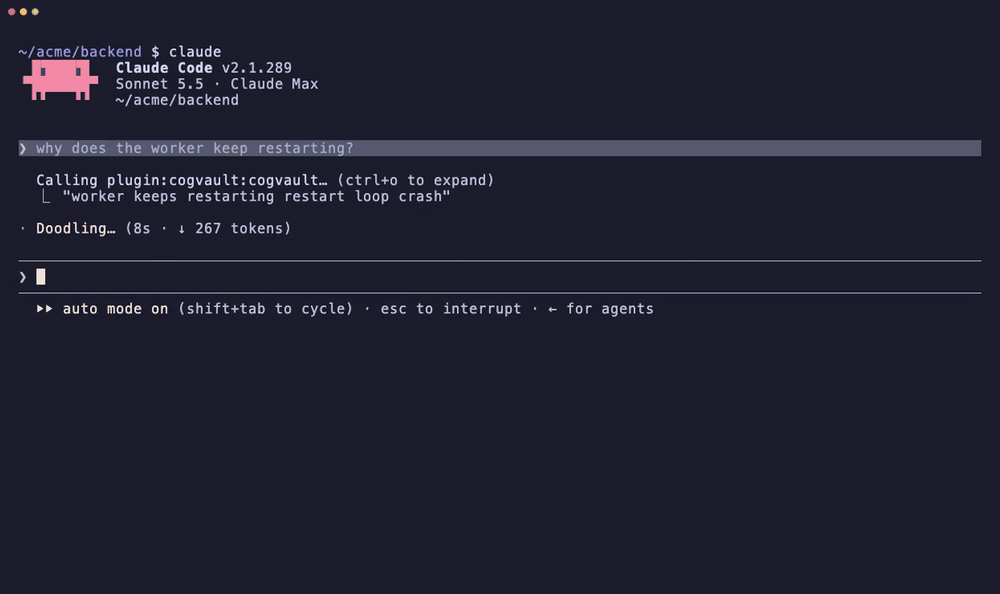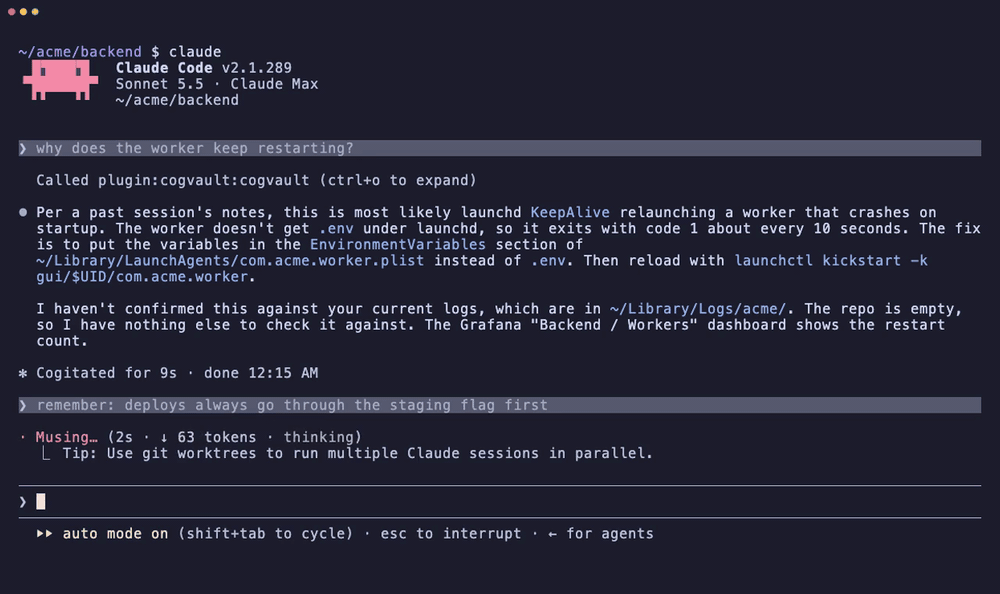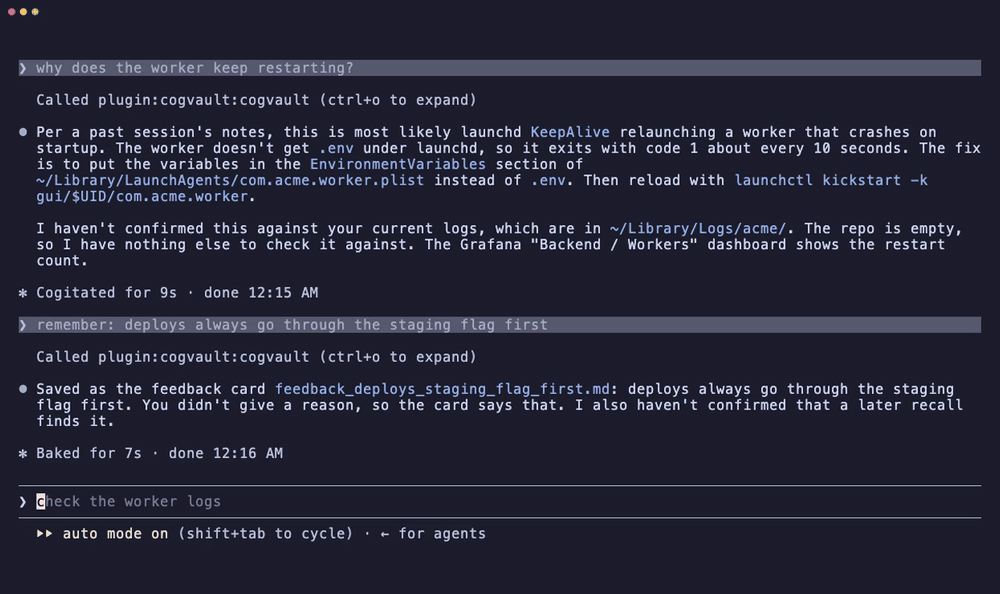 Unedited answers from a real session (Sonnet, plugin installed, a demo memory of six
cards); only the waiting time is cut.
---
## Why
Most "AI agent memory" tools want to be an autonomous LLM daemon that summarizes your
work into an opaque database or a graph you can't read. For a fleet of coding agents
that just need to *reliably recall a decision, a bug fix, or an infra detail*, that's
the wrong trade.
`cogvault` makes the opposite bet:
- **Your Markdown files are the source of truth.** Open them, edit them, `git diff`
them. The SQLite index is a derived cache — delete it and it rebuilds from the files.
- **One library, many tenants.** Each agent gets an isolated memory namespace via its
own directory. A process loads each embedding model once and shares it across
every tenant it touches; with the stdio MCP server that means one small process
per agent session, not a central daemon.
- **No LLM in the loop.** Ingest and retrieval are deterministic. Your agent *is* the
LLM — it doesn't need a second one to remember.
- **Local, private, offline.** [FastEmbed](https://github.com/qdrant/fastembed) runs
on-device. Nothing leaves your machine.
## Compared to
Checked against each project's README and docs on 2026-10-05.
| | cogvault | [basic-memory](https://github.com/basicmachines-co/basic-memory) | [mem0](https://github.com/mem0ai/mem0) | [Graphiti](https://github.com/getzep/graphiti) | [Letta Code](https://github.com/letta-ai/letta-code) |
|---|---|---|---|---|---|
| Source of truth | Markdown files | Markdown files | Vector DB (Qdrant / pgvector) | Graph DB (Neo4j, FalkorDB, …) | Markdown in a git repo per agent |
| LLM needed to store or recall | No | No (optional reranker) | Yes by default (`add()` extracts facts) | Yes to ingest | Yes — the agent edits its memory |
| Retrieval | Vector + BM25, RRF, decay, MMR | Full-text + vector, optional rerank | Semantic + BM25 + entities | Semantic + BM25 + graph | File search; hybrid optional |
| Infra | One process, SQLite file | One process, SQLite (Postgres optional) | Library, or Docker + Postgres server | A graph database | Letta backend |
**Pick something else when:** you want an LLM to distil and merge facts for you (mem0),
relationships between entities are the point (Graphiti), you want the agent to manage its
own memory (Letta), or you want a richer notes app around the same Markdown idea, with
Obsidian sync and a hosted option (basic-memory — the closest to cogvault).
**Pick cogvault when:** you run several agents and want each one's memory isolated in its
own directory behind one process; you want recall to be deterministic and offline; and you
want to *measure* it — `cogvault eval` scores recall on your agents' real queries and
`cogvault analyze` lists what they tried to recall and couldn't.
## How it works


