---
### Without a docs server
- LLMs hallucinate API signatures that don't exist
- Entire files dumped into context — 3,000–15,000 tokens per doc
- Architecture decisions buried across dozens of files
- Every repeated lookup pays full context cost
### With Gnosis MCP
- `search_docs` returns ranked, highlighted excerpts — typically 300–800 tokens
- Real answers grounded in your actual docs, not guesses from training data
- One local index across hundreds of files — instant multi-doc search
- **5–10× token savings** per lookup when your corpus covers the question
---
## What makes gnosis-mcp different
- **Your data stays on your machine.** SQLite by default, PostgreSQL at scale — nothing leaves the host.
- **Index anything that's docs-shaped.** Markdown, git commit history, crawled websites — one index, one search API.
- **Measured, not marketed.** Ships BEIR SciFact numbers (0.671 nDCG@10 — within 1 % of the Lucene BM25 baseline), a reproducible eval harness (`gnosis-mcp eval`), and a chunk-size sweep showing where the quality plateau actually sits.
Full side-by-side vs Context7 / docs-mcp-server / mcp-local-rag: [gnosismcp.com#compare](https://gnosismcp.com/#compare).
---
## Features
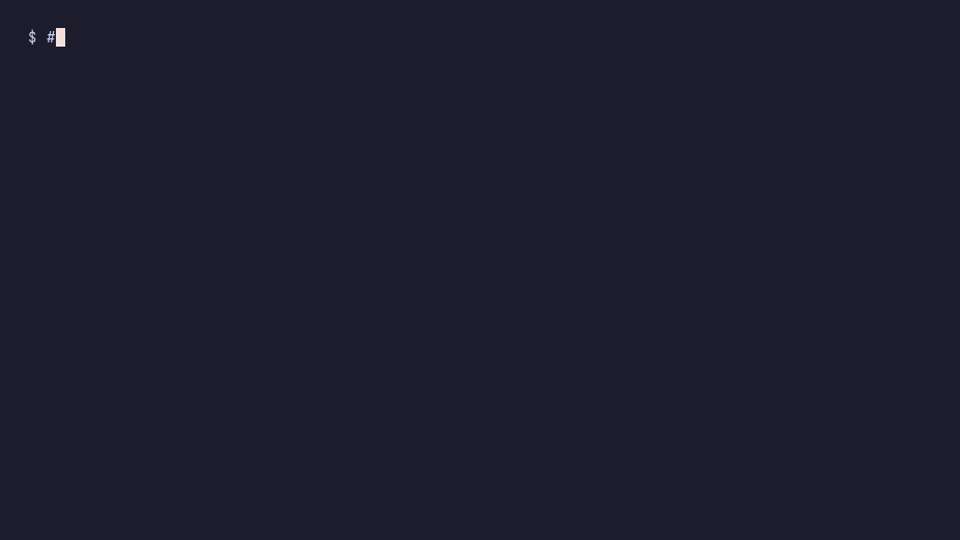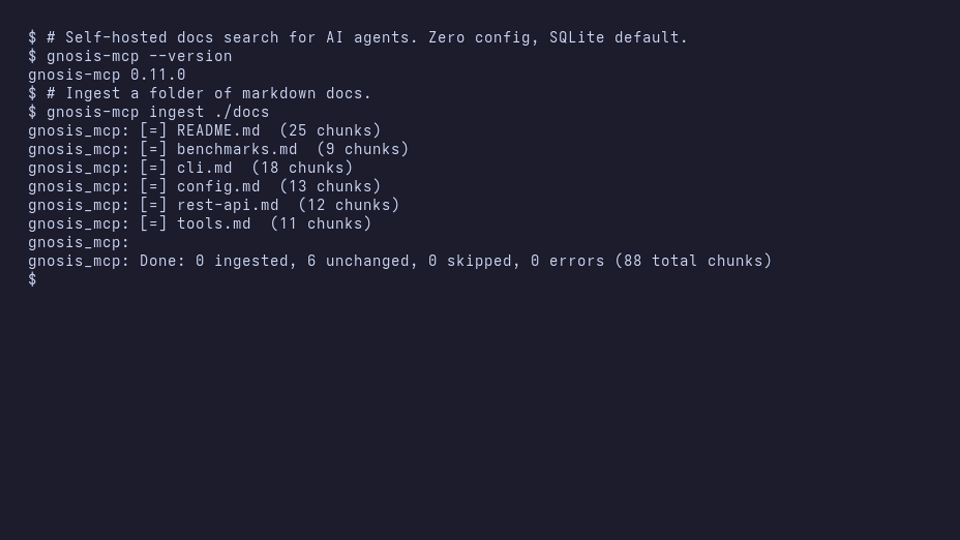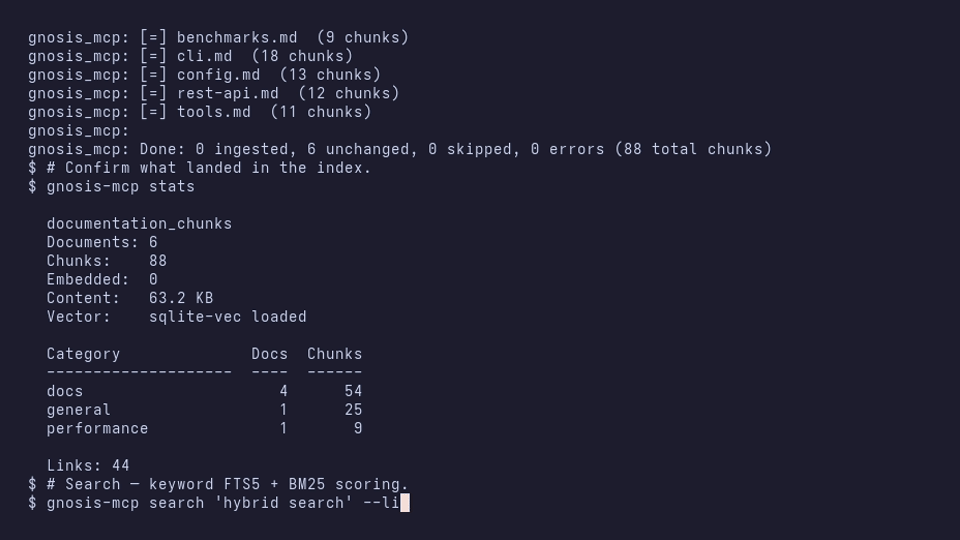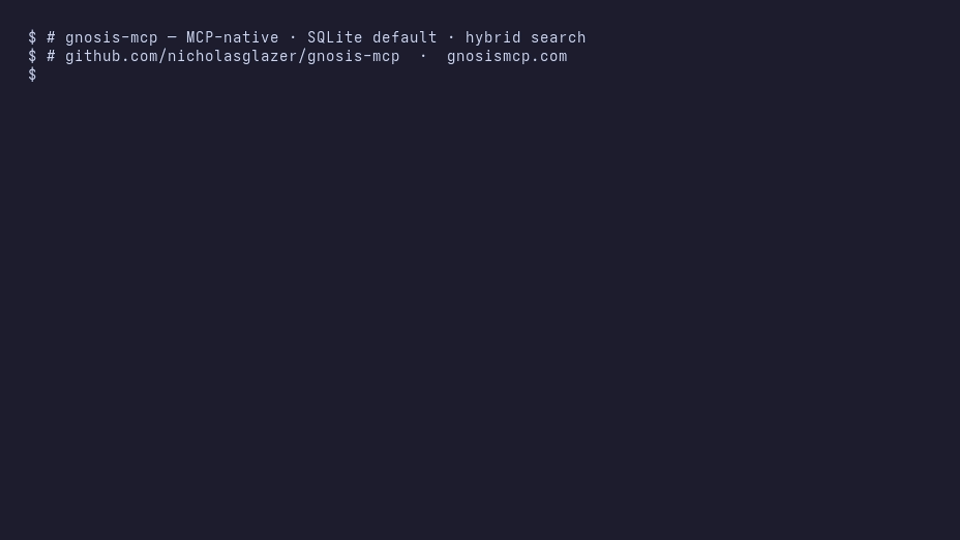
- **Zero config** — SQLite by default, `pip install` and go
- **Hybrid search** — keyword (BM25) + semantic (local ONNX embeddings, no API key). Tune RRF fusion with `GNOSIS_MCP_RRF_K`.
- **Cross-encoder reranking** — optional `[reranking]` extra with a 22M-param ONNX model. Off by default. **[Test on your own corpus before enabling](https://github.com/nicholasglazer/gnosis-mcp/blob/main/docs/bench-experiments-2026-04-18.md)** — the bundled MS-MARCO reranker hurts dev-doc retrieval in our measurements.
- **Git history** — ingest commit messages as searchable context (`ingest-git`)
- **Web crawl** — ingest documentation from any website via sitemap or link crawl
- **Multi-format** — `.md` `.txt` `.ipynb` `.toml` `.csv` `.json` + optional `.rst` `.pdf`
- **Auto-linking** — `relates_to` frontmatter creates a navigable document graph
- **Watch mode** — auto-re-ingest on file changes
- **Prune stale docs** — `gnosis-mcp ingest --prune` removes chunks whose source file was deleted. `--wipe` for a full reset before re-ingest.
- **Built-in eval harness** — `gnosis-mcp eval` prints Hit@K / MRR / Precision@K in one command, against a bundled fixed fixture set
- **PostgreSQL ready** — pgvector + tsvector when you need scale
## Performance
**Fast.** 8.7 ms mean MCP round-trip. Hybrid search p50 < 30 ms on a 700-doc corpus. Keyword QPS scales from 9,463 @ 100 docs to 471 @ 10,000 docs ([full numbers](https://gnosismcp.com/#numbers)).
**Finds the right answer.** On 558 real dev docs with 25 hand-written golden queries: Hit@5 = **0.92**, nDCG@10 = **0.87**, MRR = **0.79**. On BEIR SciFact (5,183 docs, public retrieval benchmark): nDCG@10 = **0.671** — within 1 % of the Lucene BM25 baseline.
**Tokens saved.** Each `search_docs` call returns 200–500 tokens of on-point snippets instead of the 3,000–15,000 tokens a full-file Read would have cost. Track your own with `gnosis-mcp savings` (v0.12.0+) — the ledger writes to `search_access_log` on every call and aggregates per tool per `--days N`:
```
$ gnosis-mcp savings --days 7
Tool calls: 142
Tokens returned: 7,104
Tokens baseline: 231,580
Tokens saved: 224,476
Ratio: 32.6×
```
Typical compression runs 10–60× depending on corpus coverage and query specificity — verify on yours. `access_log` is on by default; `GNOSIS_MCP_ACCESS_LOG=false` opts out.
The same ledger answers the other question — **what is this corpus being asked, and where does it come up empty** — with `gnosis-mcp usage` (v0.17.4+): calls, the queries that matched nothing, which documents are served most, which have never been served, and which clients are doing the asking.
**Reproducible.** `gnosis-mcp eval` runs a bundled retrieval-quality harness locally in one second — but it ingests nine hardcoded sample documents into a temporary database and answers ten bundled queries, so it returns the same numbers for every corpus and is a smoke test, not a measurement of your docs. To score your own corpus, run `python tests/bench/bench_real_corpus.py --corpus