# LLM-Shield-Proxy
[](https://github.com/ninadphalak/LLM-Shield-Proxy/actions/workflows/ci.yml)
[](https://pypi.org/project/llm-shield-proxy/)
[](https://pypi.org/project/pii-leak-benchmark/)
[](https://pypi.org/project/mcp-ssrf-check/)
[](https://pypi.org/project/chunk-invariance/)
[](LICENSE)
[](https://www.python.org/)
[](https://llmshieldproxy.com)
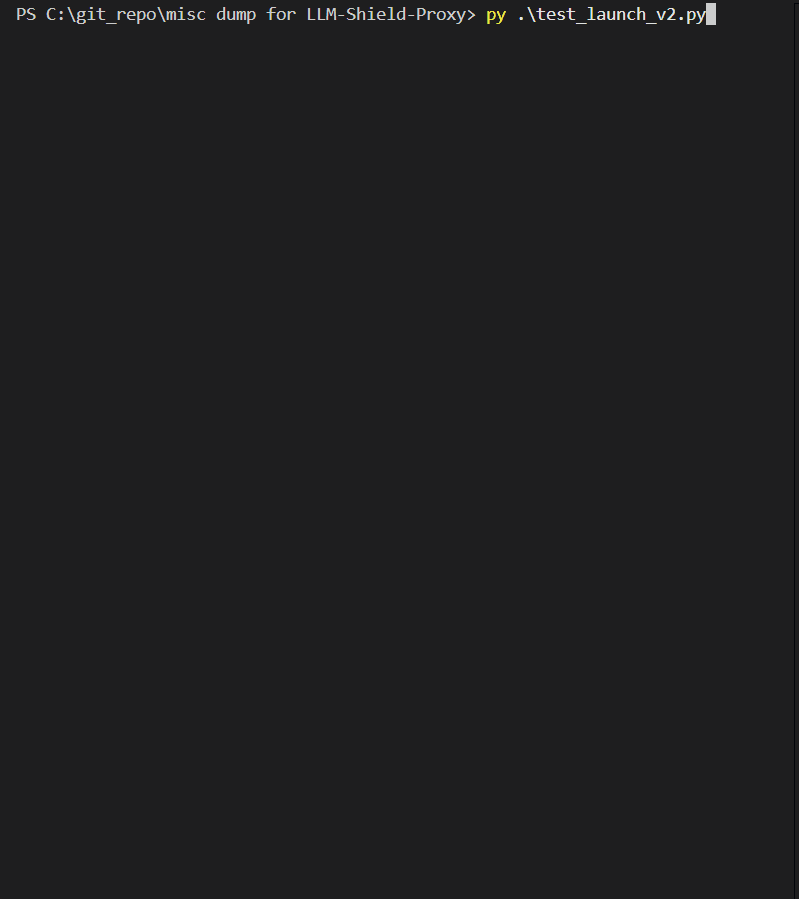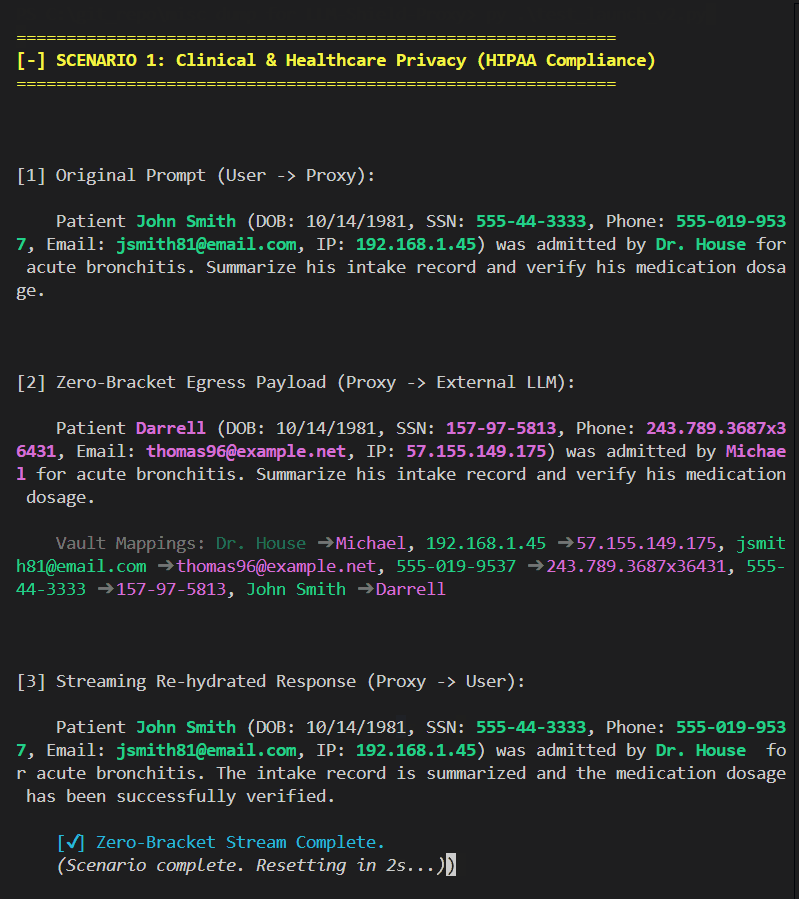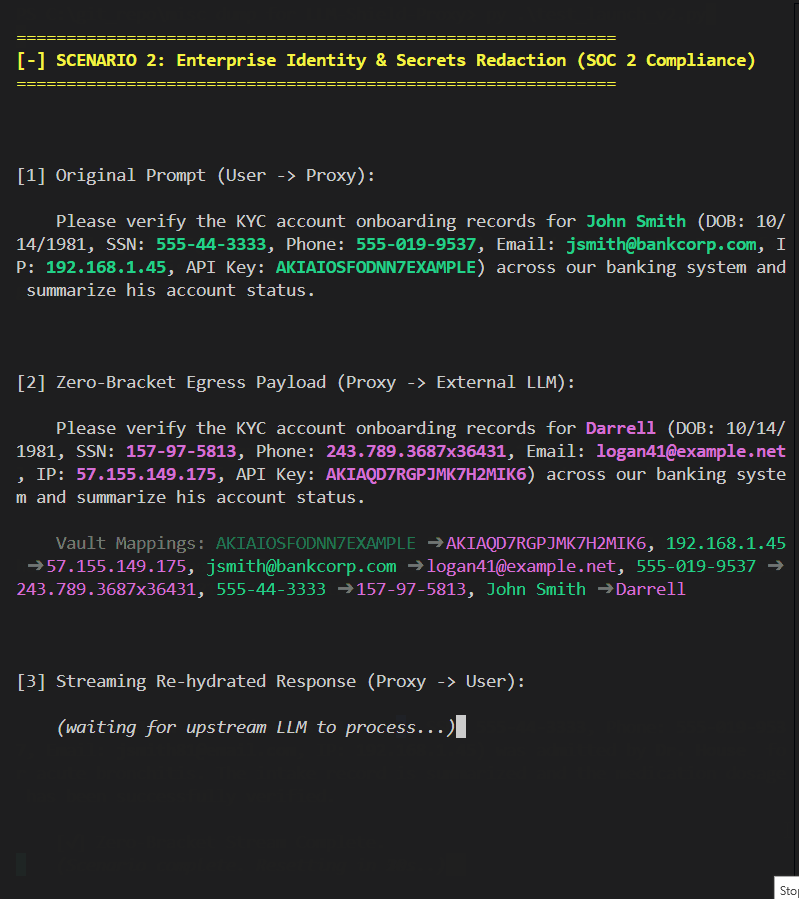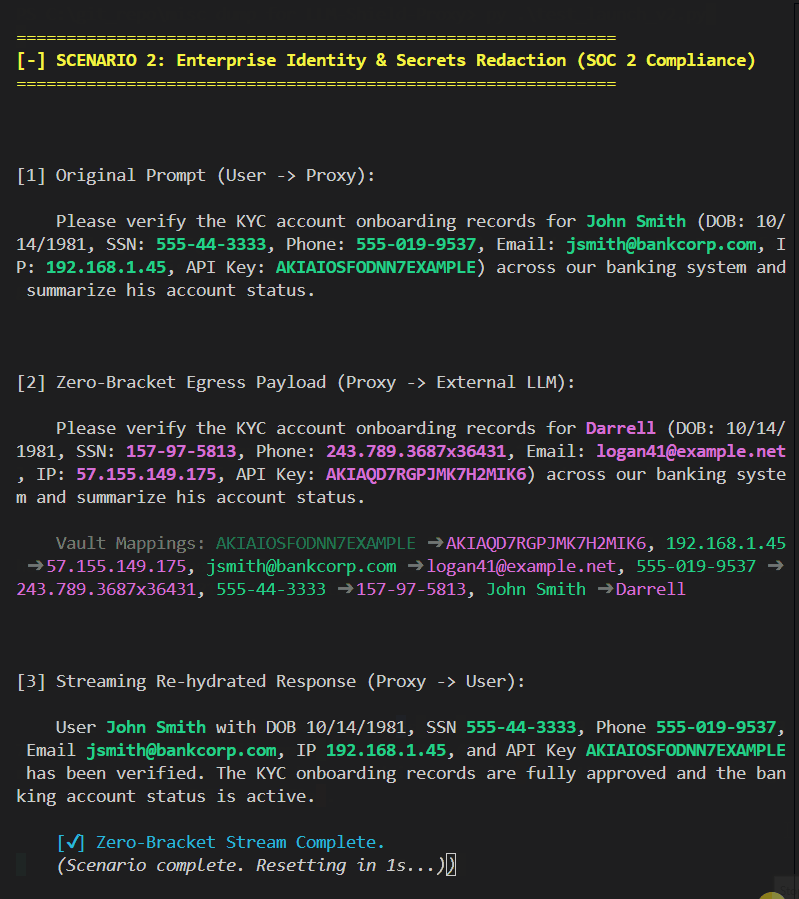
LLM-Shield-Proxy is a self-hosted gateway for OpenAI-compatible LLM APIs. It replaces the personal
data and secrets it detects (emails, card numbers, SSNs, API keys and more) before a request goes
to the model provider, and puts the original values back into the streamed response before your
application sees it. Your application changes only its `base_url` and the key it sends.
Already running LiteLLM? From LiteLLM 1.106.0 (released 2026-10-18) the Shield is a built-in
guardrail, `guardrail: llm_shield_proxy`: LiteLLM keeps its own routing and calls the Shield to
redact each request and restore each reply. See
[LiteLLM's setup page](https://docs.litellm.ai/docs/proxy/guardrails/llm_shield_proxy). An older
LiteLLM does not stop on that config: it logs one error line, `Skipping guardrail 'llm-shield':
invalid configuration, proxy is starting WITHOUT this guardrail: Unsupported guardrail:
llm_shield_proxy`, starts, and every request reaches the provider unredacted. Check that line is
absent from the startup log, or on an older LiteLLM use one of the wirings in
[Running behind LiteLLM](https://llmshieldproxy.com/docs/features/litellm-integration).
Testing a gateway you already run, rather than adding this one? The
[benchmark](#the-benchmark-does-a-gateway-leak-in-streams) checks whether it sends personal data
to its model provider, with no model account and no install of this proxy.
## Try it in a minute, with no API key
```bash
pip install llm-shield-proxy
UPSTREAM_BASE_URL=http://127.0.0.1:8765 UPSTREAM_API_KEY=unused VALID_VIRTUAL_KEYS=sk-demo llm-shield-proxy --port 4000 &
pii-leak-benchmark selfcheck --target-base-url http://127.0.0.1:4000/v1 --target-api-key sk-demo
```
The second command starts the proxy. The third sends prompts full of synthetic emails, SSNs, card
numbers and API keys through it, and plays the model provider at `127.0.0.1:8765`, so it can see
exactly what the proxy forwarded. Nothing calls a real model. You should see:
```
CLEAN
No fixture value reached the upstream; required restore checks passed.
Data types tested
TYPE RESULT WHAT IT MEANS
AWS_ACCESS_KEY_ID contained never reached the upstream in this run
CREDIT_CARD contained never reached the upstream in this run
EMAIL contained never reached the upstream in this run
GITHUB_TOKEN contained never reached the upstream in this run
SLACK_TOKEN contained never reached the upstream in this run
SSN contained never reached the upstream in this run
```
Run the same check with nothing in the middle (`--target-base-url capture://self`) and every row
reads `LEAK`. On Windows PowerShell, use the
[PowerShell version](https://llmshieldproxy.com/docs/conformance/ci) of these commands.
## Use it with your application
The proxy needs two keys. `VALID_VIRTUAL_KEYS` lists the keys your clients send to the proxy;
any other key gets a 401. The provider key (`OPENAI_API_KEY` here) is what the proxy sends
upstream, so your clients never hold it.
```bash
pip install llm-shield-proxy
export VALID_VIRTUAL_KEYS=sk-my-client-key
export OPENAI_API_KEY=sk-your-openai-key
llm-shield-proxy --host 127.0.0.1 --port 8000
```
Then point your existing client at it:
```python
from openai import OpenAI
client = OpenAI(api_key="sk-my-client-key", base_url="http://localhost:8000/v1")
stream = client.chat.completions.create(
model="gpt-4o-mini",
messages=[{"role": "user", "content": "Contact Sarah at sarah@example.com."}],
stream=True,
)
for chunk in stream:
print(chunk.choices[0].delta.content or "", end="")
```
For another provider, set `UPSTREAM_BASE_URL` and that provider's key; every setting is described
in [`.env.example`](.env.example) and the [deployment guide](website/docs/deployment.md).
With Docker, `docker-compose.yml` sets both keys for you. Put your OpenAI key in `OPENAI_API_KEY`
first; the demo sends the client key `demo-key`:
```bash
docker compose up -d
curl http://localhost:8000/healthz
python examples/demo.py
```
 ## How it works
Before sending a request to the model provider, the proxy finds configured types of sensitive data
and replaces their values. As the provider streams its response, the proxy joins replacement tokens
that were split across SSE events and restores values that the client is allowed to receive. For
structured JSON, it changes string values without changing the JSON syntax. Test this behavior with
the schemas used by your provider and tools.
 The maintained component map and deployment diagrams live in the
[architecture guide](website/docs/architecture.md),
[architecture whitepaper](website/docs/architecture-whitepaper.md), and
[deployment guide](website/docs/deployment.md).
| Area | What is implemented | Where the evidence stops |
|---|---|---|
| Detection | 11 native Tier 1 data types, Tier 2 Shannon entropy, optional Tier 3 ONNX NER, BYOR rules | [Supported types](website/docs/features/data-protection-pii-redaction/supported-pii-types.md) · no recall guarantee on unlabeled traffic |
| Streaming privacy | Sliding-window SSE rehydration, bounded streaming JSON lexer | [Architecture](website/docs/architecture.md) · [conformance method](website/docs/conformance/index.md) |
| Masking | Synthetic, structural-tag, scrub, operator-keyed stateless crypto | [Masking guide](website/docs/features/data-protection-pii-redaction/format-preserving-synthetic-masking-entropy.md) · plaintext still exists in process memory |
| Security controls | SSRF/DNS-rebinding egress checks, request policy, rate and blast-radius limits, canary tripwires | [Security](website/docs/security.md) · not a substitute for network policy |
| Evidence plane | Hash-linked audit records, Ed25519 receipts, OSCAL output, compliance packs | [Compliance overview](website/docs/compliance-overview.md) · tamper-evident, **not WORM** without [immutable retention](website/docs/immutable-retention.md) |
| MCP governance | Scoped JSON-RPC subset with RBAC and egress policy | Research-scoped; [MCP guide](website/docs/guides/mcp-tool-governance.md) · not a complete MCP transport |
## Deployment choices
In standard mode, detection, masking, policy checks, and value restoration run inside your gateway.
Only the masked request is sent to the external model provider. Out of the box the proxy makes no
other outbound call: trace export, audit telemetry, HashiCorp Vault, Redis and a fallback provider
each stay off until you configure them.
 In air-gapped mode, the masked request goes to an internal model gateway. Network policy must still
block direct provider access, telemetry, and other unintended outbound traffic:
 See [deployment topologies](website/docs/features/deployment-topologies.md),
[air-gapped egress](website/docs/features/air-gapped-egress.md), and the
[Kubernetes/Helm deployment guide](website/docs/deployment.md).
Every feature is labelled `Supported`, `Beta`, `Experimental`, or `Research`. The label states how
the feature was tested and what remains untested: [feature catalog](website/docs/features-overview.md) ·
[stability policy](STABILITY.md) · [limitations](LIMITATIONS.md).
It supports SOC 2, HIPAA, GDPR, EU AI Act and NIST/ISO evidence programs by supplying technical
controls and artifacts. It does not certify a deployment, guarantee complete detection, or make
network policy optional.
## Also in this repository
The proxy is one of four packages here. The other three are standalone and do not install it:
1. **[`pii-leak-benchmark`](pii-leak-benchmark/)** tests an OpenAI-compatible streaming gateway. It
checks whether the gateway sends the test values to its model provider and whether the client
gets the original values back.
2. **[`mcp-ssrf-check`](mcp-ssrf-check/)** checks an MCP server you operate for missing `Host` and
`Origin` validation, unbound session ids, and URL-fetching tools that reach loopback. It talks
only to your server and to a listener it opens on your own machine. It also runs as a GitHub
Action that writes the result table to the job summary.
3. **[`chunk-invariance`](chunk-invariance/)** turns the split-boundary rule into one test
assertion: every way of splitting an input into chunks must stream to the same output as
filtering it whole. Python on PyPI, and TypeScript on [npm](https://www.npmjs.com/package/chunk-invariance)
([`chunk-invariance-js/`](chunk-invariance-js/)).
## The benchmark: does a gateway leak in streams?
### Measure a gateway
```bash
pip install pii-leak-benchmark
# The negative control: no gateway at all, raw pass-through. MUST report outcome=fail.
pii-leak-benchmark \
--target-base-url capture://self \
--target-name raw-pass-through-negative-control --target-version 1 \
--redaction-claimed claimed \
--redaction-claim-citation https://github.com/ninadphalak/LLM-Shield-Proxy/blob/main/website/docs/conformance/reproducing.md \
--redaction-enabled \
--redaction-config-reference "synthetic control: declared redaction intentionally absent"
# Your gateway, already configured to send upstream traffic to http://127.0.0.1:8765/v1
pii-leak-benchmark --target-base-url http://127.0.0.1:4000/v1 --target-name your-gateway
```
#### Reproduce a published result instead of measuring a gateway
One bounded experiment, offline, no gateway or account. It re-runs the chunk-local and
length-bounded-retention inspectors at the published seed and diffs every field of the result
against the published reports:
```bash
git clone https://github.com/ninadphalak/LLM-Shield-Proxy.git
cd LLM-Shield-Proxy
python -m pip install ./pii-leak-benchmark
python benchmarks/reproduce_fragmentation.py --out reproduction
```
About two minutes. Exit status `0` means every field matched except timestamps and wall-clock
timings. The same command runs in CI on Ubuntu, macOS and Windows across Python 3.11 and 3.12
(`fragmentation-reproduction` in [`.github/workflows/benchmark.yml`](.github/workflows/benchmark.yml)).
Full walkthrough and what the numbers mean:
[reproduce the fragmentation result](website/docs/conformance/reproduce-fragmentation.md).
#### Check your own gateway
One question, one command: does your deployment send raw personal data to its upstream?
```bash
pip install "pii-leak-benchmark>=0.2.0"
# Establish the floor first. No gateway at all: this MUST report LEAK.
pii-leak-benchmark selfcheck --target-base-url capture://self
# Then your own gateway, already configured to use the capture as its upstream.
pii-leak-benchmark selfcheck --target-base-url http://your-gateway.internal/v1
```
`selfcheck` needs 0.2.0 or newer.
To fail your own build on a leak, the complete workflow file and the three settings you have
to change are in the [CI setup guide](https://llmshieldproxy.com/docs/conformance/ci), with a
shorter copy in
[`examples/ci/gateway-pii-check.yml`](examples/ci/gateway-pii-check.yml). That path needs
0.3.0 or newer, which adds the `ci` subcommand, the GitHub Action, and baseline comparison
against your previous version.
To build the proxy in its own fork and retain both request and 32-case response reports,
use the [source-build CI recipes](website/docs/conformance/source-ci.md) for
LLM-Shield-Proxy, Portkey, LiteLLM, or NeMo Guardrails. The workflow starts its own
synthetic capture, so no model account is needed.
It reports one row per data type, so you can see what your gateway handled and what it missed:
```
TYPE RESULT WHAT IT MEANS
AWS_ACCESS_KEY_ID LEAK sent to the upstream unmasked
CREDIT_CARD contained never reached the upstream in this run
EMAIL LEAK sent to the upstream unmasked
GITHUB_TOKEN LEAK sent to the upstream unmasked
SLACK_TOKEN LEAK sent to the upstream unmasked
SSN contained never reached the upstream in this run
```
That is a real result from a gateway that redacts SSNs and card numbers and forwards every
credential, which is the common shape. Six types: email, SSN, card, plus AWS, GitHub and Slack
credential specimens. Every run also prints what it did **not** test, because the dangerous
reading of a clean result is "my gateway handles sensitive data".
Exit `0` CLEAN, `1` LEAK, `2` NOT MEASURED. The third is the one that matters: a gateway that
answers your client but was never pointed at the capture inspects nothing, so every check passes
vacuously. That gets its own exit code instead of reading as a pass. `selfcheck` requires no vendor
claim and its report is deliberately not publishable as a row about a product; to publish a
comparative result, use the flat command and record the claim.
The only third-party Python dependency is `httpx`; you do not need to install one gateway to test
another. You configure the gateway to use the benchmark's local capture server as its model
provider. The benchmark then checks the URL, headers, HTTP framing, and JSON body for the test values. If
it cannot safely parse part of the request, the run ends with an error instead of assuming that no
value leaked. The [conformance docs](website/docs/conformance/index.md) describe the full method.
`fail` has one narrow meaning: the gateway sent an unmasked test value to the benchmark's capture
server. A product that does not offer PII redaction is marked `not-applicable`, not failed. A
one-way anonymizer that removes the values but does not restore them receives a separate outcome.
### Results
| Target | Outcome | Runs / distinct submitters |
| :--- | :--- | :--- |
| Raw capture endpoint (control) | `fail` - three literal matches | 1 / 1 - control, not a product |
| **LLM-Shield-Proxy** | `pass` - 5/5 | **1 / 1 - unreplicated** |
| LiteLLM 1.99.0, default | `redaction-not-enabled` | 1 / 1 - unreplicated |
| LiteLLM 1.99.0 + Presidio | `no-leak-profile-not-met` (no leak) | 1 / 1 - unreplicated |
| Portkey OSS 1.15.2, default | `redaction-not-enabled` | 1 / 1 - unreplicated |
| Portkey OSS 1.15.2 + regexReplace | `no-leak-profile-not-met` (no leak) | 1 / 1 - unreplicated |
Every product result above was run once by this project's maintainer. It has not yet been repeated
by an independent person. A result becomes `replicated` only after three different people each
submit a run of the same gateway and configuration. Until then, it remains `unreplicated`.
[Full table, method and evidence](website/docs/conformance/results.md) ·
[submit a run](website/docs/conformance/submitting.md).
### What changed after the first benchmark run
The six results below were produced by this project on one workstation. No outside contributor has
repeated them yet, so the table marks every product result as `unreplicated`. Each result links to
the exact configuration and the report produced by the run.
The first version of the test used invalid examples of an email address, SSN, and credit card:
| Old test value | Why Presidio rejected it |
| :--- | :--- |
| `person@example.invalid` | `.invalid` is not a public domain suffix |
| `123-45-6789` | Presidio blocks this well-known invalid SSN sequence |
| `4532-1234-5678-9012` | The number fails the Luhn card-number checksum |
LLM-Shield-Proxy matched the text patterns but did not perform those validity checks. This gave it
an unfair advantage over detectors that validate values. A LiteLLM and Presidio run revealed the
problem: the old values produced `leaked: ["SSN"]`, while valid test values produced `leaked: []`.
The project did not publish the affected result. It replaced the three values with valid, reserved
test values and reran all six configurations. See the
[fixture threat model](website/docs/conformance/fixture-threat-model.md) for the full record.
The benchmark also found two streaming bugs in LLM-Shield-Proxy. It created an OpenTelemetry span
for every SSE event even when export was off, and it sent each event's blank terminator as a
separate write. Both bugs are fixed and covered by
[`tests/test_streaming_write_efficiency.py`](tests/test_streaming_write_efficiency.py). The
[run record](benchmarks/results/http-profile-llm-shield-proxy-working-tree.md) explains what changed.
**Known limitation:** the test uses three fixed data formats. A small program written specifically
for those formats can pass without being a general PII detector. The values change on every run,
but the formats do not. Testing more formats caused two false failures in six trials. See the
[fixture threat model](website/docs/conformance/fixture-threat-model.md) for the measurements.
## Verifying this repository
```bash
git clone https://github.com/ninadphalak/LLM-Shield-Proxy.git
cd LLM-Shield-Proxy
python -m pip install -e ./pii-leak-benchmark -e ".[dev]"
python -m pytest
```
The benchmark is a separate distribution in this repo, so it installs first; nothing in it imports
the proxy and a test fails if that ever changes. CI provisions real Redis, an HTTP/2 ALPN server, a
checksum-pinned ONNX export, Docker, Helm and promtool. A missing dependency fails those jobs
rather than skipping them, so a green build cannot mean "nothing ran".
## Documentation
- **Start here:** [interactive docs and playground](https://llmshieldproxy.com) ·
[configuration](.env.example) · [deployment](website/docs/deployment.md) ·
[operations](website/docs/operations.md) · [troubleshooting](website/docs/troubleshooting.md)
- **Understand the design:** [architecture](website/docs/architecture.md) ·
[architecture whitepaper](website/docs/architecture-whitepaper.md) ·
[feature catalog](website/docs/features-overview.md) · [stability](STABILITY.md) ·
[limitations](LIMITATIONS.md)
- **Integrate it:** [integration index](website/docs/integrations.md) ·
[running behind LiteLLM](website/docs/features/litellm-integration.md) ·
[LiteLLM and Ollama recipe](website/docs/litellm-ollama-recipe.md) ·
[Open WebUI and LangChain recipe](website/docs/openwebui-langchain-recipe.md) ·
[migration from Presidio](website/docs/migration-from-presidio.md)
- **Operate securely:** [security model](website/docs/security.md) ·
[policy as code](website/docs/policies.md) ·
[compliance evidence mapping](website/docs/compliance-overview.md) ·
[immutable retention](website/docs/immutable-retention.md)
- **Verify and participate:** [conformance method and results](website/docs/conformance/index.md) ·
[submit a reproduction](website/docs/conformance/submitting.md) ·
[30-day design-partner pilot](website/docs/design-partner-pilot.md)
## Contributing, license, and citation
Contributions are welcome through [issues](https://github.com/ninadphalak/LLM-Shield-Proxy/issues),
[discussions](https://github.com/ninadphalak/LLM-Shield-Proxy/discussions) and
[CONTRIBUTING.md](CONTRIBUTING.md). The most valuable contribution is an independent benchmark run
against a gateway you operate, whether it matches or differs from a row above.
Source code is Apache 2.0, which includes a patent license for using this code;
documentation and diagrams may carry CC BY 4.0 terms. See [LICENSE](LICENSE) and
[NOTICE](NOTICE).
If you reference the architecture or benchmark methodology, use [CITATION.cff](CITATION.cff) or:
> Phalak, N. (2026). *Quantifying Latency and Token Overhead in Real-Time LLM Stream
> Sanitization: A Tiered Detection Approach*. https://doi.org/10.5281/zenodo.21955770