RoboRSI
Stable, efficient, and reusable robot self-evolution in complex real-world environments.
English | 简体中文

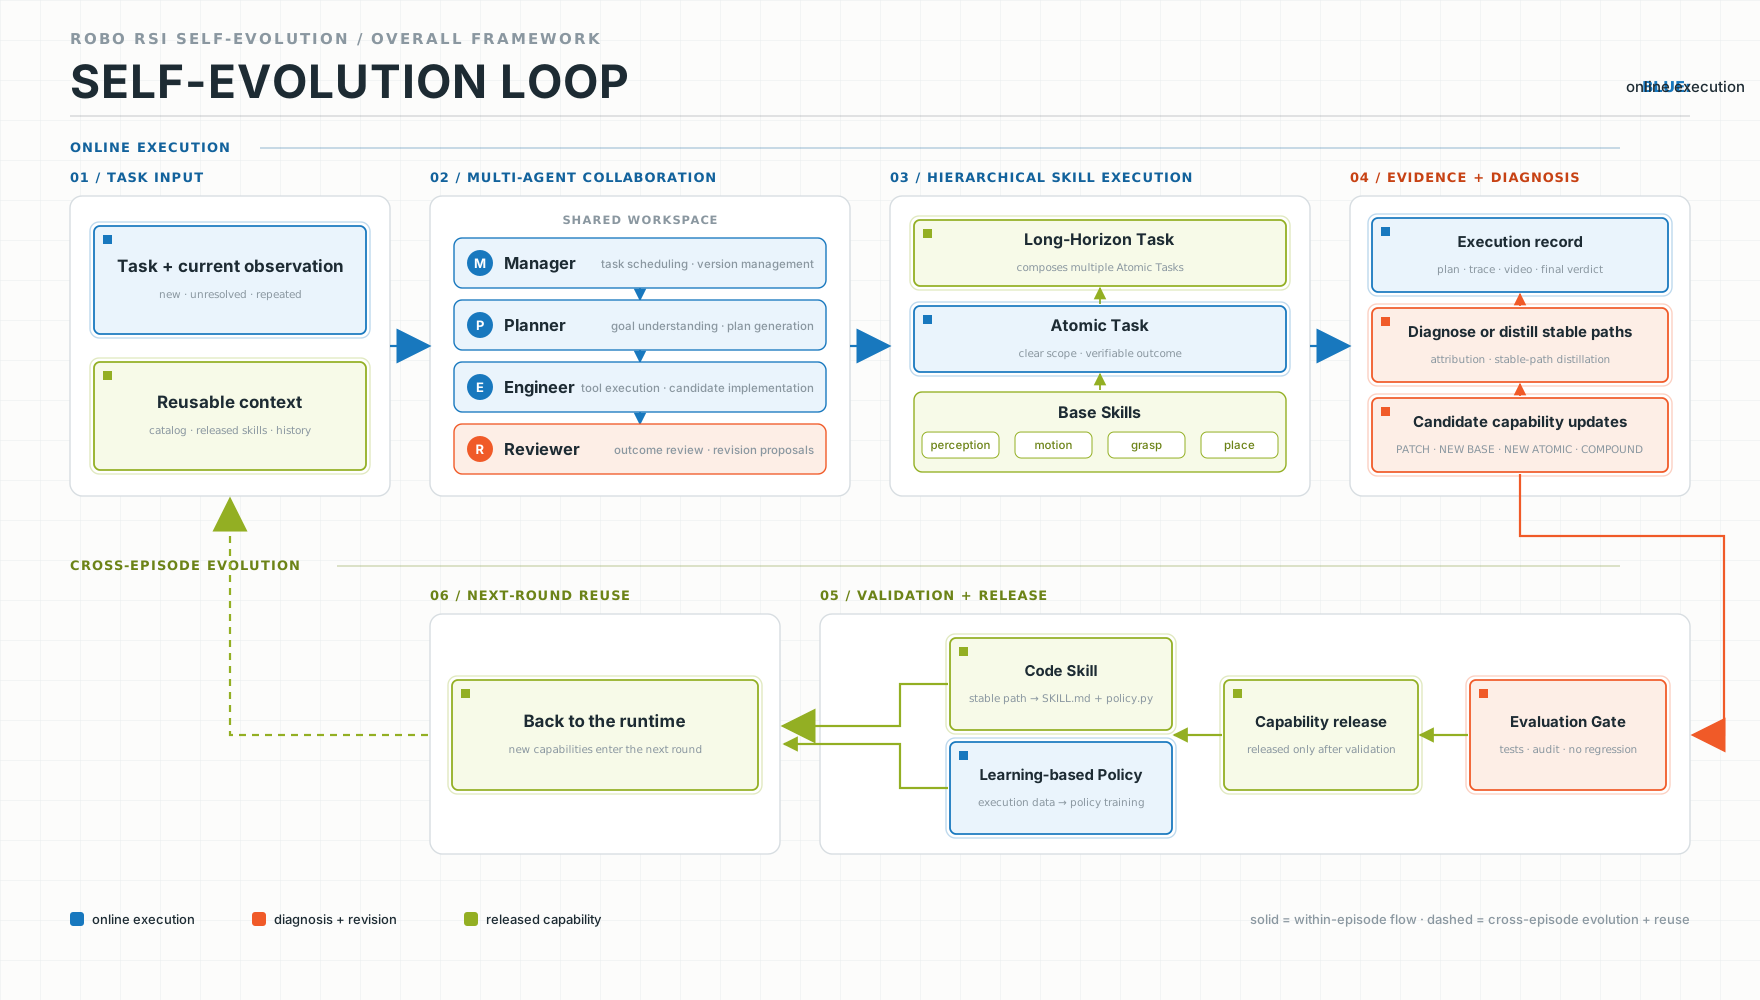
RoboRSI is a multi-agent harness for robot self-evolution. A Manager
decomposes tasks, a Planner writes executable plans, an Engineer drives
skills against the live environment, and an independent Reviewer diagnoses
the visible trace. Top-down Skill Refinement (TSR) keeps every capability in
a task–skill tree: online exploration finds a solution, stable workflows
consolidate into code, execution data can train a learning-based policy, and
failures return to the earliest responsible node.
Project page:
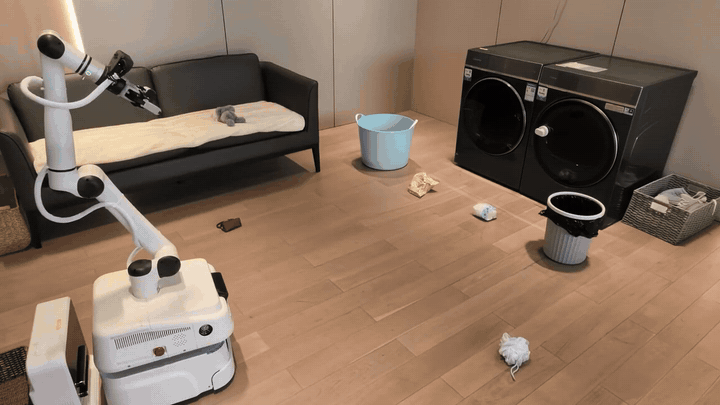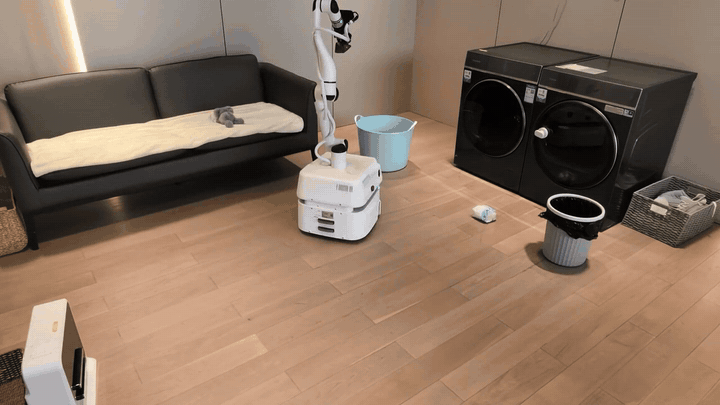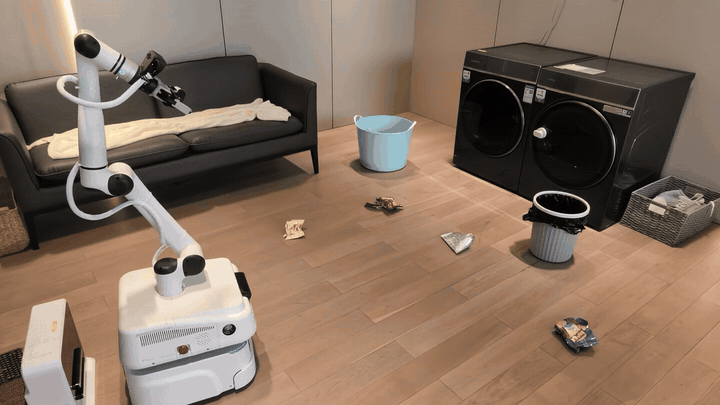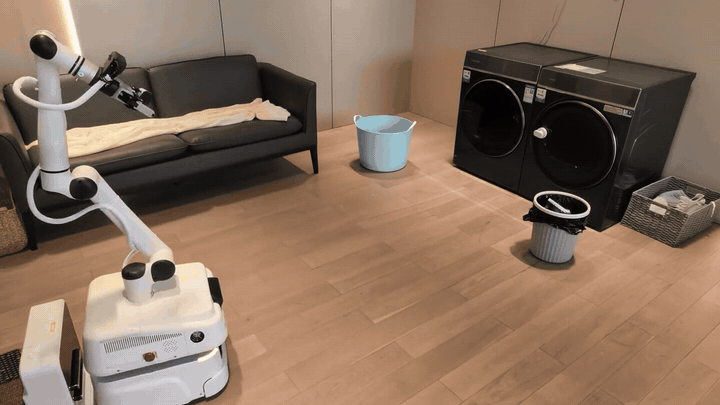
Real-robot full task chain (16× timelapse) — full video with exact tool traces on the project page
## Results
| Metric | Result | Scope |
|---|---:|---|
| LIBERO cumulative task pass rate | **95/120** | Cross-release adaptive coverage; ten sequential rounds moved 32/120 → 83/120 |
| LIBERO-PRO cumulative task pass rate | **80/120** | Five adaptive releases, 43 → 80 cumulative task coverage |
| LIBERO-Plus perturbation-instance pass rate | **398/840** adaptive Pass@2 | 840 = 7 perturbation categories × 120 instances; fixed release 261/840; +16.3 points |
| Matched Code-on / Code-off episode pass rate | **174/600 vs 129/600** | 120 tasks × 5 initial layouts per group; +7.5 points |
| Matched efficiency panel (118 tasks) | tokens **−29.4%** · VLM calls **−27.2%** · wall time **−17.0%** | Median Code-on vs Code-off |
| RoboTwin cumulative task pass rate | **36/50** | Planner + Engineer + Reviewer; single-role baseline 9/50 |
| Corrective learning-based policy case | 1 matched task success | 304-frame corrective trajectory → 2,432 samples → 1,000-step fine-tune |
Cumulative task pass rates count tasks passed at least once across evolving
releases; they are not frozen-policy scores or fixed-method Pass@k. Full
calibers, videos, and exact tool traces are on the
[project page](https://lab.noematrix.ai/blog/2-roborsi-research-preview/).
## How It Works
```
long_horizon// task family: user instruction → ordered atomic sequence
▼
atomic// atomic task: clear scope, verifiable outcome; stable
▼ paths consolidate into code (e.g. visual_pick_place)
base/// base skills: perception, motion, grasp, place —
callable by atomics and exposed to the agent as tools
```
```
Manager ──► Planner ──► Engineer ──► Reviewer
task queue plan.md tool loop root cause + revision proposal
```
When a task keeps failing, the Reviewer locates the earliest responsible
node and proposes a skill change; a no-regression gate on a real simulator
task must pass before the change is committed. Every applied change is an
ordinary git commit, so the history stays auditable.
Evaluation (`roborsi eval` / `eval-suite`) runs the same role chain against a
frozen release with self-evolution and persistent write-back disabled.
Success is decided only by the simulator's own predicate after the agent
loop ends; journals are append-only, and `roborsi eval-audit` recomputes
scores independently.
## Installation
### One-click reproduction
```bash
git clone --recursive https://github.com/nssmd/RoboRSI.git && cd RoboRSI
export OPENAI_API_KEY="..." # any OpenAI-compatible Responses endpoint
scripts/reproduce_libero_pro.sh
```
The script creates an isolated environment, installs RoboRSI, clones
LIBERO-PRO, downloads the official perturbation assets from
[`zhouxueyang/LIBERO-Pro`](https://huggingface.co/datasets/zhouxueyang/LIBERO-Pro),
configures and health-checks the backend, starts the PyRoKi IK/trajectory
service, launches a frozen Pass-1 campaign, and audits the journal.
It is idempotent and resumable. A fresh campaign evaluates the current
frozen release; it does not replay the cumulative results above
(see [docs/EVALUATION.md](./docs/EVALUATION.md)).
### Manual installation
See [docs/INSTALLATION.md](./docs/INSTALLATION.md) and
[docs/DOCKERINSTALLATION.md](./docs/DOCKERINSTALLATION.md).
LIBERO-Plus (840 perturbation instances, frozen): `scripts/reproduce_libero_plus.sh` (see [docs/EVALUATION.md](./docs/EVALUATION.md)).
Connecting your own robot: see [roborsi/embodied/embodiment/README.md](./roborsi/embodied/embodiment/README.md).
```bash
pip install -e ".[libero]"
git clone --depth 1 https://github.com/Zxy-MLlab/LIBERO-PRO.git
hf download zhouxueyang/LIBERO-Pro --repo-type dataset --local-dir ./LIBERO-PRO-assets
roborsi libero configure \
--root ./LIBERO-PRO \
--bddldir ./LIBERO-PRO-assets/bddl_files \
--initdir ./LIBERO-PRO-assets/init_files
roborsi libero doctor --backend libero --task libero_object/0 --reset
roborsi web # evolution dashboard :8787
```
## Community
Scan to join the WeChat user group (the QR code is refreshed periodically):
## Citation
```bibtex
@misc{noematrix2026roborsi,
author = {{Noematrix Team}},
title = {RoboRSI: Stable, Efficient, and Reusable Robot Self-Evolution in Complex Real-World Environments},
year = {2026},
month = sep,
howpublished = {Research Blog},
url = {https://lab.noematrix.ai/blog/2-roborsi-research-preview/}
}
```