# slimctx — the token optimizer for AI agents
[](https://github.com/omkar9854/token_optimizer/actions/workflows/ci.yml)
[](https://pypi.org/project/slimctx/)
[](https://registry.modelcontextprotocol.io/?search=token_optimizer)
[](LICENSE)
[](pyproject.toml)
[](pyproject.toml)
**Zero-dependency, fully-reversible context compression for AI agents.**
slimctx compresses what your agent reads — tool outputs, logs, JSON, source
files, prose — before it reaches the LLM. Same answers, fraction of the
tokens. Pure Python stdlib: no ML models, no downloads, no network calls,
ever. Auditable end to end in ~1,600 lines.
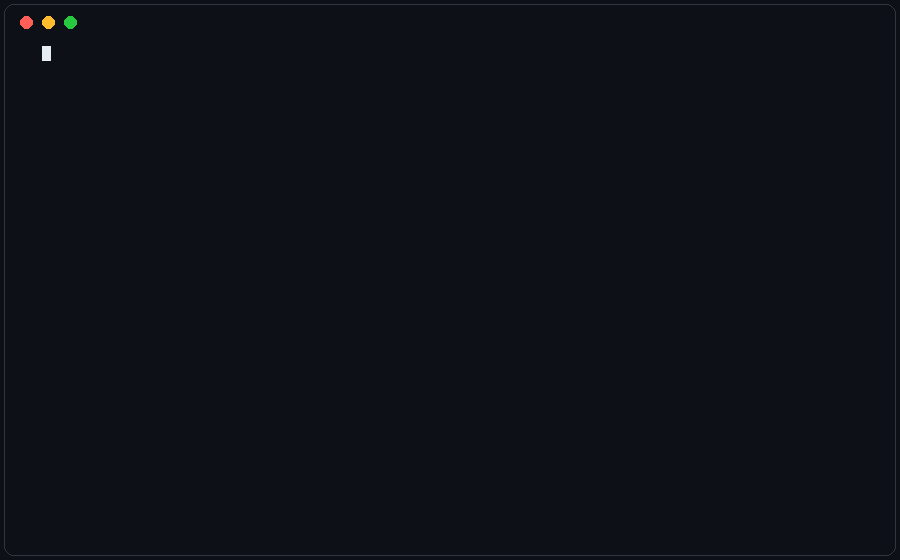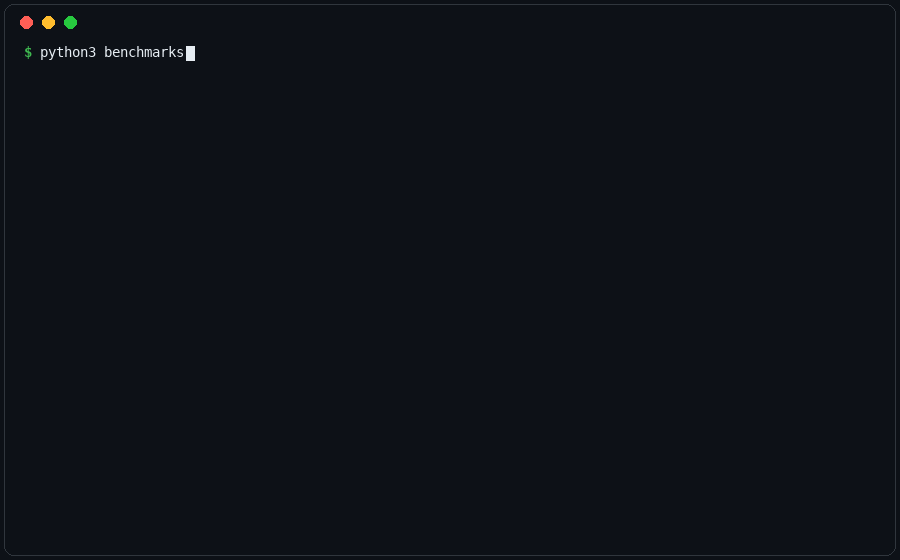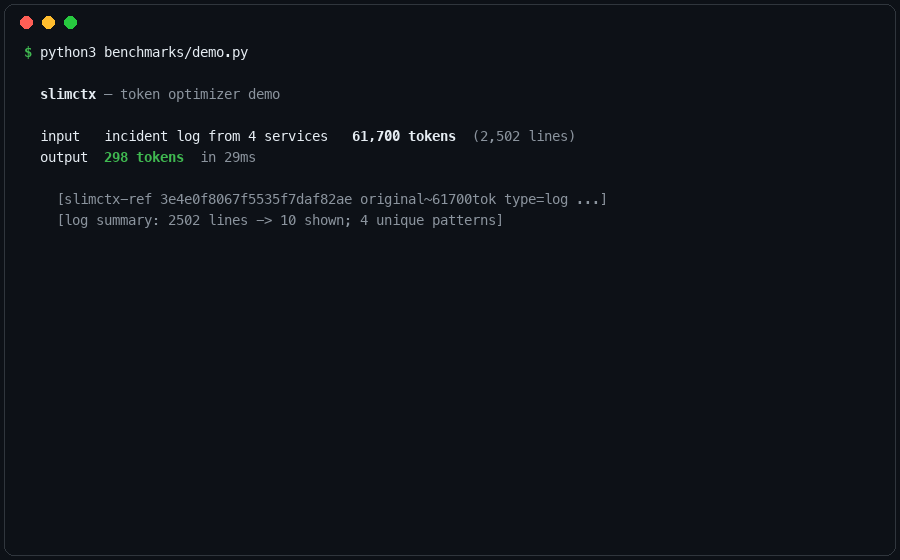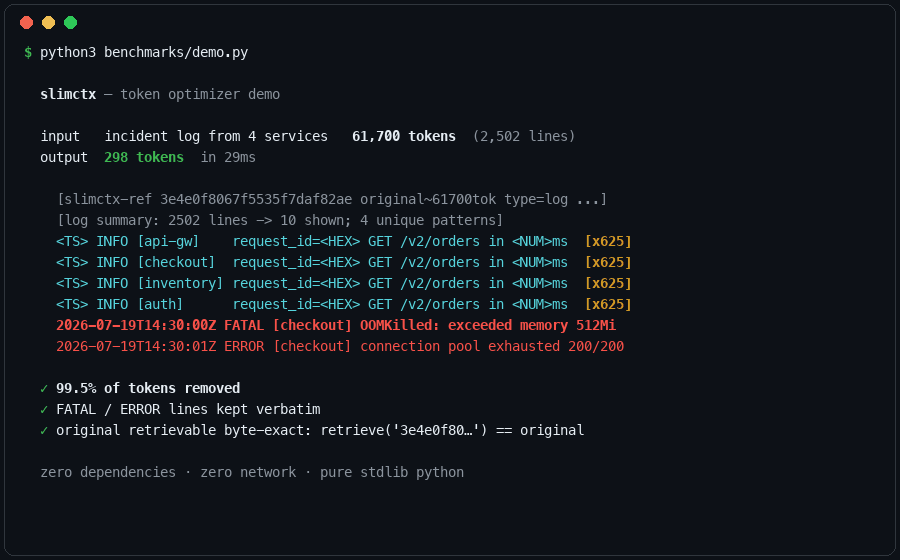
Live output of python3 benchmarks/demo.py — run it yourself, nothing is staged.
```python
from slimctx import Pipeline, Config
pipe = Pipeline(Config(target_tokens=32_000))
result = pipe.compress(messages) # OpenAI/Anthropic-style dicts
print(result.savings_ratio) # e.g. 0.82
original = pipe.retrieve("a1b2c3d4...") # byte-exact original, any time
```
## Results (synthetic workloads modeled on real agent traffic)
| Workload | Before | After | Savings | Key facts kept |
|----------------------------|-------:|-------:|--------:|:--------------:|
| Code search (100 results) | 5,557 | 916 | **84%** | ✓ |
| SRE incident debugging | 61,699 | 298 | **100%** | ✓ |
| GitHub issue triage | 12,836 | 975 | **92%** | ✓ |
| Codebase exploration | 5,734 | 2,760 | **52%** | ✓ |
Every run also verifies that each planted "needle" (the FIXME, the OOMKill,
the outlier) survives compression, and that every lossy transform is
byte-exact reversible. Reproduce with `python3 benchmarks/bench.py`.
## How it works
```
messages ──► ContentRouter ──► one of:
├─ JSON : lossless tabularization (repeated keys → header,
│ constant columns → legend), then relevance-ranked
│ row selection only if still over budget
├─ LOG : Drain-style template mining — repeated lines
│ collapse to `pattern [x1432]`; errors verbatim
├─ CODE : AST skeleton — signatures + docstrings kept,
│ bodies elided EXCEPT those relevant to the query
└─ TEXT : extractive sentence selection (BM25 + salience
+ position), verbatim, never paraphrased
```
### The four guarantees
1. **Universal reversibility.** Before *any* lossy transform, the original
goes into a content-addressed store (memory / SQLite / bring-your-own
cipher) and the output carries a `[slimctx-ref ...]` marker. The
model — or you — can always get the byte-exact original back.
2. **Errors are never dropped.** Every compressor pins error/warning
content: log errors pass verbatim, salient JSON rows are kept, salient
sentences outrank filler.
3. **Deterministic output.** Same input → byte-identical output, across
runs and processes. Compressed prefixes stay stable, so provider
prompt-caches (Anthropic/OpenAI) keep hitting.
4. **Net gain or no-op.** If a transform doesn't save enough tokens to pay
for its marker, the original is kept untouched. The live zone (system
prompt + last N messages) is never modified at all.
## Why not just use Headroom?
[Headroom](https://github.com/headroomlabs-ai/headroom) is the established
project in this space and is more featureful today (provider proxy with SSE
streaming, agent wrappers, cross-agent memory, an ML compression model).
slimctx makes a different set of trade-offs, aimed at locked-down /
client-site deployments:
| | Headroom | slimctx |
|---|---|---|
| Reversibility | JSON only (CCR); dropped text is gone | **every** lossy transform |
| Log handling | generic text scoring | **template mining** (`[x1432]` collapse) |
| Code handling | AST skeleton | AST skeleton **+ query-relevant bodies kept** |
| Dependencies | Rust core, ONNX runtime, 261MB HF model | **stdlib only** |
| Network egress | HuggingFace pull on first run | **none, ever** |
| Store encryption | none (plaintext SQLite) | **cipher hook** (bring your own) |
| Determinism | cache-aligner component | **by construction** (pure functions + memo) |
| Audit surface | ~10s of KLOC across 3 languages | **~1,200 lines of Python** |
If you need the proxy/wrap ecosystem, use Headroom. If you need something
you can read in an afternoon, run air-gapped, and certify for a client
environment, use slimctx.
## Install / test
```bash
pip install slimctx # from PyPI — or vendor the slimctx/ directory
python -m pytest tests/ -q # 26 tests: invariants, not examples
python3 benchmarks/bench.py # reproduce the numbers above
```
## Integration sketches
**As a library (any framework):** call `pipe.compress(messages)` right
before your provider SDK call; expose `pipe.retrieve` as a tool named
`retrieve` so the model can pull originals.
**As an MCP server (GitHub Copilot, Claude Code, Cursor, ...):** ships
built in, stdlib-only:
```bash
python3 -m slimctx.mcp_server --db ~/.slimctx/store.db
```
See [USAGE.md](USAGE.md) for the GitHub Copilot (`.vscode/mcp.json`) setup
and a security deployment checklist.
**Encrypted store:**
```python
from cryptography.fernet import Fernet # optional, your choice
f = Fernet(key)
store = SqliteStore("ccr.db", cipher=(f.encrypt, f.decrypt))
pipe = Pipeline(store=store)
```
## License
Apache-2.0. Original implementation — no code derived from Headroom.