# Optifeed Radar
[](https://www.npmjs.com/package/optifeed-radar)
[](https://github.com/optifeed/optifeed-radar/actions/workflows/ci.yml)
[](LICENSE)
[](https://nodejs.org)
[](https://glama.ai/mcp/servers/optifeed/optifeed-radar)
[](https://skills.sh/optifeed/optifeed-radar/optifeed-radar)
**Open-source AI visibility checker. Now on npm - run it with `npx optifeed-radar`.**
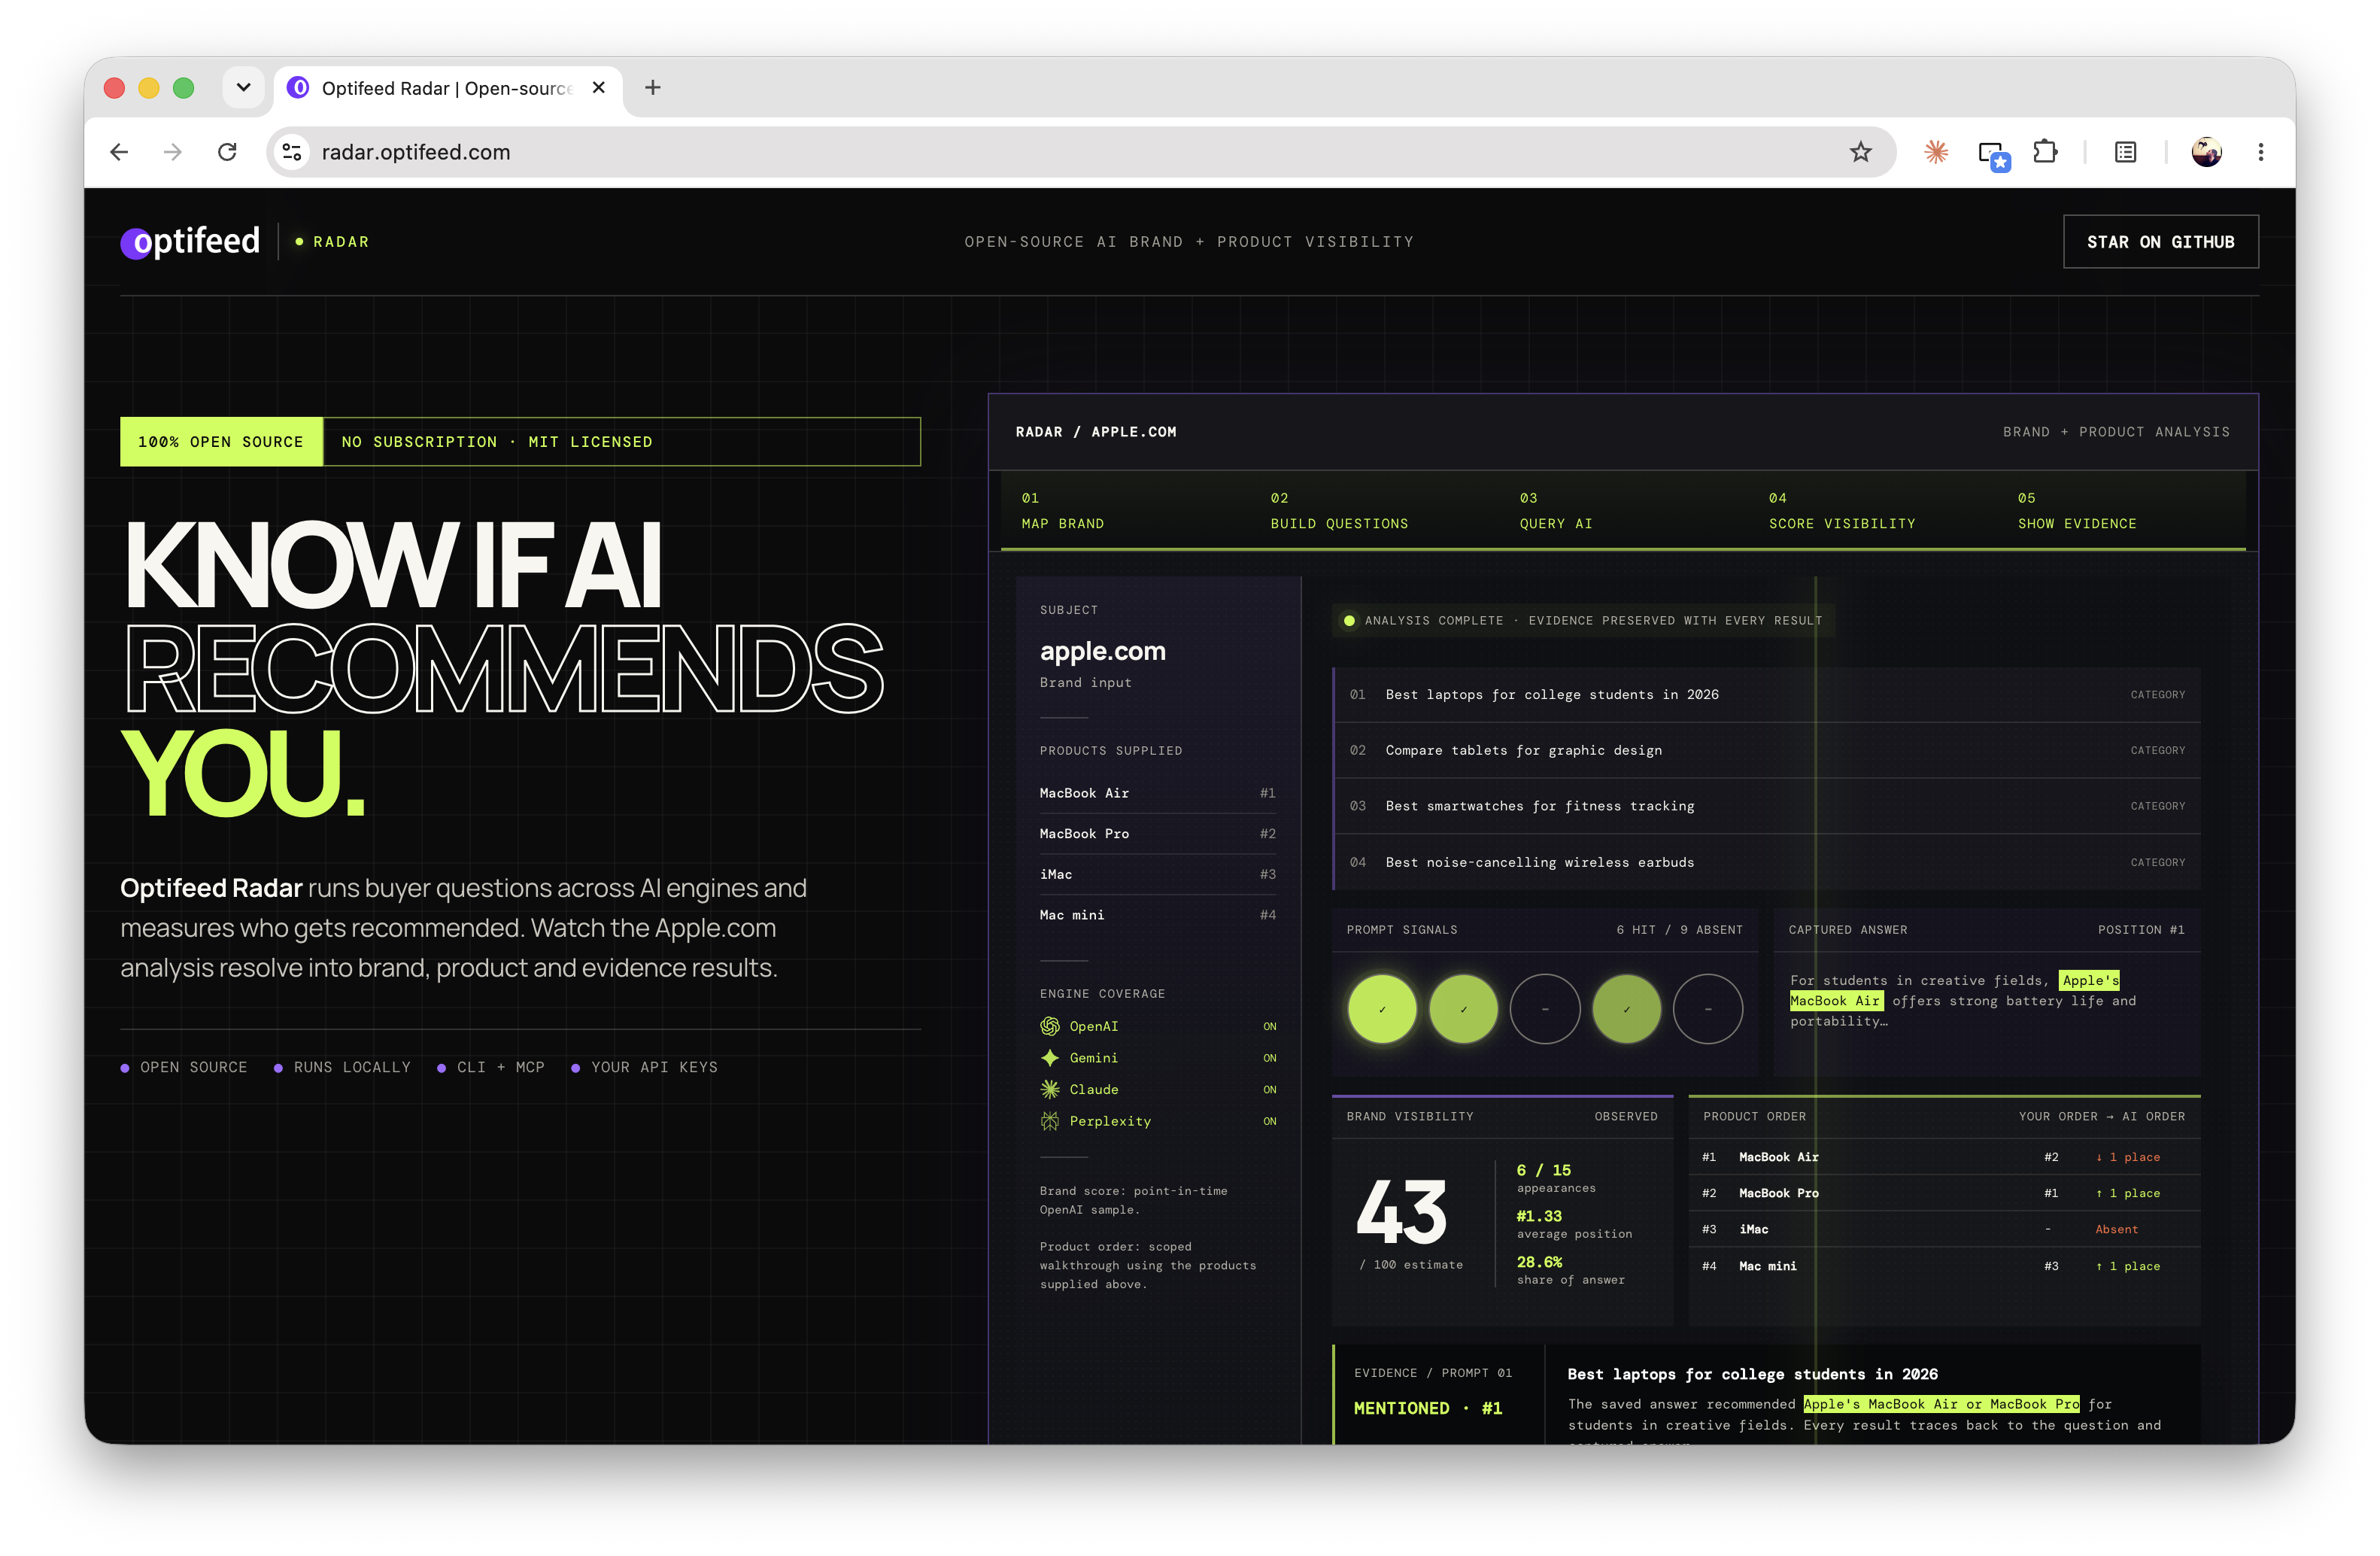
Is your brand recommended when buyers ask AI? Optifeed Radar checks whether the
models behind ChatGPT, Perplexity, Gemini and Claude actually recommend you, and
tells you where you stand against competitors. It runs locally, uses your own
API keys, and has no Optifeed-hosted backend.
It is built for two kinds of AI agents at once: it measures how **AI agents**
see and recommend you, and it can be **run by your own AI agents** (CLI, JSON,
and an MCP server). People also call this AI visibility, generative engine
optimization (GEO), answer engine optimization (AEO), or AI-SEO.
## 60-second setup
No install needed - `npx` fetches and runs it. The zero-key `audit` runs end
to end with no API keys and no AI calls:
```bash
npx optifeed-radar audit yourbrand.com
```
It checks AI-crawler access (robots.txt), llms.txt, schema.org structured
data, meta basics, and your sitemap, then prints a 0-100 AI-readiness score.
The `check` pipeline runs once you set at least one engine API key. Put it in a
`.env` file in the directory you run from, or export it:
```bash
echo "OPENAI_API_KEY=sk-..." > .env # any one engine key gets you started
npx optifeed-radar check yourbrand.com
```
The CLI loads `.env` from the directory you run it in, so there is no shell
setup step. Exporting the keys works too (`export OPENAI_API_KEY=...`), and an
exported key always wins over the same key in `.env`. `config` shows which
keys were found and which file they came from, never the values.
It discovers your brand, generates a buyer-prompt pack, asks the engines, and
scores recommendation, position, and share of voice into one AI Visibility
Score. The score reads only the unbranded buyer questions (did the AI surface
you unprompted); questions that name your brand are reported separately as
reputation. All four engines are verified live against their production APIs
(2026-07-20).
Working from a clone instead? Run `npx tsx src/cli/index.ts ` so flags
reach the CLI unchanged, or use the `npm run dev` script with `--` before the
arguments (`npm run dev -- check yourbrand.com --report out.html`).
## Install the Agent Skill
Radar also ships as an open Agent Skill for Codex, Claude Code, Cursor, and
other compatible AI agents. Install it directly from this repository:
```bash
npx skills add optifeed/optifeed-radar --skill optifeed-radar
```
Add `-g` to make it available across your projects. Then ask, for example:
> Use $optifeed-radar to run the free AI-readiness audit on yourbrand.com,
> explain the three highest-impact findings, and do not start a paid check.
The MCP server supplies executable tools. The Agent Skill supplies the working
method around them: start with the zero-key audit, confirm scope and cost before
paid engine calls, use a cap, and report sampling limits with the result. The
skill can also drive the CLI when MCP is not configured.
### Install the Claude Code plugin
The Claude plugin bundles the same skill and starts Radar's MCP server from the
published npm package. In Claude Code, run:
```text
/plugin marketplace add https://github.com/optifeed/optifeed-radar.git
/plugin install optifeed-radar@optifeed
```
Restart Claude Code or run `/reload-plugins`, then invoke
`/optifeed-radar:optifeed-radar` or ask Claude to audit a domain in plain
language. Node 20 or newer is required. The free audit needs no provider keys;
paid visibility checks use provider keys from Claude Code's environment.
The standalone skill and Claude plugin do not create a public ChatGPT app.
ChatGPT support will be marketed separately after Radar is packaged and tested
against OpenAI's plugin and MCP distribution route.
### See it in action
Run a full visibility check from the terminal, from brand discovery and buyer
prompt generation through live engine queries and scoring.
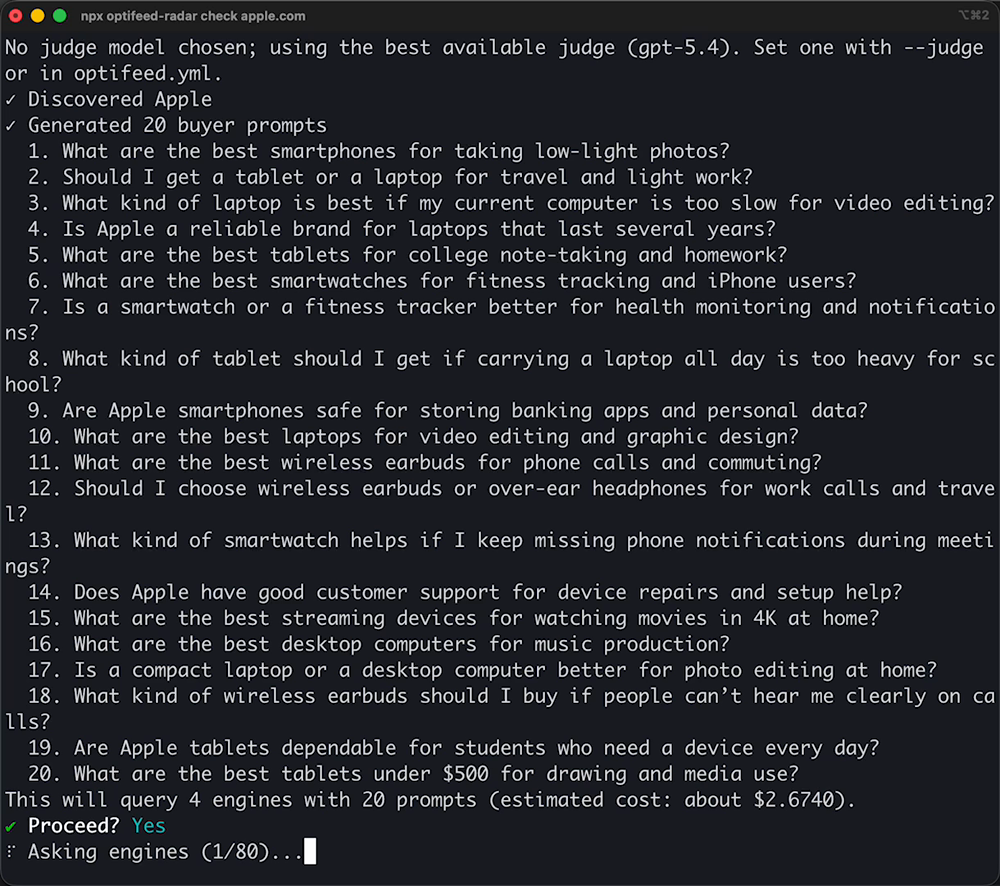
Watch the 15-second CLI demo
## What it does
Optifeed Radar asks real AI engines real buyer questions and measures whether
your brand gets recommended - not whether you rank in a search index, but
whether the answer an AI gives a buyer names you. Grounded engines (which cite
web sources) are reported separately from parametric ones (which answer from
model weights alone), because they behave differently. An engine counts as
grounded only for the answers where it actually searched: asking for grounded
mode is a request a model can decline, so the report says when an engine
searched on only some of its answers. [METHODOLOGY.md](METHODOLOGY.md) has the
formula.
The questions match what you sell. If you make your own products, buyers are
asked what to buy and you are measured against rival makers. If you are a shop
selling other companies' products, buyers are asked where to buy and you are
measured against rival shops - product questions get answered with
manufacturers, so scoring a shop on them reports a zero that says nothing about
the shop. The tool works this out from your site and stores it as
`businessType` in `profile.json`; edit it if it guessed wrong.
One level down, `shopping` does the same thing for individual products you
name (beta). Each product gets its own 0-100 visibility score, and the report
is ordered by what the engines did: any product they answered about but never
recommended leads, since that is the finding worth reading, then the rest by
visibility, and last anything the run could not measure at all. The order you
list your products in carries no ranking meaning; it only breaks ties between
identical scores. Each product is checked twice over - category
buying questions that never name it, and questions that do - and when a
product is absent the report leads with the rival products the engines named
instead, which is the more useful half of a zero. Because every product is
asked its own questions, the scores say how decisively each one wins its own
shelf, not that one product beats another. You name the products; nothing is
imported or crawled.
## Use it from your AI agents (MCP)
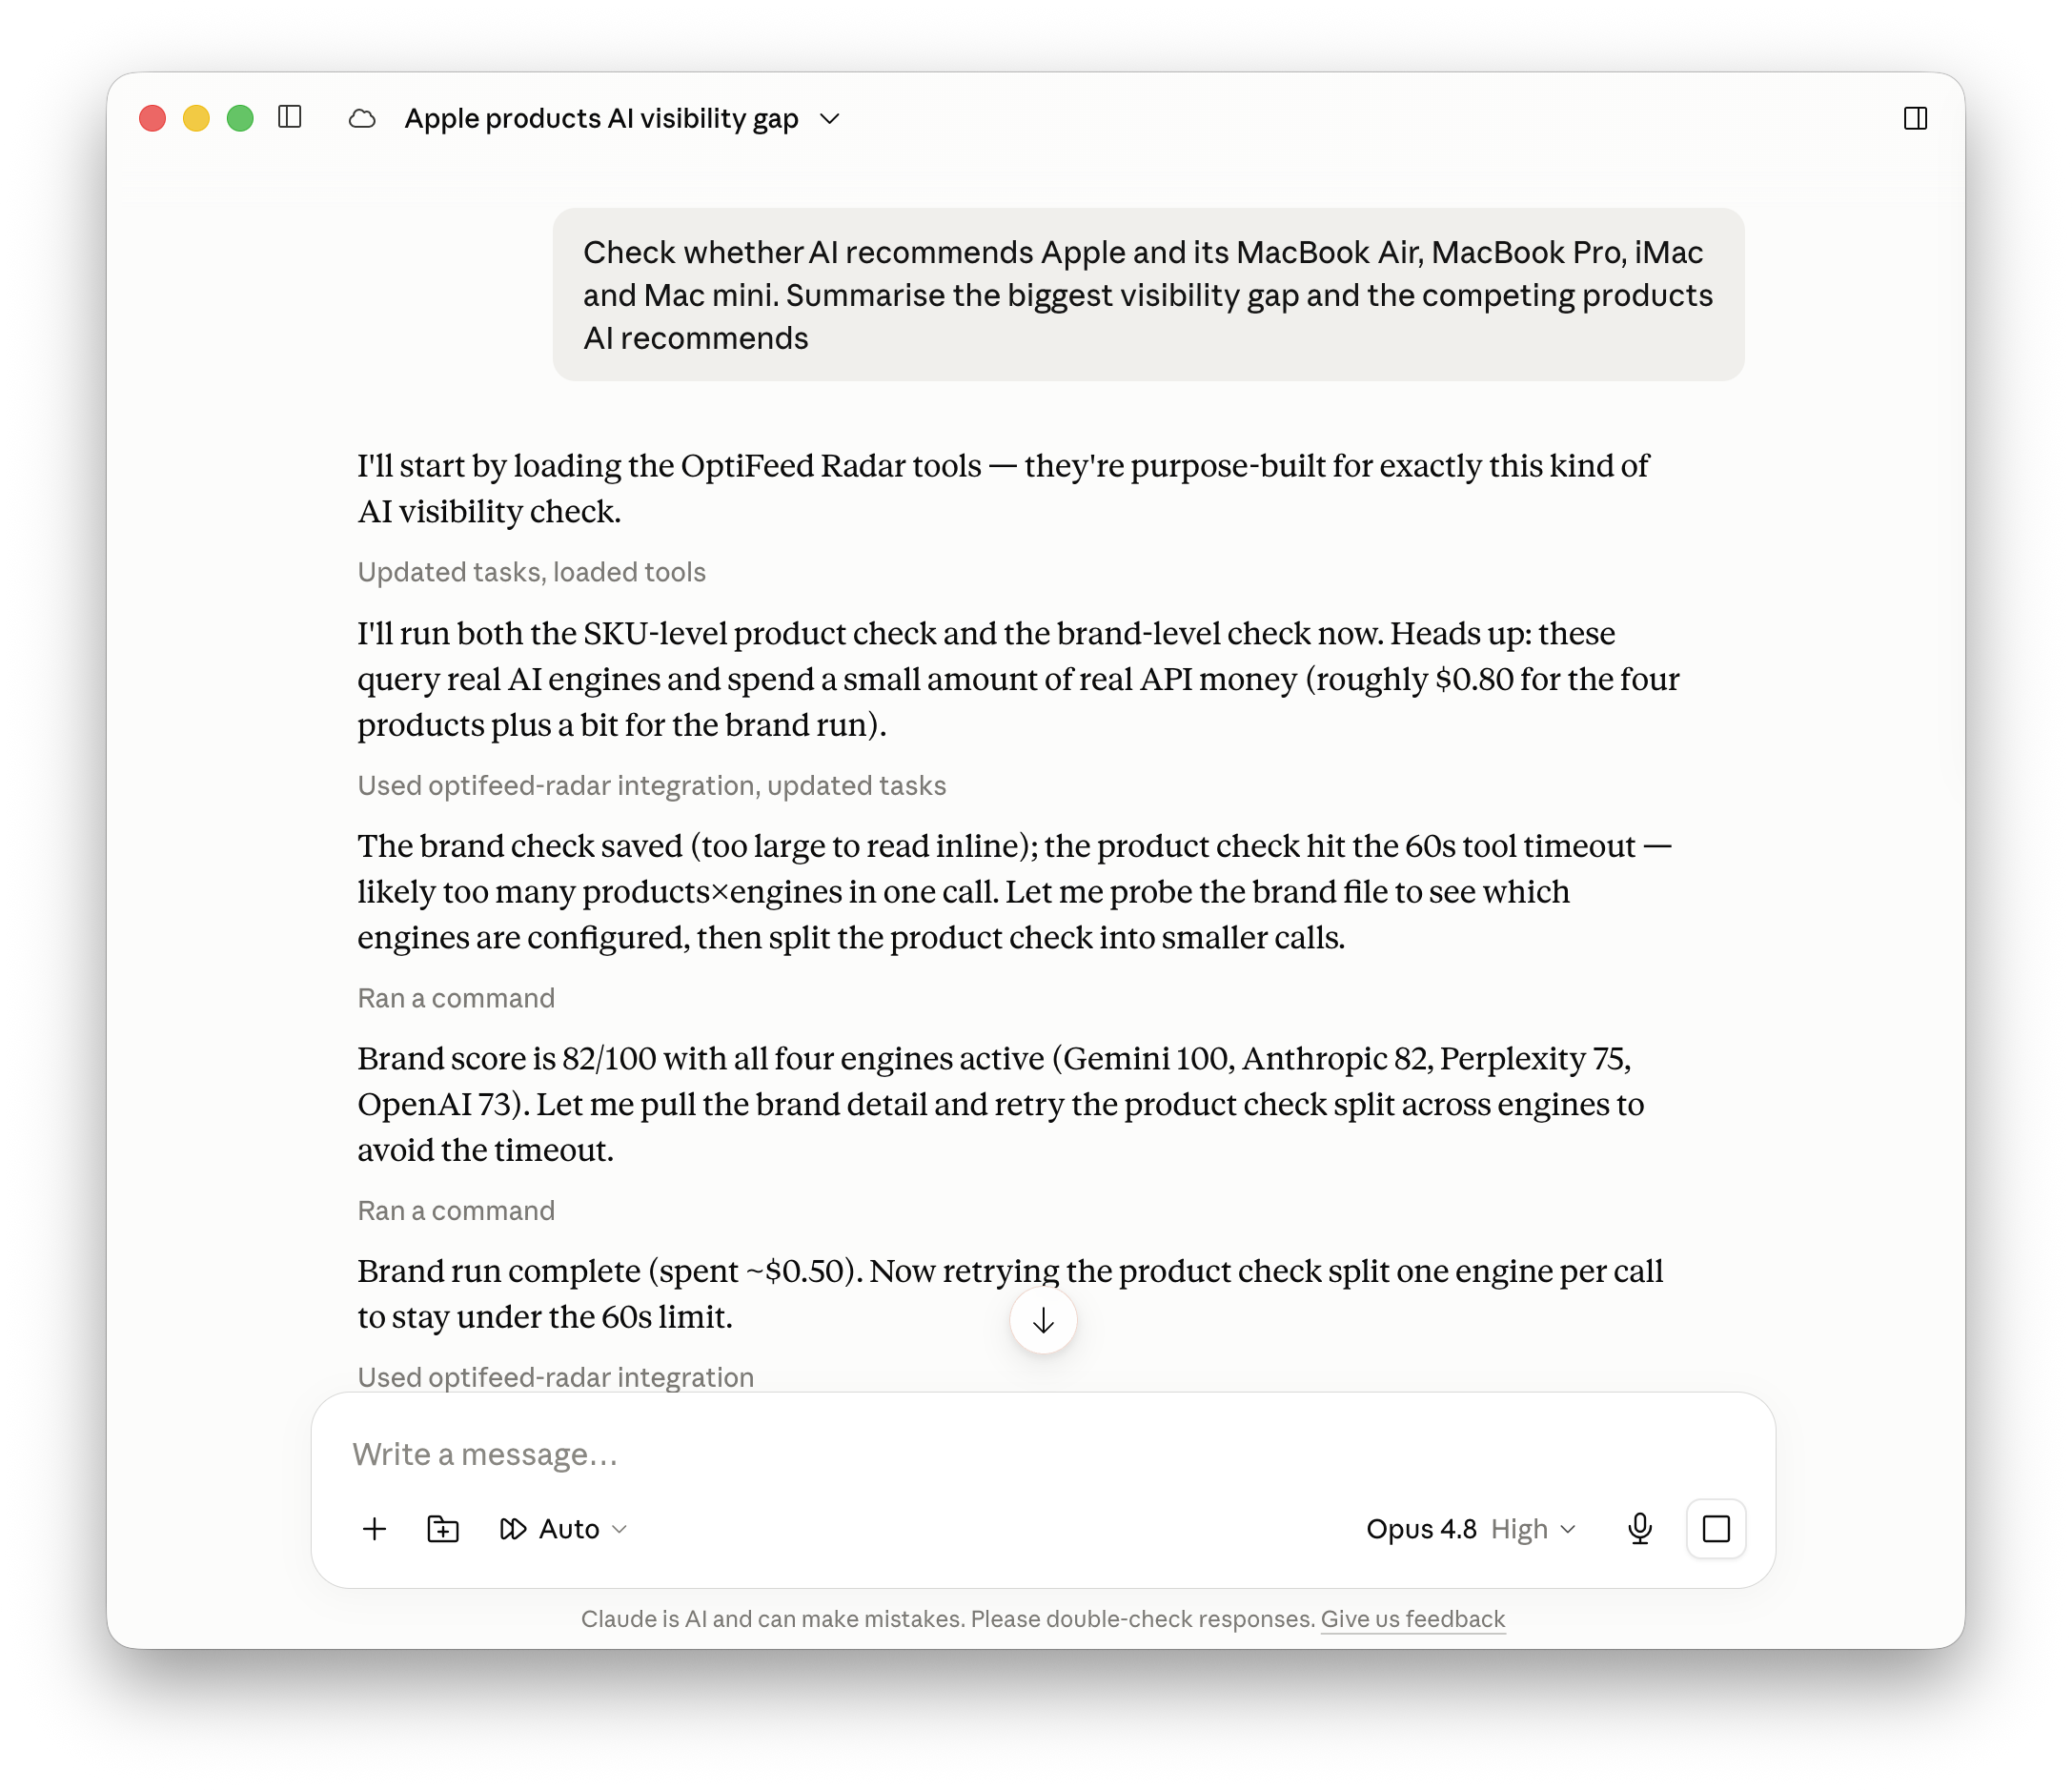
The `optifeed-mcp` server exposes the same capability to AI agents. It runs
over stdio, and `npx` fetches it on demand - no clone or build needed.
Claude Desktop (`claude_desktop_config.json`). The fastest way to open it is
Settings -> Developer -> Edit Config, which creates the file if it does not
exist yet. On disk it lives at:
- macOS: `~/Library/Application Support/Claude/claude_desktop_config.json`
- Windows: `%APPDATA%\Claude\claude_desktop_config.json`
```json
{
"mcpServers": {
"optifeed-radar": {
"command": "npx",
"args": ["-y", "--package=optifeed-radar", "optifeed-mcp"],
"env": {
"OPENAI_API_KEY": "sk-..."
}
}
}
}
```
Claude Desktop reads that file at startup, so quit and reopen it after editing.
Claude Code (`.mcp.json` in your project):
```json
{
"mcpServers": {
"optifeed-radar": {
"command": "npx",
"args": ["-y", "--package=optifeed-radar", "optifeed-mcp"]
}
}
}
```
Cursor (`.cursor/mcp.json`) and Windsurf (`mcp_config.json`) use the same
shape:
```json
{
"mcpServers": {
"optifeed-radar": {
"command": "npx",
"args": ["-y", "--package=optifeed-radar", "optifeed-mcp"]
}
}
}
```
Working from a clone instead? Build first (`npm install && npm run build`),
then run the server with `node` pointed at the built entrypoint - replace
`/path/to/optifeed-radar` with your clone path:
```json
{
"mcpServers": {
"optifeed-radar": {
"command": "node",
"args": ["/path/to/optifeed-radar/dist/mcp/index.js"]
}
}
}
```
### Example prompts
Once it is connected, ask your AI agent in plain language. These map onto the
five tools and the arguments they accept:
- "Run a free AI-readiness audit on yourbrand.com." -> `audit_store`, no keys,
no cost.
- "What buyer questions should yourbrand.com be visible for?" ->
`generate_buyer_queries`, so you can review the pack before paying for a run.
- "Check yourbrand.com's AI visibility, quick mode, cap it at 20 cents." ->
`check_visibility` with `quick` and `max_cost`.
- "Check yourbrand.com on OpenAI and Perplexity only." -> `check_visibility`
with `engines`.
- "Check whether AI recommends my products: Aria 2, Presto X, Brew Mini, in
that order, for yourbrand.com." -> `shopping_check`. Input order is not a
ranking; it only breaks ties between products with identical scores.
- "Check the Aria 2, a quiet home espresso machine, and the Presto X, a fast
dual-boiler, on yourbrand.com. Cap it at one dollar." -> `shopping_check`
with a descriptor per product and `max_cost`. Saying what each product IS is
what rescues an opaque model name: without it the questions are guessed from
the store category.
- "What changed since the last visibility run on yourbrand.com?" ->
`get_snapshot_diff`, free, and it needs two saved runs before it can compare.
Start with the audit prompt: it needs no keys, so it confirms the server is
wired up before anything spends API credit. `check_visibility` runs
non-interactively (no confirmation prompt over MCP), so the `max_cost` cap is
what bounds a run your AI agent starts - it defaults to $0.50.
`shopping_check` is bigger, so its default cap scales with the list, at $0.20
per product you name.
## Tools and cost
| Surface | Name | What it does | Cost |
| ------- | ------------------------ | --------------------------------------------------------------- | ------------------------------ |
| CLI | `audit` | Zero-key AI-readiness check (robots, llms.txt, schema, sitemap) | Free, no AI calls |
| CLI | `check` | Full pipeline: buyer prompts, engines, AI Visibility Score | BYO keys |
| CLI | `shopping` | Products you name: your ranking vs AI's, and the rival shelf | BYO keys |
| CLI | `diff` | What changed between your last two runs | Free (reads a saved snapshot) |
| CLI | `sources` | Domains the AI cited, and your share of voice | Free (reads a saved snapshot) |
| CLI | `queries` | Show or export your buyer-prompt pack | Free |
| CLI | `config` | Which engine keys are set, where state is stored | Free |
| MCP | `check_visibility` | Run a visibility check for a domain | BYO keys |
| MCP | `audit_store` | Run the zero-key readiness audit | Free |
| MCP | `generate_buyer_queries` | Produce the buyer-prompt pack | BYO keys (usually under $0.05) |
| MCP | `shopping_check` | Same product check, for your AI agents | BYO keys |
| MCP | `get_snapshot_diff` | Compare two saved runs | Free |
Cost transparency: `audit` queries no AI engines and costs nothing. `check`
spends your own API credit. Measured on real runs (2026-07-20, `--quick` =
8 buyer prompts):
| run | measured cost |
| -------------------------------- | -------------- |
| `audit` | free |
| `check --quick`, one engine | about $0.09 |
| `check --quick`, all four | $0.41 to $0.46 |
| `check --quick --grounded`, four | $0.85 to $1.09 |
Your cost varies with engine, prompt-pack size, and provider pricing. Grounded
runs cost roughly 3x parametric ones, because web search is billed on top of
tokens: Google charges per search query, and one answer can trigger several.
The grounded range spans three real runs: two finished clean at about $0.85,
and one that was reined in by its own cap spent $1.09, so treat the top of the
range as the planning number.
`shopping` was measured on 2026-07-23: two products across all four engines in
`--grounded` mode, 32 answers, **$0.70 for the run - about $0.35 per product**.
That is the expensive corner (grounded runs cost roughly 3x parametric ones),
so a parametric four-engine run lands well under it. Each product costs about
4 prompts on every engine with a key, and products in the same category share
their category questions, which are asked once and scored for each product.
The MCP tool's default cap is $0.20 per product, which a grounded run will
reach, so raise `max_cost` when you want grounded across four engines. Use
`--max-cost` and start with two or three products.
How long it takes, measured the same way (2026-07-22):
| run | measured time |
| -------------------------------- | ------------------ |
| first `npx` (install, once) | about 8 seconds |
| `audit` | 0.3 to 1.7 seconds |
| `check --quick`, four engines | 47 to 51 seconds |
| `check --quick --grounded`, four | about 97 seconds |
The install figure was measured from the packed tarball with an empty npm
cache, so a cold `npx optifeed-radar audit yourbrand.com` from the registry
should finish in about ten seconds. A `check` takes as long as the
engines take to answer: it queries
several of them across a whole prompt pack, and that wait is provider latency
we do not control. `check` reports live progress while it runs, so you can see
which phase it is in rather than watching a blank terminal.
Every run reports what it actually spent, split into setup (brand discovery
and prompt generation) and engine calls, so you can reconcile it against your
provider bill. Declining at the confirmation prompt still reports the setup
cost, because discovery runs before that prompt.
`--max-cost 0.20` caps spend. The cap is checked before every call and hitting
it returns a partial result flagged as capped, never an error. It is a strong
bound rather than an absolute ceiling: an engine's cost is not known until its
call returns, so a run can exceed the cap by at most the cost of one
unmeasured call per engine. Any overshoot is always reported, never hidden.
Useful `check` flags: `--json` (raw envelope), `--report report.html`
(self-contained report), `--max-cost 0.50`, `--quick` (smaller prompt pack),
`--grounded` (web-search mode where engines support it), `--fail-under 50`
(exit non-zero below a threshold, for CI), `--yes` (skip the cost prompt so an
AI agent can run it unattended).
A `check` that could not measure anything exits non-zero and prints why. Buyer
prompts come from one call to the judge model, so if that call fails - no API
credit, a rate limit, an unusable response - there is nothing to ask the
engines, and the run stops before spending on them rather than reporting an
empty result as a finished one. Declining the cost prompt yourself is a choice,
not a failure, and still exits zero.
## Example
```bash
npx optifeed-radar audit example.com # free readiness score
npx optifeed-radar check example.com --quick --yes
npx optifeed-radar shopping example.com --products "Aria 2, Presto X" --yes
npx optifeed-radar diff example.com # what changed since last run
npx optifeed-radar sources example.com # who the AI cited
npx optifeed-radar config # which keys are set
```
`config` reports only whether each key is present, never the key value.
For `shopping`, list up to 10 products per run in any order; only the first 10
are checked, and the report is ordered by what the engines did, not by what
you typed. A file
gives each product a descriptor, which is what rescues an opaque product
name - "Aria 2" tells an engine nothing, "quiet home espresso machine" tells
it everything:
```yaml
products:
- name: Aria 2
aliases: [Aria II]
descriptor: quiet home espresso machine
- name: Presto X
descriptor: fast dual-boiler espresso machine
```
```bash
npx optifeed-radar shopping example.com --products-file products.yml --yes
```
## FAQ
**What is AI visibility?** Whether AI engines recommend your brand when a buyer
asks them a question, rather than whether you rank in a traditional search
index. It is also called generative engine optimization (GEO) or answer engine
optimization (AEO).
**Is there an MCP server?** Yes. The `optifeed-mcp` server exposes
`check_visibility`, `audit_store`, `generate_buyer_queries`, `shopping_check`
and `get_snapshot_diff` to your AI agents over stdio.
**What does it cost?** The `audit` command is free and needs no keys. The
`check` pipeline spends your own engine API credit: measured at about $0.09 for
a quick single-engine run, $0.41 to $0.46 across all four, and $0.85 to $1.09
with `--grounded`. Every run reports what it spent, and `--max-cost` caps it. You
bring your own keys; there is no Optifeed-hosted billing.
**Where is my data stored?** Optifeed Radar runs locally, saves snapshots on
your machine, and has no Optifeed-hosted backend. Each key is sent only to its
corresponding AI provider as required to make API calls and is never logged;
prompts and responses are handled under that provider's data policies.
**Which engines does it support?** OpenAI (ChatGPT), Anthropic (Claude), Google
(Gemini), and Perplexity. Set any one key to start; set more for broader
coverage.
**Which model does each engine ask?** `gpt-5.6-sol`, `claude-sonnet-5`,
`gemini-flash-latest` and `sonar`, through each provider's API rather than the
consumer chat product. Every answer records the model that produced it, so a
saved run always says what it measured. The OpenAI model is a pinned snapshot:
a floating `-latest` alias can be repointed without notice, which would let a
`diff` show movement that came from the engine changing rather than from your
visibility changing.
**How is the score computed?** From sampling real engine answers to unbranded
buyer questions, scoring recommendation, position, and share of voice. Scores
are estimates and vary between runs. See [METHODOLOGY.md](METHODOLOGY.md) for
the full method.
## For directory maintainers
One-liners for awesome-mcp-servers, ClawHub, and Smithery listings:
- **Optifeed Radar** - Ask real AI engines real buyer questions and score
whether a brand gets recommended. CLI plus MCP server, runs locally, BYO keys.
- **Optifeed Radar (MCP)** - `check_visibility`, `audit_store`,
`generate_buyer_queries`, `shopping_check`, and `get_snapshot_diff` for
measuring brand and product AI visibility (GEO / AEO) from your AI agents.
Search intents this serves: AI visibility checker, does AI recommend my brand,
generative engine optimization (GEO) tool, answer engine optimization (AEO),
ChatGPT brand visibility, AI-SEO, MCP server for brand visibility.
## What this does NOT do
- It is a point-in-time check, not continuous monitoring.
- Scores are estimates from sampling and vary between runs - they are not a
guaranteed ranking.
- It does not find your products for you. `shopping` checks the products you
name, up to 10 per run; there is no catalog or feed import.
- `check` and `shopping` spend your own API credit; only `audit` is free.
- It is not a traditional SEO rank tracker.
Catalog discovery (pulling your products from a store or a feed) and feed
linting against the Agentic Commerce Protocol (ACP) and the Universal Commerce
Protocol (UCP) will arrive in later releases - join the waitlist at
[optifeed.com](https://www.optifeed.com/).
## Status
Under active development, and the repo is public so you can follow along. If
this is useful to you, a star genuinely helps. Scores are estimates and say so.
Your API keys are used only to call their corresponding providers and are never
logged or stored by Optifeed Radar.
## License
MIT
More at optifeed.com: