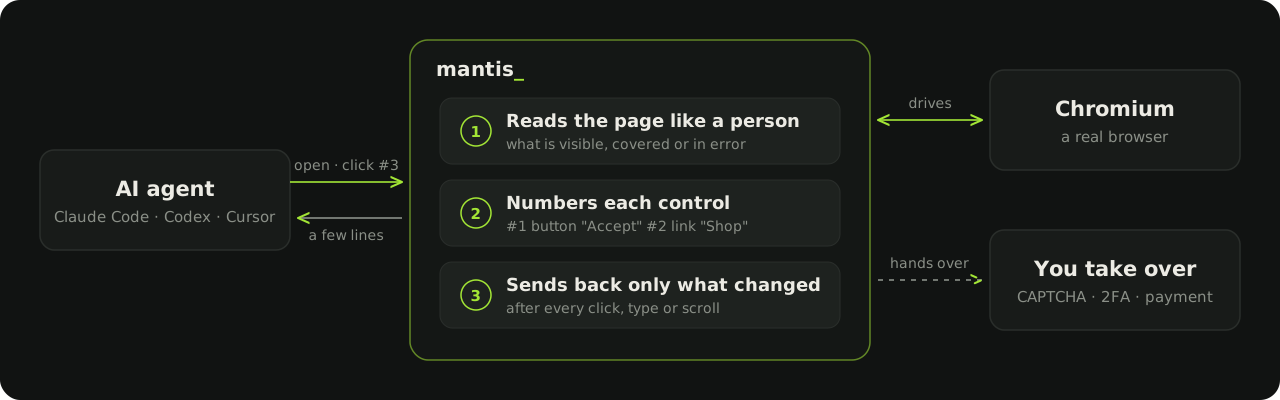
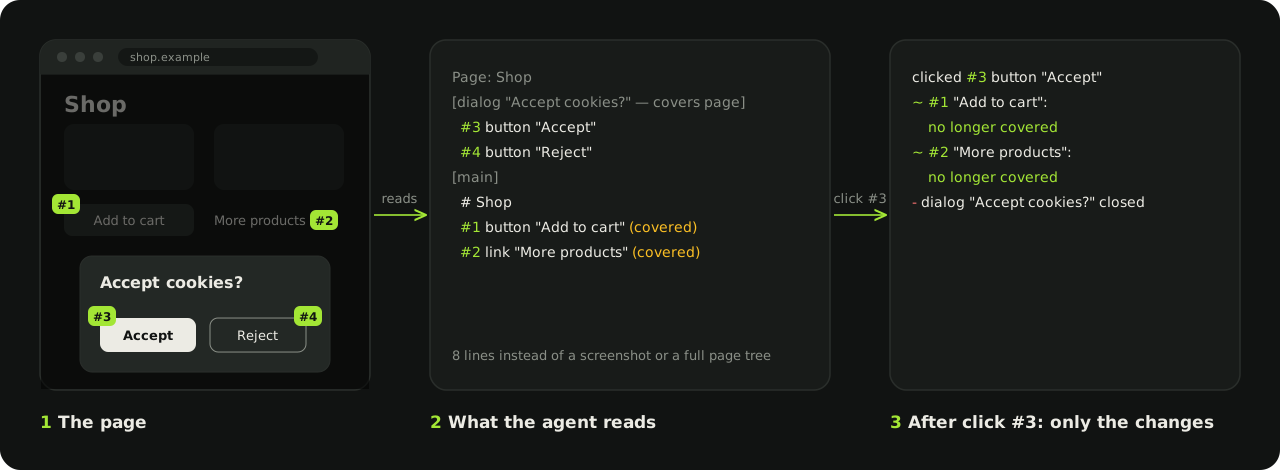
**Lets AI agents browse the web as short, numbered text instead of screenshots.**
[perzian.dev/mantis](https://perzian.dev/mantis/) · by [Perzian](https://perzian.dev)
It works with Claude Code, Codex, Cursor or your own agent as an MCP server. [Install in two commands](docs/SETUP.md#install).
```bash
npx -y -p mantis-browser mantis install
claude mcp add mantis -- npx -y -p mantis-browser mantis-mcp
npx -y -p mantis-browser mantis read https://example.com # try it without an agent
```
Windows, Linux servers and other agents: [SETUP](docs/SETUP.md#install).
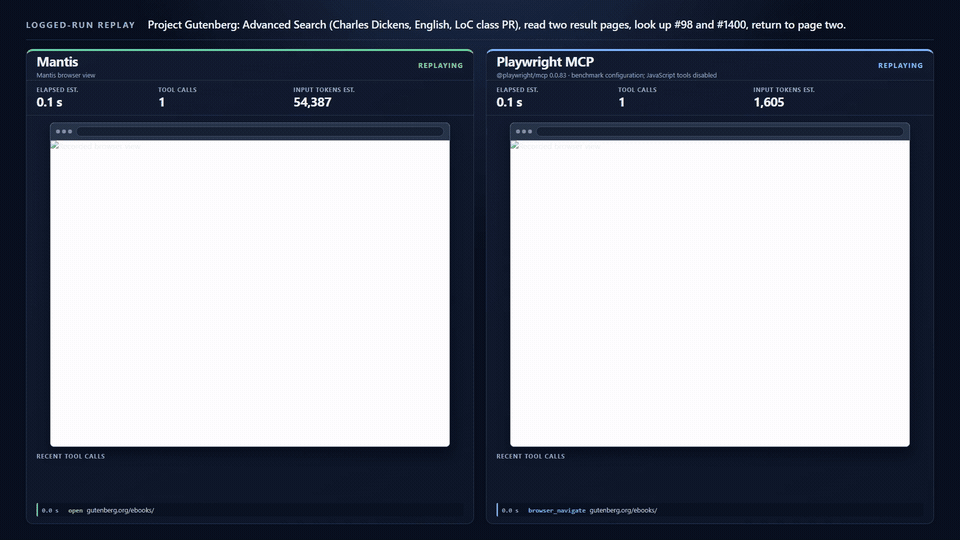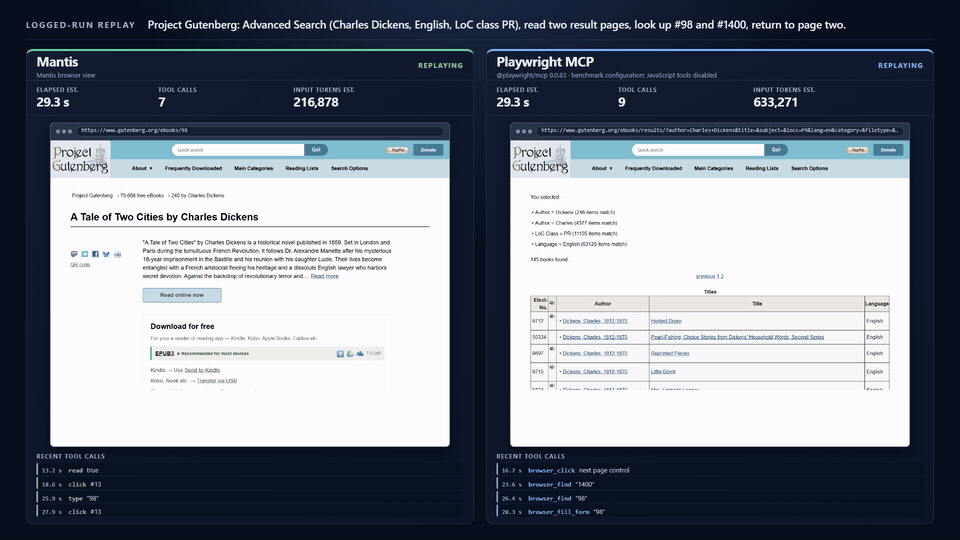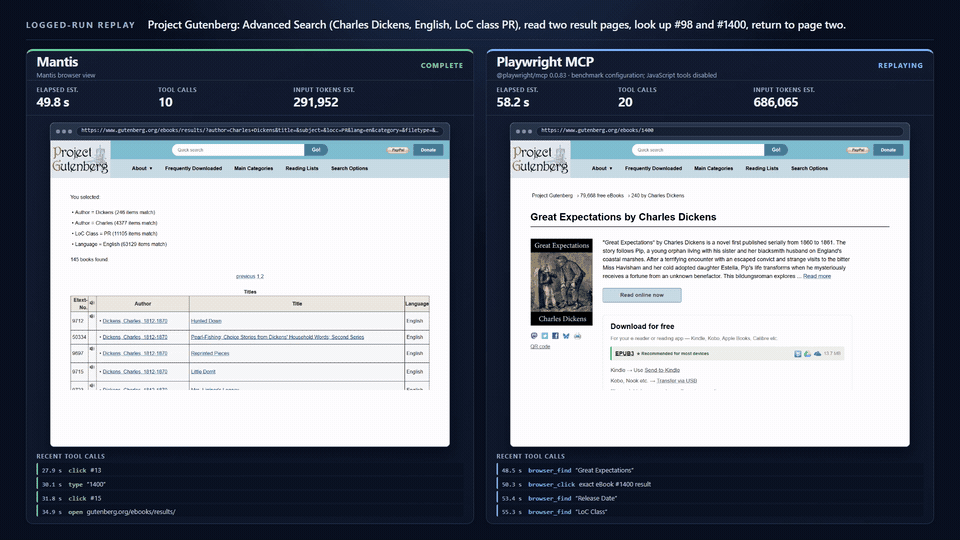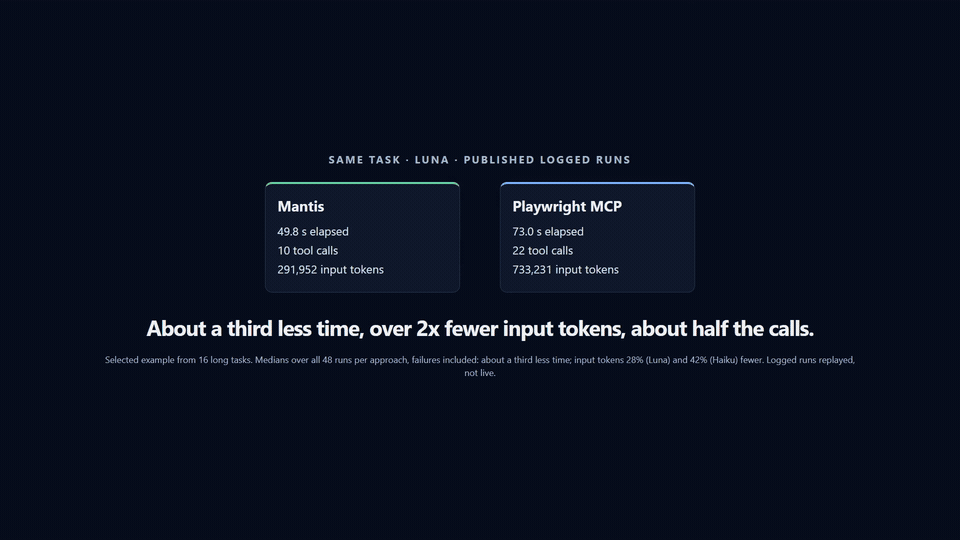
*One real task (Luna, logged runs replayed): about a third less time, over 2x fewer input tokens, about half the calls. This is a selected example from 16 long tasks; medians across all 16 are in [Results](#results). [Full video](video/mantis-demo.mp4).*
Security and threat model: [SECURITY.md](SECURITY.md).
## How it works
## What the agent sees
## Results
Mantis vs the accessibility tree (Playwright MCP) on public sites, `gpt-6-luna` and `claude-haiku-5-5`. Every cell is a per-run median; time is end-to-end wall time per run:
**Long tasks** (correct: 14 tasks, 42 runs per cell, deterministic answer keys; medians: all 16 tasks, 48 runs per cell):
| | Luna Mantis | Luna tree | Haiku Mantis | Haiku tree |
|---|---:|---:|---:|---:|
| Correct | **35/42** | 34/42 | **42/42** | 41/42 |
| Input tokens (median) | **262k** | 362k | **432k** | 746k |
| Tool calls (median) | **18** | 25 | **26** | 32 |
| Time (median) | **50s** | 75s | **90s** | 135s |
**Short tasks** (30 tasks, 90 runs per cell):
| | Luna Mantis | Luna tree | Luna screenshot | Haiku Mantis | Haiku tree | Haiku screenshot |
|---|---:|---:|---:|---:|---:|---:|
| Correct | 88/90 | 86/90 | **90/90** | **90/90** | 88/90 | 88/90 |
| Input tokens (median) | **63k** | 99k | 104k | 43k | 88k | **33k** |
| Tool calls (median) | **2** | 4 | 7 | **3** | 5 | 6 |
| Time (median) | **27s** | 31s | 35s | 24s | 31s | **23s** |
Long tasks: about a third less time and 28-42% fewer input tokens than the tree, with accuracy within one run. Short tasks: accuracy equal or better than the tree, 36-51% fewer input tokens and 13-22% less time. Screenshots score 2 runs higher on Luna but use more tokens and time there; on Haiku they use fewer tokens.
Scores come from deterministic answer keys on the final page state. Two long iframe/tab tasks can't be keyed and are left out of the long-task counts. Method, screenshot baseline and caveats: [bench/RESULTS.md](bench/RESULTS.md).
## Limitations
- No canvas input: canvas, WebGL, maps and drawing apps are described only as canvas, with no coordinate click or draw tool.
- Login and bot walls need `ask_human`, which needs a display.
- Benchmarked only on read, navigate and form-fill tasks on public sites, with two models. The screenshot baseline is this project's own tool, and a few tasks were swapped after results ([disclosed](bench/RESULTS.md)).
- Page content is untrusted data; see [SECURITY.md](SECURITY.md).
- Small v0.1.x beta.
## Learn more
- [How it works in detail](docs/APPROACH.md)
- [Claude skill](skill/README.md): teaches Claude how to read Mantis output
- [Install, configuration and tool reference](docs/SETUP.md)
- [Re-running the benchmarks](bench/README.md)
## License
MIT