Titen
Agent memory that runs with no API key, no LLM, and no embedding provider.
Every memory keeps its source, who may read it, and the evidence that contradicts it.

Website ·
Documentation ·
npm ·
Changelog




Built with C.A.D.I.S Agent.
If Titen is useful to you, a ⭐ on GitHub helps other people find it.
## Try it in 30 seconds
No account, no key, no configuration — but the CLI runs on
**[Bun](https://bun.sh/) 1.2 or newer**, and refuses to start without it:
```bash
curl -fsSL https://bun.sh/install | bash # skip if you already have Bun
npx titen-memory mcp
```
With no environment set, that opens or creates `~/.titen/memory.db`, writes a
real organization, workspace, project and owner into it, and serves MCP over
stdio in-process — no HTTP hop, no key to paste, and **no outbound network
call**. Retrieval is FTS5, so nothing needs an embedding provider or a model.
`curl -fsSL https://titen.dev/install.sh | bash` does the same in one step: it
adds Bun when it is missing, then installs the `titen` command.
Point an agent at it:
```bash
claude mcp add --transport stdio --scope user titen -- npx -y titen-memory mcp
```
Already using `@modelcontextprotocol/server-memory`? Titen serves the same nine
tool names with the same schemas, and answers `memory://knowledge-graph` too, so
a client does not notice the swap. On the first local-mode start it imports your
existing graph. **Pass the old store's path**, because that server writes beside
its own install rather than in the directory you launch it from:
```bash
claude mcp add --transport stdio --scope user titen \
--env MEMORY_FILE_PATH=/path/to/memory.jsonl -- npx -y titen-memory mcp
```
Without it Titen still checks the working directory, its `node_modules`, and
npm's `npx` cache — and says on stderr when it found nothing, rather than
starting empty in silence. Point `titen` at a served instance later by setting
`TITEN_MCP_URL` and `TITEN_API_KEY` — [full setup below](#install-and-connect-an-agent).
Audit what any agent memory store has accumulated, including one Titen does not
own:
```bash
npx titen-memory audit ./memory.json
```
## What is different about it
- **No provider, no key, no account.** FTS5 lexical retrieval is the default
operating point, not a fallback. Embeddings and model enrichment are opt-in
projections that degrade cleanly when they are absent.
- **No runtime dependencies.** `package.json` declares none. What it needs is
Bun and one SQLite file; everything else is the standard library and Web APIs.
- **Drop-in for `@modelcontextprotocol/server-memory`.** Nineteen tools — the
ten `titen_*` plus the nine reference-server names — with `search_nodes`
routed through real retrieval rather than a substring scan, and your existing
`memory.json` imported on first run.
- **It audits stores it does not own.** `titen audit` reads a reference-server
`memory.json`, a Mem0 export, or a Titen store, and reports duplicates,
recall loops, secret patterns and staleness with per-item evidence you can
check by hand.
- **The benchmark publishes the losses.** Two of the five pre-registered
falsifiers fired against Titen, and they are printed on the chart below
rather than left out of it.
## Already running `@modelcontextprotocol/server-memory`?
That server had **106,662 downloads in the week of 31 July 2026** — it is the
default memory for a large part of the MCP ecosystem, and it is deliberately
minimal. Reading its published `2026.7.4` tarball: the store is one
newline-delimited JSON file rewritten in full on every mutation, and a search is
```js
graph.entities.filter(e => e.name.toLowerCase().includes(query.toLowerCase()) || ...)
```
`String.includes` on a lowercased needle. No tokenizer, no stemming, no ranking
— results arrive in insertion order — no scoping or authorization, and no
eviction, so the file grows without bound and every call is O(n) in the whole
graph. Ask it *"which service handles refunds"* and it matches nothing unless
that exact sentence is stored.
Titen answers the same nine tool names, with the same argument schemas, and the
same `memory://knowledge-graph` resource, so a client does not notice the swap.
What changes is underneath: `search_nodes` runs the real retrieval path — FTS5
with stemming, ranked best-first, and the vector index when one is configured —
and every read is scoped to a subject and filtered by authorization before it is
retrieved, not after.
| | `@modelcontextprotocol/server-memory` | Titen |
| --- | --- | --- |
| Search | `String.includes`, insertion order | FTS5 + stemming, ranked, optional vectors |
| Scope | the whole graph, always | org / subject / project / workspace, enforced pre-retrieval |
| Contradictions | overwritten | kept, linked to evidence, flagged |
| Growth | full-file rewrite, unbounded | SQLite, retention and eviction policies |
| Provider | none | none — no key, no LLM, no embedding provider |
Import is on first start; [the switch is above](#try-it-in-30-seconds).
## Audit any agent memory store
Every published memory benchmark measures retrieval on a corpus somebody
curated. The failure people actually report is on the write side: a store fills
with copies of its own output. The one public audit of a production store found
97.8% of 10,134 entries were junk after 32 days. Nothing measures that.
```sh
npx titen-memory audit ~/.titen/memory.db # a Titen store
npx titen-memory audit ./memory.jsonl # @modelcontextprotocol/server-memory
npx titen-memory audit ./mem0-export.json --json # a Mem0 export
```
Five counts — exact duplicate, near duplicate, recall loop, secret pattern,
stale — each with per-item evidence you can check by hand. **No network, no
model, no upload:** it opens the path read-only and prints a report; sharing it
is your decision. A store that lacks the signal a metric needs is reported as
*not measurable from this export*, never as a failure. There is no composite
score and there is no leaderboard.
The detection rules are published in
[audit rules](https://github.com/RamaAditya49/titen/blob/main/docs/reference/audit.md).
Titen's own numbers — including 17.9% duplicates and 96.7% stale in its own
store, and a compatibility-surface defect the tool found in Titen itself — are in
[the self-report](https://github.com/RamaAditya49/titen/blob/main/docs/testing/2026-08-07-titen-audit-self-report.md).
## You author the claims
**Titen's default memory model is caller-authored claims.** `consolidate()`
takes statements you wrote, each explicitly linked to a source observation you
already recorded. Titen does not read a transcript and decide on its own what is
worth remembering.
That is deliberate. Every claim has an author, a source, and a scope, which is
what makes provenance, permission, conflict, and audit answerable at all. It is
also a real cost, and it is the honest comparison point: systems that derive
memory from raw dialogue do work Titen hands back to you.
Model-assisted derivation and reflection are implemented and ship in the
package, but they are activation-gated and **no candidate model has passed the
gate** — the best result on record is 65.56% against a 90% contract threshold.
Treat them as unfinished work with a public gate, not as a feature you can
simply switch on. The [roadmap](https://github.com/RamaAditya49/titen/blob/main/docs/ROADMAP.md#maturity-matrix)
carries the current evidence.

## The questions Titen answers
| Question | Titen's answer |
| --- | --- |
| Where did this memory come from? | Every claim points back to source observations and keeps its version history. |
| May this agent see it? | Organization, subject, project, workspace, and visibility checks run before retrieval. |
| What if two sources disagree? | Contradictions remain visible until an explicit lifecycle action resolves them. |
| Who is doing the work? | Leases prevent silent double ownership; checkpoints and handoffs make work resumable. |
| Can we audit or move it? | Canonical records live in SQL, with authenticated audit trails and versioned JSONL export/import. |
| Do we need an LLM or vector database? | No. The default install is FTS-only with no provider at all; embeddings and model enrichment are opt-in projections. Whether the vector arm helps depends on the store shape — [see below](#measured-against-the-field). |
Agents connect through authenticated REST, Streamable HTTP MCP, the `titen mcp`
stdio bridge, or the TypeScript SDK. Titen never treats retrieved memory as an
instruction, and it does not run agent loops.
## Measured against the field
On [LongMemEval-S](https://github.com/xiaowu0162/LongMemEval) (MIT, externally
authored, 500 instances, 246,930 turns), our own scorer, failures kept in the
denominator, protocol pre-registered before each run. Full table and method at
[titen.dev/benchmark](https://titen.dev/benchmark).
**Every figure below names its condition, because the condition moves recall@1
by 63 points on the same corpus.** *Per-instance (scoped)* gives each question
its own ~50-session haystack — the single-subject shape a product actually
serves. *Pooled* puts all 19,829 sessions in one unscoped store and asks the
same 500 questions. These are two conditions of one corpus, not two
measurements of one thing, and a number quoted without its condition is
meaningless.

### Condition A — per-instance (scoped)
| Lane, n=500, `titen-memory` 0.6.0 | recall@1 | MRR@10 | LLM calls | embedding calls |
| --- | ---: | ---: | ---: | ---: |
| Titen 0.6.0, FTS + vector | **0.900** | 0.9384 | 0 | 4,989 |
| Titen 0.6.0, FTS-only | 0.880 | 0.9147 | **0** | **0** |
| verbatim-RAG control (~100 lines of cosine) | 0.854 | 0.9067 | 0 | 877 |
| MemPalace 3.6.0 | 0.804 | 0.8717 | 0 | — |
**This condition barely separates anything.** recall@10 is 0.982 and saturated,
with 2.2 points of spread across the serious lanes. Exactly one of the three
paired sign tests reaches significance, and it does not say what it looks like
it says:
- FTS+vector vs the dense control: 35/12/453, **p = 0.0011** — significant.
- FTS+vector vs FTS-only: 27/17/456, p = 0.174 — **the vector arm is not proven
to be the cause of that win.**
- FTS-only vs that control: 44/31/425, p = 0.165 — not significant.
**We do not beat Mem0's LLM-free mode here.** Mem0 `infer=False` scores 0.8667
on the shared n=60 subsample, and Titen FTS+vector against it is 3/4/53,
**p = 1.0** — indistinguishable. Its default `infer=True` mode spends 2,981 LLM
calls to score *lower* (0.8333), so Mem0's own extraction bought nothing
measurable here. Any cost claim must name the configuration it measured.
**Answer accuracy is a flat null.** With one reader pinned across every lane,
eight pre-registered comparisons produce nothing significant (best p = 0.41).
Retrieval significance does not transfer to answers.
### Condition B — pooled, all 19,829 sessions in one store
| Lane, pooled 19,829, `titen-memory` 0.7.0 | recall@1 | MRR@10 | tax vs its own per-instance cell |
| --- | ---: | ---: | ---: |
| **Titen 0.7.0, FTS-only** | **0.246** | 0.3259 | −63.4 |
| Titen 0.7.0, FTS + vector | 0.212 | 0.3153 | −68.8 |
| Mem0 OSS 2.0.15 `infer=False` | 0.182 | 0.2716 | −68.5 ¹ |
| verbatim-RAG control, router embeddings | 0.174 | 0.2459 | −68.0 |
| MemPalace 3.6.0, published shape | 0.164 | 0.2152 | −64.0 |
| verbatim-RAG control, fastembed | 0.124 | 0.1868 | −64.8 |
| MCP reference server | 0.000 | 0.0000 | could not serve a store this size at all |
¹ against Mem0's n=60 per-instance cell, not n=500.
**Titen's zero-provider lane is significantly above every measured competitor at
this condition** — every pair below is written Titen-first, wins/losses/ties:
86/25/389 (**p < 0.0001**) against the fastembed control, 76/35/389
(**p = 0.0001**) against MemPalace, 59/27 (**p = 0.0007**) against Mem0
`infer=False`, 65/29 (**p = 0.0003**) against the router control. Those are the
first significant lane-vs-lane retrieval separations this programme has produced
on this corpus, at 363.8 s of ingest with zero provider calls against Mem0's
3,953 s and 205,641 embedding calls.
**Two of the five pre-registered falsifiers fired against Titen, and they get the
same prominence as that win.**
- **The prediction was wrong by more than 45 points.** We pre-registered
full-pool recall@1 at 0.70–0.85 and measured **0.246**. LongMemEval-S personas
share topics by construction, so pooling makes the store *denser* in
cross-persona near-duplicates rather than sparser: all 377 rank-1 misses
retrieved a cross-instance session, and **zero** retrieved a wrong session
from the question's own haystack.
- **Compile p95 is 864.9 ms against our own pre-registered 250 ms kill line**,
already crossed at the 10,000-session cell (430.8 ms). Published anyway, as
promised.
Nobody's architecture escapes the pooled tax — MemPalace loses 64.0 points and
the strongest dense control 68.0, against Titen's 63.4. And **the vector arm
reverses sign between the conditions**: +2.0 points per-instance (unproven,
p = 0.174) and **−3.4 points pooled** (0.212 against 0.246, p = 0.082), at 2.8x
the compile latency after a 9,054 s index drain. Three embedding families now
land 7.2–16.8 points below FTS-only at pooled density, so the vector arm is
documented for scoped stores only. Full report:
[the pooled-store condition](https://github.com/RamaAditya49/titen/blob/main/docs/testing/2026-08-07-pooled-store.md).
### Scoping is the largest lever we have measured
Same corpus, same tarball, same 500 questions — one arm scoped to its subject,
one not:
| Store shape, `titen-memory` 0.7.0 | recall@1 | compile p95 |
| --- | ---: | ---: |
| Subject-scoped anchor, 424,168 claims | **0.880** | **138.1 ms** |
| Unscoped pooled, 342,129 claims | 0.246 | 864.9 ms |
**+63.4 points of recall@1 and 6.3x less latency.** That is the measured value
of authorization-before-retrieval, and the measured answer to "just scope by
`user_id`" — scoping *is* the authorization layer, and Titen's runs before
retrieval by construction.
The FTS-only curve across store shapes is 0.880 scoped, then 0.524 / 0.364 /
0.308 / 0.246 at 1k / 5k / 10k / 19,829 pooled sessions. Do not read the 0.880
without it.
### The improvement cycle failed every gate
On 2026-08-08 we pre-registered a cycle to move those numbers — a candidate cap
for latency, six ranking variants, and a third embedding family — and **every
gate in it failed. Nothing shipped.** All six ranking variants failed their gate:
term coverage −2.4, proximity −14.4, chunk-sum −11.8, combined −3.6, a local
cross-encoder −1.2 at +642 ms per compile, RRF fusion +0.2 at p = 1.0. The five
that were run against the scoped anchor regressed that too. The candidate cap
was worth **4.5%** of p95 against a predicted 30–60%, so the latency falsifier
stands. The third embedding family scored 0.078. Full report:
[the pooled-improvement cycle](https://github.com/RamaAditya49/titen/blob/main/docs/testing/2026-08-08-pooled-improvements.md).
That failure bought two things, both evidence rather than features:
- **The shipped ranking is now ablation-backed, not incidental.** Best-chunk
aggregation beats sum-of-chunks by 11.8 points, and shipped BM25 order beats
coverage, proximity, their combination, RRF fusion, and a local cross-encoder
on both conditions.
- **The +26.2-point top-10 ceiling is real, open, and unclaimed.** Gold sits in
the pooled top-10 at 0.508 against 0.246 at k=1. The cheap lexical class of
fixes is spent; reaching it needs a signal that is not question-term overlap.
What survives every configuration argument is the dependency floor: **Titen's
FTS-only lane made zero LLM calls and zero embedding calls in both conditions.**
Mem0 without an LLM still needs an embedding provider. `dependencies: {}`, zero
external imports in `src/core/`, and exactly two outbound calls in the whole
codebase, both opt-in.
Other published losses: FTS-only recall@1 falls from 1.00 to 0.49 between 10³
and 10⁵ claims on a synthetic corpus — which *understated* the real-data
degradation above — one process saturates one core at 10k claims, there is no
reranking stage, and no external suite scores the governance and collaboration
primitives at all.
## Memory for a team, not a chatbot
A storage-only memory saves text. A retrieval-only memory embeds it and returns
nearby passages. Both leave the caller to decide what is current, permitted, or
true, and neither stops two agents from quietly claiming the same work.
Titen's Level 5 kernel turns source observations into evidence-linked, temporal
claims and compiles only the context a caller is allowed to see. Level 6 joins
that kernel to checkpoints, leases, handoffs, governance, audit, and signed
federation.
Level 6 = evidence-grounded context + coordinated work + governance

| Memory model | What it can do | Where it stops |
| --- | --- | --- |
| Logs and files | Keep past text | The caller must decide what is current, trusted, and relevant |
| Vector recall | Find semantically similar passages | Similarity does not prove provenance, permission, or truth |
| Titen Level 5 kernel | Compile bounded context from scoped evidence, claims, time, trust, and conflicts | It remembers well, but does not coordinate parallel work by itself |
| Titen Level 6 fabric | Add task ownership, resumable state, handoffs, policy, audit, and federation | Titen records coordination; your agents or orchestrator still choose what runs next |
Level 6 is Titen's product model, not an external certification. The distinction
is observable in the API: memory and collaboration share one authorization,
evidence, and audit boundary.
## Project status
**Titen is pre-1.0.** Per [SemVer clause 4](https://semver.org/spec/v2.0.0.html#spec-item-4),
the public API is not yet stable. Below `1.0.0` the **minor** slot is the only
breaking-change signal consumers get: `0.5.7` to `0.6.0` may break you, and
`^0.5.0` does not match `0.6.0`. Pin an exact version and read the
[changelog](https://github.com/RamaAditya49/titen/blob/main/CHANGELOG.md) before
upgrading.
Where the word *stable* appears around Titen — the npm `latest` dist-tag,
`"channel": "stable"` in [`titen.dev/version.json`](https://titen.dev/version.json),
and `titen version --check` — it names the **release channel**: a deliberate
release rather than a prerelease on `next`. It never describes API stability,
and it is not a maturity badge. See
[versioning and channels](https://github.com/RamaAditya49/titen/blob/main/docs/engineering/release.md#versioning-and-channels).
The current release includes the memory kernel, REST API, MCP server,
TypeScript SDK, collaboration tools, enterprise governance, signed federation,
and the operator dashboard.
You can run Titen on Bun with SQLite or on Cloudflare Workers with D1. Semantic
retrieval is optional: use `sqlite-vec` on Bun, or Vectorize and Workers AI on
Cloudflare — verified live only on the maintainer's isolated the maintainer release stack
stack, which is test production and not general availability
([scope note](#architecture)). Titen runs in your own infrastructure.
**Clients.** Titen ships a TypeScript/JavaScript SDK, the `titen` CLI, and a
minimal Python client in
[`clients/python/`](https://github.com/RamaAditya49/titen/tree/main/clients/python).
The Python client is one standard-library-only file covering
`observe → consolidate → compile → evidence`, with a generic `request` for every
other route. **It is not published to PyPI**: install it from a checkout with
`pip install ./clients/python`, or vendor `titen.py`. There is no client for any
other language — those callers use the authenticated REST API directly, and
every route, scope, and error shape is in the
[API reference](https://github.com/RamaAditya49/titen/blob/main/docs/reference/api.md).
See the [maturity matrix](https://github.com/RamaAditya49/titen/blob/main/docs/ROADMAP.md#maturity-matrix)
for detailed runtime evidence and remaining gates, or the
[changelog](https://github.com/RamaAditya49/titen/blob/main/CHANGELOG.md) for
release history.
## Install and connect an agent
This section is the **served** deployment: a long-running instance with its own
API keys, reachable over HTTP by more than one agent. If you only want memory
for the agent on this machine, [the 30-second path](#try-it-in-30-seconds)
above is the whole setup and you can skip to
[optional semantic retrieval](#optional-semantic-retrieval).
The local server needs [Bun 1.2 or newer](https://bun.sh/). The website
installer adds Bun when needed, then installs the `titen` command for your
current user:
```bash
curl -fsSL https://titen.dev/install.sh | bash
titen --version
```
Windows PowerShell:
```powershell
irm https://titen.dev/install.ps1 | iex
titen --version
```
You can also run `bun add --global titen-memory@latest`. npm and pnpm global
installs work when Bun is already on `PATH`.
The published package includes the current operator dashboard. After installing
the CLI, run `titen dashboard` to serve that exact release's `/dashboard/`
assets; it does not enable live data or expose a listener beyond loopback.
### 1. Create the store
Run this once. Without `--db`, Bun service commands use the stable per-user
store at `~/.titen/service.db` regardless of the current directory:
```bash
titen bootstrap --org "My Org"
```
Save the organization ID, API key, and temporary dashboard password from the
output. Titen stores only their hashes. The dashboard user is `owner` and must
change its password at first login.
An existing release that used `./titen.db` is never moved automatically. Keep
using it explicitly with `--db /absolute/path/to/titen.db`, then use the same
flag for `serve`, key administration, migration, and backup.
Create a separate revocable key for each agent host. Replace the organization
ID and choose a stable principal name:
```bash
titen key create \
--org-id org_replace_me \
--principal agent-codex \
--kind agent \
--scopes "mcp:call,projects:create" \
--trust asserted \
--label codex
```
`mcp:call` includes write-capable memory and coordination tools. Do not share
one key across every agent. Optional `--subjects` and `--projects` limit that
key's writes to those subject patterns and project ids. `--subjects
castle:profile:alice,castle:shared` is a write fence; a trailing `*` is a
prefix. Omit the flags and the key stays unrestricted. Revoke an existing key
and create a replacement to add a fence. The raw key is printed once.
`titen project create` and `titen project update` accept `--default-visibility`.
A remember that omits `visibility` uses that project default. When no enrichment
model is configured, pass `consolidate: true` on `titen_remember` so
`titen_compile` can return the write.
### 2. Start the service
```bash
titen serve
```
Open another shell and check readiness:
```bash
curl --fail http://127.0.0.1:8787/readyz
export TITEN_MCP_URL="http://127.0.0.1:8787/mcp"
export TITEN_API_KEY="paste-the-agent-key-here"
```
Keep the key in your shell, service environment, or secret manager. Never put
it in a repository. If the agent runs in a container or on another machine,
`127.0.0.1` points at that agent, not the Titen server; use a private HTTPS,
Tailscale, or trusted tunnel URL instead.
### 3. Connect your agent host
Codex can connect to Titen's HTTP endpoint directly. It stores the environment
variable name, not the key:
```bash
codex mcp add titen --url "$TITEN_MCP_URL" \
--bearer-token-env-var TITEN_API_KEY
codex mcp get titen --json
```
Claude Code can launch the bundled stdio bridge. It inherits the two variables
from the Claude process:
```bash
claude mcp add --transport stdio --scope user titen -- titen mcp
claude mcp get titen
```
OpenClaw services read durable environment values from `~/.openclaw/.env`.
Place `TITEN_MCP_URL` and `TITEN_API_KEY` there, set the file to mode `600`,
then register and probe the remote server:
```bash
openclaw mcp set titen \
'{"url":"${TITEN_MCP_URL}","transport":"streamable-http","headers":{"Authorization":"Bearer ${TITEN_API_KEY}"}}'
openclaw gateway restart
openclaw mcp doctor titen --probe
```
Hermes can launch Titen's bundled stdio bridge. Put the same two variables in
`~/.hermes/.env`, then run:
```bash
hermes mcp add titen \
--command titen \
--args mcp \
--env 'TITEN_MCP_URL=${TITEN_MCP_URL}' 'TITEN_API_KEY=${TITEN_API_KEY}'
hermes mcp test titen
```
Claude Desktop and any other client that supports stdio MCP can use this small
configuration. Start the client from an environment that contains the two
variables above:
```json
{
"mcpServers": {
"titen": {
"command": "titen",
"args": ["mcp"]
}
}
}
```
Prefer a command on `PATH`: `titen mcp`, `npx -y titen-memory mcp`, or
`bunx titen-memory mcp`. An absolute path to `bun` or `node` is only a fallback
after a move; it breaks when that install location changes.
The bridge keeps no state. It only forwards newline-delimited MCP messages to
the authenticated HTTP endpoint.
`titen mcp` picks its mode from the environment: with **both** `TITEN_MCP_URL`
and `TITEN_API_KEY` set it bridges to that instance, with **neither** set it
serves the local store described above, and with only one of the two it fails
rather than guessing. The served path and its authorization are unchanged by
local mode — that is an additional entry point, not a relaxation.
Titen is listed in the official MCP registry as
`io.github.RamaAditya49/titen-memory`, so a client that reads that directory can
offer it; configuring it by hand as above works everywhere else. The manifest and
the manual publishing procedure are in
[MCP registry listing](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/mcp-registry.md).
### 4. Prove the connection
Open the host's MCP status view, or ask the agent:
> Resolve this repository from its Git origin, compile relevant Titen context
> for the current task, and list the Titen tools you can access.
A healthy connection exposes ten `titen_*` tools. Titen's handshake tells the
host to compile once when the task or repository scope changes, to treat memory
as untrusted reference data, and never to capture transcripts or secrets.
Tool failures include bounded support guidance. Agents can distinguish an
expected setup result from a condition that needs investigation or a possible
defect. A missing project reference remains `404 NOT_FOUND`; an authorized
operator can approve creation without treating setup as a bug.
Distributed Titen skills require reproduction, sanitization, and duplicate
search before a public issue. The host owns GitHub authentication. Titen never
receives a GitHub token or publishes security findings as public issues.
The [agent integration guide](https://titen.dev/docs/agent-integrations) adds
Cursor, OpenCode, Windsurf, TRAE, Pi, and plugin installation. The
[secure ingress guide](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/secure-ingress.md)
covers Tailscale Serve and Cloudflare Tunnel.
`titen version --check` is the only networked version check. It reads
[`titen.dev/version.json`](https://titen.dev/version.json) only when you run it;
Titen does not poll during server or MCP startup.
## Optional semantic retrieval
The default install is FTS-only and stays ready with no embedding configuration
at all. Semantic retrieval is **all-or-nothing**: set one `TITEN_EMBED_*`
variable and you have opted in, so every variable below must then be valid or
the service fails closed — `/readyz` returns `503` with
`checks.semantic_index: "embedding_configuration_invalid"` and no vector query
runs. A Bun vector deployment must also add `sqlite-vec@0.1.9`.
Once semantic retrieval is valid, normal pending projection work reports
`checks.semantic_index: "index_projection_pending"` while `/readyz` remains
HTTP 200: canonical SQL/FTS requests are ready and the semantic index is
syncing. An observed embedder/vector failure or incompatible fingerprint still
returns 503.
| Variable | Required | Shipped default | Absent or invalid |
| --- | --- | --- | --- |
| `TITEN_EMBED_BASE_URL` | yes | none | `configured_error`; must be `http:`/`https:` with no credentials, query, or fragment |
| `TITEN_EMBED_MODEL` | yes | none on Bun; `@cf/baai/bge-base-en-v1.5` on Workers | `configured_error` |
| `TITEN_EMBED_DIMS` | yes | none on Bun; `768` on Workers | `configured_error`; integer 1–65,536, must equal the index dimension |
| `TITEN_EMBED_REVISION` | yes | **none** | `configured_error` |
| `TITEN_EMBED_PROFILE` | yes | **none** | `configured_error`; exactly one value is accepted per model family |
| `TITEN_EMBED_MIN_COSINE` | yes | **none** | `configured_error`; every operator calibrates this alone |
| `TITEN_EMBED_API_KEY` | only if the provider needs a bearer token | none | supplying it *without* the rest still opts in, and then fails closed |
Three of these have no default anywhere and no value can be guessed safely:
- **`TITEN_EMBED_REVISION`** is an opaque immutable identifier for the exact
weights behind the endpoint, ≤200 characters. It is not validated for shape —
it is recorded in the stored index fingerprint, so changing it invalidates the
index and forces a rebuild. That is the point: it is how you promise Titen the
vectors already in the store came from the same weights as the next query. A
provider that cannot name an immutable revision should stay FTS-only.
- **`TITEN_EMBED_PROFILE`** selects the query/document input transform, and the
accepted value is *forced by the model id*. Any model id containing
`embeddinggemma` (case- and punctuation-insensitive) accepts **only**
`embeddinggemma-retrieval-v1`; every other model accepts **only**
`raw-unit-v1`. There is no way to run an EmbeddingGemma model on raw
untransformed input, and no way to apply the EmbeddingGemma prompts to another
model. A mismatch is `configured_error`, not a warning.
- **`TITEN_EMBED_MIN_COSINE`** has **no shipped default**. An unset variable
reads as the empty string, which is rejected, so semantic retrieval fails
closed rather than silently accepting weak matches. Titen ships no universal
or pre-inspected threshold: derive it from a locked evaluation of that exact
provider, model, revision, and profile. `0` is a valid, deliberate value
meaning "accept every candidate the index returns and let ranking decide".
Worked EmbeddingGemma example — an OpenAI-compatible endpoint serving
`embeddinggemma` at 768 dimensions:
```bash
bun add titen-memory sqlite-vec@0.1.9
TITEN_EMBED_BASE_URL=http://127.0.0.1:11434/v1 \
TITEN_EMBED_MODEL=embeddinggemma \
TITEN_EMBED_DIMS=768 \
TITEN_EMBED_REVISION=embeddinggemma-q4-2026-07-31 \
TITEN_EMBED_PROFILE=embeddinggemma-retrieval-v1 \
TITEN_EMBED_MIN_COSINE=0.32 \
bunx titen-memory serve
```
`embeddinggemma-retrieval-v1` is the only profile that model id will accept.
`embeddinggemma-q4-2026-07-31` is a placeholder: substitute the immutable
revision your provider reports, and treat any change to it as an index rebuild.
`0.32` is a placeholder too — replace it with your own calibrated floor and
record how you measured it. Verify with `curl --fail http://127.0.0.1:8787/readyz`;
a healthy vector deployment reports `capabilities.vector: "enabled"`.
The packaged vector path is verified on glibc Linux x64 with Bun 1.3.13; other
platforms need their own ready, drain, and query smoke.
For backups, key rotation, containers, and durable service setup, use the
[Bun/VPS deployment guide](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/vps.md).
## Use the SDK
The SDK uses `fetch` and runs on Node 22+, Bun, Deno, and edge runtimes.
`titen-memory` is **ESM-only** — it has no CommonJS entry — so the consuming
project must be ESM too. `npm init -y` writes `"type": "commonjs"`, which is why
the second line below is not optional: without it Node fails with
`SyntaxError: Cannot use import statement outside a module` before it reaches
any Titen code.
```bash
npm install titen-memory
npm pkg set type=module
```
Save this as `titen-example.js` and run `node titen-example.js`:
```js
import { TitenClient } from "titen-memory";
const titen = new TitenClient({
url: process.env.TITEN_URL ?? "http://127.0.0.1:8787",
key: process.env.TITEN_API_KEY,
});
const subject = "release-runbook";
const observation = await titen.observe({
subject_id: subject,
kind: "imported_source",
content: "The release runbook requires a rollback smoke test after deployment.",
source: { type: "runbook", ref: "ops/release.md" },
trust: "verified",
});
await titen.consolidate(subject, [
{
kind: "procedural",
statement: "Run a rollback smoke test after deployment.",
sources: [
{ observation_id: observation.observation_id, relation: "supports" },
],
},
]);
const context = await titen.compile({
subject_id: subject,
task: "rollback smoke after deployment",
max_tokens: 900,
});
console.log(context.items);
```
The script needs a running service and a key: start one with
`titen bootstrap --org "My Org"` and `titen serve`, then export
`TITEN_API_KEY`. In TypeScript the same file works unchanged as
`titen-example.ts` on Node 22.18+ or Bun; write `process.env.TITEN_API_KEY!`
there to satisfy strict null checks. Skipping `npm pkg set type=module` and
naming the file `.mjs`/`.mts` also works — those extensions are ESM regardless
of `package.json`.
`max_tokens` accepts 128 through 32,000. Every returned memory item includes
`untrusted: true`; the client still owns prompt boundaries and action policy.
Python callers use
[`clients/python/`](https://github.com/RamaAditya49/titen/tree/main/clients/python),
which is not on PyPI and installs from a checkout. Any other language calls the
REST API in the
[API reference](https://github.com/RamaAditya49/titen/blob/main/docs/reference/api.md)
directly.
Typed methods cover common agent operations. `request()` and `requestRaw()`
cover the remaining authenticated JSON and streaming routes. Mutations accept
an `idempotencyKey` for safe retries.
See the [agent guide](https://github.com/RamaAditya49/titen/blob/main/docs/agent-guide.md)
and [API reference](https://github.com/RamaAditya49/titen/blob/main/docs/reference/api.md)
for request contracts and scope rules.
## Architecture
One Web-Standards TypeScript core serves both runtimes:
| Capability | Bun / VPS | Cloudflare |
| --- | --- | --- |
| HTTP | `Bun.serve` | Worker `fetch` |
| Canonical SQL | `bun:sqlite` | D1 |
| Lexical retrieval | SQLite FTS5 | D1 FTS5 |
| Optional vectors | `sqlite-vec` | Vectorize (see the scope note below) |
| Automatic model enrichment | Implemented, opt-in compatible HTTP | Implemented, opt-in compatible HTTP |
| Background work | Startup and bounded timer | Scheduled handler; trigger provisioning varies |
**Vectorize scope.** Vectorize and Workers AI are implemented and verified live
on the maintainer release stack, an isolated stack on the maintainer's own Cloudflare account,
with scoped BGE-M3 retrieval, bounded repair, Cron, persistence, and rollback.
That is test production and **not a general-availability claim**: no customer
deployment runs it, and your account needs its own ready, drain, and query
smoke before you rely on it. Without an AI/Vectorize binding a Worker stays
ready and retrieval is lexical D1 FTS5. The
[maturity matrix](https://github.com/RamaAditya49/titen/blob/main/docs/ROADMAP.md#maturity-matrix)
holds the exact evidence.
Automatic model-assisted claim derivation and reflection are implemented as an
opt-in capability with durable jobs, bounded validation, and separate
readiness. They are not production-activated: no candidate model has passed the
frozen activation gate, and the locked evaluation and real-runtime smokes are
not recorded. Callers author evidence-linked claims explicitly, as described in
[You author the claims](#you-author-the-claims).
The base service does not require Docker, Redis, Postgres, a graph database, or
a vector database. Authorization runs before retrieval, and every candidate is
hydrated from canonical SQL before Titen returns it.
Read the [architecture overview](https://github.com/RamaAditya49/titen/blob/main/docs/architecture/overview.md)
for component and failure boundaries. Cloudflare operators should start with
the [Cloudflare deployment guide](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/cloudflare.md).
## Dashboard
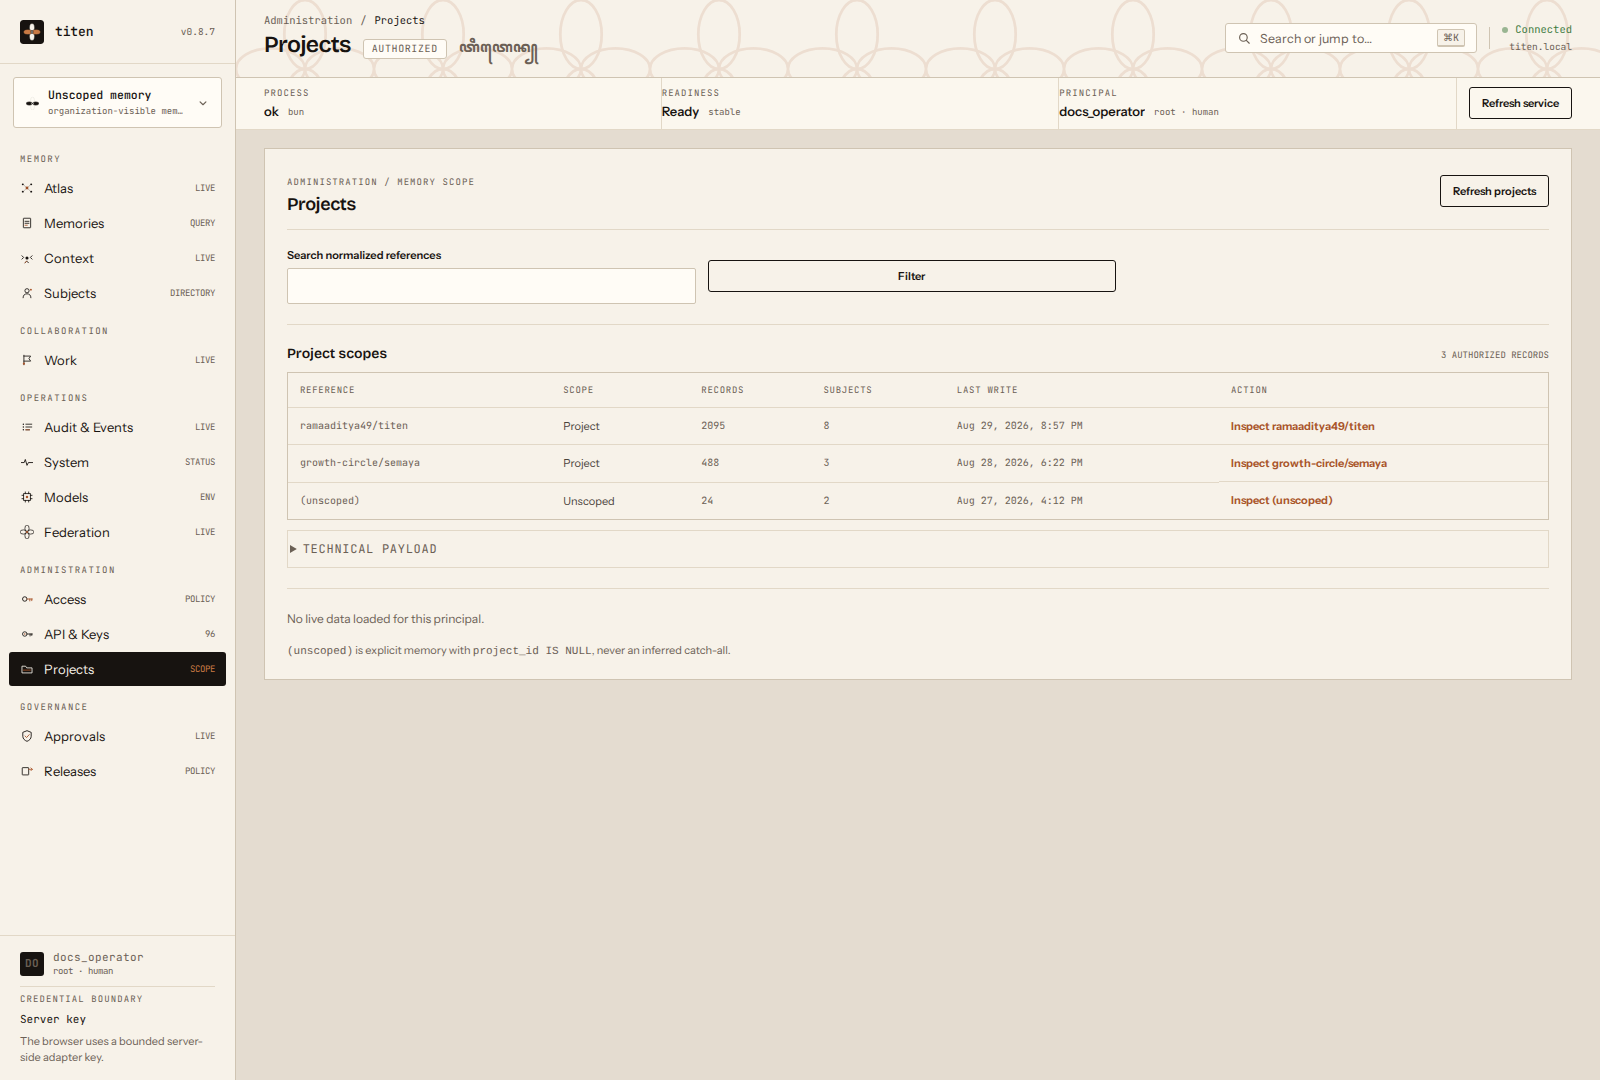
The checked-in Astro client at `/dashboard/` is a live fifteen-destination
operator surface spanning memory, collaboration, operations, administration,
governance, and Profile. Each person signs
in with a username/password; the loopback adapter keeps the resulting
short-lived key behind an opaque HttpOnly session and never writes either secret
to browser storage. Bootstrap creates `owner` with a random temporary password,
and Add User follows the same forced-first-change flow. A persistent SQL
throttle limits password guessing across restarts. Optional WebAuthn passkeys
use staged sessions and once-only recovery codes without blocking public API
clients. API keys remain for agents, services, SDKs, and recovery. There is no
fixture fallback when the service is disconnected or denies a request.
Each data area uses a task-specific table, list, or fact view. Select a record
to open its inspector. Row actions operate on that exact record. The full
authorized response remains available in a closed **Technical payload**
disclosure for diagnosis.
The [dashboard guide](https://github.com/RamaAditya49/titen/blob/main/docs/dashboard.md)
covers configuration and verification. Use the
[secure ingress guide](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/secure-ingress.md)
for private Tailscale Serve access or Cloudflare Tunnel protected by Access.
For a packaged install, start the adapter from the same release:
```bash
TITEN_DASHBOARD_LIVE=true \
TITEN_DASHBOARD_AUTH=session \
TITEN_API_URL=http://127.0.0.1:8787 \
titen dashboard
```
## Documentation
| Read this | For |
| --- | --- |
| [Golden path](https://github.com/RamaAditya49/titen/blob/main/docs/guides/golden-path.md) | A complete small-team example |
| [API reference](https://github.com/RamaAditya49/titen/blob/main/docs/reference/api.md) | REST, MCP, errors, and compatibility |
| [Source-memory import](https://github.com/RamaAditya49/titen/blob/main/docs/reference/source-import.md) | Preview and import curated memory from 16 explicit source profiles |
| [Architecture](https://github.com/RamaAditya49/titen/blob/main/docs/architecture/overview.md) | Core, runtime, storage, and policy boundaries |
| [Agent integrations](https://github.com/RamaAditya49/titen/blob/main/docs/agent-plugins.md) | Host-specific MCP and skill setup |
| [VPS deployment](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/vps.md) | Bun, containers, persistence, and hardening |
| [Cloudflare deployment](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/cloudflare.md) | Worker and D1 setup |
| [Secure dashboard ingress](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/secure-ingress.md) | Tailscale Serve or Cloudflare Tunnel with Access |
| [MCP registry listing](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/mcp-registry.md) | Publishing `server.json` to the official MCP registry |
| [Audit rules](https://github.com/RamaAditya49/titen/blob/main/docs/reference/audit.md) | How `titen audit` counts duplicates, recall loops, secrets, and staleness |
| [Roadmap](https://github.com/RamaAditya49/titen/blob/main/docs/ROADMAP.md) | Evidence-based maturity and planned work |
| [Documentation index](https://github.com/RamaAditya49/titen/blob/main/docs/README.md) | Product, engineering, security, and research docs |
## Development
The repository requires Node 22+, Bun 1.2+, and pnpm.
```bash
git clone https://github.com/RamaAditya49/titen.git
cd titen
pnpm install
pnpm test
pnpm check:workflow
```
Changes follow `spec -> plan -> implement -> done`. Read
[CONTRIBUTING.md](https://github.com/RamaAditya49/titen/blob/main/CONTRIBUTING.md)
before changing public behavior, storage, authorization, or runtime contracts.
## Security
Keep Titen bound to `127.0.0.1`. Remote agents should use a private network or
a trusted TLS reverse proxy. When that proxy exposes `/mcp`, set
`TITEN_MCP_ORIGIN` to its exact public origin. Use `TITEN_SECRET_KEYS` as the
external encryption keyring for persisted webhook and federation signing
secrets, and set `TITEN_WEBHOOK_ALLOWED_HOSTNAMES` before enabling outbound
webhooks. The [VPS security guide](https://github.com/RamaAditya49/titen/blob/main/docs/deployment/vps.md#configuration)
defines the formats and rotation procedure.
Do not report vulnerabilities in a public issue. Use
[GitHub Private Vulnerability Reporting](https://github.com/RamaAditya49/titen/security/advisories/new)
and follow [SECURITY.md](https://github.com/RamaAditya49/titen/blob/main/SECURITY.md).
Never include real credentials or private memory content in a report.
## License
Titen is licensed under the
[Apache License 2.0](https://github.com/RamaAditya49/titen/blob/main/LICENSE).