repowise: evidence-backed codebase intelligence

Understand your codebase without paying your agent to rediscover it.

Repowise indexes your code, dependency graph, git history, tests,
documentation, and decisions once, then gives agents and developers cited answers,
change impact, and concrete code-health fixes.
Open the live Repowise demo

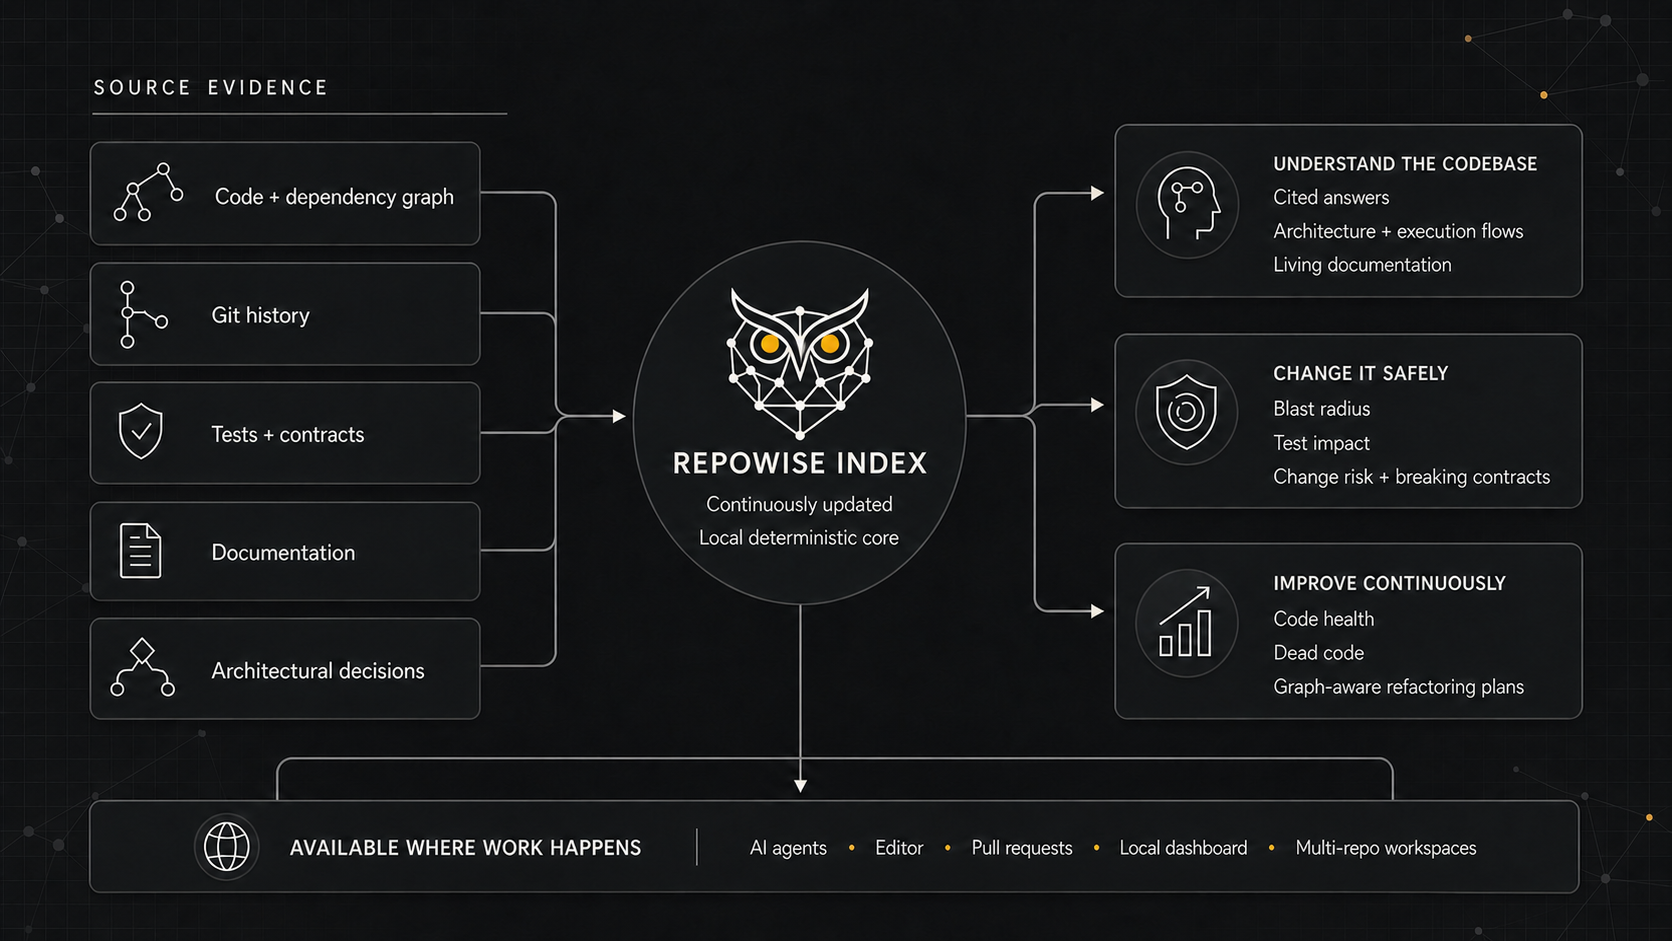
Repowise connects code and dependency data, git history, tests and contracts, documentation, and architectural decisions in one continuously updated local index that gives developers and AI agents cited understanding, change impact, and concrete code-health improvements across editors, pull requests, dashboards, and multi-repository workspaces

−31.6%

97.2%

2.3×

less agent output
3.8 vs 7.2 tool calls
n=43 · p<0.0001
smaller context payload
393 vs 13,984 tokens
30 Flask commits
more defects surfaced
same 20%-of-lines budget
2,770 files · p=0.003

Graph accuracy leader at matched coverage.
No tool finding as much was more precise in all 7 compiler-graded cells.
5 tools · 37,853 oracle edges

Zero LLM calls for graph, risk, health, tests, dead code, and PR review. Generated prose is optional. Every benchmark publishes its sample, method, limitations, and losing rows.

Free and self-hosted · core analysis stays on your infrastructure · no API key needed · AGPL-3.0 or commercial
Explore Repowise's own code Repowise code health PyPI version License: AGPL 3.0

Why Repowise · Agents · Changes · Code health · Workspaces · Evidence · Enterprise · Docs

--- ## One index. Three ways to use it. | **Understand the code** | **Change it safely** | **Improve it continuously** | |---|---|---| | Ask cited questions · explore architecture and execution flows · read always-current docs · recover the decisions behind the code | See symbol-level blast radius · run only the tests a diff exercises · catch missing companion files · detect breaking contracts before merge | Find defect-prone files · separate maintainability from performance risk · remove dead code · hand concrete, graph-aware refactoring plans to an agent | These are not disconnected scanners. The graph locates what git history flags; code health measures it; tests show what guards it; decisions explain why it exists; and the same evidence reaches your agent, editor, pull request, local dashboard, and cross-repository system map.
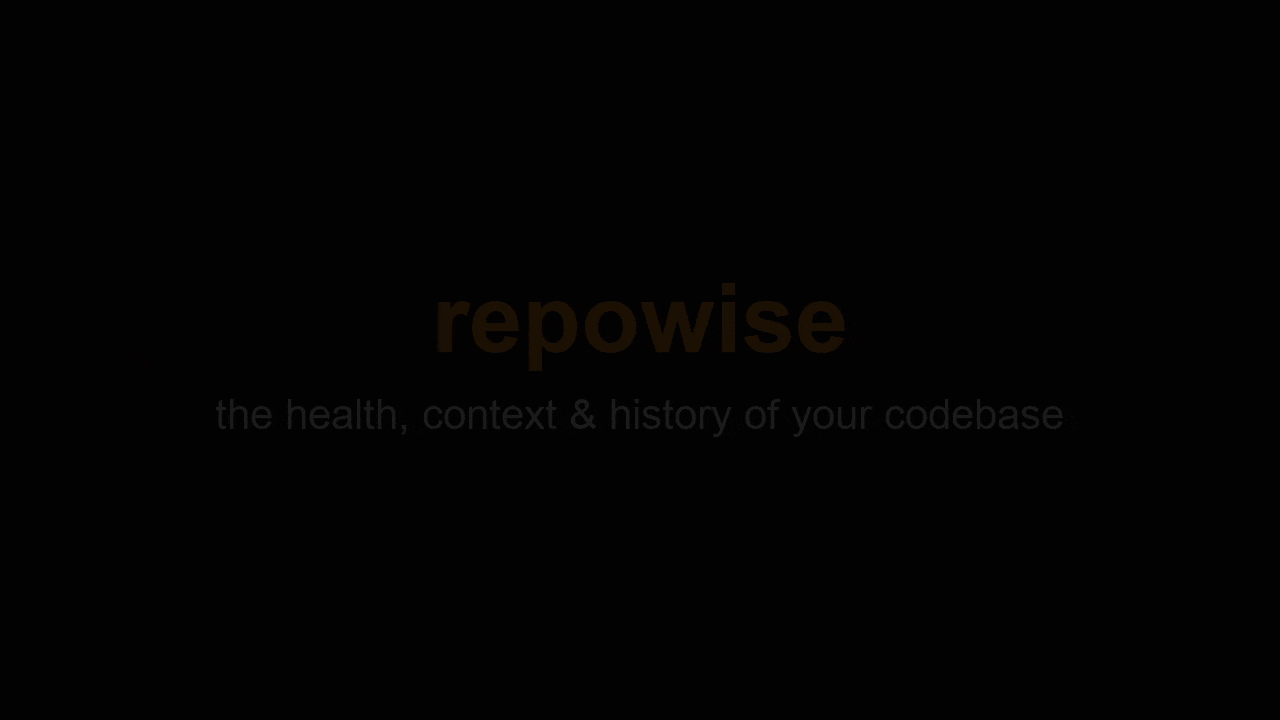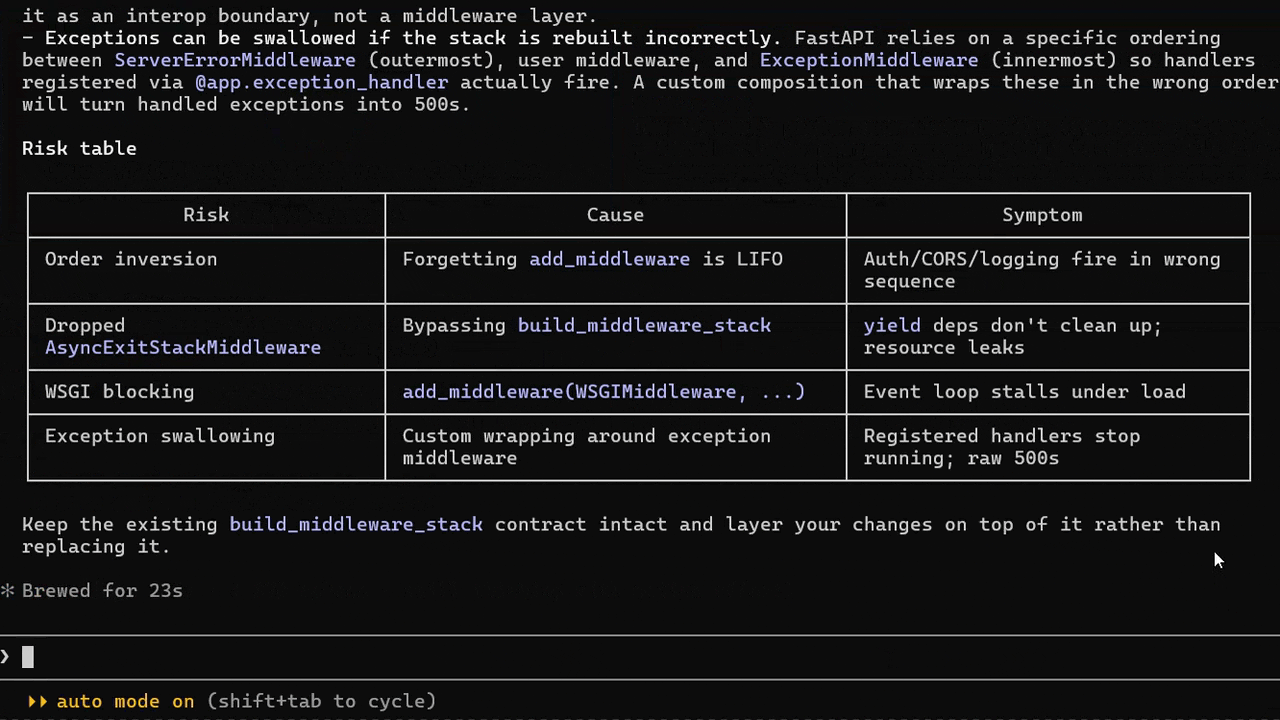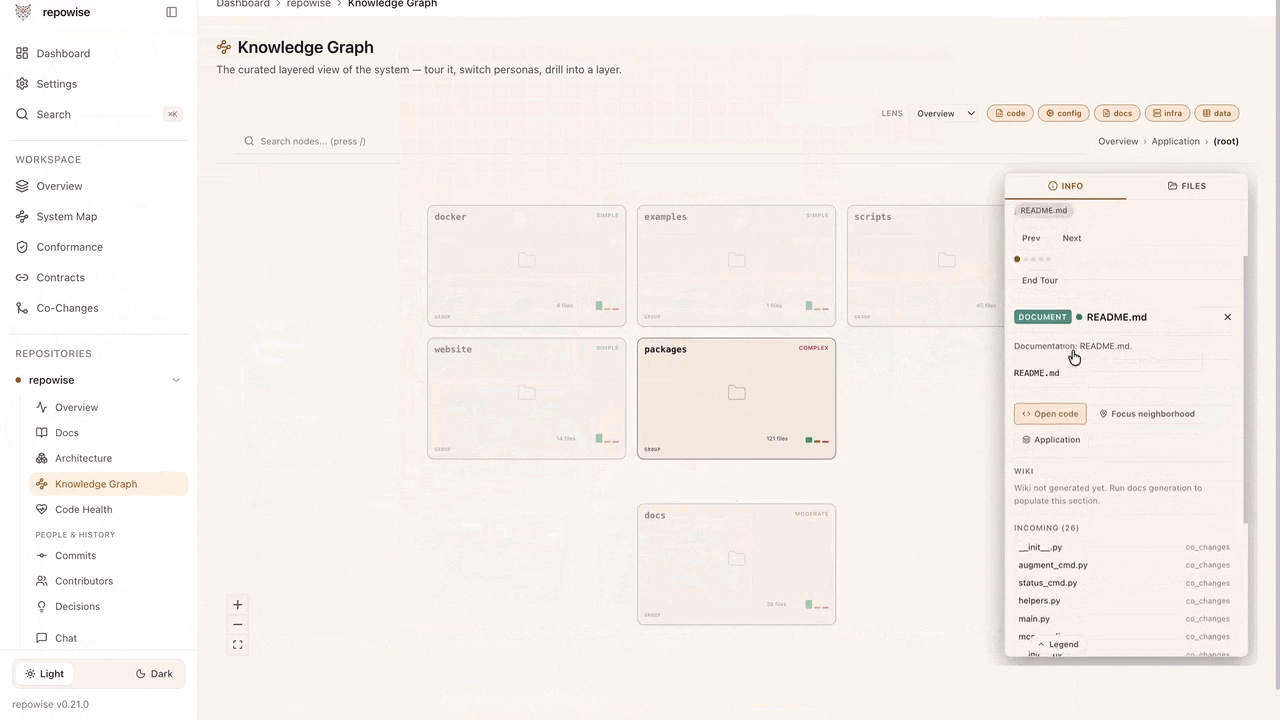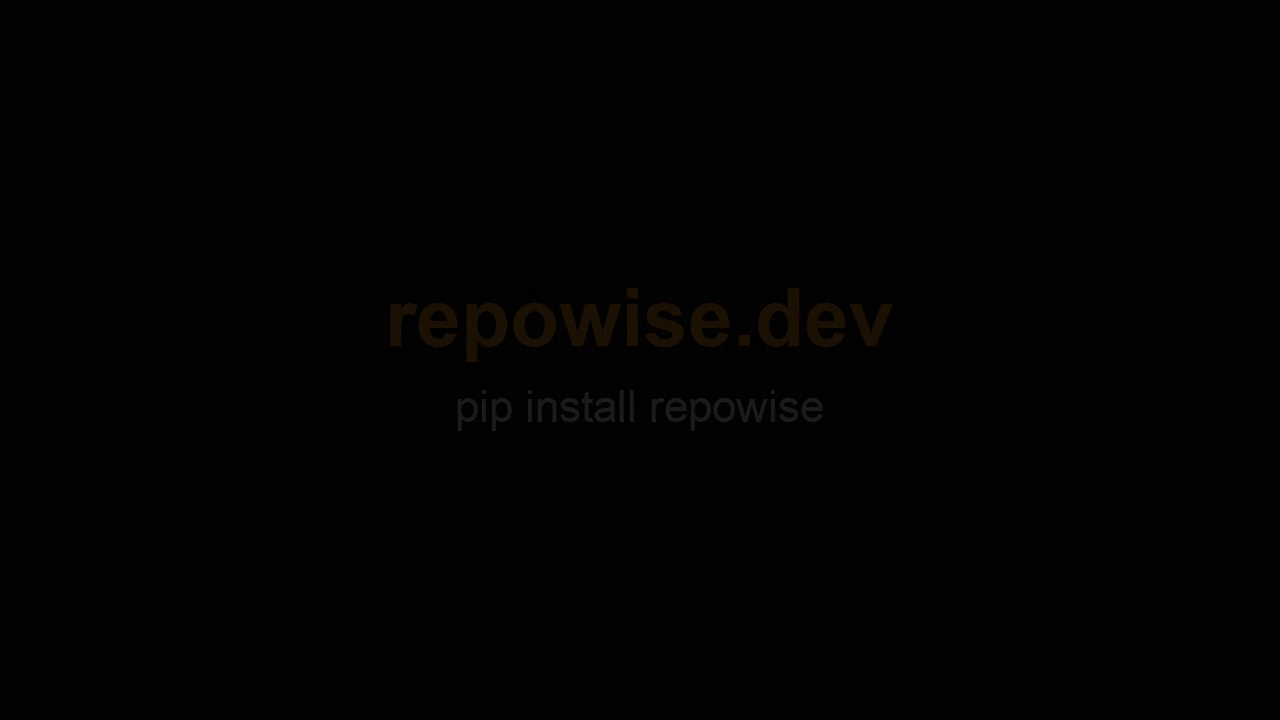
The Repowise dashboard running locally: health scores, the code-health map, a graph-aware refactoring plan, change coupling, and the generated documentation

A dashboard tour recorded on this repository. The same local index powers the UI, MCP tools, editor views, and PR analysis. No API key and nothing uploaded.

### Pick your front door | If you care about… | Start here | |---|---| | **A coding agent that understands the repository** | Repowise finds the right files, returns task-shaped context in fewer calls, and proactively supplies decisions and risk. [For agents ↓](#your-agent-stops-guessing) | | **Safer pull requests and faster test feedback** | Get change risk, symbol-level callers, co-change partners, and a measured or graph-inferred test run list before merge. [Change intelligence ↓](#know-whats-dangerous-before-you-merge) | | **Finding and fixing the code most likely to hurt you** | A defect-validated 1–10 health score across defect risk, maintainability, and performance, followed by the concrete refactoring plan. [Code health ↓](#code-health) | | **Understanding an estate, not one repository** | Match backend and frontend contracts, catch breaking providers, map downstream services, enforce architecture rules, and query every repo through one MCP endpoint. [Workspaces ↓](#past-one-repo) | | **Rolling this out across an engineering organization** | Keep analysis on your infrastructure, give agents and reviewers the same evidence, and add commercial licensing, security controls, custom extensions, and SLA-backed support. [Teams and enterprise ↓](#for-teams-and-enterprises) | ## Start in minutes (no API key) ```bash pip install repowise cd /path/to/your/repo repowise init --no-prose -y repowise serve ``` That builds the graph, git, decisions, health, dead-code and structural-wiki layers locally. Connect Claude Code, Codex, Cursor or any MCP host, or open the dashboard. `init` wires Claude Code automatically. Then ask your agent: *"Use Repowise `get_overview` to summarize this repository"* or *"What breaks if I change `src/auth.py`?"* [Full setup, every agent, and optional model-written prose →](docs/start/QUICKSTART.md) --- ## Your agent stops guessing Every question your agent asks about a repository has an answer that could have been computed ahead of time. *Who calls this function? What breaks if I change it? Why is it written this way? Which files are actually dangerous?* Without an index, the agent rediscovers that answer on every task: grep, read, re-read, forget. Repowise exposes **ten task-shaped MCP tools** to Claude Code, Codex, Cursor, VS Code and anything else that speaks MCP: graph, git, docs, decisions, and ten MCP tools behind one index. See [the canonical surface](#the-ten-mcp-tools). Most tools are built around data entities (one file, one symbol), which forces agents into long chains of sequential calls. These are built around **tasks**: pass several targets in one call, get complete context back. Because the exploration work is already done, that phase mostly disappears. In a measured agent loop across 43 questions on `django/django`, Repowise cut the agent's own output by **31.6%** (p<0.0001) and reached the answer in **3.8 tool calls instead of 7.2**. That is the end-to-end result. One mechanism is much larger but narrower: loading a commit's context through `get_context` costs **393 tokens instead of 13,984**, or 97.2% less. That is one retrieval payload, not a claim of 97.2% total agent savings. Both measurements and every competitor row are published in [the benchmark report](docs/BENCHMARKS.md). **And it arrives without being asked.** Optional [hooks](docs/agent/HOOKS.md) push context into the session at the moment it matters: the governing architectural decision when your agent edits a file that decision covers, a warning when it touches a file with a run of recent bug fixes, a compact briefing at session start. Repowise also generates your `CLAUDE.md` and `AGENTS.md` from the real index, so even an agent with no MCP support starts informed. **It learns from how you actually work.** Switch on transcript capture (`repowise decision source set session --on`) and Repowise reads your own agent transcripts for the corrections you keep making ("use the shared HTTP client, not raw requests"), turning the durable ones into tracked decisions it delivers back later. Transcripts never leave your machine; one batched model call per update turns the candidates that clear the deterministic gates into records, and `--no-llm` keeps the gates and drops that call. The wiki generation budget tilts toward the modules you and your agent ask about most, with no switch needed.
What the index builds | Foundation | What it contributes | |---|---| | **Graph** | File + symbol dependencies across 26 AST-parsed languages, confidence-stamped call resolution, communities, centrality, cycles, and execution flows | | **Git** | Hotspots, ownership, co-change, bus factor, and bug-fix history: behavioral signals static analysis cannot see | | **Docs** | A wiki for every module and file, rebuilt incrementally with freshness and confidence scoring plus hybrid search | | **Decisions** | Architectural rationale mined from five index-time sources plus human and agent capture, each claim traced to evidence | | **Code health** | 49 deterministic detectors across defect risk, maintainability, and performance, followed by concrete refactoring plans | The structural wiki needs no model. Model-written prose is an optional upgrade, one page or directory at a time. Six of the seven decision sources are deterministic too; only comment archaeology needs a provider. [The intelligence layers →](docs/layers/INTELLIGENCE_LAYERS.md) · [How the graph earns trust →](docs/layers/GRAPH.md)
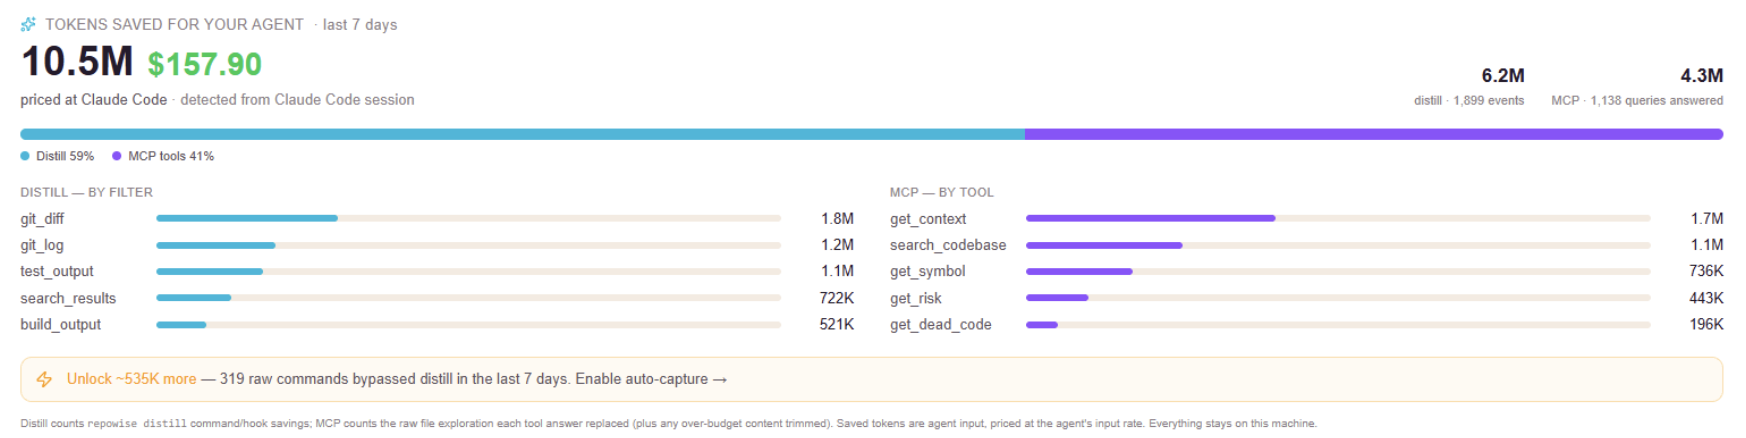
### Also: stop paying for output nobody reads Most of what an agent reads back from a shell command is noise: 300 lines of passing tests wrapped around 4 failures, full commit bodies when it asked "what changed recently". `repowise distill ` compresses command output **before the agent reads it**, errors first, exit code preserved. ```bash repowise distill pytest # 61% fewer tokens, all 11 failure lines kept repowise distill git log -50 # 89% fewer tokens repowise saved # what distillation saved you, in tokens and dollars ``` Nothing is lost. Every omission leaves an inline `[repowise#]` marker that `repowise expand ` reverses in full, so the agent can always pull the detail back without re-running the command. Small outputs pass through untouched. An opt-in hook rewrites noisy commands automatically, shown to you for approval first.
repowise Costs dashboard: tokens and dollars saved across distill and the MCP tools

The Costs dashboard tallies both savings surfaces, priced at your own agent's model. Example from a week of heavy local use.

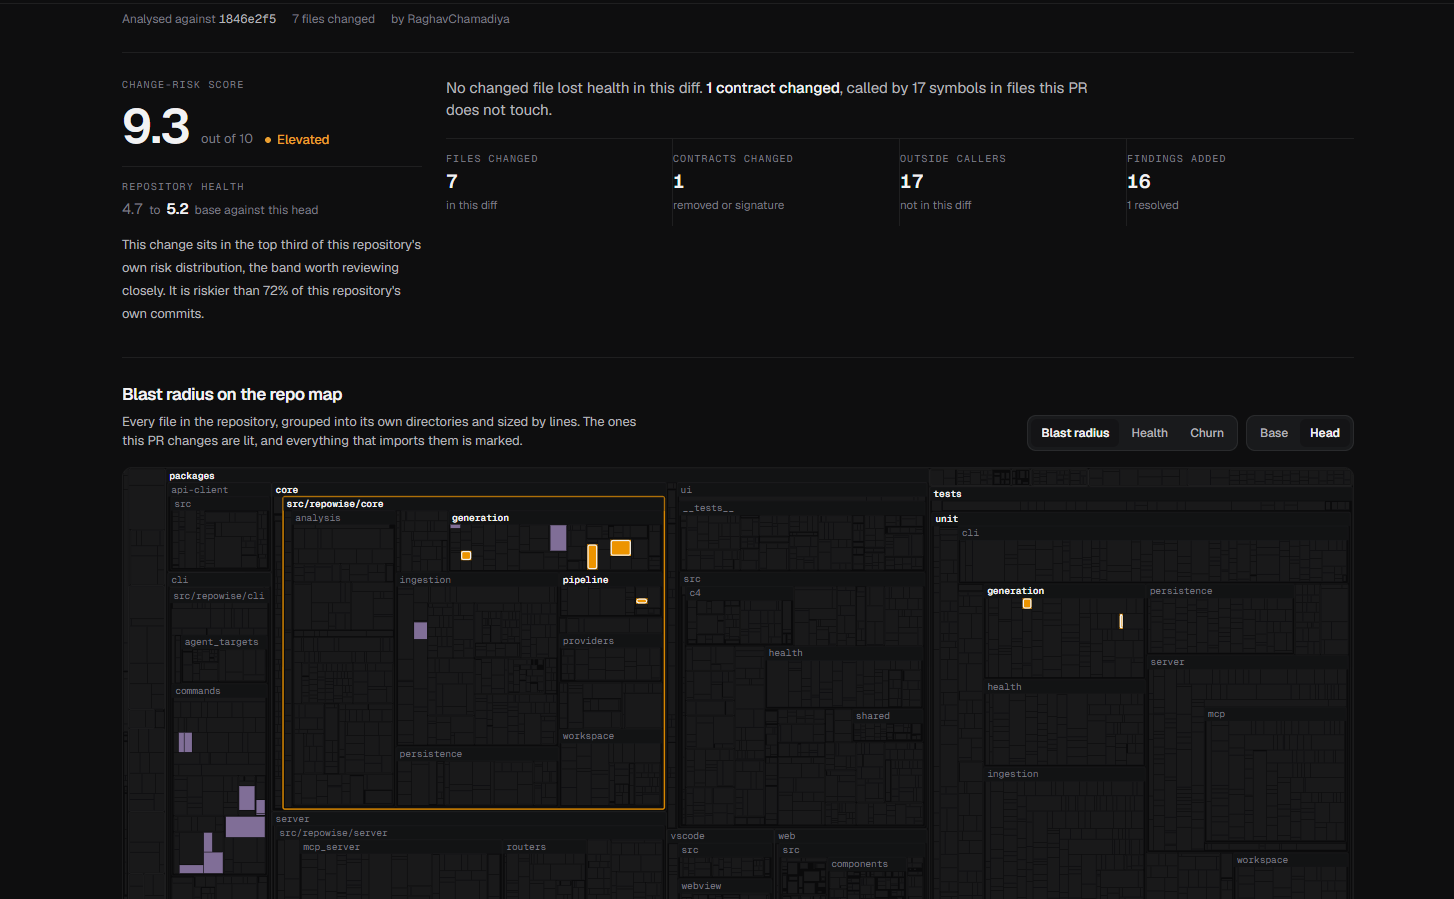
Full guide: **[docs/agent/DISTILL.md →](docs/agent/DISTILL.md)** --- ## Know what's dangerous before you merge Four deterministic signals, all computed from the graph and git history, no LLM: - **Change risk.** Score any commit or `base..HEAD` range **0-10** from the shape of the diff, ranked against your repo's own recent commits. PR mode returns directives rather than vibes: `may_break`, `missing_cochanges`, `missing_tests`, `tests_to_run`. One command: `repowise risk main..HEAD`. ([reference →](docs/layers/CHANGE_RISK.md)) - **Bug history.** Which files and symbols actually get bug-fixed, and how recently. Doc, test and config commits are filtered out so the count means what it says, and a file with a run of recent fixes gets flagged as a bug magnet while you edit it. ([reference →](docs/layers/BUG_HISTORY.md)) - **[Test intelligence](#which-tests-cover-this-file-without-a-coverage-report).** Which tests reach a file and which ones a diff actually exercises, from the call graph, with or without a coverage report. ([reference →](docs/layers/TEST_INTELLIGENCE.md)) - **Change coordination.** Which other open branches edit the files you are editing, every row saying why it is listed (`same file`, or a co-change pair with the commit counts behind it), and whether the diff in front of you is one change or several groups the index links nothing between. Both stay quiet when there is nothing to report. `repowise overlap` and `repowise risk`. ([reference →](docs/layers/CHANGE_RISK.md#branch-overlap)) Plus the free **[Repowise PR Bot](#the-pr-bot)**, which puts all of it on every pull request. Zero LLM calls. --- ## Which tests cover this file, without a coverage report Ingest LCOV, Cobertura or Clover and you get the measured answer. **Most repositories never produce one**, so the graph answers instead: a test file that imports a source file *reaches* it, which is a recorded edge rather than the name-shaped guess everything else falls back to. That fallback fails in both directions, and this repo is the proof. Five of its six worst bug-magnet files have no test named for them and read as untested while the graph names 3 to 23 test files each. The sixth is worse: matching on basename paired the *health* engine with the *distill* engine's tests and called it tested. ```bash repowise impacted-tests main..HEAD # only the tests this diff actually exercises repowise health # untested hotspots, now graph-aware ``` Dogfooded against a real coverage run --contexts=test: 95.7% precision on what reaches a file and 97.5% on the run list, at a 100% hit rate, against 72.1% and 94.8% for the one-hop import walk this replaced. The two tiers are never averaged: rows are stamped basis: "measured" or "inferred", measured wins outright where both can answer, and the inferred tier may never produce a percentage. Sound as a floor, unsound as a quantity, and labelled so. Test intelligence → --- ## The PR bot Install the [GitHub App](https://github.com/apps/repowise-bot) and the index shows up where the decision actually gets made. One comment per pull request, edited in place on every push rather than reposted, and **a green PR gets no comment at all**. See a real comment on a real PR, not a mockup: [repowise-dev/repowise#1204](https://github.com/repowise-dev/repowise/pull/1204). What decides a review is inline. What is context sits behind one fold, so the comment stays about seventeen rows whatever it finds. - **Blast radius, at symbol level.** The contracts this PR changed and every caller of them in a file the PR does not touch. Importing a module says nothing about whether the function you changed is the one being called, so file-level impact is the wrong altitude for the question a reviewer actually has. - **Before you merge.** The tests that import your changed files, and the files that changed alongside them in past commits but are missing here. - **A Check Run that can gate the merge**, with annotations on the specific lines the PR added. Advisory by default. - **Change risk**, scored against the repository's own commit distribution rather than an absolute scale, so it stays meaningful on a repo whose typical commit is large. - **AI vs human authorship** of the changed files, with the average health of each. - Then hotspots, hidden coupling, declining health, dead code and the change map, one fold down. ### And a page the comment links to Markdown runs out. The comment shows three callers and says "+6 more"; the page shows all nine. Public, no sign-in, on a repository the reader has never seen. The dark Repowise per-PR analysis page showing change risk, repository health, changed contracts, outside callers, newly added findings, and a blast-radius treemap of the repository The page leads with change risk and newly introduced findings, then maps every changed file and outside caller across the repository. [See it live →](https://repowise.dev/pr/repowise-dev/repowise/1204) **[Install the PR bot →](https://github.com/apps/repowise-bot)** · [how it works →](https://www.repowise.dev/bot) --- ## ★ Know exactly what to fix A score that says *"this file is risky"* is where most tools stop. Repowise scores every file, locates where the risk concentrates, and then names the specific fix.
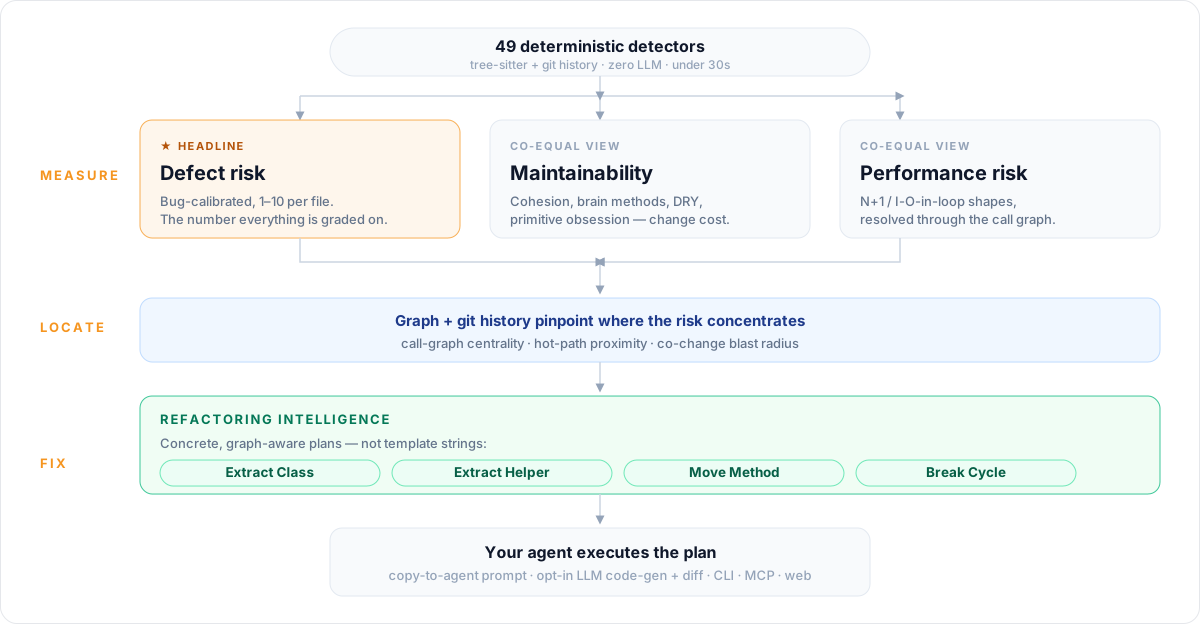
repowise code-health loop: deterministic markers fan into three signals, the graph and git history locate where risk concentrates, and refactoring intelligence emits concrete plans your agent executes
Every file is scored 1-10 by **49 deterministic detectors** (McCabe complexity, brain methods, LCOM4 cohesion, god classes, native Rabin-Karp clone detection, untested hotspots, change entropy, prior-defect history and more), split into three lenses: **defect risk**, **maintainability**, and **performance**: static N+1 and I/O-in-loop risk traced *across* files through the call graph, where file-local linters found **0** of the cross-function cases and repowise surfaced ~90. Only **26** of the 49 are permitted to move the defect number, because that is the number carrying published accuracy claims. > **Zero LLM calls, zero cloud, zero new runtime dependencies.** Pure Python over > tree-sitter and git data, **under 30 seconds** on a 3,000-file repo, a budget > enforced by a CI test, not an estimate. Marker weights are **calibrated against a > real defect corpus, not hand-tuned**: every file scored at a commit preceding the > bug window so nothing leaks backward, and an L2-logistic fit with file size as an > explicit control, so a marker only earns weight for defect lift *beyond* being big. > Only the learned constants ship. **It proves itself on your repo, not just on a benchmark.** After every index, Repowise checks its own flags against your git history and reports what it found: *"16 of the 20 lowest-health files had a bug fix in the last 6 months, 3.3x the 24% baseline."* If that number is bad on your codebase, you will see it. (It is an association on your indexed history, not a forward prediction, the leakage-free version is [in the benchmarks](docs/BENCHMARKS.md#5-code-health-predicts-defects).) Then it names the fix. Not "this class is too big", but **Extract Class**, **Extract Helper**, **Move Method**, **Break Cycle**, **Split File**, or **Extract Method**, with the exact methods, edges and symbols that move, the **blast radius** of callers and co-changing files that have to move with them, and a graph-aware ranking so a fix on a central hub outranks the same fix on a leaf. Extract Method goes down to an intra-procedural dataflow pass that lifts the exact span and infers a behavior-preserving signature. ```bash repowise health # KPIs and lowest-scoring files repowise health --refactoring-targets # ranked, concrete plans repowise health --trend # snapshots plus declining-health alerts ``` The dashboard renders each plan as a card with a copy-to-agent button. An optional LLM step, never in the indexing path and only on request, expands any plan into generated code and a unified diff. Validated on 21 open-source repos across 9 languages (2,826 files, scored at a fixed point and checked against the following 6 months of bug fixes, keyword-labelled): ROC AUC 0.737 [0.683, 0.787]. The signal is correlated with file size and weakens sharply within a fixed size band, which we report rather than bury. Independently recomputed from the raw data. Against CodeScene, the leading commercial code-health tool, on the same 2,770 files and the same defect labels, ranking by repowise health surfaces 2.3x the defects under a fixed review budget (paired, p = 0.003). Full head-to-head, methodology and limitations → Guides: **[code health](docs/layers/CODE_HEALTH.md)** · **[refactoring](docs/layers/REFACTORING.md)** --- ## See all of it `repowise serve` starts the full web dashboard next to the MCP server. No separate setup, all local.
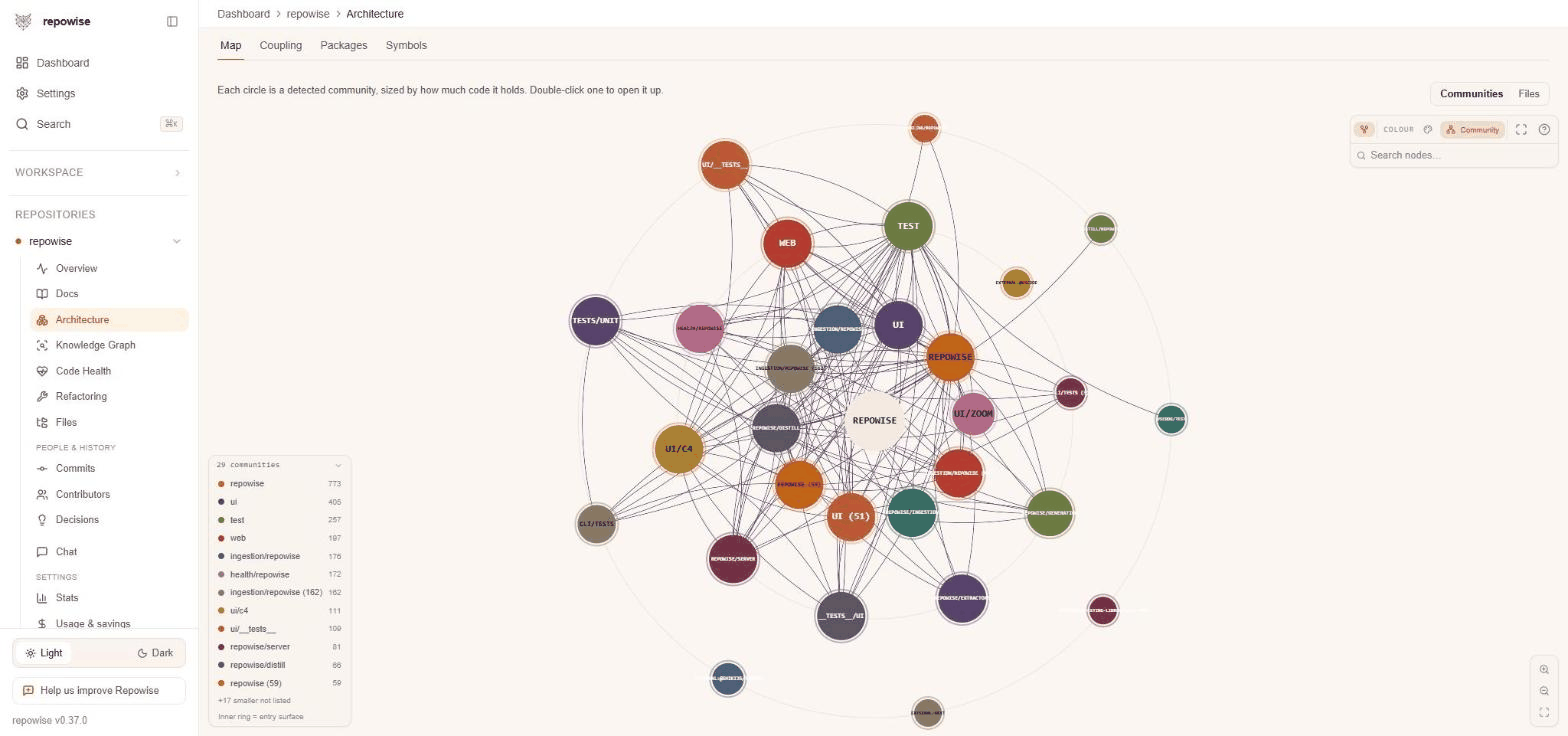
Architecture view: the dependency graph laid out and explorable, with a context drawer per node
Architecture · the dependency graph, laid out and explorable, with per-node context and change coupling
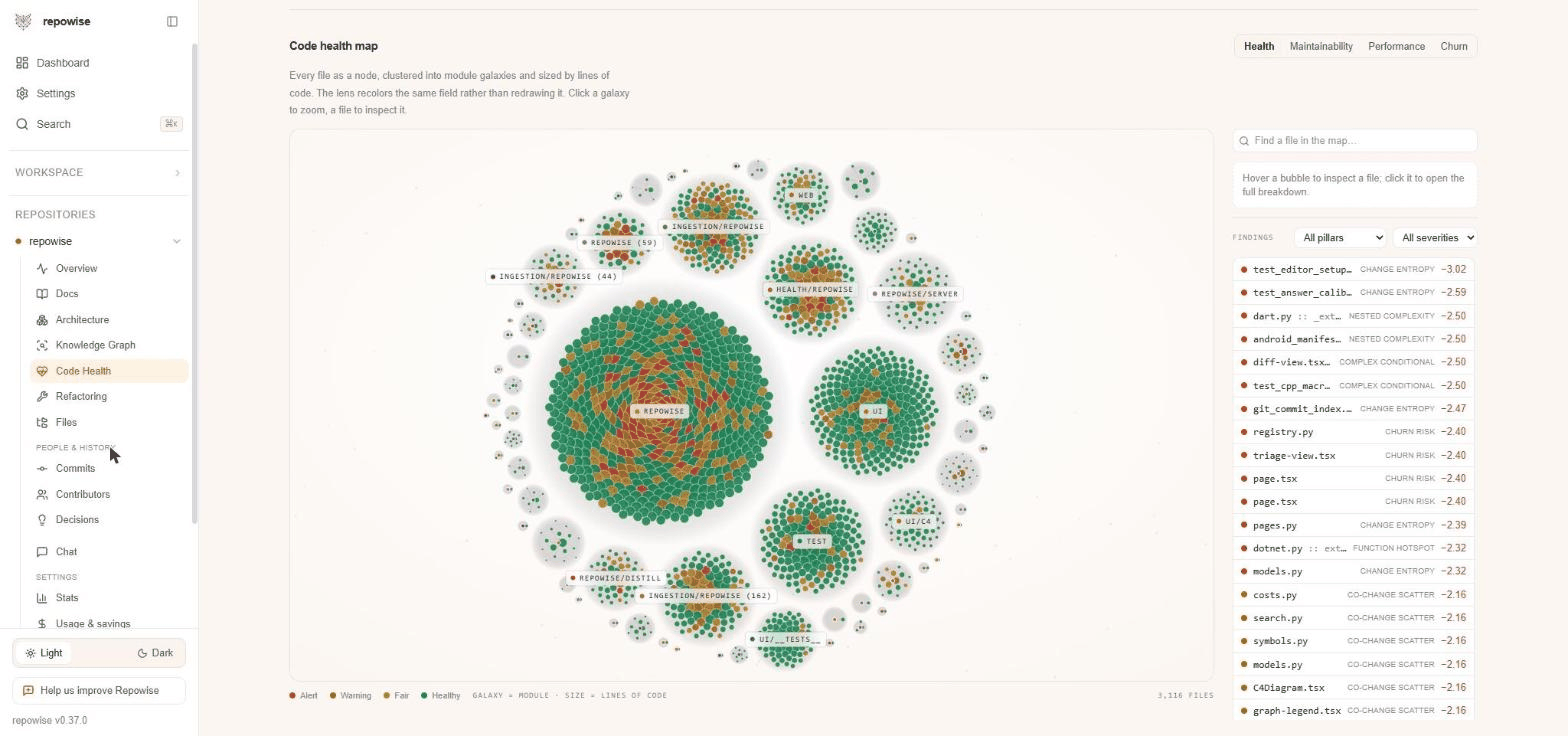
Code health map: every file as a bubble, hover to inspect score, coverage and tests
Code Health · every file as a bubble, hover any one to inspect its score, size, coverage and findings
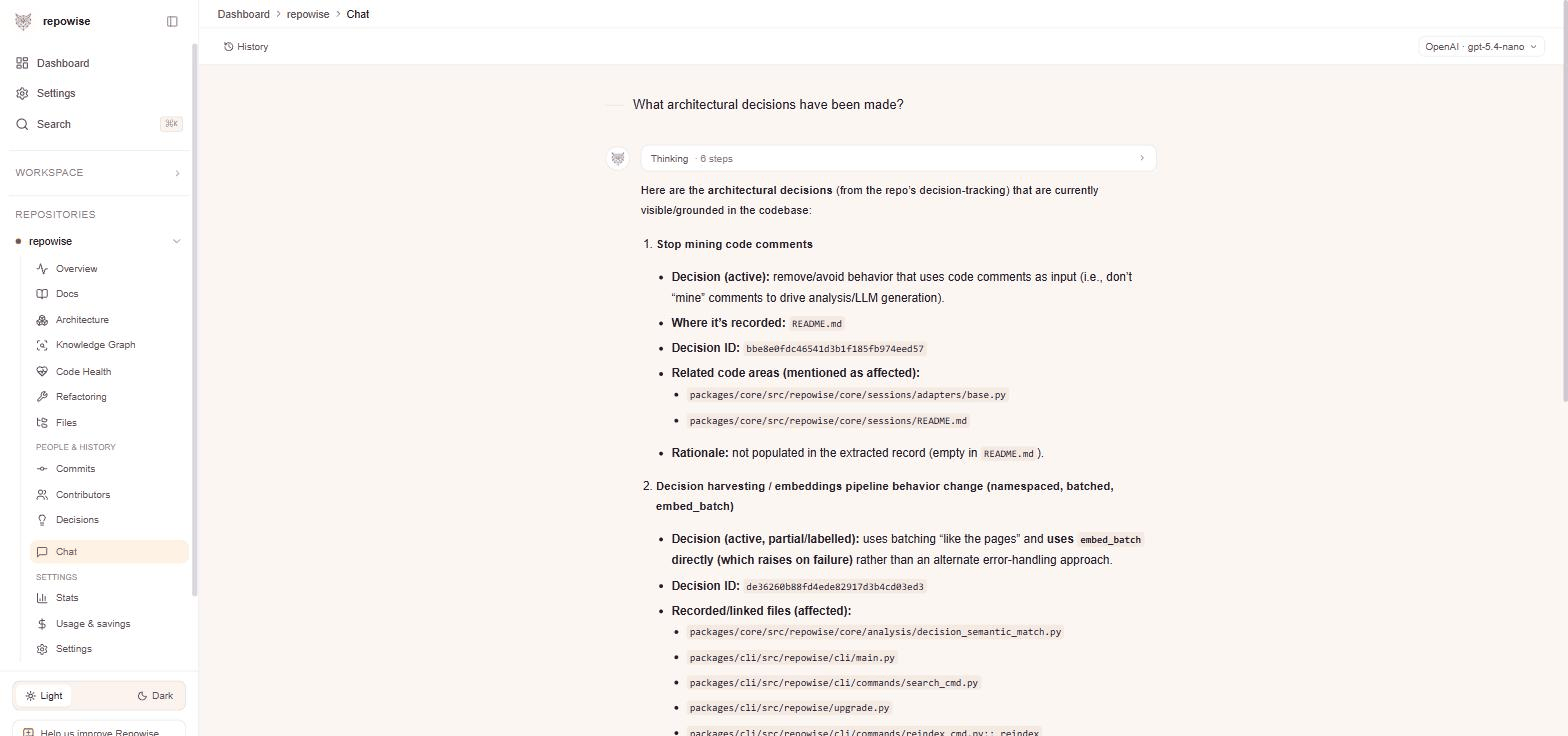
Chat view: ask questions against the indexed repo, with answers that cite the files and pages they came from
Chat · ask the codebase a question, answers cite the files and pages they came from
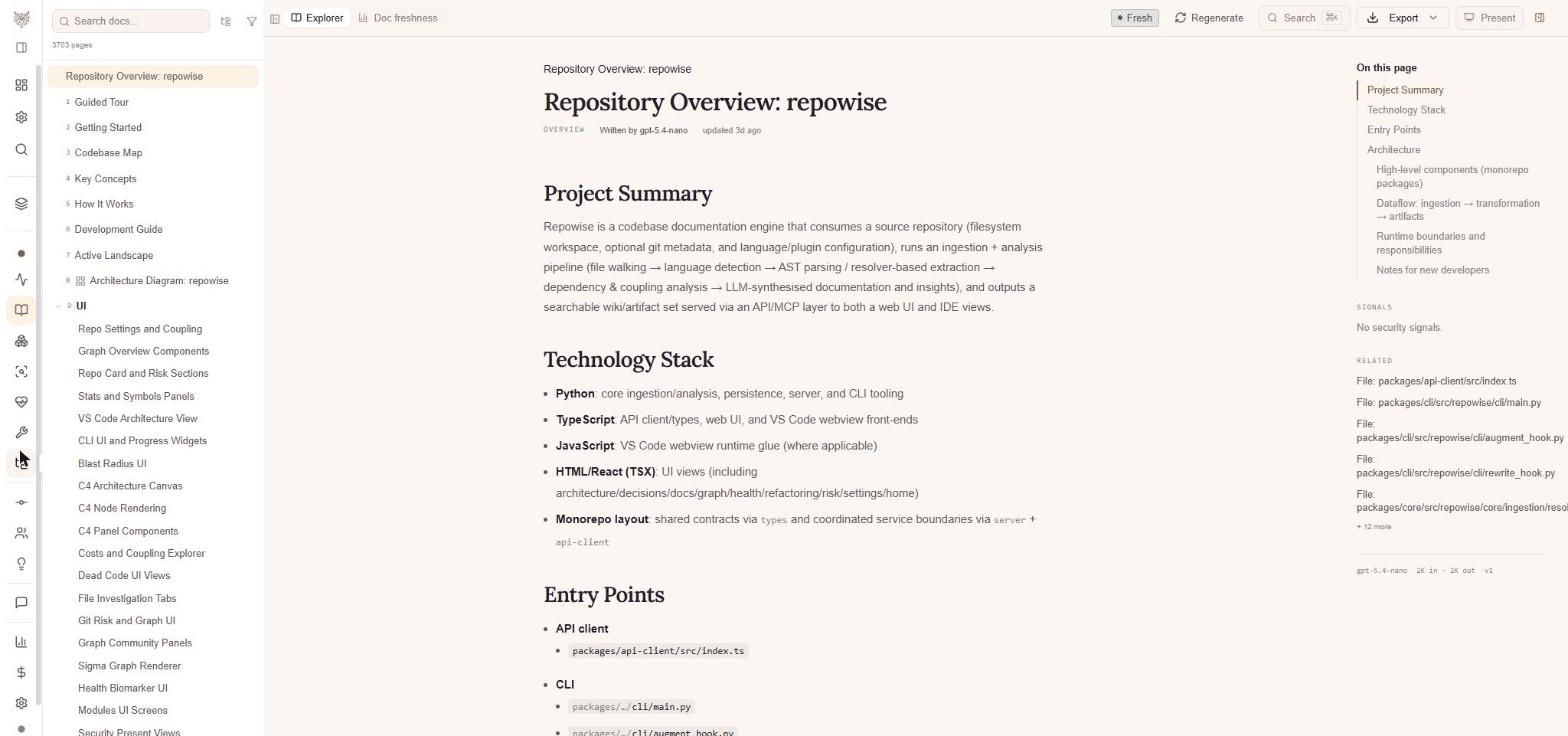
Docs view: auto-generated wiki pages with a tree, mermaid diagrams, and freshness badges
Docs · auto-generated wiki pages for the whole codebase, with confidence and freshness badges
Also in there: **Chat** (ask the codebase in natural language) · **Docs** (the generated wiki, with Mermaid and a graph sidebar) · **Architecture** and **C4** (Context → Containers → Components) · **Knowledge Graph** plus a zoomable canvas map · **Risk**, **Hotspots**, **Coupling** and **Blast radius** · **Contributors** · **Decisions** (evidence drawer and evolution timeline) · **Symbols** · **Security** · **Dead code** · **Stats** · **Costs** · **Workspace**. Every view and what each one answers: **[docs/start/DASHBOARD.md →](docs/start/DASHBOARD.md)** --- ## One intelligence layer across your software estate Real systems are not one repository, and the expensive failures live in the gaps between them. Change a backend contract and Repowise can name the frontend calls that consume it, the services downstream, the historical companion files missing from the change, and the architecture rule the new dependency violates before it ships. | Workspace intelligence | What it answers | |---|---| | **Contract map** | Which services provide and consume each HTTP, gRPC, event, socket, and data contract? Links retain exact/candidate confidence and the source evidence. | | **Cross-repo blast radius** | If this provider changes, which downstream services are in structural reach, and which ones may drift through historical co-change? | | **Breaking-change guard** | Was an endpoint removed or a supported OpenAPI / proto / signature shape changed incompatibly, and which consumer files are linked to that contract? | | **Test impact** | Which tests in the consumer repos should run for this provider change, measured from coverage or inferred from the call graph, and which links could not be determined? | | **Architecture as code** | Does the live system graph violate declared dependency rules or contain cycles? `repowise workspace check` gates CI. | | **Architecture health** | How coupled is the estate? Track propagation cost, the cyclic core, service roles, and a deterministic 1–10 architecture score. | | **Federated context** | One dashboard and one MCP server answer across every repository while preserving repo-level evidence. | The system map models **services**, not merely repository boxes, and never conflates a real contract with “these files often changed together.” HTTP field-level comparison supports the bounded OpenAPI 3.x JSON subset documented in the workspace guide; matched consumers prove endpoint exposure, not field use or runtime failure. **[Workspace guide and exact support matrix →](docs/scale/WORKSPACES.md)** Worktrees and updates stay lightweight: a linked worktree seeds its index from the base checkout automatically, and post-commit hooks, file watching, webhooks, or polling keep each repository and the cross-repo graph current. --- ## In your editor The **Repowise** VS Code extension puts the index where code actually gets written: know what your change breaks before you push (riskiest files ranked, what is downstream, forgotten companion files, missing tests, suggested reviewers), health in the gutter and status bar, callers and ownership on hover, refactoring plans as CodeLens, and the full dashboards inside the editor. One install also registers the MCP server with VS Code, so the same local index serves both you and your agent, and exposes six tools to GitHub Copilot. Quiet by default, everything toggleable, nothing leaves your machine. Install from the Marketplace (search **Repowise**) or Open VSX, then run **Repowise: Set Up This Repository**. Guide: **[docs/agent/VSCODE.md →](docs/agent/VSCODE.md)** --- ## Supported agents **Six agents wired end to end · two at the Full tier · every other MCP host one paste away.**
See integration tiers and supported agents

Full tier   Claude Code Codex CLI

Good tier   VS Code Cursor OpenCode Hermes

**Full** is every surface repowise has: MCP tools, skills, slash commands, a managed instructions file, hook-level interception of tool calls, and transcript mining after the session. **Good** is the honest half of that: MCP tools and the config to reach them, but no hook-level interception and no transcript mining. A Good-tier agent can ask repowise anything; repowise never sees the tool calls in between. The tier is computed from what each integration actually wires, so this list cannot claim a depth the code does not have. Everything else that speaks MCP is one snippet away. `repowise agents print-config claude-code` prints a stdio server entry to paste into Cline, Windsurf, Zed, Gemini CLI or any other host that keys on `mcpServers`, and repowise writes nothing. Adding an agent takes **one descriptor file and one registry line**, with no changes to the orchestrators. Full matrix and the contributor recipe: **[docs/agent/INTEGRATIONS.md →](docs/agent/INTEGRATIONS.md)**
--- ## Supported languages **26 languages parsed to AST · 40 on a five-rung ladder · framework-aware where an ecosystem handler exists.** "Do you support X" has five useful answers, not two, so languages land on a ladder and every rung says what it buys you.
See the complete language ladder

Full tier   Python TypeScript JavaScript Svelte Vue Java Kotlin Go Rust C++ C# Scala Ruby

Good tier   C Swift PHP Dart Object Pascal / Delphi COBOL GDScript / Godot VB.NET Elixir F# Objective-C  · Partial   Luau Razor / Blazor

Below those two rungs the ladder keeps going, and a language on a lower rung is still doing real work rather than being ignored: | Rung | Languages | What you get | |---|---|---| | **Full** (13) | Python · TypeScript · JavaScript · Svelte · Vue · Java · Kotlin · Go · Rust · C++ · C# · Scala · Ruby | The whole pipeline: AST symbols, import resolution, a resolved call graph, heritage, docstrings, framework edges, **and code-health markers** | | **Good** (11) | C · Swift · PHP · Dart · Object Pascal · COBOL · GDScript · VB.NET · Elixir · F# · Objective-C | All of the above except the full health suite, subject to the language-specific ceilings in the full matrix | | **Partial** (2) | Luau / Roblox · Razor / Blazor | Luau: AST symbols and `require()` resolution, Rojo and `.luaurc` aware. Razor: component symbols, `@code` and component-tag call edges, C# health markers; no import resolution yet | | | | ⎯⎯ *tree-sitter parsing stops here; the rungs below come from git and imports* ⎯⎯ | | **Lightweight** (6) | Clojure · Haskell · Lean 4 · Erlang · HTML · QML | A real file-to-file import graph, and no symbol-level claims | | **Structural** (8) | R · Zig · Julia · Elm · OCaml · Crystal · Nim · D | Git history: blame, hotspots, co-change, ownership, bug history | **Every language ships in the open-source distribution.** None is gated behind the commercial licence, and none will be. COBOL now ships at the Good tier; languages still moving up the ladder are tracked on the **[roadmap →](ROADMAP.md#languages)**. SQL and dbt projects get real `ref()` / `source()` lineage, shell scripts get function-level symbols, HTML pages contribute their `