` | path to the audit log file (defaults to `./auditreach.log.jsonl` if omitted) |
node dist/cli.js verify-log --path ./auditreach.log.jsonl
### `auditreach mcp`
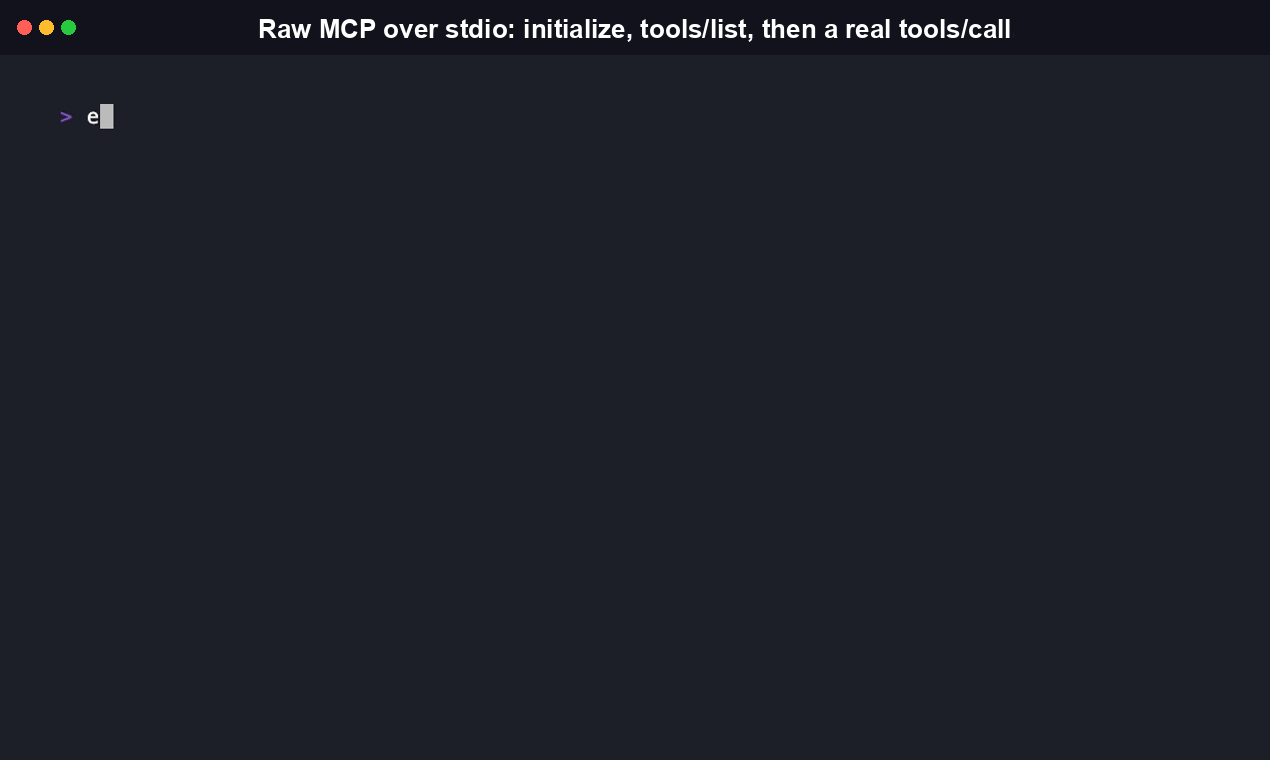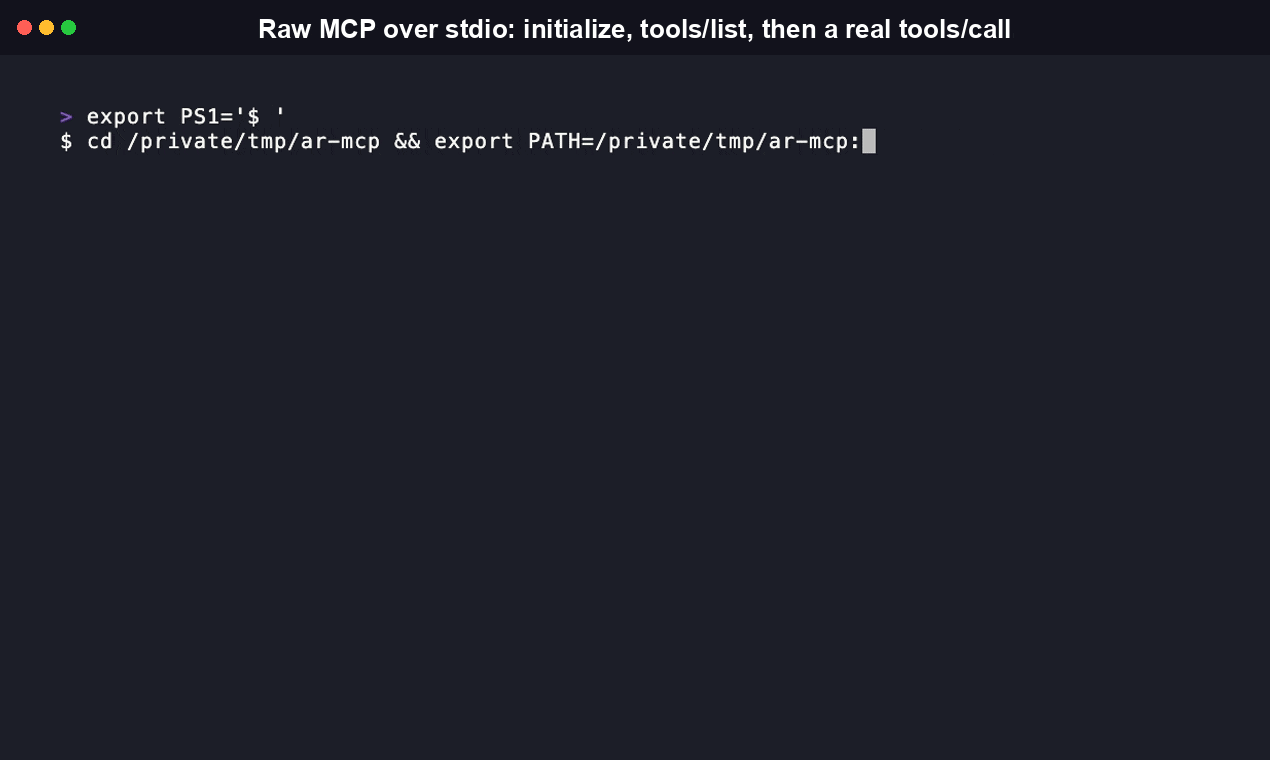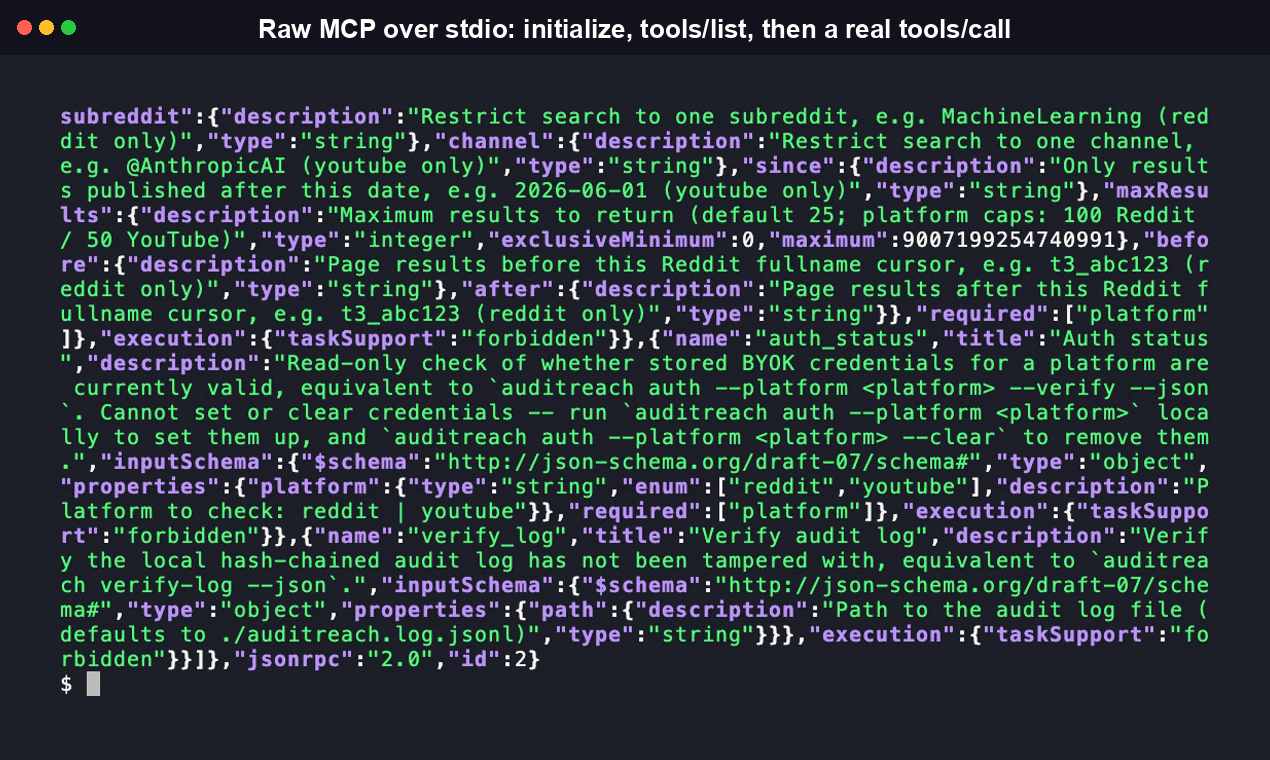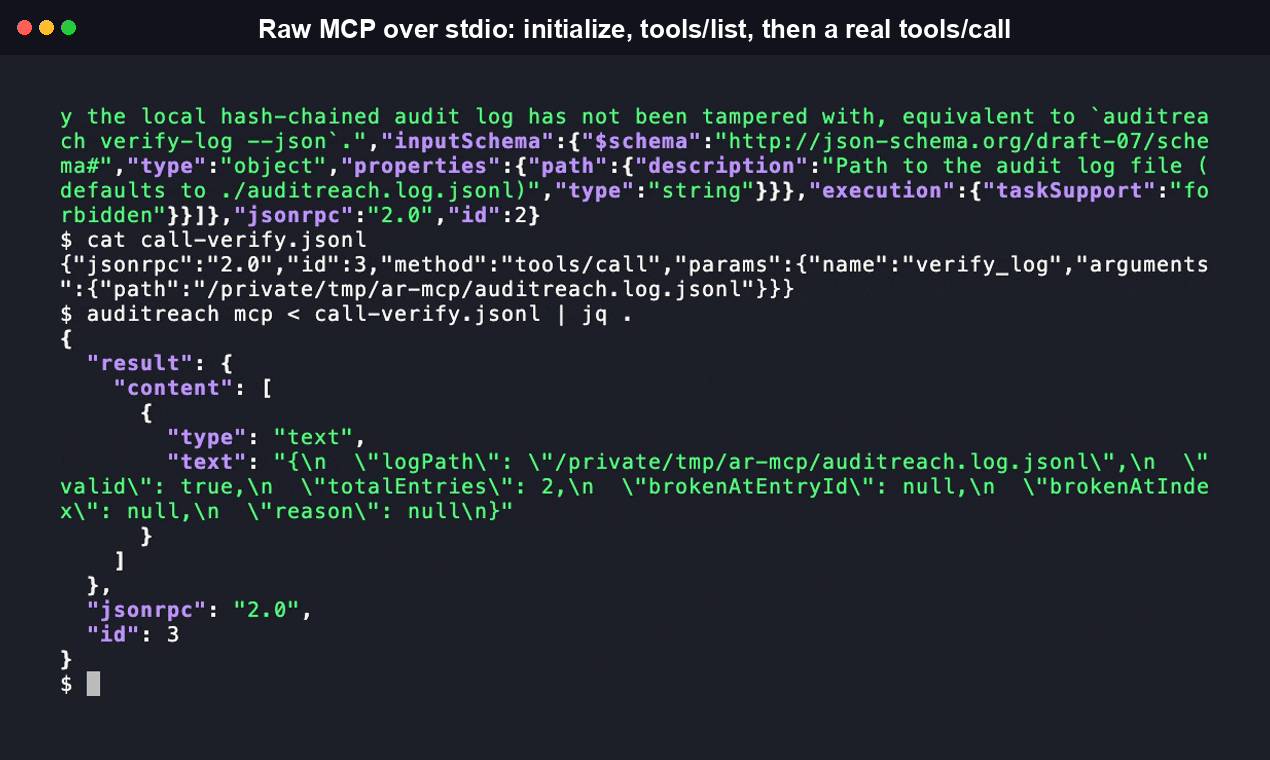
Run a [Model Context Protocol](https://modelcontextprotocol.io) server over stdio (built on the official `@modelcontextprotocol/sdk`), exposing exactly 3 tools so an AI agent can call this CLI directly instead of shelling out and parsing stdout:
| Tool | Equivalent to | Notes |
| ------------- | ------------------------------------------------ | -------------------------------------------------------------------------------------- |
| `search` | `auditreach search --json` | Same parameters: platform, query, subreddit/channel, since, maxResults, before/after |
| `auth_status` | `auditreach auth --platform --verify --json` | **Read-only.** Checks whether stored credentials are valid -- cannot set or clear them |
| `verify_log` | `auditreach verify-log --json` | Same parameters: path |
node dist/cli.js mcp
# or, once published: npx auditreach-cli mcp
Add it to your MCP client's config (for Claude Desktop, `claude_desktop_config.json`). Either
distribution works since both ship the same `mcp` subcommand:
```json
{
"mcpServers": {
"auditreach": {
"command": "npx",
"args": ["-y", "auditreach-cli", "mcp"]
}
}
}
```
or, from the PyPI package:
```json
{
"mcpServers": {
"auditreach": {
"command": "uvx",
"args": ["--from", "auditreach-cli", "auditreach", "mcp"]
}
}
}
```
Setting up or clearing BYOK credentials (`auditreach auth --platform
` / `--clear`) is deliberately **not** exposed over MCP -- that stays a local-CLI-only, human-driven action, so a calling agent can check whether credentials work but can never provision or wipe them itself. See [`.well-known/agent.json`](.well-known/agent.json) for the machine-readable manifest (auth requirements, tool schemas, invocation commands) that an agent or agent registry can read to discover this server without a human reading the README first.
Run `auditreach --help` any time to see the exact flags your installed version supports.
## Library API reference
`auditreach-cli` doubles as an importable library. Every export below comes straight from `dist/index.d.ts` in the published package.
```ts
import {
RedditClient,
YoutubeClient,
getCredential,
setCredential,
deleteCredential,
getRedditCredentials,
getYoutubeCredentials,
appendAuditLogEntry,
getLastEntryHash,
computeEntryHash,
verifyAuditLogChain,
credentialFingerprint,
canonicalJson,
sha256Hex,
DEFAULT_AUDIT_LOG_PATH,
executeSearch,
SearchCommandError,
checkAuthStatus,
executeVerifyLog,
buildMcpServer,
runMcpServerCommand,
} from "auditreach-cli";
```
**Clients**
- `new RedditClient(credentials: RedditCredentials)` -- talks to Reddit's official OAuth API only, using the password grant ("script app" flow). `.search(options: RedditSearchOptions): Promise`, `.verifyCredentials(): Promise`.
- `new YoutubeClient(credentials: YoutubeCredentials)` -- wraps the official YouTube Data API v3. `.search(options: YoutubeSearchOptions): Promise`, `.verifyCredentials(): Promise` (a 1-quota-unit call, no query needed).
```ts
const credentials = getRedditCredentials();
if (!credentials) throw new Error("run `auditreach auth --platform reddit` first");
const client = new RedditClient(credentials);
const outcome = await client.search({
query: "agent memory poisoning",
subreddit: "MachineLearning",
});
```
**Credentials** (`setCredential` / `getCredential` / `deleteCredential` / `getRedditCredentials` / `getYoutubeCredentials`) -- all credential I/O goes through this module. It's the one place allowed to touch a raw secret; values come back only to hand directly to a client's constructor, never to log or print.
**Audit log**
- `appendAuditLogEntry(entryWithoutHash: UnhashedAuditLogEntry, logPath?: string): Promise` -- the only write path into the log; entries are never edited or deleted in place.
- `getLastEntryHash(logPath?: string): Promise`
- `computeEntryHash(entry: UnhashedAuditLogEntry): string`
- `verifyAuditLogChain(logPath?: string): Promise` -- re-derives every entry's hash and checks the chain end to end.
- `DEFAULT_AUDIT_LOG_PATH` -- `"./auditreach.log.jsonl"`
```ts
const result = await verifyAuditLogChain();
if (!result.valid) {
console.error(`Chain broken at entry ${result.brokenAtIndex}: ${result.reason}`);
}
```
**Crypto utilities**
- `canonicalJson(value: unknown): string` -- recursively sorts object keys so the same logical entry always serializes to the same bytes, which the hash chain depends on to verify deterministically.
- `sha256Hex(input: string): string`
- `credentialFingerprint(secret: string): string` -- keeps only the last 6 hex characters of a scrypt-derived hash (emitted in the audit log as `scrypt:<6 hex>`), enough to distinguish rotated keys in a local audit log, never enough to be a partial credential leak.
**Command cores and MCP**
- `executeSearch(args)`, `checkAuthStatus(platform)`, `executeVerifyLog(path?)` -- the same programmatic cores the `search` / `auth --verify` / `verify-log` CLI commands and the MCP tools both call into; none of them write to console/stdout, so they're safe to call from any host, including one sharing stdout with an MCP transport.
- `SearchCommandError` -- the error class `executeSearch` throws for an expected, user-actionable failure: no BYOK credentials stored yet for the target platform, or a Reddit search called without `--query`. Catch it specifically to distinguish "you called this wrong" from a real network/API failure.
- `buildMcpServer({ version }): McpServer` -- constructs the MCP server (from `@modelcontextprotocol/sdk`) with the `search` / `auth_status` / `verify_log` tools registered, without starting a transport -- useful for testing or embedding in a larger MCP server.
- `runMcpServerCommand({ version })` -- what `auditreach mcp` runs: builds the server and connects it over stdio. Never returns while the server is running.
No generated API docs site exists yet (no TypeDoc build wired into CI) -- the exports above are the complete public surface. Check `dist/index.d.ts` in the published package for exact types.
The Python package (`auditreach-cli` on PyPI) exposes the same surface with `snake_case` names -- `from auditreach import RedditClient, YoutubeClient, get_reddit_credentials, verify_audit_log_chain, ...` -- see [python/README.md](python/README.md) for the full Python API reference.
## Platform coverage
| Platform | API used | Status | Known constraint |
| ----------- | ----------------------------------------------- | ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Reddit | Reddit API (OAuth2 password grant, direct REST) | Shipped | Rate limits are generally workable for real research volumes |
| YouTube | YouTube Data API v3 (`googleapis`) | Shipped | Quota-based (10,000 units/day default), generally workable |
| X (Twitter) | X API v2 | **Not yet shipped** | X's official API pricing and post-volume caps have been widely reported as prohibitive for small teams doing meaningful research since the 2023 pricing changes. Deferred until a real user needs it enough to fund working around that constraint -- shipping it half-working would undercut the entire "honest about what official APIs can and can't do" premise this tool is built on. |
## Result limits
`--max-results ` controls how many items a single `search` call returns. Leave it off and auditreach silently applies a default of 25 -- the same shape of surprise PRAW's `get_comments()` had for years ([praw#119](https://github.com/praw-dev/praw/issues/119)): a caller who does not already know to pass the flag gets a quietly truncated result set.
> [!NOTE]
> A search that returns exactly the applied limit (25 by default, or your `--max-results` value) may not be the full result set. auditreach prints a stderr warning when this happens, but scripts that only parse stdout/`--json` output won't see it -- check for the warning or pass an explicit `--max-results` if completeness matters.
| Platform | Default (flag omitted) | Maximum (`--max-results`) |
| -------- | ---------------------- | ------------------------- |
| Reddit | 25 | 100 |
| YouTube | 25 | 50 |
Values above the cap are silently clamped to it. For Reddit, `--before`/`--after` let you page through a search's result set using the real cursor Reddit's own response returns, up to Reddit's own ~1,000-item search cap (see [Success stories](#success-stories) for why cursor pagination alone can't go further than that); YouTube has no equivalent yet. Whenever the number of items returned equals the limit that was actually applied, whether that is the silent default or an explicit `--max-results` value, auditreach prints a warning to stderr telling you more results may exist and how to raise `--max-results` (up to the platform cap).
## What is a "consent basis," honestly
The `consent_basis` field on every audit-log entry names the specific platform API terms and auth mechanism used for that query. It certifies that the request went through the platform's official, documented API surface under the credentials you supplied. **It does not certify that your specific use case is legally sufficient for your jurisdiction or contract** -- that determination is yours to make, informed by an accurate, complete, tamper-evident record of what actually happened.
## Self-hosting / local-only by default
Nothing about auditreach requires a hosted account or server. Every command runs entirely on your machine; the audit log is a plain file you own. This is the same flow as [Install](#install) above:
git clone https://github.com/RudrenduPaul/auditreach.git
cd auditreach
npm install
npm run build
node dist/cli.js search --platform reddit --query "..."
## Development
**TypeScript (this package):**
npm install
npm run lint # ESLint
npm run format # Prettier check
npm run typecheck # tsc --noEmit --strict
npm run test:coverage # vitest, 91 tests, 95.1% statement coverage
**Python (`python/`):**
cd python
python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
pytest # 95 tests
See `CONTRIBUTING.md` for the rules on adding a new platform client -- the short version: official API only, honest rate-limit disclosure, tests that mock the network boundary, never anything that reads or writes a raw credential outside `src/auth/credential-store.ts` (or `python/src/auditreach/auth/credential_store.py` on the Python side).
## Security
See `SECURITY.md` for the vulnerability disclosure policy. A pre-launch OWASP/STRIDE review found zero CRITICAL/HIGH findings in auditreach's own code. `ip-address` and `hono` -- both pulled in transitively by the official `@modelcontextprotocol/sdk` dependency's HTTP-transport code, a path `auditreach mcp` never runs (it only ever starts the SDK's stdio transport, `StdioServerTransport`) -- previously carried advisories; `package.json`'s `overrides` field now pins both to patched versions. As of this writing, `npm audit --audit-level=high` on a fresh install reports 0 vulnerabilities. GitHub secret scanning and push protection are enabled on this repo.
## Success stories
Four real issues reported against `praw-dev/praw` -- PRAW, Reddit's official Python API
wrapper, and the closest thing this project has to prior art -- root-caused against
auditreach's own source and used to close genuine gaps in this tool before it had a
single outside user. Each line below is tied to the actual report that prompted it.
- **[praw#614](https://github.com/praw-dev/praw/issues/614)** (@mananwason) -- asked how
to page past Reddit's ~1,000-result search cap. The real fix is narrower than that:
Reddit's own API returns no before/after cursor at all once you're past that cap,
cursor-based paging or not -- confirmed directly in the issue thread. What `search()`
actually does now is extract the real cursor from Reddit's response
(`SearchOutcome.nextCursor`) and expose `--before`/`--after` flags so you can page
through the results within a single search's capped result set, instead of only ever
seeing the first page. Going past the 1,000-item cap itself needs cloudsearch
timestamp-window re-querying, which isn't built yet.
- **[praw#1939](https://github.com/praw-dev/praw/issues/1939)** (@Auditormadness9) -- hit
an undiagnosed 400 error caused by a subreddit name that still carried a leading `r/`
prefix. Search errors now name that specific cause when it's the likely culprit:
previously the CLI just returned a bare status code and left the guessing to you.
- **[praw#984](https://github.com/praw-dev/praw/issues/984)** (@MaxMatti) -- asked for a
simple way to check whether Reddit bot credentials were still valid, without PRAW's
confusing `getMe()`-recursion workaround. `auditreach auth --platform reddit --verify`
does exactly that now: one lightweight check, no search required, nothing written to
disk.
- **[praw#119](https://github.com/praw-dev/praw/issues/119)** (@nsp) -- hit PRAW's
historic silent 25-result default, discoverable only by reading an unrelated base
class's docstring; PRAW's own maintainer admitted he "wasn't sure the best way to make
this clear." `--help` and this README now state the real default and per-platform
caps, and a runtime warning fires whenever a search actually got truncated.
## FAQ
**What is auditreach, and what makes it different from other Reddit/YouTube research tools?**
It is a BYOK CLI (and MCP server) that talks to Reddit and YouTube only through their official, documented APIs, using your own API keys, and writes a hash-chained audit-log entry for every query -- platform, endpoint, scope, and the specific consent/ToS basis for that call. The differentiator is what it refuses to do: no cookie import, no shared-session scraping, no code path that pretends to be a logged-in human. See [Why auditreach exists](#why-auditreach-exists) for the full reasoning and [How it compares](#how-it-compares) for the table against named alternatives.
**What platforms and versions does auditreach run on?**
The npm package (`auditreach-cli`) requires Node.js 20 or newer (`engines` field in `package.json`). The PyPI package (also `auditreach-cli`) requires Python 3.10+ (`requires-python` in `python/pyproject.toml`), which also carries the `Operating System :: OS Independent` classifier. Credentials go into your OS keychain through `@napi-rs/keyring` (npm) or `keyring` (PyPI) instead of a config file, so there is no platform-specific setup beyond having Node or Python installed.
**Does auditreach store my Reddit or YouTube credentials anywhere?**
No. Credentials go straight into your OS keychain through `@napi-rs/keyring` (`src/auth/credential-store.ts`). There is no config file, no environment variable, and no code path that writes a raw credential to disk.
**How many results does a search return by default, and can I get more?**
25, silently, unless you pass `--max-results` -- see [Result limits](#result-limits). The hard cap is 100 for Reddit and 50 for YouTube. A stderr warning fires whenever a search actually hits the applied limit, whether that's the silent default or an explicit value you passed.
**How do I check my credentials are still valid without running a real search?**
`node dist/cli.js auth --platform reddit --verify` (or `--platform youtube`). It performs the minimal authenticated check and reports pass or fail, with no `--query` needed, no results file written, and no audit-log entry appended.
**Is the audit log actually tamper-evident, or just a log file?**
Tamper-evident: each entry's hash is computed from its own content and the next entry references it, so `verify-log` can point to the exact entry a hand-edit broke. See the demo under [What it does](#what-it-does).
**What are auditreach's current limitations?**
Two worth knowing up front. First, X (Twitter) is not shipped -- X API v2's pricing and post-volume caps have been prohibitive for small teams doing real research since the 2023 changes; see [Platform coverage](#platform-coverage). Second, Reddit paging: `search()` reads the real `after`/`before` cursor out of Reddit's own response and exposes `--before`/`--after` flags to page through a single search's result set, but that does not get you past Reddit's own ~1,000-item search cap -- see the [praw#614 success story](#success-stories) for what the fix covers and doesn't.
**How does the MCP server mode work?**
`auditreach mcp` (npm) or `pipx run auditreach-cli mcp` (PyPI) starts a [Model Context Protocol](https://modelcontextprotocol.io) server over stdio, built on the official `@modelcontextprotocol/sdk` / `mcp` SDKs. It exposes exactly 3 tools -- `search`, `auth_status` (read-only, cannot set or clear credentials), and `verify_log` -- each a thin wrapper around the same programmatic core the CLI commands use, so nothing is reimplemented for the agent path. See [`auditreach mcp`](#auditreach-mcp) above for the full tool table and [`.well-known/agent.json`](.well-known/agent.json) for the machine-readable manifest an agent registry can read directly.
**How does auditreach compare to Agent-Reach specifically?**
Agent-Reach covers more platforms (six, versus auditreach's two) by importing a logged-in browser session and scraping as that user, at zero API cost. auditreach only calls official, documented APIs with your own keys and writes a hash-chained consent/audit entry per query; it has no session-import code path at all. Neither approach is strictly better -- they're built for different buyers. See [How it compares](#how-it-compares) for the full side-by-side.
**Is auditreach free to use commercially, and what does the license actually require?**
Yes. auditreach is Apache 2.0 (see `LICENSE`), which permits commercial use, modification, and redistribution, including as part of a closed-source product. The conditions are: include a copy of the license with anything you redistribute, mark any files you modified, and keep the existing copyright/attribution notices. It does not grant rights to auditreach's name or trademarks.
## Contributing
See `CONTRIBUTING.md` for the rules on adding a new platform client. Short version: official API only, honest rate-limit disclosure, tests that mock the network boundary, never a code path that reads or writes a raw credential outside `src/auth/credential-store.ts`.
## License
Apache 2.0. See `LICENSE`.