# SeqKit - a cross-platform and ultrafast toolkit for FASTA/Q file manipulation
- [**Try SeqKit in your browser**](https://sandbox.bio/tutorials/seqkit-intro) (Tutorials and Exercises provided by [sandbox.bio](https://sandbox.bio/tutorials/seqkit-intro))
- **Documents:** [http://bioinf.shenwei.me/seqkit](http://bioinf.shenwei.me/seqkit)
([**Usage**](http://bioinf.shenwei.me/seqkit/usage/),
[**FAQs**](http://bioinf.shenwei.me/seqkit/faq/),
[**Tutorial**](http://bioinf.shenwei.me/seqkit/tutorial/),
and
[**Benchmark**](http://bioinf.shenwei.me/seqkit/benchmark/))
- **Source code:** [https://github.com/shenwei356/seqkit](https://github.com/shenwei356/seqkit)
[](https://github.com/shenwei356/seqkit)
[](https://github.com/shenwei356/seqkit/blob/master/LICENSE)
- **Latest version:** [](https://github.com/shenwei356/seqkit/releases)
[](http://bioinf.shenwei.me/seqkit/download/)
[](http://bioinf.shenwei.me/seqkit/download/)
[](https://anaconda.org/bioconda/seqkit)
- **[Please cite](#citation):** [](https://doi.org/10.1002/imt2.191) [](https://doi.org/10.1002/imt2.191)
- **Others**: [](https://biotreasury.rjmart.cn/#/tool?id=10081)
 ## Features
- **Easy to install** ([download](http://bioinf.shenwei.me/seqkit/download/))
- Providing statically linked executable binaries for multiple platforms (Linux/Windows/macOS, amd64/arm64)
- Light weight and out-of-the-box, no dependencies, no compilation, no configuration
- `conda install -c bioconda seqkit`
- **Easy to use**
- Ultrafast (see [technical-details](http://bioinf.shenwei.me/seqkit/usage/#technical-details-and-guides-for-use) and [benchmark](http://bioinf.shenwei.me/seqkit/benchmark))
- Seamlessly parsing both FASTA and FASTQ formats
- Supporting (`gzip`/`xz`/`zstd`/`bzip2`/`lz4` compressed) STDIN/STDOUT and input/output file, easily integrated in pipe
- Reproducible results (configurable rand seed in `sample` and `shuffle`)
- Supporting custom sequence ID via regular expression
- Supporting [Bash/Zsh autocompletion](http://bioinf.shenwei.me/seqkit/download/#shell-completion)
- **Versatile commands** ([usages and examples](http://bioinf.shenwei.me/seqkit/usage/))
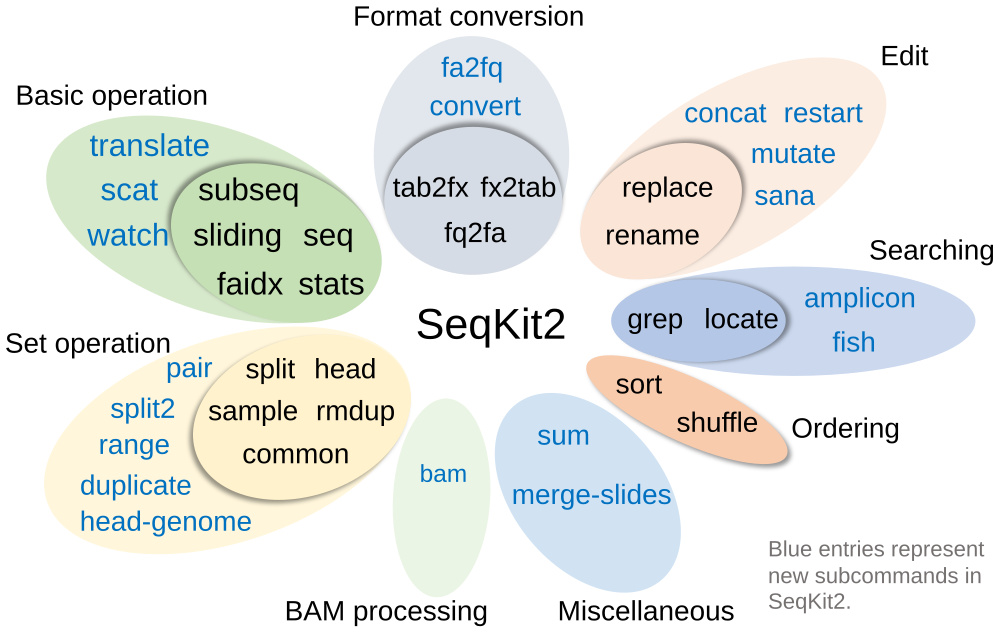
- Practical functions supported by [39 subcommands](#subcommands)
## Installation
#### Method 1: Download binaries
Go to [Download Page](http://bioinf.shenwei.me/seqkit/download), where you can find download links to various platforms.
#### Method 2: Install via Pixi
pixi global install -c bioconda seqkit
#### Method 3: Install via conda
conda install -c bioconda seqkit
#### Method 4: Install via homebrew
brew install seqkit
## Subcommands
|Category |Command |Function |Input |Strand-sensitivity|Multi-threads|
|:----------------|:-------------------------------------------------------------------|:--------------------------------------------------------------------------------------------|:--------------|:-----------------|:------------|
|Basic operation |[seq](https://bioinf.shenwei.me/seqkit/usage/#seq) |Transform sequences: extract ID/seq, filter by length/quality, remove gaps… |FASTA/Q | | |
| |[stats](https://bioinf.shenwei.me/seqkit/usage/#stats) |Simple statistics: #seqs, min/max_len, N50, Q20%, Q30%… |FASTA/Q | |✓ |
| |[subseq](https://bioinf.shenwei.me/seqkit/usage/#subseq) |Get subsequences by region/gtf/bed, including flanking sequences |FASTA/Q |+ or/and - | |
| |[sliding](https://bioinf.shenwei.me/seqkit/usage/#sliding) |Extract subsequences in sliding windows |FASTA/Q |+ only | |
| |[faidx](https://bioinf.shenwei.me/seqkit/usage/#faidx) |Create the FASTA index file and extract subsequences (with more features than samtools faidx)|FASTA |+ or/and - | |
| |[translate](https://bioinf.shenwei.me/seqkit/usage/#translate) |translate DNA/RNA to protein sequence |FASTA/Q |+ or/and - | |
| |[watch ](https://bioinf.shenwei.me/seqkit/usage/#watch ) |Monitoring and online histograms of sequence features |FASTA/Q | | |
| |[scat ](https://bioinf.shenwei.me/seqkit/usage/#scat ) |Real time concatenation and streaming of fastx files |FASTA/Q | |✓ |
|Format conversion|[fq2fa](https://bioinf.shenwei.me/seqkit/usage/#fq2fa) |Convert FASTQ to FASTA format |FASTQ | | |
| |[fx2tab](https://bioinf.shenwei.me/seqkit/usage/#fx2tab) |Convert FASTA/Q to tabular format |FASTA/Q | | |
| |[fa2fq](https://bioinf.shenwei.me/seqkit/usage/#fa2fq) |Retrieve corresponding FASTQ records by a FASTA file |FASTA/Q |+ only | |
| |[tab2fx](https://bioinf.shenwei.me/seqkit/usage/#tab2fx) |Convert tabular format to FASTA/Q format |TSV | | |
| |[convert](https://bioinf.shenwei.me/seqkit/usage/#convert) |Convert FASTQ quality encoding between Sanger, Solexa and Illumina |FASTA/Q | | |
|Searching |[grep](https://bioinf.shenwei.me/seqkit/usage/#grep) |Search sequences by ID/name/sequence/sequence motifs, mismatch allowed |FASTA/Q |+ and - |partly, -m |
| |[locate](https://bioinf.shenwei.me/seqkit/usage/#locate) |Locate subsequences/motifs, mismatch allowed |FASTA/Q |+ and - |partly, -m |
| |[amplicon](https://bioinf.shenwei.me/seqkit/usage/#amplicon) |Extract amplicon (or specific region around it), mismatch allowed |FASTA/Q |+ and - |partly, -m |
| |[fish](https://bioinf.shenwei.me/seqkit/usage/#fish) |Look for short sequences in larger sequences |FASTA/Q |+ and - | |
|Set operation |[sample](https://bioinf.shenwei.me/seqkit/usage/#sample) |Sample sequences by number or proportion |FASTA/Q | | |
| |[sample2](https://bioinf.shenwei.me/seqkit/usage/#sample2) |Sample sequences by number or proportion (version 2) |FASTA/Q | | |
| |[rmdup](https://bioinf.shenwei.me/seqkit/usage/#rmdup) |Remove duplicated sequences by ID/name/sequence |FASTA/Q |+ and - | |
| |[common](https://bioinf.shenwei.me/seqkit/usage/#common) |Find common sequences of multiple files by id/name/sequence |FASTA/Q |+ and - | |
| |[duplicate](https://bioinf.shenwei.me/seqkit/usage/#duplicate) |Duplicate sequences N times |FASTA/Q | | |
| |[split](https://bioinf.shenwei.me/seqkit/usage/#split) |Split sequences into files by id/seq region/size/parts (mainly for FASTA) |FASTA preferred| | |
| |[split2](https://bioinf.shenwei.me/seqkit/usage/#split2) |Split sequences into files by size/parts (FASTA, PE/SE FASTQ) |FASTA/Q | | |
| |[head](https://bioinf.shenwei.me/seqkit/usage/#head) |print the first N FASTA/Q records, or leading records whose total length >= L |FASTA/Q | | |
| |[head-genome](https://bioinf.shenwei.me/seqkit/usage/#head-genome) |Print sequences of the first genome with common prefixes in name |FASTA/Q | | |
| |[range](https://bioinf.shenwei.me/seqkit/usage/#range) |Print FASTA/Q records in a range (start:end) |FASTA/Q | | |
| |[pair](https://bioinf.shenwei.me/seqkit/usage/#pair) |Patch up paired-end reads from two fastq files |FASTA/Q | | |
|Edit |[replace](https://bioinf.shenwei.me/seqkit/usage/#replace) |Replace name/sequence by regular expression |FASTA/Q |+ only | |
| |[rename](https://bioinf.shenwei.me/seqkit/usage/#rename) |Rename duplicated IDs |FASTA/Q | | |
| |[concat](https://bioinf.shenwei.me/seqkit/usage/#concat) |Concatenate sequences with same ID from multiple files |FASTA/Q |+ only | |
| |[restart](https://bioinf.shenwei.me/seqkit/usage/#restart) |Reset start position (rotate) for circular genomes |FASTA/Q |+ only | |
| |[mutate](https://bioinf.shenwei.me/seqkit/usage/#mutate) |Edit sequence (point mutation, insertion, deletion) |FASTA/Q |+ only | |
| |[sana](https://bioinf.shenwei.me/seqkit/usage/#sana) |Sanitize broken single line FASTQ files |FASTQ | | |
|Ordering |[sort](https://bioinf.shenwei.me/seqkit/usage/#sort) |Sort sequences by id/name/sequence/length |FASTA preferred| | |
| |[shuffle](https://bioinf.shenwei.me/seqkit/usage/#shuffle) |Shuffle sequences |FASTA preferred| | |
|BAM processing |[bam](https://bioinf.shenwei.me/seqkit/usage/#bam) |Monitoring and online histograms of BAM record features |BAM | | |
|Miscellaneous |[sum](https://bioinf.shenwei.me/seqkit/usage/#sum) |Compute message digest for all sequences in FASTA/Q files |FASTA/Q | |✓ |
| |[merge-slides](https://bioinf.shenwei.me/seqkit/usage/#merge-slides)|Merge sliding windows generated from seqkit sliding |TSV | |
Notes:
- Strand-sensitivity:
- `+ only`: only processing on the positive/forward strand.
- `+ and -`: searching on both strands.
- `+ or/and -`: depends on users' flags/options/arguments.
- Multiple-threads: Using the default 4 threads is fast enough for most commands, some commands can benefit from extra threads.
## Citation
Wei Shen\*, Botond Sipos, and Liuyang Zhao. 2024. SeqKit2: A Swiss Army Knife for Sequence and Alignment Processing. ***iMeta*** e191. [doi:10.1002/imt2.191](https://doi.org/10.1002/imt2.191).
## Contributors
- [Wei Shen](https://github.com/shenwei356)
- [Botond Sipos](https://github.com/botond-sipos): `bam`, `scat`, `fish`, `sana`, `watch`.
- [others](https://github.com/shenwei356/seqkit/graphs/contributors)
## Acknowledgements
We thank all users for their valuable feedback and suggestions. We thank all contributors for improving the code and documentation.
We appreciate [Klaus Post](https://github.com/klauspost) for his fantastic packages (
[compress](https://github.com/klauspost/compress) and [pgzip](https://github.com/klauspost/pgzip)
) which accelerate gzip file reading and writing.
## Contact
[Create an issue](https://github.com/shenwei356/seqkit/issues) to report bugs,
propose new functions or ask for help.
## License
[MIT License](https://github.com/shenwei356/seqkit/blob/master/LICENSE)