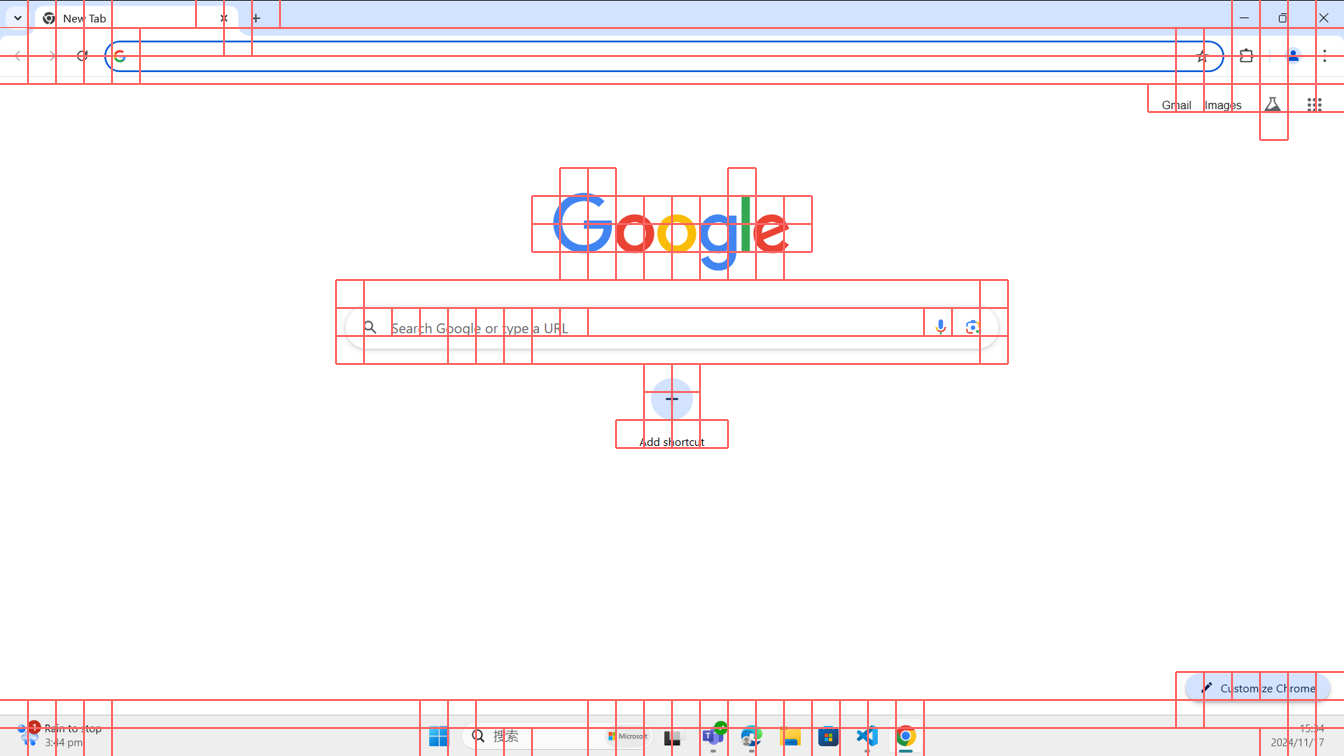
# ShowUI
Open-source, End-to-end, Lightweight, Vision-Language-Action model for GUI Agent & Computer Use.
ShowUI 是一款开源的、端到端、轻量级的视觉-语言-动作模型,专为 GUI 智能体设计。
📑 Paper
| 🤗 Hugging Models
| 🤗 Spaces Demo
| 📝 Slides
| 🕹️ OpenBayes贝式计算 Demo
🤗 Datasets | 💬 X (Twitter)
| 🖥️ Computer Use
| 📖 GUI Paper List
| 🤖 ModelScope
> [**ShowUI: One Vision-Language-Action Model for GUI Visual Agent**](https://arxiv.org/abs/2411.17465)
> [Kevin Qinghong Lin](https://qinghonglin.github.io/), [Linjie Li](https://scholar.google.com/citations?user=WR875gYAAAAJ&hl=en), [Difei Gao](https://scholar.google.com/citations?user=No9OsocAAAAJ&hl=en), [Zhengyuan Yang](https://zyang-ur.github.io/), [Shiwei Wu](https://scholar.google.com/citations?user=qWOFgUcAAAAJ), [Zechen Bai](https://www.baizechen.site/), [Weixian Lei](), [Lijuan Wang](https://scholar.google.com/citations?user=cDcWXuIAAAAJ&hl=en), [Mike Zheng Shou](https://scholar.google.com/citations?user=h1-3lSoAAAAJ&hl=en)
>
Show Lab @ National University of Singapore, Microsoft
## 🔥 Update
- [x] [2026.2.21] [ShowUI-pi](https://github.com/showlab/showui-pi) has been accepted to **CVPR 2026**.
- [x] [2025.12.31] We released [**ShowUI-Aloha**](https://github.com/showlab/ShowUI-Aloha) for human demonstration workflow.
- [x] [2025.12.31] We released [**ShowUI-π**](https://github.com/showlab/showui-pi) for GUI dragging.
- [x] [2025.3.2] Support fine-tuning and inference of the lastest base model **Qwen2.5-VL**.
- [x] [2025.2.27] ShowUI has been accepted to **CVPR 2025**.
- [x] [2025.2.13] Support **vllm** inference.
- [x] [2025.1.20] Support Navigation tasks: Mind2Web, AITW, Miniwob training and evaluator.
- [x] [2025.1.17] Support **API Calling** via Gradio Client, simply run `python3 api.py`.
- [x] [2025.1.5] Release the [`ShowUI-web`](https://huggingface.co/datasets/showlab/ShowUI-web) dataset.
- [x] [2024.12.28] Update GPT-4o annotation recaptioning scripts.
- [x] [2024.12.27] Update training codes and instructions.
- [x] [2024.12.23] Update `showui` for UI-guided token selection implementation.
- [x] [2024.12.15] ShowUI received **Outstanding Paper Award** at [NeurIPS2024 Open-World Agents workshop](https://sites.google.com/view/open-world-agents/schedule).
- [x] [2024.12.9] Support int8 Quantization.
- [x] [2024.12.5] **Major Update: ShowUI is integrated into [OOTB](https://github.com/showlab/computer_use_ootb?tab=readme-ov-file) for local run!**
- [x] [2024.12.1] We support iterative refinement to improve grounding accuracy. Try it at [HF Spaces demo](https://huggingface.co/spaces/showlab/ShowUI).
- [x] [2024.11.27] We release the [arXiv paper](https://arxiv.org/abs/2411.17465), [HF Spaces demo](https://huggingface.co/spaces/showlab/ShowUI) and [`ShowUI-desktop`](https://huggingface.co/datasets/showlab/ShowUI-desktop).
- [x] [2024.11.16] [`showlab/ShowUI-2B`](https://huggingface.co/showlab/ShowUI-2B) is available at huggingface.
## 🤖 vllm Inference
See [inference_vllm.ipynb](inference_vllm.ipynb) for vllm inference.
> To leverage multiple GPUs for faster inference, you can adjust the gpu_num parameter
## ⚡ API Calling
Run `python3 api.py` by providing a screenshot and a query.
> Since we are based on huggingface gradio client, you don't need a GPU to deploy the model locally 🤗
## 🖥️ Computer Use
See [Computer Use OOTB](https://github.com/showlab/computer_use_ootb?tab=readme-ov-file) for using ShowUI to control your PC.
https://github.com/user-attachments/assets/f50b7611-2350-4712-af9e-3d31e30020ee
## ⭐ Quick Start
See [Quick Start](QUICK_START.md) for local model usage.
## 🤗 Local Gradio
See [Gradio](GRADIO.md) for installation.
## 🚀 Training
Our Training codebases supports:
- [x] Grounding and Navigation training: Mind2Web, AITW, Miniwob
- [x] Self-customized model: ShowUI, Qwen2VL, Qwen2.5VL
- [x] Efficient Training: DeepSpeed, BF16, QLoRA, SDPA / FlashAttention2, Liger-Kernel
- [x] Multiple datasets mixed training
- [x] Interleaved data streaming
- [x] Image randomly resize (crop, pad)
- [x] Wandb training monitor
- [x] Multi-GPUs, Multi-nodes training
See [Train](TRAIN.md) for training set up.
## 🕹️ UI-Guided Token Selection
Try [`test.ipynb`](test.ipynb), which seamless support for Qwen2VL models.
## ✍️ Annotate your own data
Try [`recaption.ipynb`](recaption.ipynb), where we provide instructions on how to recaption the original annotations using GPT-4o.
## ❤ Acknowledgement
We extend our gratitude to [SeeClick](https://github.com/njucckevin/SeeClick) for providing their codes and datasets.
Special thanks to [Siyuan](https://x.com/who_s_yuan) for assistance with the Gradio demo and OOTB support.
## 🎓 BibTeX
If you find our work helpful, please kindly consider citing our paper.
```
@misc{lin2024showui,
title={ShowUI: One Vision-Language-Action Model for GUI Visual Agent},
author={Kevin Qinghong Lin and Linjie Li and Difei Gao and Zhengyuan Yang and Shiwei Wu and Zechen Bai and Weixian Lei and Lijuan Wang and Mike Zheng Shou},
year={2024},
eprint={2411.17465},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2411.17465},
}
```
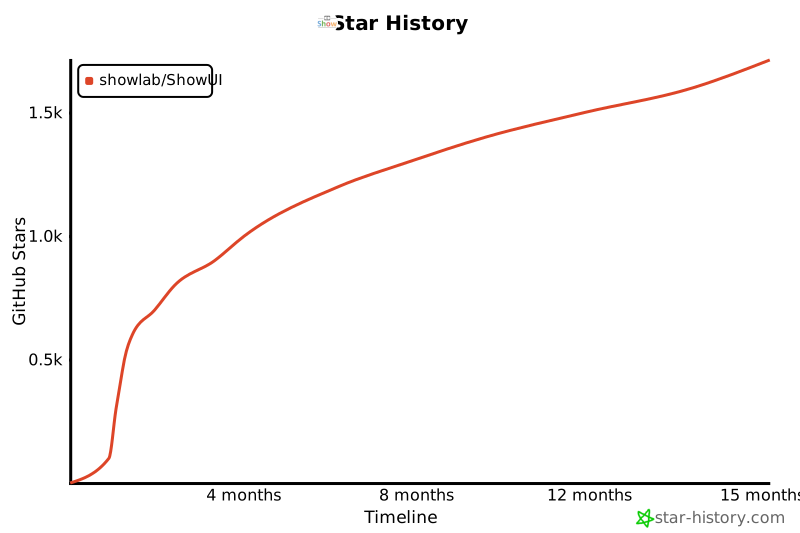
If you like our project, please give us a star ⭐ on GitHub for the latest update.
[](https://star-history.com/#showlab/ShowUI&Timeline)