# HKEx Filing Scraper
> **An open-source scraper for 25+ years of HKEx regulatory filings** — into any of nine databases, with full-text extraction, graph linking, and a read-only MCP server for AI agents.
[](https://github.com/simonmak-ascent/hkex-filing-scraper/actions/workflows/ci.yml)
[](https://registry.modelcontextprotocol.io/v0/servers?search=com.ascent-partners/hkex-filings)
[](https://glama.ai/mcp/connectors/com.ascent-partners/hkex-filings)
[](https://github.com/simonmak-ascent/hkex-filing-scraper/releases)
[](https://pypi.org/project/hkex-filing-scraper/)
[](https://www.python.org/downloads/)
[](https://hkex-listco-updates.ascent-partners.com/)
[](https://hkex-listco-updates.ascent-partners.com/ai-agents/)
[](https://github.com/astral-sh/ruff)
[](https://opensource.org/licenses/MIT)
## Overview
**The US has EDGAR full-text search. Japan has EDINET. Hong Kong has a search form that returns
one page at a time.** There is no bulk, machine-readable, full-text corpus of HKEx filings. This
builds one.
An open-source Python tool that scrapes 25+ years of Hong Kong Stock Exchange (HKEx)
regulatory filings and ingests them into **any combination of nine databases** — with
full-text and table extraction, chunk-level coverage, optional graph linking, and a
**read-only MCP server** so AI agents can query the corpus or the live site.
It speaks the undocumented HKEx JSON API directly, which is faster and more resilient than
driving a browser.
## Vendors & Integrations
**Databases** — nine first-class destinations, in documented popularity order (see the
[support matrix](docs/sinks/README.md)):
- [PostgreSQL](docs/sinks/postgresql.md) — production-grade open-source relational
- [MySQL](docs/sinks/mysql.md) / [MariaDB](docs/sinks/mysql.md) — GPL relational servers, one driver
- [SQLite](docs/sinks/sqlite.md) — zero-server file database, no install needed
- [MongoDB](docs/sinks/mongodb.md) — document database
- [Neo4j](docs/sinks/neo4j.md) — property-graph database
- [ClickHouse](docs/sinks/clickhouse.md) — columnar analytics engine
- [DuckDB](docs/sinks/duckdb.md) — in-process analytical engine
- [SurrealDB](docs/sinks/surrealdb.md) — multi-model graph + document database
**AI clients** — any MCP-capable agent; ready-made configuration for
[Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode, Manus, and Perplexity](docs/ai-agents.md).
**Available on** — [PyPI](https://pypi.org/project/hkex-filing-scraper/) ·
[Glama](https://glama.ai/mcp/connectors/com.ascent-partners/hkex-filings) ·
[MCP Registry](https://registry.modelcontextprotocol.io/) ·
[hosted gateway](https://hkex-listco-updates.ascent-partners.com/api/mcp).
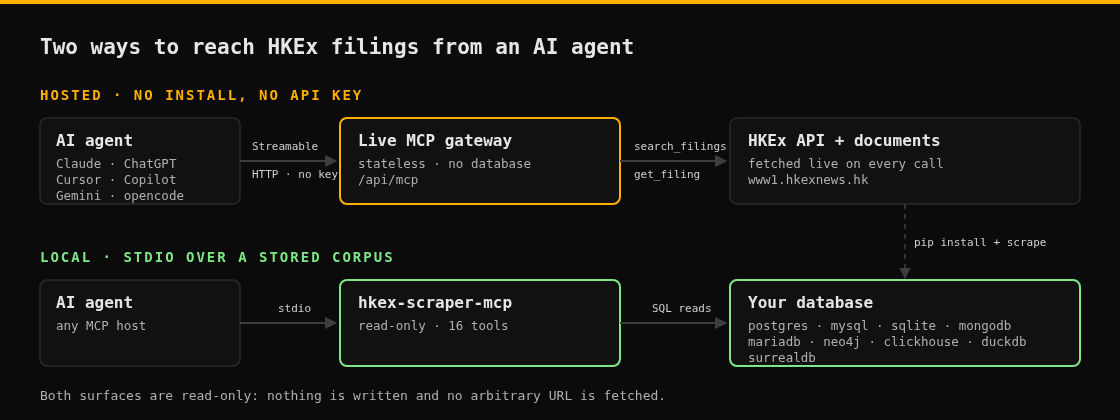
## Two Ways to Use It
| | **Hosted MCP gateway** | **Local pipeline** |
| --- | --- | --- |
| What | A public endpoint you point an AI agent at | The `hkex-scraper` CLI |
| Setup | None — paste a URL | `pip install` + one environment variable |
| Data | Live from HKEx, nothing stored | Stored in your database(s) |
| Docs | [Live MCP gateway](docs/live-mcp.md) · [AI agent support](docs/ai-agents.md) | [Getting started](docs/getting-started.md) |
## Use the Hosted MCP Gateway
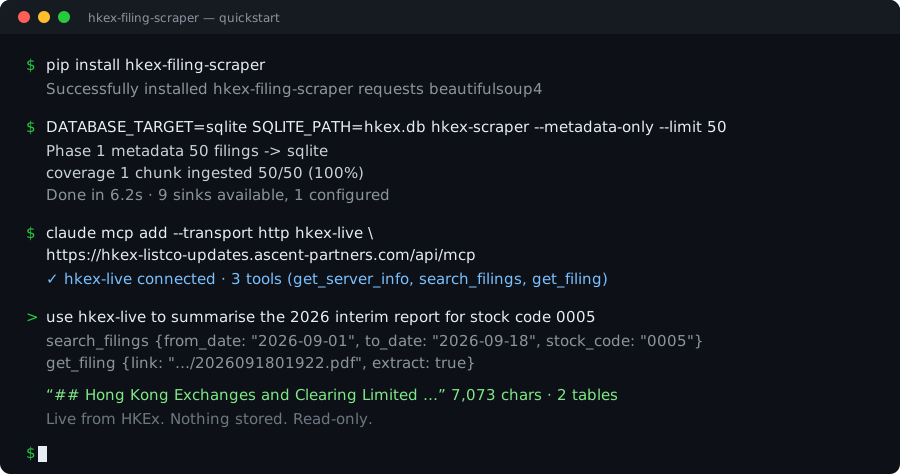
POST, Streamable HTTP, **no API key**:
```text
https://hkex-listco-updates.ascent-partners.com/api/mcp
```
Four read-only tools: `get_server_info`, `search_filings` (a window of at most 31 days, with
optional stock-code, title, document-type, category, and stock-name filters),
`list_filing_facets` (browse what a window contains), and `get_filing` (downloads one
document and extracts its text and tables).
Point a client at it — for example opencode:
```json
{
"$schema": "https://opencode.ai/config.json",
"mcp": {
"hkex-live": {
"type": "remote",
"url": "https://hkex-listco-updates.ascent-partners.com/api/mcp"
}
}
}
```
Then ask:
```text
Use hkex-live to list the filings published between 2026-09-01 and 2026-09-18,
then summarise the interim report.
```
Ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode,
Manus, and Perplexity is in [AI agent support](docs/ai-agents.md) — and for a stored corpus,
the [stdio MCP server](docs/mcp.md) exposes a wider tool catalog and is published on
[Glama](https://glama.ai/mcp/connectors/com.ascent-partners/hkex-filings). The gateway is listed
in the [official MCP Registry](https://registry.modelcontextprotocol.io/) as
`com.ascent-partners/hkex-filings`.
> **Featured on Glama** — the read-only [stdio MCP server](docs/mcp.md) is also published on
> [Glama](https://glama.ai/mcp/connectors/com.ascent-partners/hkex-filings), where Glama scans the
> built server and scores tool-definition quality (currently 4.7/5).
## Quick Start (≤ 5 minutes)
**Fastest path:** no install — use the hosted gateway at
`https://hkex-listco-updates.ascent-partners.com/api/mcp` (Streamable HTTP), or install and run
locally:
```bash
pip install hkex-filing-scraper # core; SQLite needs no server
pip install "hkex-filing-scraper[all]" # Excel + dotenv + every driver + the MCP server
cp .env.example .env # then set DATABASE_TARGET (below)
hkex-scraper --metadata-only --limit 100
```
Optional extras: `excel`, `postgres`, `mysql`, `duckdb`, `mongodb`, `clickhouse`, `neo4j`,
`mcp`, `pdf`, `all`, `dev`.
`DATABASE_TARGET` is an ordered, comma-separated list of sink ids; the order decides which
sink serves reads. To start with no server:
```ini
DATABASE_TARGET=sqlite
SQLITE_PATH=hkex.db
```
`hkex-scraper` runs the full pipeline (metadata + documents + graph); `hkex-scraper
--full-history` covers everything since April 1999. The schema is created automatically.
Full install options and per-sink settings are in [Getting started](docs/getting-started.md).
## Database Support
Every sink is a first-class destination; rows are in documented popularity order. The full
matrix — licenses, capability differences, per-engine notes — is in
[Database sinks](docs/sinks/README.md).
| Sink | Model | License | Extra | Idempotent upsert |
| ---- | ----- | ------- | ----- | ----------------- |
| `postgres` | relational | PostgreSQL License | `postgres` | `ON CONFLICT DO UPDATE` |
| `mysql` / `mariadb` | relational | GPLv2 | `mysql` | `ON DUPLICATE KEY UPDATE` |
| `sqlite` | relational | Public domain | — | `ON CONFLICT DO UPDATE` |
| `mongodb` | document | SSPL¹ | `mongodb` | `update_one(upsert=True)` |
| `neo4j` | graph | GPLv3 (Community) | `neo4j` | `MERGE` |
| `clickhouse` | columnar | Apache-2.0 | `clickhouse` | `ReplacingMergeTree` + read-merge |
| `duckdb` | relational | MIT | `duckdb` | `ON CONFLICT DO UPDATE` |
| `surrealdb` | graph + document | BSL 1.1¹ | — | `UPSERT` / `RELATE` |
¹ Source-available, not OSI-approved — labeled exceptions per
[ADR 0003](docs/adr/0003-sink-support-policy.md).
Valid sink ids, in documented order: `postgres`, `mysql`, `sqlite`, `mongodb`, `mariadb`, `neo4j`, `clickhouse`, `duckdb`, `surrealdb`. Set one variable and the same run feeds every sink:
```ini
# Order sets read precedence.
DATABASE_TARGET=postgres,sqlite
POSTGRES_DSN=postgresql://user:password@localhost:5432/hkex
SQLITE_PATH=hkex.db
```
## How This Compares
Four ways to get HKEx filings, and what each one costs you.
| | This project | HKEXnews web search | Browser automation you write | Licensed HKEx feed |
| --- | --- | --- | --- | --- |
| Bulk export | Yes | No — page-at-a-time | Yes | Yes |
| History to April 1999 | Yes | Yes, manually | Depends on your code | Yes |
| Full text of documents | Extracted from PDF/HTML/Excel | No — you open each file | You build the extractor | Varies by contract |
| Structured tables | Extracted to Markdown | No | You build it | Varies |
| Coverage verification | Per-chunk, auditable | Not applicable | You build it | Vendor SLA |
| Lands in your engine | 9 engines, any combination | No | Whatever you wire up | Usually one format |
| Speed | JSON API, no browser | Manual | Slower — renders pages | Fast |
| Cost | Free, MIT | Free | Your time | Subscription |
| Commercial redistribution | See [docs/legal.md](docs/legal.md) | Restricted | Restricted | Licensed |
If you need licensed, redistributable, SLA-backed data, buy the feed. If you need a complete
local corpus for research, compliance, or RAG, this replaces the pipeline you would otherwise
write yourself.
## How It Works
```mermaid
flowchart LR
A[HKEx JSON API] --> B[Phase 1: metadata]
B --> C[Canonical record]
C --> D{DATABASE_TARGET}
D --> E[(PostgreSQL)]
D --> F[(MySQL / MariaDB)]
D --> G[(SQLite)]
D --> H[(MongoDB)]
D --> I[(Neo4j)]
D --> J[(ClickHouse)]
D --> K[(DuckDB)]
D --> L[(SurrealDB)]
B --> M[Graph linking]
M --> D
B --> N[Phase 2: download and extract]
N --> C
```
- **Phase 1** scrapes filing metadata through a JSF session, splitting the range into monthly
chunks and deduplicating on a 16-character MD5 `filingId`.
- **Phase 2** downloads each filing's PDF/HTML/Excel document, extracts text and tables to
Markdown, and writes the payload.
- **Graph linking** (optional) writes `has_filing` and `references_filing` edges when
`COMPANY_TABLE` is set.
- **Failure isolation** — a failure on one sink is logged and counted but never blocks
another; the run exits non-zero if any configured sink failed.
Deeper detail: [Architecture](docs/architecture.md) · [ADR 0002](docs/adr/0002-multi-sink-architecture.md).
## HKEx API session
```mermaid
sequenceDiagram
autonumber
participant C as hkex-scraper
participant J as HKEx site (JSF)
participant A as HKEx JSON servlet
C->>J: GET /search/titlesearch.xhtml
J-->>C: HTML + javax.faces.ViewState
C->>J: POST form (from/to dates + ViewState)
C->>A: GET /search/titleSearchServlet.do (rowRange paging)
A-->>C: JSON page of filings
Note over C: generate_monthly_chunks() splits ranges > 1 month
C->>C: dedupe on 16-char MD5 filingId
```
## Data model
```mermaid
erDiagram
COMPANY ||--o{ EXCHANGE_FILING : has_filing
EXCHANGE_FILING ||--o{ DOCUMENT : has_document
EXCHANGE_FILING ||--o{ EXCHANGE_FILING : references_filing
EXCHANGE_FILING ||--o{ SCRAPE_COVERAGE : chunk_of
EXCHANGE_FILING {
string filingId "16-char MD5"
string stockCode
string title
datetime dateTime
}
DOCUMENT {
text documentText
array documentTables
}
SCRAPE_COVERAGE {
int apiCount
int ingestedCount
int uniqueCount
string runId
}
```
`exchange_filing` and `scrape_coverage` are SCHEMAFULL; `has_filing` /
`references_filing` are the graph edges written by `graph.py`.
## Sink contract and read routing
```mermaid
flowchart LR
CANON["canonical record
per filing / document / coverage / edge"] --> DISPATCH["dispatch to every configured sink"]
DISPATCH --> S1["sink A"]
DISPATCH --> S2["sink B"]
DISPATCH --> SN["sink N"]
S1 -.->|error| LOG["logged + counted
never blocks the others"]
READ["reads: pending filings · tickers · titles · coverage"] --> FIRST["first configured sink
whose capabilities include reads"]
DISPATCH --> EXIT["sink_exit_code()
non-zero if any sink failed"]
```
## Features
- **Fast API scraping** — direct HKEx JSON API; no browser or Selenium.
- **Full history** — every filing from April 1999 to today, with chunk-level coverage checks.
- **Document processing** — PDF/HTML/Excel text and structured tables, extracted to Markdown.
- **Multi-sink** — any ordered combination of nine databases, each with native idempotent upserts.
- **AI-ready** — a hosted live MCP gateway plus a local stdio MCP server.
- **Resumable and observable** — batching, parallel downloads, stalled-job detection, per-sink
counters, and `--coverage-report` / `--parity-report` / `--verify`.
- **Optional dependencies** — the core is `requests` + `beautifulsoup4`; drivers and document
extraction are extras with graceful fallbacks.
## Documentation
- [Getting started](docs/getting-started.md) · [Configuration](docs/configuration.md) · [CLI](docs/cli.md)
- [Database sinks (matrix)](docs/sinks/README.md) — [PostgreSQL](docs/sinks/postgresql.md), [MySQL/MariaDB](docs/sinks/mysql.md), [SQLite](docs/sinks/sqlite.md), [MongoDB](docs/sinks/mongodb.md), [Neo4j](docs/sinks/neo4j.md), [ClickHouse](docs/sinks/clickhouse.md), [DuckDB](docs/sinks/duckdb.md), [SurrealDB](docs/sinks/surrealdb.md)
- [Live MCP gateway](docs/live-mcp.md) · [AI agent support](docs/ai-agents.md) · [MCP server](docs/mcp.md)
- [Architecture](docs/architecture.md) · [Troubleshooting](docs/troubleshooting.md) · [Testing](docs/testing.md)
- [Roadmap](docs/roadmap.md) · [De-risking register](docs/de-risking.md) · [Upgrading](docs/upgrading.md)
- [What's new](docs/news.md) · [Releasing](docs/releasing.md) · [Legal & Terms of Use](docs/legal.md) · [Changelog](CHANGELOG.md)
- **Docs site:** · [Try it locally (`examples/`)](examples/README.md)
## Development
```bash
pip install -e ".[dev,all]"
ruff check # lint (py310, line-length 100)
ruff format --check # formatting
pytest # unit tests (no DB or network required)
```
Tests are pure unit tests; SQLite and DuckDB contract tests run in-process, and integration
tests that need a server are skipped unless that sink is configured. See
[Testing](docs/testing.md).
CI and deployment run through the APG workbench pipeline.
The deploy smoke check probes the public vhost, not a local port.
## Contributing
See [CONTRIBUTING.md](CONTRIBUTING.md); report security issues per [SECURITY.md](SECURITY.md).
Ideas and questions are welcome in
[Discussions](https://github.com/simonmak-ascent/hkex-filing-scraper/discussions).
Built by [Ascent Partners](https://www.ascent.partners).
If this saves you time, a ⭐ on GitHub helps others find it.
## Use with Context7
Up-to-date HKEx Filing Scraper documentation is indexed on [Context7](https://context7.com/simonmak-ascent/hkex-filing-scraper), so coding agents can pull it into context on demand. With the Context7 MCP server or `ctx7` CLI installed, name the library in your prompt:
```text
use library /simonmak-ascent/hkex-filing-scraper for API and docs
```
## License
MIT — see [LICENSE](LICENSE). That covers **this project's code only**; optional dependencies
carry their own licenses, notably the `pdf` extra (PyMuPDF / pymupdf4llm), which is
**AGPL-3.0** and deliberately excluded from `.[all]`. See
[docs/legal.md](docs/legal.md#third-party-licenses).
**Data & Terms of Use:** this is a research tool for the undocumented HKEx JSON API, and it is
not affiliated with or endorsed by HKEx. Commercial redistribution of HKEx data may require a
licensed HKEx feed; see [docs/legal.md](docs/legal.md).