# Iris-3B
**Pixel-space generation & general vision learner**
Generative priors are a promising foundation for downstream vision tasks. In
this project we explore pixel-space generative models as an alternative to
vision foundation models such as DINOv2.
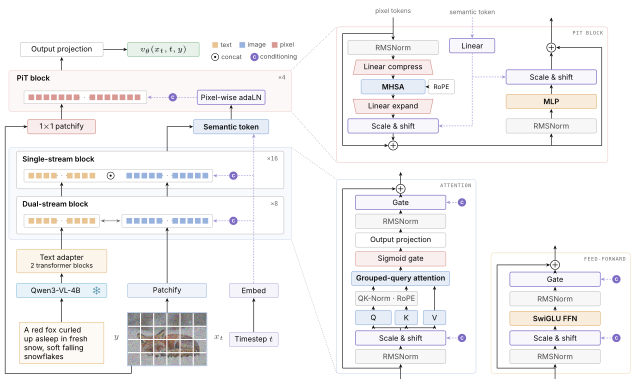
Iris-3B is a 3B-parameter diffusion transformer that generates directly in
pixel space: no VAE, no latent space, every pixel is produced by the model, so
nothing is lost to a lossy, texture-biased latent. It is not only an image
generator: the same pixel-space prior, fine-tuned, estimates monocular depth and
restores and upscales images — one backbone, three tasks. This repository contains the
model, the training and fine-tuning code, and inference.
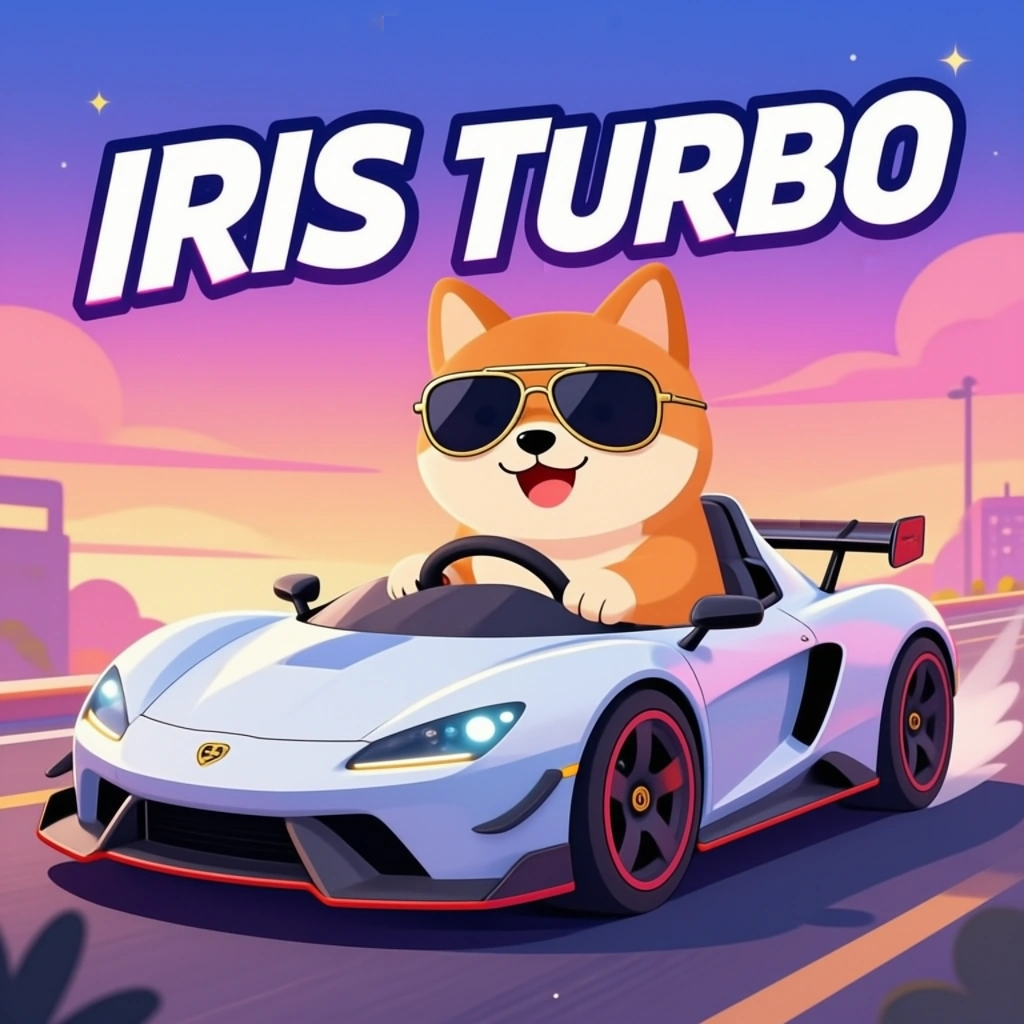
[Iris-3B Turbo](#iris-3b-turbo) is a 4-step distilled version of Iris-3B: a
1024×1024 image in about 0.7 s on one H100.
[](https://arxiv.org/abs/2610.09450)
[](https://speridlabs.com/research/iris)
[](https://huggingface.co/speridlabs/iris-3b)
[](https://huggingface.co/spaces/speridlabs/iris-3b)
[](https://huggingface.co/spaces/speridlabs/iris-3b-turbo)
[](LICENSE)
[](https://www.python.org/downloads/)
https://github.com/user-attachments/assets/2345a853-c673-4ddb-83b9-7e05c83198ed
## Generations
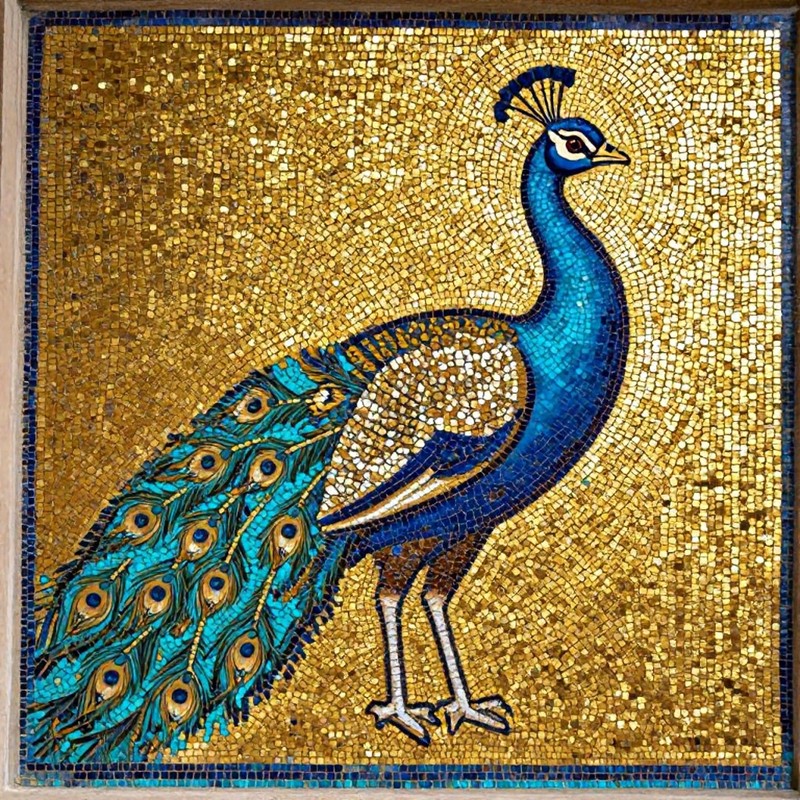
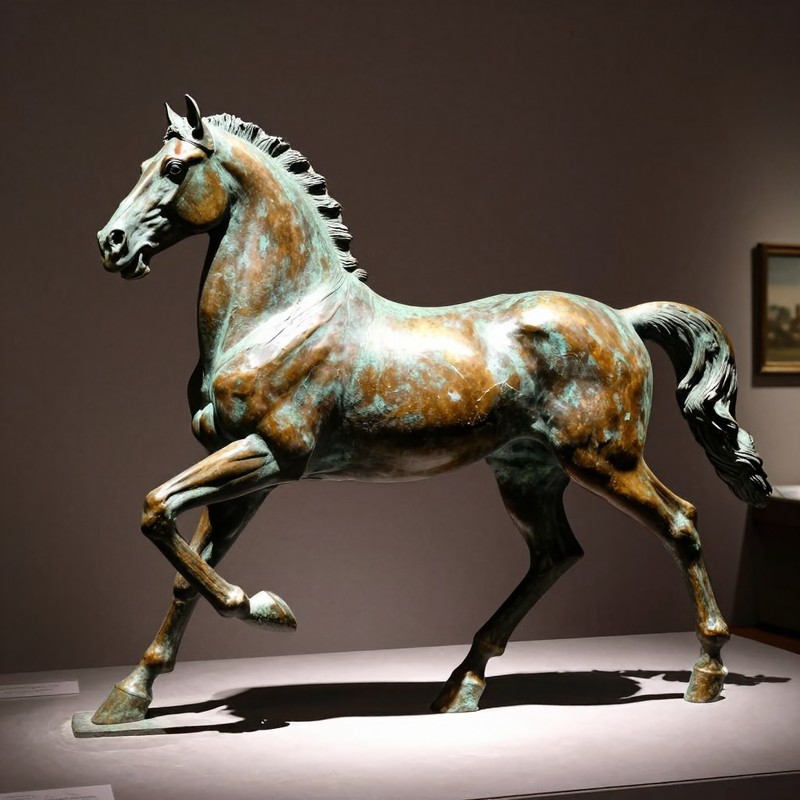
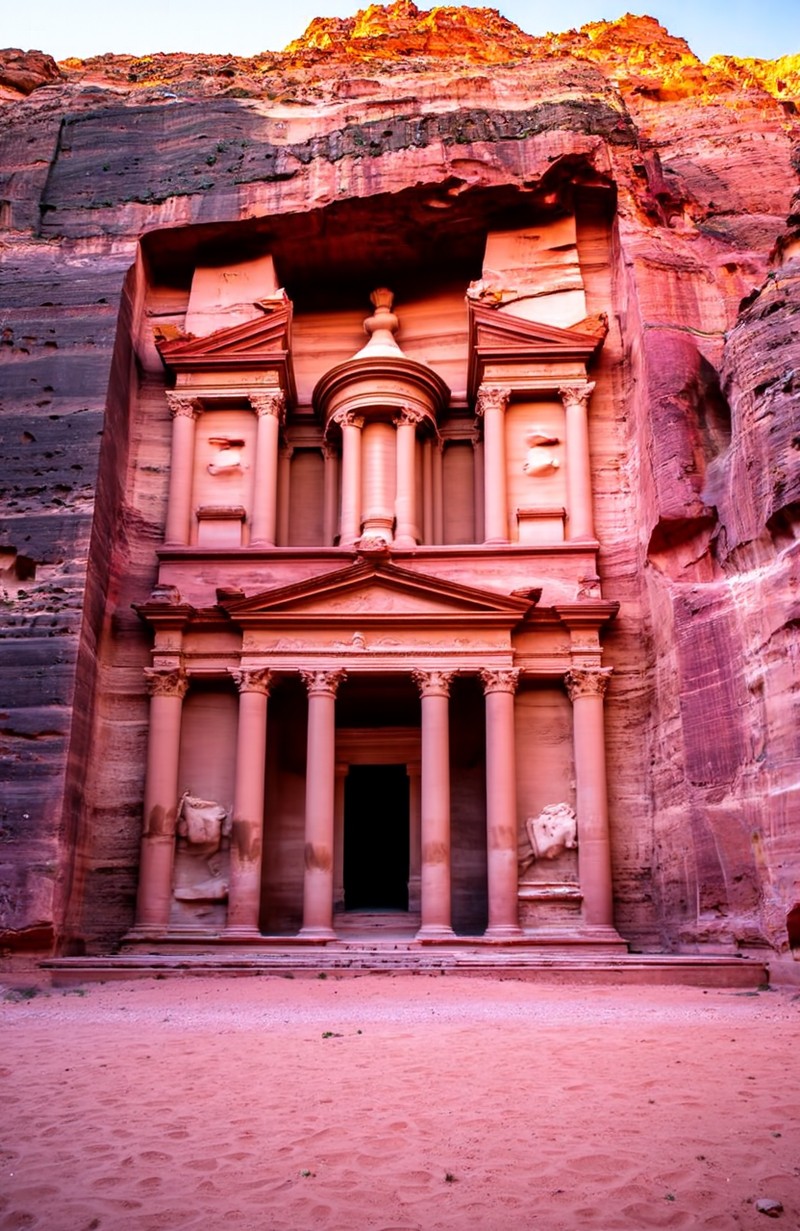
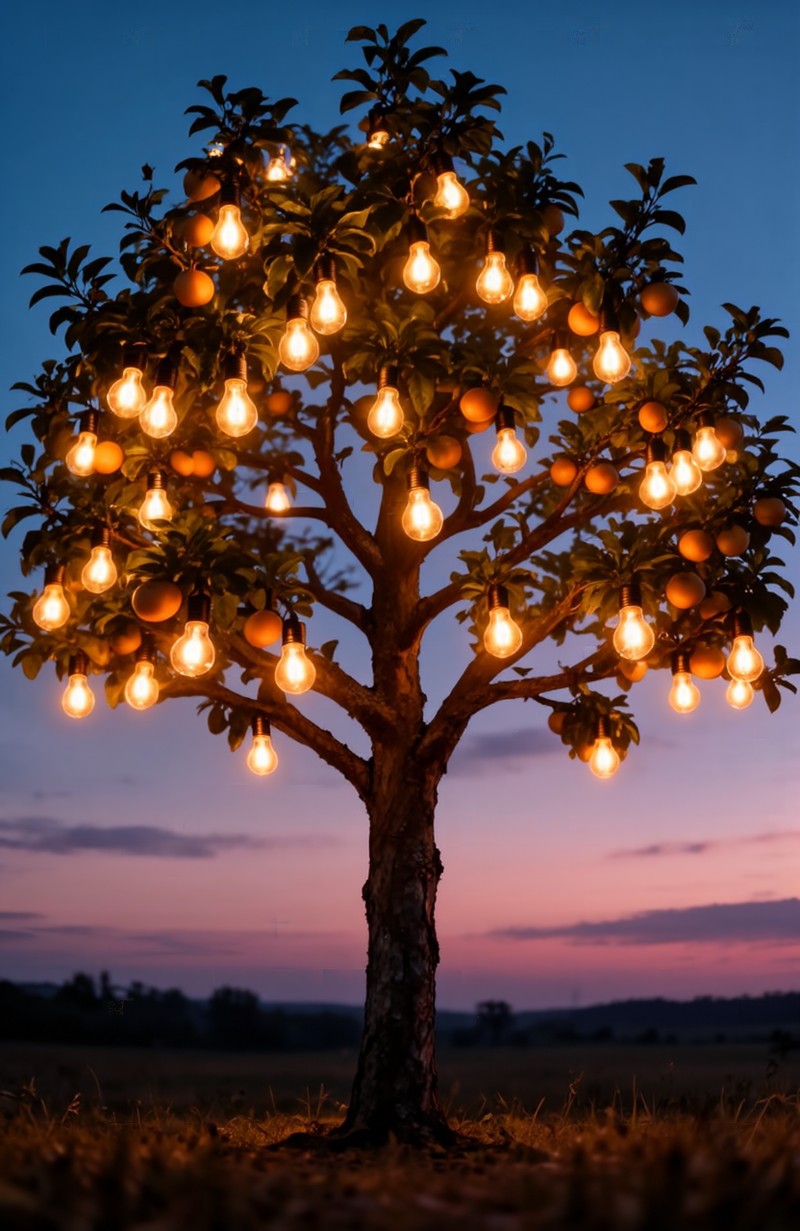
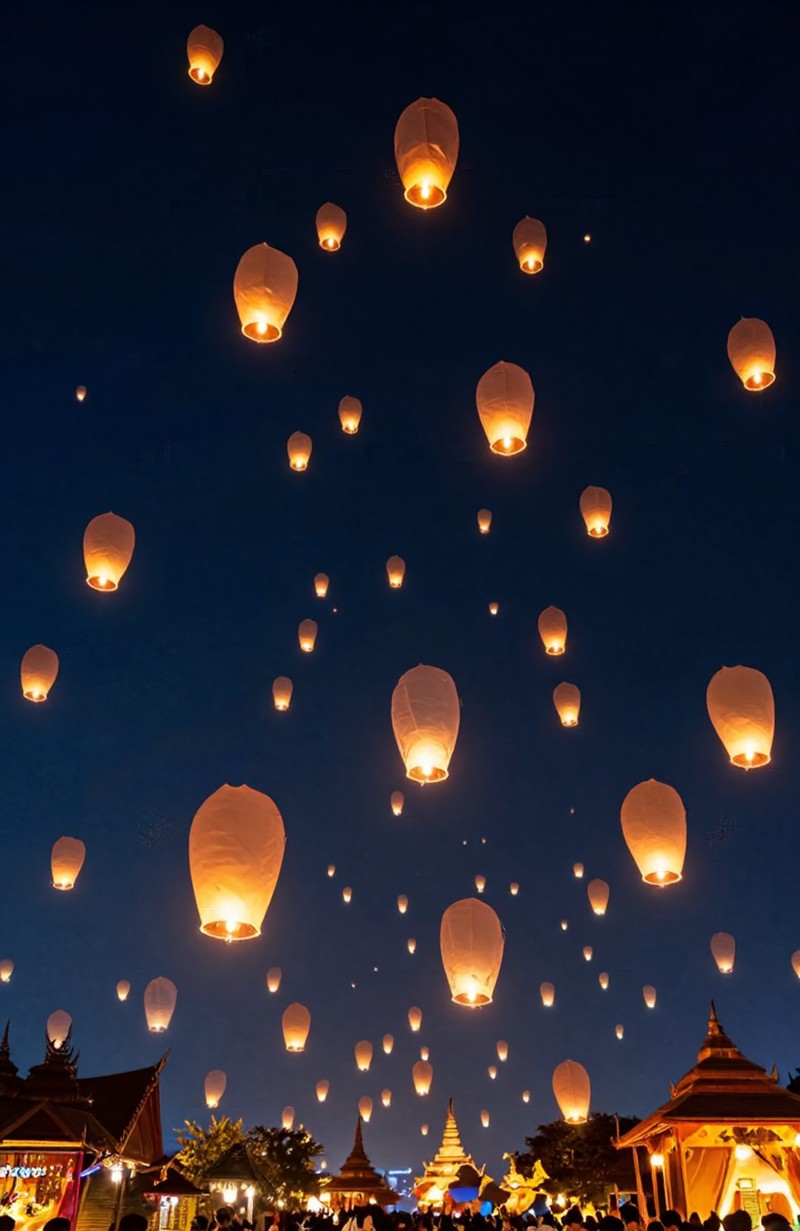
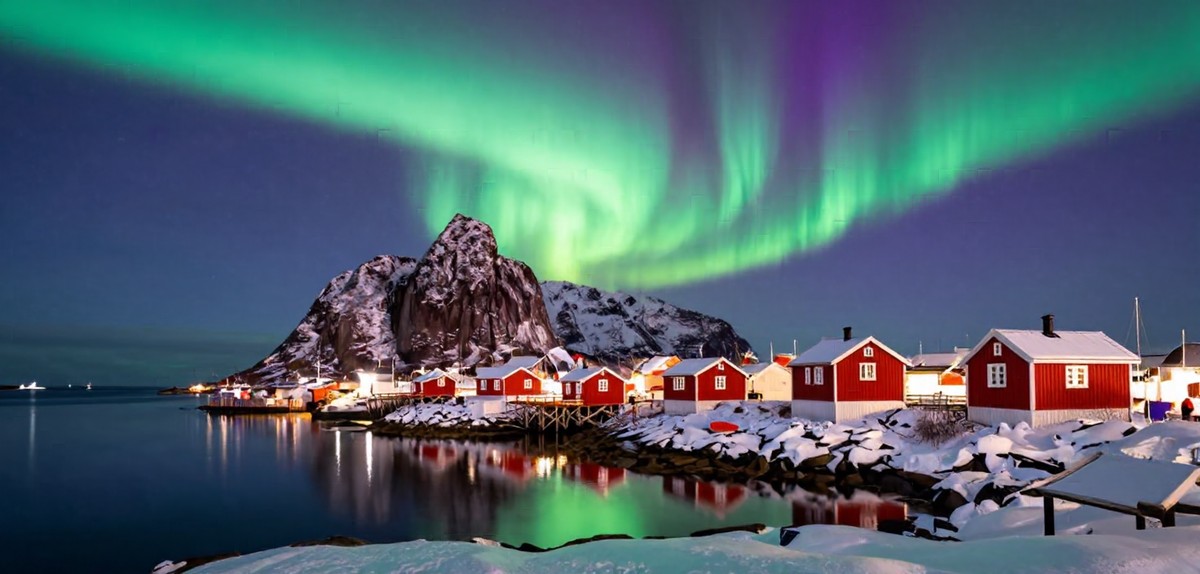
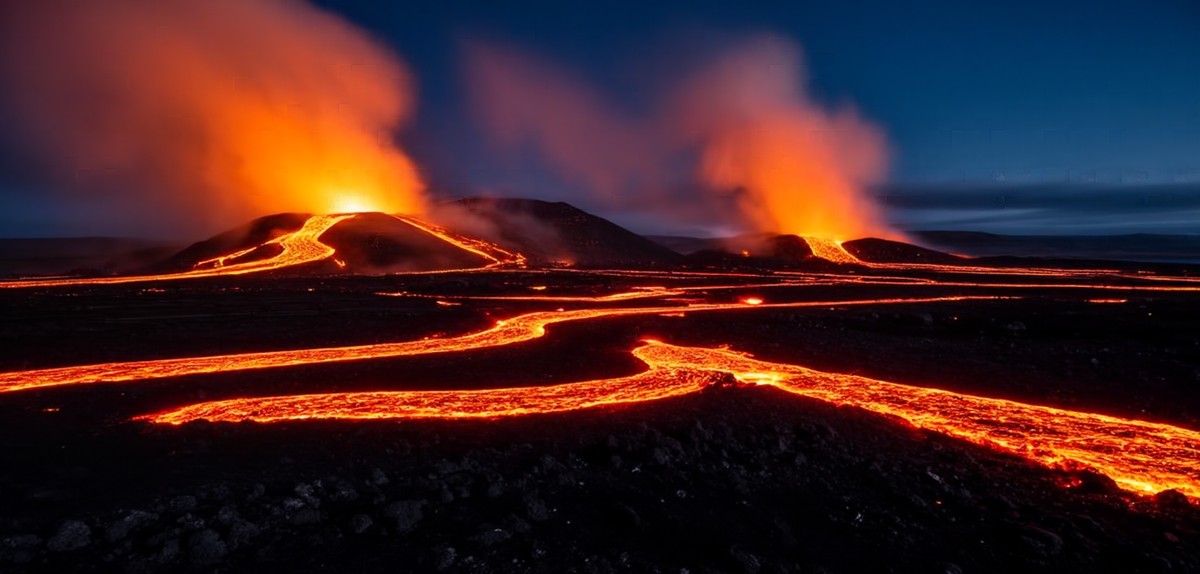
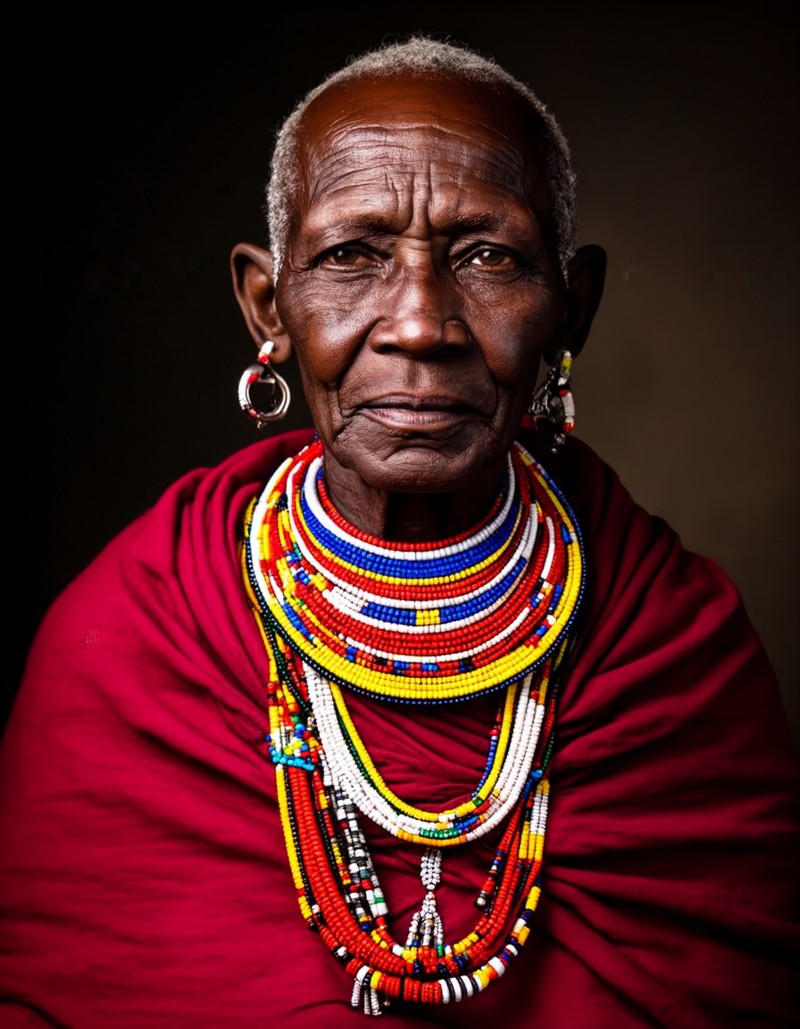
Samples from the final checkpoint at native aspect ratios of about one megapixel
(CFG 3, 100 steps, one fixed seed, no prompt rewriting).
 Studio portrait of a Maasai elder wearing vibrant beaded jewelry, deep red cloth, dark backdrop, Rembrandt lighting, ultra detailed skin texture |
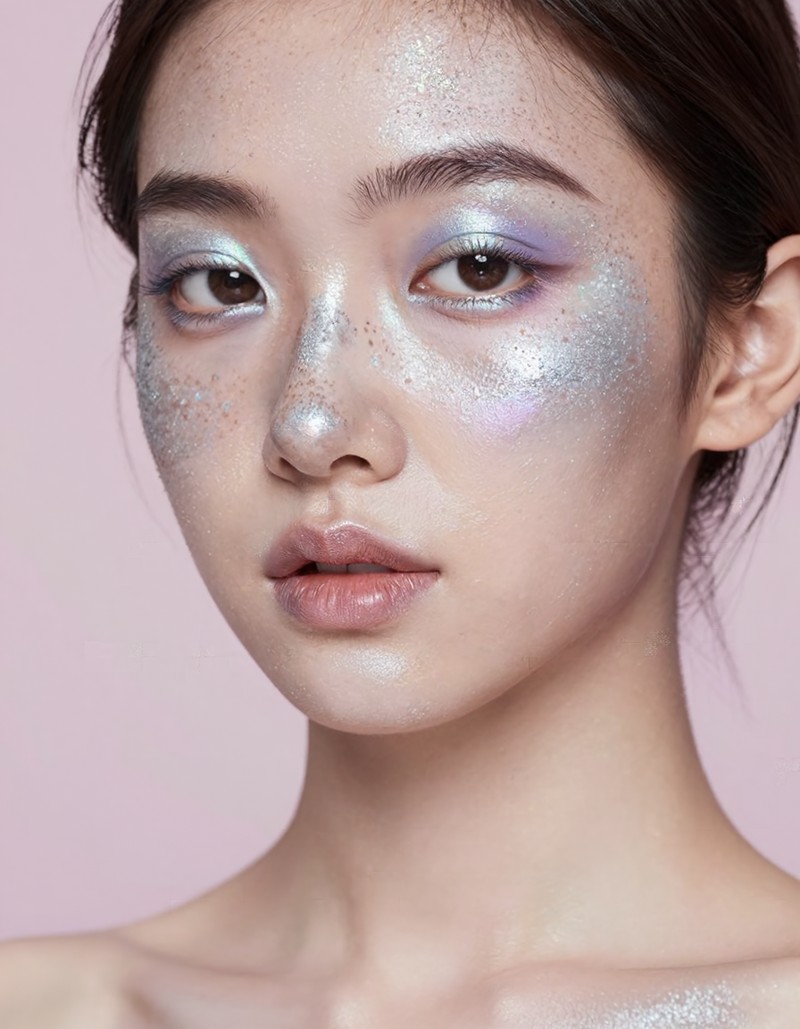
 Close-up portrait of a young woman with silver glitter freckles and iridescent makeup, soft pastel background, high fashion beauty photography |
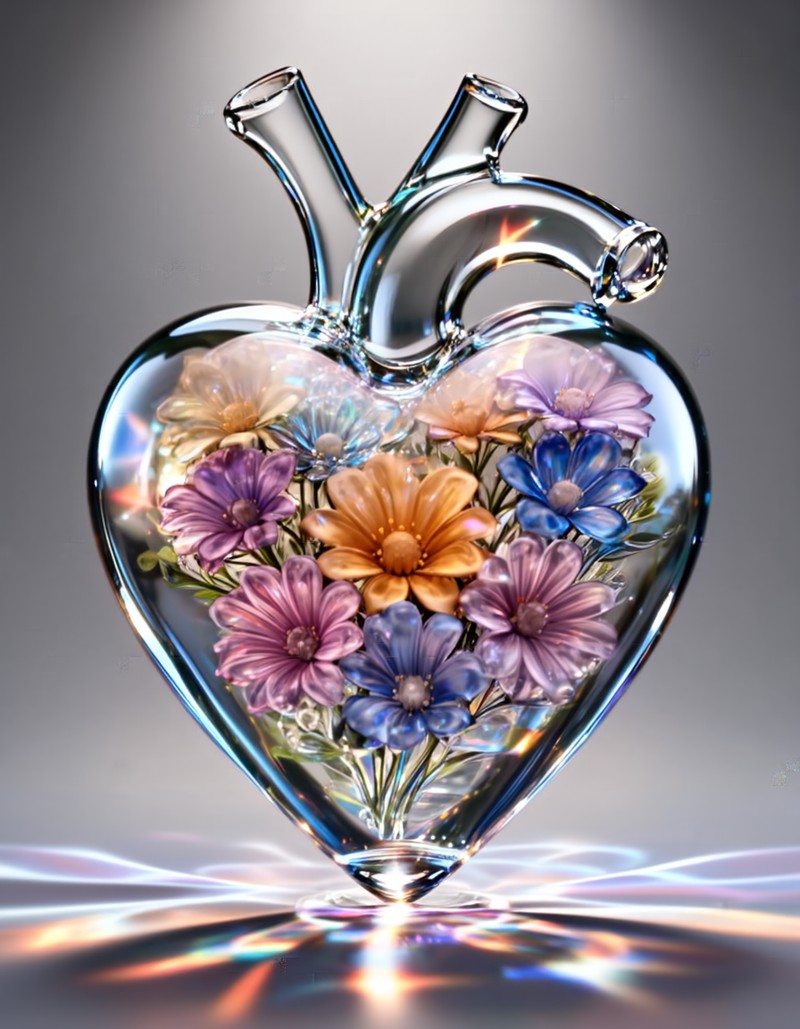
 A glass sculpture of a heart filled with flowers, caustics and reflections, 3D render |
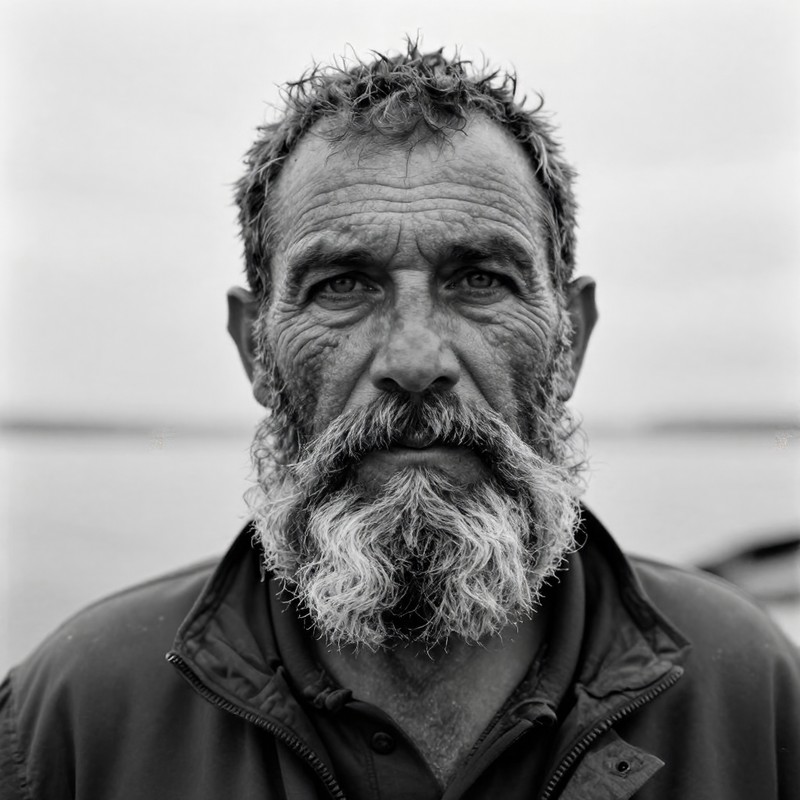
 Black and white portrait of a fisherman with a thick grey beard and deep wrinkles, piercing eyes, overcast light, fine grain film photograph |
 A Byzantine-style mosaic of a peacock made of tiny gold and turquoise tiles, shimmering texture |
 A bronze sculpture of a horse in motion, patina, dramatic museum spotlight |
 The ancient city of Petra with the Treasury carved into pink sandstone, morning light |
 A tree with lightbulbs instead of fruits glowing at dusk, surreal concept art |
 Thousands of sky lanterns rising into the night sky at Yi Peng festival in Chiang Mai |
 The aurora borealis swirling green and violet over a snowy Lofoten fishing village with red wooden cabins, reflections in a calm fjord, night photograph |
 Volcanic eruption at night in Iceland, rivers of glowing lava flowing across black fields, plumes of steam lit orange, long exposure |
More samples: [project page](https://speridlabs.com/research/iris#gallery).
## One prior, many tasks
Iris-3B is a general vision learner, not only a text-to-image model: the same
pixel-space backbone, fine-tuned with no architectural change, does dense
vision tasks where detail matters. Both fine-tunes ship with the release (see
[Depth, image restoration and upscaling](#depth-image-restoration-and-upscaling) for usage).
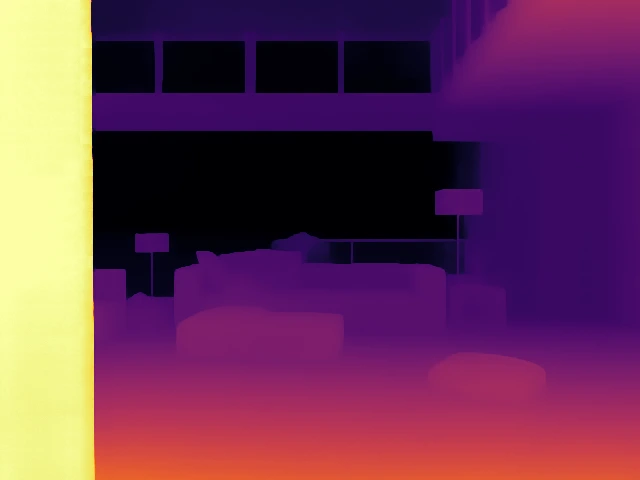
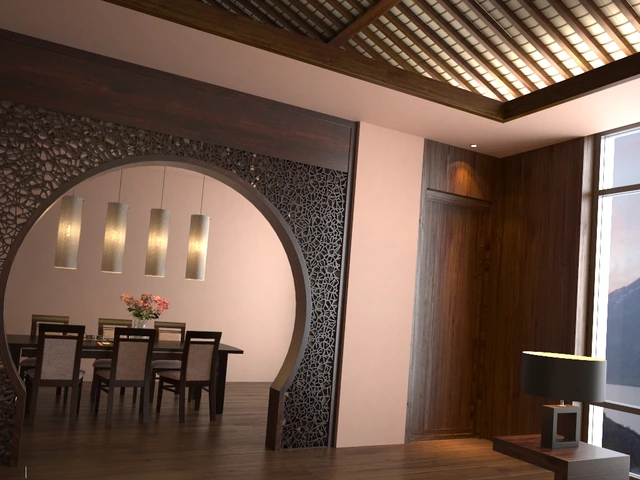
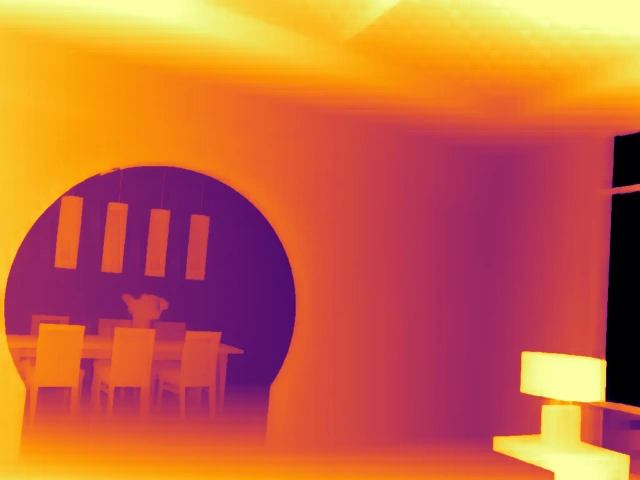
**Monocular depth** — photo → relative depth, one forward pass:
 Photo |
 Iris-3B depth |
 Photo |
 Iris-3B depth |
**Image restoration and upscaling** — degraded input → restored image:
 Input |
 Iris-3B |
 Input |
 Iris-3B |
Interactive depth point clouds and before/after sliders: [project page](https://speridlabs.com/research/iris#downstream)
· [demo](https://huggingface.co/spaces/speridlabs/iris-3b).
## Model

| | |
|---|---|
| Parameters | 3B (excluding the frozen text encoder) |
| Trunk | 24 blocks at width 2560: 8 dual-stream (separate image/text weights, joint attention) + 16 single-stream; GQA 20 query / 5 key-value heads, gated attention, sandwich RMSNorm, shared-bias adaLN |
| Patch size | 16 |
| Pixel head | 4 pixel-transformer (PiT) blocks: each patch is decoded back to pixels with per-pixel modulation, attending across patches |
| Text encoder | Qwen3-VL-4B-Instruct (frozen), 12 hidden layers aggregated by a learned layer-attention adapter |
| Objective | rectified flow, v-prediction, logit-normal timesteps |
## Install
```bash
pip install -e . # Python >= 3.11, PyTorch >= 2.7.1
pip install -e ".[dev]" # + pytest, ruff
```
## Inference
```bash
hf download speridlabs/iris-3b --local-dir iris-3b --exclude "depth/*" "upscaler/*" "turbo/*" # ~12 GB
python scripts/sample.py --checkpoint iris-3b \
--prompt "a red fox sleeping in fresh snow, golden hour"
```
`--checkpoint` is a directory holding `model.safetensors` + `config.yaml`, or a
training `.pth` (its EMA weights and embedded config are used). Defaults:
1024×1024, 100 DPM-Solver++ (order 2) steps, CFG 3. Use `--txt-file` for a
prompt list, `--steps`, `--seed`, `--negative-prompt` to adjust.
Turn a training checkpoint into a release directory (EMA weights only, FP32 by
default, config reduced to model/text-encoder/flow settings):
```bash
python scripts/export_checkpoint.py output/run/checkpoints/latest.pth exported/iris-3b
```
### Depth, image restoration and upscaling
The release also ships Iris-3B fine-tuned for monocular depth estimation and
for image restoration and upscaling — the general-vision-learner side of
the model — in the `depth/` and `upscaler/` folders of the same Hugging Face
repo (~12 GB each). Both run the full model in
a single forward pass with the empty prompt, so no text encoder is loaded.
```bash
python scripts/depth.py photo.jpg --out depth_out # .npy + colorized .png
python scripts/upscale.py photo.jpg --out upscaled # _x4.png
```
- **Depth** returns relative log depth at the input resolution (−1 near, +1
far). It is affine-invariant, not metric: fit a scale and shift in log space
to compare with ground truth. Inputs above 1024 px on the long side are
downscaled for the model (`--max-side 0` keeps native resolution).
- **Restoration** is a one-step restorer trained on 1024×1024 crops (4× of
256×256 inputs). The input is upsampled bicubically to 4×; outputs smaller
than 1024 on the short side are run as one tile, larger ones as overlapping
1024×1024 tiles (stride 512) blended with a Gaussian window, followed by a
wavelet colour fix against the bicubic upsample. By default inputs are first
downscaled to at most 512 px short side / 1024 px long side, which caps the
output at 2048×4096 (21 tiles); `--no-budget` keeps the input size.
Python API: `iris3b.downstream.depth.DepthPredictor` and
`iris3b.downstream.restoration.Restorer`. Fine-tuning checkpoints are converted
with `scripts/export_downstream.py`.
### Demo
The Gradio app behind the [Hugging Face Space](https://huggingface.co/spaces/speridlabs/iris-3b)
(text-to-image, depth and upscaling tabs) is in `demo/`; it runs on ZeroGPU
there and on any local GPU. All three models together take ~45 GB of GPU memory;
with `IRIS_OFFLOAD=1` they stay on the CPU and each request moves only the model it
needs to the GPU (~20 GB peak), which is what the Space does:
```bash
pip install -e ".[ui]"
python demo/app.py # IRIS_MODEL_REPO= to use other weights
```
## Iris-3B Turbo

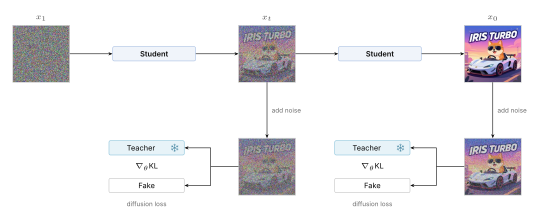
Iris-3B Turbo is a 4-step distilled version of Iris-3B. Classifier-free
guidance is baked into the weights, so each step is a single forward pass; a
1024×1024 image takes about 0.7 s on one H100 (batch 4). It is a full
fine-tune of all 3B parameters, not a LoRA, and ships in the
[`turbo/`](https://huggingface.co/speridlabs/iris-3b/tree/main/turbo) folder of
the Hugging Face repo (~6 GB, bf16). Try it in the
[Turbo demo](https://huggingface.co/spaces/speridlabs/iris-3b-turbo).
```bash
hf download speridlabs/iris-3b --include "turbo/*" --local-dir iris-3b # ~6 GB
python scripts/sample.py --checkpoint iris-3b/turbo \
--prompt "a red fox sleeping in fresh snow, golden hour"
```
`scripts/sample.py` recognises the folder by its `distill.yaml` and samples
with the schedule saved there: σ = 1, 0.938, 0.833, 0.625, deterministic
flow-Euler steps that reuse the noise implied by the current state, and no CFG.
The schedule is part of the model, so `--steps`, `--order`, `--shift`,
`--cfg-scale` and `--negative-prompt` do not apply; the prompt, `--height`,
`--width` and `--seed` do. Weights are upcast to FP32 and run under BF16
autocast, as in the evaluation below. Python API:
`iris3b.sampling.generate_few_step`. Turbo was distilled at about one megapixel
in 7 aspect buckets: 1024×1024, 752×1344, 896×1344, 896×1200 and their
transposes. The image above was generated on an H100 with `--seed 6` and the
prompt *Colorful animated cartoon poster: a smiling shiba inu in aviator
sunglasses behind the wheel of a low futuristic supercar, dynamic angle, neon
sunset sky, with big bold vector lettering "IRIS TURBO" in the sky*.
### Benchmarks
| Model | GenEval | DPG-Bench | LongText-Bench (EN) | OneIG-Bench (EN) |
|---|---|---|---|---|
| Iris-3B | 0.798 | 86.52 | 0.857 | 0.540 |
| Iris-3B Turbo | 0.820 | 86.68 | 0.804 | 0.516 |
| [iris-3b-turbo-lora](https://huggingface.co/pentacoxian-dev/iris-3b-turbo-lora) r2-1000 | 0.760 | 85.05 | 0.733 | 0.486 |
| OneIG-Bench (EN) | Alignment | Text | Reasoning | Style | Diversity |
|---|---|---|---|---|---|
| Iris-3B | 0.863 | 0.889 | 0.279 | 0.449 | 0.220 |
| Iris-3B Turbo | 0.862 | 0.848 | 0.283 | 0.433 | 0.154 |
| iris-3b-turbo-lora r2-1000 | 0.851 | 0.721 | 0.258 | 0.445 | 0.153 |
All models at 1024×1024 with the official scorers and the same prompts and
seeds; Iris-3B with its default sampling settings. The community adapter was run
with its recommended settings through its own code. Turbo is slightly ahead of
the base model on prompt following (GenEval, DPG-Bench) and behind it on long
rendered text and on OneIG-Bench, where the gap is mostly text and diversity.
### Training recipe

Turbo is distilled from Iris-3B with
[Trajectory Distribution Matching](https://arxiv.org/abs/2503.06674) (TDM),
data-free, as a full fine-tune of all 3B parameters in two stages. The trainer
is included: `scripts/distill.py` with one config per stage.
| | Stage 1 | Stage 2 (released) |
|---|---|---|
| Config | `configs/iris3b/turbo_stage1_6step.yaml` | `configs/iris3b/turbo_stage2_4step.yaml` |
| Steps (σ) | 6 (1, 0.926, 0.833, 0.714, 0.556, 0.333) | 4 (1, 0.938, 0.833, 0.625) |
| Initialization | Iris-3B | student: stage-1 EMA; fake network: stage 1 |
| Student updates | 1,600 | 500 |
| Global batch | 64 | 16 |
| Student / fake-network LR | 1e-6 / 5e-6 | 2.5e-7 / 2.5e-6 |
| EMA decay | 0.999 | 0.9995 |
| Prompts | ~981K | ~1.19M |
- **Networks**: frozen Iris-3B teacher, the student and a "fake" score network
trained online on the student's outputs; deterministic flow-Euler step
transitions.
- **Guidance**: CFG 3.5 (empty negative prompt) baked into the teacher target;
the student samples without CFG.
- **Optimizer**: AdamW, betas (0, 0.999), weight decay 0, gradient clipping 1.0,
constant LR, one fake update per student update.
- **Precision**: FP32 weights under BF16 autocast.
- **Resolution**: about 1 MP in 7 aspect buckets, one per global batch:
1024×1024, 752×1344, 896×1344, 896×1200 and their transposes.
- **Prompts**: text only, no images. Stage 1: fine-grained text-to-image
prompts, MONET captions, rendered-text prompts and SFT captions, about 12%
with quoted text. Stage 2: MONET captions, captions of text-rendering sources
and other SFT captions. The prompt sets are not released.
- **Release**: the stage-2 EMA weights, exported in bf16.
```bash
torchrun --nproc_per_node=8 scripts/distill.py --config configs/iris3b/turbo_stage1_6step.yaml \
teacher=iris-3b prompts_file=prompts.txt
torchrun --nproc_per_node=2 scripts/distill.py --config configs/iris3b/turbo_stage2_4step.yaml \
teacher=iris-3b prompts_file=prompts.txt \
init_from=output/turbo/stage1_6step/checkpoints/step_00001600.pth
python scripts/export_distilled.py output/turbo/stage2_4step/checkpoints/step_00000500.pth \
exported/iris-3b-turbo --dtype bf16
```
`teacher` is the exported Iris-3B directory from [Inference](#inference) and
`prompts_file` a UTF-8 text file with one prompt per line. Interrupted runs
continue with `resume_from=/checkpoints/latest.pth`;
`strategy=fsdp2` shards the student, the fake network and their optimizer
states across GPUs when DDP does not fit.
### Thanks to the community turbo LoRA
The first few-step Iris came from the community:
[pentacoxian-dev](https://huggingface.co/pentacoxian-dev) built
[iris-3b-turbo-lora](https://huggingface.co/pentacoxian-dev/iris-3b-turbo-lora)
([code](https://github.com/pentaCoxian/iris-3b-turbo),
[demo](https://huggingface.co/spaces/pentacoxian-dev/iris-3b-turbo)), a 4-step
DMD2 distillation packaged as a rank-64 LoRA. It is a lightweight 460 MB adapter
trained on a single consumer GPU, far easier to download, share and build on
than a full 6 GB checkpoint. Thank you, it is a joy to see Iris picked up by
the community this quickly.
### Limitations
- Dense or long rendered text is less reliable than with the base model.
- Less variety across seeds: different seeds for one prompt give more similar
images.
- Faint grain or speckle can appear on flat, vector-style backgrounds.
- Sampling is fixed at 4 steps, with no CFG or negative prompt.
## Training
### Data
Training reads tar shards indexed by a `wids-meta.json`. Each sample is an
image plus a JSON with its `caption`, `height` and `width`. Build them from a
folder of images with `.txt`/`.json` caption sidecars, or from a Hugging Face
dataset:
```bash
python scripts/prepare_wids.py folder /path/to/images --out /data/my-set
python scripts/prepare_wids.py hf user/dataset --split train \
--image-column image --caption-column text --out /data/my-set
```
### Recipe
Iris-3B was trained in three resolution stages followed by supervised
fine-tuning, each resuming from the previous one. The configs list only what
differs from the defaults in `src/iris3b/config.py`:
| Config | Resolution | Steps | Global batch | Shift | Notes |
|---|---|---|---|---|---|
| `configs/iris3b/stage1_256.yaml` | 256² | 0 → 365K | 1024 | 2 | REPA (DINOv2-B/14, weight 0.5) |
| `configs/iris3b/stage2_512.yaml` | 512, multi-aspect | 365K → 530K | 1024 | 3 | |
| `configs/iris3b/stage3_1024.yaml` | 1024, multi-aspect | 530K → 625K | 512 | 4 | LR 5e-5 |
| `configs/iris3b/sft_1024.yaml` | 1024, multi-aspect | 625K → 665K | 512 | 4 | constant LR 4e-5, no warmup |
Common to all stages: hybrid Muon — Muon (momentum 0.95, Nesterov, RMS-matched
LR) for hidden weight matrices, AdamW (β₁ 0.9, β₂ 0.95) for embeddings, norms and
biases — with weight decay 0, gradient clipping at 0.5 and a constant LR of 1e-4
after a 2K-step linear warmup unless noted. EMA decay 0.9999, 10% caption dropout
for classifier-free guidance, logit-normal (0, 1) timesteps with the
resolution-dependent shift above. From the 512 stage on, RoPE uses isotropic
coordinates for non-square images. bf16, FSDP2 hybrid sharding, `torch.compile`.
Single node:
```bash
torchrun --nproc_per_node=8 scripts/train.py --config configs/iris3b/stage1_256.yaml \
data.data_dirs=[/data/my-set] train.expected_global_batch=128
```
Multi-node (run on every node with its own `NODE_RANK`):
```bash
NNODES=8 NODE_RANK=0 MASTER_ADDR=node0 \
scripts/launch_multinode.sh configs/iris3b/stage1_256.yaml data.data_dirs=[/data/my-set]
```
Any config key can be overridden as `key=value` after the config path.
### Tests
```bash
pytest -q
```
## Acknowledgements
The dual-level design (a patch-level transformer followed by a pixel-level
transformer head) follows the architecture described in
[PixelDiT](https://arxiv.org/abs/2511.20645). This is an independent
implementation; it contains no code from that project. We also build on
[DiT](https://arxiv.org/abs/2212.09748),
[REPA](https://arxiv.org/abs/2410.06940),
[Muon](https://kellerjordan.github.io/posts/muon/) through
[Dion](https://github.com/microsoft/dion),
[Qwen3-VL](https://github.com/QwenLM/Qwen3-VL),
[DINOv2](https://github.com/facebookresearch/dinov2) and, for Iris-3B Turbo,
[TDM](https://arxiv.org/abs/2503.06674).
## License
The code in this repository and the model weights on
[Hugging Face](https://huggingface.co/speridlabs/iris-3b) are licensed under the
[Apache License 2.0](LICENSE); see also [NOTICE](NOTICE).
Third-party components are not redistributed here and remain under their own
licenses:
| Component | Use | License |
|---|---|---|
| [Qwen3-VL-4B-Instruct](https://huggingface.co/Qwen/Qwen3-VL-4B-Instruct) | frozen text encoder, downloaded at runtime | Apache 2.0 |
| [DINOv2](https://github.com/facebookresearch/dinov2) | REPA teacher (training only), downloaded at runtime | Apache 2.0 |
| [Dion](https://github.com/microsoft/dion) | Muon optimizer, pip dependency | MIT |
## Citation
```bibtex
@article{licai2026iris,
title = {Iris-3B: Going Beyond the Latent with Pixel-Space
Diffusion Training, Conversion and Fine-Tuning},
author = {Li Cai, Hanqiu and Garabito, Chema},
journal = {arXiv preprint arXiv:2610.09450},
year = {2026},
url = {https://arxiv.org/abs/2610.09450}
}
```
---
**Made with ❤️ by [speridlabs.com](https://speridlabs.com)**