---
title: "Shared MCP pool"
description: "ainb runs one MCP server process per server name, shared across every host session over a unix socket: so a swarm of Claude/Codex/Copilot sessions stops spawning a node/bun process per session per MCP. Configure with [mcp_pool], import from .mcp.json, install for other agent CLIs."
---
import { Tabs, TabItem, Steps, Card, CardGrid, Aside } from '@astrojs/starlight/components';
Every Claude Code session normally spawns its **own** node/bun process for each configured MCP server. Run a swarm of sessions and that multiplies into dozens of processes hogging CPU and RAM ([anthropics/claude-code#45880](https://github.com/anthropics/claude-code/issues/45880) reports kernel panics from 510 node processes). The **shared MCP pool** fixes this: a standalone `ainb mcp daemon` spawns each MCP server **once** behind a unix socket, and every session attaches through a tiny `ainb mcp proxy` stdio shim. N sessions, one backend process.
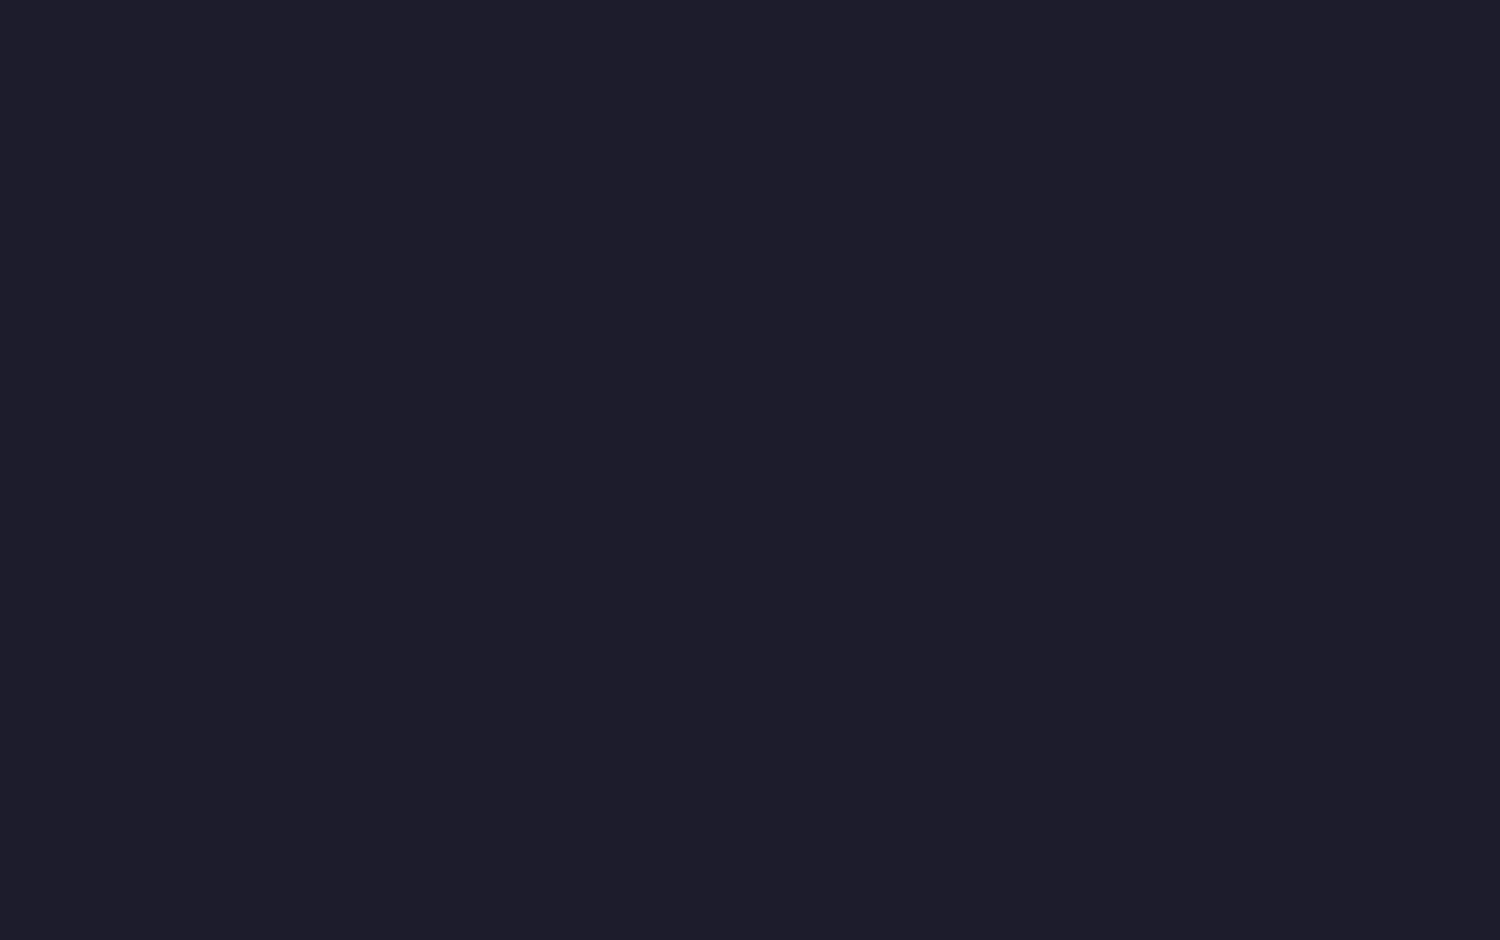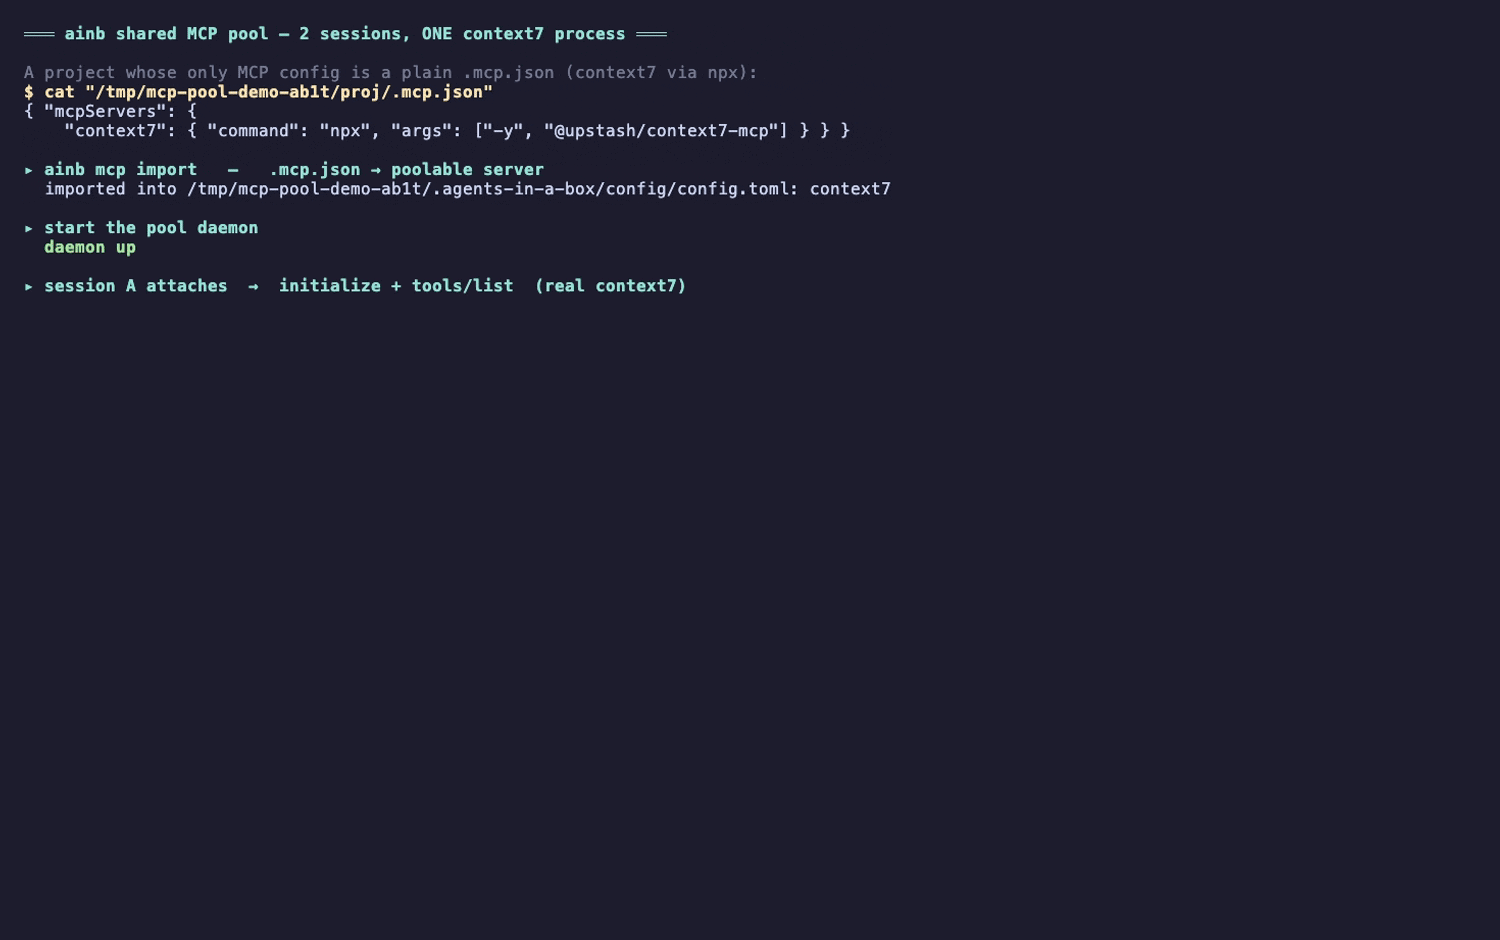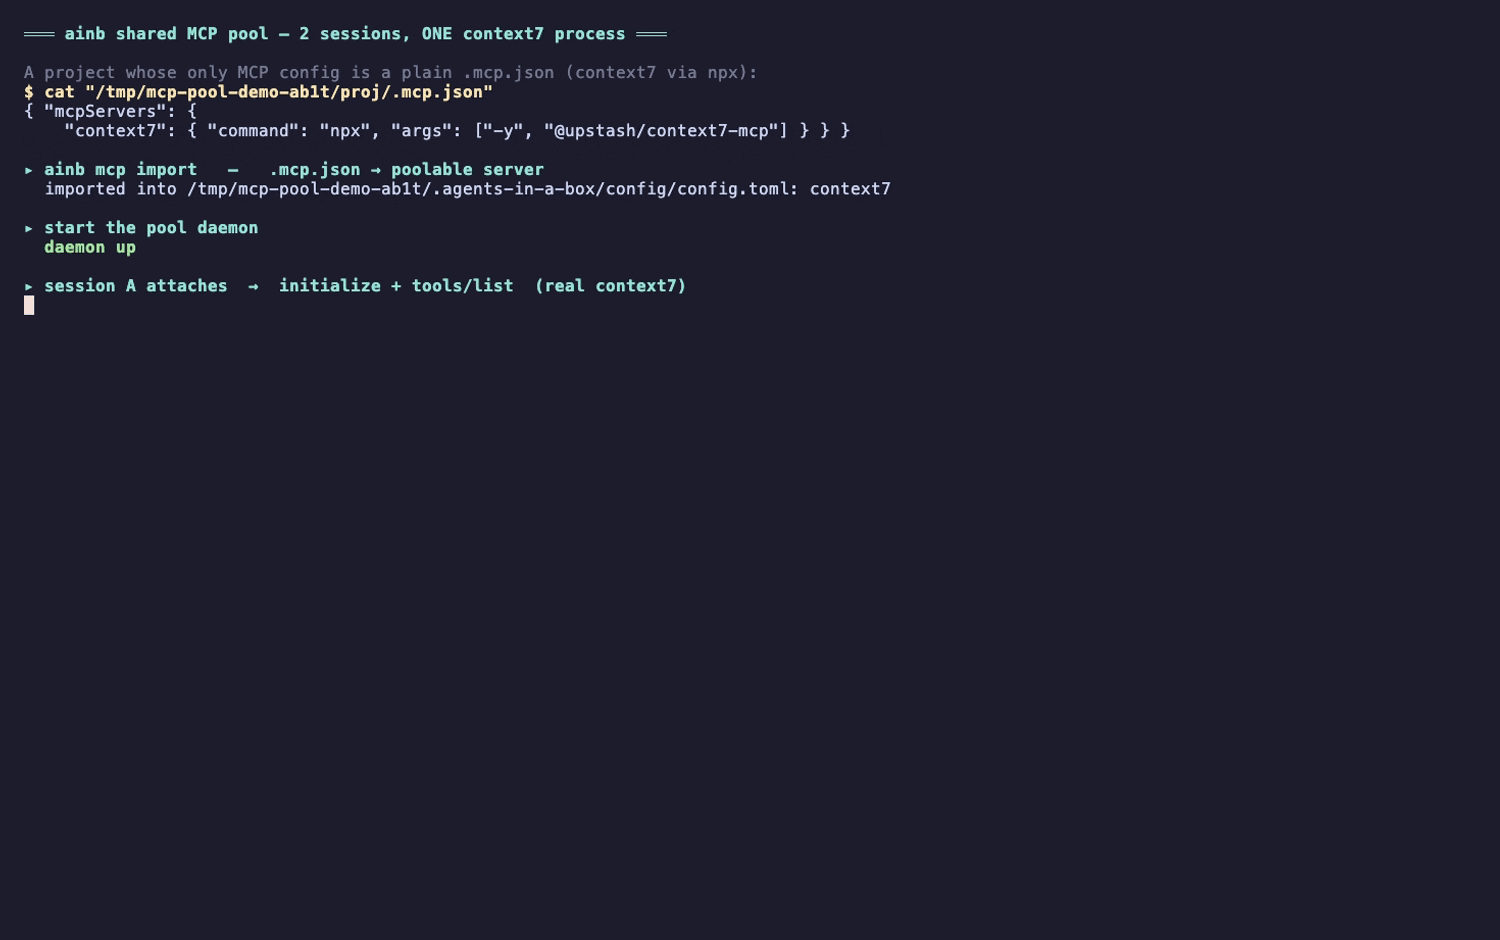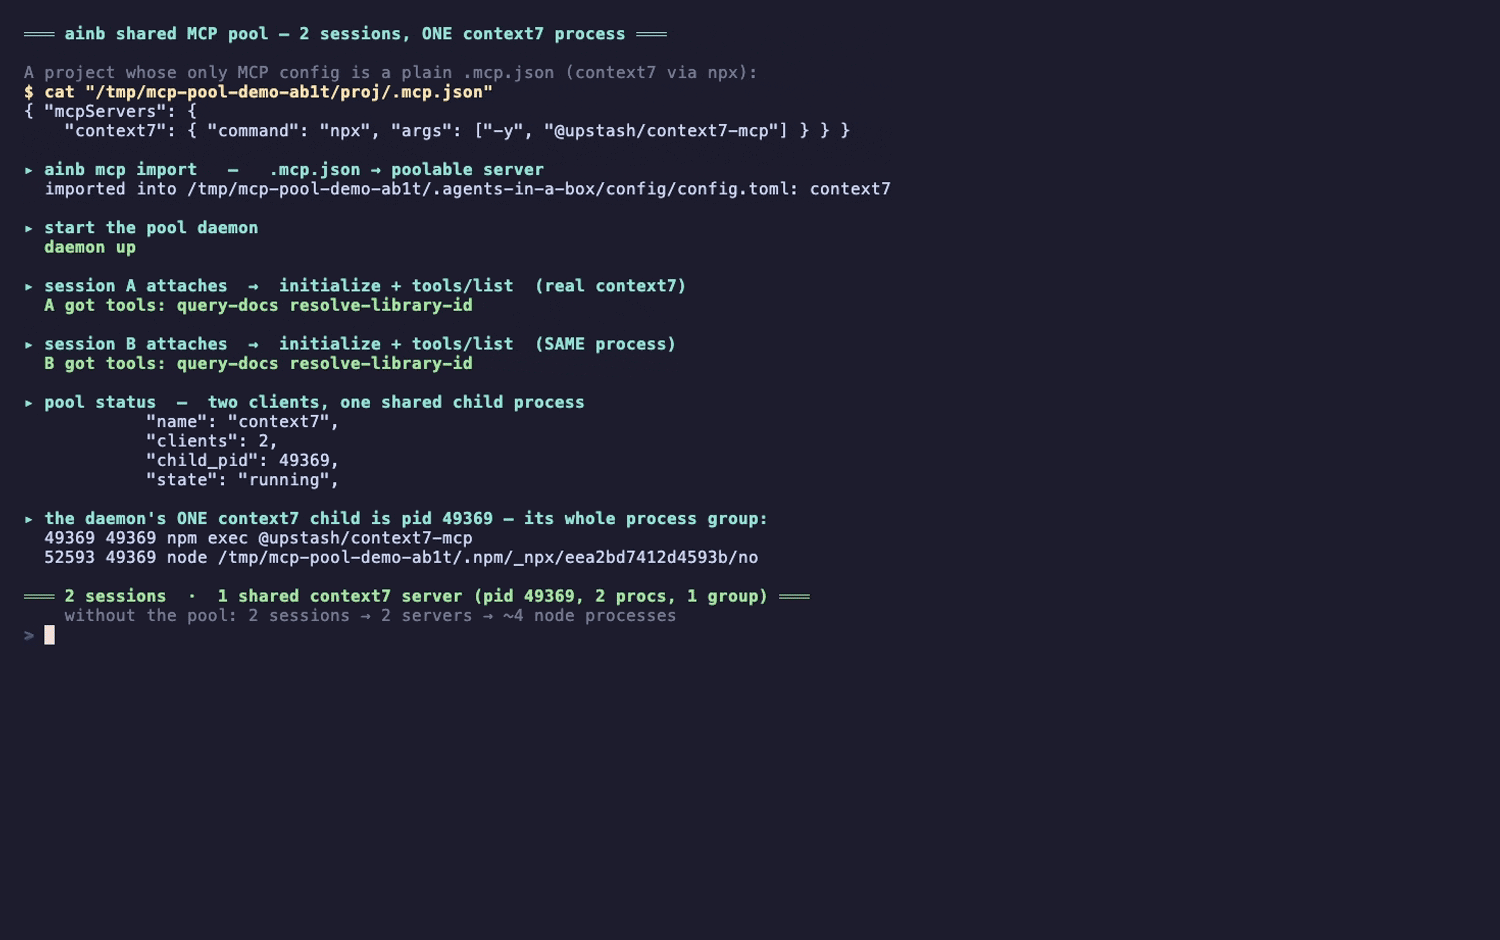
*Two sessions attach to a real context7 server and both receive its tools (`resolve-library-id`, `query-docs`). `ainb mcp status` reports `clients: 2` against one `child_pid`: a single shared process group. Without the pool, those two sessions would spawn two separate context7 servers.*
node procs that kernel-panicked a Mac: [claude-code#45880](https://github.com/anthropics/claude-code/issues/45880).
processes measured by the community shared-proxy workaround (7 sessions × 5 servers).
live e2e assertions pass: `scripts/validate-mcp-pool.sh`.
## The problem: MCP process explosion
MCP's stdio transport is one-client-only by design: the client launches the server as a subprocess and owns its stdin/stdout pipe. So every session that wants a server spawns its own copy. Multiply by a swarm of worktree sessions and the math gets ugly fast: Anthropic issue `claude-code#45880` reports 15 sessions × 34 servers demanding up to 510 node processes: enough to trigger hardware-watchdog kernel panics. The community workaround (a shared HTTP proxy) measured an 80% process / 77% memory reduction. ainb bakes that win in natively, no extra runtime.
## Quick start
1. The pool is **on by default**: there's nothing to enable for a basic setup.
2. Point at any project that has MCP servers in its `.mcp.json` (or in ainb config), then start a session as usual:
```bash
ainb run --repo . --worktree
```
ainb ensures the daemon is running and rewrites the worktree's `.mcp.json` so each pooled server points at the shim.
3. Confirm sessions are sharing one backend:
```bash
ainb mcp status # look for "clients": N against a single "child_pid"
```
## Walkthrough: from scratch
The full journey in one recording: a project whose only MCP config is a plain `.mcp.json`, made poolable with `ainb mcp import`, two sessions attaching to a **real** context7 server, and the proof that both share **one** backend process.
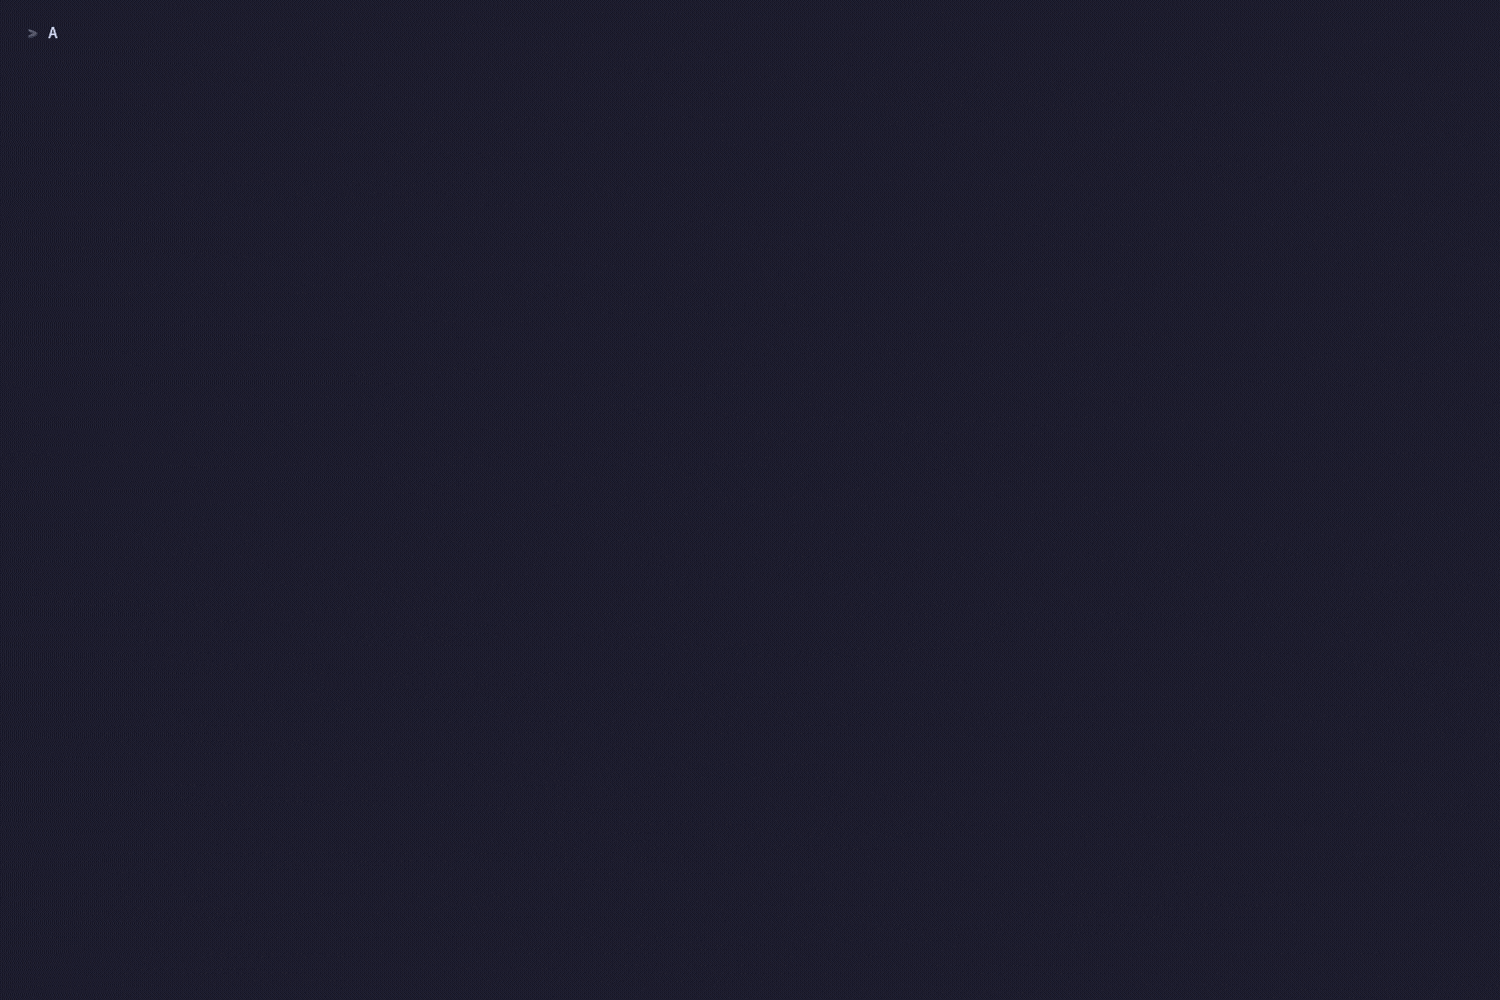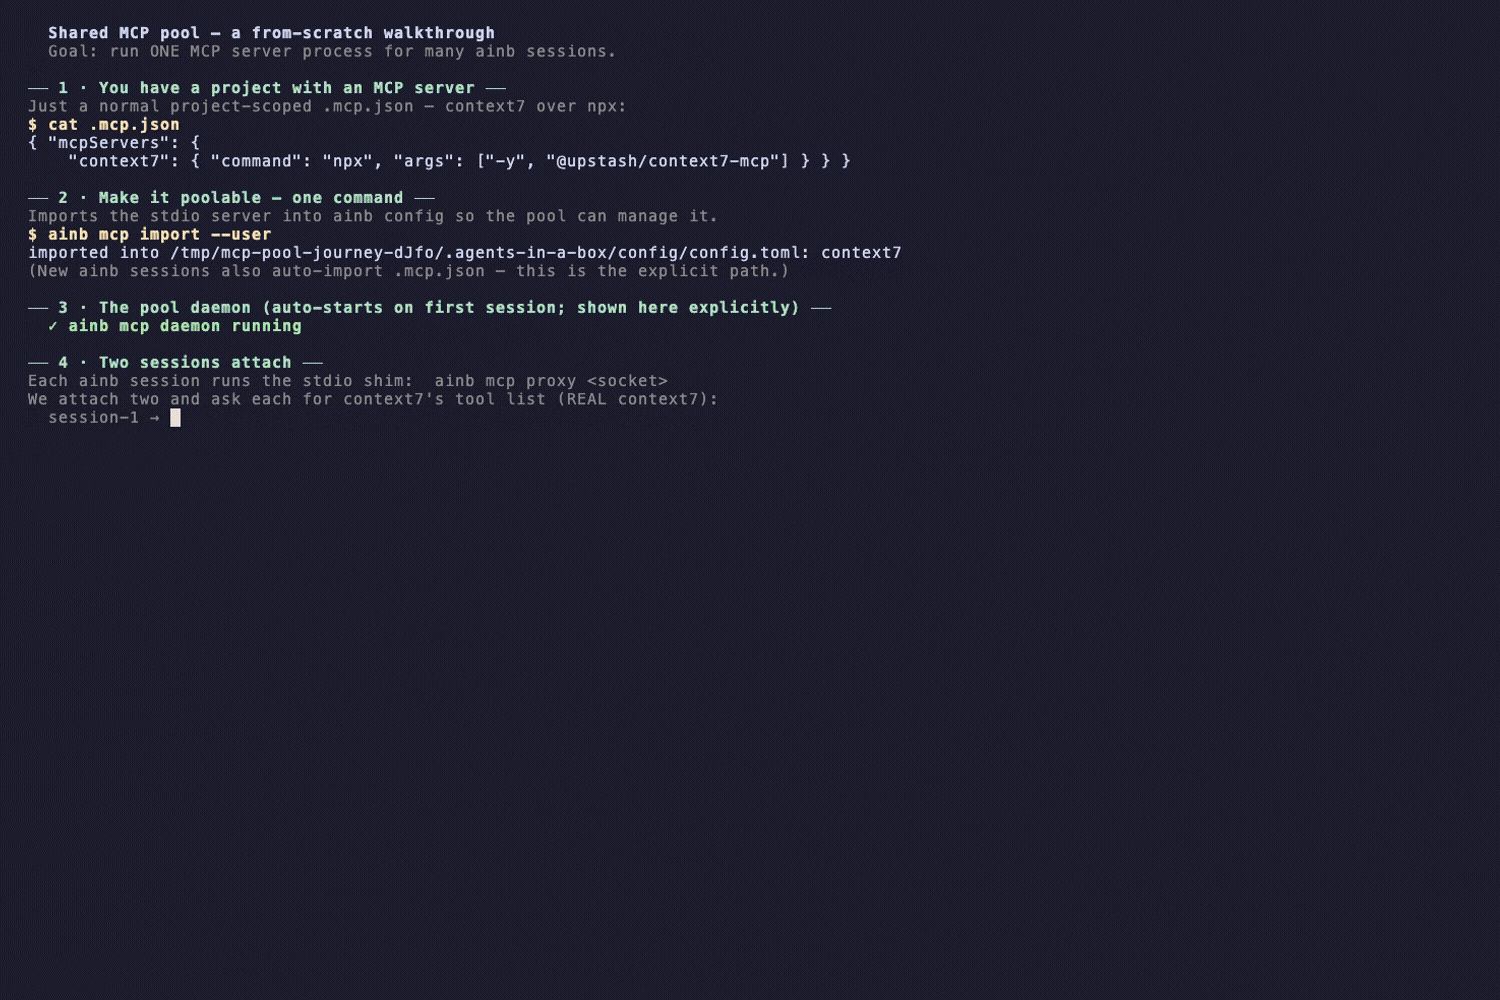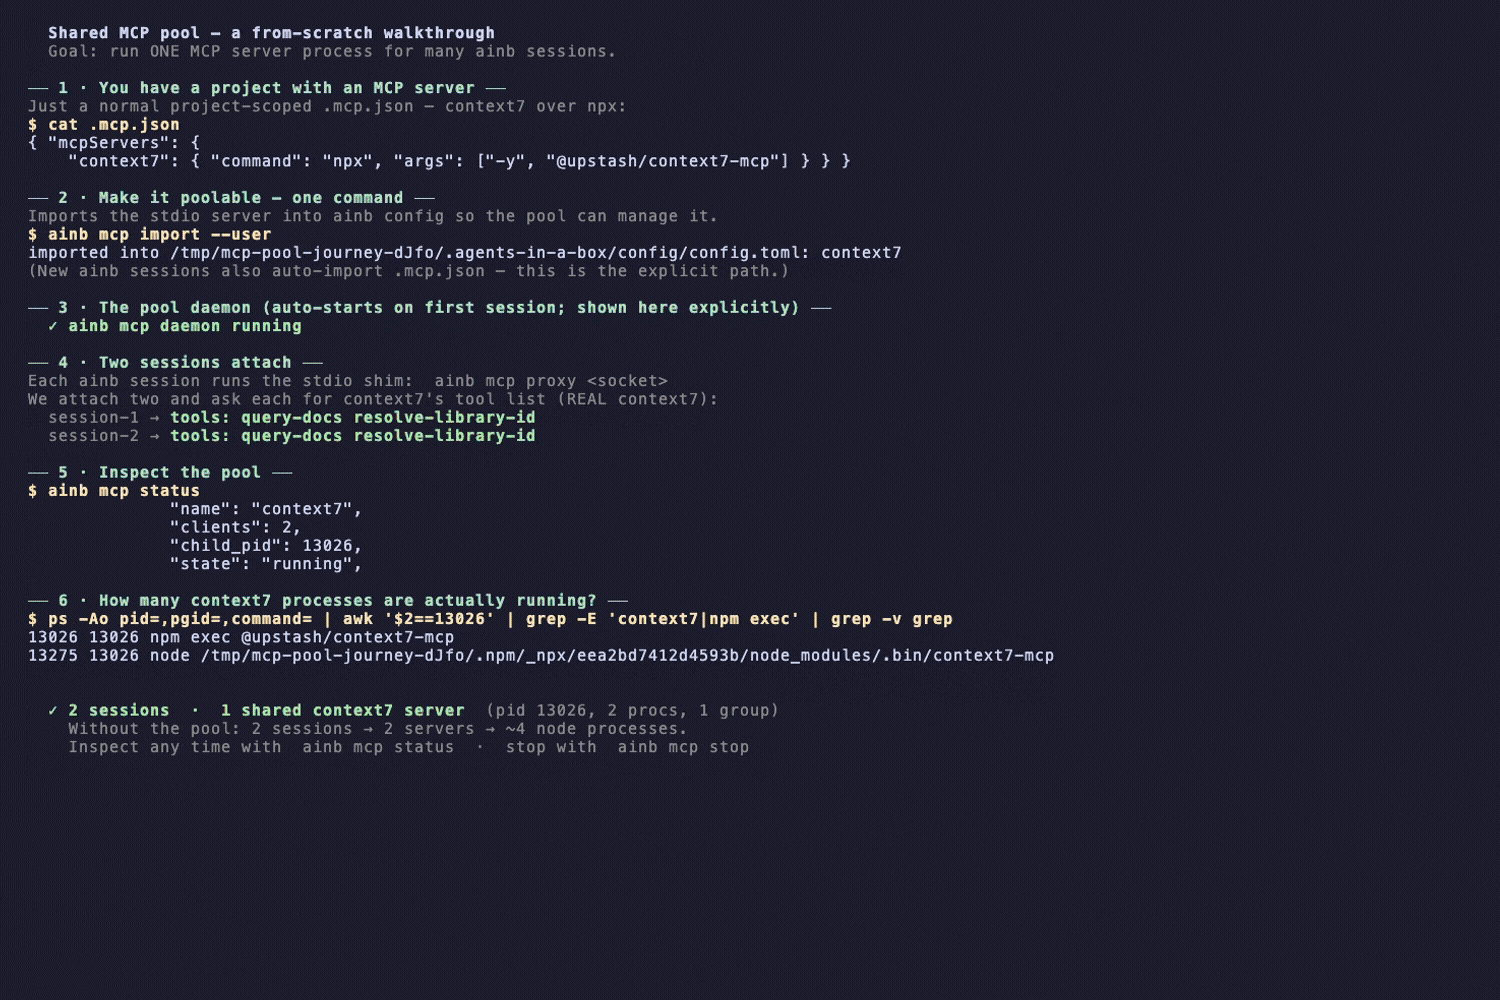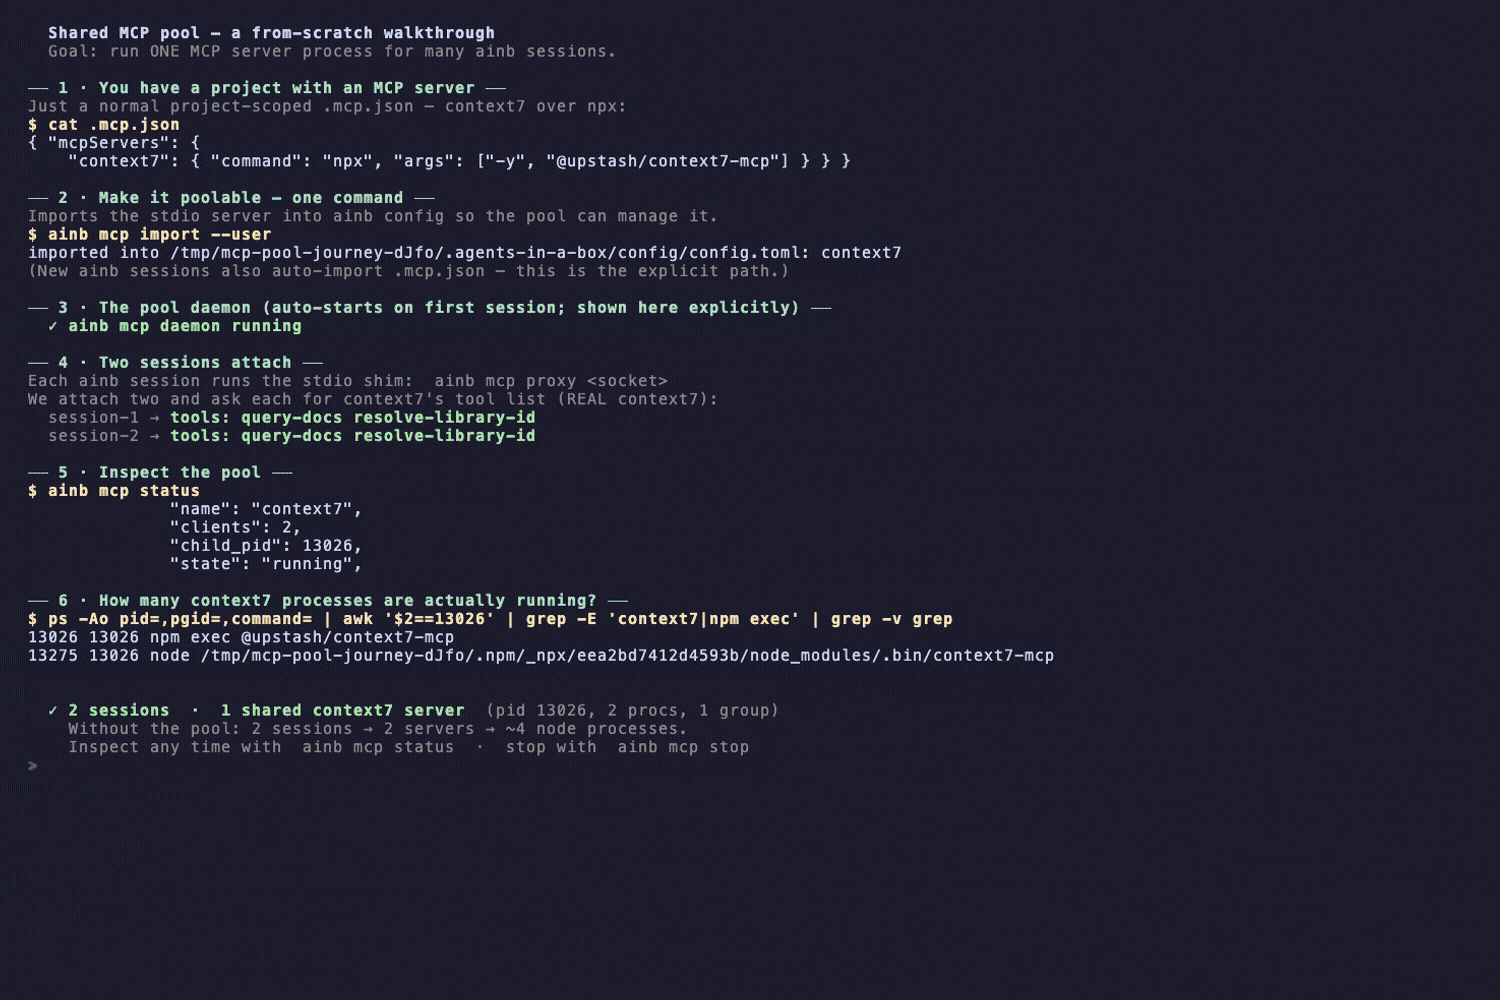
*Every command in the recording is one you'd run yourself. Reproduce it with `scripts/mcp-pool-journey.sh` (real context7, isolated `$HOME`, no Claude auth needed).*
## Wire it up: per agent
The shim is just a stdio command, so any agent CLI can funnel into the same backend processes. Claude is automatic; Codex and Copilot need one wiring command.
Zero-config: the pool is wired automatically when you `ainb run`.
1. Have your MCP servers in the project's `.mcp.json` (or in ainb config).
2. Start a session:
```bash
ainb run --repo . --worktree
```
Stdio servers in the worktree's `.mcp.json` are auto-imported into the pool and the file is rewritten to point at the shim. Nothing else to do.
3. Verify:
```bash
ainb mcp status
```
Codex reads a global MCP config, so wire it once.
1. Install the pool shim into Codex's config (a `.bak` backup is written first):
```bash
ainb mcp install --codex
```
This adds shim entries to `~/.codex/config.toml` pointing at the pool sockets.
2. Make sure the daemon is up: any ainb Claude session starts it, or run it yourself:
```bash
ainb mcp daemon &
```
3. Start Codex. Its MCP sessions now share the same backend processes as your Claude sessions.
Same one-time wiring for GitHub Copilot CLI.
1. Install the pool shim into Copilot's config (a `.bak` backup is written first):
```bash
ainb mcp install --copilot
```
This writes shim entries into `~/.copilot/mcp-config.json`.
2. Ensure the daemon is running:
```bash
ainb mcp daemon &
```
3. Start Copilot: its MCP servers now attach to the shared pool.
Wire both at once with `ainb mcp install --codex --copilot`. A Codex session, a Copilot session, and three Claude sessions then all funnel into the same context7 process.
## Configure the pool
Pool settings and per-server opt-out live in `config.toml` (user-level `~/.agents-in-a-box/config/config.toml`, or per-repo `.ainb/config.toml`), or in the TUI under **Configuration → MCP Pool**. You usually don't have to hand-write any of this: see the **.mcp.json** and **import** tabs.
```toml
# ~/.agents-in-a-box/config/config.toml (user-level)
# …or ./.ainb/config.toml (per-repo override)
[mcp_pool]
enabled = true # default true
idle_grace_secs = 300 # reap a pooled server's child N seconds after its last session detaches
daemon_idle_grace_secs = 900 # exit the whole daemon after N seconds with NO clients (0 = never)
[mcp_servers.context7]
name = "context7"
description = "docs server"
enabled_by_default = true
shared = true # set false for stateful servers (browser/db bridges) → per-session spawn
installation = { type = "PreInstalled" }
definition = { type = "Command", command = "npx", args = ["-y", "@upstash/context7-mcp"] }
```
You don't have to declare servers in ainb config at all. A project whose only MCP config is a plain `.mcp.json`:
```json
{
"mcpServers": {
"context7": { "command": "npx", "args": ["-y", "@upstash/context7-mcp"] }
}
}
```
`ainb run` auto-imports the stdio entry, registers it with the daemon, and rewrites `.mcp.json` to point at the shim. Remote (`http`/`sse`) entries are left alone: there's no local process to pool.
Persist `.mcp.json` + Claude user-scope servers into ainb config so they're managed explicitly:
```bash
ainb mcp import # → ./.ainb/config.toml (project)
ainb mcp import --user # → ~/.agents-in-a-box/config/config.toml (user-level)
```
Existing config entries are never overwritten; comments and formatting are preserved.
```bash
ainb mcp status
```
```json
{
"servers": [
{
"name": "context7",
"clients": 2,
"child_pid": 40859,
"state": "running"
}
]
}
```
`clients: 2` against a single `child_pid` is the proof two sessions share one process.
## Monitor the pool
Open the **MCP** entry in the home sidebar (or press `p` for *pool*) for a live overlay of what's served right now: and **which sessions share each backend process**.
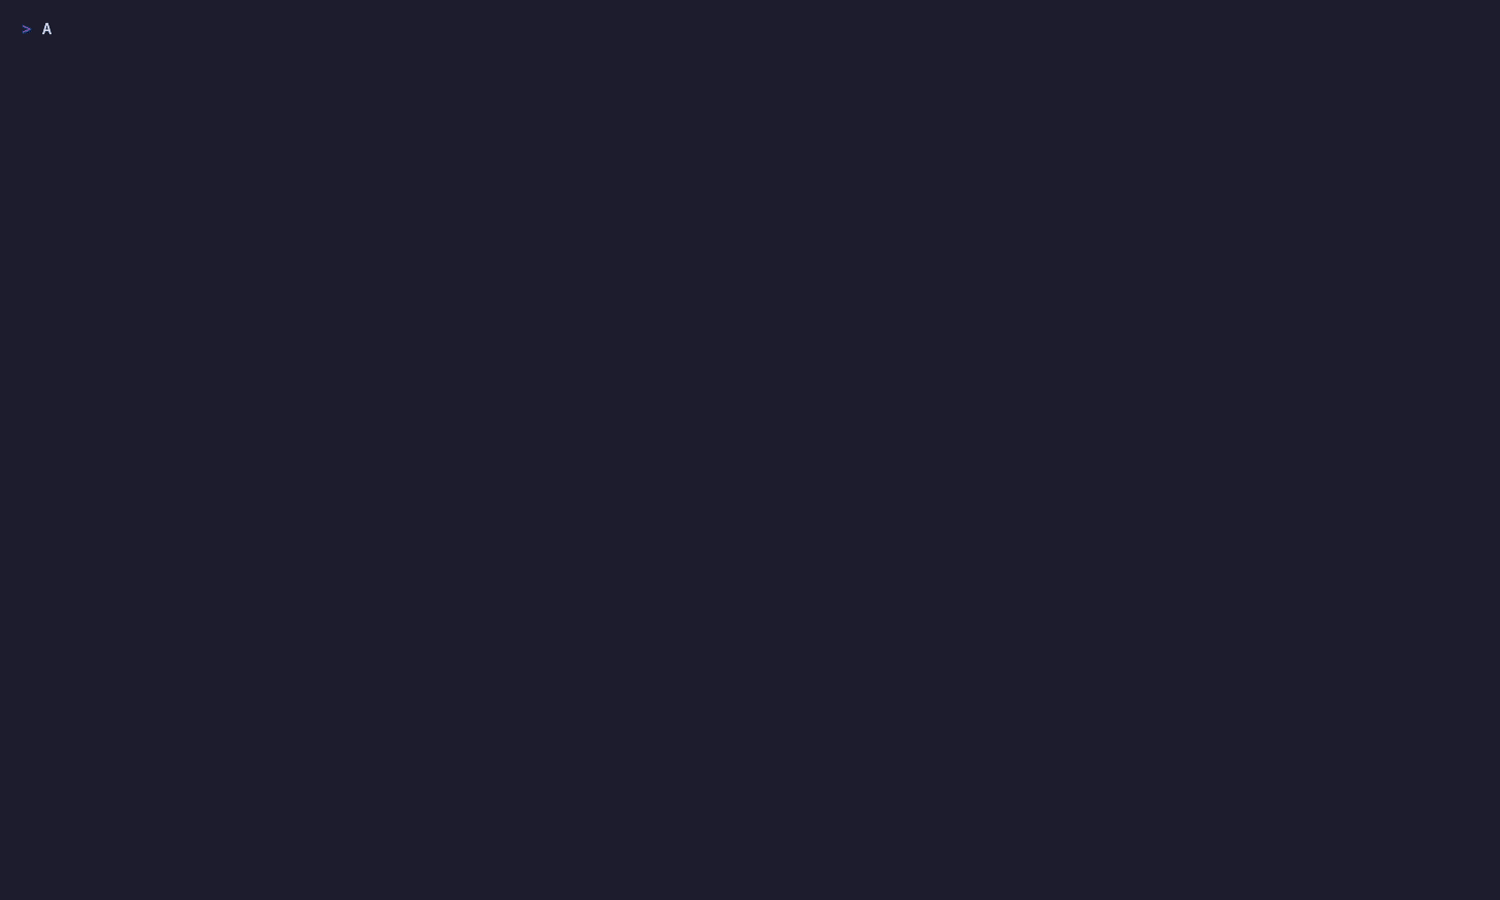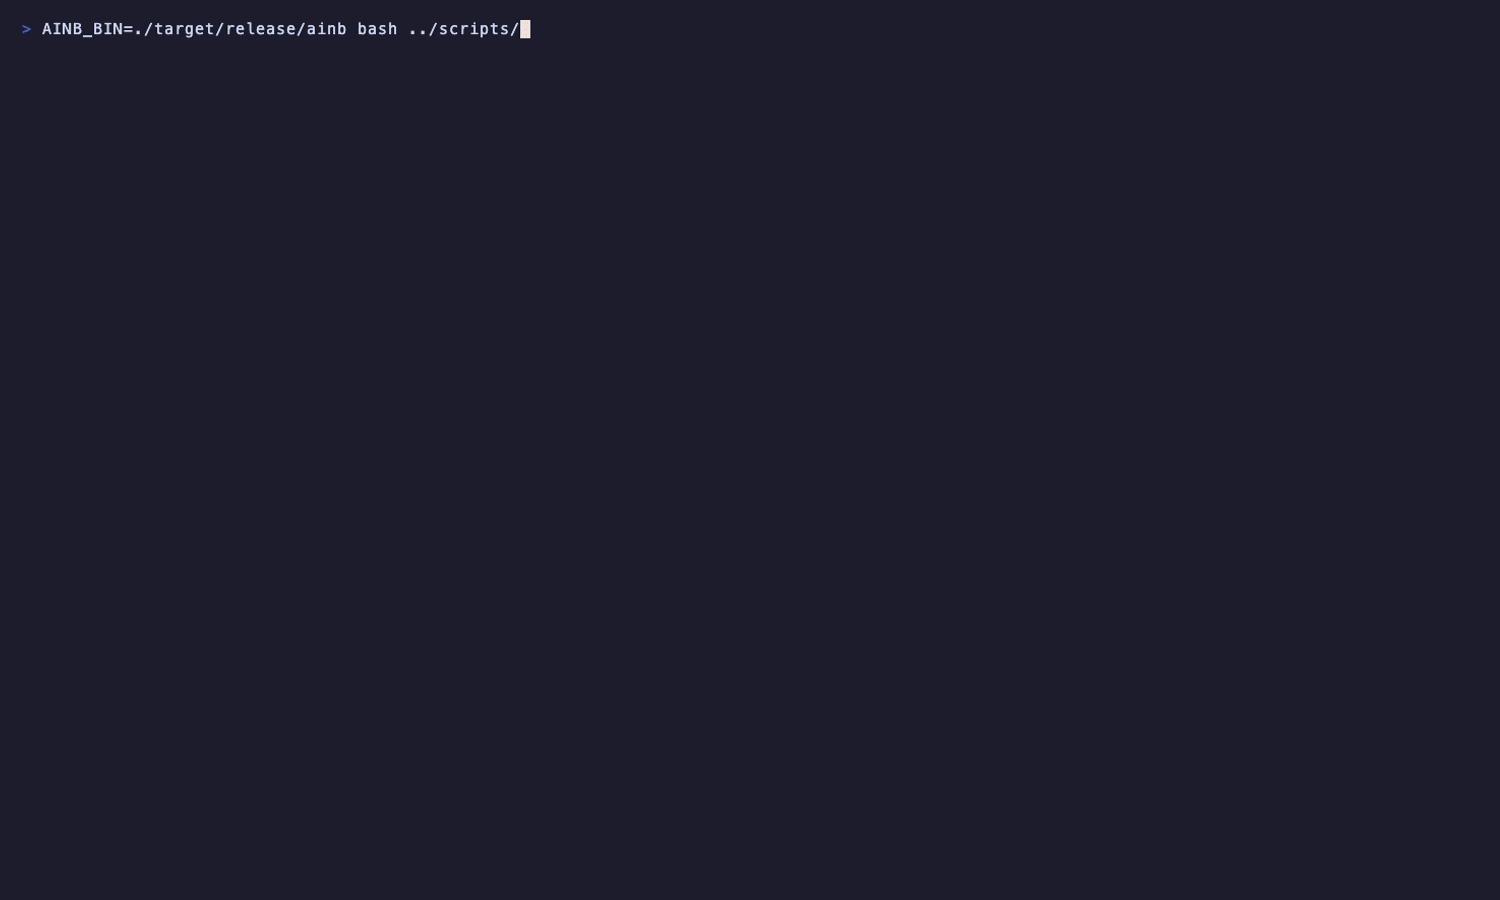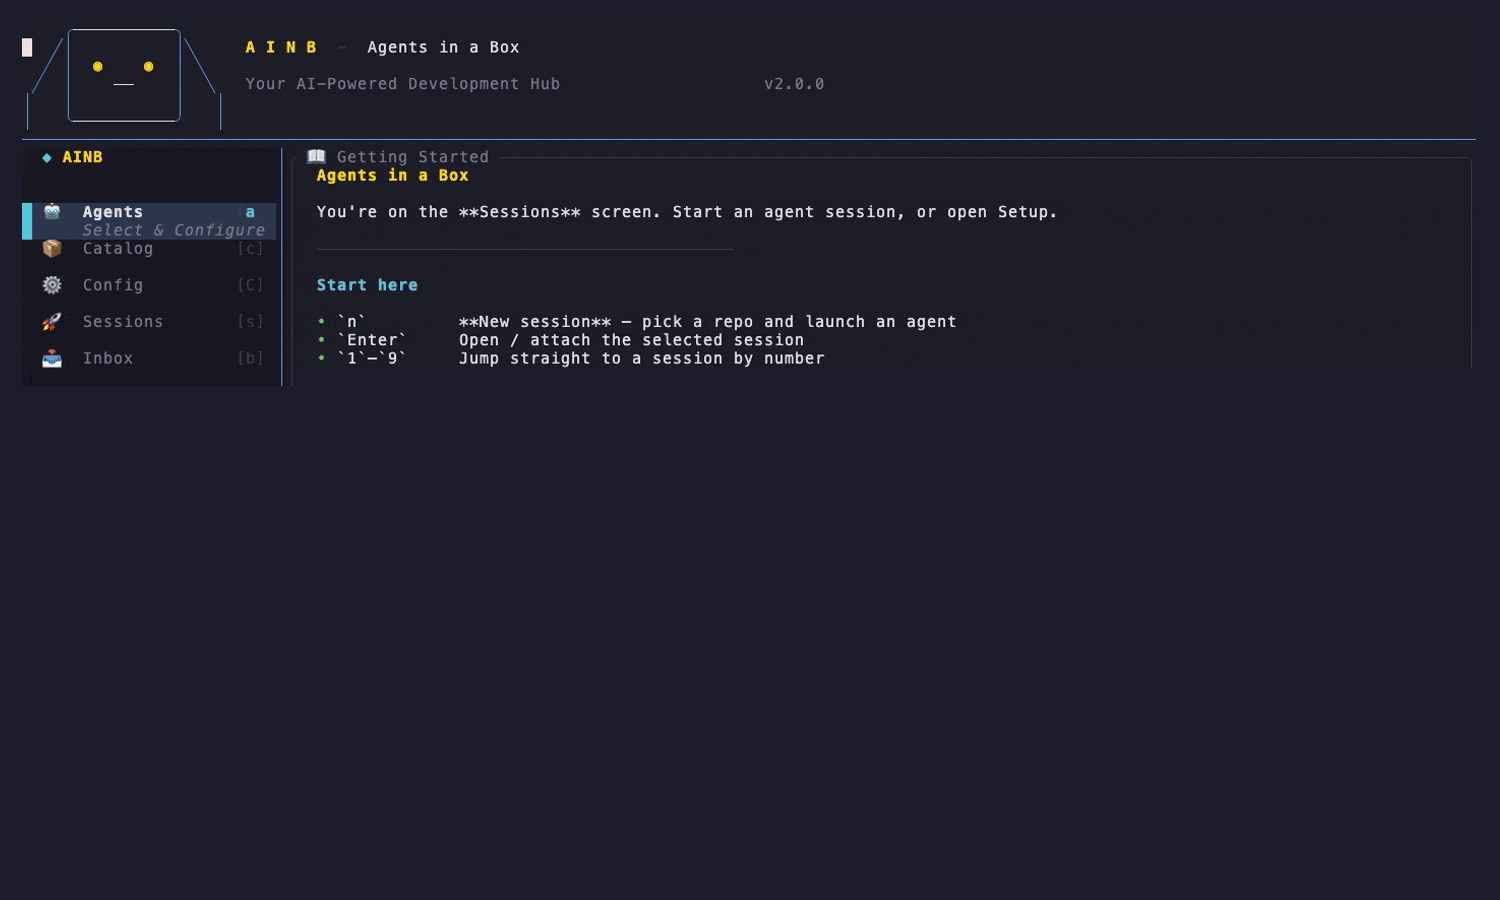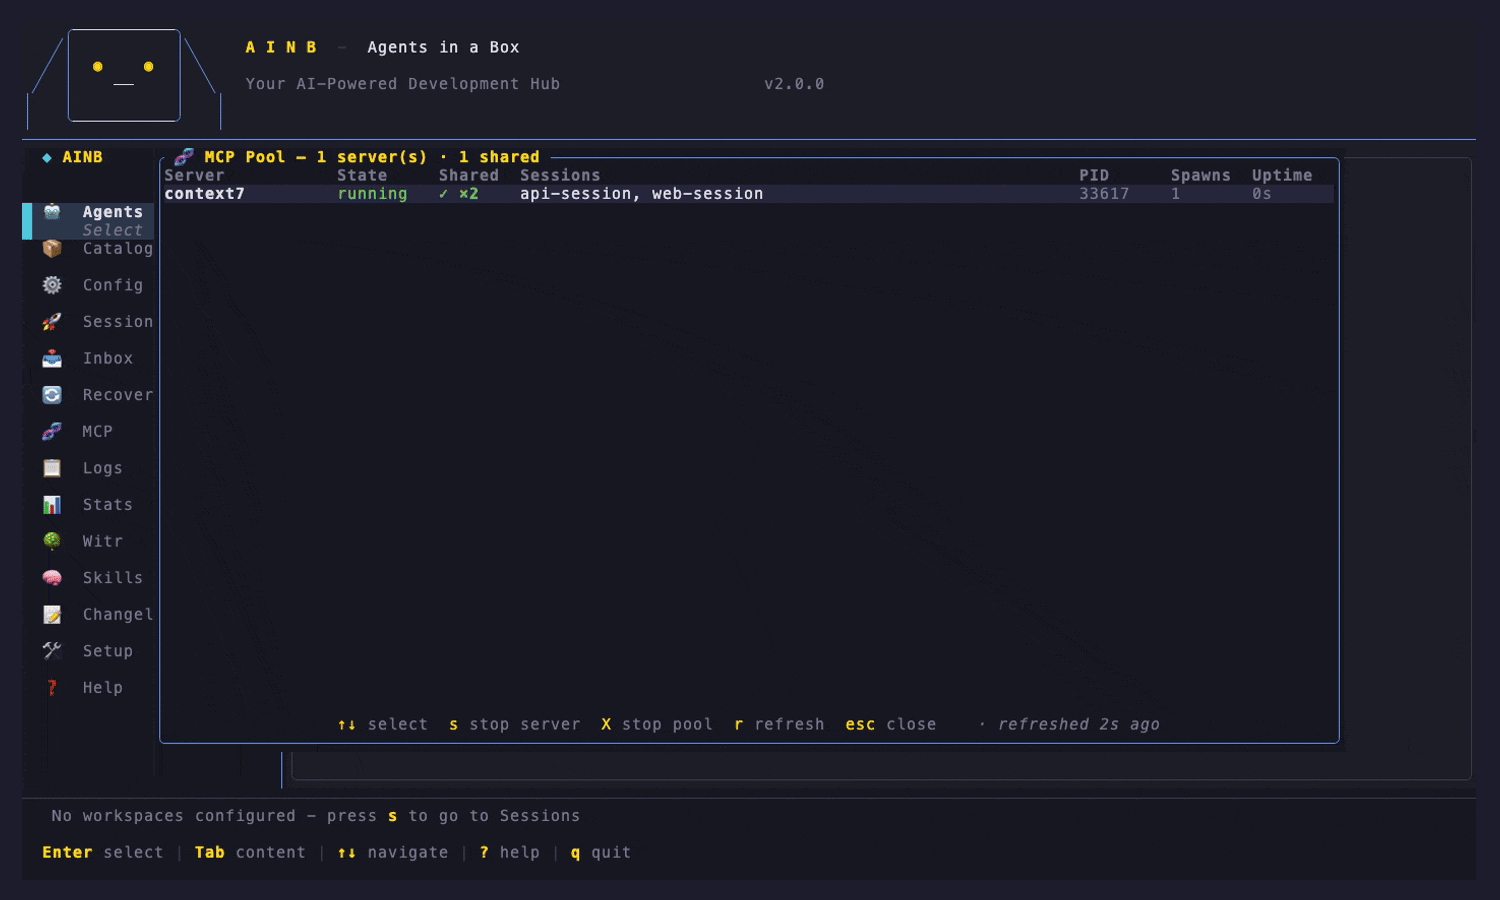
*Two sessions sharing one context7 process: the overlay names them (`api-session`, `web-session`) against a single `pid`. The session label is the ainb session name, passed through the shim's `--session` flag.*
What the table shows per server: **state** (running / grace / idle / failed), **shared** (`✓ ×N` when more than one session is attached), the **session names**, the backend **pid**, **spawn count**, and **uptime**.
Actions:
- **`i`: import**: pulls stdio servers from your Claude user scope (`~/.claude.json`): plus the launch directory's `.mcp.json` if there is one: into the **global user config** (`~/.agents-in-a-box/config/config.toml`), then makes them show up in the table right away: if the pool daemon is running they're registered with it; if it isn't, **import starts it** (the daemon loads every configured server on boot), so you never get an "imported ✓" with an empty table. The overlay is a *global* pool view (it isn't bound to any worktree), so import targets the user config: the one config read from anywhere; per-worktree `.mcp.json` servers are already auto-imported at session create. Import is additive: existing entries are never overwritten, and servers whose command doesn't resolve on the host are skipped. The result (`▸ imported … · started pool`) shows in a line above the help bar.
- **`s`: stop server** (confirmed): reaps the selected server's process; attached sessions reconnect and the next attach respawns it.
- **`X`: stop pool** (confirmed): shuts the whole daemon down; every session falls back to its own MCP processes.
- **`r`** refreshes on demand; **`esc`** / **`q`** closes.
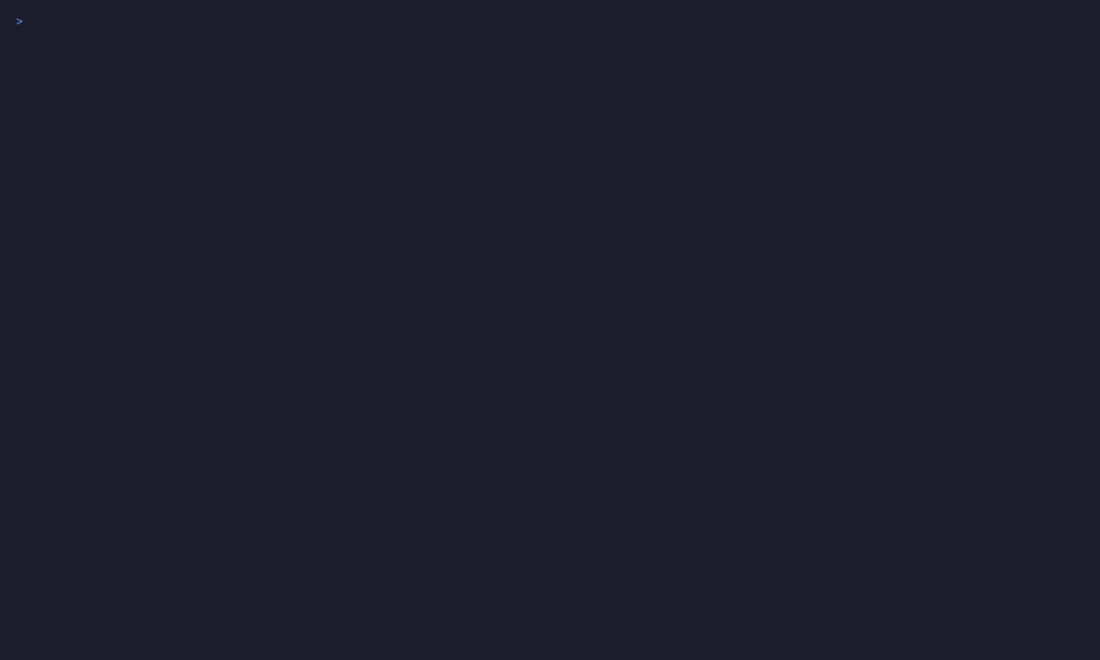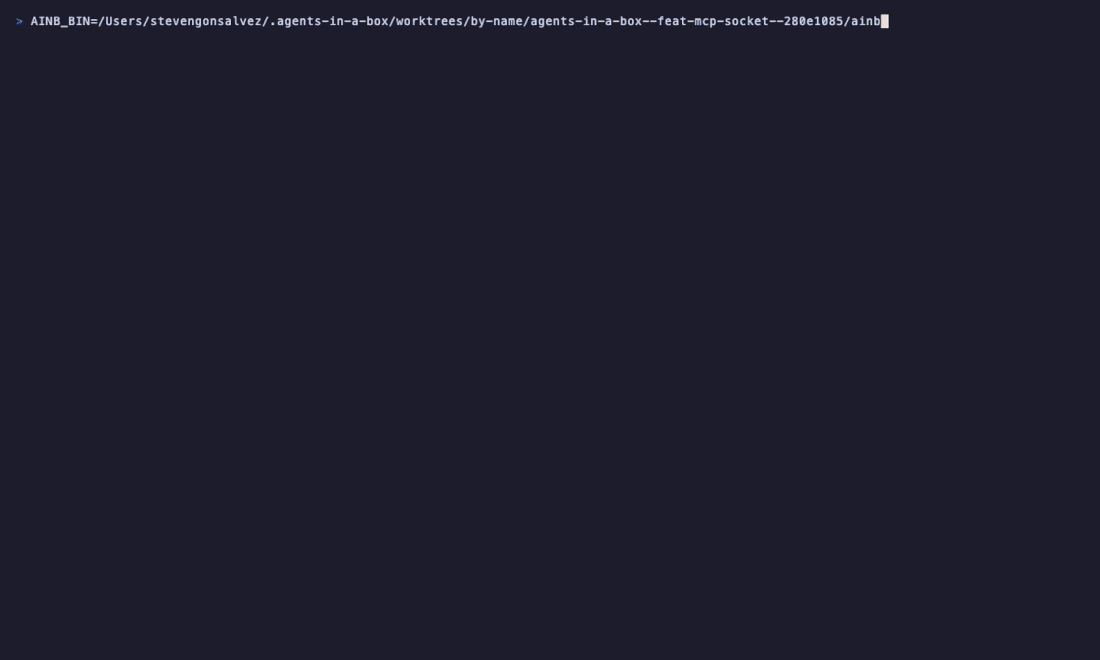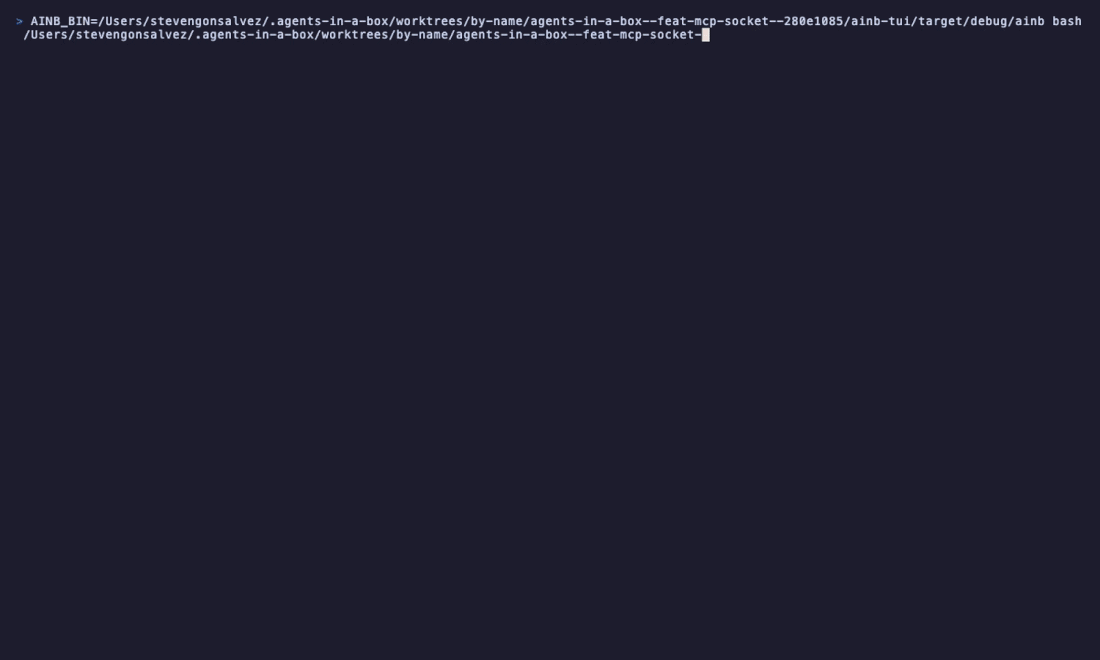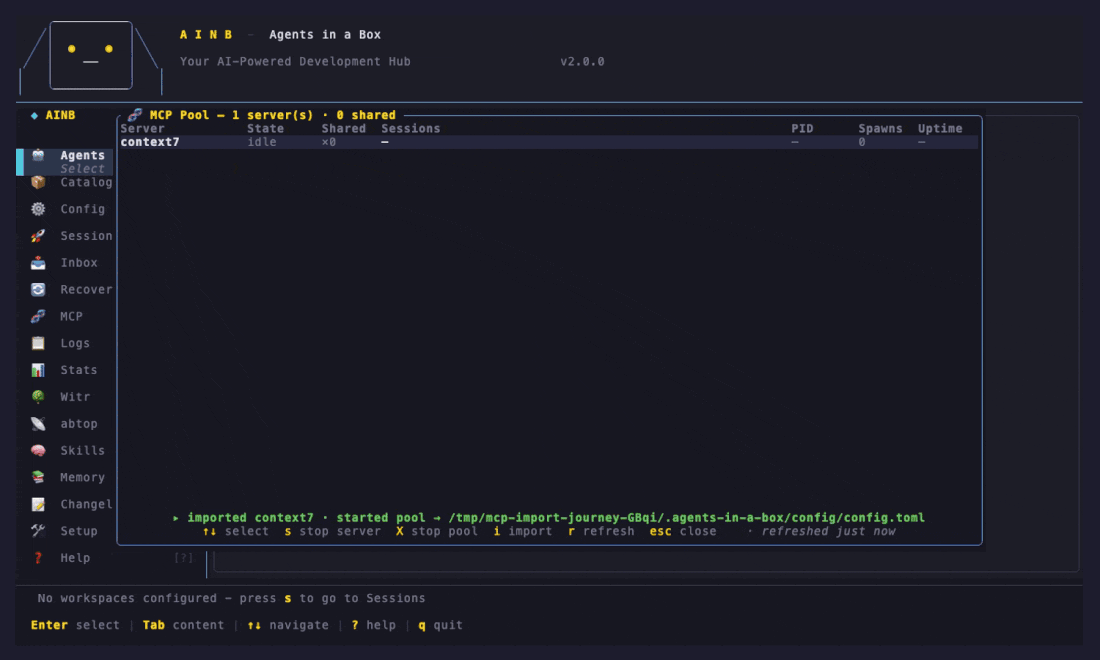
*Press `i` in the overlay to bring servers in from `.mcp.json` without dropping to a shell: it writes the config and registers them live.*
## How it works
```
session A ──stdio── ainb mcp proxy ──┐
session B ──stdio── ainb mcp proxy ──┼─ unix socket ─ ainb mcp daemon ─ 1× context7 (npx)
session C ──stdio── ainb mcp proxy ──┘ (id-rewrite mux, init cache, refcount)
```
A tool call fans in: many stdio shims, one socket, one child.
1. **A session attaches.** At session create, `ainb run` ensures the daemon is up, then rewrites the worktree's `.mcp.json` so each pooled server's entry becomes the shim (`ainb mcp proxy `). When the agent launches that "server", it's really launching the shim: a line-framed stdio↔socket bridge with exponential-backoff reconnect, so a daemon blip recovers in seconds.
2. **The daemon lazy-spawns the real server.** The first client to connect triggers the one-and-only spawn of the actual MCP command (e.g. `npx -y @upstash/context7-mcp`), in its own process group so npx/uvx grandchildren die with it. Restarts are rate-limited.
3. **The mux multiplexes every client onto that one child.** Each client's JSON-RPC request `id` is rewritten to a mux-global counter so two sessions both opening at `id:1` never collide; the mapping is stored so responses can be addressed back.
4. **Responses route to the right session.** The mux restores the original id and forwards the reply to only the owning session; progress notifications route by `progressToken`. When the last client detaches, a grace timer (`idle_grace_secs`) reaps the child.
If anything fails: daemon down, server not on PATH: the session silently falls back to spawning its own MCP, so a session never fails to start because of the pool. Host/tmux sessions only; Docker sessions keep their per-container MCP init.
## One daemon per machine: lifecycle & scaling
**Running several `ainb` windows does *not* start several daemons.** There is exactly **one daemon per user**, keyed by the control socket at `~/.agents-in-a-box/mcp/sockets/control.sock`. Every `ainb` instance: and every Codex/Copilot session wired with `ainb mcp install`: discovers and shares that one daemon, which in turn keeps one child process per server. Ten windows all using context7 = **one** `context7` process, not ten.
The singleton is enforced by two independent guards, so even a dead heat collapses to one survivor:
1. **Discover before spawn.** Before starting a daemon, `ensure_daemon()` (what `ainb run` and the overlay's import call) connects to the control socket and `ping`s it. If it answers, nothing is spawned.
2. **Exclusive bind.** If a daemon *is* spawned, it re-checks the socket and then `bind()`s it: an OS-exclusive operation. If two instances race past step 1 simultaneously, the first binds and the second's bind fails, so it logs and exits. A crashed daemon's stale socket fails the liveness `connect` and is cleaned up automatically, so a fresh start is never blocked.
Scope is **per `$HOME`**: same user → same daemon. (Sandboxes with a custom `$HOME` get their own pool: that's how the test harnesses stay isolated.)
### What it costs at rest
| Mechanism | Effect |
|---|---|
| **Lazy spawn** | At daemon start only lightweight listener tasks exist; the child process spawns on **first attach**. An idle pool is essentially free. |
| **Refcounted sharing** | N session shims → **1 child** per server. The win scales with how many sessions you run. |
| **Per-server reap** | `idle_grace_secs` (default 300) after the last client detaches, the **child** is killed but the listener stays: the next attach respawns it. |
| **Daemon self-shutdown** | `daemon_idle_grace_secs` (default 900; `0` = never) with **zero** clients anywhere, the **whole daemon** exits and removes its sockets. `ainb run` / import restart it on demand, so an unused: or orphaned: pool never lingers. |
## The hard parts the mux had to solve
A naive byte-pipe (the agent-deck approach this started from) leaks state across sessions. The ainb mux fixes the two worst cases so a shared server behaves correctly per-client.
## Gotchas worth knowing
- **Host/tmux sessions only.** Docker sessions keep their per-container MCP init: the pool doesn't touch that path.
- **The daemon reads config at *its* cwd**, so sessions in other projects push their server definitions over the control socket (`register`) rather than relying on what the daemon saw at startup.
- **Shared identity.** Env/credentials bake in at spawn and are shared by every attached session: fine for tool servers, a reason to set `shared = false` for anything per-user-authenticated.
- **Failure never blocks a session.** Daemon down, server not on PATH, socket gone: the session silently falls back to spawning its own MCP, exactly like today.
## Commands
| Command | What it does |
|---------|--------------|
| `ainb mcp daemon` | Run the pool daemon in the foreground (auto-spawned detached by `ainb run`) |
| `ainb mcp status` | Per-server JSON: client count, shared child pid, state |
| `ainb mcp stop` | Stop the daemon and its pooled children |
| `ainb mcp import [--user]` | Import stdio servers from `.mcp.json` / Claude user scope into config |
| `ainb mcp install --codex --copilot` | Point other agent CLIs at the pool shim |
| `ainb mcp proxy ` | The stdio↔socket shim (used inside generated `.mcp.json`; you won't call it directly) |
## FAQ
Does it work for any MCP, or just npm/npx?
Any **stdio** server: npx, uvx, bun, a compiled binary, `docker run -i`. The mux speaks newline-delimited JSON-RPC over the child's stdio, which is identical regardless of runtime. Remote `http`/`sse` servers aren't pooled (there's no local process to share).
What stops two sessions' requests from colliding?
The mux rewrites every request id to a global counter and remembers which session owned the original id, so responses and progress route back to exactly one session. Claude Code always starts ids at 1: that's the collision this prevents.
How was "one process" actually proven?
Two ways. The committed GIF drives real context7 with two shim attaches and reads `child_pid` + the process group. And `scripts/validate-mcp-pool.sh 3` spins up three real ainb Claude sessions and asserts one backend, three shims, a working tool call from every session, kill-one-survives resilience, and post-grace reaping: 11/11 green.
What happens when a pooled server crashes mid-call?
The daemon reaps the zombie and drops the clients; their shims reconnect with backoff while the health loop respawns the child (rate-limited). In-flight requests are lost and the agent retries: the same contract a per-session server gives you.
## Verify it yourself
The compact GIF at the top is recorded from a reproducible demo that uses **real** context7:
```bash
cargo build --release
AINB_BIN=ainb-tui/target/release/ainb scripts/mcp-pool-demo.sh
```
A heavier end-to-end check spins up three real ainb Claude sessions and asserts one backend process, three shim attachments, a working tool call from every session, kill-one-survives resilience, and post-grace reaping:
```bash
scripts/validate-mcp-pool.sh 3
```
## See also
- [CLI reference](/tui/cli)
- [Overview](/tui/overview)