# Gemma 3 MoE builder
**Turn a dense [Gemma-3-270m](https://huggingface.co/google/gemma-3-270m) into a Mixture-of-Experts
(MoE) model — and serve it on CPU with `llama.cpp`.**

`gemma3moe-builder` is a small, dependency-light toolkit that **sparse-upcycles** a dense Gemma-3-270m
into a routed MoE (`gemma3moe`: a linear router + N `Gemma3MLP` experts, top-k with renormalized
weights), lets you continue-train / fine-tune it, and ships the patches to **run it on `llama.cpp` in
CPU** at high throughput. MoE gives you far more parameters (capacity) while keeping the **active**
compute — and therefore CPU speed — close to the original 270m.
- 🧩 **Upcycle** any gemma-3-270m checkpoint (trimmed or full vocab) into N experts, top-k.
- 🌱 **Diverse init** (Branch-Train-miX style): seed experts from different gemma-3-270m variants.
- 🏋️ **Train** with a plain 🤗 Transformers `Trainer` (+ optional load-balance / z-loss).
- 🔎 **Inspect** routing: load balance, dead experts, entropy, per-task specialization.
- ⚡ **Serve on CPU** via `llama.cpp` (custom `gemma3moe` arch, GGUF, all K-quants).
> The FFN is **vocabulary-independent**, so experts can be seeded from *any* gemma-3-270m-derived model
> without matching tokenizers — which is what makes diverse initialization cheap.
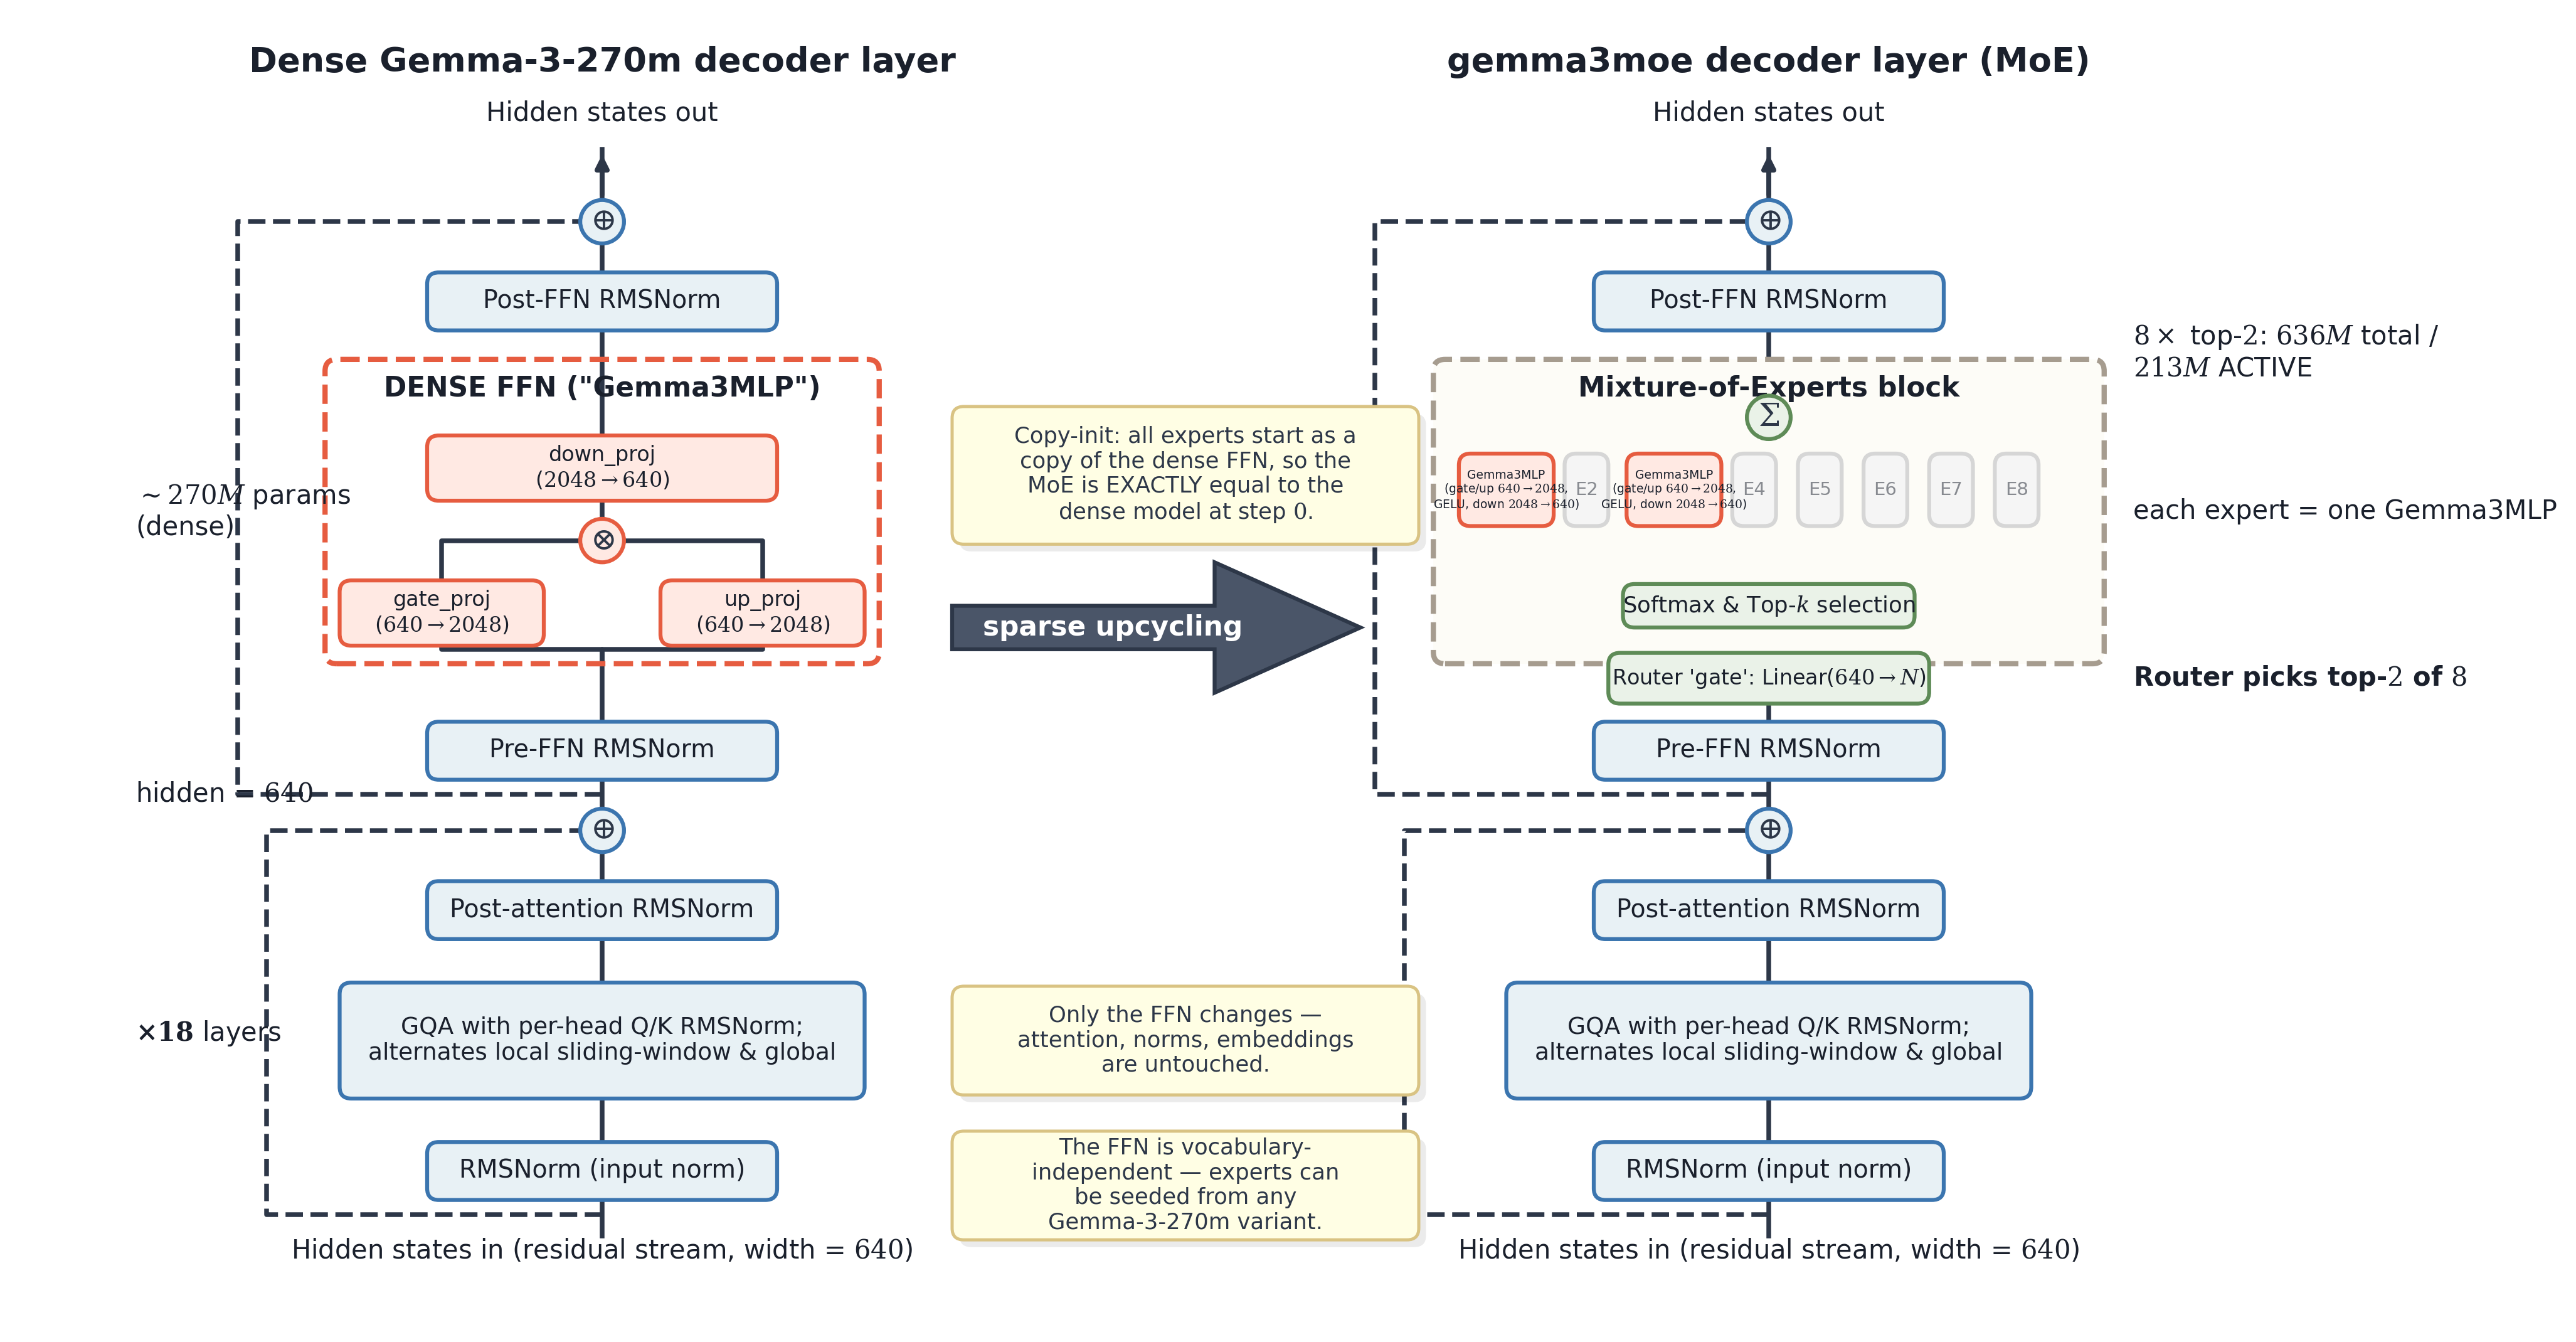
One decoder layer, before and after: only the dense FFN becomes a router + N experts (top-k). Copy-init keeps the MoE exactly equal to the dense model at step 0.
## Why MoE on a 270m?
Active params (not total) drive CPU latency. Upcycling multiplies capacity while keeping a small active
path:
| Vocab | Experts | Total params | Active (top-1 / top-2 / top-4) |
|---|---|---|---|
| full (262k) | **16** | **~1.33B** | 269M / 339M / **481M** |
| full (262k) | 8 | ~764M | 269M / 339M / 481M |
| trimmed (64k) | 8 | ~637M | 142M / 213M / 354M |
| trimmed (64k) | 16 | ~1.20B | 142M / 213M / 354M |
A trimmed **8×top-2** build (~213M active) runs at **~90–210 tok/s on Apple-Silicon CPU/Metal** and
quantizes down to **~460 MB** (Q4_K_M) — a genuinely useful model on commodity hardware.
## Install
```bash
pip install -e . # installs the `gemma3moe` package + its console commands
# training + routing tools also need `datasets`:
pip install -e .[train]
```
Each command below is available both as `python -m gemma3moe.` and as a console
entry-point (`gemma3moe-upcycle`, `gemma3moe-check`, `gemma3moe-train`, …).
## Quickstart
### 1. Upcycle (copy-init: MoE ≡ dense at start)
```bash
python -m gemma3moe.upcycle \
--src google/gemma-3-270m \
--out ./my-moe \
--num-experts 8 --top-k 2
```
Or **diverse init** — seed each expert from a different source (base / instruct / a fine-tune / a distill):
```bash
python -m gemma3moe.upcycle_multisource \
--src google/gemma-3-270m \
--out ./my-moe \
--num-experts 8 --top-k 2 \
--sources "google/gemma-3-270m:4,google/gemma-3-270m-it:4"
```
### 2. Sanity-check correctness
With copy-init, the MoE forward must equal the dense forward (byte/tolerance):
```bash
python -m gemma3moe.correctness_test --dense google/gemma-3-270m --moe ./my-moe
# or, with no downloads (in-memory tiny models, CI-friendly):
python -m gemma3moe.correctness_test --tiny
```
### 3. Train / fine-tune (optional)
```bash
python -m gemma3moe.train --init ./my-moe --train train.jsonl --val val.jsonl \
--out ./my-moe-sft --epochs 3 --aux-coef 0.003
```
### 4. Inspect routing
```bash
python -m gemma3moe.eval.router_health --ckpt ./my-moe-sft --val val.jsonl # load balance, dead experts
python -m gemma3moe.eval.router_diversity --ckpt ./my-moe-sft --prompts prompts.txt # specialization vs dense-like
```
### 5. Serve on CPU (llama.cpp)
See **[`llamacpp/README.md`](llamacpp/README.md)** — patch a fresh llama.cpp, build, convert to GGUF,
quantize, run. `k` (active experts) is baked into the GGUF via `expert_used_count`.
## Benchmarking
Active params — `shared + k × per-expert-FFN` — drive CPU latency, so throughput and memory scale
with `k`, not with the total parameter count. [`bench/benchmark.py`](bench/benchmark.py) measures
**tok/s and peak RAM** on a built llama.cpp, sweeping `k` by overriding `expert_used_count` at load
time (the same file, different active path):
```bash
python bench/benchmark.py \
--bin /path/to/llama.cpp/build/bin \
--gguf model-Q4_K_M.gguf --quant Q4_K_M \
--k 1 2 4
```
It wraps `llama-bench` (default) or `llama-cli` and prints a `quant / k → tok/s / peak RAM (MB)`
table. It only needs the Python standard library and a llama.cpp binary you have already built — it
downloads and compiles nothing, and is **not** part of the test suite / CI.
## Vocabulary trimming (optional)
Trimming the 262k vocabulary to a language-focused subset shrinks the embedding/lm_head (the largest
tensors) and speeds up CPU inference — but it is **entirely optional**; `gemma3moe-builder` works on the
full-vocab model as-is. If you do trim, use a dedicated trimmer (e.g.
[`embedding-vocab-trimmer`](https://github.com/tardellirs/embedding-vocab-trimmer)) to produce a faithful BPE, then apply the small extra converter patch
described in [`llamacpp/README.md`](llamacpp/README.md#trimmed-vocab-models-optional). The MoE builder
itself never needs a trimmed model.
## Ready-made starter checkpoint
A **16-experts / top-4, full-vocab, untrained** upcycle is published as a drop-in starting point for
your own training/fine-tuning (no need to run the upcycle yourself):
**➡️ [`tardellirs/gemma3moe-16x4-270m-starter`](https://huggingface.co/tardellirs/gemma3moe-16x4-270m-starter)** — ~1.33B total / ~481M active. Load with
`trust_remote_code=True`, then train.
Build your own with [`examples/build_16x4_starter.sh`](examples/build_16x4_starter.sh).
## Repository layout
```
gemma3moe/ # installable Python package
modeling_gemma3_moe.py # the gemma3moe Transformers architecture (router + N experts, top-k)
_registry.py # register the arch + load checkpoints (shared helper)
upcycle.py # copy-init upcycle (MoE ≡ dense at start)
upcycle_multisource.py # diverse Branch-Train-miX init
train.py # plain Trainer SFT (+ aux load-balance / z-loss)
correctness_test.py # MoE-forward == dense-forward check
eval/
router_health.py # load balance / dead experts
router_diversity.py # entropy, expert cos-sim, per-task input-dependence
tests/ # CPU-only, no-download pytest suite
llamacpp/
README.md # build + convert + run guide
gemma3moe.cpp # the llama.cpp graph (Gemma-3 + build_moe_ffn)
patch_convert.py # converter (Python) patch
patch_cpp.py # runtime (C++) patch
patch_trimmed_vocab.py # optional: trimmed-vocab converter fixes
bench/
benchmark.py # tok/s + peak RAM on llama.cpp, swept over k (active experts)
examples/
build_16x4_starter.sh # reproduce the starter checkpoint
docs/
NOTES.md # practical MoE lessons (init, aux loss, scaling N, specialization)
pyproject.toml # packaging, dependencies, console entry-points
```
## How it works
`gemma3moe` keeps the entire Gemma-3 stack and replaces each layer's dense `Gemma3MLP` with a
`Gemma3MoeMLP`: a linear router (`gate`) selects the top-k of N experts (each a full `Gemma3MLP`),
softmax-weights them, and renormalizes. **Copy-init** (all experts = the dense FFN) makes the MoE
*exactly* equal to the dense model at step 0, so training only has to differentiate the experts — a
stable, well-behaved starting point (this equivalence is asserted in both the Python and C++ paths).
## License
Code: Apache-2.0. Model weights derive from Gemma-3 and are subject to the
[Gemma Terms of Use](https://ai.google.dev/gemma/terms).
## Citation
```bibtex
@software{gemma3moe_builder,
title = {gemma3moe-builder: sparse-upcycling Gemma-3 into a CPU-served Mixture-of-Experts},
year = {2026},
url = {https://github.com/tardellirs/gemma3moe-builder}
}
```