[English](README.md) | [简体中文](README.zh.md)
# dsh-files
A DeepSeek Harness plugin that does exactly one thing: the **`read_document` tool** — structured text extraction for binary documents (PDF / DOCX / XLSX) plus enhanced text reading (encoding fallback, paging, sheet-level access) that the built-in read tool rejects.
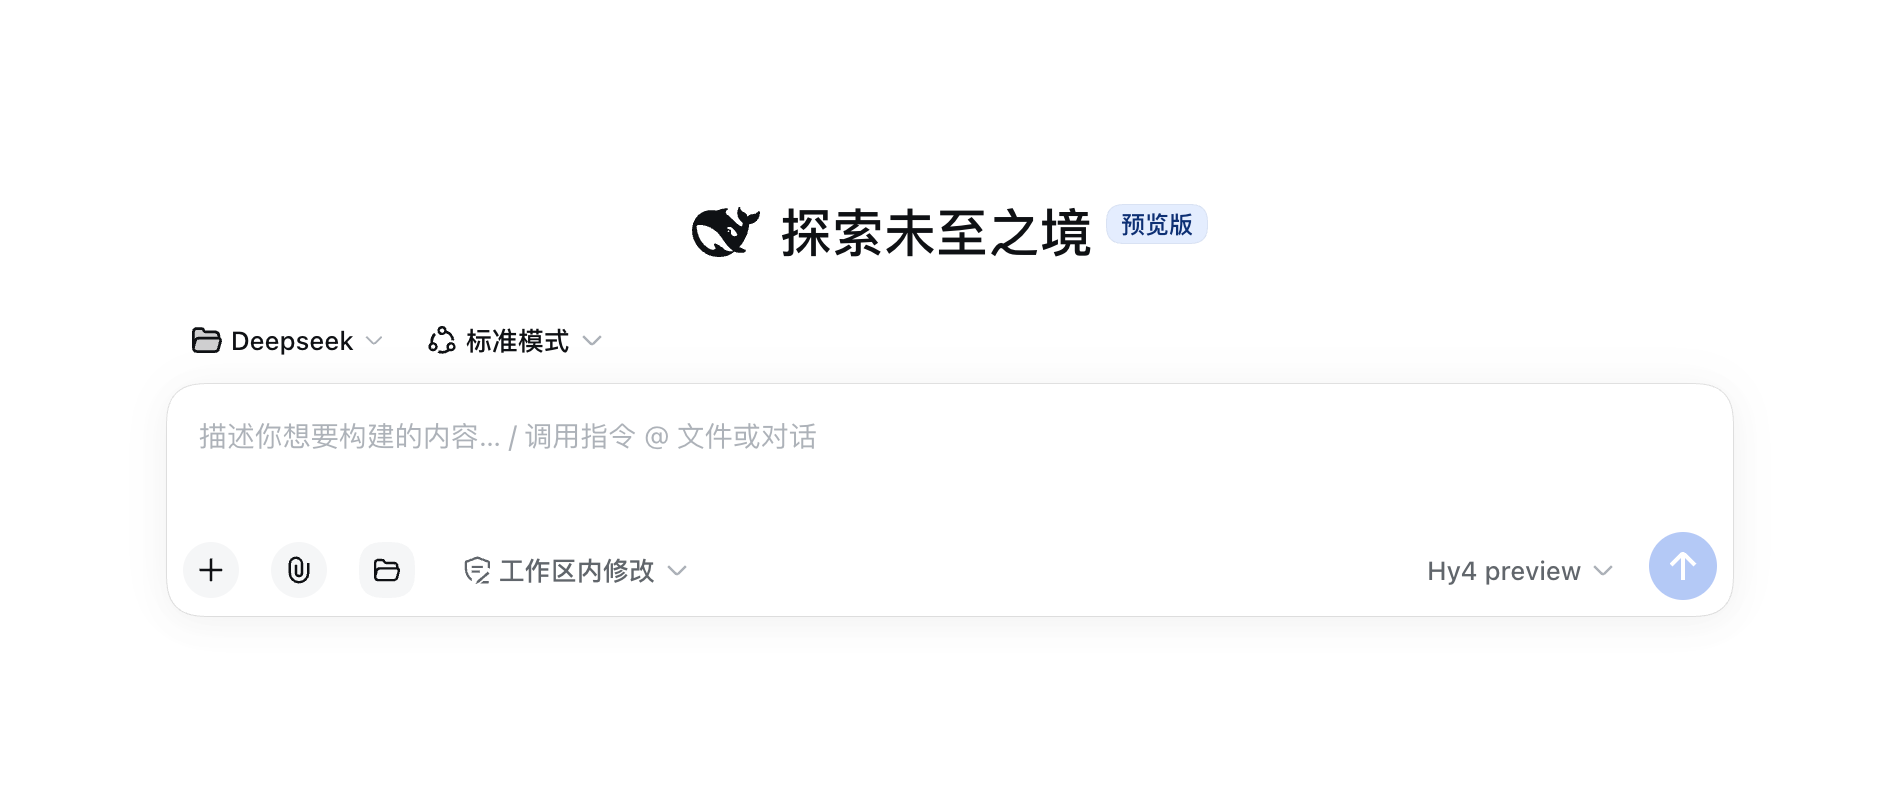
> Upload, images and `@` reference were removed in 0.5.0 — harness 0.1.3 ships them natively (universal file upload, the image vision pipeline, unified `@file`/`@session` reference), and does it better. This plugin is part of the [taxueseek plugin matrix](https://github.com/taxueseek#deepseek-harness-%E6%8F%92%E4%BB%B6); the flagship is [argo](https://github.com/taxueseek/argo).
## Why it exists
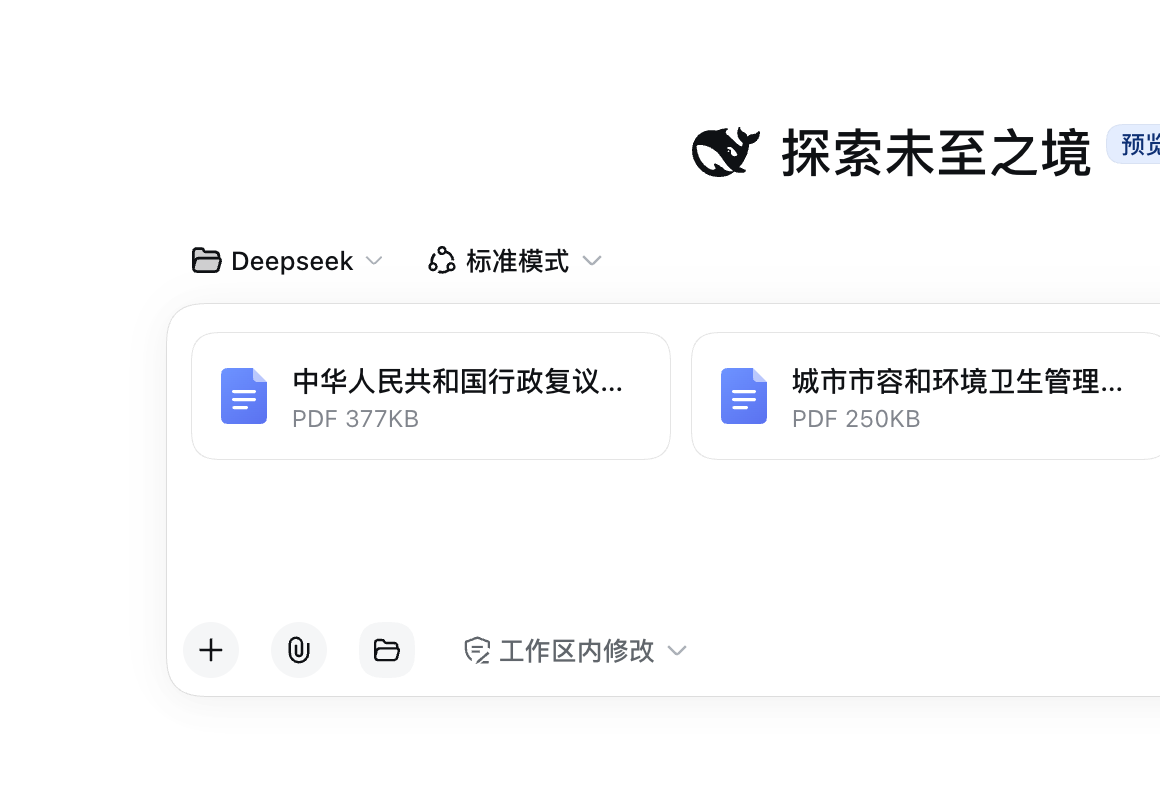
Native upload in harness 0.1.3 stores files as byte objects and hands the model one handle line (name, size, digest, read-only path) to read with **file tools** — but the built-in read tool rejects binary content with `FS_NOT_TEXT`. Structured text extraction for PDF / DOCX / XLSX is the gap the official stack leaves open; this plugin fills it.
## Capabilities
- **Content sniffing**: PDF header / ZIP central-directory members / UTF-8 (fatal) / UTF-16 BOM / GB18030 — decided from bytes, never from extensions; disguised files (an exe renamed .pdf) are rejected. The format hint is only a last resort when bytes are fully unknown
- **Encoding chain**: UTF-16 BOM → UTF-8 (fatal, NUL rejected) → GB18030 (fatal) → UTF-16 without BOM (high-confidence guard); GBK Chinese and BOM-less UTF-16 both read
- **Paged reads**: line numbers + offset/limit; the per-call character budget differs by format (text full, xlsx 3/4, pdf/docx 1/2), overflow truncates with an explicit remaining-lines marker
- **Line-number policy**: text (code/config) carries line numbers for precise edits; PDF/DOCX/XLSX are paragraph flows without line numbers (saves tokens)
- **XLSX sheet-level reads**: `list_sheets` names the sheets, the `sheet` parameter reads one sheet in full (no row cap), out-of-range errors list the available sheets
- **Scanned PDFs are explicit**: a PDF with no text layer returns an explicit notice, not an empty string
- **Cooperative cancellation**: parsing listens on the execution signal; user cancel / session close aborts immediately
- **Output projection**: text results project onto the official `card: 'read'` file card; reads go through `ctx.fs` and inherit session sandbox and fs-observation policy
- **Reading restraint**: the systemPrompt section instructs "probe structure first, read precisely, stop when you have enough"
## Install
Requires harness ≥ 0.1.3-alpha.1.
```sh
curl -fsSL https://raw.githubusercontent.com/taxueseek/dsh-files/main/install.sh | sh
# restart dsh web
```
Manual equivalent:
```sh
dsh plugin --profile web add git+https://github.com/taxueseek/dsh-files.git
# restart dsh web
```
> The npm package named `dsh-files` is an unrelated third-party placeholder — install only via the script or the git command above.
## Configuration
```yaml
- id: files-toolkit
name: 'dsh-files'
config:
maxFileBytes: 25165824 # byte cap for one document read
readLimit: 2000 # lines returned per call (paging is cheap)
sheetRowLimit: 200 # rows kept per worksheet
maxSheets: 5 # sheets read per workbook
maxOutputChars: 24000 # per-call window character budget (truncated with a marker)
readTimeoutMs: 120000 # per-call timeout (raise for huge PDFs)
```
## Security
- Parsing dependencies are read-only and maintained: `pdfjs-dist` (Mozilla), `mammoth`, `read-excel-file`
- ZIP central-directory probing never expands members; malicious archives are rejected safely
- Reads go through `ctx.fs`, inheriting the session sandbox, same rights as the built-in read tool
## Development
```sh
pnpm install
pnpm test
pnpm build
npx tsc --noEmit
```
## License
MIT