Most software has the memory of a goldfish. This one doesn’t.


# memkeeper
Local-first memory for AI agents. A fast, embeddable memory engine that stores,
ranks, and retrieves an agent's durable context, entirely on your machine, with
no required network or LLM calls.
> Memkeeper is the open-source, local-first control plane that AI agents run on: durable memory, project context, coordinated task handoffs, and deny-by-default permissions, all deterministic and on your own machine. *This repo is the memory engine at its core.*
> ℹ️ **Generated release mirror.** This repo is generated from a private
> development repo and published as releases. The `main` branch may be
> regenerated, so **pin to tagged releases** (or the release artifacts) rather
> than to arbitrary `main` commits — tagged releases are stable. See
> [CONTRIBUTING.md](CONTRIBUTING.md) for how to contribute; issues, security
> reports, and design feedback are the best paths today.
- **Local-first.** A single SQLite database. No server, no cloud, no telemetry.
- **Fast at prompt time.** Deterministic BM25/FTS retrieval with optional ONNX
semantic embeddings and a cross-encoder reranker.
- **Durable by design.** Atomic writes, schema-versioned storage, and a
retention model that promotes recurring, high-signal memories to a durable tier.
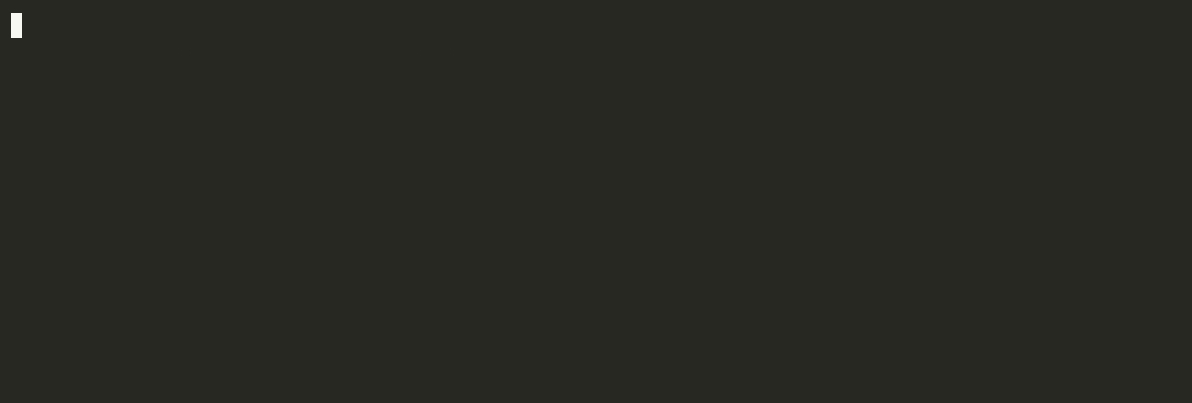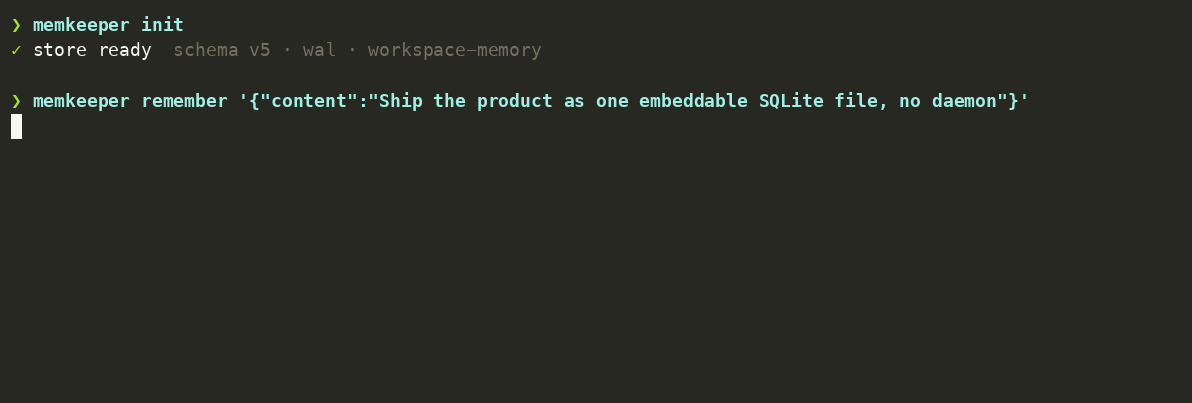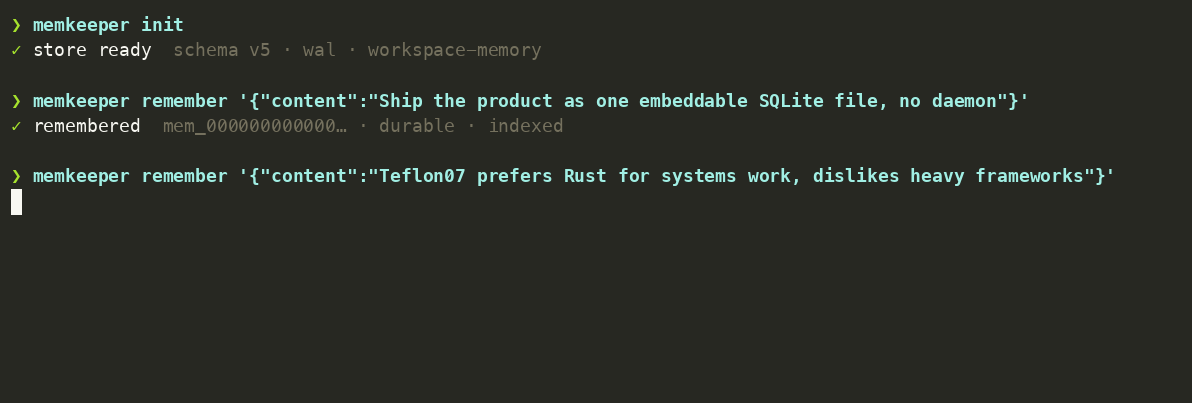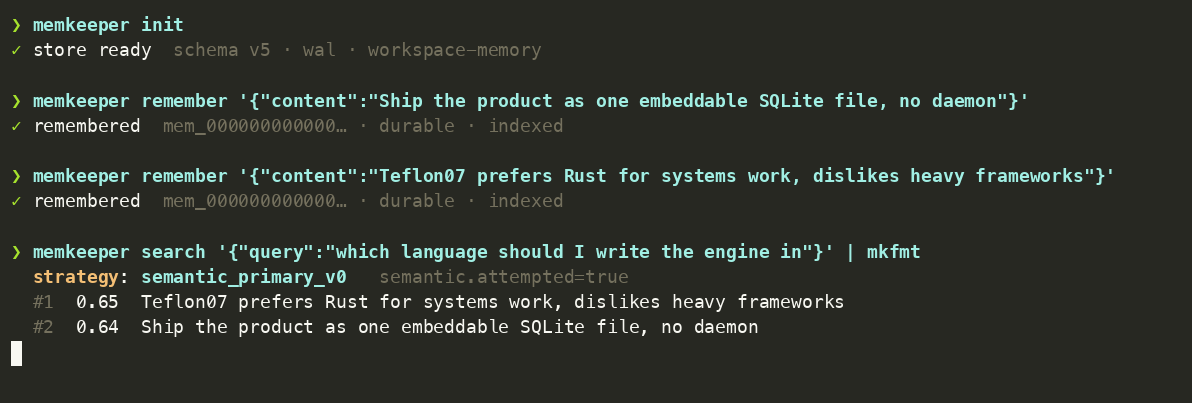
Real CLI output, formatted for readability via scripts/mkfmt. The search query shares no keywords with the memory it surfaces.
> Status: pre-release (v0.5.3). APIs and the wire protocol may change before 1.0.
## Quickstart
```sh
# Install the latest release binary (macOS arm64 / Linux x86_64) to ~/.local/bin.
# It's self-contained — nothing else to install.
curl -fsSL https://raw.githubusercontent.com/teflon07/memkeeper/main/install.sh | bash
# Optional, one-time: fetch on-device semantic models. Lexical search works without it.
memkeeper pull-models
# Create a store, remember something, search it back.
memkeeper init
memkeeper remember --json '{"content":"memkeeper stores memories in a local SQLite database"}'
memkeeper search --json '{"query":"where are memories stored","limit":3}'
```
That's the whole install: a self-contained binary, no runtime network/LLM/API key.
Prefer not to pipe a script to your shell? Grab a binary from the
[releases page](https://github.com/teflon07/memkeeper/releases) and verify its
`.sha256`, or [build from source](#build-from-source). The store defaults to
`~/.memkeeper/store.sqlite` when `--store` is omitted; a `--json` value can also be
`@` or `-` (stdin) instead of an inline string, which avoids shell-quoting
pitfalls (handy in Windows PowerShell).
## Upgrade from v0.2.x
v0.3.0 introduced the schema 5 to schema 6 upgrade; v0.4.0 through v0.5.3 keep
schema 6 unchanged. The migration is transactional, but schema 6 stores cannot
be opened by v0.2.x. Stop any long-running `memkeeper` process and keep a
schema 5 backup until you verify the upgrade.
Back up the store with your v0.2.x binary before installing the current release:
```sh
STORE=~/.memkeeper/store.sqlite
memkeeper backup --store "$STORE" --output "$STORE.schema5.bak" --json
```
Install the current release, run the migration explicitly, and verify the result
before restarting any long-running process:
```sh
curl -fsSL https://raw.githubusercontent.com/teflon07/memkeeper/main/install.sh | bash
memkeeper init --store "$STORE" --json
memkeeper doctor --store "$STORE" --json
```
`init` is safe to rerun. If you need to roll back, restore the schema 5 backup
before starting the older binary.
## Use it from your agent (MCP)
memkeeper speaks MCP (JSON-RPC 2.0 over stdio), so any MCP client —
Claude Code, Cursor, and others — can read and write memory during a session. Point
your client's MCP config at the **native binary** (no Python, no extra deps):
```json
{ "mcpServers": { "memkeeper": { "command": "memkeeper", "args": ["mcp"] } } }
```
The agent calls `remember` to capture a durable fact and `search` to recall it later,
across separate sessions, with the same retrieval as the CLI.
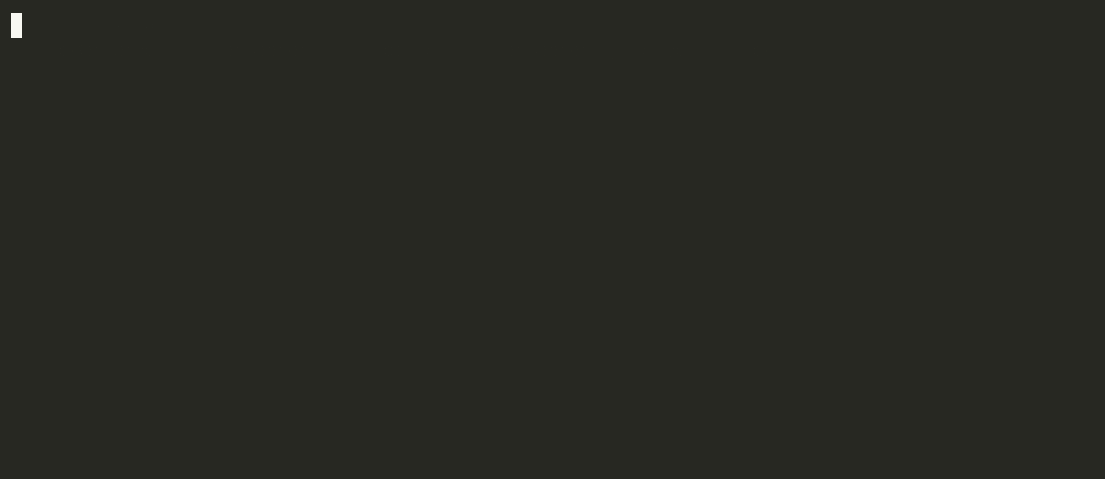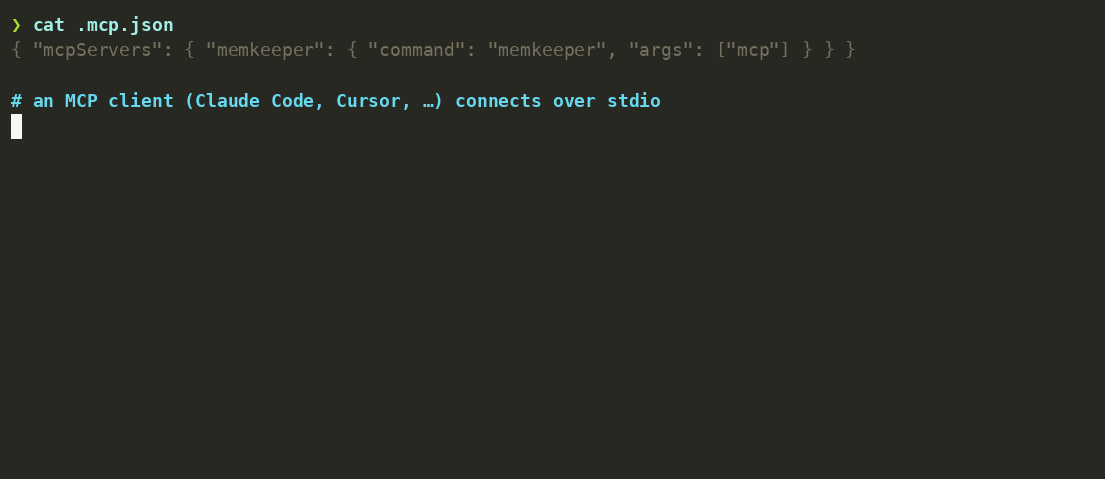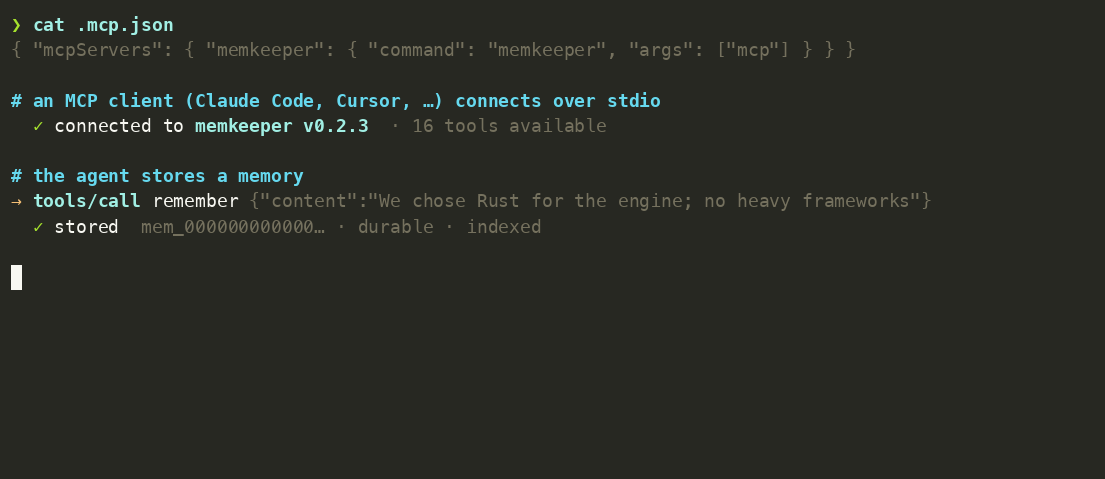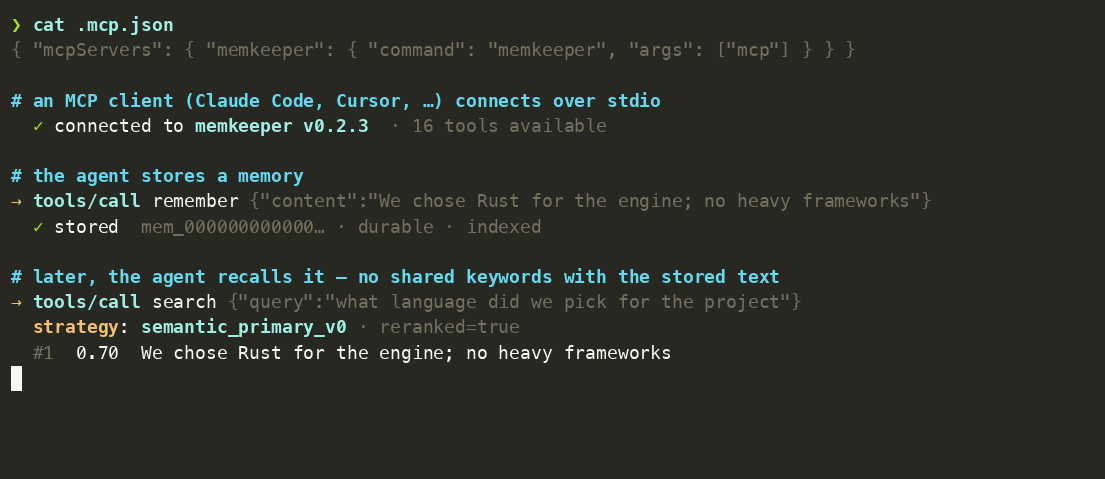
Real memkeeper mcp JSON-RPC round-trips, formatted for readability via scripts/mcpfmt.
## What to store
memkeeper holds **self-contained memories**: facts, decisions, preferences,
lessons. Each `remember` is one memory written to stand on its own, with its
context and intent intact (store "the user likes pineapple on pizza," not just
"pineapple"). Atomic means one idea per memory, not a stripped keyword.
Retrieval, dedup, supersession, and the entity graph all work best at that grain.
Two ends to avoid:
- **Too small:** a bare keyword or fragment that drops the point.
- **Too large:** a whole document. The curated memory tier has no chunking, and
the embedder sees only the first ~512 tokens of an entry, so loading long files
(for example, an entire markdown library) gives weak semantic recall on those
entries (lexical BM25 still indexes the full text). To bring whole documents in,
don't store them as memories — use the [document store](#document-store-rag),
memkeeper's separate RAG tier that chunks and embeds files into an isolated
space (the [`memkeeper-ingest`](https://github.com/teflon07/memkeeper-ingest)
add-on imports whole folders this way). Or distill the document down to its
takeaways and store those as memories.
## Capturing memories
memkeeper is **curated** memory you populate deliberately — not an automatic
transcript logger. Memories get in two ways:
- **Directly** — `memkeeper remember --json '{"content":"…"}'`, from the CLI or a
script.
- **From an agent** — the native [MCP server](#use-it-from-your-agent-mcp) lets an MCP
client (Claude and other agents) call `remember` during a session, so durable facts
are captured as they come up. When a confirmed memory names entities or states a
relationship, the MCP tool asks the agent to include a bounded graph projection
in the same call. memkeeper validates and commits the memory, exact aliases, and
typed relationships atomically. The one memory ID is the relationship evidence.
memkeeper does not run a second LLM or background extractor for this. The MCP host
agent supplies the structured graph fields while making the normal `remember`
call. Raw CLI callers can supply the same `graph` object explicitly.
On the *retrieval* side, `memkeeper hook retrieve` is a Claude Code
UserPromptSubmit hook client that injects relevant memories into the prompt — so an
agent recalls without an explicit search. It retrieves; capture stays a deliberate
`remember`.
## Semantic retrieval (default)
memkeeper has three retrieval modes. **Local semantic is the default and the
recommended, fully on-device mode.** Pick one up front — the embedding backend is
recorded in the store, so changing it means re-embedding (`reindex --embed`), not a
flip.
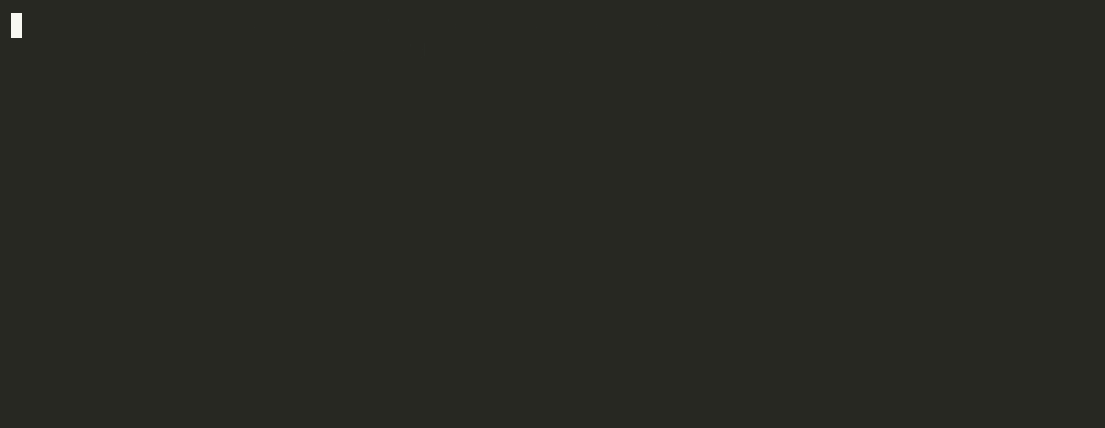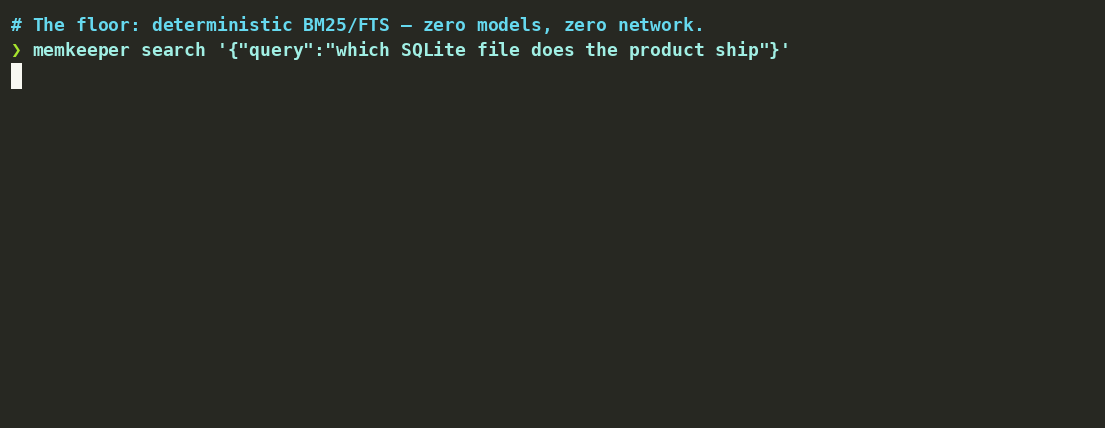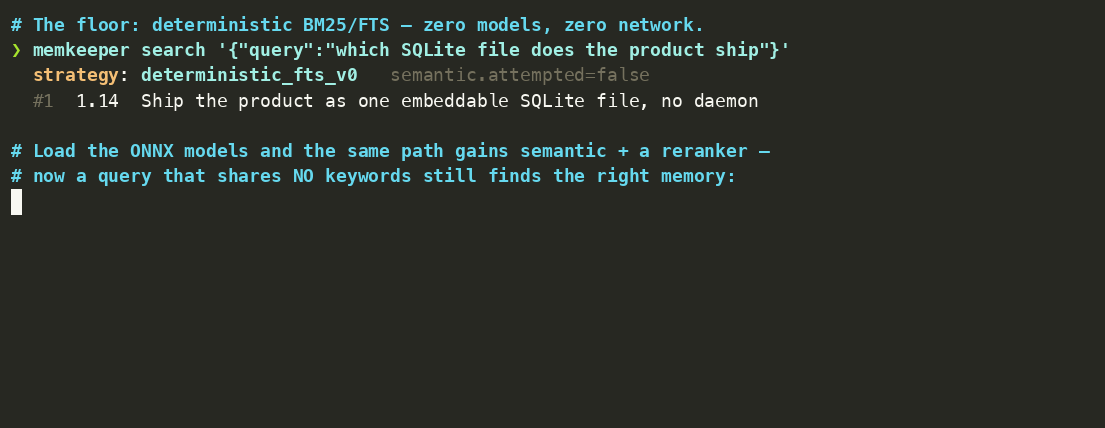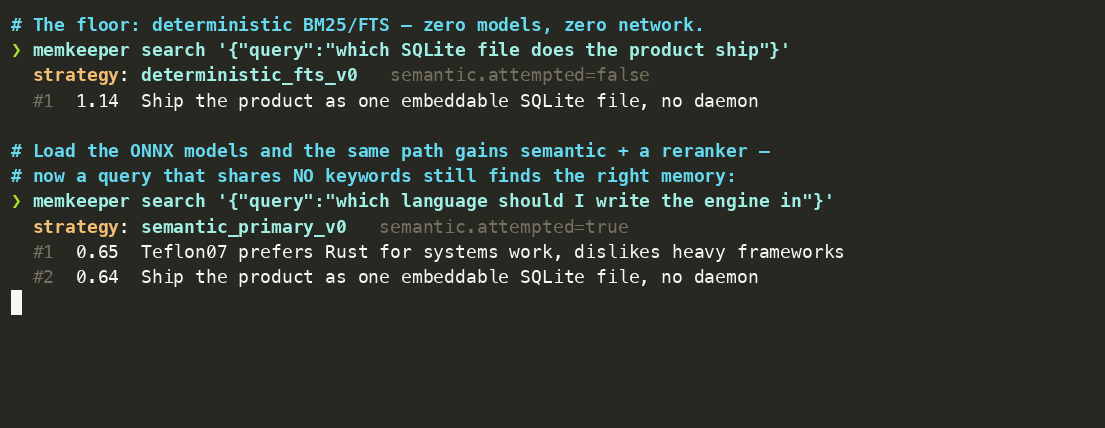
The deterministic floor (zero models, zero network) and semantic + rerank on top — same store, same query path. Real output via scripts/mkfmt.
| Mode | Network | Setup |
|---|---|---|
| **Local semantic** (default) | none | install binary, then `pull-models` |
| **Lexical only** | none | works out of the box; just skip `pull-models` |
| **Off-device semantic** | embeds via an API | set `MEMKEEPER_EMBED_PROVIDER=openai` + base URL + key |
> **Privacy:** off-device semantic sends your memory **text** to the embeddings
> provider to be vectorized. Use it only where that is acceptable; the two on-device
> modes never send memory content anywhere.
### Local semantic (default)
The release binary ships semantic-capable (the ONNX runtime is statically
bundled), so there's no rebuild — it just needs the embed + rerank models, which
aren't downloaded automatically. Fetch them once:
```sh
# Needs curl; ~2.1GB, or --quantized for ~0.6GB (slightly lower recall).
memkeeper pull-models
```
`pull-models` writes to `~/.memkeeper/models/` (override with `MEMKEEPER_MODELS_DIR`
or `--dir`) — exactly where memkeeper looks by default. So semantic turns on with
**no env vars to set**: run a `search` afterward and it's active.
If the models are missing, memkeeper does not degrade *silently*: it logs their
absence and points you at `pull-models`, marks results semantic-unavailable
(e.g. `"semantic":{"attempted":false,"reason":"missing_embedding"}`), and **falls
back to lexical (BM25/FTS)** so search keeps working. Set
`MEMKEEPER_REQUIRE_SEMANTIC=1` to **fail closed** instead — refuse the request
rather than serve degraded results — in any deployment that must never silently
run lexical-only.
Embeddings are computed when a memory is **written**. Memories you stored before
the models were present (for example, the one from the Quickstart above) are
lexical-only until embedded. Backfill existing memories once with:
```sh
memkeeper reindex --embed
```
New memories written with the models in place are embedded automatically.
### Lexical only
Skip `pull-models` and the release binary runs deterministic, model-free
**lexical-only** (BM25/FTS) retrieval — zero network, zero models. Building from
source with `--no-default-features` produces a leaner binary that omits the ONNX
runtime entirely (see [Build from source](#build-from-source)).
### Off-device semantic (no model download)
Prefer not to download the ONNX models? Point memkeeper at an OpenAI-compatible
embeddings API (OpenAI, OpenRouter, or any compatible proxy) instead. This mode
embeds and reranks over the network rather than loading the local models, so it
needs no `pull-models`:
```sh
# Embeddings (required for semantic): any OpenAI-compatible /embeddings endpoint.
export MEMKEEPER_EMBED_PROVIDER=openai # "openai" = the OpenAI-compatible API dialect
export MEMKEEPER_EMBED_BASE_URL=https://api.openai.com/v1/embeddings # or your provider, e.g. OpenRouter
export MEMKEEPER_EMBED_API_KEY=sk-...
export MEMKEEPER_EMBED_MODEL=text-embedding-3-small
export MEMKEEPER_EMBED_DIMS=1536
# Reranking (optional, recommended): Cohere /rerank dialect, which OpenRouter speaks.
export MEMKEEPER_RERANK_PROVIDER=openrouter
export MEMKEEPER_RERANK_API_KEY=sk-...
export MEMKEEPER_RERANK_MODEL=cohere/rerank-v3.5
```
The **prebuilt release binaries support all three modes** (`--features semantic,api`):
run `pull-models` for fully on-device local semantic (the default and recommended
mode), configure an API key for off-device semantic, or configure neither and they
serve lexical (BM25/FTS). `MEMKEEPER_REQUIRE_SEMANTIC=1` makes them refuse rather
than serve degraded.
Prebuilt binaries are published for **macOS (Apple Silicon)** and **Linux x86_64**.
**Windows is experimental** — there's no prebuilt binary, but it builds and runs
from source; see [docs/windows.md](docs/windows.md). (`serve --socket` is Unix-only
there; the http dashboard and stdio serve are cross-platform.)
### How `pack` combines semantic and graph retrieval
`pack` uses one retrieval path. Semantic and lexical matches supply memory
seeds, exact entity and alias matches supply graph seeds, and bounded
evidence-backed graph traversal joins both sets on canonical memory IDs. Every
candidate then competes in the same cross-encoder rerank pool. Graph candidates
receive no reserved slots or automatic demotion, and there is no production
graph on/off mode. A store with no eligible graph route simply returns the
semantic and lexical pool unchanged.
### Switching the embedding model
The embedding backend is recorded per store, and memkeeper refuses to mix vectors
from different models (they live in different vector spaces). To switch — local↔
off-device, or between models — change the embedding env vars, then re-embed every
memory under the new model in one step:
```sh
./target/release/memkeeper reindex --embed --store ~/.memkeeper/store.sqlite
```
This wipes the old vectors, records the new active model, and re-embeds all active
memories in one transaction. It is the supported way to change models; there is no
partial mix.
## Document store (RAG)
Alongside curated memories, memkeeper can hold a separate tier of ingested
document chunks for retrieval-augmented use. Chunks live in their own space
(default `documents`), isolated from the curated memory tier, so they never
receive supersession, dedup, graph, or promotion treatment.
- `ingest` — store a document source as embedded, isolated chunks. Re-ingesting
the same `source_path` repairs that chunk's provenance in place; identical
content under a different path is kept as an independent chunk.
- `document-search` — hybrid (BM25 + vector) search over the chunks, with a
citation back to `source_path` and chunk index.
- `document-get` — fetch a document's chunks by path, or one chunk by id.
- `document-duplicates` — surface exact-content duplicate chunks (the same
content held under different sources) as clusters. `stats` also reports a
`document_duplicate_clusters` count so you know when there are duplicates worth
reviewing.
- `document-prune` — delete the specific chunks you choose (supports `dry_run`).
Deletion is always explicit: review duplicates, decide which copies to keep,
then prune the rest.
- `promotion-candidates` / `mark-extracted` — rank chunks that earned retrieval
traffic, and mark a chunk extracted once it has been promoted into a memory.
Run `memkeeper schema ` for each command's accepted JSON fields. Over
`serve --http`, reads (search/get/duplicates) are available on the read-only
dashboard. Writes (`ingest`, `document-prune`) are disabled unless you set a
write token: start the server with `MEMKEEPER_HTTP_WRITE_TOKEN=` in the
environment, then send it on write requests as `Authorization: Bearer `.
With no token set, the HTTP server is read-only.
## The dashboard
`memkeeper serve --http` starts a read-only local dashboard (default
`http://127.0.0.1:7777`) for browsing memories and the entity graph. Point it at a
store with `--store ` (or `MEMKEEPER_STORE`); it uses the default store
otherwise.
**A fresh store starts empty — that's expected.** Two views, populated
differently:
- The **memory list** fills as you `remember`.
- The **graph** visualizes *entities and relationships*, which are a separate layer
from raw memories. Native MCP `remember` captures bounded entities, aliases, and
typed relationships with a confirmed memory when the host agent supplies them.
Raw CLI callers can pass the same graph structure, or curate it with
`entity-upsert` / `relationship-upsert`. The `dream graph` task may add generic
`related_to` links for visualization, but those links are not retrieval
evidence. Plain memories without graph fields still fill the list without
adding graph edges.
## Benchmarks
On [LoCoMo](https://github.com/snap-research/locomo) (10 multi-session dialogues,
1,982 evidence-bearing questions), memkeeper's default semantic retrieval scores:
| Metric | Score |
|---|---|
| recall@20 | 0.768 |
| hit@20 | 0.880 |
| MRR | 0.668 |
Prompt-time search on a warm `serve` daemon (ONNX models loaded once) runs in
**~25 ms** p50/p95, about 32× faster than a cold per-call binary that reloads the
models on every query.
Full methodology, per-config results (including the late-interaction upgrade), and
a reproduction script are in [docs/benchmarks.md](docs/benchmarks.md).
## Build from source
Building is optional — the [Quickstart](#quickstart) binary is self-contained.
Build from source to track the latest `main`, produce a leaner lexical-only binary,
or develop.
**Prerequisites:** a **Rust toolchain** (stable, via [rustup](https://rustup.rs);
edition 2021, Rust 1.56+) and a **C toolchain** for the native deps (bundled SQLite
plus the ONNX runtime for semantic search). macOS: Xcode Command Line Tools
(`xcode-select --install`); Debian/Ubuntu: `build-essential`. Building fetches
crates from crates.io the first time; after that a clean build is offline.
```sh
# Semantic build (default): local embeddings + cross-encoder rerank.
cargo build --release
# ...or lexical-only — omits the ONNX runtime and models entirely:
cargo build --release --no-default-features
# The binary lands at ./target/release/memkeeper (not on PATH). To install it:
cargo install --path crates/memkeeper-cli # then a bare `memkeeper` works
```
Then `memkeeper pull-models` to enable semantic, exactly as in the Quickstart.
## Workspace layout
| Crate | Role |
|---|---|
| `memkeeper-core` | Core types and retrieval policy |
| `memkeeper-store` | SQLite storage, schema, indexing, promotion |
| `memkeeper-embed` | ONNX embeddings + cross-encoder reranker |
| `memkeeper-protocol` | Wire protocol (`memkeeper.v0.1`) |
| `memkeeper-cli` | The `memkeeper` binary (CLI + daemon) |
Editor/agent integrations live under `adapters/` (an MCP bridge and a thin
extension client).
## Further reading
Design notes and benchmarks on the [memkeeper blog](https://memkeeper.ai/blog/):
- [Local-first memory for AI agents](https://memkeeper.ai/blog/local-first-memory-for-ai-agents): why the default should be your own machine, not a hosted vector DB.
- [Why hybrid retrieval beats pure vector search](https://memkeeper.ai/blog/hybrid-retrieval-vs-vector-search): what BM25, dense embeddings, and a cross-encoder each cover.
- [A memory that says "I don't know"](https://memkeeper.ai/blog/memory-that-says-i-dont-know): abstention, and the number we publish to prove it.
- [Benchmarking agent memory on LoCoMo](https://memkeeper.ai/blog/benchmarking-agent-memory-locomo): the method and a script to reproduce the numbers.
- [Where memkeeper fits](https://memkeeper.ai/blog/where-memkeeper-fits): an honest comparison to mem0, Zep, and Graphiti.
- [Getting started in ten minutes](https://memkeeper.ai/blog/getting-started-with-memkeeper): from install to recall, including MCP wiring.
## Memkeeper family
[Warden](https://github.com/teflon07/memkeeper-warden) is a companion capability
broker and execution gate: it decides whether an agent's requested action (a
shell command, a file read/write) is allowed by a declared, auditable policy, and
logs every decision. memkeeper remembers; Warden guards.
## License
Dual-licensed under either of [MIT](LICENSE-MIT) or
[Apache-2.0](LICENSE-APACHE) at your option.
## Contributing
See [CONTRIBUTING.md](CONTRIBUTING.md). Contributions require signing the project
[Contributor License Agreement](docs/CLA.md) — the CLA bot prompts you on your
first pull request. You keep the copyright to your contributions.