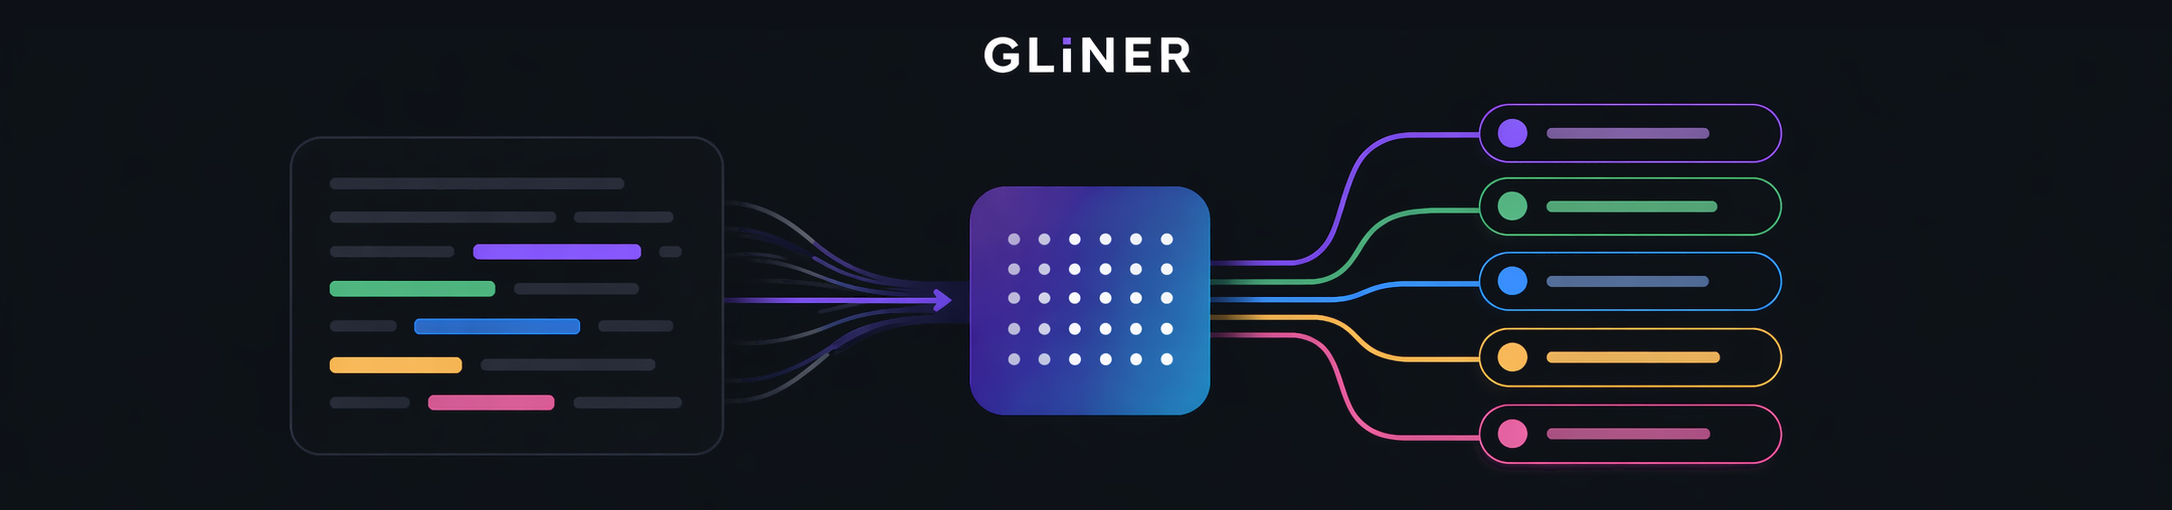
# GLiNER: Generalist and Lightweight Model for Named Entity Recognition
**Zero-shot NER | Streaming NER | Relation Extraction | PII Detection | Information Extraction | Token Classification**
|
Zero-shot Recognition
Extract any entity type — no labeled data or task-specific training required
|
Runs Anywhere
CPU, INT8 quantization, torch.compile, ONNX export — deploy on any hardware
|
Millions of Labels
Bi-encoder pre-computes label embeddings, scaling to 100+ entity types without degradation
|
|
NER + Relations
Build knowledge graphs in a single pass with the joint RelEx architecture
|
PII Detection
State-of-the-art multilingual PII models covering major entity types across 100+ languages
|
Fine-Tune in Minutes
Few-shot learning on small datasets — bring your own labels and get competitive results fast
|
## Quick Start
### Installation
**With pip:**
```bash
pip install gliner
```
**With uv (faster):**
```bash
uv pip install gliner
```
**With serving support (Ray Serve):**
```bash
uv pip install gliner[serve] # or: pip install gliner ray[serve]
```
### Basic Usage
```python
from gliner import GLiNER
model = GLiNER.from_pretrained("gliner-community/gliner_small-v2.5")
text = """
Cristiano Ronaldo dos Santos Aveiro (born 5 February 1985) is a Portuguese
professional footballer who plays as a forward for and captains both Saudi Pro
League club Al Nassr and the Portugal national team.
"""
labels = ["person", "date", "organization", "location"]
entities = model.predict_entities(text, labels, threshold=0.5)
for entity in entities:
print(entity["text"], "=>", entity["label"])
```
**Output:**
```
Cristiano Ronaldo dos Santos Aveiro => person
5 February 1985 => date
Al Nassr => organization
Portugal => location
```
## 🚀 Optimizations
GLiNER models are already small, but quantization and compilation can make them significantly faster and more memory-efficient, important when running on edge devices, serving at high throughput, or keeping GPU costs low.
- **`torch.compile`** fuses operations and removes Python overhead, yielding up to ~1.5x speedup with no quality loss.
- **FP16 quantization** (`quantize=True`) halves model memory and speeds up matrix operations. Combined with compilation, this gives up to **~1.9x faster GPU inference** with virtually no quality loss.
- **INT8 quantization** cuts memory by another 2x on top of FP16 and is supported out of the box, however, models need to be trained with Quantization-Aware Training (QAT) to preserve accuracy at INT8 precision.
```python
model = GLiNER.from_pretrained(
"gliner-community/gliner_small-v2.5",
map_location="cuda",
quantize=True,
compile_torch_model=True,
)
```
Find more information on compilation and other optimizations in the [documentation](https://urchade.github.io/GLiNER/usage.html#quantization-compilation-flashdeberta).
## Serving
For production workloads — high-throughput pipelines, multi-user services, or anywhere you need to go beyond single-process `model.inference()` calls — GLiNER provides a Ray Serve-based serving layer. It adds dynamic batching that automatically groups incoming requests, memory-aware batch sizing that prevents CUDA OOM by calibrating against your GPU, precompiled kernels for common batch sizes to avoid first-call latency, horizontal scaling across multiple GPUs via Ray replicas, and an HTTP API for language-agnostic access.
```bash
python -m gliner.serve --model gliner-community/gliner_small-v2.5 --dtype fp16
```
Then query from Python:
```python
from gliner.serve import GLiNERClient
client = GLiNERClient() # connects to http://localhost:8000/gliner
results = client.predict(
["John works at Google", "Paris is in France"],
labels=["person", "organization", "location"],
)
```
More information on serving options and parameters can be found in the [documentation](https://urchade.github.io/GLiNER/serving.html).
## Training
GLiNER models are easy to fine-tune on your own data. Prepare your dataset as a JSON file and use the training script:
```bash
python train.py --config configs/config.yaml
```
Or train programmatically:
```python
from gliner import GLiNER
model = GLiNER.from_pretrained("gliner-community/gliner_small-v2.5")
model.train_model(
train_dataset=train_data,
eval_dataset=eval_data,
output_dir="models",
max_steps=10000,
per_device_train_batch_size=8,
learning_rate=1e-5,
bf16=True,
)
```
For detailed training examples, see the [example notebooks](https://github.com/urchade/GLiNER/tree/main/examples):
- [Documentation on training](https://urchade.github.io/GLiNER/training.html)
- [Fine-tuning on Colab](https://colab.research.google.com/drive/1HNKd74cmfS9tGvWrKeIjSxBt01QQS7bq?usp=sharing)
- [Synthetic Data Generation](https://github.com/urchade/GLiNER/blob/main/examples/synthetic_data_generation.ipynb)
## Architectures
GLiNER supports multiple architectures tailored to different use cases:
| Architecture | Description | Example Model |
|---|---|---|
| **Uni-encoder** | Strong zero-shot capabilities, supports up to ~50 entity types. The original GLiNER architecture. | [gliner_multi_pii-v1](https://huggingface.co/urchade/gliner_multi_pii-v1) |
| **Bi-encoder** | Scalable to massive numbers of entity types via separate text and label encoding. | [gliner-bi-base-v2.0](https://huggingface.co/knowledgator/gliner-bi-base-v2.0) |
| **RelEx** | Joint NER and relation extraction in a single model. | [gliner-relex-large-v1.0](https://huggingface.co/knowledgator/gliner-relex-large-v1.0) |
| **GLiNER Decoder** | Hybrid architecture for open NER: entity types are generated with a small decoder for maximum flexibility. | [gliner-decoder-large-v1.0](https://huggingface.co/knowledgator/gliner-decoder-large-v1.0) |
| **StreamingSpan** | Causal span model that reuses decoder, label, and word caches for incremental NER and rolling prediction updates. | [gliner-stream-pii-v1.0](https://huggingface.co/knowledgator/gliner-stream-pii-v1.0) |
For more details, see the [documentation](https://urchade.github.io/GLiNER/architectures.html).
## Popular Use Cases
- **[Compliance & PII Redaction](https://urchade.github.io/GLiNER/usage.html#compliance--pii-redaction)** — detect and mask 40+ types of personal data (SSN, credit cards, passports, emails, IBANs, etc.) across documents and data pipelines
- **[Knowledge Graph Construction](https://urchade.github.io/GLiNER/usage.html#knowledge-graph-construction)** — jointly extract entities and relations to power Graph RAG, semantic search, and analytics
- **[Large-Scale Entity Extraction](https://urchade.github.io/GLiNER/usage.html#large-scale-entity-extraction)** — use the bi-encoder to tag millions of documents against hundreds or thousands of entity types in production
- **[Domain-Specific NER](https://urchade.github.io/GLiNER/usage.html#domain-specific-ner)** — fine-tune on biomedical, legal, financial, or any specialized corpus with minimal labeled data
- **[Multi-lingual Information Extraction](https://urchade.github.io/GLiNER/usage.html#multi-lingual-information-extraction)** — extract structured data from 100+ languages with a single model
- **[Search & Retrieval Augmentation](https://urchade.github.io/GLiNER/usage.html#search--retrieval-augmentation)** — parse queries into structured entities to improve search relevance and RAG pipelines
## Ecosystem
GLiNER has a rich ecosystem of community projects and integrations:
| Project | Description |
|---|---|
| [GLiNER2](https://github.com/fastino-ai/GLiNER2) | Unified multi-task model for NER, text classification, and structured data extraction |
| [GLiClass](https://github.com/Knowledgator/GLiClass) | Zero-shot text classification using GLiNER-style architecture |
| [GLinker](https://github.com/Knowledgator/GLinker) | Entity linking with GLiNER |
| [GLiNER.cpp](https://github.com/Knowledgator/GLiNER.cpp) | C++ implementation for high-performance inference |
| [gline-rs](https://github.com/fbilhaut/gline-rs) | Rust implementation of GLiNER |
| [vllm-factory](https://github.com/ddickmann/vllm-factory) | vLLM integration for scalable GLiNER serving |
| [gliner-spacy](https://github.com/theirstory/gliner-spacy) | spaCy integration for GLiNER |
## Documentation
Full documentation is available at [urchade.github.io/GLiNER](https://urchade.github.io/GLiNER).
## Authors & Creators
GLiNER was originally developed by:
* [Urchade Zaratiana](https://www.linkedin.com/in/urchade-zaratiana-36ba9814b/)
* Nadi Tomeh
* Pierre Holat
* Thierry Charnois
We gratefully acknowledge the contributions of the open-source community, whose efforts have helped shape and improve this project.
## Maintainers
Urchade Zaratiana
Member of technical staff at Fastino

|
Ihor Stepanov
Co-Founder at Knowledgator
|
## Community
- [Discord — GLiNER Community](https://discord.gg/x7hQsjX2Kk)
- [Reddit — r/GLiNER](https://www.reddit.com/r/GLiNER/)
- [HuggingFace](https://huggingface.co/gliner-community)
## Contributing
We welcome contributions from the community! Here's how to get started:
1. **Fork** the repository and create a new branch from `main`.
2. **Install** the development dependencies: `pip install -e ".[dev]"`.
3. **Make your changes** — bug fixes, new features, documentation improvements, and new examples are all appreciated.
4. **Lint and format** your code with [Ruff](https://docs.astral.sh/ruff/) before committing:
```bash
ruff check . --fix
ruff format .
```
5. **Write tests** for any new functionality and make sure existing tests pass.
6. **Submit a pull request** with a clear description of what you changed and why.
For bug reports and feature requests, please [open an issue](https://github.com/urchade/GLiNER/issues). For questions and discussions, join us on [Discord](https://discord.gg/x7hQsjX2Kk).
## Citations
If you find **GLiNER** useful in your research, please consider citing the original paper:
```bibtex
@inproceedings{zaratiana-etal-2024-gliner,
title = "{GL}i{NER}: Generalist Model for Named Entity Recognition using Bidirectional Transformer",
author = "Zaratiana, Urchade and
Tomeh, Nadi and
Holat, Pierre and
Charnois, Thierry",
booktitle = "Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers)",
year = "2024",
url = "https://aclanthology.org/2024.naacl-long.300",
pages = "5364--5376",
}
```
## Related and Follow-up Work
The GLiNER family has since been extended to additional information extraction and classification tasks:
### GLiNER multi-task
```bibtex
@misc{stepanov2024glinermultitaskgeneralistlightweight,
title={GLiNER multi-task: Generalist Lightweight Model for Various Information Extraction Tasks},
author={Ihor Stepanov and Mykhailo Shtopko},
year={2024},
eprint={2406.12925},
archivePrefix={arXiv},
primaryClass={cs.LG},
url={https://arxiv.org/abs/2406.12925},
}
```
### GLiNER bi-encoder
```bibtex
@misc{stepanov2026millionlabelnerbreakingscale,
title={The Million-Label NER: Breaking Scale Barriers with GLiNER bi-encoder},
author={Ihor Stepanov and Mykhailo Shtopko and Dmytro Vodianytskyi and Oleksandr Lukashov},
year={2026},
eprint={2602.18487},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2602.18487},
}
```
### GLiNER2
```bibtex
@misc{zaratiana2025gliner2efficientmultitaskinformation,
title={GLiNER2: An Efficient Multi-Task Information Extraction System with Schema-Driven Interface},
author={Urchade Zaratiana and Gil Pasternak and Oliver Boyd and George Hurn-Maloney and Ash Lewis},
year={2025},
eprint={2507.18546},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2507.18546},
}
```
### GLiGuard
```bibtex
@misc{zaratiana2026gliguardschemaconditionedclassificationllm,
title={GLiGuard: Schema-Conditioned Classification for LLM Safeguard},
author={Urchade Zaratiana and Mary Newhauser and George Hurn-Maloney and Ash Lewis},
year={2026},
eprint={2605.07982},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2605.07982},
}
```
### GLiNER2-PII
```bibtex
@misc{zaratiana2026gliner2piimultilingualmodelpersonally,
title={GLiNER2-PII: A Multilingual Model for Personally Identifiable Information Extraction},
author={Urchade Zaratiana and Ash Lewis and George Hurn-Maloney},
year={2026},
eprint={2605.09973},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2605.09973},
}
```
## Support and Funding
This project has been supported and funded by **F.initiatives** and **Laboratoire Informatique de Paris Nord**.
F.initiatives has been an expert in public funding strategies for R&D, Innovation, and Investments (R&D&I) for over 20 years. With a team of more than 200 qualified consultants, F.initiatives guides its clients at every stage of developing their public funding strategy: from structuring their projects to submitting their aid application, while ensuring the translation of their industrial and technological challenges to public funders. Through its continuous commitment to excellence and integrity, F.initiatives relies on the synergy between methods and tools to offer tailored, high-quality, and secure support.
We also extend our heartfelt gratitude to the open-source community for their invaluable contributions, which have been instrumental in the success of this project. ❤️
---
GLiNER — open-source named entity recognition, zero-shot NER, relation extraction, PII detection, information extraction, knowledge graph construction, NLP, natural language processing, token classification, text mining, lightweight NER model, transformer-based NER