*Note: This is an external implementation of the algorithm in the following paper:*
Wei Zhou1,2, Xiongwei Zhu1, Lingdong Kong2, Bo Chen1, Lei Zhang3, Yongyuan Liang4, Xiaoxia Hou1, Tian Ye5,
Xian Sun6, Yingshuo Wang7, Linfeng Li2, Shengqiong Wu8, Leigang Qu2, Feng Li9,
Wei Liu1,†, Julian McAuley3, Tat-Seng Chua2
1 ByteDance Seed
·
2 NUS
·
3 UC San Diego
·
4 UMD
5 HKUST (Guangzhou)
·
6 Duke
·
7 UC Berkeley
·
8 Oxford
·
9 HKUST
† Corresponding Author
---
## 🧠 Method
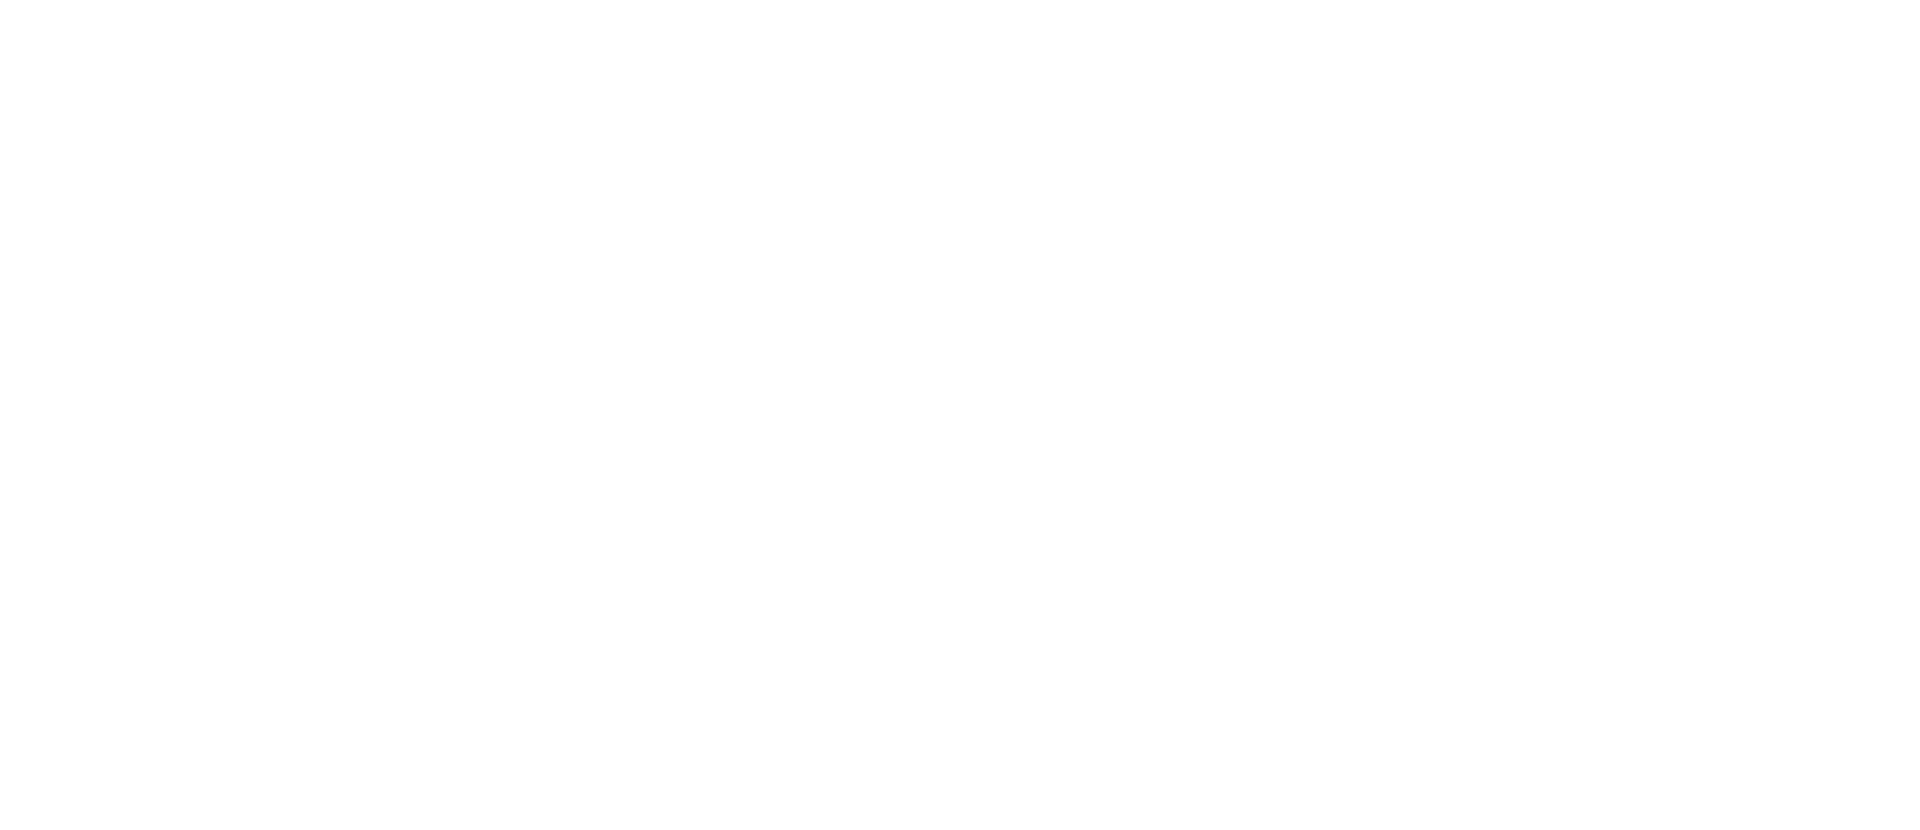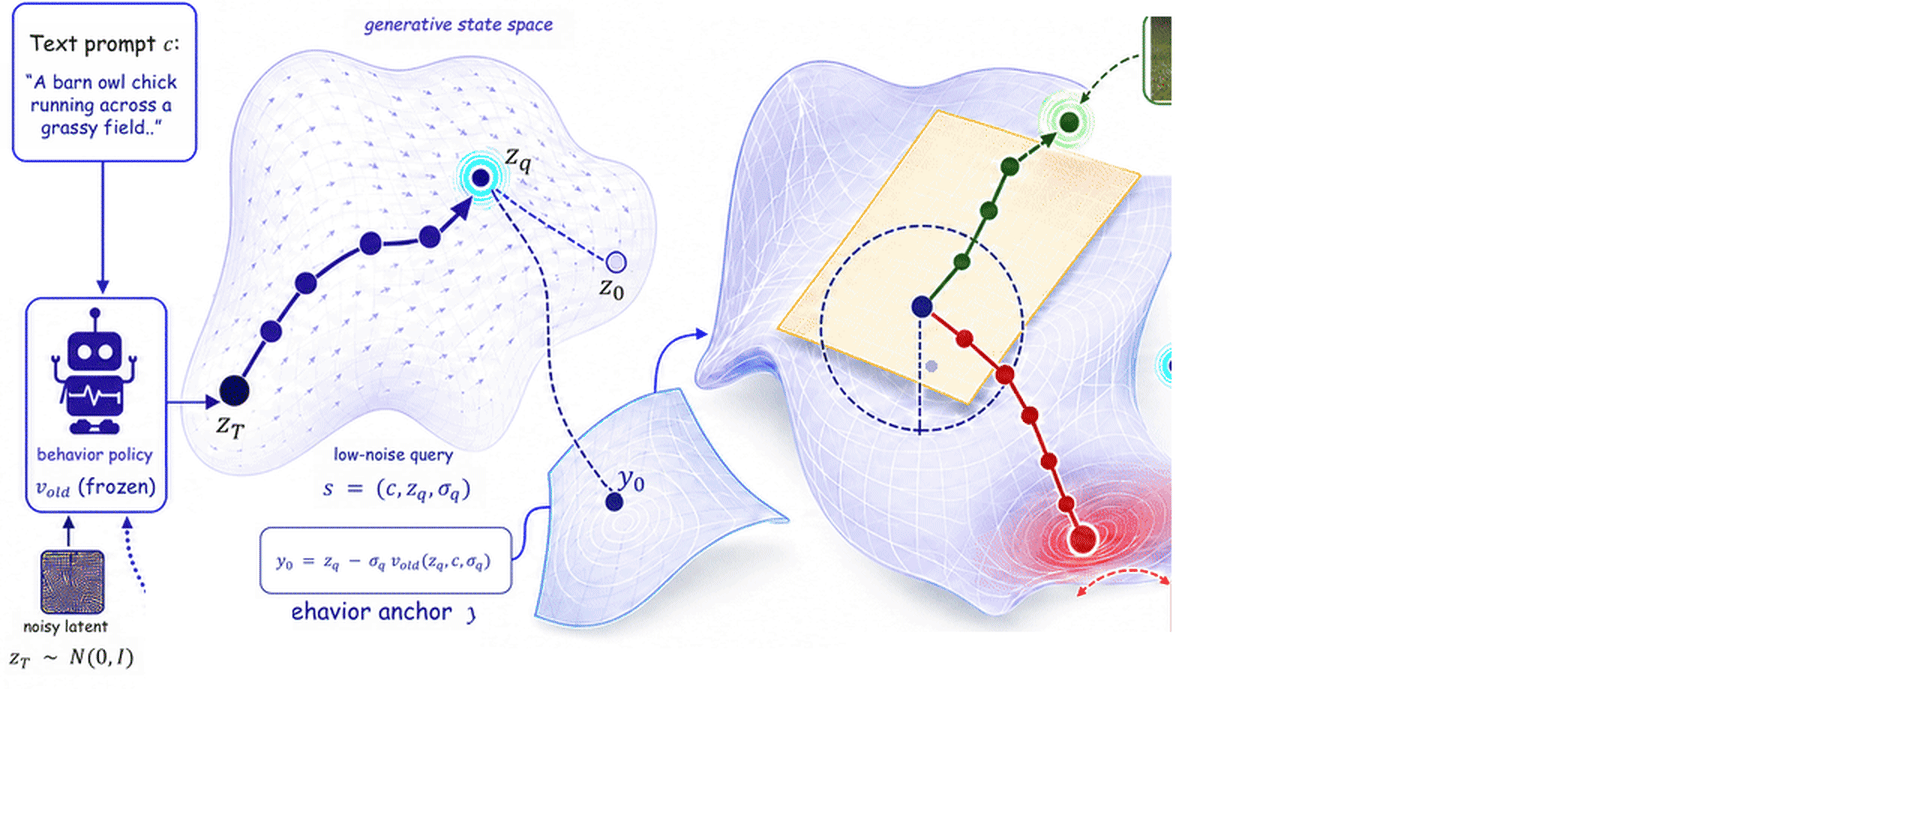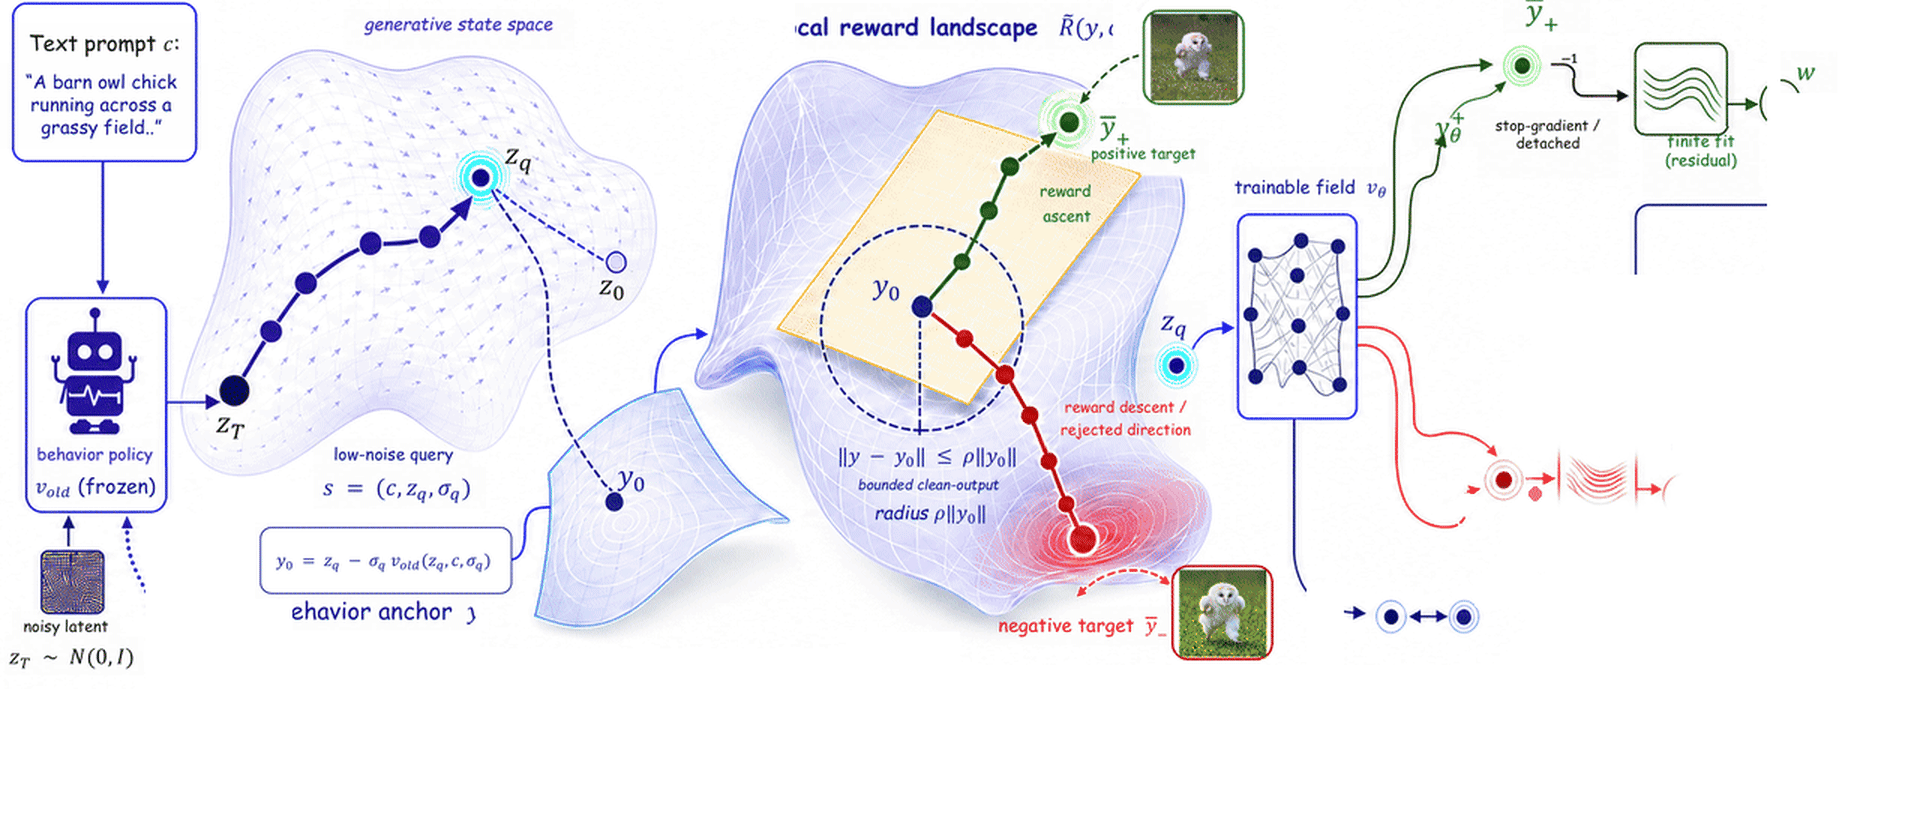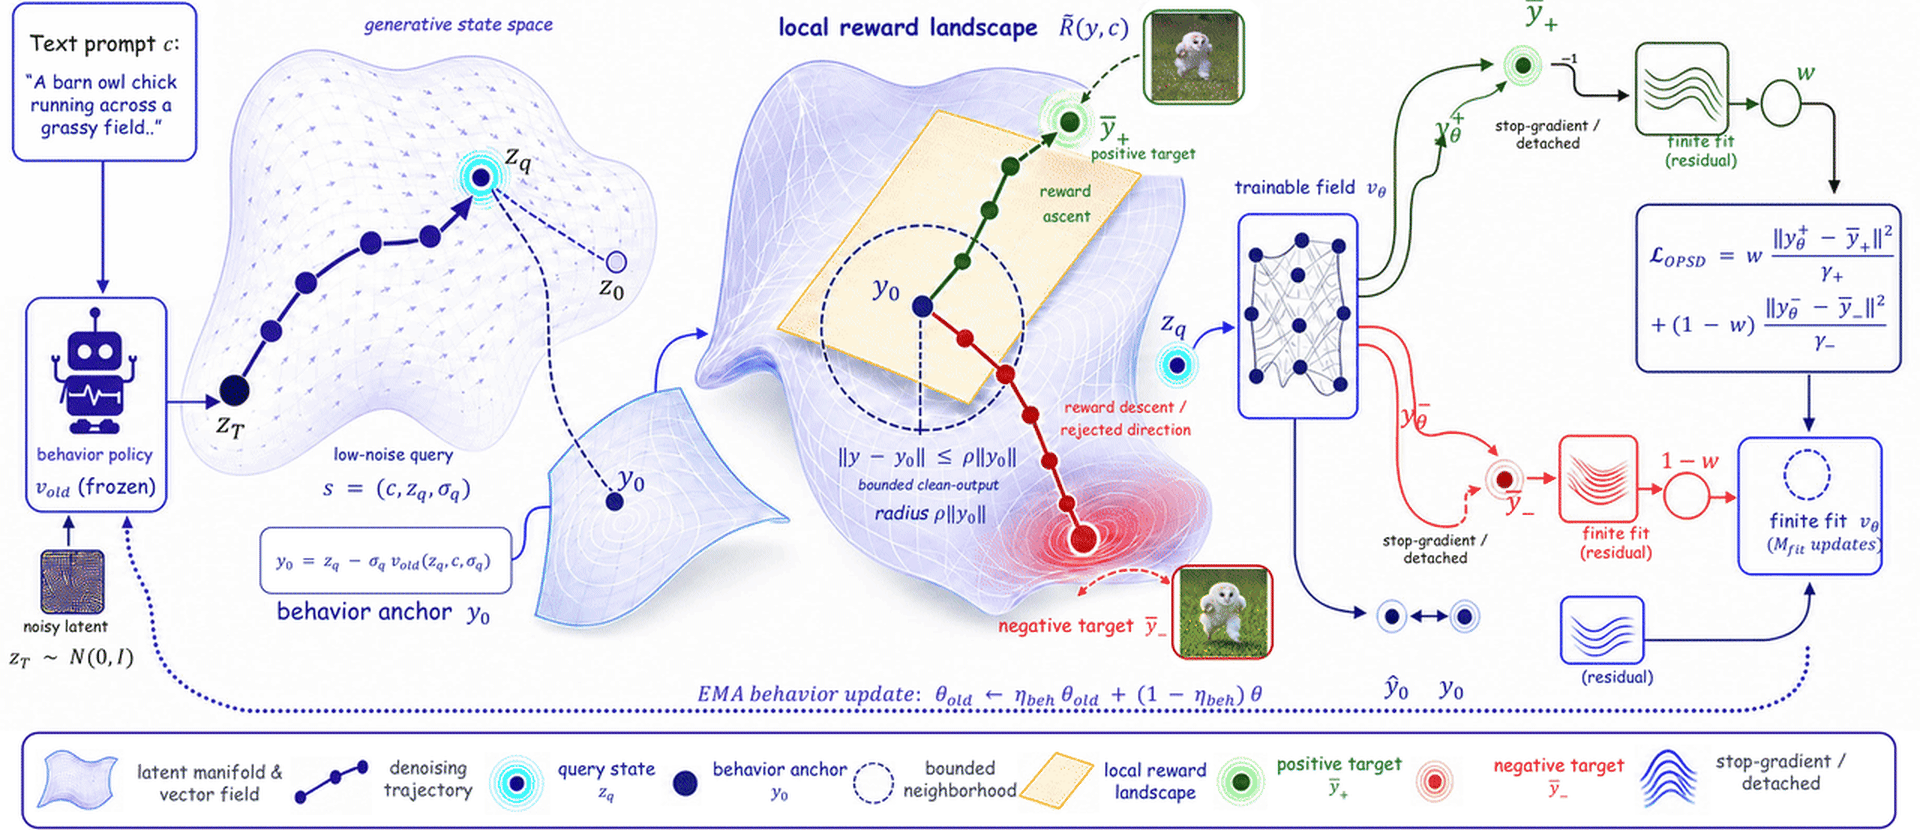
At query $s=(c,z_q,\sigma_q)$, the frozen behavior policy defines a clean-output anchor
$$
y_0 = z_q - \sigma_q v_{\mathrm{old}}(z_q,c,\sigma_q).
$$
DiffusionOPSD applies normalized reward-gradient steps inside a relative trust region,
$$
y_+ \leftarrow y_+ + h\frac{\nabla_y \widetilde R(y_+,c)}{\|\nabla_y \widetilde R(y_+,c)\|_2+\epsilon},
\qquad
y_- \leftarrow y_- - h\frac{\nabla_y \widetilde R(y_-,c)}{\|\nabla_y \widetilde R(y_-,c)\|_2+\epsilon},
$$
then fits the detached targets through positive and negative branches:
$$
\mathcal L_{\mathrm{OPSD}}
= \omega\frac{\|y_\theta^+-\bar y_+\|_2^2}{\gamma_+}
+ (1-\omega)\frac{\|y_\theta^- -\bar y_-\|_2^2}{\gamma_-}.
$$
The implementation uses detached mean-absolute residual normalizers, elementwise-mean squared residuals, and optimizes $c_{\mathrm{adv}}\mathcal L_{\mathrm{OPSD}}$ with $c_{\mathrm{adv}}=5$.
Minimal pseudocode:
```python
trajectory = rollout(behavior_policy, prompt)
query = select_low_noise_state(trajectory)
anchor = behavior_policy.clean_output(query).detach()
weight = group_normalized_endpoint_weight(trajectory.reward)
positive = bounded_reward_ascent(anchor, reward).detach()
negative = bounded_reward_descent(anchor, reward).detach()
prediction = trainable_policy.clean_output(query.detach())
loss = detached_target_loss(prediction, anchor, positive, negative, weight)
loss.backward()
optimizer.step()
update_behavior_policy_ema()
```
---
## 📊 Main Results
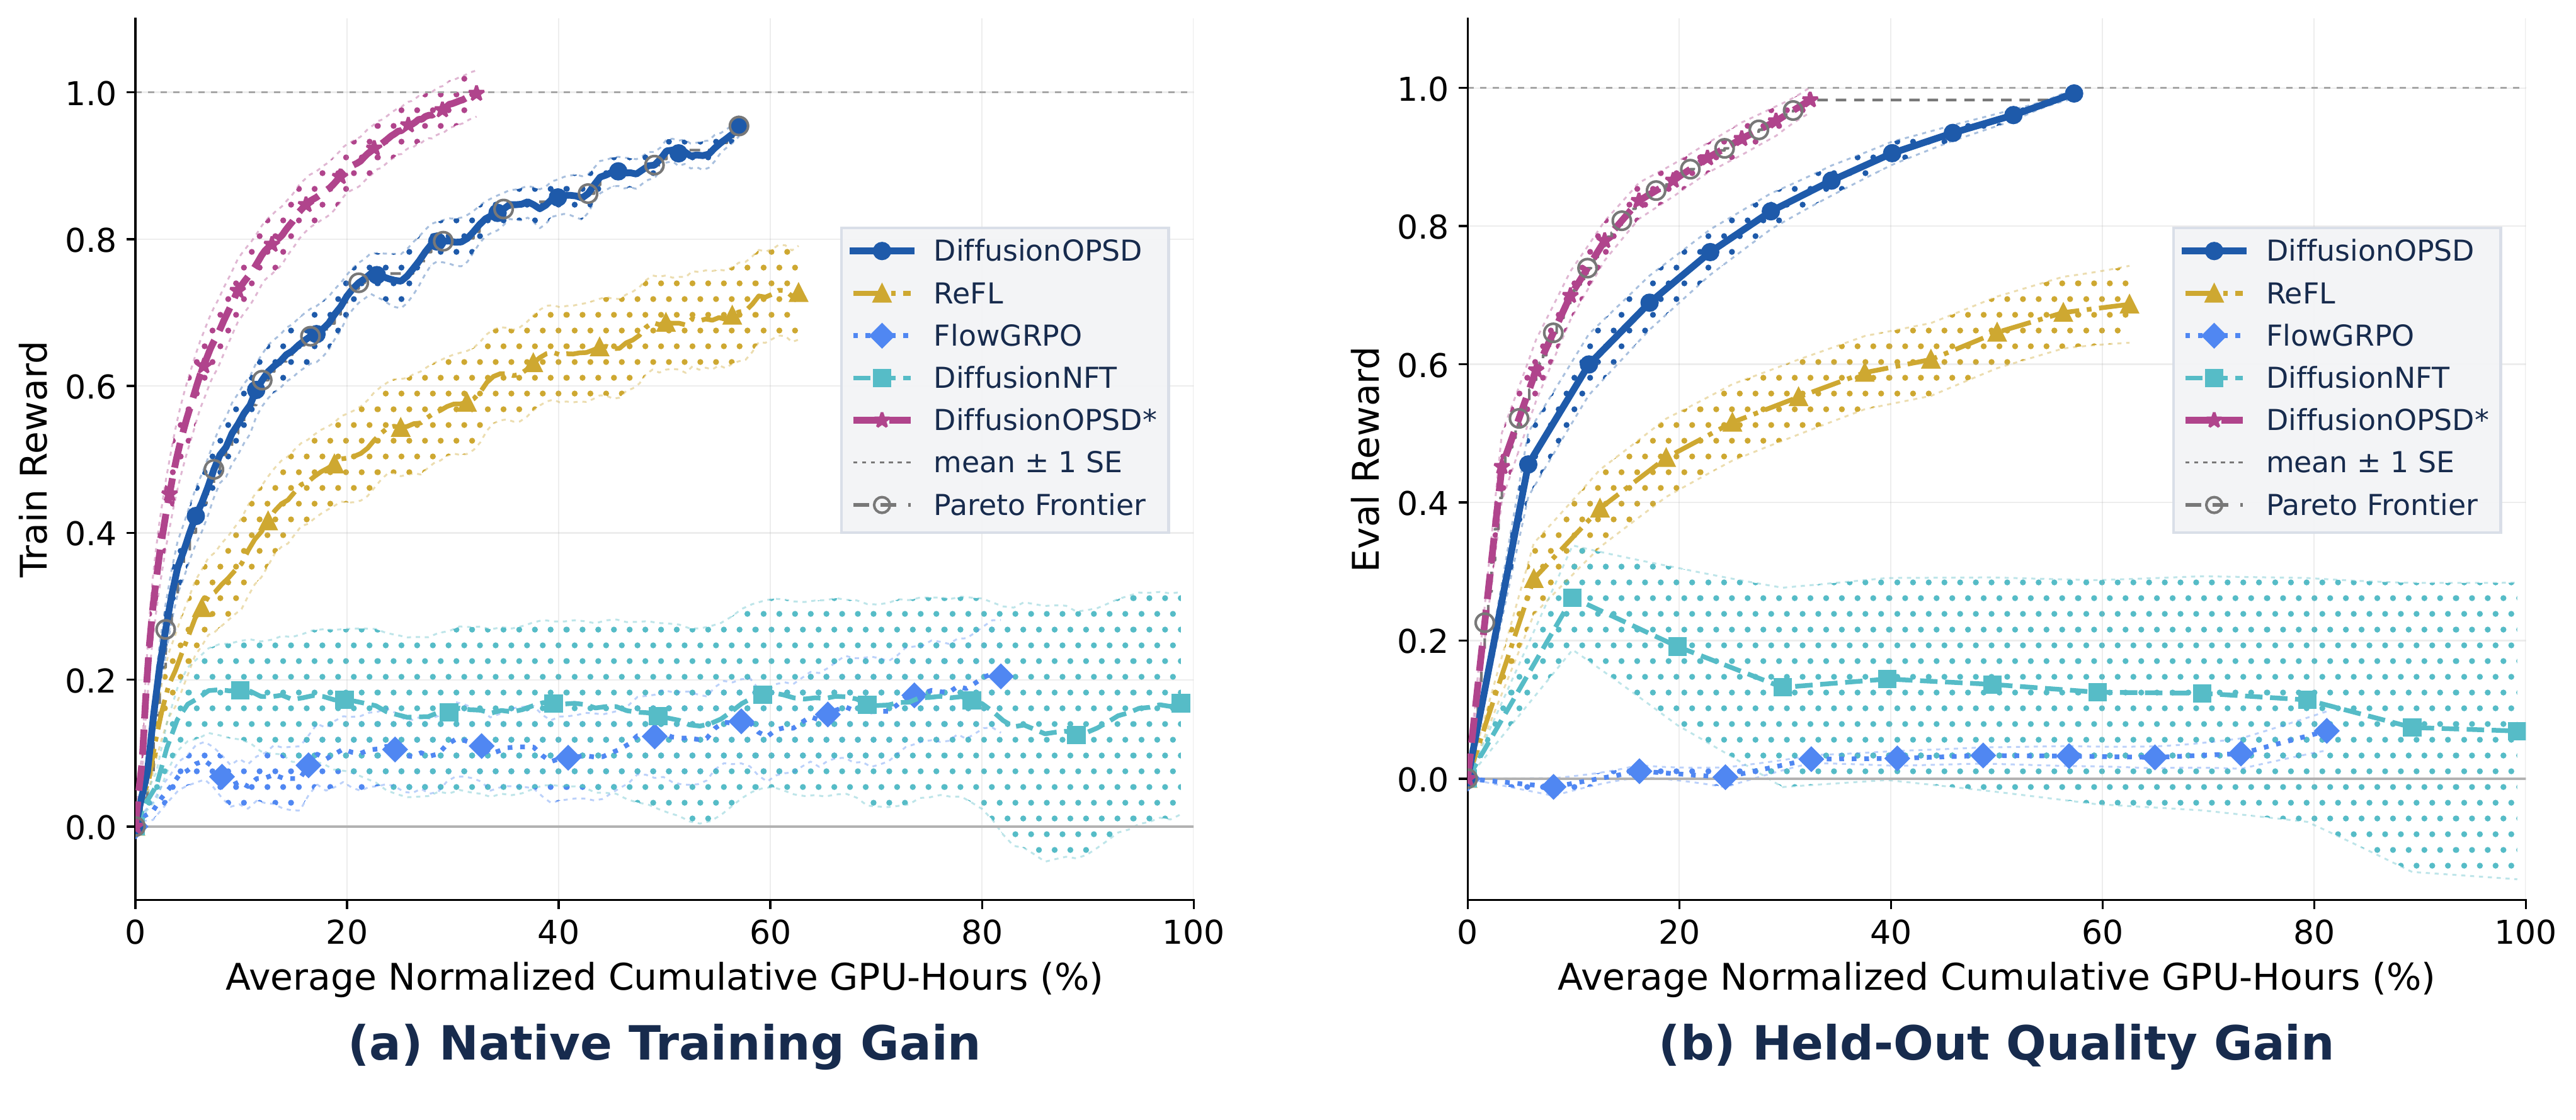
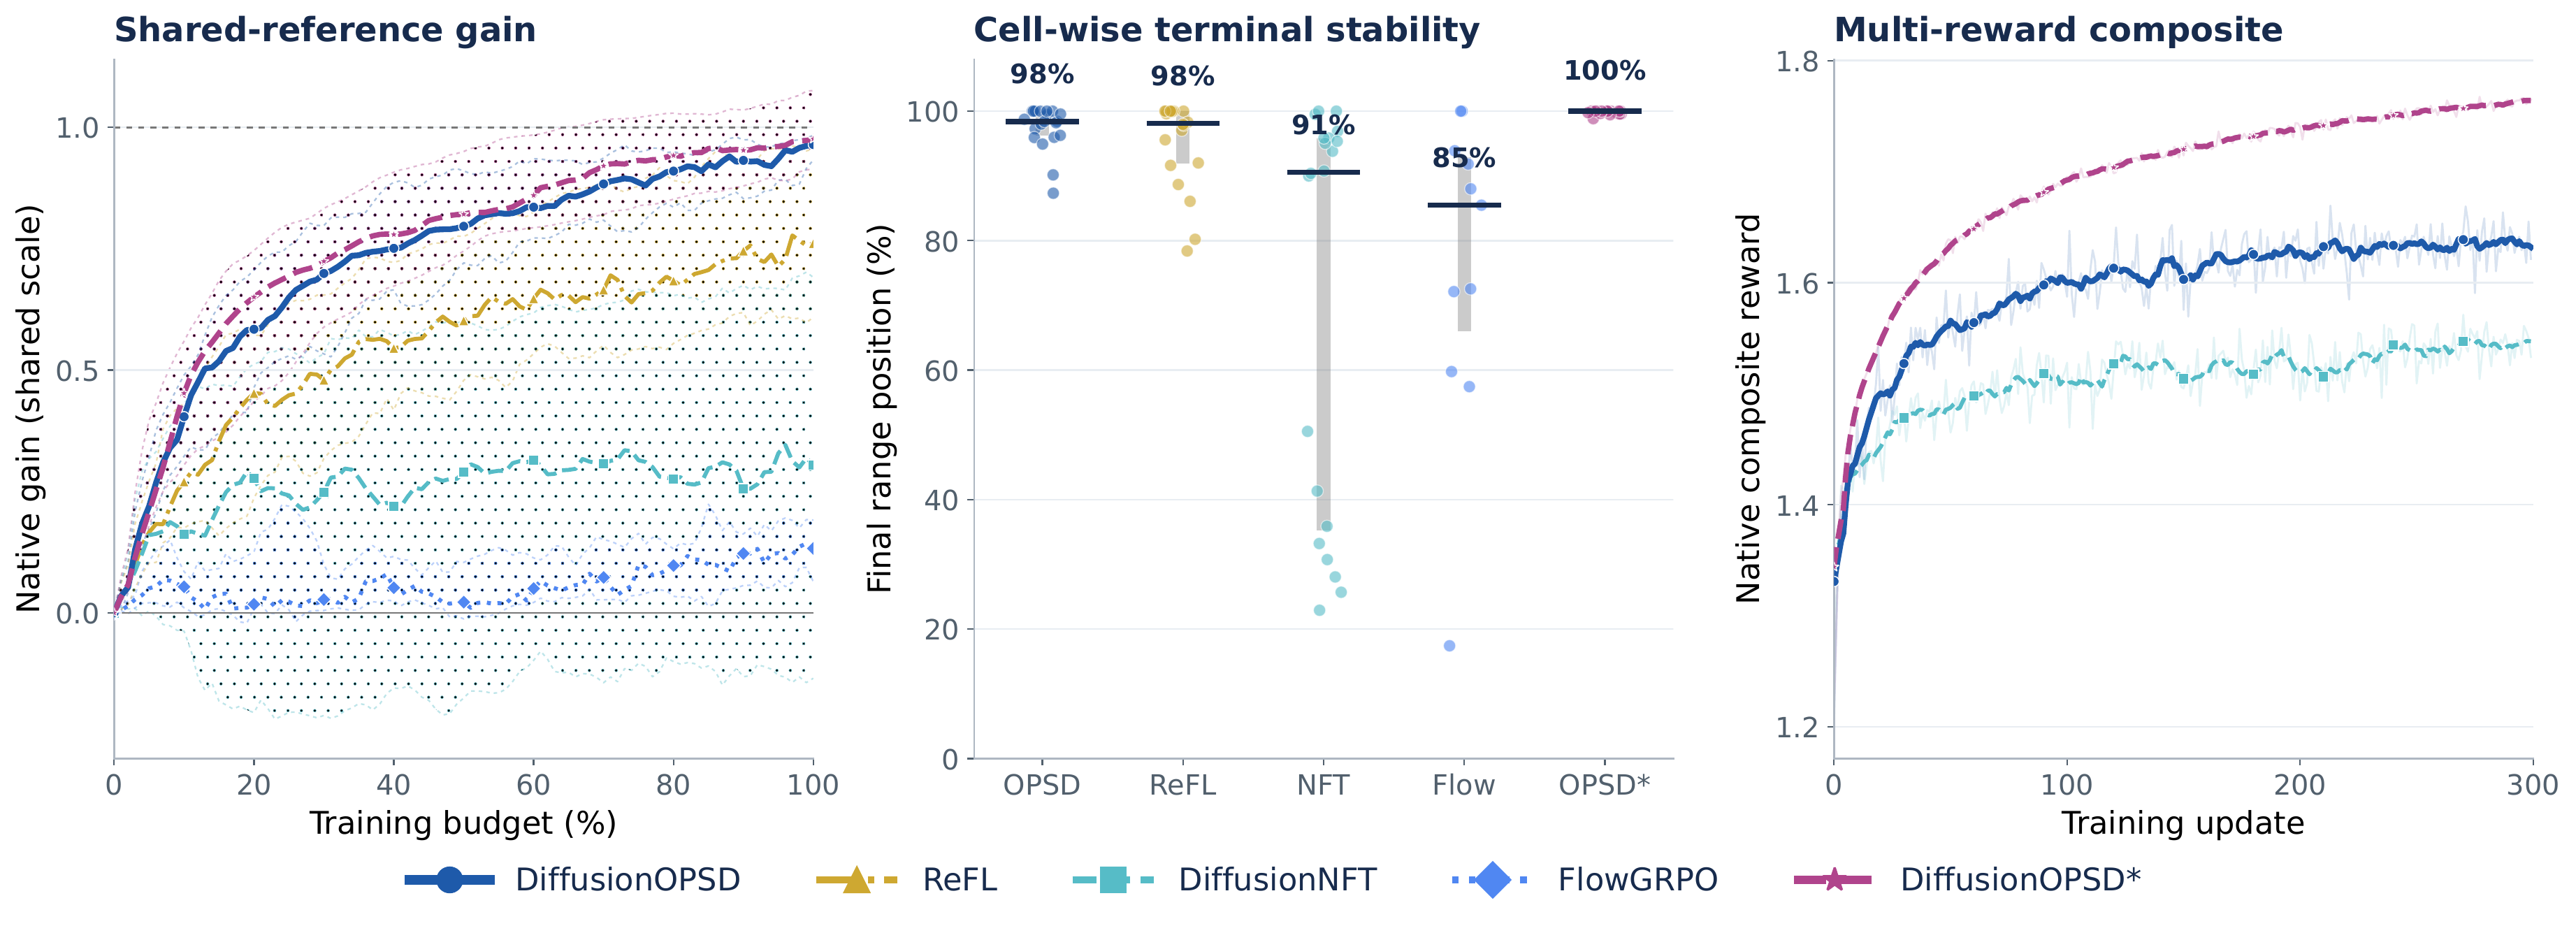
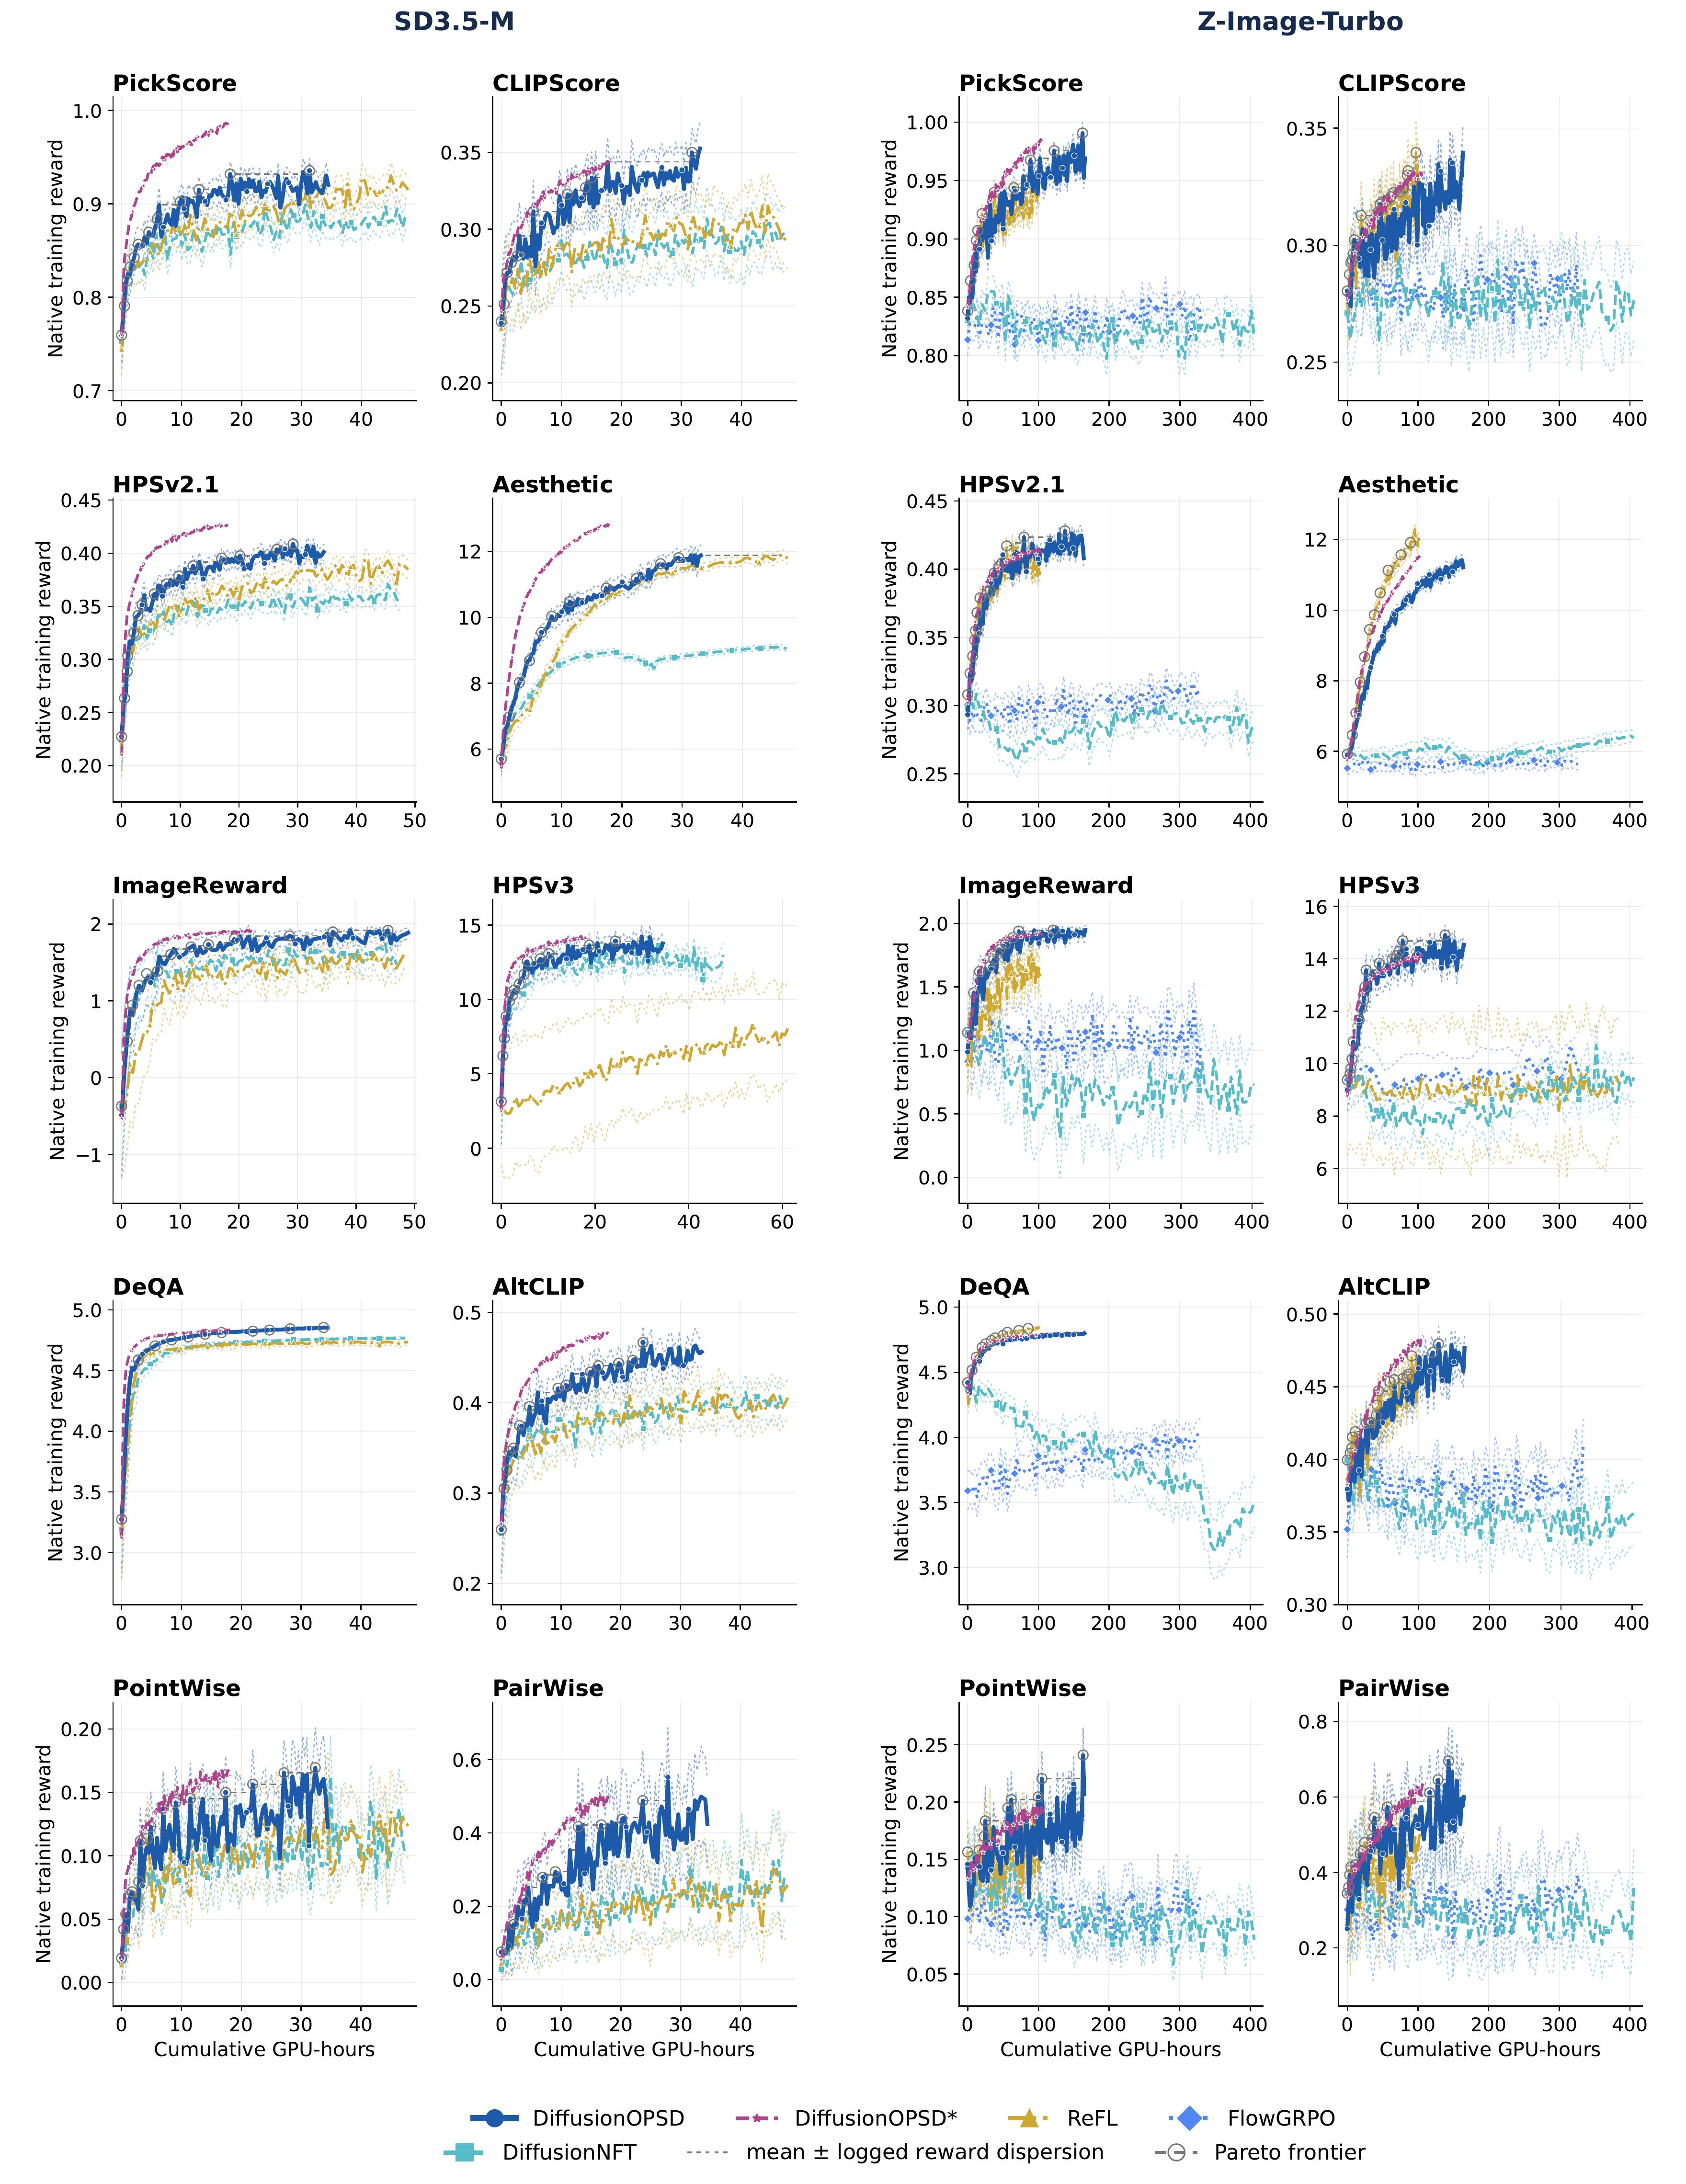
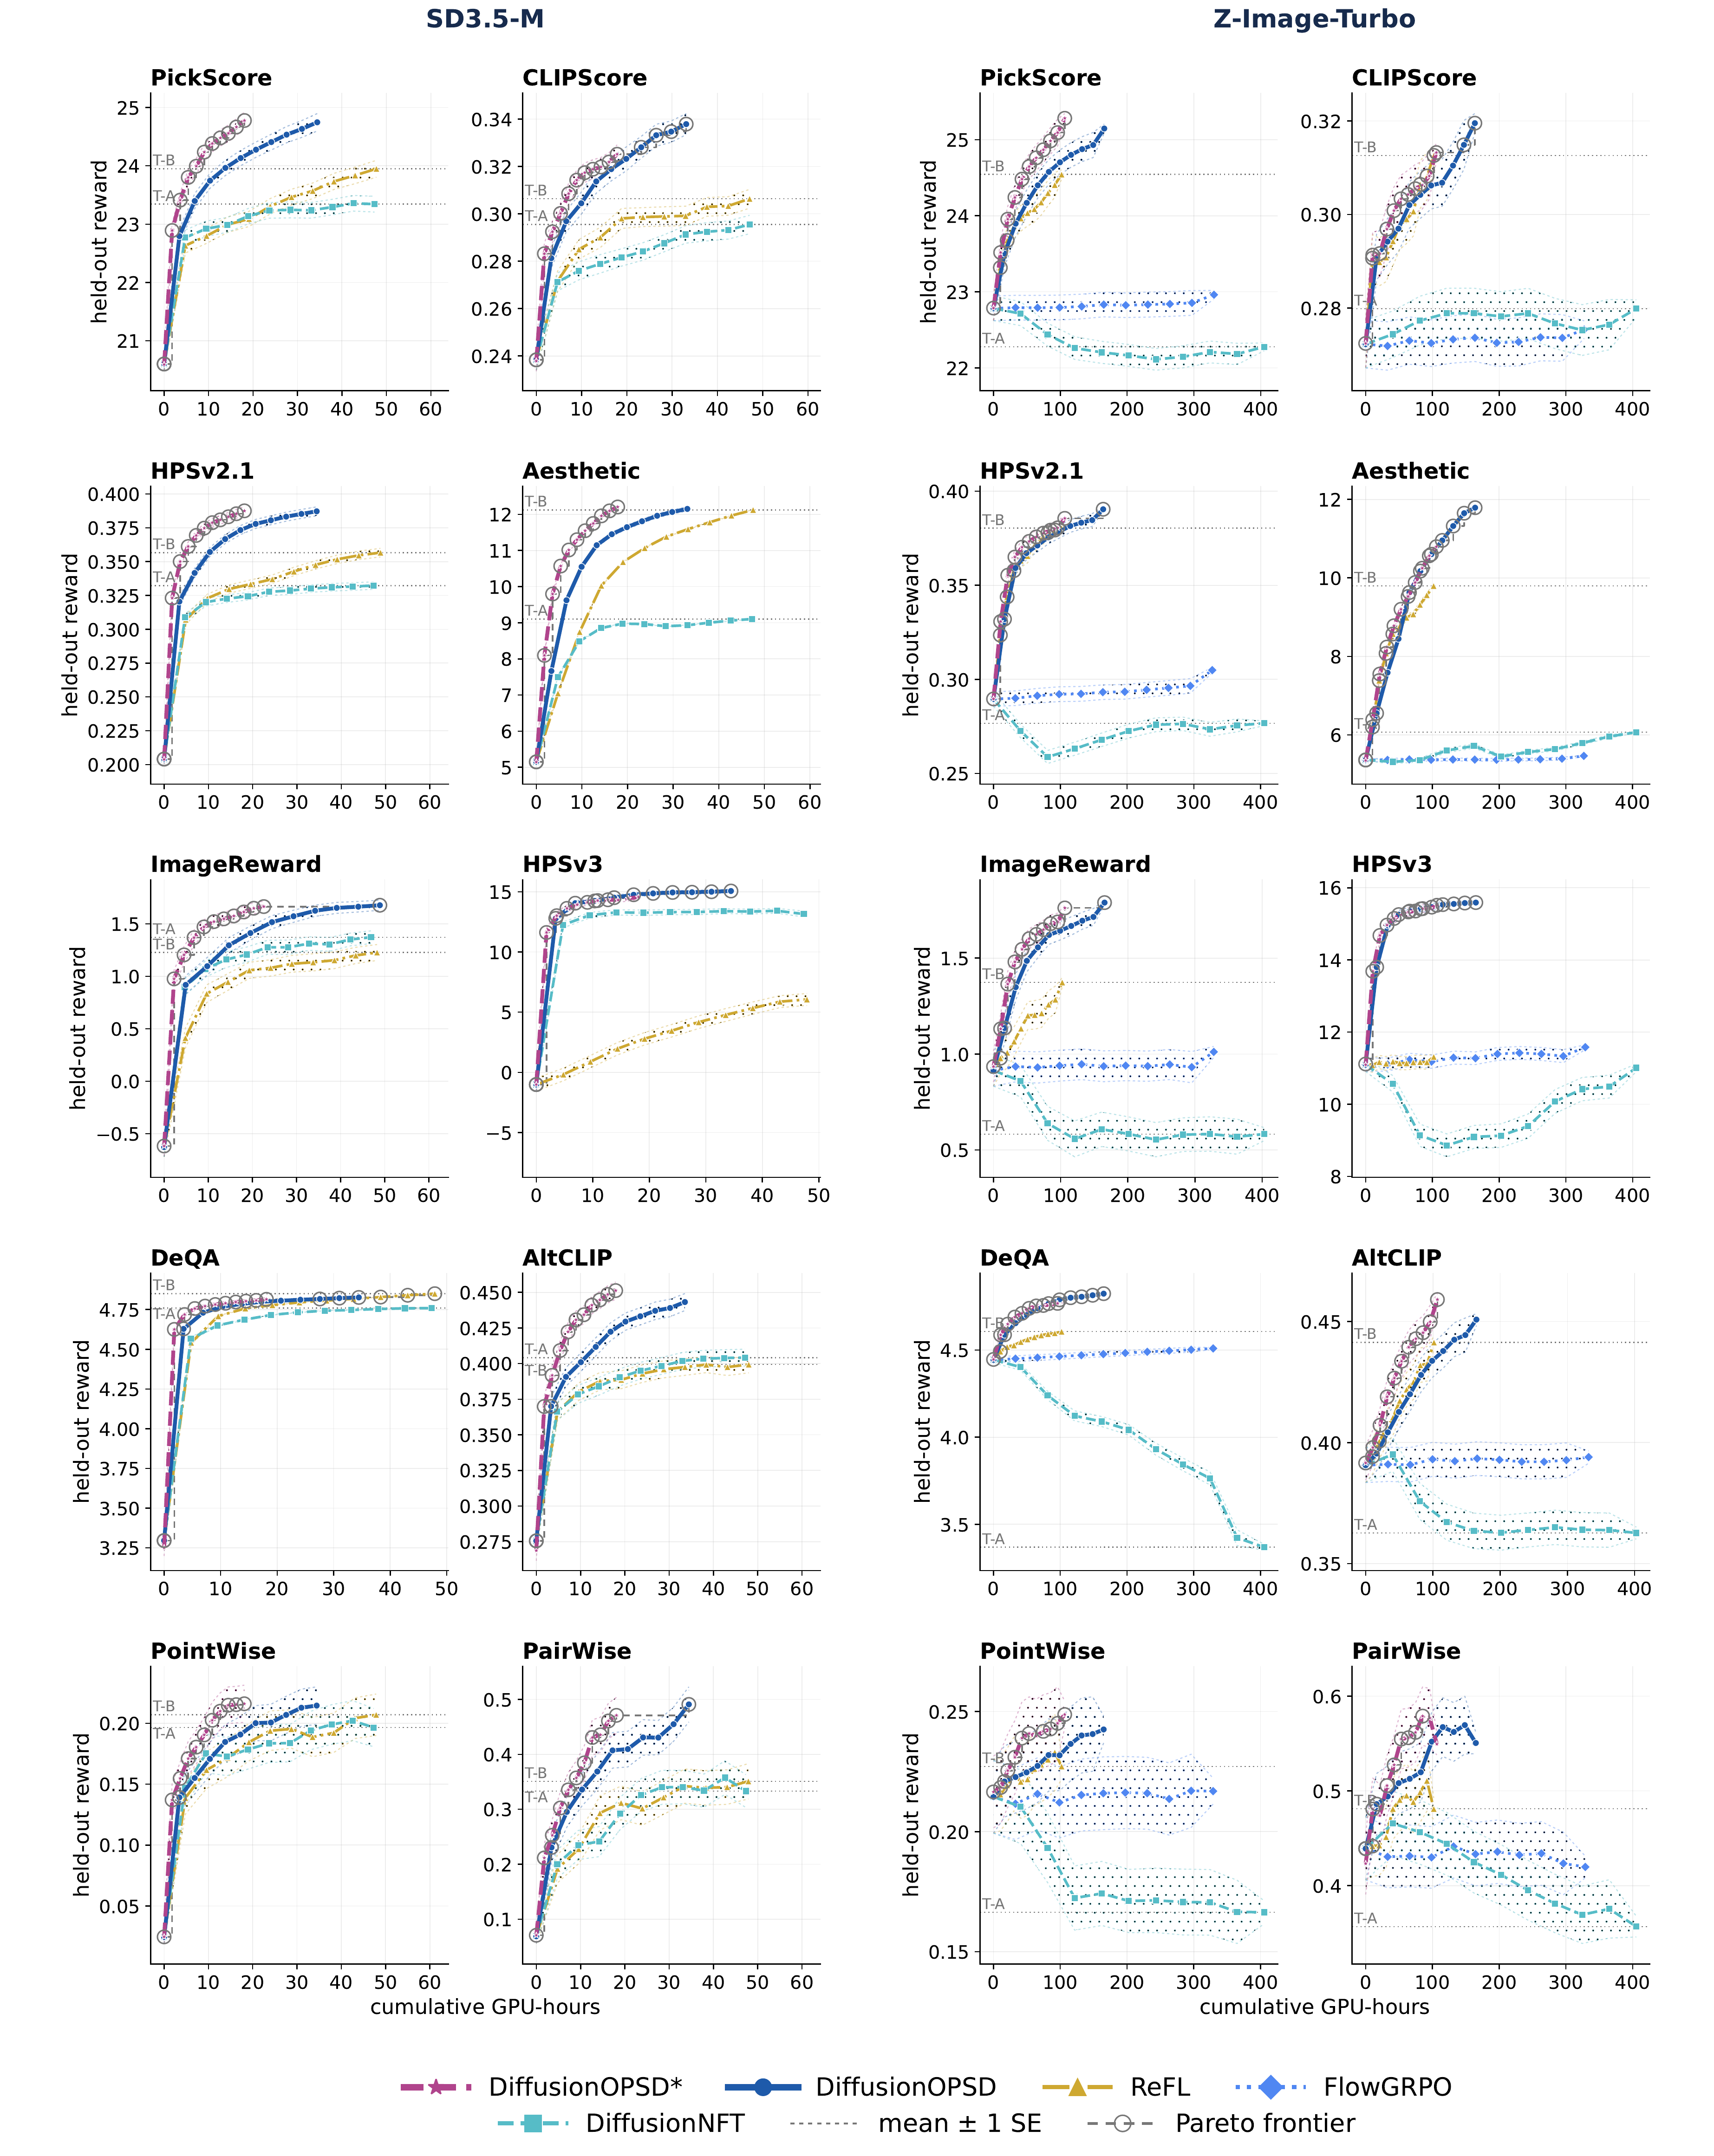
Reward-specific checkpoints are evaluated on their matched held-out objective. Higher is better.
### SD3.5-M
| Method | Pick | CLIP | HPSv2.1 | Aes | ImgR | HPSv3 | DeQA | AltCLIP | Point | Pair |
|---|---:|---:|---:|---:|---:|---:|---:|---:|---:|---:|
| ReFL | 23.92 | 0.308 | 0.358 | **12.09** | 1.28 | 6.18 | 4.85 | 0.408 | 0.193 | 0.290 |
| DiffusionNFT | 23.43 | 0.298 | 0.336 | 9.11 | 1.46 | 13.51 | 4.76 | 0.412 | 0.199 | 0.323 |
| **DiffusionOPSD** | **24.94** | **0.340** | **0.390** | 12.08 | **1.76** | **15.14** | **4.94** | 0.450 | 0.214 | **0.465** |
| **DiffusionOPSD\*** | **24.94** | 0.327 | **0.390** | **12.09** | 1.73 | 14.79 | 4.81 | **0.458** | **0.216** | 0.463 |
### Z-Image-Turbo
| Method | Pick | CLIP | HPSv2.1 | Aes | ImgR | HPSv3 | DeQA | AltCLIP | Point | Pair |
|---|---:|---:|---:|---:|---:|---:|---:|---:|---:|---:|
| FlowGRPO | 22.96 | 0.275 | 0.305 | 5.46 | 1.01 | 11.58 | 4.51 | 0.394 | 0.217 | 0.420 |
| ReFL | 24.54 | 0.313 | 0.380 | 9.79 | 1.37 | 11.32 | 4.60 | 0.441 | 0.227 | 0.481 |
| DiffusionNFT | 22.28 | 0.280 | 0.277 | 6.07 | 0.58 | 11.01 | 3.37 | 0.363 | 0.166 | 0.357 |
| **DiffusionOPSD** | 25.15 | **0.320** | **0.390** | 10.74 | **1.79** | **15.59** | **4.78** | 0.451 | 0.243 | **0.551** |
| **DiffusionOPSD\*** | **25.28** | 0.314 | 0.386 | **10.80** | 1.76 | 15.51 | 4.77 | **0.459** | **0.249** | 0.549 |
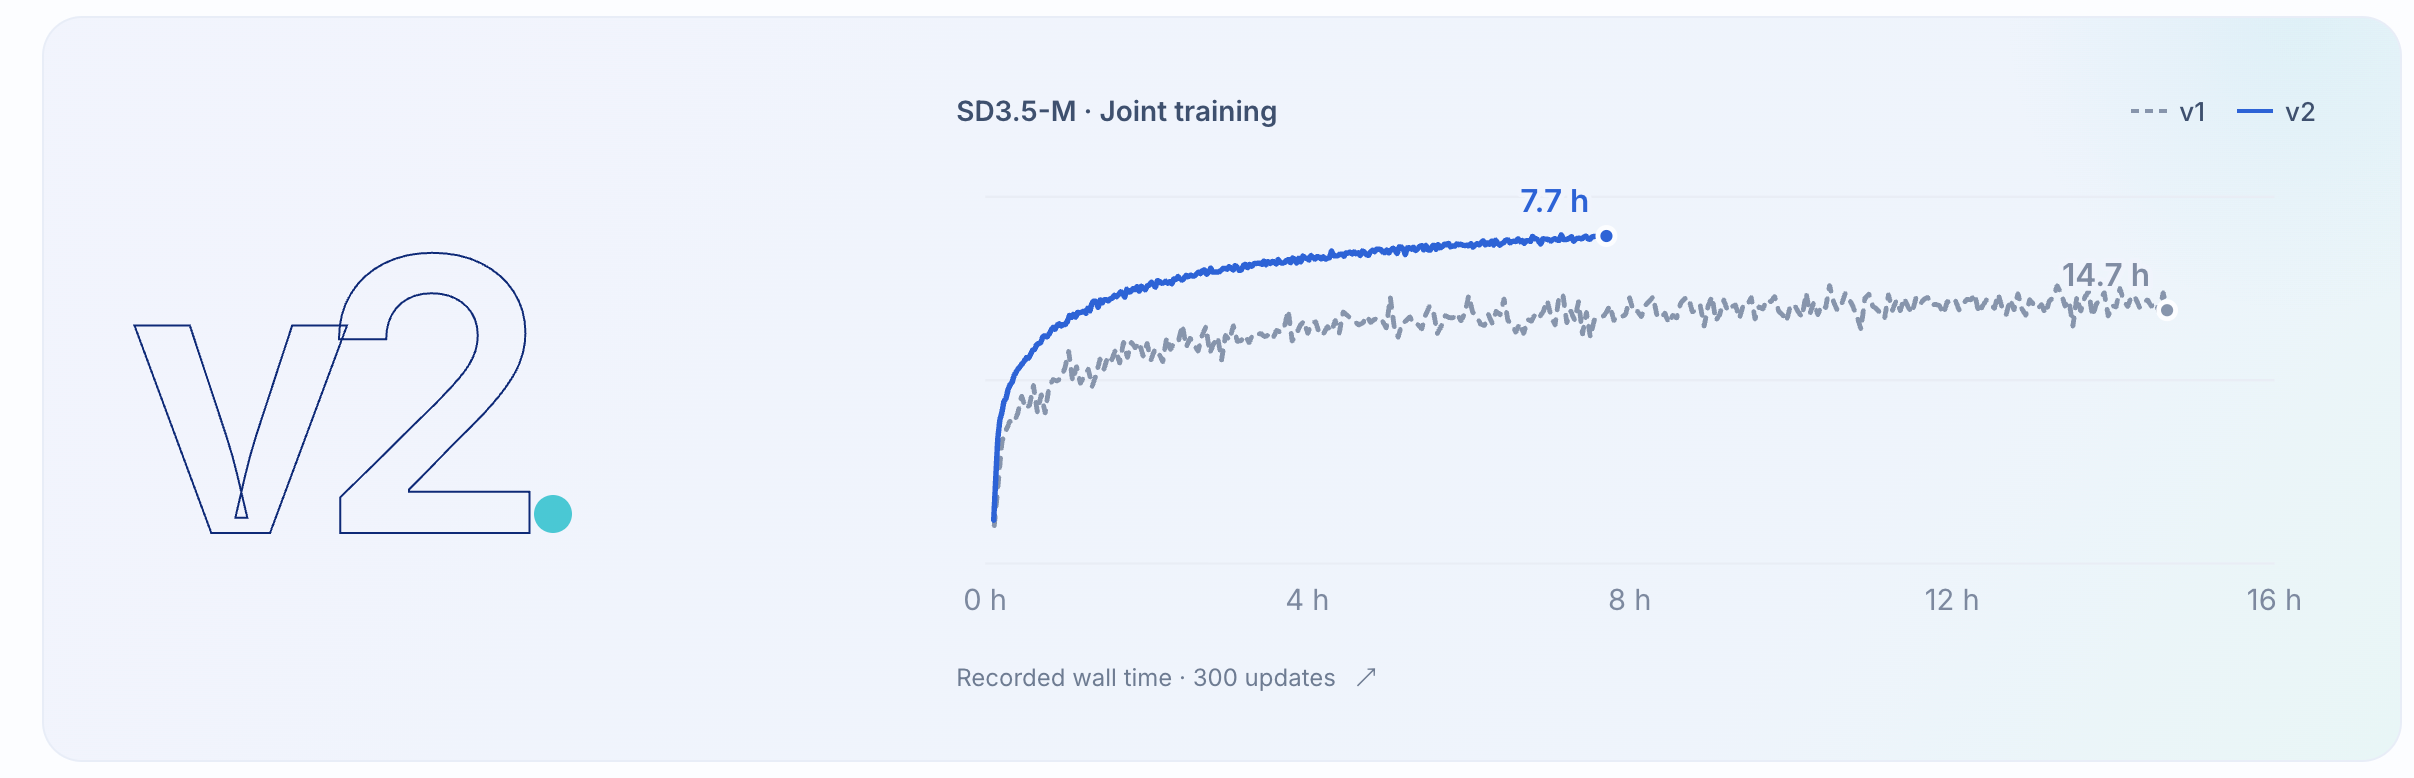
### Training efficiency
Eight-GPU profiles; initialization, calibration, and evaluation are excluded.
| Backbone | Method | Seconds / update | Peak VRAM | GPU-h / 100 updates | Relative to NFT |
|---|---|---:|---:|---:|---:|
| SD3.5-M | DiffusionNFT | 212.4 | 47.8 GB | 47.2 | 1.00× |
| SD3.5-M | **DiffusionOPSD** | **126.9** | 50.0 GB | **28.2** | **0.60×** |
| Z-Image-Turbo | DiffusionNFT | 1826.2 | 49.9 GB | 405.8 | 1.00× |
| Z-Image-Turbo | **DiffusionOPSD** | **674.0** | 61.5 GB | **149.8** | **0.37×** |
![]() |
![]() |
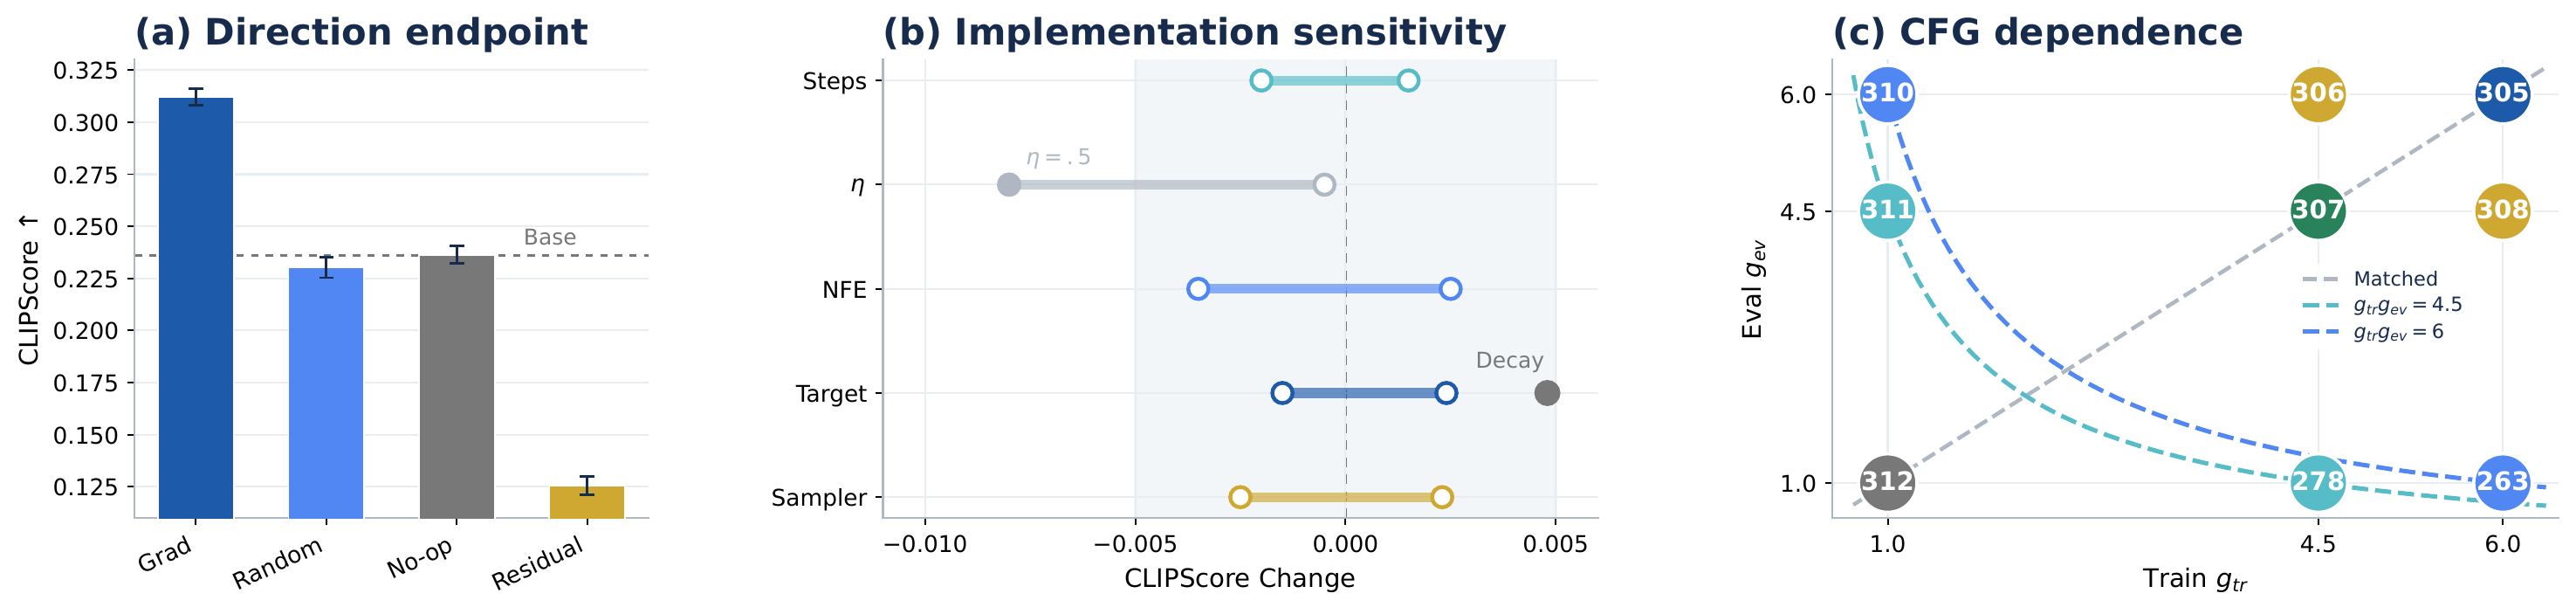
| Native training rewards across ten objectives and two backbones. | Held-out quality versus cumulative GPU-hours. |