# 📄 VDE-Bench: Visual Document Editing Benchmark
**"Edit the requested text or table. Preserve the rest of the document."**
*A comprehensive bilingual benchmark for instruction-guided image editing on dense Chinese and English documents.*
[](https://arxiv.org/abs/2602.00122)
[](https://huggingface.co/datasets/hongzhuyi/VDEBench)
[](https://huggingface.co/datasets/hongzhuyi/VDEBench)
[](https://hf-mirror.com/datasets/hongzhuyi/VDEBench)
[](./LICENSE)
**[English](README.md)** · **[Simplified Chinese](README_zh.md)**
[News](#news) · [Highlights](#key-highlights) · [Leaderboard](#leaderboard) · [Tasks & Coverage](#tasks--dataset-coverage) · [Quick Start](#quick-start) · [Citation](#citation)
---
| Total Examples | Text-Region Edits | Table-Region Edits | Languages | Task Types | Evaluation Granularity |
|:---:|:---:|:---:|:---:|:---:|:---:|
| **3,506** | **1,578** | **1,928** | **English · Chinese** | **7** | **Local · Global** |
## News
- 🚀 **2026-11-01 — Full Model Evaluation Batch Released:** Complete **Local** and **Global** evaluation results across all **3,506 examples** for six image-editing models (`FLUX.2-klein-4B`, `BAGEL-7B-MoT`, `Qwen-Image-Edit-2511`, `FireRed-Image-Edit-1.1`, `Qwen-Image-Edit-2509`, and `OmniGen2`) are now available on the [Hugging Face Leaderboard](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/README.md).
- 🤗 **2026-10-28 — Hugging Face Official Benchmark:** VDE-Bench is officially recognized as an **Official Benchmark on the Hugging Face Hub**, featuring an interactive leaderboard for both local edit-region and global full-page evaluation! 🎉 Thanks to the Hugging Face team for supporting the integration! [[Dataset & Leaderboard]](https://huggingface.co/datasets/hongzhuyi/VDEBench) · [[HF Mirror]](https://hf-mirror.com/datasets/hongzhuyi/VDEBench) · [[Official Confirmation]](https://huggingface.co/datasets/hongzhuyi/VDEBench/discussions/2#6ae1ea439ae693f8c312af8d)
## Introduction
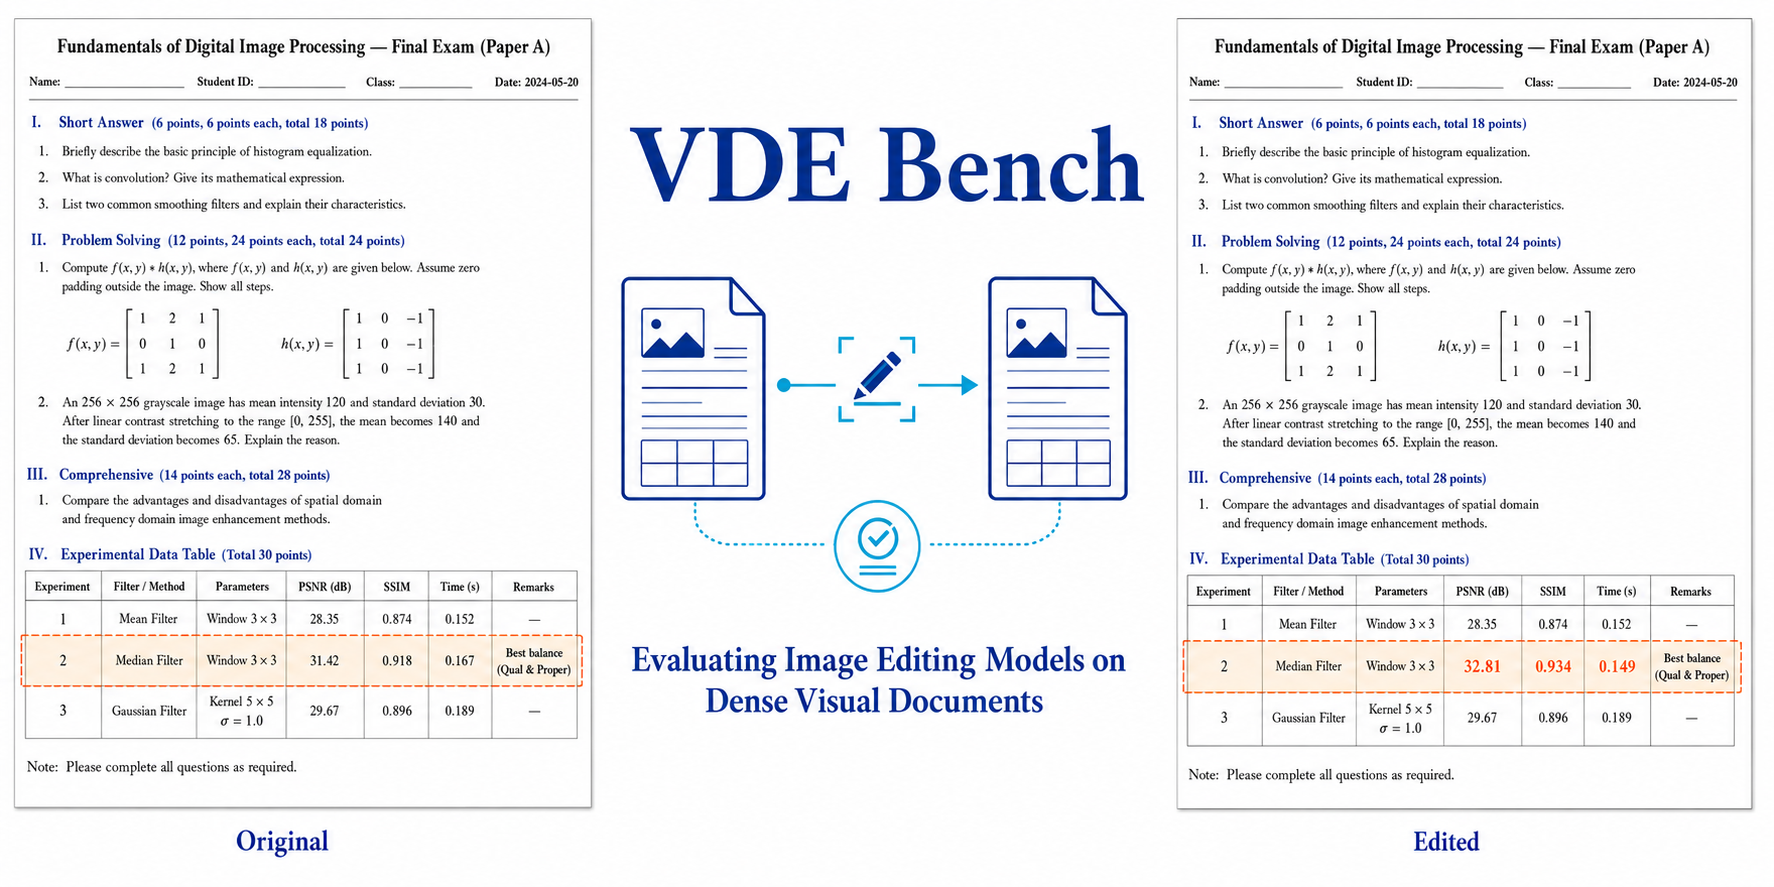
**VDE-Bench (Visual Document Editing Benchmark)** evaluates how well image-editing models follow natural-language instructions to make precise changes to **dense Chinese and English document images**. Models must locate and edit the requested text or table content while preserving the surrounding text, table structure, typography, and page layout.
The benchmark contains **3,506 instruction-guided editing examples**, comprising **1,578 text-region edits** and **1,928 table-region edits** across **seven task types**: text replacement, addition, and deletion; table text modification, addition, and deletion; and table structure editing. Each example pairs an input document image, a natural-language editing instruction, and a reference target image with annotated editing regions, changed-pixel masks, and structured OCR annotations.
## Key Highlights
- **🎯 Real-World Dense Document Scenarios:** Sourced and curated from diverse bilingual document pages (including [OmniDocBench](https://github.com/opendatalab/OmniDocBench), [DocGenome](https://huggingface.co/datasets/U4R/DocGenome), and [DocLayNet](https://github.com/DS4SD/DocLayNet)), testing fine-grained edits amidst complex layouts.
- **🧩 Seven Fine-Grained Editing Tasks:** Systematically covers **Text Replacement**, **Text Addition**, **Text Deletion**, **Table Text Modification**, **Table Text Addition**, **Table Text Deletion**, and **Table Structure Editing**.
- **⚖️ Dual-Granularity Evaluation Protocol:** Evaluates models at both the **Local (edit-region)** level—measuring whether the requested change succeeded—and the **Global (full-page)** level—measuring whether unedited context was faithfully preserved.
- **📐 Multi-Dimensional Metric Suite:** Combines OCR and structural parsing metrics (`IoU`, `CDM`, `BLEU-4`, `TEDS`) with perceptual and semantic image-quality metrics (`PSNR`, `SSIM`, `LPIPS`, `FID`, `CLIP Score`).
- **🛠️ End-to-End Open Toolkit:** Ships with Parquet dataset streaming on Hugging Face, multimodal LLM synthesis pipelines, vLLM-based OCR backend servers (`PaddleOCR-VL` and `Hunyuan OCR`), layout distribution analyzers, and human annotator agreement tools (`Fleiss' Kappa`, `Krippendorff's Alpha`).
## Leaderboard
The table below summarizes the full evaluation across all **3,506 test examples** (`default/test` split). **Local** is the headline benchmark score; both **Local** and **Global** report the equally weighted mean of four block-pooled OCR metrics: `(IoU + CDM + BLEU-4 + TEDS) / 4` on a `0–1` scale (higher is better).
| Rank | Model | Local Score ↑ *(Headline)* | Global Score ↑ | Detailed Breakdown |
|:---:|---|:---:|:---:|:---:|
| 🥇 | **[FLUX.2-klein-4B](https://huggingface.co/black-forest-labs/FLUX.2-klein-4B)** | **0.767** | **0.807** | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/flux2_klein_4b/results.json) |
| 🥈 | **[BAGEL-7B-MoT](https://huggingface.co/ByteDance-Seed/BAGEL-7B-MoT)** | **0.706** | **0.786** | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/bagel_7b_mot/results.json) |
| 🥉 | **[Qwen-Image-Edit-2511](https://huggingface.co/Qwen/Qwen-Image-Edit-2511)** | **0.656** | 0.699 | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/qwen_image_edit_2511/results.json) |
| 4 | **[FireRed-Image-Edit-1.1](https://huggingface.co/FireRedTeam/FireRed-Image-Edit-1.1)** | 0.638 | 0.750 | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/firered_image_edit_1_1/results.json) |
| 5 | **[Qwen-Image-Edit-2509](https://huggingface.co/Qwen/Qwen-Image-Edit-2509)** | 0.618 | 0.639 | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/qwen_image_edit_2509/results.json) |
| 6 | **[OmniGen2](https://huggingface.co/OmniGen2/OmniGen2)** | 0.565 | 0.581 | [JSON](https://huggingface.co/datasets/hongzhuyi/VDEBench/blob/main/results/2026-11-01/omnigen2/results.json) |
> 💡 Explore the interactive leaderboard and earlier checkpoints on the [Hugging Face Dataset Page](https://huggingface.co/datasets/hongzhuyi/VDEBench) (or via [HF-Mirror](https://hf-mirror.com/datasets/hongzhuyi/VDEBench)).
## Tasks & Dataset Coverage
All configurations expose the frozen benchmark through a single `test` split. The `default` configuration contains all **3,506** examples, while `text` and `table` provide region-specific subsets:
| Region Subset | Editing Task | Examples | Share | Primary Evaluation Focus |
|---|---|---:|---:|---|
| **Text** (`1,578`) | Text Replacement | 575 | 16.4% | Accurate character replacement & font consistency |
| **Text** (`1,578`) | Text Addition | 504 | 14.4% | Line/block insertion & local layout adaptation |
| **Text** (`1,578`) | Text Deletion | 499 | 14.2% | Clean text removal & background inpainting |
| **Table** (`1,928`) | Table Text Modification | 524 | 14.9% | In-cell text editing without breaking cell borders |
| **Table** (`1,928`) | Table Text Addition | 472 | 13.5% | Populating cells while preserving grid alignment |
| **Table** (`1,928`) | Table Text Deletion | 472 | 13.5% | Clearing cell text while maintaining table rules |
| **Table** (`1,928`) | Table Structure Editing | 460 | 13.1% | Row/column insertion, deletion, & cell merging (`TEDS`) |
| **Total** | **7 Tasks** | **3,506** | **100.0%** | **Local (edit region) + Global (full document page)** |
## Repository Contents
| Module | Directory | Description |
|---|---|---|
| **Data Generation** | `data_generation/` | Multimodal LLM pipelines for cropping, editing, instruction synthesis, and quality filtering |
| **OCR & Structure Eval** | `evaluation/ocr_eval/` | Unified text and table OCR benchmark (`IoU`, `CDM`, `BLEU-4`, `TEDS`) in Global & Local modes |
| **Image Quality Eval** | `evaluation/image_quality/` | Perceptual and semantic similarity metrics (`PSNR`, `SSIM`, `LPIPS`, `FID`, `CLIP Score`) |
| **Layout Analysis** | `evaluation/layout_analysis/` | Vision-LLM layout element extraction, heatmaps, and spatial distribution reports |
| **Annotator Agreement** | `evaluation/agreement/` | Inter-annotator reliability metrics (`Fleiss' Kappa`, `Krippendorff's Alpha`) |
| **Analysis & Reporting** | `analysis/` | Dataset distribution plots, language breakdowns, and LaTeX table generators |
| **OCR Backends** | `ocr_backends/` | Deployment scripts and clients for `PaddleOCR-VL` (via vLLM) and `Hunyuan OCR` |
## Table of Contents
- [News](#news)
- [Introduction](#introduction)
- [Key Highlights](#key-highlights)
- [Leaderboard](#leaderboard)
- [Tasks & Dataset Coverage](#tasks--dataset-coverage)
- [Repository Contents](#repository-contents)
- [Installation](#installation)
- [Repository Layout](#repository-layout)
- [Quick Start](#quick-start)
- [0. Loading the dataset from Hugging Face](#0-loading-the-dataset-from-hugging-face)
- [1. Generating the benchmark](#1-generating-the-benchmark)
- [2. Running OCR on predictions](#2-running-ocr-on-predictions)
- [3. OCR-based evaluation](#3-ocr-based-evaluation)
- [4. Image-quality evaluation](#4-image-quality-evaluation)
- [5. Layout analysis](#5-layout-analysis)
- [6. Inter-annotator agreement](#6-inter-annotator-agreement)
- [Data Format](#data-format)
- [Citation](#citation)
- [License](#license)
---
## Installation
```bash
git clone https://github.com/zion-zion-zion/VDE-Bench.git
cd VDE-Bench
# Core dependencies
pip install -r requirements.txt
# Sub-module specific dependencies (install only what you need)
pip install -r evaluation/image_quality/requirements.txt
pip install -r evaluation/layout_analysis/requirements.txt
```
Tested with **Python 3.10+**, **PyTorch 2.x**, and **CUDA 11.8 / 12.1**.
---
## Repository Layout
Click to expand/collapse full directory tree
```text
VDE-Bench/
├── data_generation/ # Scripts to build the benchmark
│ ├── prompts.py # All editing prompts (text / table / figure)
│ ├── llm_client.py # Thin OpenAI-compatible client for image-editing & text LLMs
│ ├── edit_table_crop.py # Crop+edit table regions (nano image-edit LLM)
│ ├── edit_figure_crop.py # Crop+edit figure regions
│ ├── edit_text_fullpage.py # Full-page text editing (given an instruction)
│ ├── edit_table_fullpage.py # Full-page table editing
│ ├── generate_text_instruction.py # Generate text add/delete instructions
│ ├── generate_table_instruction.py # Generate table add/delete/structure-edit instructions
│ ├── infer_instruction_from_pair.py # Infer editing instruction from (before, after) pair
│ ├── classify_instruction.py # Classify instruction into text-add / text-delete / table-structure
│ ├── pdf_to_images.py # PDF -> page images
│ ├── paste_labeled_region.py # Paste human-labeled region back into the original image
│ ├── merge_and_copy_images.py # Merge multiple info JSONs + copy & rename images
│ ├── filter_high_score_items.py # Keep only items rated 3/3 by reviewers
│ └── filter_by_id.py # Intersect two JSONs by `image_input`
│
├── evaluation/
│ ├── ocr_eval/ # Main OCR benchmark
│ │ ├── eval_unified.py # Unified text+table OCR evaluation (global / local modes)
│ │ ├── eval_text_region.py # Stand-alone text-region evaluation
│ │ ├── run_eval_ocr.sh # Example runner (global)
│ │ └── run_eval_ocr_local.sh # Example runner (local, edit-region-only)
│ │
│ ├── image_quality/ # PSNR / SSIM / LPIPS / FID / CLIP Score
│ │ ├── evaluate.py
│ │ ├── metrics.py
│ │ ├── run_eval.sh
│ │ ├── run_eval_local.sh
│ │ └── requirements.txt
│ │
│ ├── layout_analysis/ # Layout element extraction + distribution metrics
│ │ ├── main.py
│ │ ├── constants.py
│ │ ├── extraction.py
│ │ ├── metrics.py
│ │ ├── visualization.py
│ │ ├── report.py
│ │ ├── generate_heatmap.py
│ │ ├── layout_evaluation.py
│ │ ├── run_vlm.sh
│ │ └── requirements.txt
│ │
│ └── agreement/ # Inter-annotator agreement (Fleiss kappa, Krippendorff alpha)
│ ├── fleiss_kappa.py
│ ├── krippendorff_alpha.py
│ └── metrics.py
│
├── analysis/ # Paper-time analysis / table & figure generation
│ ├── plot_dataset_statistics.py
│ ├── compute_edit_type_metrics.py
│ ├── compute_edit_type_metrics_global.py
│ ├── compute_language_metrics.py
│ ├── generate_results_table.py
│ ├── ambiguify_instructions.py
│ ├── check_image_output.py
│ ├── clean_table_output.py
│ └── fix_missing_data_source.py
│
├── ocr_backends/
│ ├── paddleocr_vl/
│ │ ├── run_paddle_server.sh # vLLM-hosted PaddleOCR-VL server
│ │ └── paddle_ocr_client.py # Minimal client
│ └── hunyuan_ocr/
│ └── hunyuan_client.py
│
├── scripts/
│ └── upload_to_hf.py # Helper to push a data archive to HuggingFace
│
├── requirements.txt
├── LICENSE
├── .gitignore
├── README.md # English documentation
└── README_zh.md # Simplified Chinese documentation
```
---
## Quick Start
### 0. Loading the dataset from Hugging Face
You can stream or download the benchmark directly via `datasets` without manual archive extraction:
```python
from datasets import load_dataset
# Choose name="default" (all 3,506 items), "text" (1,578), or "table" (1,928)
ds = load_dataset(
"hongzhuyi/VDEBench",
name="default",
split="test",
streaming=True,
)
example = next(iter(ds))
print(example["id"], example["instruction"])
example["image_input"].save("input.png")
example["image_output"].save("reference.png")
```
All scripts that call a hosted (OpenAI-compatible) LLM expect the following environment variables:
```bash
export LLM_API_BASE="https://your-llm-endpoint.example.com/v1"
export LLM_API_KEY="sk-your-token-here"
```
They can also be passed as CLI flags (`--api_base`, `--api_key`). **Never hard-code credentials in source files.**
### 1. Generating the benchmark
From raw source document images and their OCR annotations (OmniDocBench format):
```bash
# (a) crop + edit each table region
python data_generation/edit_table_crop.py \
--source_json /path/to/OmniDocBench.json \
--image_root /path/to/source/images \
--output_dir outputs/table_edited \
--output_json outputs/table_edited.json \
--model gemini-3-pro-image \
--num_samples 150
# (b) generate text editing instructions, then apply them
python data_generation/generate_text_instruction.py \
--source_json /path/to/OmniDocBench.json \
--image_root /path/to/source/images \
--output_json outputs/text_instructions.json \
--model gemini-2.5-flash
python data_generation/edit_text_fullpage.py \
--instruction_json outputs/text_instructions.json \
--output_dir outputs/text_edited \
--output_json outputs/text_edited.json \
--model gemini-3-pro-image
```
### 2. Running OCR on predictions
```bash
# Option A: PaddleOCR-VL via vLLM
bash ocr_backends/paddleocr_vl/run_paddle_server.sh # starts server on :8118
python ocr_backends/paddleocr_vl/paddle_ocr_client.py \
--image_dir /path/to/predicted_images \
--output_dir /path/to/predicted_ocr
```
### 3. OCR-based evaluation
Evaluate on *both* text and table edits in one pass:
```bash
bash evaluation/ocr_eval/run_eval_ocr.sh \
\
/path/to/_text_ocr \
/path/to/_table_ocr
```
For *local* (edit-region-only) evaluation, use the human-labeled bboxes:
```bash
bash evaluation/ocr_eval/run_eval_ocr_local.sh \
\
/path/to/_text_ocr \
/path/to/_table_ocr
```
Metrics reported per block and in aggregate:
| Metric | Level | Notes |
|--------|-------|-------|
| IoU | block | over `matched ∪ unmatched_gt` blocks |
| CDM | block | Character-level Detection Match, over matched blocks only |
| BLEU | block | BLEU over matched blocks only |
| TEDS | block | Table-only, over matched blocks only |
### 4. Image-quality evaluation
```bash
python evaluation/image_quality/evaluate.py \
--groups \
text \
table \
--padding 0 --device cuda \
--output_json results_iq.json
```
Pass `none` in place of the info-JSON to run in global (full-image) mode.
### 5. Layout analysis
```bash
# (a) host a vision LLM for element extraction (vLLM example)
bash evaluation/layout_analysis/run_vlm.sh
# (b) run the pipeline
python evaluation/layout_analysis/main.py run \
--image_dir /path/to/document_images \
--output_dir ./layout_results \
--model vlm --port 63332
```
### 6. Inter-annotator agreement
```bash
python evaluation/agreement/fleiss_kappa.py \
--input ratings.json \
--dimensions spatial textual style
python evaluation/agreement/krippendorff_alpha.py \
--input ratings.json
```
---
## Data Format
**Editing item** JSON (the format of each benchmark entry):
```json
{
"id": 48234,
"image_input": "inputs/_page_.jpg",
"image_output": "outputs/_page__modified.png",
"instruction": "Delete the text \"Win on cost and scale\" from the sub-header.",
"instruction type": "text deletion",
"language": "english",
"data_source": "eastmoney",
"label_output": [
{"x": 12.3, "y": 4.1, "width": 30.0, "height": 4.5}
]
}
```
- `label_output` bboxes are percentages relative to the edited image.
- See `evaluation/ocr_eval/eval_unified.py` for exact matching rules.
---
## Citation
If you find VDE-Bench useful, please cite:
```bibtex
@article{yi2026vdebench,
title = {VDE Bench: Evaluating The Capability of Image Editing Models to Modify Visual Documents},
author = {Yi, Hongzhu and Yang, Yujia and Wang, Yuanxiang and Li, Tong and Guan, Zhenyu and Zong, Tianyu and Chen, Jiahuan and Bao, Chenxi and Yang, Tiankun and Jin, Haopeng and Yuan, Yixuan and Wang, Xinming and Yu, Tao and Gao, Ruilin and Tao, Ruiwen and Liang, Haijin and Ma, Jin and Luo, Jinwen and Yeshani and Zuo, Xinyu and Xu, Jungang},
journal = {arXiv preprint arXiv:2602.00122},
year = {2026},
url = {https://arxiv.org/abs/2602.00122}
}
```
---
## License
This project is released under the [Apache License 2.0](./LICENSE).
The underlying document data may be subject to separate licenses from their respective source datasets (e.g. OmniDocBench). Please consult those repositories before redistribution.