中文 | English


🖥️ Interactive Demo | 🌐 Project Website | 📄 Technical Report
## 🔥 News - 🤝 **Oct 26, 2026 — Community integrations:** Run Hy-Nomas with [SGLang](https://github.com/sgl-project/sglang/pull/46124), [ComfyUI](https://github.com/PedroMarinhoDev/ComfyUI-Hy-Nomas), or [Reactor Runtime](reactor/README.md). See [Community Contributions](#-community-contributions) for details. - 📄 **Oct 26, 2026 — Technical report:** Updated the [Hy-Nomas technical report](https://github.com/Tencent-Hunyuan/Hy-Nomas/blob/main/Hy_Nomas_Tech_Report.pdf). - 🌍 **Oct 25, 2026 — WanGP support:** [WanGP v18.81](https://github.com/deepbeepmeep/WanGP), by [@deepbeepmeep](https://x.com/deepbeepmeep), adds Hy-Nomas world generation with keyboard exploration and text-driven events. See the [announcement](https://x.com/deepbeepmeep/status/2114503683295662230) and [integration commit](https://github.com/deepbeepmeep/WanGP/commit/c4d3efce4cd896c6e14fcb82787577bfc3181b99). - 🛠️ **Oct 23, 2026 — Diffusers inference:** Added a [Diffusers inference example](#inference-with-diffusers). - 🎮 **Oct 21, 2026 — Interactive demo:** Explore multi-turn text and camera control in the [online demo](https://hy-nomas.hy.tencent.com/demo), or follow the [deployment guide](apps/README.md) to run it yourself. - 🚀 **Oct 21, 2026 — Initial code release:** Training and inference code include [LoRA fine-tuning](#lora-fine-tuning) and [single-GPU inference](#inference-with-low-mem-gpu). Get the [model weights](https://huggingface.co/tencent/Hy-Nomas) to start exploring. ## 🎥 Demo https://github.com/user-attachments/assets/e7a2528c-4ccc-461c-8f09-207650f1f0bd ## 🧩 Community Contributions If you develop/use Hy-Nomas in your projects, welcome to let us know. - **WanGP** — [WanGP](https://github.com/deepbeepmeep/WanGP), by [@deepbeepmeep](https://x.com/deepbeepmeep): Hy-Nomas support in v18.81 provides text-to-world generation, keyboard navigation and camera control, text-driven events, and adjustable history memory. Explorations can be saved and resumed or recorded as videos. See the [announcement](https://x.com/deepbeepmeep/status/2114503683295662230) and [integration commit](https://github.com/deepbeepmeep/WanGP/commit/c4d3efce4cd896c6e14fcb82787577bfc3181b99). - **SGLang** — [SGLang Diffusion](https://github.com/sgl-project/sglang), by [@sgl_project](https://x.com/sgl_project): Hy-Nomas support is merged into `main`, covering offline video jobs and real-time streaming sessions. See the [integration PR](https://github.com/sgl-project/sglang/pull/46124). - **ComfyUI** — [ComfyUI-Hy-Nomas](https://github.com/PedroMarinhoDev/ComfyUI-Hy-Nomas), by [@LatentSpacer](https://x.com/LatentSpacer): A community integration with chained video segments and interactive WASD camera control. - **Reactor Runtime** — [Hy-Nomas integration guide](reactor/README.md), contributed by [@Rising0321](https://github.com/Rising0321): A streaming service and browser demo with live prompt updates, WASD/arrow camera control, and uploaded camera trajectories while retaining world history. See the [integration PR](https://github.com/Tencent-Hunyuan/Hy-Nomas/pull/3). Thank you to the contributors for building on Hy-Nomas! Building with Hy-Nomas? We welcome community projects, integrations, tutorials, and LoRA adapters. Share your work by [opening an issue](https://github.com/Tencent-Hunyuan/Hy-Nomas/issues) or submitting a pull request to add it to this section. Contributions to this repository are covered in the [contribution guide](CONTRIBUTING.md). --- ## Table of Contents - [🔥 News](#-news) - [🎥 Demo](#-demo) - [🧩 Community Contributions](#-community-contributions) - [Model Introduction](#model-introduction) - [Key Features](#key-features) - [Usage](#usage) - [Environment Setup](#environment-setup) - [Model Assets](#model-assets) - [Inference](#inference) - [Inference with Source Code](#inference-with-source-code) - [Inference with Low-Mem GPU](#inference-with-low-mem-gpu) - [Inference with Diffusers](#inference-with-diffusers) - [Interactive Demo](#interactive-demo) - [Reactor Runtime](#reactor-runtime) - [Web Demo](#web-demo) - [LoRA Fine-Tuning](#lora-fine-tuning) - [SFT Data Preparation](#sft-data-preparation) - [Offline Sequence Packing](#offline-sequence-packing) - [Training and Merging](#training-and-merging) - [Contributing](CONTRIBUTING.md) - [Security](SECURITY.md) - [License](#license) - [Contact Us](#contact-us) --- ## Model Introduction **Hy-Nomas** is a free-form interactive video world generation model. It supports free-form multi-turn text prompt control or camera control. This repository provides the training, inference, interactive demo, and data annotation code. ## Key Features - **Segment-based generation:** Autoregressive segment-wise world generation controlled by either segment level prompt or camera control signal, maintaining a lifelong KV cache for consistency. - **Free-form Prompt Control:** Control the world generation with any kind of free form user prompt to generate imaginary object, style, scene, and actions. - **Camera control:** Condition generation on camera trajectories alongside text prompts. - **Distilled inference:** Inference uses 4-8 denoising steps and a finetuned PixelUMM decoder for 32-channel DCAE-V latents. - **Interactive demo:** A web interface supports generation across multiple turns and decoding at segment boundaries. - **Fine-tuning and data preparation:** Lora fine-tuning with customized video dataset, and prepare training data from local videos with our annotation workflow. ## Usage ### Environment Setup Choose one of the following two setup options. **We strongly recommend the pre-packaged Docker image**, which provides the Python environment, PyTorch, and the required CUDA attention kernels together. #### Option 1: Pre-packaged Docker Image (Recommended) Prepare a Linux host with a compatible NVIDIA driver, Docker, and NVIDIA Container Toolkit. Run these commands from the repository root: ```bash export HY_NOMAS_IMAGE="hynomasoss/hynomasoss:cu130" docker pull "$HY_NOMAS_IMAGE" docker run --rm -it --gpus all --ipc=host --network=host \ -v "$PWD:/workspace/Hy-Nomas" \ -w /workspace/Hy-Nomas \ "$HY_NOMAS_IMAGE" bash ``` Run the remaining commands inside the container, using its pre-installed Python environment. Place model assets under the mounted repository or add a volume mount for your model directory; use the paths visible inside the container in the launch commands below. #### Option 2: Manual Installation Prepare Linux, Python 3.12+, uv, a compatible NVIDIA driver, the CUDA 13.0 Toolkit (`nvcc`), and a C++ compiler. Run the following from the repository root: ```bash uv sync --extra all source .venv/bin/activate ``` The `all` extra includes PyTorch 2.10.0 (CUDA 13.0), FlashAttention 2, FlashAttention 3, and MagiAttention. `pyproject.toml` configures the PyTorch CUDA index, the official FA3 source, and disables build isolation for the attention kernels so their builds can use the environment's PyTorch. Kernel compilation may take some time. ### Model Assets The model repository contains DiT generation models, LoRA adapters, video autoencoders and decoders, and Nomas-PE for online prompt enhancement. Download all model weights from `tencent/Hy-Nomas` on Hugging Face, preserving the repository directory structure: ```bash export Hy_Nomas_Model_Path=/path/to/Hy-Nomas hf download tencent/Hy-Nomas --local-dir "${Hy_Nomas_Model_Path}" ``` Set `Hy_Nomas_Model_Path` to your download directory once. The commands below reuse its existing value, defaulting to `/path/to/Hy-Nomas` in a new shell. Click a model name below to view its files on Hugging Face. | Category | Model asset | Purpose | |:---|:---|:---| | DiT | **[Base autoregressive DiT (FP32)](https://huggingface.co/tencent/Hy-Nomas/tree/main/DiT/base_ar)** | Non-distilled checkpoint for segment forcing LoRA fine-tuning. | | DiT | **[Distilled DiT (FP32)](https://huggingface.co/tencent/Hy-Nomas/tree/main/DiT/distilled)** | Checkpoint for fast, 4/6/8-step inference and the interactive demo. Also serves as the base for merging fine-tuned LoRA adapters. | | DiT | **[Quantized Distilled DiT (INT8)](https://huggingface.co/tencent/Hy-Nomas/tree/main/DiT/distilled_int8)** | Quantized checkpoint for low-memory inference, including single-GPU deployment. | | DiT | **[Cinematic LoRA](https://huggingface.co/tencent/Hy-Nomas/tree/main/DiT/lora_weights/cinematic)** | LoRA adapter using cinematic data, to be merged into the distilled DiT to enhance the visual quality of generated worlds. | | DiT | **[Robotics LoRA](https://huggingface.co/tencent/Hy-Nomas/tree/main/DiT/lora_weights/dual_arm_robotics)** | LoRA adapter trained on the [RealSource-World](https://huggingface.co/datasets/RealmanRobot/RealSource-World) real-world robotic-arm dataset, to be merged into the distilled DiT to enhance the robotics simulation capability of generated worlds. | | VAE | **[DCAE-V](https://huggingface.co/tencent/Hy-Nomas/tree/main/VAE/DCAE-V)** | Video autoencoder for encoding training videos into latents and decoding them. | | VAE | **[Fine-tuned PixelUMM Decoder](https://huggingface.co/tencent/Hy-Nomas/tree/main/VAE/PixelUMM_FT)** | Decoder for turning generated DCAE-V latents into video frames. | | VAE | **[Quantized PixelUMM Decoder (FP8)](https://huggingface.co/tencent/Hy-Nomas/tree/main/VAE/PixelUMM_FT_FP8)** | Decoder with FP8 weights for lower memory use and accelerated decoding. | | PE | **[Nomas-PE](https://huggingface.co/tencent/Hy-Nomas/tree/main/PE)** | Online prompt-enhancement model used by the interactive demo to convert user instructions into structured generation prompts. | ### Inference #### Inference with Source Code Run from the repository root with `configs/experiment/inference.yaml`, overriding the model paths, prompt file, and output directory: ```bash export Hy_Nomas_Model_Path="${Hy_Nomas_Model_Path:-/path/to/Hy-Nomas}" bash scripts/inference/inference_from_config.sh configs/experiment/inference.yaml \ dit_weight="${Hy_Nomas_Model_Path}/DiT/distilled/diffusion_pytorch_model_ema_0_995.safetensors" \ model.vae.checkpoint="${Hy_Nomas_Model_Path}/VAE/PixelUMM_FT/diffusion_pytorch_model.safetensors" \ inference.prompt=/path/to/prompts.json \ inference.save_path=./outputs/distill ``` #### Inference with Low-Mem GPU **Hy-Nomas supports inference on a single NVIDIA GeForce RTX 4090** with `configs/experiment/single_gpu_low_mem_inference.yaml`. This configuration reduces GPU memory use through: - **INT8 DiT weights and KV cache:** Store weights and cached keys/values in INT8 while retaining BF16 computation for DiT linear layers and attention. - **Sliding-window history:** Bound the retained context instead of letting the KV cache grow with every segment. - **CPU offload:** Move the text encoder, DiT, and VAE onto the GPU for their respective processing stages and return them to CPU afterward. - **Single-GPU kernels:** Use FlexAttention for the DiT and CUTLASS FP8 for decoding, with sequence parallelism disabled (`sp_size=1`). Use a compatible INT8 DiT checkpoint and FP8 decoder checkpoint. Run on a host or container exposing one GPU to `nvidia-smi`: ```bash export Hy_Nomas_Model_Path="${Hy_Nomas_Model_Path:-/path/to/Hy-Nomas}" bash scripts/inference/inference_from_config.sh configs/experiment/single_gpu_low_mem_inference.yaml \ dit_weight="${Hy_Nomas_Model_Path}/DiT/distilled_int8/diffusion_pytorch_model_ema_0_995_int8.safetensors" \ model.vae.checkpoint="${Hy_Nomas_Model_Path}/VAE/PixelUMM_FT_FP8/diffusion_pytorch_model_fp8.safetensors" \ inference.prompt=/path/to/prompts.json \ inference.save_path=./outputs/single_gpu ``` CPU offload requires enough system RAM for the models and adds CPU–GPU transfer overhead. Peak GPU memory depends on resolution and segment length. #### Inference with Diffusers Upgrade your diffusers to use `HyNomasModularPipeline`. ```bash pip install -e "diffusers[hy-nomas] @ git+https://github.com/jiaxiangc/diffusers.git@hy-nomas" ``` Hy-Nomas supports multi-turn interactive generation. This example generates two five-second segments. ```python import json import torch from diffusers import HyNomasModularPipeline from diffusers.utils import export_to_video pipe = HyNomasModularPipeline.from_pretrained("tencent/Hy-Nomas-Diffusers") pipe.load_components(dtype=torch.bfloat16) pipe.to(device="cuda", dtype=torch.bfloat16) # Use the FlashAttention and MagiAttention kernels installed with Hy-Nomas. pipe.transformer.enable_reference_attention(text_backend="flash_varlen", deterministic=True) prompts = [ { "Style": "Cinematic fantasy", "perspective_view": "Third-person view", "subject_list": [{ "subject_id": "fox", "display_name": "a small orange fox", "subject_attribute": "Orange fur, white chest, and a fluffy tail.", }], "segments": [{ "visual_description_long": ( "A small orange fox stands on a stone path in a luminous forest. " "Blue fireflies drift between the trees." ), "contained_actions": [{ "start_time": "00:00.000", "end_time": "00:05.000", "action_description": "The fox walks slowly along the path.", }], }], }, { "segments": [{ "description_change": "Glowing blue flowers open beside the path as the fox continues forward.", "contained_actions": [{ "start_time": "00:00.000", "end_time": "00:05.000", "action_description": "The fox passes the flowers and looks around.", }], }], }, ] videos = pipe( prompt=[json.dumps(prompt) for prompt in prompts], height=704, width=1280, num_frames=240, segment_latent_lengths=[30, 30], fps=24, num_inference_steps=4, generator=torch.Generator("cpu").manual_seed(42), output="videos", ) export_to_video(videos[0], "hy_nomas_video.mp4", fps=24, quality=None) ``` ### Interactive Demo #### Reactor Runtime The [Reactor integration guide](reactor/README.md) provides a streaming service and browser demo with live prompt updates, combined WASD/arrow camera control, and uploaded camera trajectories while retaining world history. The tested profile uses eight B200 GPUs, Docker with NVIDIA Container Toolkit, the [Reactor CLI](https://docs.reactor.inc/deploy/platform/installation), and Node.js 22. From this repository root: ```bash cd reactor reactor build reactor run --gpus '"device=0,1,2,3,4,5,6,7"' --shm-size 8g --port 8080 ``` Wait for `curl -fsS http://localhost:8080/health` to report `available`. In another terminal, from the repository root: ```bash cd reactor/demo npm ci npm run dev -- --port 5173 ``` Open **http://localhost:5173**, use Runtime endpoint **http://localhost:8080**, press **Connect**, enter a prompt, then press **Start world**. Click the video to explore with WASD and arrow keys. **Update prompt** changes future segments without restarting. See the [SSH and WebRTC guidance](reactor/README.md#remote-servers-and-ssh) when the GPU runs remotely. #### Web Demo Try the [online interactive demo](https://hy-nomas.hy.tencent.com/). See the [demo deployment guide](apps/README.md) for launching the web gateway and GPU workers, configuring model assets, and running on one or multiple hosts. The demo uses `configs/experiment/inference.yaml` by default. ## LoRA Fine-Tuning ### SFT Data Preparation Use the [captioning-harness](captioning_harness/README.md) to prepare training data from local videos. It annotates each segment, encodes video frames with DCAE-V, and packages the result as an Arrow or Parquet file for SFT. See the guide for serving K3, running annotation and packing, and attaching normalized camera trajectories. ### Offline Sequence Packing Build a packing plan from the encoded training file. Run from the repository root: ```bash python scripts/data_processing/build_sft_packing_plan.py \ --input /path/to/train.arrow \ --output /path/to/train_packing.json \ --max-seq-len 360000 \ --num-groups 16 \ --seed 42 ``` This example creates 16 groups for DP16 × SP8 (128 GPUs). Choose a group count that is a multiple of your data-parallel degree, does not exceed the sample count, and has enough capacity under `--max-seq-len`. Use the same training file and row order in the training command, and pass the output JSON as `dataset.token_packing_sorted_groups_path`. See [Sequence Packing](captioning_harness/README.md#offline-sequence-packing) for details. ### Training and Merging LoRA fine-tuning starts from a **non-distilled checkpoint** and uses segment forcing training pipeline. After training, merge the learned LoRA weights into the corresponding **distilled checkpoint** to produce a new merged checkpoint for inference. 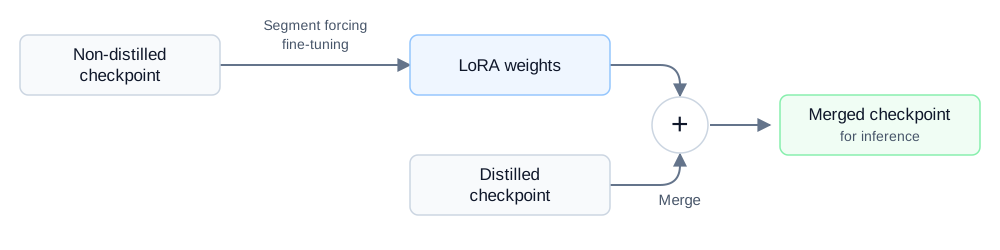 `configs/experiment/sft.yaml` enables LoRA with rank/alpha 256, zero dropout, and Muon at a constant learning rate of `1e-4` for 2,000 steps. Only LoRA parameters are trained. ```bash export Hy_Nomas_Model_Path="${Hy_Nomas_Model_Path:-/path/to/Hy-Nomas}" bash scripts/train/train_from_config.sh configs/experiment/sft.yaml \ dit_weight="${Hy_Nomas_Model_Path}/DiT/base_ar/diffusion_pytorch_model_fp32.safetensors" \ model.vae.checkpoint="${Hy_Nomas_Model_Path}/VAE/DCAE-V/dc-ae-v-1.0-f32t4c32-bf16.pt" \ dataset.data_file=/path/to/train.arrow \ dataset.token_packing_sorted_groups_path=/path/to/train_packing.json \ output_dir=./outputs/segment_lora ``` The training configuration uses SP8; 128 GPUs give DP16 × SP8. Set the launch size for your hardware and build the packing plan for the corresponding data-parallel degree. Export the saved LoRA checkpoint, then merge it into the distilled checkpoint with matching architecture and parameter shapes: ```bash export Hy_Nomas_Model_Path="${Hy_Nomas_Model_Path:-/path/to/Hy-Nomas}" python -m scripts.train.export_lora_checkpoint \ ./outputs/segment_lora/checkpoints/global_step-2000 \ ./outputs/segment_lora/adapter python -m scripts.train.merge_lora \ --base "${Hy_Nomas_Model_Path}/DiT/distilled/diffusion_pytorch_model_ema_0_995.safetensors" \ --adapter ./outputs/segment_lora/adapter \ --output ./outputs/merged_model.safetensors ``` Use `dit_weight=./outputs/merged_model.safetensors` in the [inference command](#inference). ## License This project is licensed under the [Apache License 2.0](LICENSE). ## Acknowledgement We thank the teams behind [Gemma 4](https://deepmind.google/models/gemma/gemma-4/), [Qwen3.8](https://qwen.ai/blog?id=qwen3.8), [Kimi-K3](https://github.com/MoonshotAI/Kimi-K3), [DCAE-V](https://github.com/dc-ai-projects/DC-Gen), and [MagiAttention](https://github.com/SandAI-org/MagiAttention) for their valuable contributions to the community and the models, research, and tools that support this project. ## Contact Us For questions, non-security bug reports, or suggestions, please open an issue in this repository or contact us at [hy_nomas@tencent.com](mailto:hy_nomas@tencent.com). See [CONTRIBUTING.md](CONTRIBUTING.md) for contribution guidance. Report suspected vulnerabilities privately using [SECURITY.md](SECURITY.md). ---Hy-Nomas · Free-Form Interactive World Generation.