# UI-S1: Advancing GUI Automation via Semi-online Reinforcement Learning
[[📖 Paper](https://arxiv.org/abs/2509.11543)] [[🤗 UI-S1-7B](https://huggingface.co/mPLUG/UI-S1-7B)] [[🤗 Daily Paper](https://huggingface.co/papers/2509.11543)] [[🤗 Dataset](https://huggingface.co/datasets/mPLUG/UI_S1_dataset)]
## 🔥 Overview
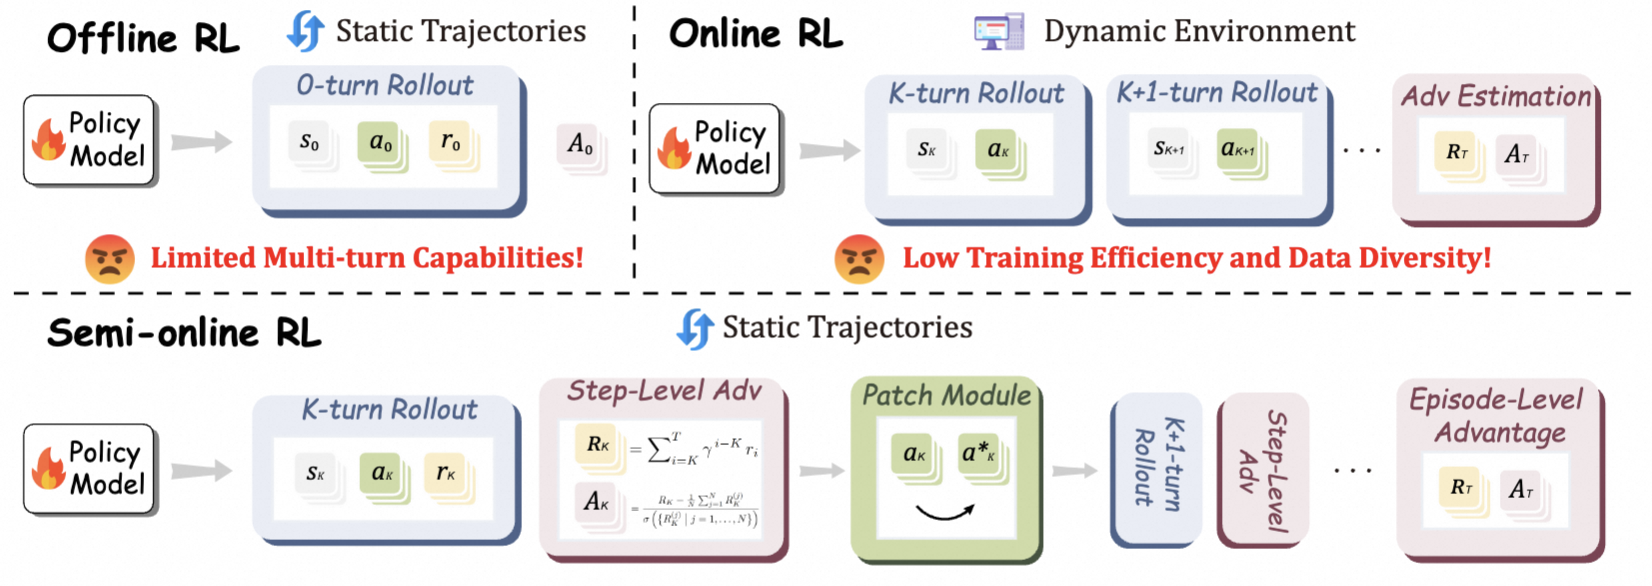
We present **Semi-online RL**, a novel paradigm that simulates online reinforcement learning using offline trajectories, thereby enabling the efficient training of MLLM-based GUI agents with enhanced multi-turn interaction capabilities.
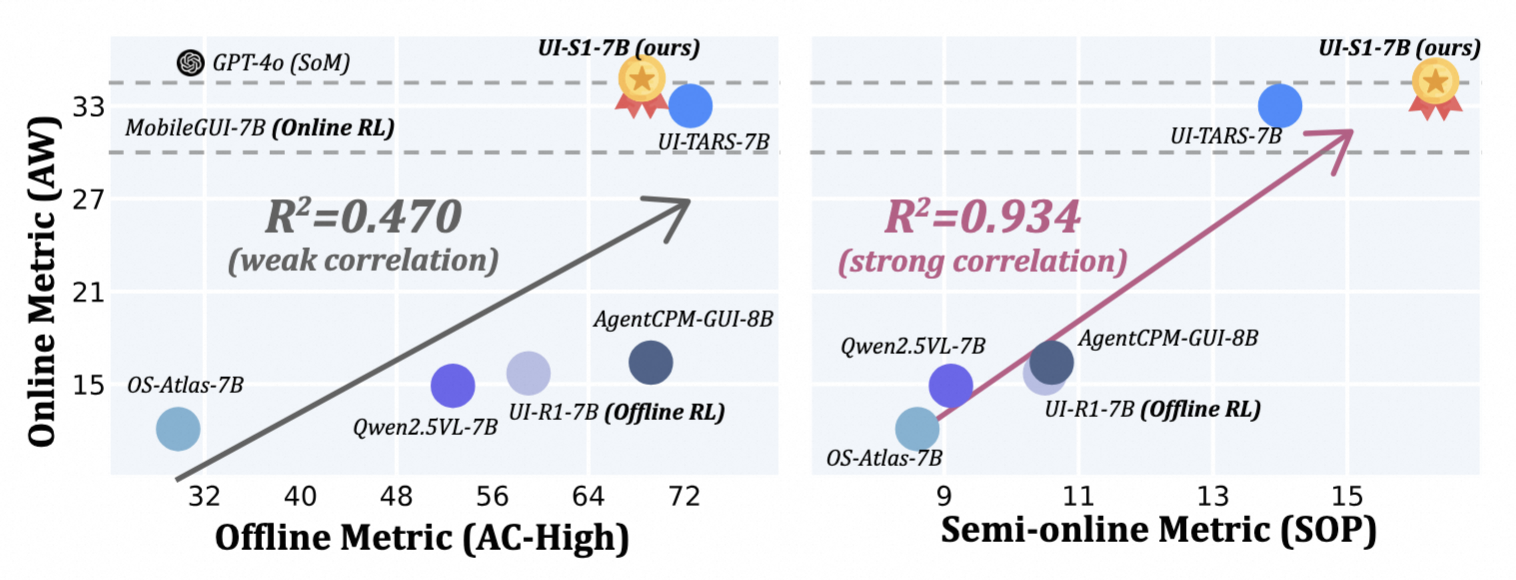
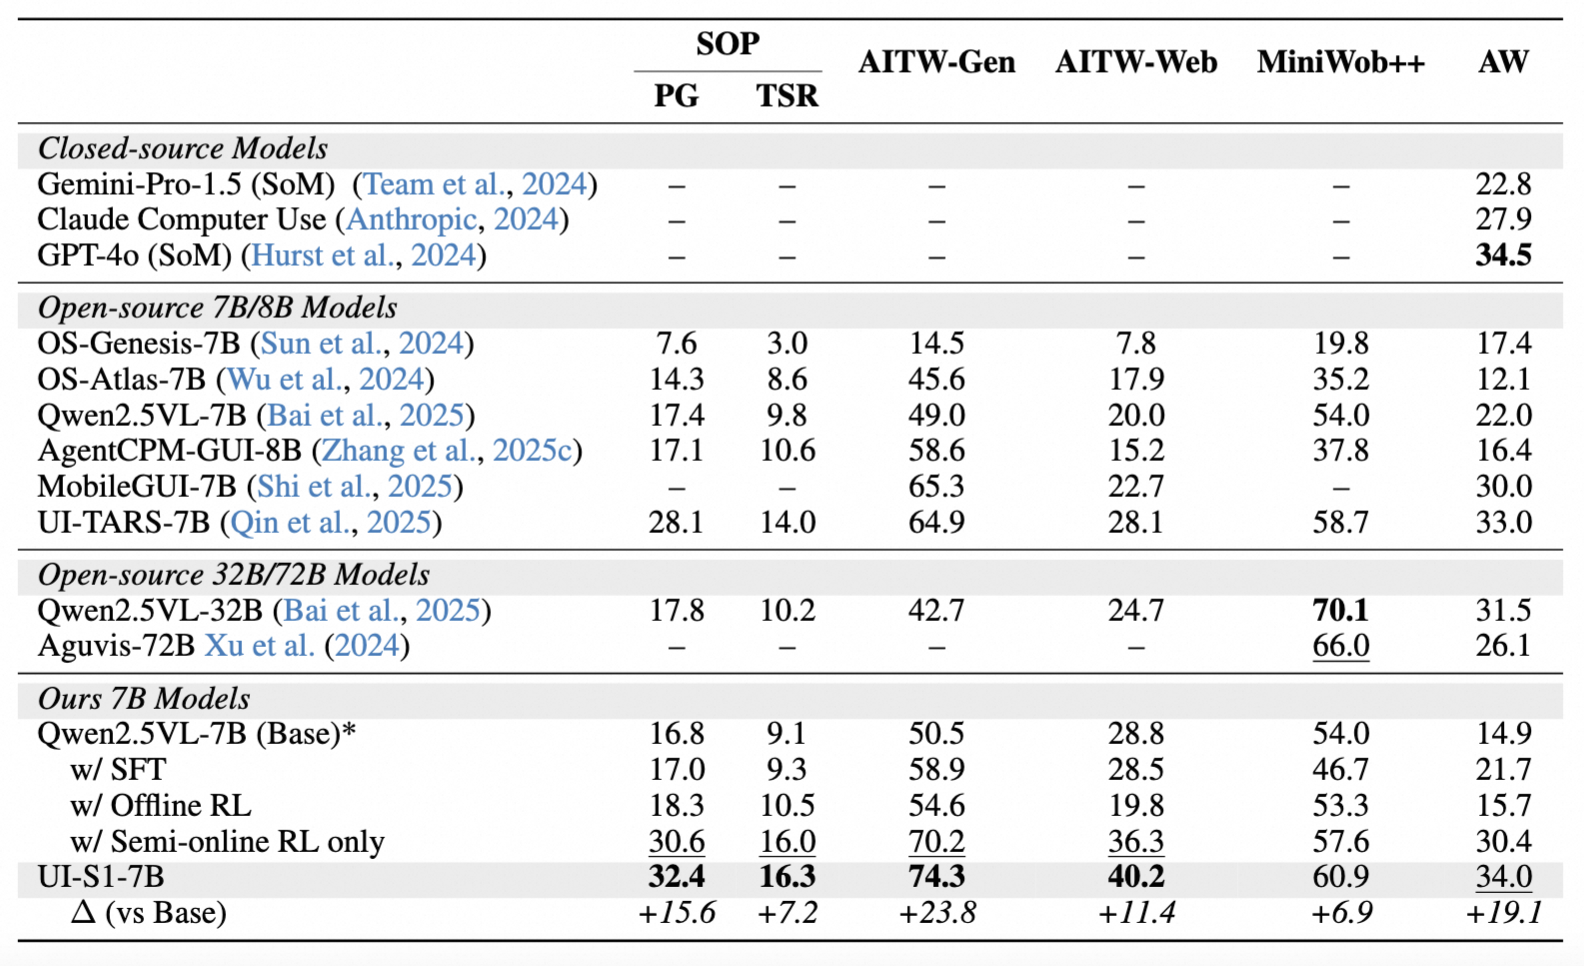
Ours UI-S1-7B achieves SOTA performance on both semi-online metric (SOP) and online metric (AndroidWorld) among open-source 7B models.
## 🗞️ News
- **`2025-04-06`**: 🔥 UI-S1 was accepted by **ACL 2026 main conference**.
- **`2025-10-28`**: We release part of our training [dataset](https://huggingface.co/datasets/mPLUG/UI_S1_dataset).
- **`2025-09-17`**: We release the UI-S1 training and evaluation code.
- **`2025-09-16`**: We release the [checkpoints](https://huggingface.co/mPLUG/UI-S1-7B) of UI-S1-7B model.
- **`2025-09-16`**: We release our [paper](https://arxiv.org/abs/2509.11543).
## Detailed results
## Setup
```shell
conda create -n ui-s1 python=3.11
conda activate ui-s1
cd UI-S1
pip install -e .
pip install vllm==0.8.2
pip install flash-attn==2.7.4.post1 --no-build-isolation
# or Installed wheel from https://github.com/Dao-AILab/flash-attention/releases/tag/v2.7.4.post1
# pip install flash_attn-2.7.4.post1+cu12torch2.6cxx11abiFALSE-cp311-cp311-linux_x86_64.whl
```
We use swanlab for training visulization. Replace your own swanlab api key and host in verl/utils/tracking.py
## Data
1. Download AndroidControl into datasets/AndroidControl/images and datasets/android_control_train_example.jsonl
2. **[New]** We also offer 1000 training examples on [Dataset](https://huggingface.co/datasets/mPLUG/UI_S1_dataset).
## Train
```shell
bash scripts/train_example.sh
python scripts/model_merger.py merge --local_dir checkpoints/XXX
```
## Inference and evaluation
```shell
# 1. Launch the vLLM server
vllm serve /checkpoints-7B --served-model-name UI-S1-7B --tensor_parallel_size 1 --trust-remote-code --limit-mm-per-prompt image=2
# 2. Evaluate UI-S1-7B's performance on SOP
python /evaluation/eval_qwenvl.py --model_name UI-S1-7B
# Evaluate other models
python /evaluation/eval_qwenvl.py --model_name Qwen2.5-VL-7B
python /evaluation/eval_agentcpm.py --model_name AgentCPM-GUI-8B
python /evaluation/eval_os-atlas-7b.py --model_name OS-Atlas-7B
python /evaluation/eval_os-genesis-7b.py --model_name OS-Genesis-7B
python /evaluation/eval_ui-tars-7b.py --model_name UI-TARS-7B
```
## ⭐️ Citation
If you find this project useful, welcome to cite us.
```bit
@article{lu2025ui,
title={UI-S1: Advancing GUI Automation via Semi-online Reinforcement Learning},
author={Lu, Zhengxi and Ye, Jiabo and Tang, Fei and Shen, Yongliang and Xu, Haiyang and Zheng, Ziwei and Lu, Weiming and Yan, Ming and Huang, Fei and Xiao, Jun and others},
journal={arXiv preprint arXiv:2509.11543},
year={2025}
}
```
## 🤝 Acknowledgements
We sincerely thank projects [verl](https://github.com/volcengine/verl) and [verl-agent](https://github.com/langfengQ/verl-agent).