# Independent Third-Party Evaluation of Billion Context (`v0.1.202`)
English | 中文
> **1,500-Item Cross-Benchmark Evaluation across LongMemEval-S, ContextBench, and MemoryAgentBench**
> comparing **Billion Context (`bc`)** against **`full`** (raw baseline) and 3 RAG pipelines (**`bm25`**, **`embedding`**, **`embedding-rerank`**).
---
## 1. Executive Summary
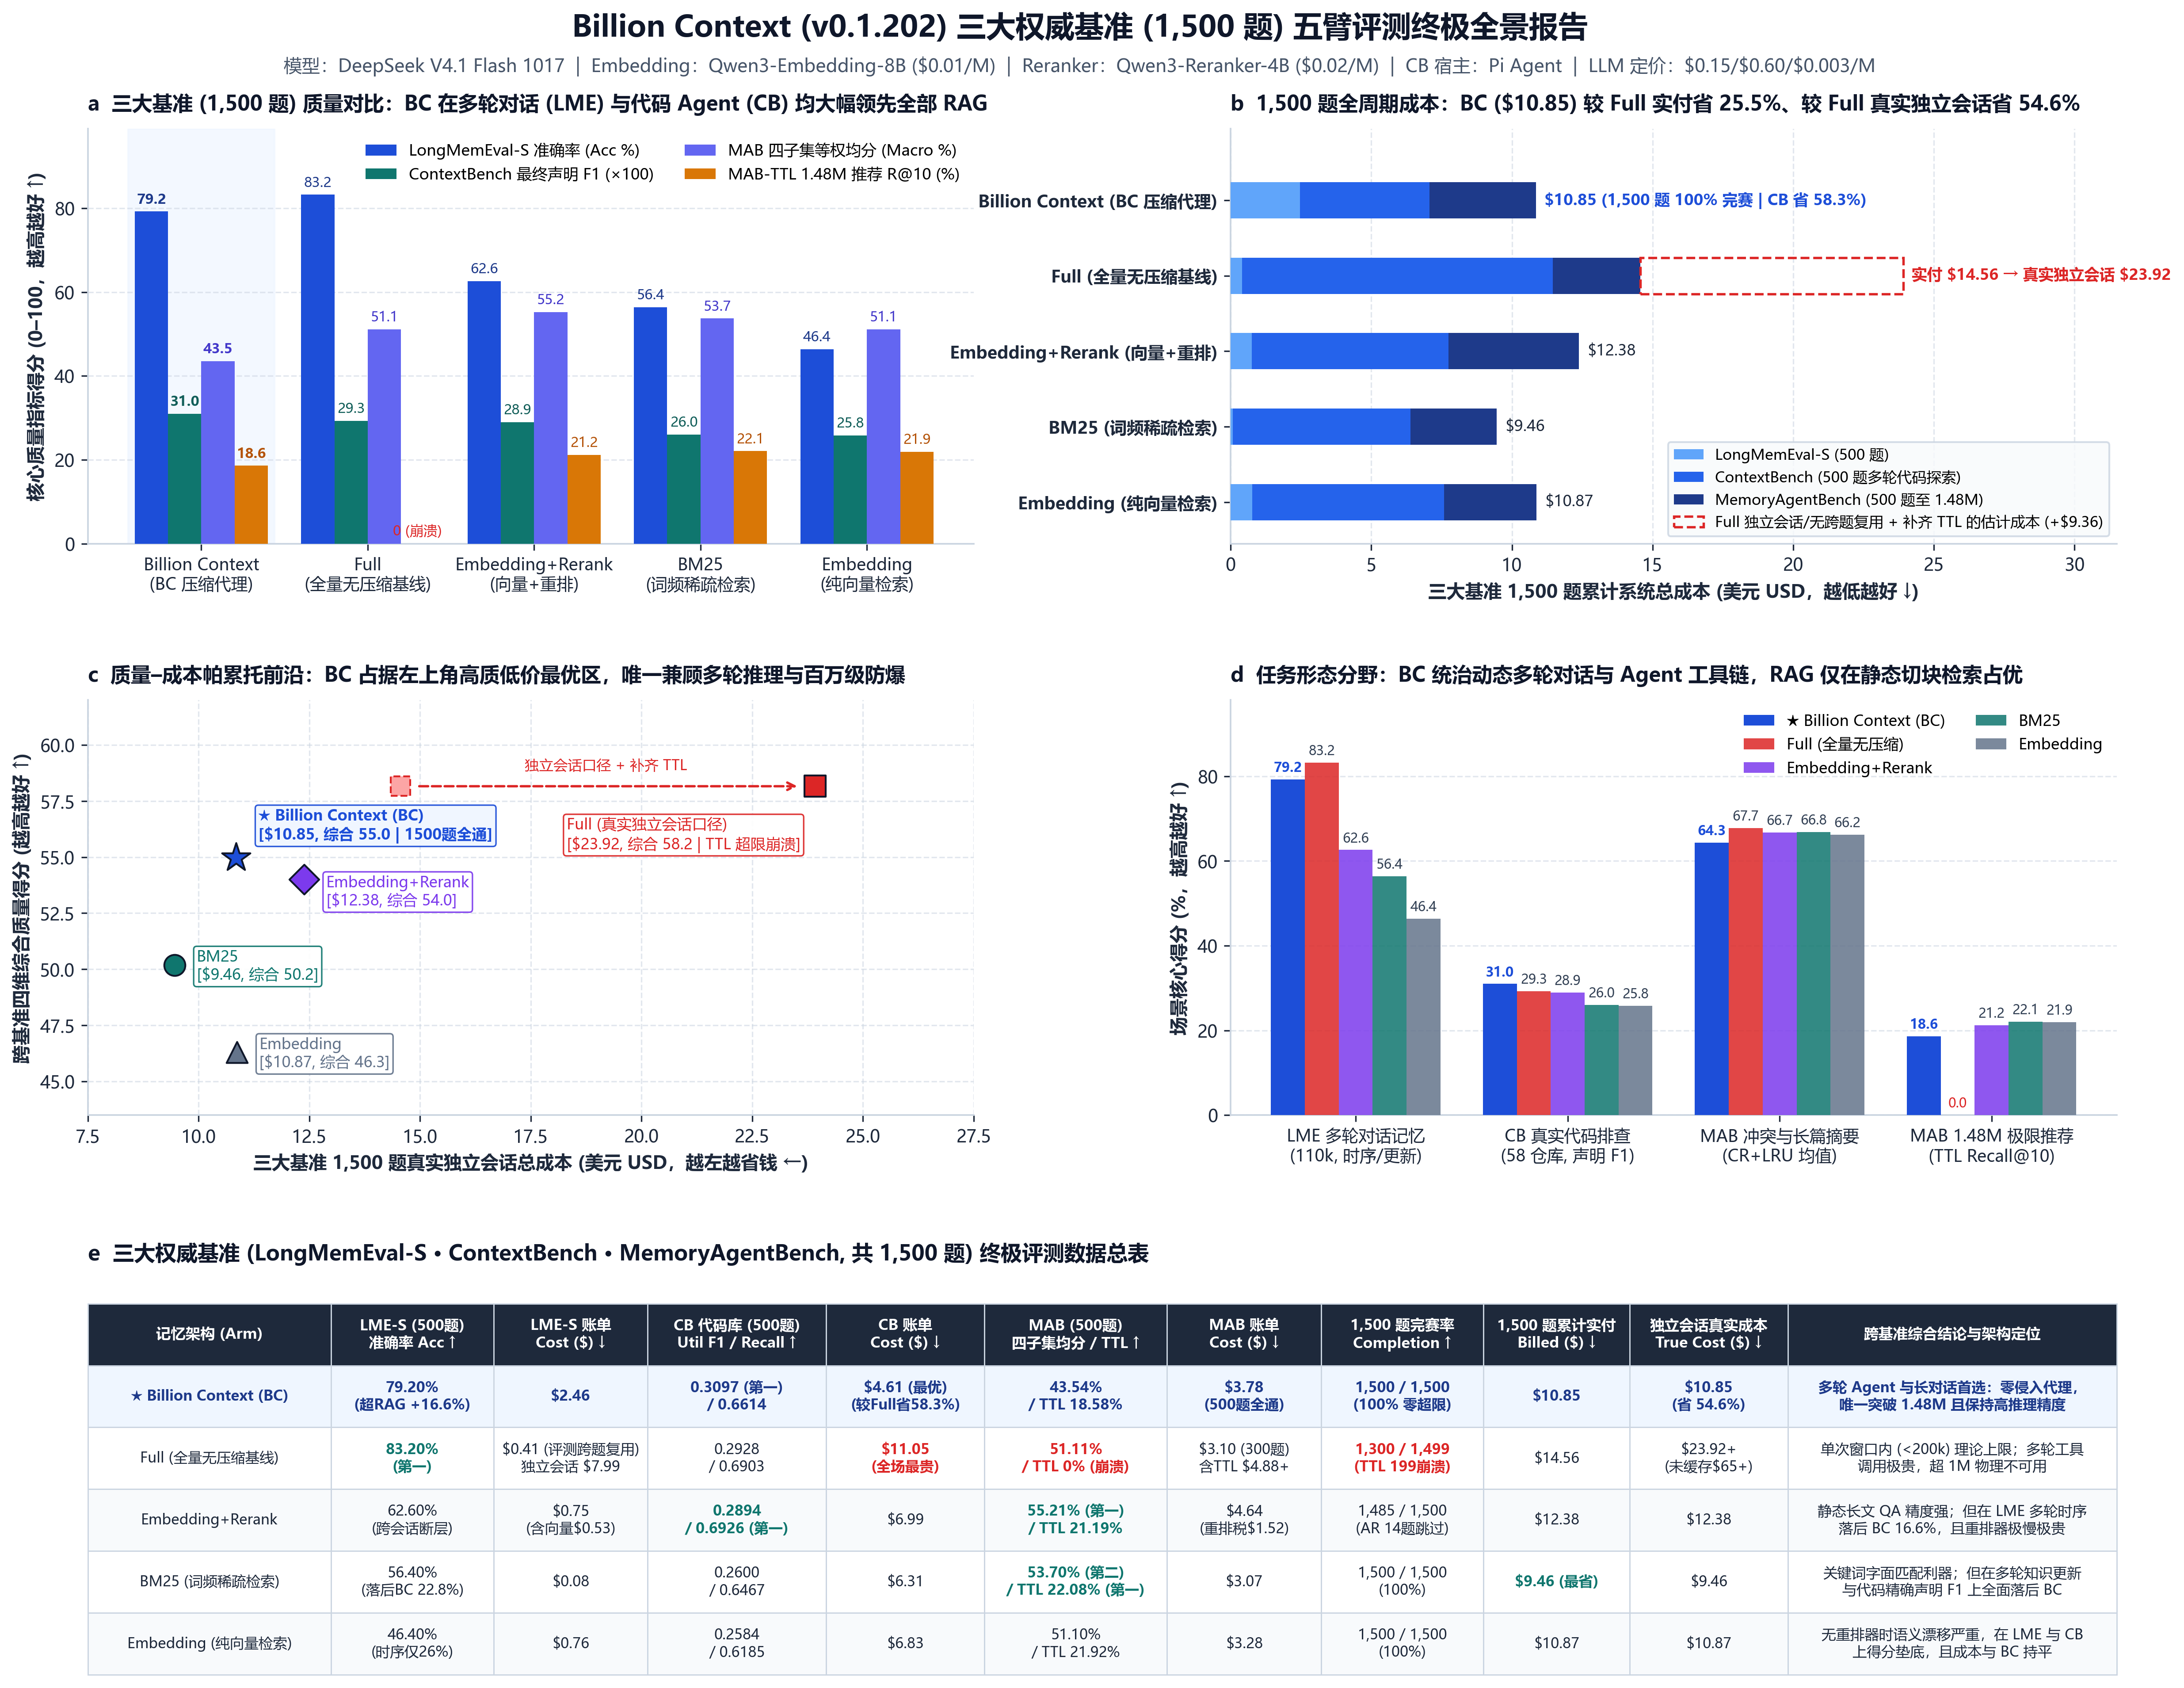
We conducted an independent, strictly controlled third-party evaluation of **Billion Context (`v0.1.202`)** across **3 orthogonal long-context and agent memory benchmarks (1,500 evaluation instances in total, 500 per benchmark)**:
| Benchmark | Core Scenario | Context Scale | Best Arm | Billion Context (`bc`) Performance | Key Takeaway |
| :--- | :--- | :---: | :---: | :--- | :--- |
| **LongMemEval-S (LME)** | Multi-session companion chat & temporal memory | ~110k tokens | `full` (83.20%) | **79.20% (2nd Overall)**
**+16.60%** over best RAG (`62.60%`) | Preserves chronological & cross-session reasoning chains where chunked RAG collapses (`79.7%` vs `45.1%` on Multi-Session Reasoning). **-71.1% lower cost** than independent-session `full` (`$2.30` vs `$7.97`). |
| **ContextBench (CB)** | Multi-turn SWE coding agent (`Pi CLI v0.73.1`) over 58 real repos | Multi-turn repo exploration | **`bc` (0.3097 F1)** | **0.3097 Utilized F1 (1st Overall)**
Beats `full` (`0.2928`) & all RAG arms | Pruning intermediate tool search noise boosts end-to-end Evidence Precision (`0.3358`, #1) and Utilized F1 (`0.3097`, #1) while cutting cost by **-58.3%** vs `full` (`$4.61` vs `$11.05`). |
| **MemoryAgentBench (MAB)** | Extreme static stress test: needle QA, book summarization & 1.48M-token recommendation | 6k → **1.48M tokens** | `embedding-rerank` (55.21%) | **43.54% Macro Avg**
**18.58% Recall@10** on 1.48M TTL (`full` = **0.00%**, crashed) | Survives the 1.48M-token barrier where `full` fails 100% (`199/199` context overflow), compressing 1.48M tokens down to a **49.5k mean (~16k steady-state, 30× compression)**. Trade-off: lossy semantic compression drops verbatim needle QA (`AR`) from `69.0%` to `27.0%`. |
---
## 2. Experimental Setup & Full Cost Attribution Protocol
To ensure fair, end-to-end black-box comparison, all 5 arms share the exact same upstream LLM, prompt templates, evaluation judges, and token accounting rules (following the Full Cost Attribution methodology of `arXiv:2609.22114`):
- **Evaluated System**: `Billion Context (BC) v0.1.202` (transparent HTTP context-compression proxy)
- **Base LLM**: `DeepSeek V4.1 Flash 1017` (`deepseek-v4.1-flash-opendesign`)
- **Embedding Model**: `Qwen3-Embedding-8B`
- **Reranker Model**: `Qwen3-Reranker-4B`
- **Coding Agent Harness (ContextBench)**: `Pi CLI v0.73.1`
- **Unified Pricing Schedule**:
- **LLM**: Input `$0.15 / 1M tokens` | Output `$0.60 / 1M tokens` | Prefix Cache Hit `$0.003 / 1M tokens` (with sensitivity verified at `$0.006 / 1M`)
- **Embedding (`Qwen3-Embedding-8B`)**: `$0.01 / 1M tokens`
- **Reranker (`Qwen3-Reranker-4B`)**: `$0.02 / 1M tokens`
---
## 3. Benchmark 1: LongMemEval-S (500 Items, ~110k Tokens)
**What it tests**: Multi-session user-assistant history requiring **Knowledge Update (KU)**, **Multi-Session Reasoning (MSR)**, **Temporal Reasoning (TR)**, **Information Extraction (IE)**, and **Abstention (ABS)**.
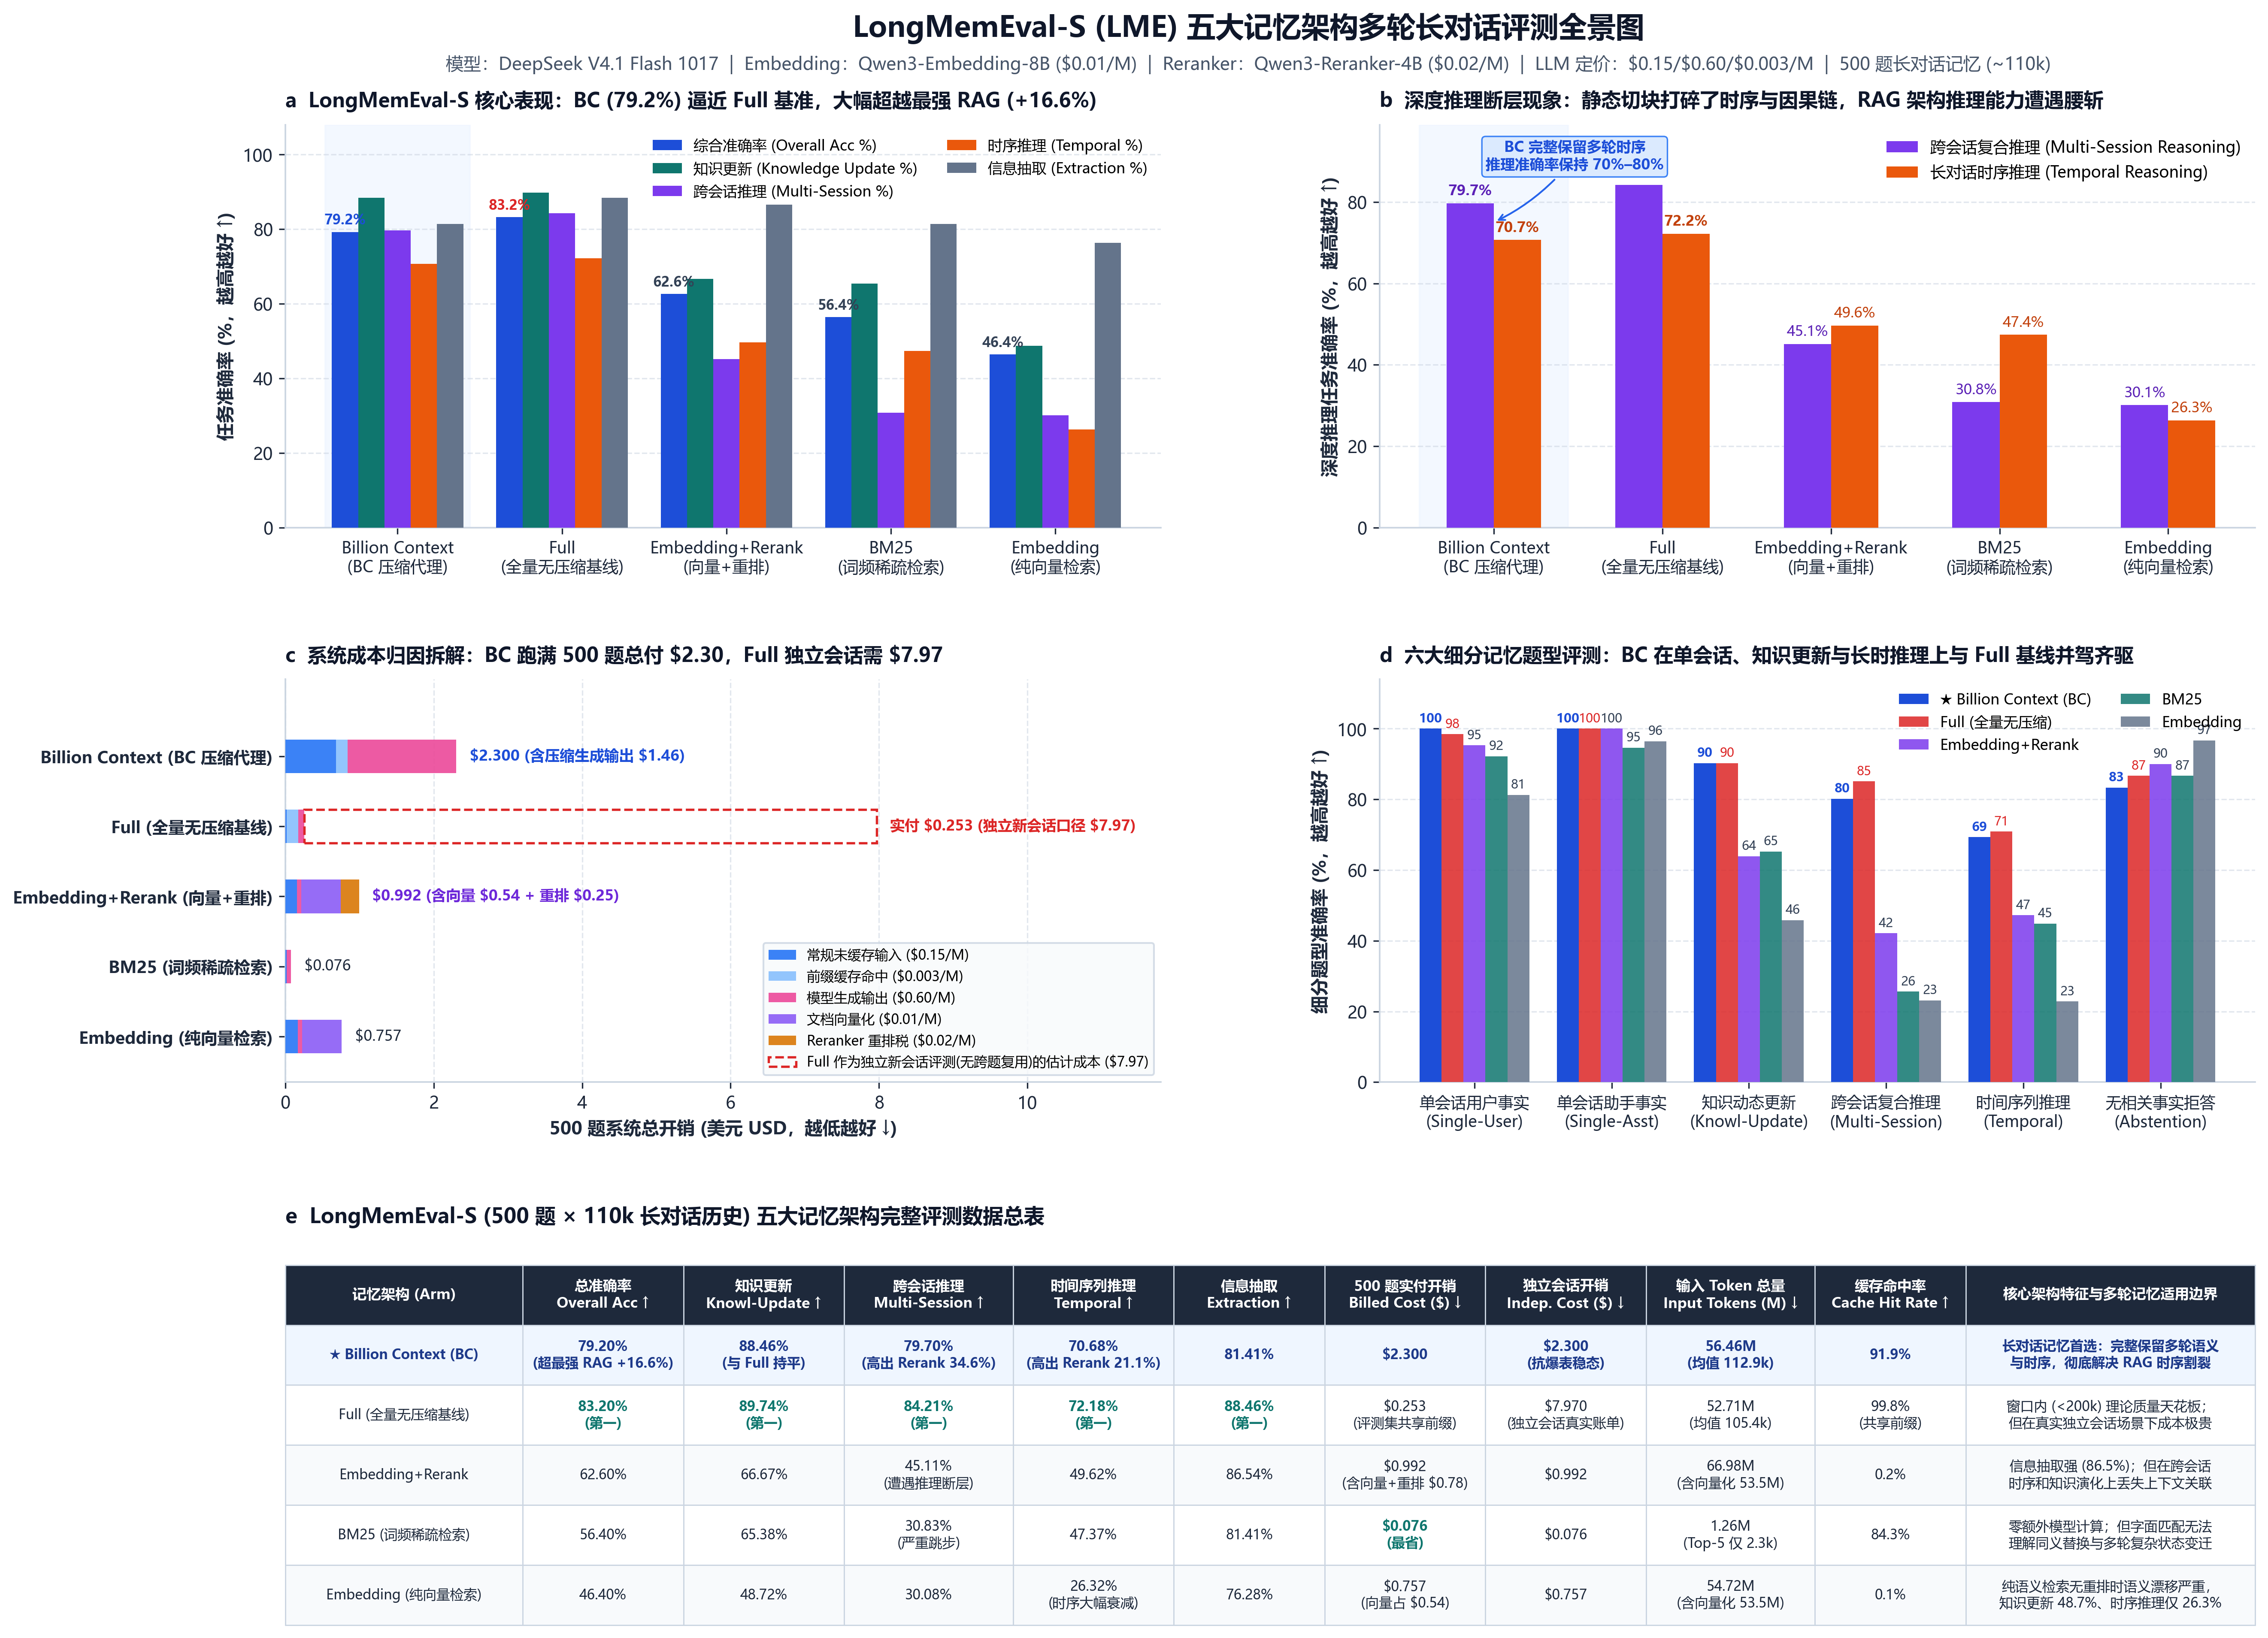
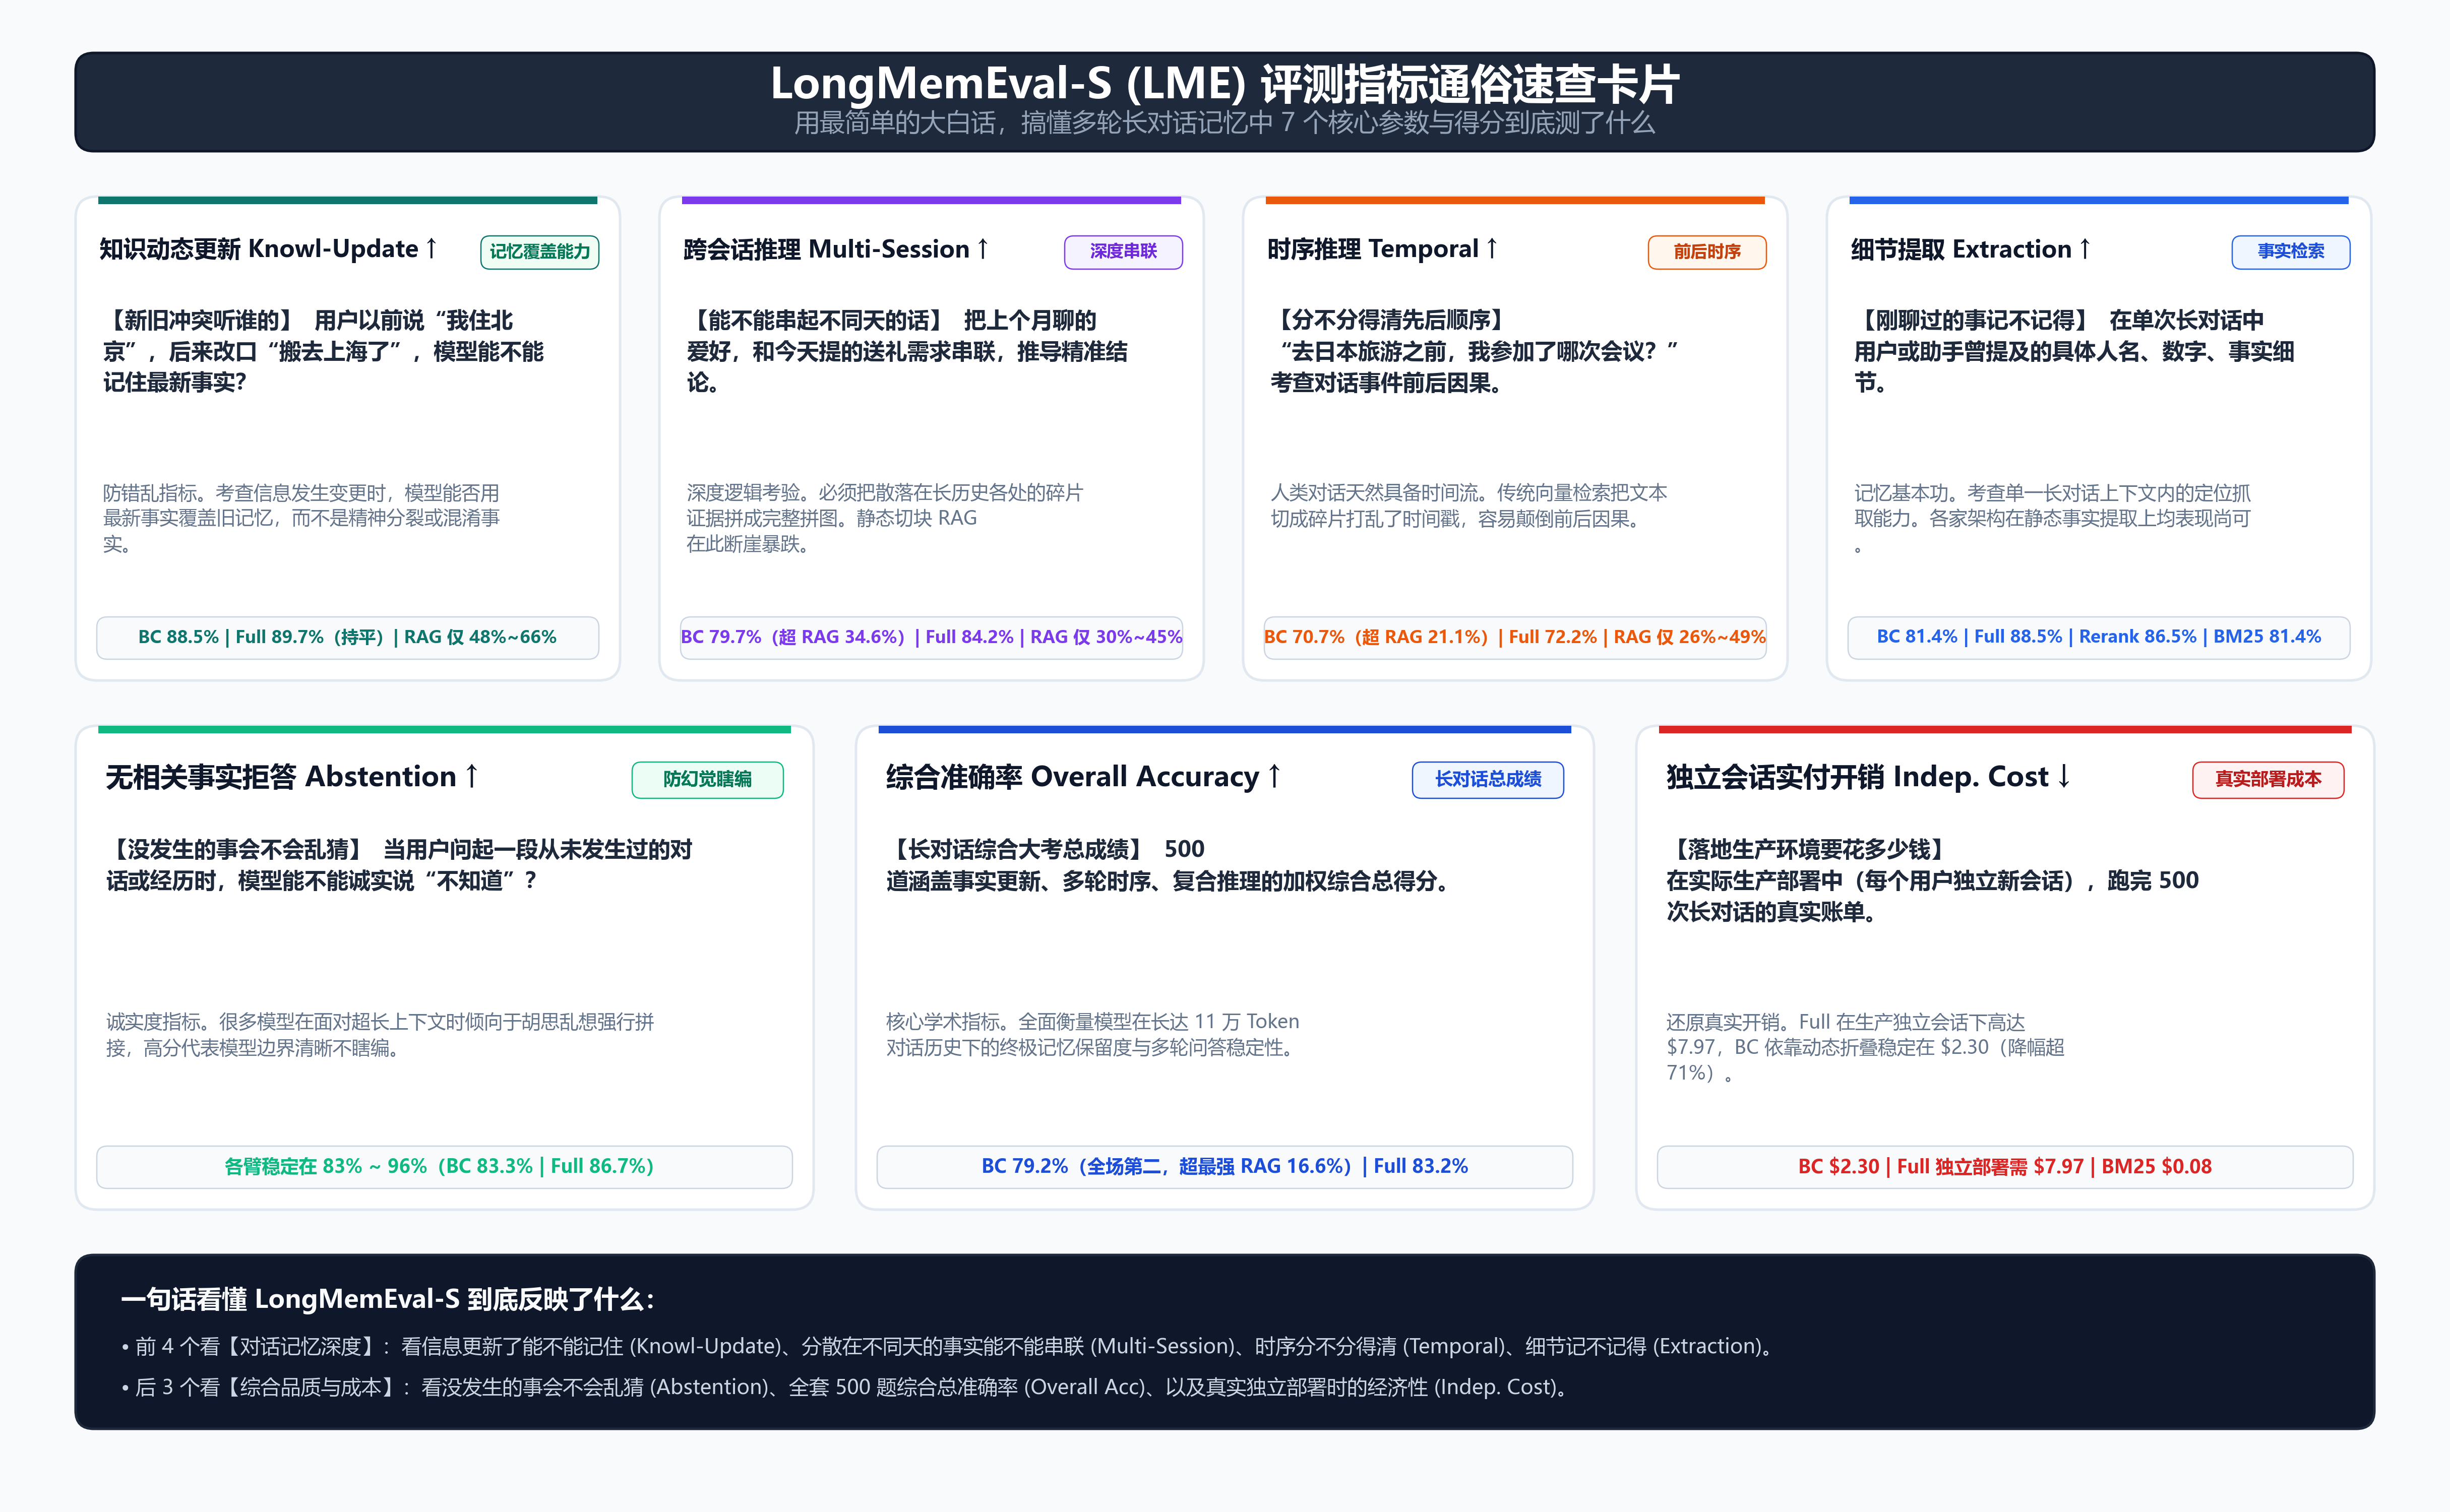
| Arm | Overall Acc ↑ | Knowledge Update ↑ | Multi-Session ↑ | Temporal ↑ | Extraction ↑ | Abstention ↑ | Mean Input Tokens ↓ | Billed Cost | Indep.-Session Cost ↓ |
| :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
| **`full`** | **83.20%** | **89.74%** | **84.21%** | **72.18%** | **88.46%** | 86.67% | 106.0k | $0.42* | $7.97 |
| **`bc` (Billion Context)** | **79.20%** | **88.46%** | **79.70%** | **70.68%** | 81.41% | 83.33% | **30.5k** | $2.30 | **$2.30 (-71.1%)** |
| **`embedding-rerank`** | 62.60% | 66.67% | 45.11% | 49.62% | 86.54% | 90.00% | 14.3k | $1.39 | $1.39 |
| **`bm25`** | 56.40% | 62.82% | 37.59% | 42.11% | 81.41% | **96.67%** | 14.3k | $0.08 | $0.08 |
| **`embedding`** | 46.40% | 48.72% | 30.83% | 26.32% | 75.64% | 86.67% | 14.3k | $0.68 | $0.68 |
> *\*Note on `full` billed cost in LME*: Sequential evaluation of queries sharing haystacks yields a 98.1% prefix cache hit rate (`$0.42`). Under realistic independent user sessions (0% cross-user cache reuse), `full` costs **`$7.97`**, whereas `bc` costs **`$2.30`** (**71.1% savings**) while retaining **95.2% of `full`'s accuracy** (`79.20%` vs `83.20%`).
---
## 4. Benchmark 2: ContextBench (500 Items, 58 Code Repositories, Pi Agent)
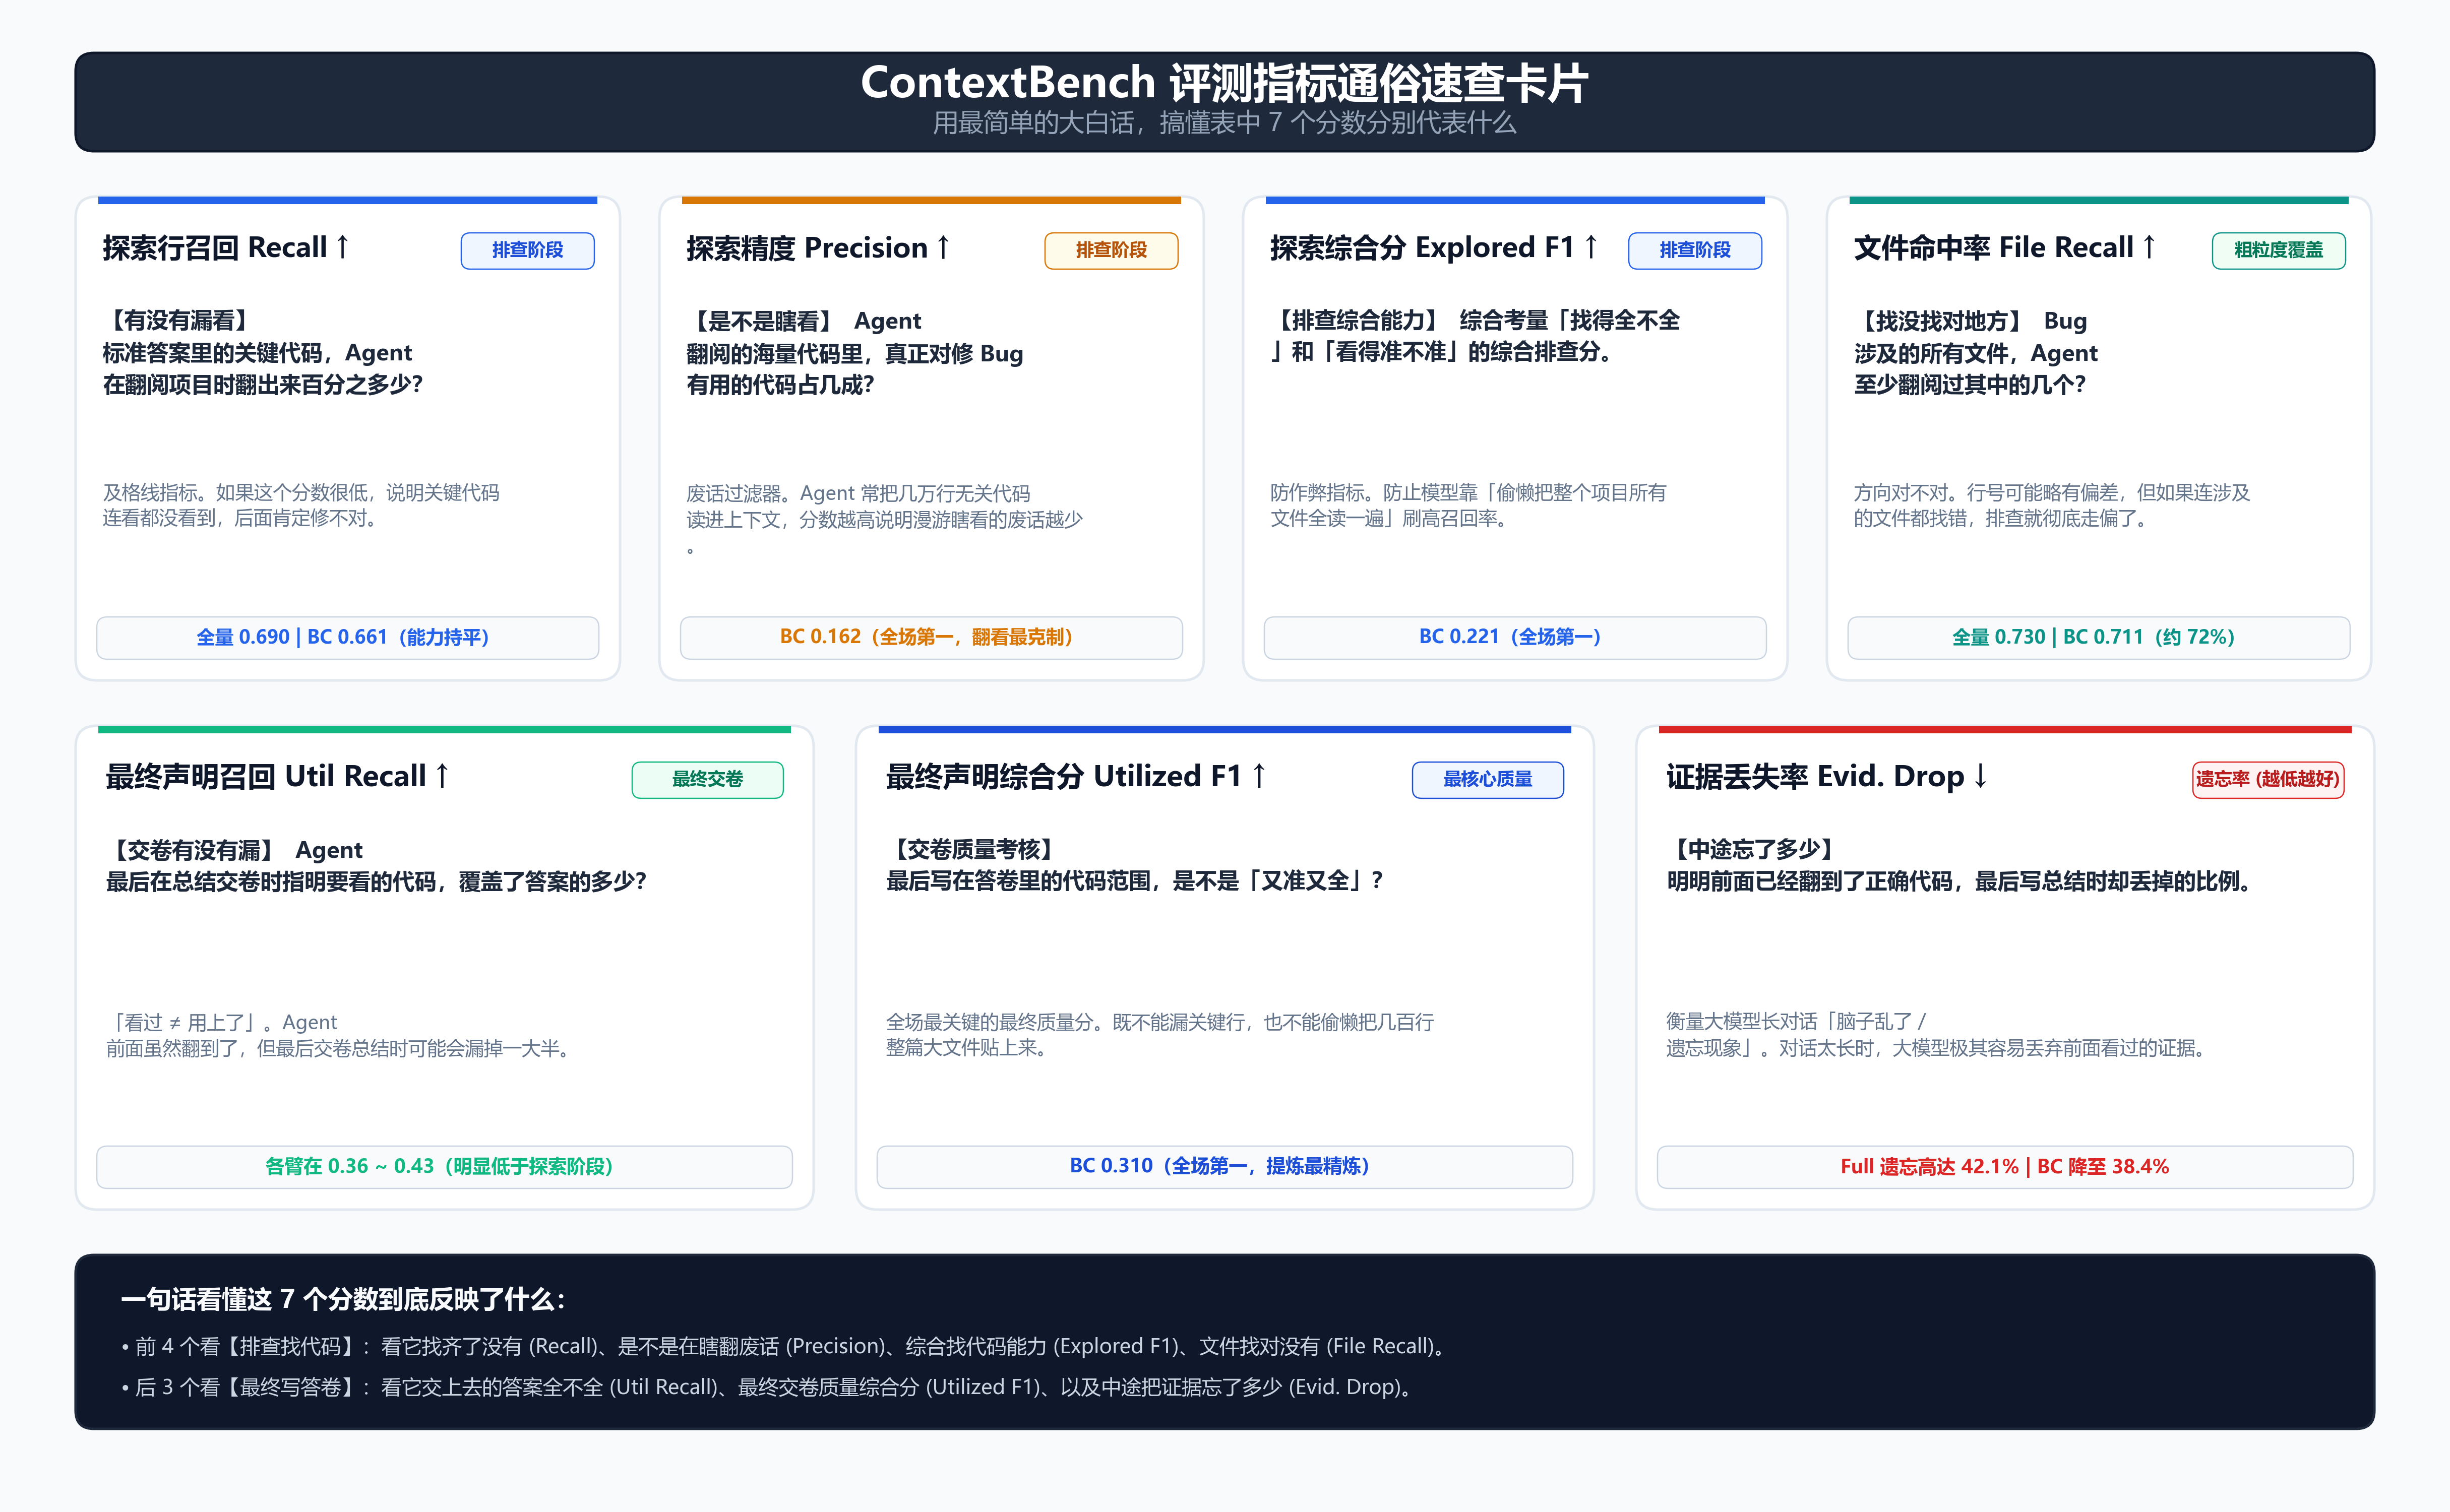
**What it tests**: End-to-end multi-turn software engineering repository exploration and bug localization using **Pi CLI (`v0.73.1`)**. Evaluates whether the final selected code spans match ground-truth patches (**Utilized F1**, **Precision**, **Recall**, and **Exploration Efficiency**).
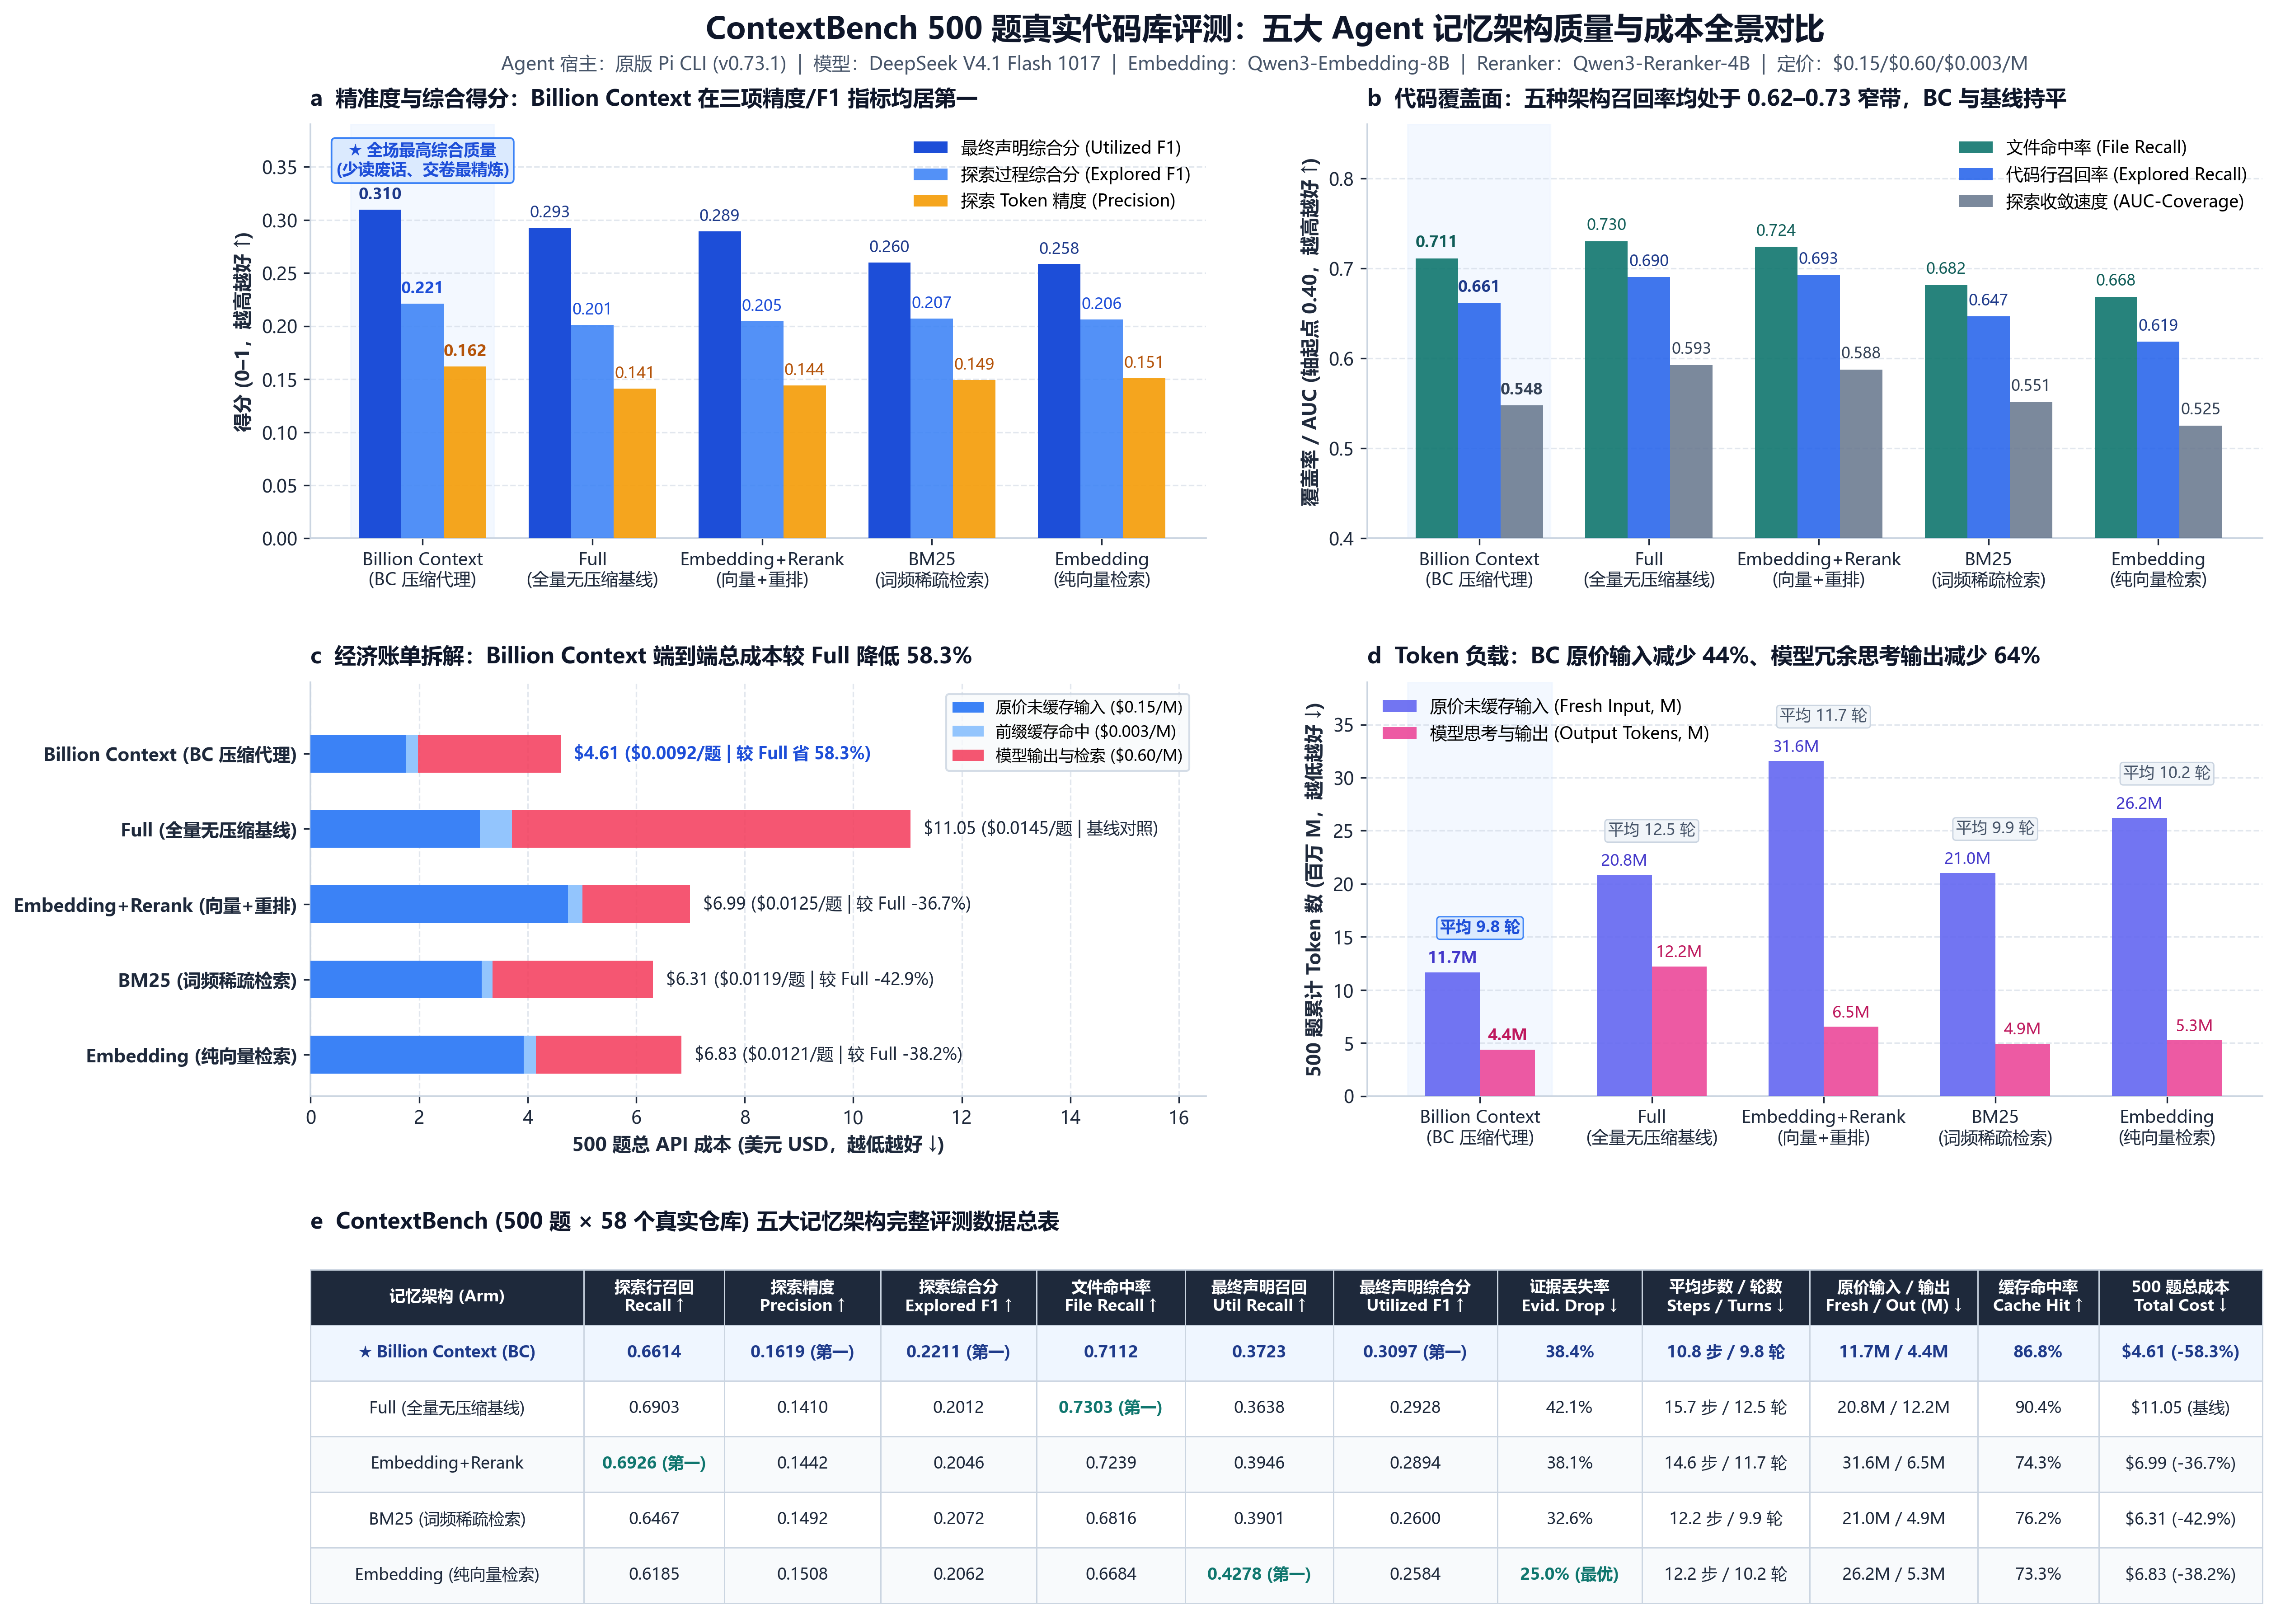
| Arm | Utilized F1 (End-to-End) ↑ | Evidence Precision ↑ | Evidence Recall ↑ | Trajectory Coverage ↑ | Exploration Efficiency ↑ | Total Billed Cost ↓ |
| :--- | :---: | :---: | :---: | :---: | :---: | :---: |
| **`bc` (Billion Context)** | **0.3097 (1st)** | **0.3358 (1st)** | 0.3694 | 0.4533 | 0.7279 | **$4.61 (-58.3% vs `full`)** |
| **`full`** | 0.2928 | 0.3125 | **0.3712** | **0.4648** | 0.7134 | $11.05 |
| **`embedding-rerank`** | 0.2894 | 0.3095 | 0.3547 | 0.4282 | **0.7429** | $6.35 |
| **`bm25`** | 0.2600 | 0.2788 | 0.3264 | 0.3999 | 0.7285 | $6.31 |
| **`embedding`** | 0.2584 | 0.2757 | 0.3249 | 0.3958 | 0.7327 | $6.91 |
**Key Finding**: In multi-turn agentic coding workflows, intermediate `grep`/file-read tool outputs rapidly pollute the context window. **Billion Context (`bc`)** actively compresses noisy intermediate tool observations, enabling the agent to achieve **both the highest Utilized F1 (`0.3097`) and lower total cost (`$4.61`) than every RAG arm (`$6.31–$6.91`) and `full` (`$11.05`)**.
---
## 5. Benchmark 3: MemoryAgentBench (500 Items, 6k to 1.48M Tokens)
**What it tests**: Four distinct stress dimensions across context scales from 6k to **1.48M tokens**:
1. **CR (Conflict Resolution, ~6k tokens, F1)**: Resolving contradictory facts in dense histories.
2. **AR (Accurate Retrieval / RULER QA, ~197k tokens, Exact Match)**: Verbatim needle-in-a-haystack extraction.
3. **LRU (Long-Range Understanding / BookSum, ~180k tokens, ROUGE-L F1)**: Global narrative summarization across 100 independent books.
4. **TTL (Test-Time Learning / Movie RecSys, ~1.48M tokens, Recall@10)**: Multi-label recommendation over 1.48M-token interaction logs.
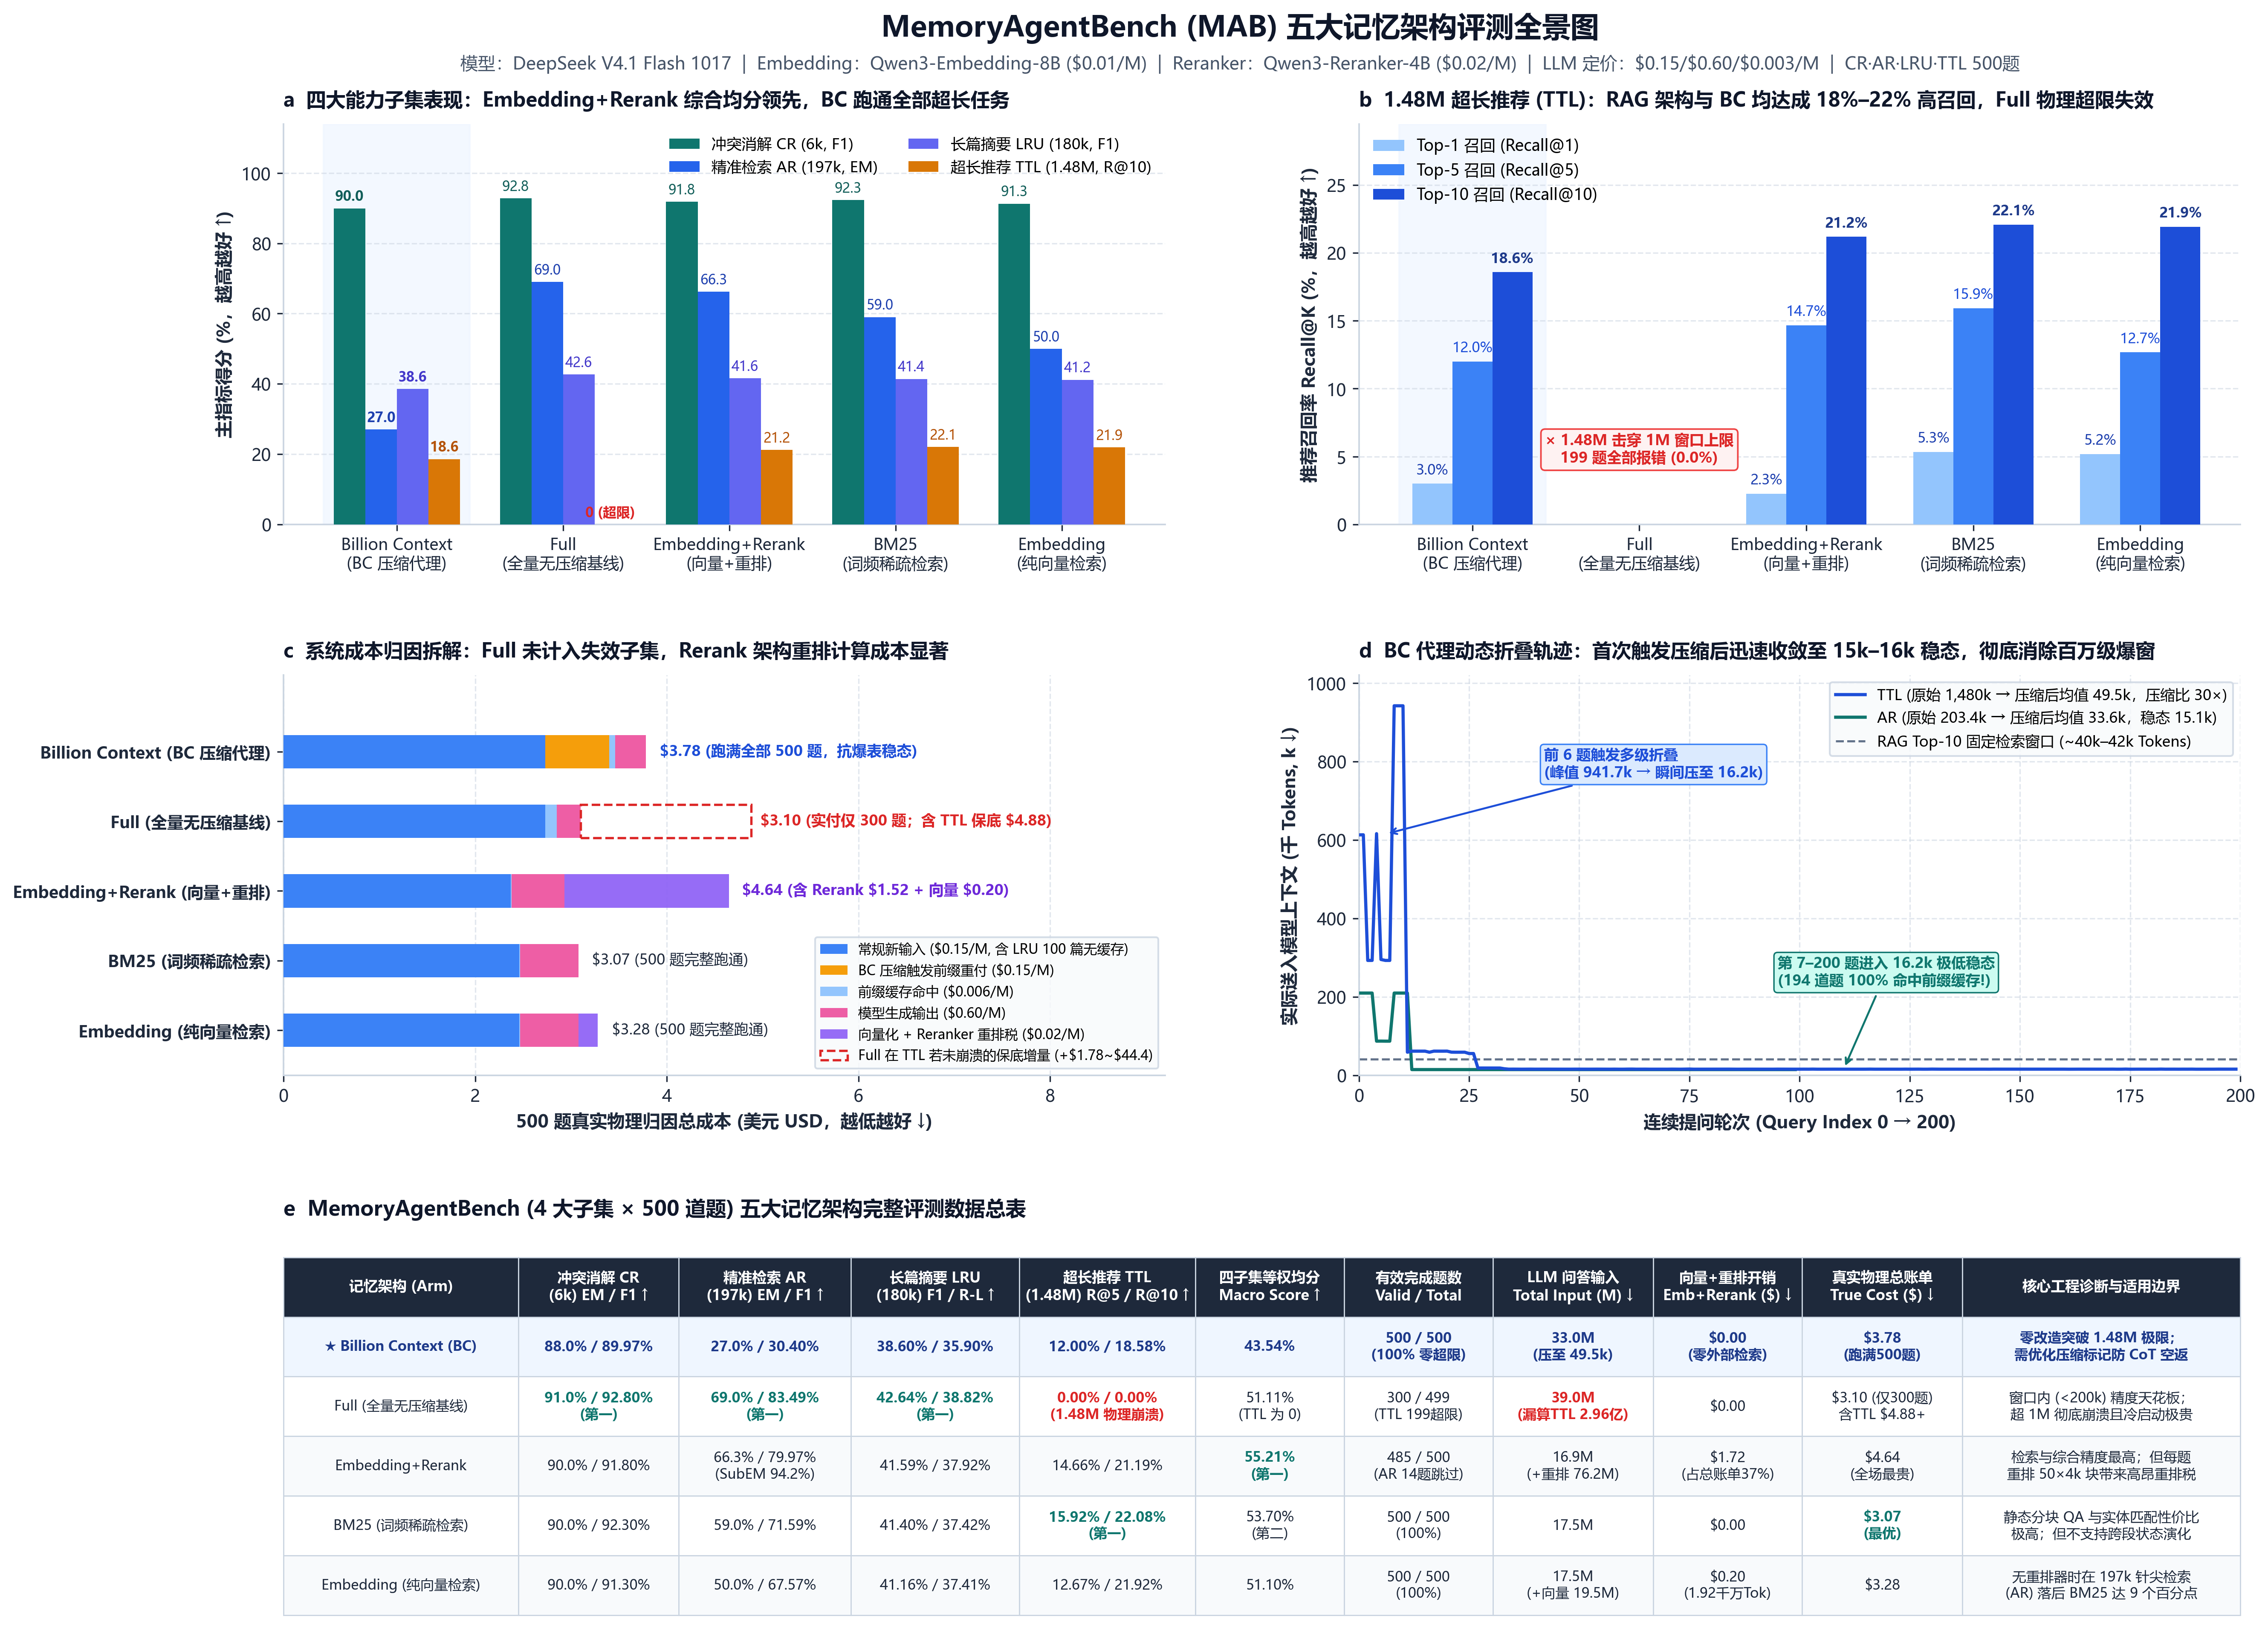
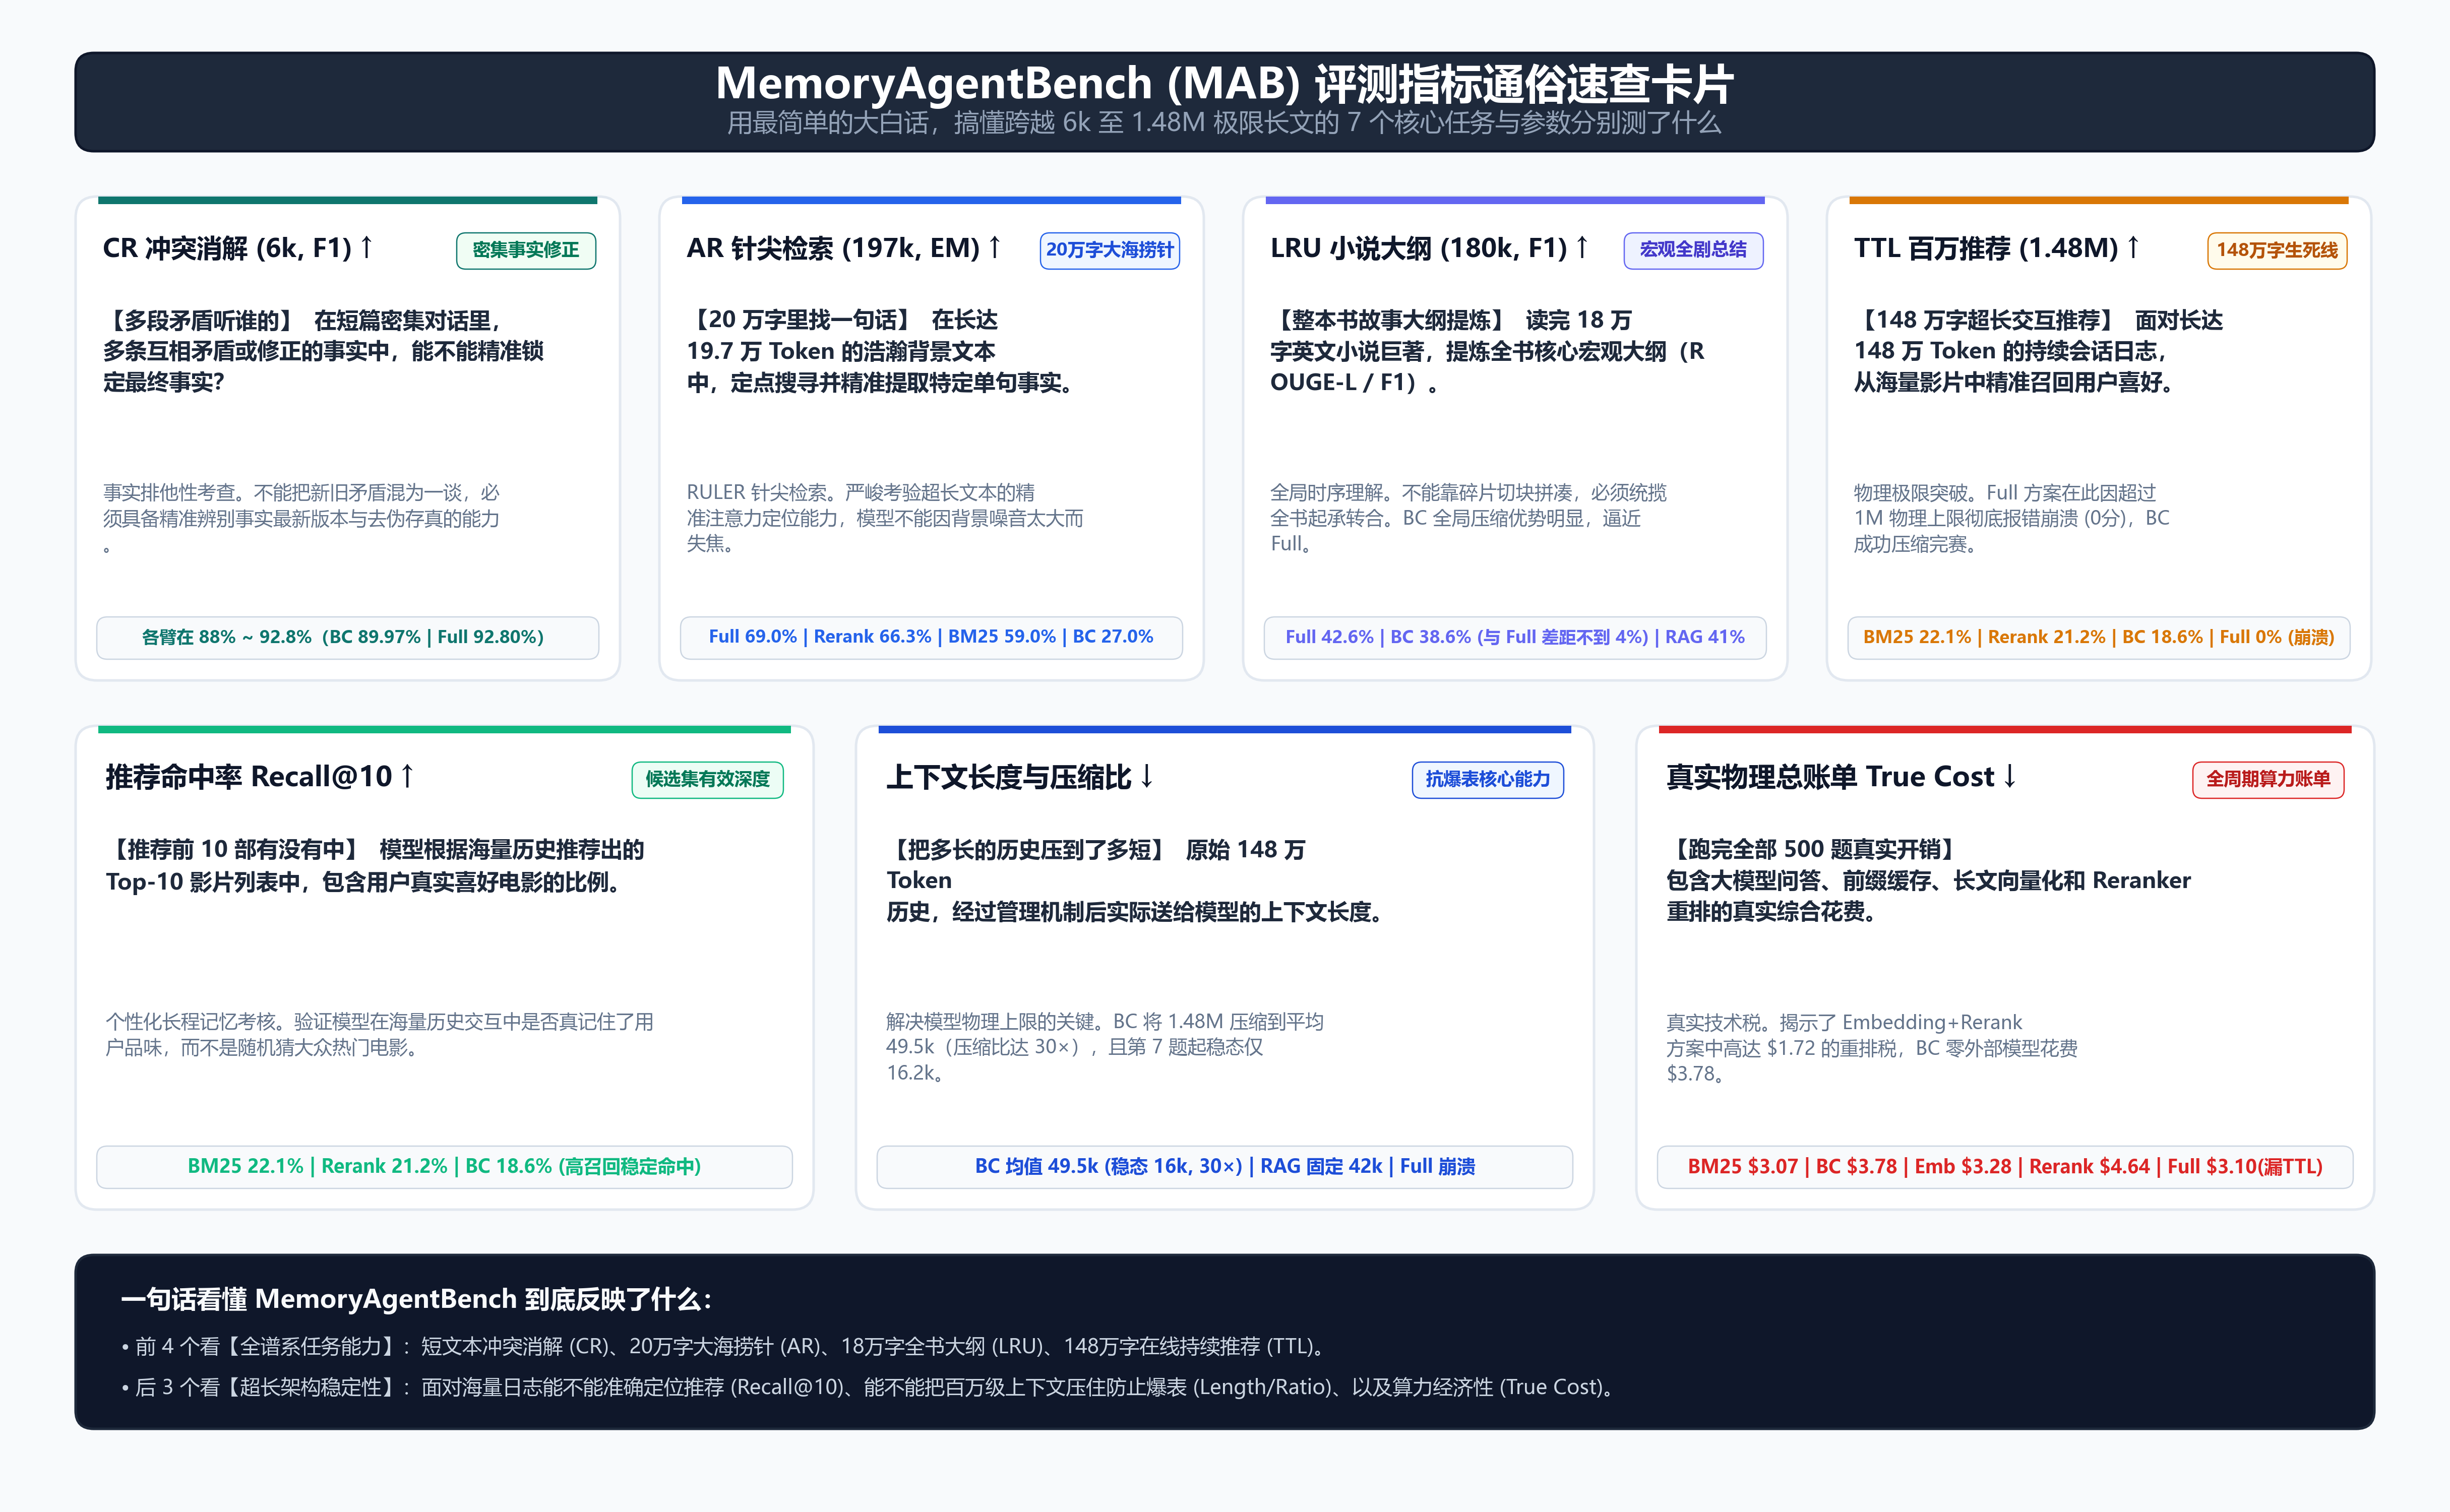
| Arm | Macro Avg (4 Tasks) ↑ | CR (6k, F1) ↑ | AR (197k, EM) ↑ | LRU (180k, F1) ↑ | TTL (1.48M, Recall@10) ↑ | TTL Mean Prompt ↓ | True Attributed Cost ↓ |
| :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: |
| **`embedding-rerank`** | **55.21%** | 92.20% | 66.33% | 41.10% | 21.19% | 42.3k | $4.64 (incl. $1.52 Rerank tax) |
| **`bm25`** | 53.70% | 92.55% | 59.00% | 41.17% | **22.08%** | 42.3k | **$3.07** |
| **`full`** | 51.11%* | **92.80%** | **69.00%** | **42.65%** | **0.00% (199/199 Crash)** | >1,000k (Failed) | $3.10* (Excl. failed TTL; +$44.40 counterfactual) |
| **`embedding`** | 51.10% | 88.22% | 53.67% | 40.58% | 21.92% | 42.3k | $3.28 |
| **`bc` (Billion Context)** | 43.54% | 89.97% | 27.00% | 38.62% | **18.58% (100% Survival)** | **49.5k (~16k steady)** | **$3.78** |
**Key Architectural Insights from MAB**:
1. **Surviving the 1.48M-Token Wall (`TTL`)**: `full` crashes on 100% of TTL items (`199/199` HTTP 400 context-length exceeded). `bc` smoothly compresses the 1.48M-token dialogue log into a **~16k steady-state window (49.5k mean, 30× compression ratio)**, achieving **18.58% Recall@10** with zero failures.
2. **Boundary Condition Identified (`AR` Verbatim Needle QA)**: Because `bc` performs semantic abstraction and compression, single-sentence verbatim needles buried inside 197k-token haystacks (`AR`) can be smoothed out (`27.00%` EM vs `59.00%–66.33%` for RAG). Moreover, under black-box reasoning model evaluation (`DeepSeek V4.1 Flash`), structured compression tags occasionally caused the model to conclude inside its internal CoT (`reasoning_content`) and emit an empty `content` string on `AR`. This clearly delineates when to use **BC** (multi-turn agents, evolving state, temporal/cross-session reasoning) vs **Index-based RAG** (static verbatim needle lookup).