# rea-video Reverse-engineer any video. Talking-head, tabletop, AI video, 3D, motion graphics, mixed edits: give it any of them,
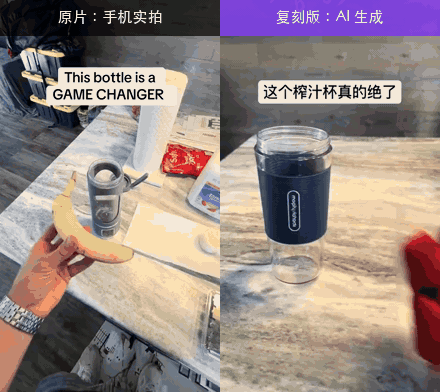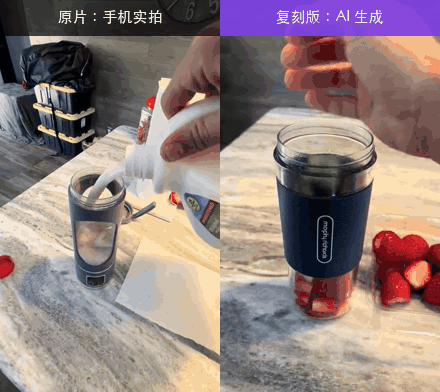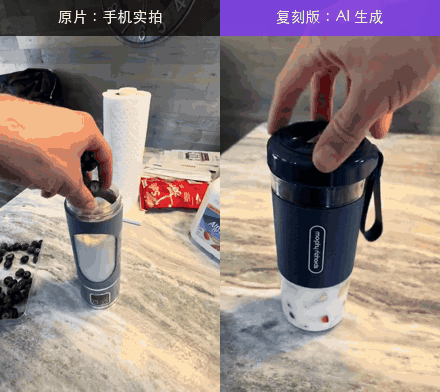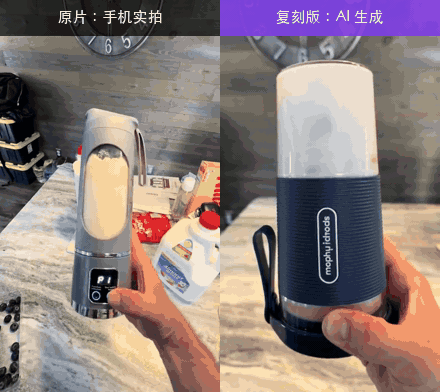
and it tells you shot by shot how the visuals, styled text, editing and audio were made, then gives you a plan to make one yourself. [中文](i18n/README_zh.md) | English | [Русский](i18n/README_ru.md) | [日本語](i18n/README_ja.md) | [한국어](i18n/README_ko.md) | [Español](i18n/README_es.md) | [Português](i18n/README_pt.md) | [Français](i18n/README_fr.md) | [Deutsch](i18n/README_de.md) [![Stars](https://img.shields.io/github/stars/JuneYaooo/rea-video?style=flat)](https://github.com/JuneYaooo/rea-video/stargazers) ![Python](https://img.shields.io/badge/python-%E2%89%A53.10-blue) ![Agent](https://img.shields.io/badge/runs%20in-Claude%20Code%20%7C%20Codex-8A2BE2) Left: TikTok original shot on a phone; right: someone's AI remake with a different product Left: a TikTok ad shot on a phone. Right: someone's AI remake with a different product swapped in.
rea-video's verdict: the left is all live footage, one set and two camera positions; the right is all AI-generated, and its 8 shots can be produced in 3 generations.
> Reports come out in the language you ask in (Chinese or English; your agent passes `--lang`). The detailed docs are in Chinese for now; your agent reads them and answers in your language. The six example reports below are in English, so you can see what a report looks like without installing anything. ## What it can break down | Video type | Examples | What you get | |---|---|---| | Live footage | Talking-head, tabletop, handheld product demo, vlog, store visit | Setups and camera positions, framing, camera moves, lighting (12 setups with gear lists), color grade | | AI video | Text/image-to-video, AI short drama, AI music video | Evidence, a reverse-engineered prompt per shot, how to batch into generations and which model to use | | Avatar | A portrait driven by audio, lip-sync | Which shots are avatar shots, what portrait and audio you need | | 3D / animation | Blender / C4D explainers, product animation, 2D animation, stop-motion | Whether to generate with a video model or render from 3D code | | Code / template | Kinetic type, UI demos, charts, slide-style cards | Text, layout and motion timing, ready to rebuild as a Remotion project | | Screen recording | Software tutorials, web demos | Which parts are real material you'll need to record yourself | | Mixed / edits | AI characters + code UI + real screen capture; live footage with AI edits | Each shot judged separately, then reassembled on the original timeline | Besides how the picture was made, every video also gets: - Captions and styled text: start and end of each line (exports to SRT / ASS), plus color, outline and how the text comes in - Stickers, emoji, picture-in-picture: where they sit and how long they stay - Editing: where the cuts are, how fast, whether they hit the beat - Audio: human or AI voice, AI or library music and its BPM, where each sound effect lands - Material you'll supply yourself: screen recordings, screenshots, product photos ## Quick start rea-video is built for AI agents. In Claude Code, Codex or any agent that can run commands, say: ```text Install https://github.com/JuneYaooo/rea-video, then break down this video: /path/to/video.mp4 ``` The agent installs the CLI, learns the workflow and runs the whole thing. You need ffmpeg and Python 3.10+.
Install by hand ```bash brew install ffmpeg # or: sudo apt install ffmpeg git clone https://github.com/JuneYaooo/rea-video && cd rea-video bash scripts/install_skill.sh # installs the CLI (pip, or pipx / a local .venv if pip is blocked) and links the skill into ~/.claude, ~/.codex, ~/.agents rea-video --help ```
You get: - a one-line summary, e.g. "41% AI video + 59% code UI, 8 s of real screen recording, library music at 122 BPM" - a remake plan, split into what to film, what to generate and what to code - a full `report.html` with per-shot frames, evidence, prompts, camera and lighting notes, and the audio breakdown Add a video-capable model — Gemini or Doubao both work: give the agent the endpoint and key. It makes live/AI/3D calls more accurate and writes a reverse-engineered prompt for every shot. Without one it still works; if your agent can see images, it will check the uncertain shots itself. ## Examples

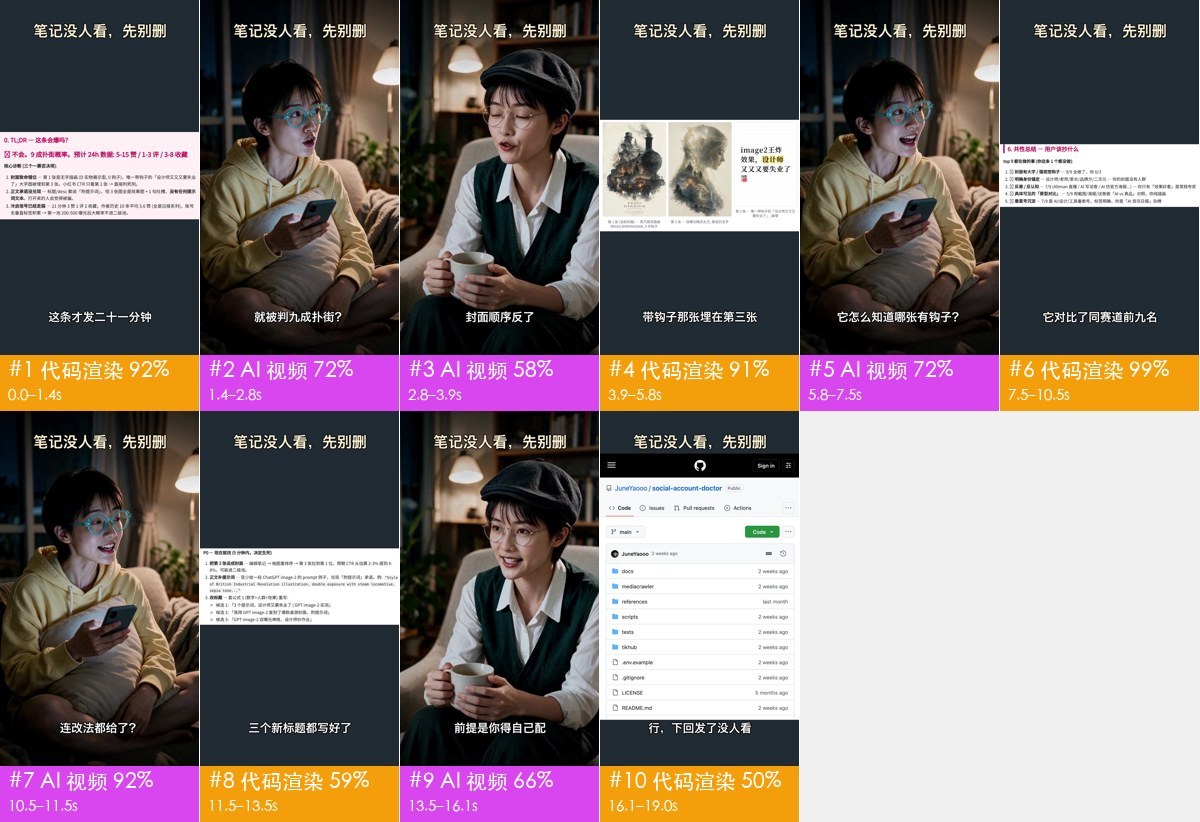
Mixed-media clip · 19 s · 10 shots
AI characters talking + code-built UI + 8 s of real screen recording. The 5 dialogue shots are split up by UI segments but share one set, so one generation covers them.
Video · Report

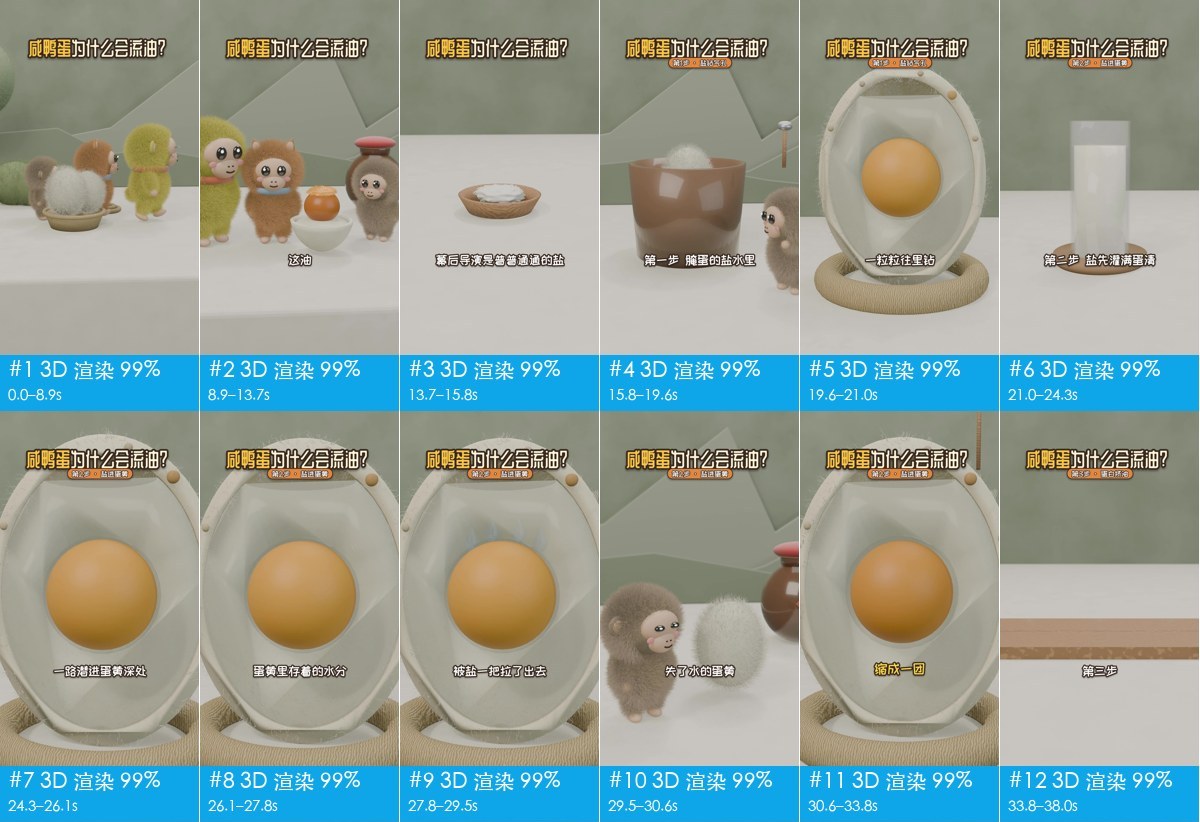
3D explainer · 67 s · 21 shots
All 3D, AI narration. Doable as 10 video generations, or have an LLM write Blender / Three.js code.
Video · Report

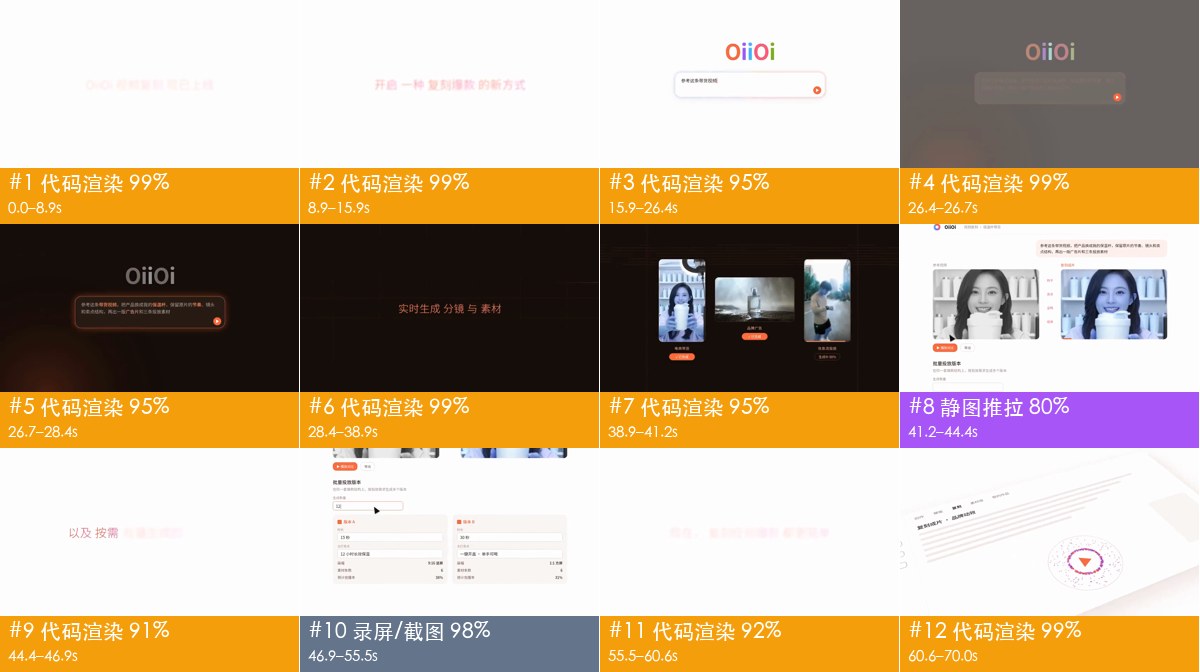
Product promo · 70 s · 12 shots
83% code-driven motion graphics, 12% screen recording. No video model needed; one Remotion project does it.
Video · Report

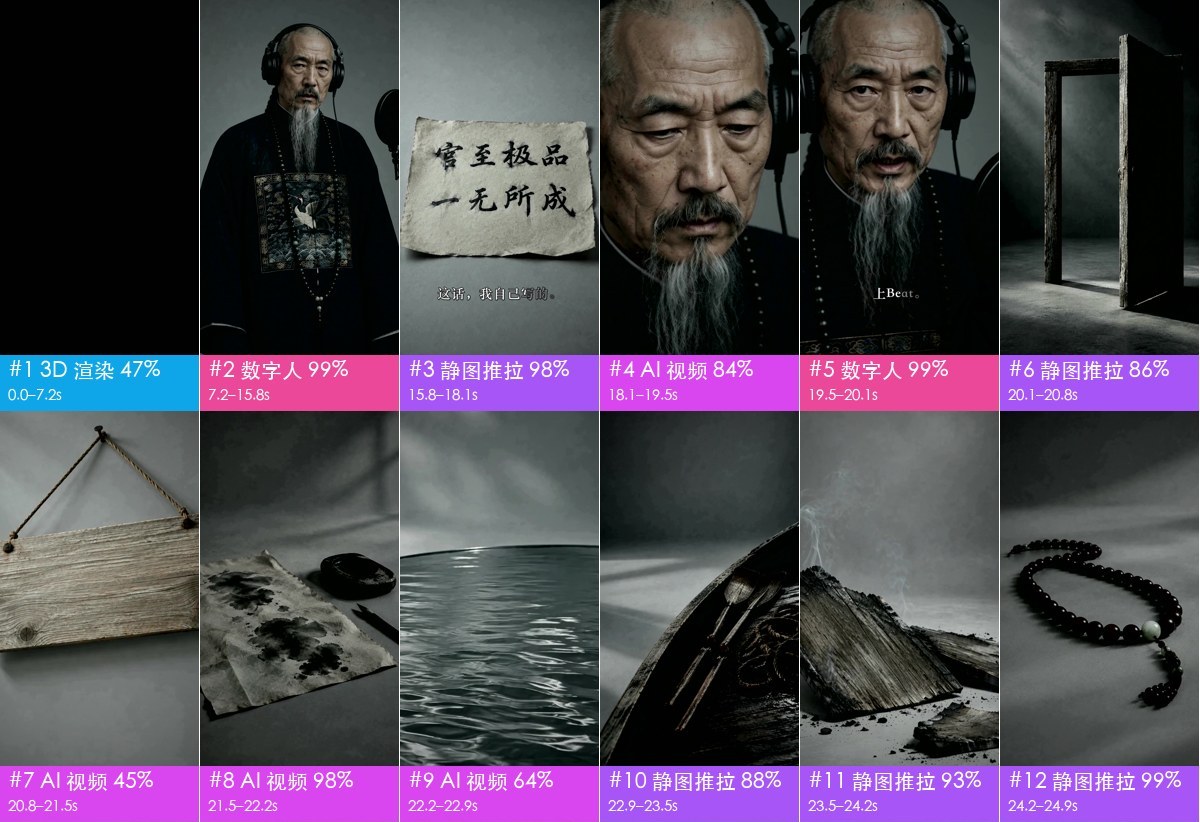
AI music video · 165 s · 86 shots
Correctly flags the song as AI-generated (it was made with Suno). The vision model called some shots "live-action drama"; the agent spotted fake Chinese characters on a scroll and ruled them AI.
Video · Report

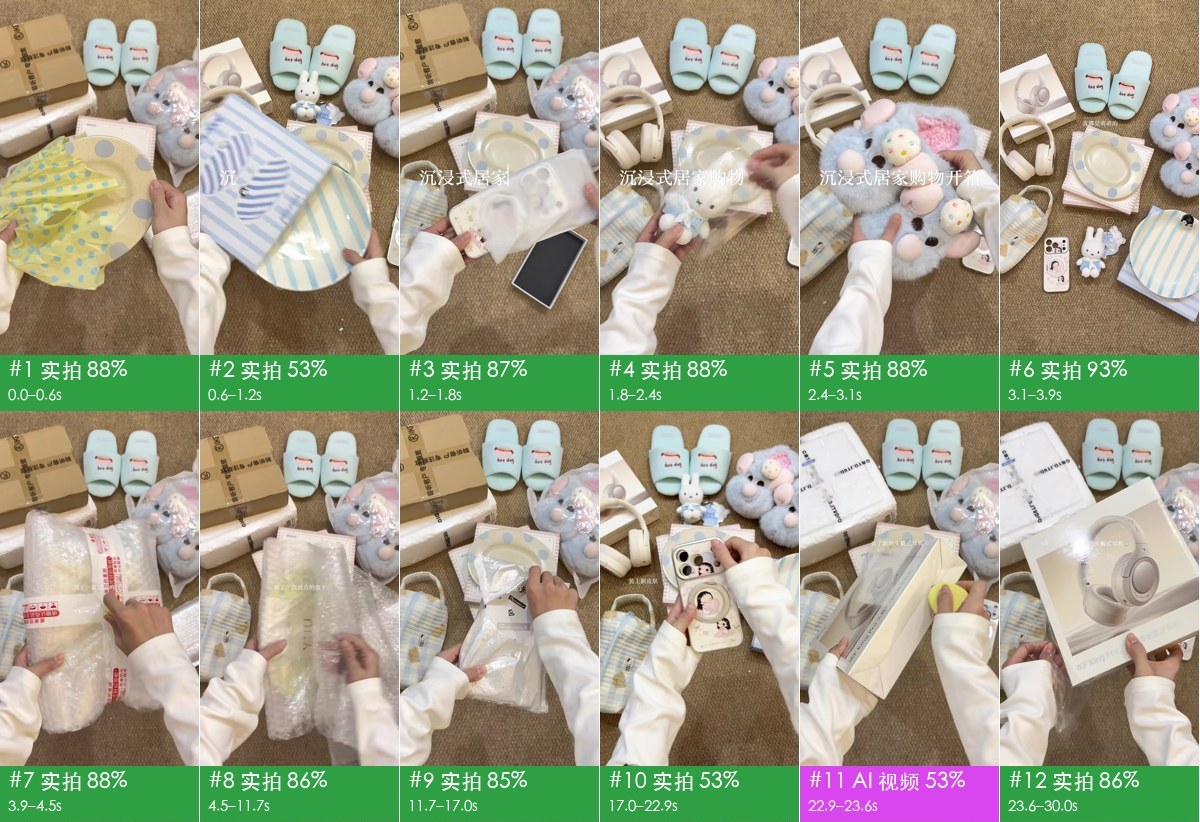
Live-action unboxing · 72 s · 29 shots
All real footage: an overhead phone rig, one rug, one camera position, no voice-over, room sound plus library BGM. After platform transcoding the offline tool called 35% of it AI; agent review brought it to 97% live-action.
Video · Report

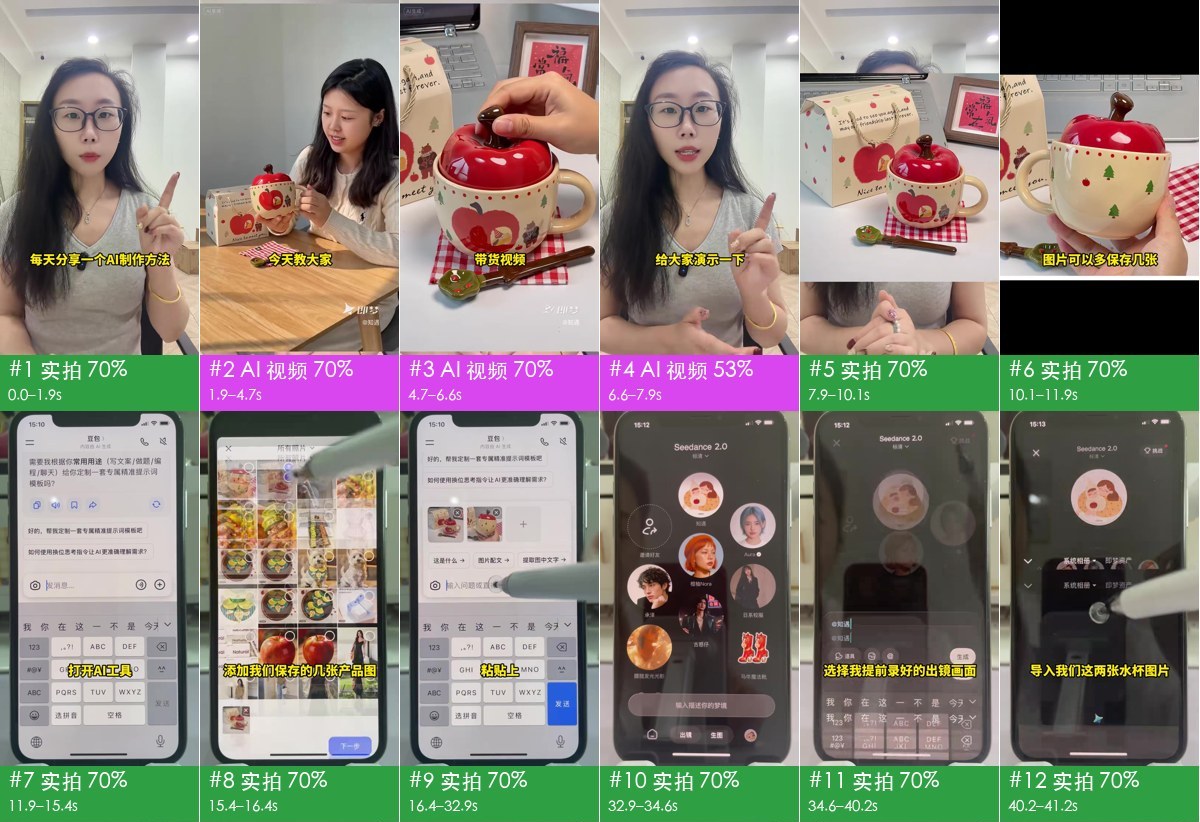
AI + real person hybrid · 58 s · 21 shots
75% real (talking head + filming a phone screen) and 25% AI: the creator fed her own on-camera clip and two product photos to Jimeng to generate a "real-person" product segment. The AI part was caught by the Jimeng watermark and garbled text on the gift box.
Video · Report
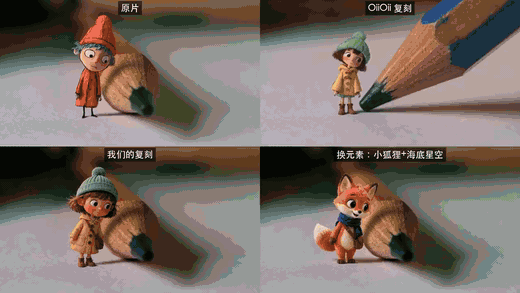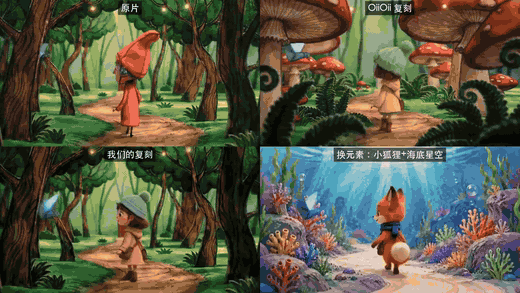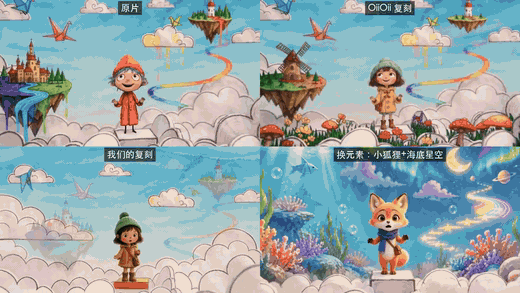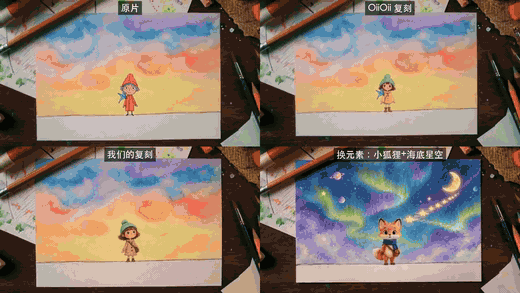
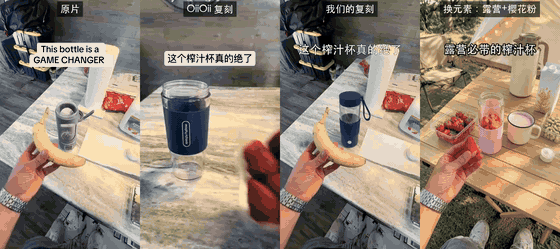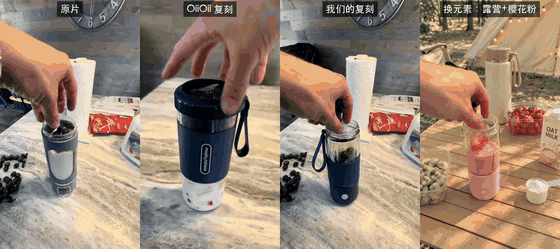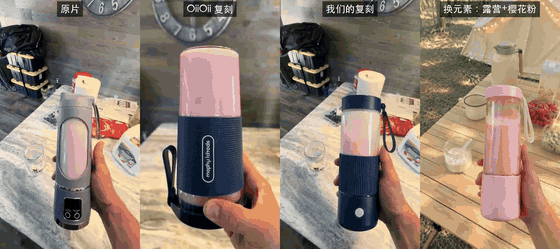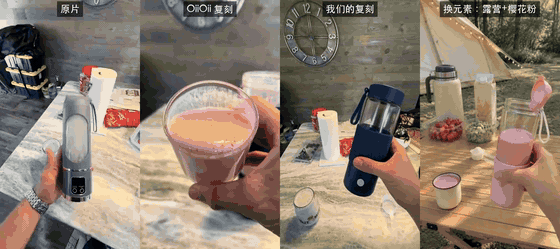
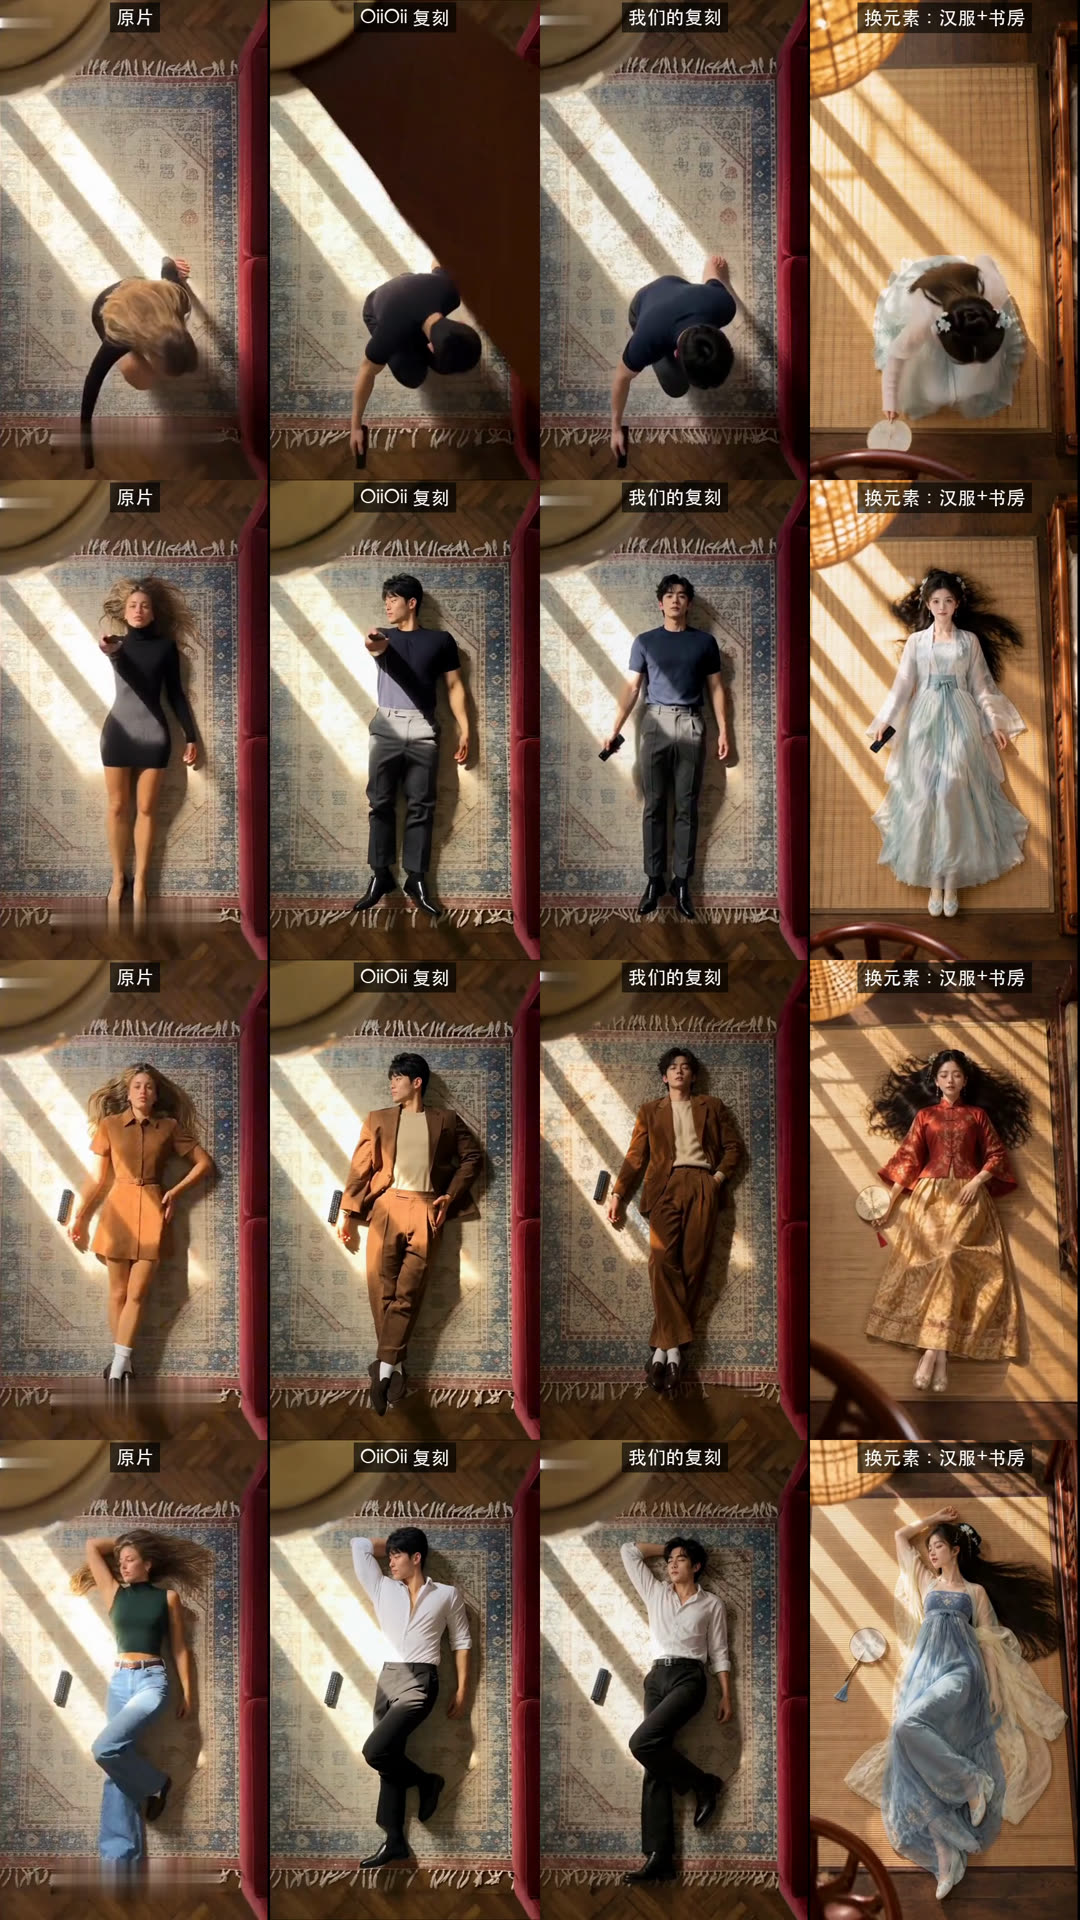
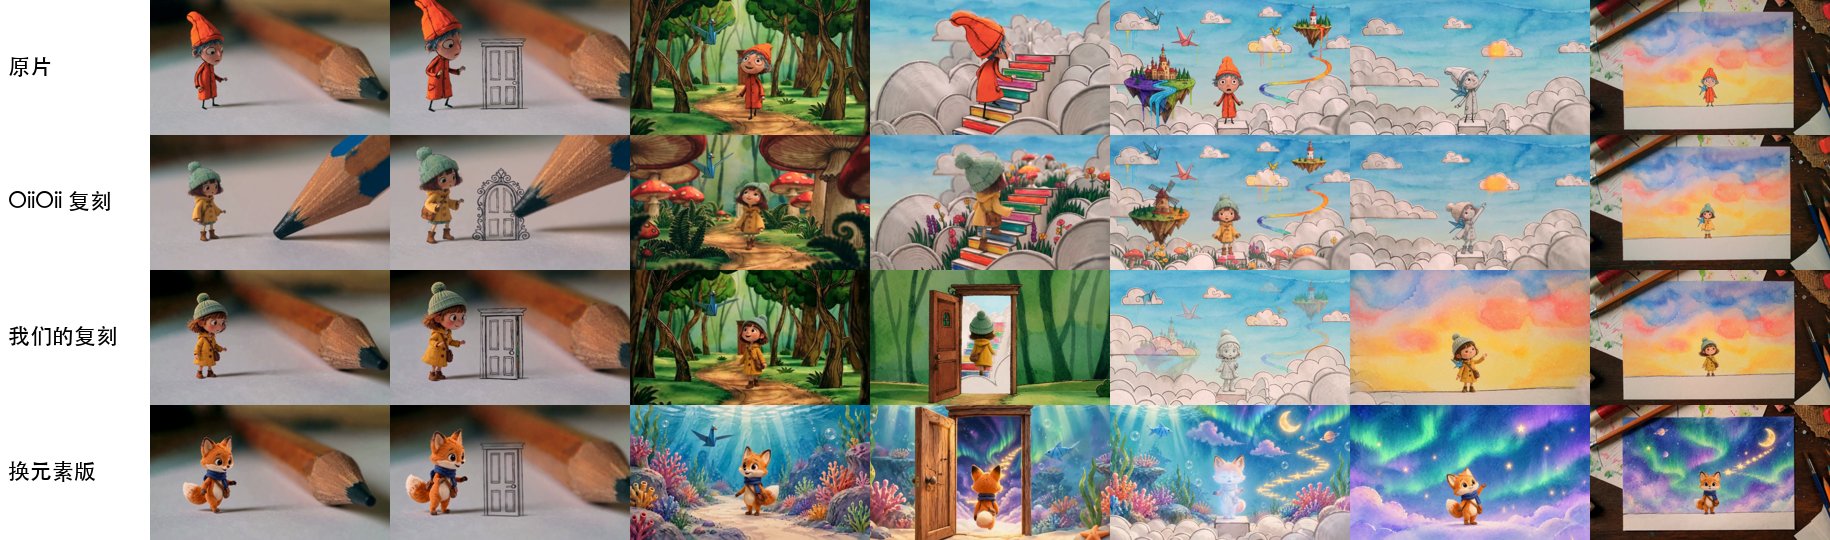
## Remakes After rea-video breaks a video down, the remake recipe in [cheap-claude-video](https://github.com/JuneYaooo/cheap-claude-video) generates a new version: camera, motion, pacing and transitions follow the original, only the elements you choose are swapped. These results were generated with a self-hosted MiniMax H3: the original shot is the motion reference, and keyframes with the swapped elements (gpt-image-2) set the look. Below are three remakes that OiiOii showed in its WeChat articles. For each we made two versions: the same swap as OiiOii, and one that also swaps the subject, setting and props. Each GIF plays four versions in sync: original, OiiOii remake, our remake, element-swap version.
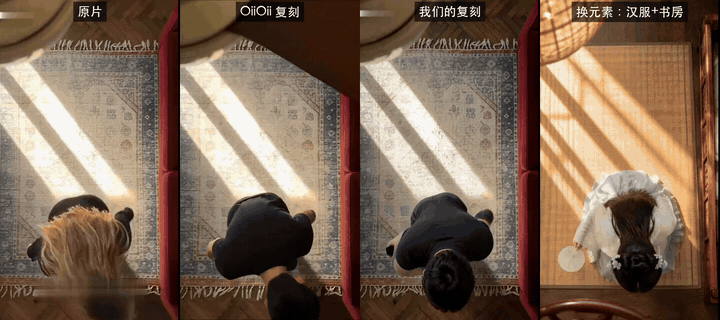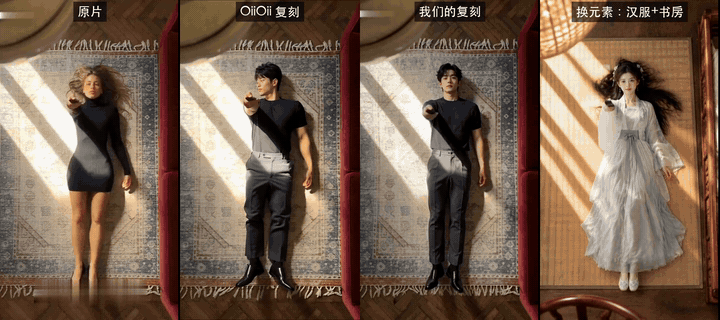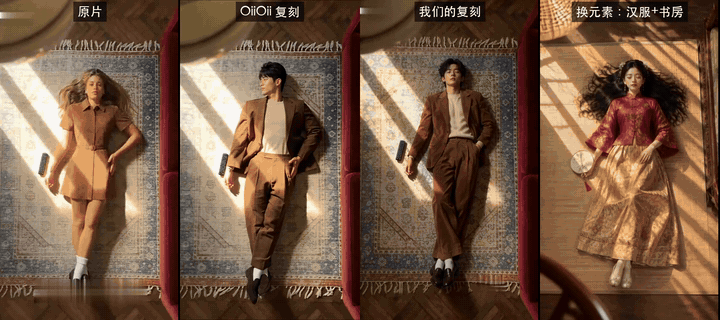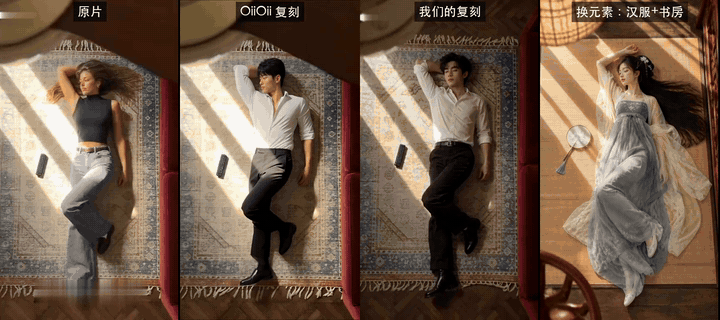
Overhead outfit change · 12 s
Same swap: woman → man, three outfits → matching menswear. Element swap: a girl in three historical Hanfu outfits in a Chinese study; the remote becomes a round fan.

HD comparison video (with audio) · same-moment stills
Paper-craft / watercolor animation · 30 s
Same swap: new clay girl as the lead. Element swap: a fox; forest → coral reef, clouds → starry sky, sunset → aurora.

HD comparison video (with audio) · same-moment stills
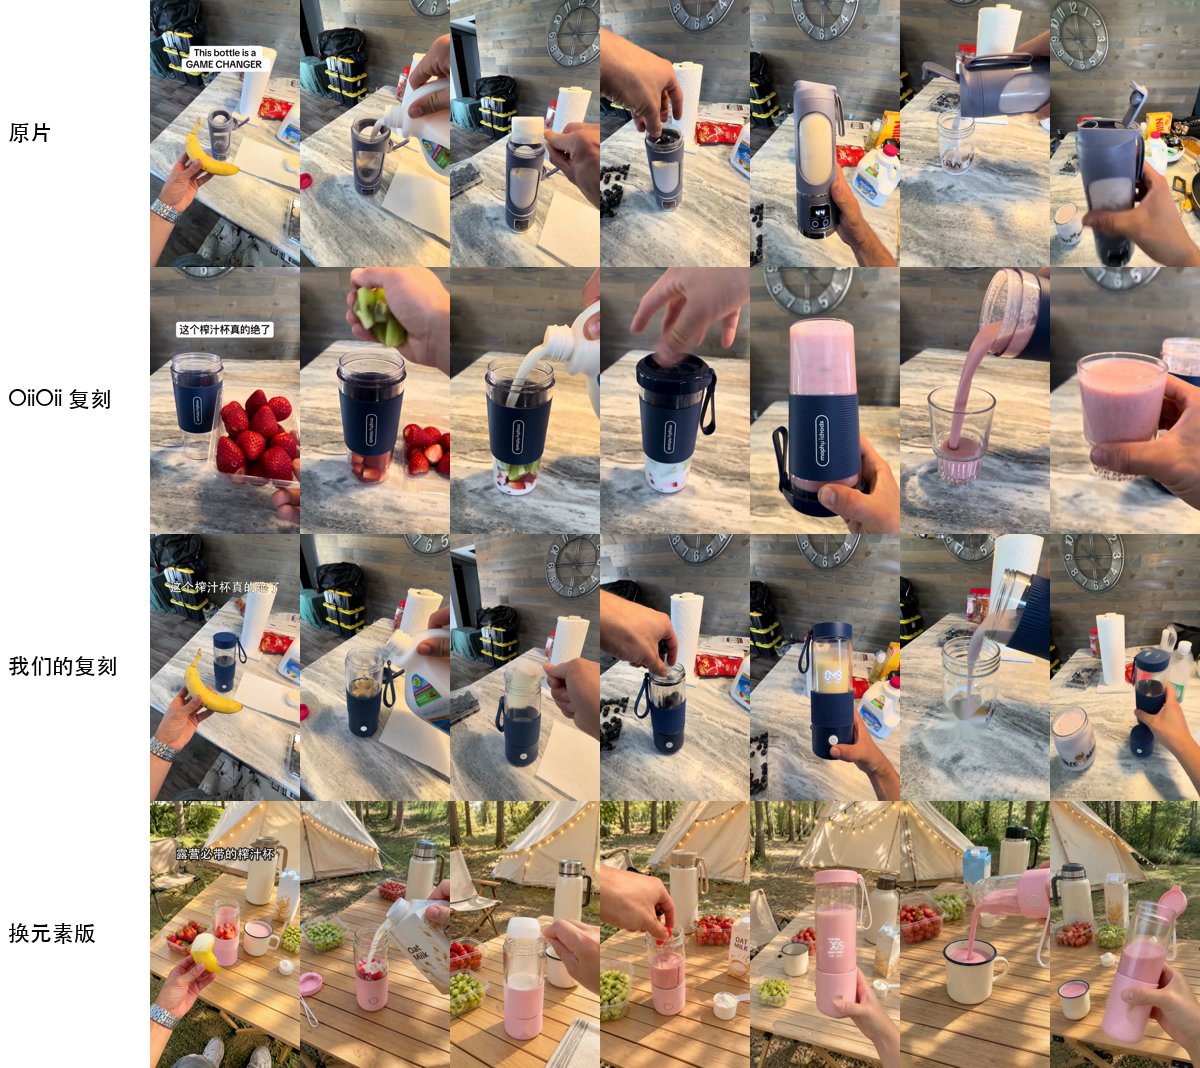
Handheld product video · 21 s · 11 shots
Same swap: an original new product, English sticker → Chinese caption. Element swap: pink product, kitchen → camping table, new ingredients.

HD comparison video (with audio) · same-moment stills
The HD comparison videos use the original audio. The originals and OiiOii versions come from the articles and are shown for comparison only. ## Accuracy How-it-was-made accuracy, weighted by shot duration: | | Tuning set (15) | Holdout (16) | Re-encoded WeChat videos (10) | |---|---|---|---| | Tools only (offline, free) | 98.3% | 99.6% / 98.9% | 88.6% | | + vision model (Gemini) | — | 99.6% / 99.8% | 99.6% | | + agent visual review | — | 99.6% / 99.8% | 100% | The two holdout numbers are holdout (9 videos) and holdout2 (7 videos). On original files the tools alone are mostly enough. Videos downloaded from platforms have been recompressed, which wipes out the noise evidence, so it takes a vision check to get back above 99%. Real-asset detection is 97–99%, and shot boundaries are all correct. Numbers and how to reproduce them: [eval/RESULTS.md](eval/RESULTS.md). ## How it works ![rea-video pipeline](docs/rea-flow_en.svg) 1. Split: cut the video into shots and separate audio into voice, music and effects. 2. Gather evidence: measure the frames (frame cadence, sensor noise, whether the whole image is panning as one plane, AIGC tags in metadata); look at the images (hands, text, physics); listen (BPM, key, singing vs speech). 3. Decide: hard evidence like AIGC tags and frame cadence outranks "looks like". Conflicts are flagged for the agent to review visually. 4. Plan the remake: batch shots according to what the target video model can actually do, such as max clip length, multi-shot support and how many reference images it takes. ## FAQ
How is this different from one-click remake tools like Hypit? [Hypit](https://github.com/hypit-ai/hypit) takes a reference video and makes a new one: the agent reads frame grids to understand the original, generates footage with the models it supports (Seedance, PixVerse, MiniMax, Wan and others), and renders captions and motion graphics in HTML. It doesn't ask how the original was made. A live-action source goes through the same pipeline; it won't tell you how many cameras were used or how it was lit. What AI video it can match depends on the models it has: no Kling or Veo, and no dedicated avatar or 3D path, and no AI music: you bring your own. It is strongest on talking-head, podcast and interview videos that follow a script, and weaker on music-driven edits, product motion graphics and cinematic shorts. rea-video doesn't render a video. It works out shot by shot whether something was filmed, AI-generated or built in code, then gives a shooting plan, prompts or a code approach for each. For a quick lookalike, Hypit is faster. To understand how the original was made and remake it cheaply, use rea-video. They work fine together.
Do I need a video-capable model? What does it cost? No. Tools-only mode is offline and free, and already accurate on original files. For recompressed platform downloads, add a video-capable model (Gemini or Doubao both work) or use an agent that can see images; you pay whatever that service charges. Automatic video generation (capsule-cinema) does a free dry run first and only calls paid models after you confirm.
Can it remake the whole video automatically? Partly. With [capsule-cinema](https://github.com/JuneYaooo/cheap-claude-video) installed, AI shots are generated and placed back on the original timeline automatically. Live shots you film from the shooting plan; code shots the agent writes as a Remotion project. See [docs/replicate.md](docs/replicate.md).
Can I just repost someone else's video? No. rea-video is for learning a video's structure, pacing and techniques, then remaking it with material you have the rights to. Don't reuse other people's footage, music, characters or likeness. Follow platform rules and local AI-content labeling requirements when you publish.
## Docs - [docs/what-it-detects.md](docs/what-it-detects.md): everything it detects (10 visual types, camera, lighting, grade, audio) - [docs/replicate.md](docs/replicate.md): remaking from the report - [docs/cases.md](docs/cases.md): case details - [docs/decompose.md](docs/decompose.md): detection rules - [docs/cli.md](docs/cli.md): CLI usage and capsule-cinema integration - [rea_video/capabilities/](rea_video/capabilities/README.md): capability tables for video / image / audio models, used to pick models for the remake plan - [eval/RESULTS.md](eval/RESULTS.md): eval results The docs are in Chinese for now. ## Community Questions, breakdowns and remake ideas: [GitHub Discussions](https://github.com/JuneYaooo/rea-video/discussions). Chat with us on [Discord](https://discord.gg/dZj8D3GqWT). Chinese speakers can also find us on [linux.do](https://linux.do/). Want a video broken down? Open a [request issue](https://github.com/JuneYaooo/rea-video/issues/new?template=request_breakdown.yml) with the link and we'll publish the result as a case. ## Credits Inspired by [REA (Reverse Engineer Anything)](https://github.com/morluto/rea): trace from what you see back to how it was made, back every claim with evidence, and verify by measurement.