**Start here:** [Try the demo](https://OpenMOSS.github.io/MOSS-VL-Demo/#/) · [Quick start](#-quick-start) · [Real-time inference](#real-time-inference) · [Offline inference](#offline-inference) · [Model weights](https://huggingface.co/collections/OpenMOSS-Team/moss-vl)
https://github.com/user-attachments/assets/678ec713-0e01-4792-a5b3-c72e483c4d5f
# MOSS-VL
**MOSS-VL** is an open-weight model series for long-form, real-time video understanding, built on a unified **cross-attention** architecture. All three models are 11B-parameter and open-weight.
* **`MOSS-VL-Realtime`**: real-time interaction over continuous video streams — interruptible at any moment, answering on the fly, and deciding on its own when to respond and when to keep watching.
* **`MOSS-VL-Instruct`**: built for offline use, with particular strength in complex long-video understanding and in-depth dialogue.
* **`MOSS-VL-Base`**: an open pre-trained foundation offering strong video–language representations for continued pre-training and downstream fine-tuning.
Unlike the default paradigm of offline video models ("watch first, answer after"), **MOSS-VL-Realtime** is designed for real-time interaction on continuous video streams: it runs multimodal perception and text generation in parallel on a continuously arriving stream, natively supporting multi-turn real-time dialogue and dynamic scene understanding, autonomously deciding when to speak, achieving fine-grained temporal grounding, and streaming its responses.
---
### Key Enhancements
* **Interruptible & Real-time**: Breaking the limits of offline processing, users can ask questions at any timestamp in the video stream. The model instantly responds based on the currently received frames, achieving open-source SOTA latency in streaming interaction.
* **Proactive Silence**: Equipped with dynamic judgment capabilities, the model autonomously stays silent and continues observing when contextual information is insufficient or no key events have occurred.
* **Dynamic Correction**: Cognition updates dynamically with the visual feed. As new frames continue to stream in, the model can instantly capture state changes and correct its previous outputs.
### Core Architecture
At the architectural level, **MOSS-VL-Realtime** adopts the following core designs:
- **Cross-Attention Architecture**: Decouples visual encoding from language reasoning, significantly reducing response latency on dynamic video streams, with native support for interleaved image, video, and text inputs.
- **Absolute Timestamps**: Every sampled frame is anchored to a precise time marker via dedicated special tokens. The model uses this to reason about pacing, duration, and motion dynamics, and it natively adapts to variable frame rates.
- **XRoPE (Cross-Attention Rotary Position Embedding)**: Maps text tokens and video patches into a unified 3D `(t, h, w)` coordinate space, enabling patch-level and moment-level grounding across the entire video.
---
## 🔥 News
- **2026/09/21**: 🌐 Bundled the realtime demo ([`./third_party/realtime-demo/`](./third_party/realtime-demo/)) — a complete frontend-plus-backend application with a built-in memory system, plus ASR and local/cloud TTS for full voice interaction, running on the SGLang-Omni inference backend.
- **2026/09/18**: ⚡ Bundled the specialized SGLang-Omni realtime inference backend ([`./third_party/sglang-omni/`](./third_party/sglang-omni/)): dynamic multi-session scheduling and data-parallel replicas serve multiple concurrent video streams with substantially higher throughput, using the [MOSS-VL-Realtime-SGLANG](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Realtime-SGLANG) checkpoint.
- **2026/08/31**: ⚖️ Published the MOSS-VL quantization tutorial ([English](quantization/README.md) | [中文](quantization/README_zh.md)): our FP8-Dynamic and NF4 recipes, KV-cache quantization, and how to quantize your own fine-tuned (e.g. SFT) MOSS-VL checkpoints.
- **2026/08/28**: 📋 Released the [list of open-source datasets](docs/open_source_datasets.md) used in MOSS-VL training.
- **2026/08/21**: 🤝 MOSS-VL is now supported by [ms-swift](https://github.com/modelscope/ms-swift), enabling image/video inference with `swift infer` and LoRA or full-parameter fine-tuning with `swift sft`. See [PR #9944](https://github.com/modelscope/ms-swift/pull/9944).
- **2026/08/15**: 📚 Published the [MOSS-VL Technical Report](https://arxiv.org/abs/2608.15045) on arXiv, covering the model architecture, training curriculum, real-time inference system, and comprehensive offline and streaming evaluations.
- **2026/08/14**: 🤝 MOSS-VL is now supported by [LlamaFactory](https://github.com/hiyouga/LlamaFactory), with LoRA and full fine-tuning workflows available out of the box. See the [English tutorial](https://blog.llamafactory.net/en/posts/moss_vl_finetuning/) or [Chinese tutorial](https://blog.llamafactory.net/posts/moss_vl_finetuning/), and the [Mosi AI blog post](https://mosi.cn/blog/moss-vl-llamafactory).
- **2026/08/11**: ⚡ Released 24 GiB quantized checkpoints for MOSS-VL, with FP8 and NF4 variants for both Instruct-0708 and Realtime: **MOSS-VL-Instruct-0708-FP8** ([Hugging Face](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0708-FP8) | [ModelScope](https://modelscope.cn/models/openmoss/MOSS-VL-Instruct-0708-FP8)), **MOSS-VL-Instruct-0708-NF4** ([Hugging Face](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0708-NF4) | [ModelScope](https://www.modelscope.cn/models/openmoss/MOSS-VL-Instruct-0708-NF4)), **MOSS-VL-Realtime-FP8** ([Hugging Face](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Realtime-FP8) | [ModelScope](https://www.modelscope.cn/models/openmoss/MOSS-VL-Realtime-FP8)) and **MOSS-VL-Realtime-NF4** ([Hugging Face](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Realtime-NF4) | [ModelScope](https://modelscope.cn/models/openmoss/MOSS-VL-Realtime-NF4)), enabling efficient inference on a single 24 GB NVIDIA GPU.
- **2026/07/14**: 🏆 MOSS-VL-Realtime achieved **66.0 on PA@OmniMMI** and received an official shout-out from [OmniMMI](https://github.com/OmniMMI/OmniMMI).
- **2026/07/14**: 🚀 Released **[MOSS-VL-Realtime](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Realtime)** for real-time video understanding on continuous streams, together with the new **[MOSS-VL-Instruct-0708](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0708)** and **[MOSS-VL-Base-0708](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Base-0708)**.
- **2026/04/24**: 🚀 SGLang officially supports MOSS-VL; see [sgl-project/sglang](https://github.com/sgl-project/sglang).
- **2026/04/22**: 🚀 Released SGLang-based inference support for MOSS-VL. See [`./third_party/sglang/`](./third_party/sglang/).
- **2026/04/22**: 🤗 Updated HuggingFace inference code to the latest version.
- **2026/04/08**: 🚀 Released [MOSS-VL-Base-0408](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Base-0408) and [MOSS-VL-Instruct-0408](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0408).
---
## 📊 Performance
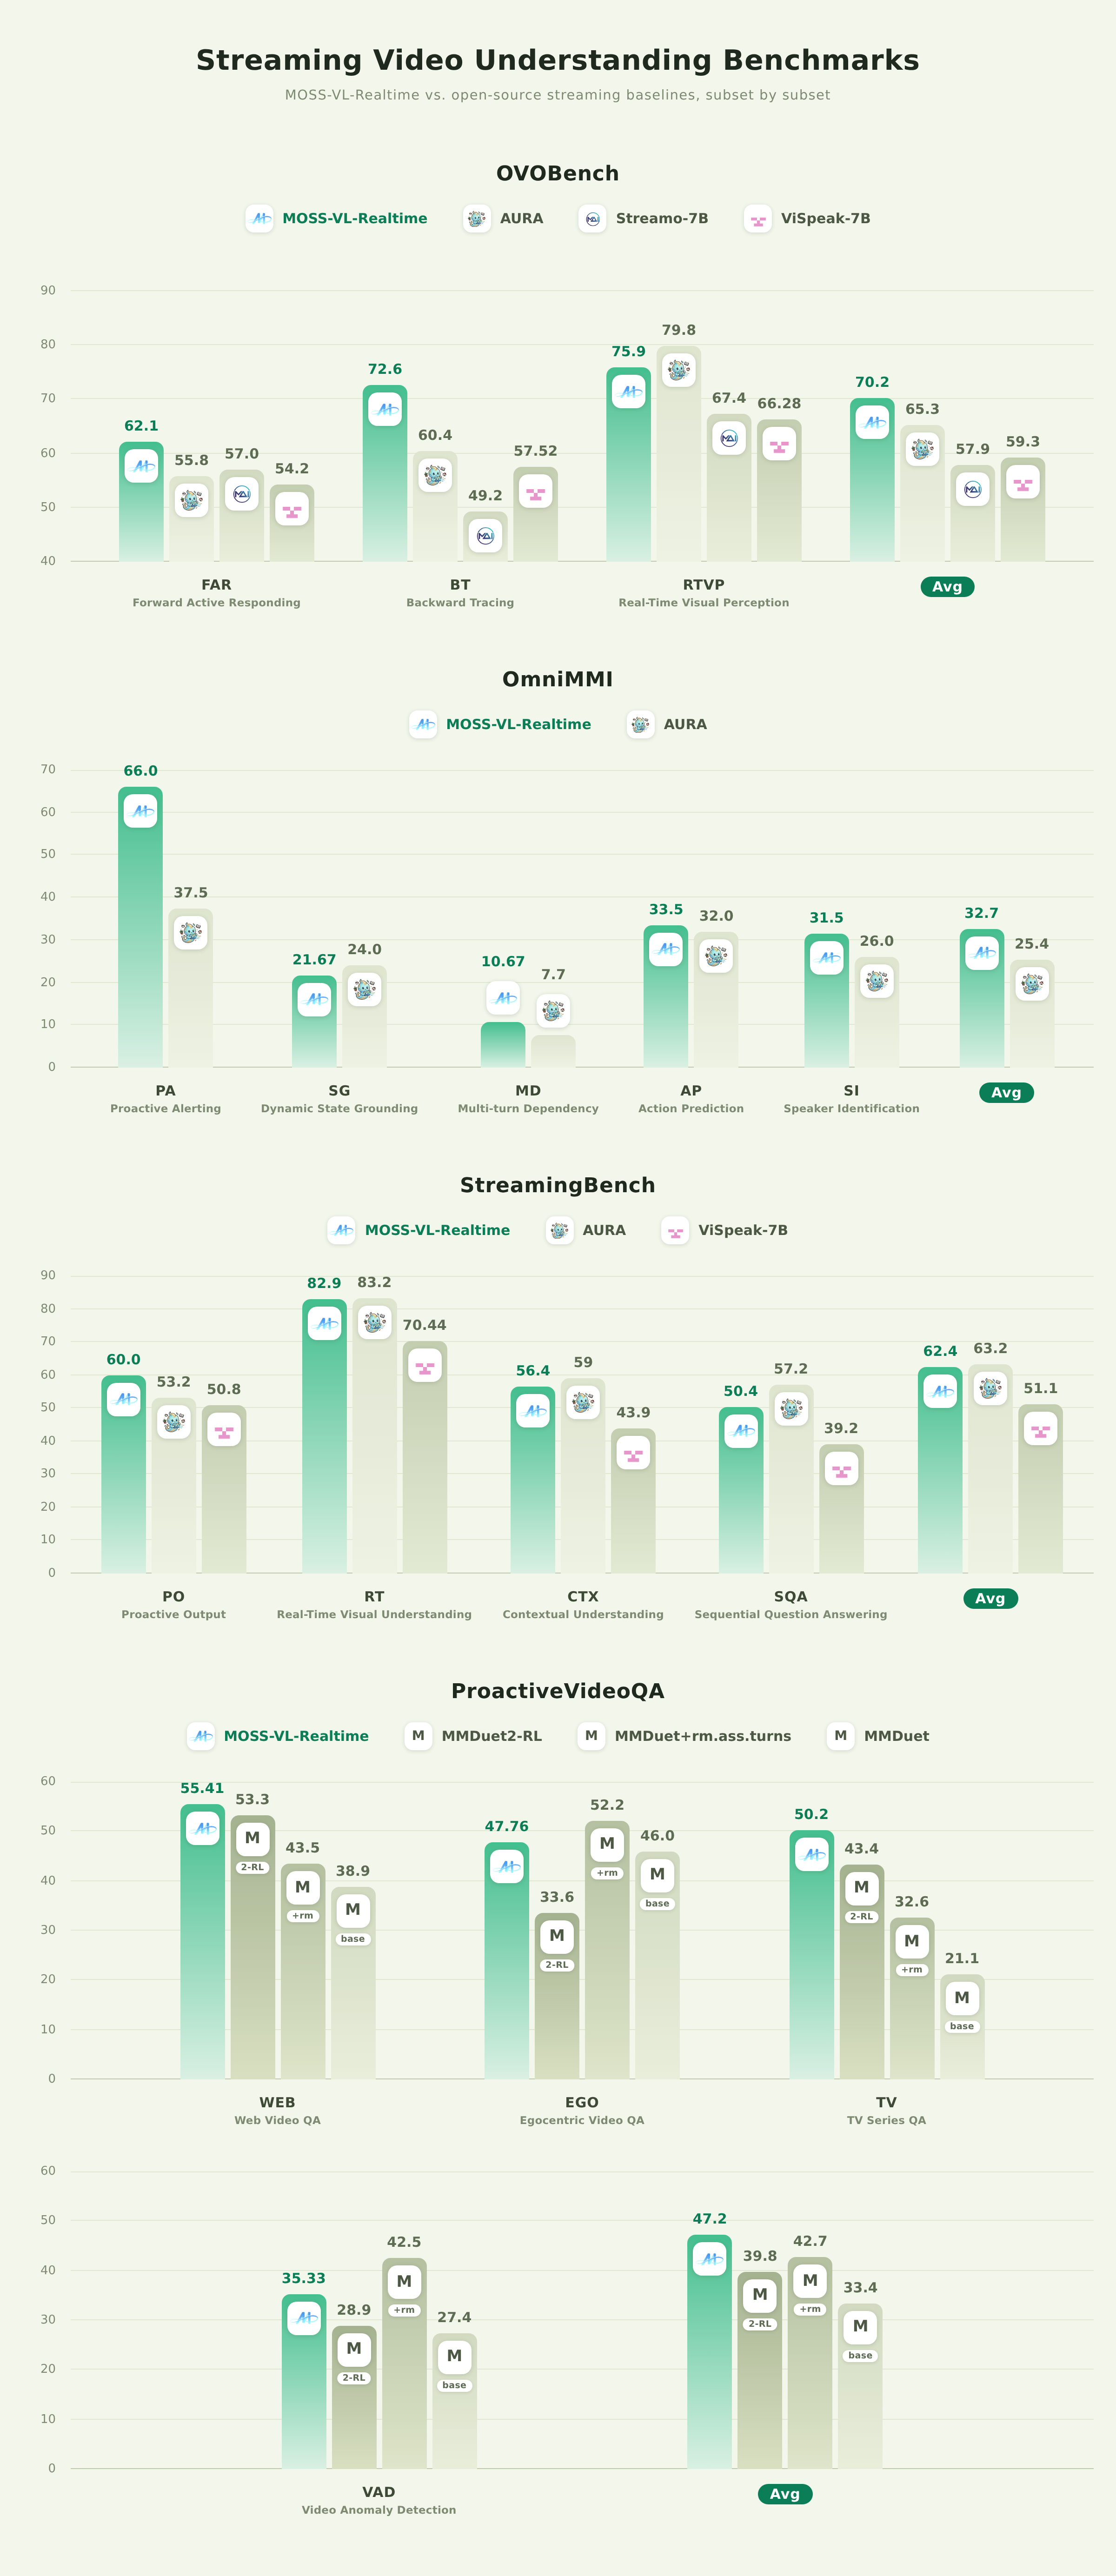
MOSS-VL-Realtime delivers significantly stronger streaming interaction capabilities, achieving open-source SOTA results on multiple streaming video understanding benchmarks. Its "proactive speaking" ability stands out in particular: the model leads on all three proactivity evaluations — Proactive Alerting in OmniMMI, Proactive Output in StreamingBench, and ProactiveVideoQA.
### Streaming Benchmark
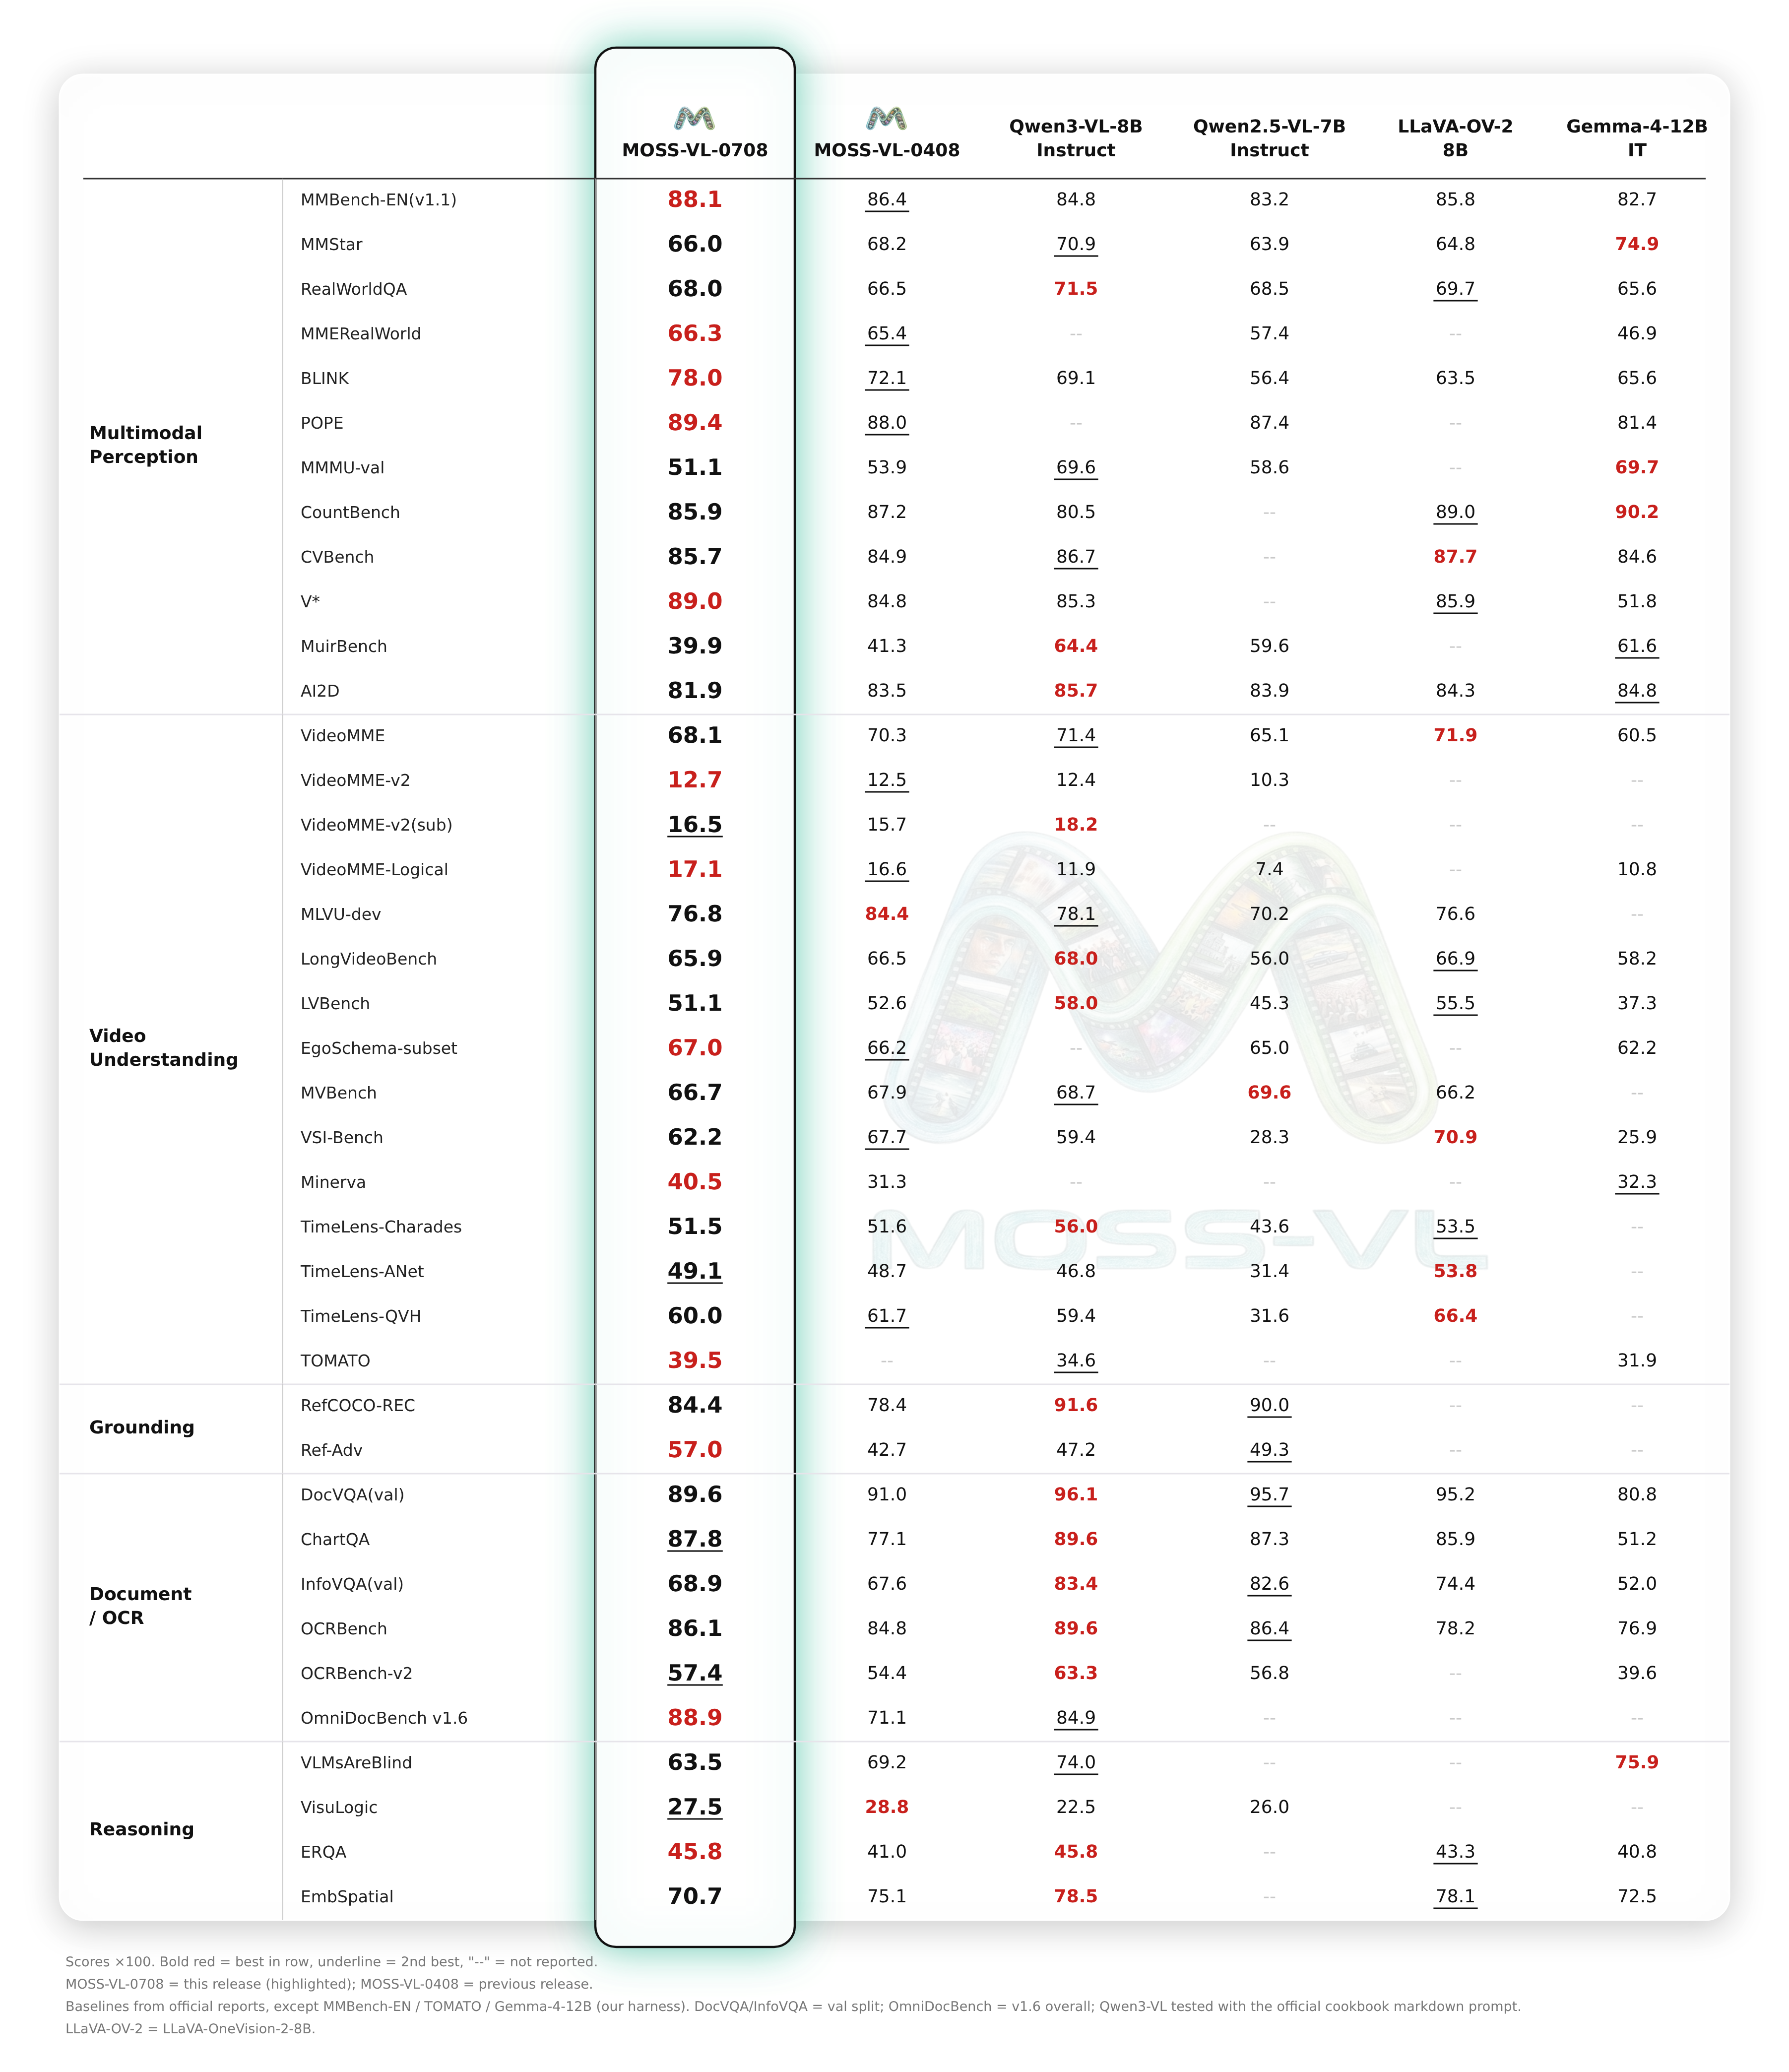
We have systematically restructured and deeply optimized our data system, comprehensively strengthening the model's foundational capabilities and instruction-interaction experience, while maintaining a high level of stability across offline evaluations.
Offline Multimodal Benchmark — Click to Expand
> For comprehensive benchmark breakdowns, comparison systems, and detailed tables of all objective metrics, please refer to our **[Technical Blog](https://openmoss.ai/MOSS-VL/)**.
---
## 🚀 Quick Start
### Environment Setup
```bash
conda create -n moss_vl python=3.12 pip -y
conda activate moss_vl
pip install -i https://pypi.org/simple --no-build-isolation -r requirements.txt
```
### Real-time Inference
Real-time inference consumes timestamped frames incrementally, so the model can keep perceiving a live video stream while it answers and can accept new questions at any time. The fastest way to replay a local video against its media clock is:
```bash
CUDA_VISIBLE_DEVICES=0 python inference/realtime/run_online_inference.py \
--checkpoint OpenMOSS-Team/MOSS-VL-Realtime \
--source video \
--video path/to/example.mp4 \
--sample-fps 1 \
--playback-speed 1 \
--max-frames 256
```
Keep `--playback-speed 1` for model inference so frames arrive on the original timeline. The runtime provides three integration levels:
- `model.create_realtime_session(...)` for direct frame, prompt, and output control
- `model.online_generate(...)` for queue-based inference workers
- `--serve` for a FastAPI WebSocket service that accepts external JPEG/PNG frames or replays server-local videos
It also supports streaming JSONL samples, cameras, screen capture, and synthetic sources. See [`inference/realtime/README.md`](./inference/realtime/README.md) for the complete CLI, input format, and WebSocket protocol.
For production multi-stream serving, use the specialized SGLang-Omni backend in [`third_party/sglang-omni/`](./third_party/sglang-omni/): dynamic multi-session scheduling and data-parallel replicas deliver substantially higher realtime throughput. A complete full-stack demo — browser frontend, service backend, built-in memory system, and ASR/TTS voice input and output — is packaged in [`third_party/realtime-demo/`](./third_party/realtime-demo/).
### Offline Inference
Offline inference supports full-modality queries (interleaved text, image, and video inputs). The fastest way to get a first result is `offline_batch_generate`:
```python
import torch
from transformers import AutoModelForCausalLM, AutoProcessor
checkpoint = "OpenMOSS-Team/MOSS-VL-Realtime"
processor = AutoProcessor.from_pretrained(checkpoint, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
checkpoint, trust_remote_code=True, device_map="auto", torch_dtype=torch.bfloat16
)
queries = [{
"messages": [{"role": "user", "content": [
{"type": "image", "image": "path/to/example.jpg"},
{"type": "text", "text": "Describe this image."}
]}],
"generate_kwargs": {"max_new_tokens": 256, "do_sample": False},
}]
with torch.no_grad():
result = model.offline_batch_generate(processor, queries)
print([item["text"] for item in result["results"]])
```
---
## 🛠️ Advanced Resources & Ecosystem
### Specialized FlashAttention-3 Backend
The [`third_party/flash-attention-src/`](./third_party/flash-attention-src/) directory contains the
FlashAttention-3 backend used by MOSS-VL cross-attention. It adds the
`cross_kv_boundary` interface, which represents the visible KV prefix of each
query row with one `int32` value instead of materializing a dense attention
mask. The source is derived from upstream FlashAttention and is bundled here
with its original license and attribution. See
[`third_party/flash-attention-src/README.md`](./third_party/flash-attention-src/README.md) for the mask
contract, supported paths, build instructions, and source lineage.
### Deployment & Inference Engines
MOSS-VL can also be efficiently deployed with the following inference backends:
- **SGLang**: see [`third_party/sglang/README.md`](./third_party/sglang/README.md)
- **SGLang-Omni (realtime serving)**: specialized multi-session realtime backend with dynamic scheduling and data-parallel replicas — see [`third_party/sglang-omni/README.md`](./third_party/sglang-omni/README.md)
### Fine-Tuning
We provide a lightweight SFT framework built on HuggingFace `transformers.Trainer`. It supports full-parameter training and LoRA, with the vision encoder, language model, and LM head independently controllable.
```bash
# Full-parameter SFT (vision encoder frozen by default)
bash finetune/scripts/run_sft.sh
# LoRA SFT
pip install -i https://pypi.org/simple peft
bash finetune/scripts/run_sft_lora.sh
```
See [`finetune/README.md`](finetune/README.md) for full documentation.
MOSS-VL also works out of the box with the mainstream fine-tuning frameworks [LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory) ([PR #10708](https://github.com/hiyouga/LLaMA-Factory/pull/10708)) and [ms-swift](https://github.com/modelscope/ms-swift) ([PR #9944](https://github.com/modelscope/ms-swift/pull/9944)) — both LoRA and full-parameter fine-tuning are supported.
### Quantization
We release FP8 and NF4 quantized checkpoints for both Instruct-0708 and Realtime, and share the calibration-free PTQ recipes behind them in [`quantization/README.md`](quantization/README.md) ([中文教程](quantization/README_zh.md)). The guide covers selective layer coverage — which language-model Linears to quantize versus which multimodal modules stay in BF16 — runtime KV-cache quantization for Transformers and SGLang, and reproduction scripts that work directly on your own fine-tuned or SFT checkpoints.
### Model Download
This generation ships three models from the same rebuilt data: **MOSS-VL-Realtime** for continuous video streams, **Instruct** for offline tasks, and **Base** for continued pre-training and fine-tuning.
| Model | Params | Context | Best for | 🤗 HuggingFace | 🤖 ModelScope |
| :--- | :---: | :---: | :--- | :--- | :--- |
| **MOSS-VL-Realtime** | `11B` | `256K` | Real-time interaction on continuous video streams | [Link](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Realtime) | [Link](https://www.modelscope.cn/models/openmoss/MOSS-VL-Realtime-0708) |
| **MOSS-VL-Instruct-0708** | `11B` | `256K` | Offline chat / inference / downstream tasks | [Link](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0708) | [Link](https://www.modelscope.cn/models/openmoss/MOSS-VL-Instruct-0708) |
| **MOSS-VL-Base-0708** | `11B` | `256K` | Continued pre-training / fine-tuning | [Link](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Base-0708) | [Link](https://www.modelscope.cn/models/openmoss/MOSS-VL-Base-0708) |
**Previous generation:**
| Model | Params | Context | Best for | 🤗 HuggingFace | 🤖 ModelScope |
| :--- | :---: | :---: | :--- | :--- | :--- |
| **MOSS-VL-Base-0408** | `11B` | `256K` | Continued pre-training / fine-tuning | [Link](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Base-0408) | [Link](https://modelscope.cn/models/openmoss/MOSS-VL-Base-0408) |
| **MOSS-VL-Instruct-0408** | `11B` | `256K` | Chat / inference / downstream tasks | [Link](https://huggingface.co/OpenMOSS-Team/MOSS-VL-Instruct-0408) | [Link](https://modelscope.cn/models/openmoss/MOSS-VL-Instruct-0408) |
---
## 📑 Roadmap & TODO List
### ✅ Milestones
- [x] **Core Architecture:** Implementation of Cross-attention RoPE (XRoPE).
- [x] **High-performance Infra:** Integrated Megatron-LM + CUDA Flash Attention 3.
- [x] **Model Release:** Open-sourced `MOSS-VL-Base` and `MOSS-VL-Instruct`.
- [x] **Inference:** Inference code for both image and video understanding.
- [x] **Real-time Capabilities:** Released **MOSS-VL-Realtime** — real-time video understanding on continuous streams.
### 🚀 Upcoming
- [ ] **Training Engine:** Full training code for MOSS-VL.
- [ ] **RL Post-training:** Reinforcement Learning for MOSS-VL series.
- [x] **Documentation:** Published the MOSS-VL Technical Report.
- [ ] **Cookbooks:** Task-level runnable notebooks.
---
## 🤝 Acknowledgement
We would like to express our gratitude to **NVIDIA** for the [Megatron-LM](https://github.com/NVIDIA/Megatron-LM) framework and the **Qwen Team** for their powerful [Qwen](https://github.com/QwenLM/Qwen) series language models, which serve as the foundation of our training infrastructure and core LLM. We also thank the **SGLang Team** for their high-performance [SGLang](https://github.com/sgl-project/sglang) serving framework, which powers efficient deployment of MOSS-VL.
## 📜 Citation
```bibtex
@misc{mossvl,
title = {MOSS-VL Technical Report},
author = {Wang, Pengyu and Tan, Chenkun and Zhou, Shaojun and Zhou, Qirui and Chen, Yanxin and He, Xingyang and Zeng, Huazheng and Cheng, Jijun and Wang, Chenghao and Qian, Xiaomeng and Wang, Pengfei and Huang, Zhan and Gao, Shanqing and Huang, Wei and Cao, Longjun and Ran, Wu and Liu, Jie and Zhu, Changtai and Wang, Hongkai and Tian, Yixian and Liu, Chenghao and Ye, Zhen and Wang, Xinghao and Jiang, Botian and Feng, Guoguo and Fei, Zhaoye and Li, Ruixiao and Chen, Mingshu and Gao, Yang and Cheng, Qinyuan and Li, Shimin and Qiu, Xipeng},
year = {2026},
eprint = {2608.15045},
archivePrefix = {arXiv},
primaryClass = {cs.CV},
url = {https://arxiv.org/abs/2608.15045}
}
@misc{mossvideopreview,
title = {{MOSS-Video-Preview: Toward Real-Time Video Understanding via Cross-Attention}},
author = {Pengyu Wang and Chenkun Tan and Shaojun Zhou and Wei Huang and Qirui Zhou and Zhan Huang and Zhen Ye and Jijun Cheng and Xiaomeng Qian and Yanxin Chen and Xingyang He and Huazheng Zeng and Chenghao Wang and Pengfei Wang and Hongkai Wang and Shanqing Gao and Yixian Tian and Chenghao Liu and Xinghao Wang and Botian Jiang and Xipeng Qiu},
year = {2026},
eprint = {2606.07639},
archivePrefix = {arXiv},
primaryClass = {cs.CV},
url = {https://arxiv.org/abs/2606.07639}
}
```
## Star History