 Watch the full demo video
# WildDet3D:
Scaling Promptable 3D Detection in the Wild


Weikai Huang♥1,2
Jieyu Zhang♥1,2
Sijun Li2
Taoyang Jia2
Jiafei Duan1,2
Yunqian Cheng1
Jaemin Cho1,2
Matthew Wallingford1
Rustin Soraki1,2
Chris Dongjoo Kim1
Shuo Liu1,2
Donovan Clay1,2
Taira Anderson1
Winson Han1
Ali Farhadi1,2
Bharath Hariharan3
Zhongzheng Ren♥1,2,4
Ranjay Krishna♥1,2
♥ core contributors
1Allen Institute for AI 2University of Washington 3Cornell University 4UNC-Chapel Hill
## Demo & Applications
|
|
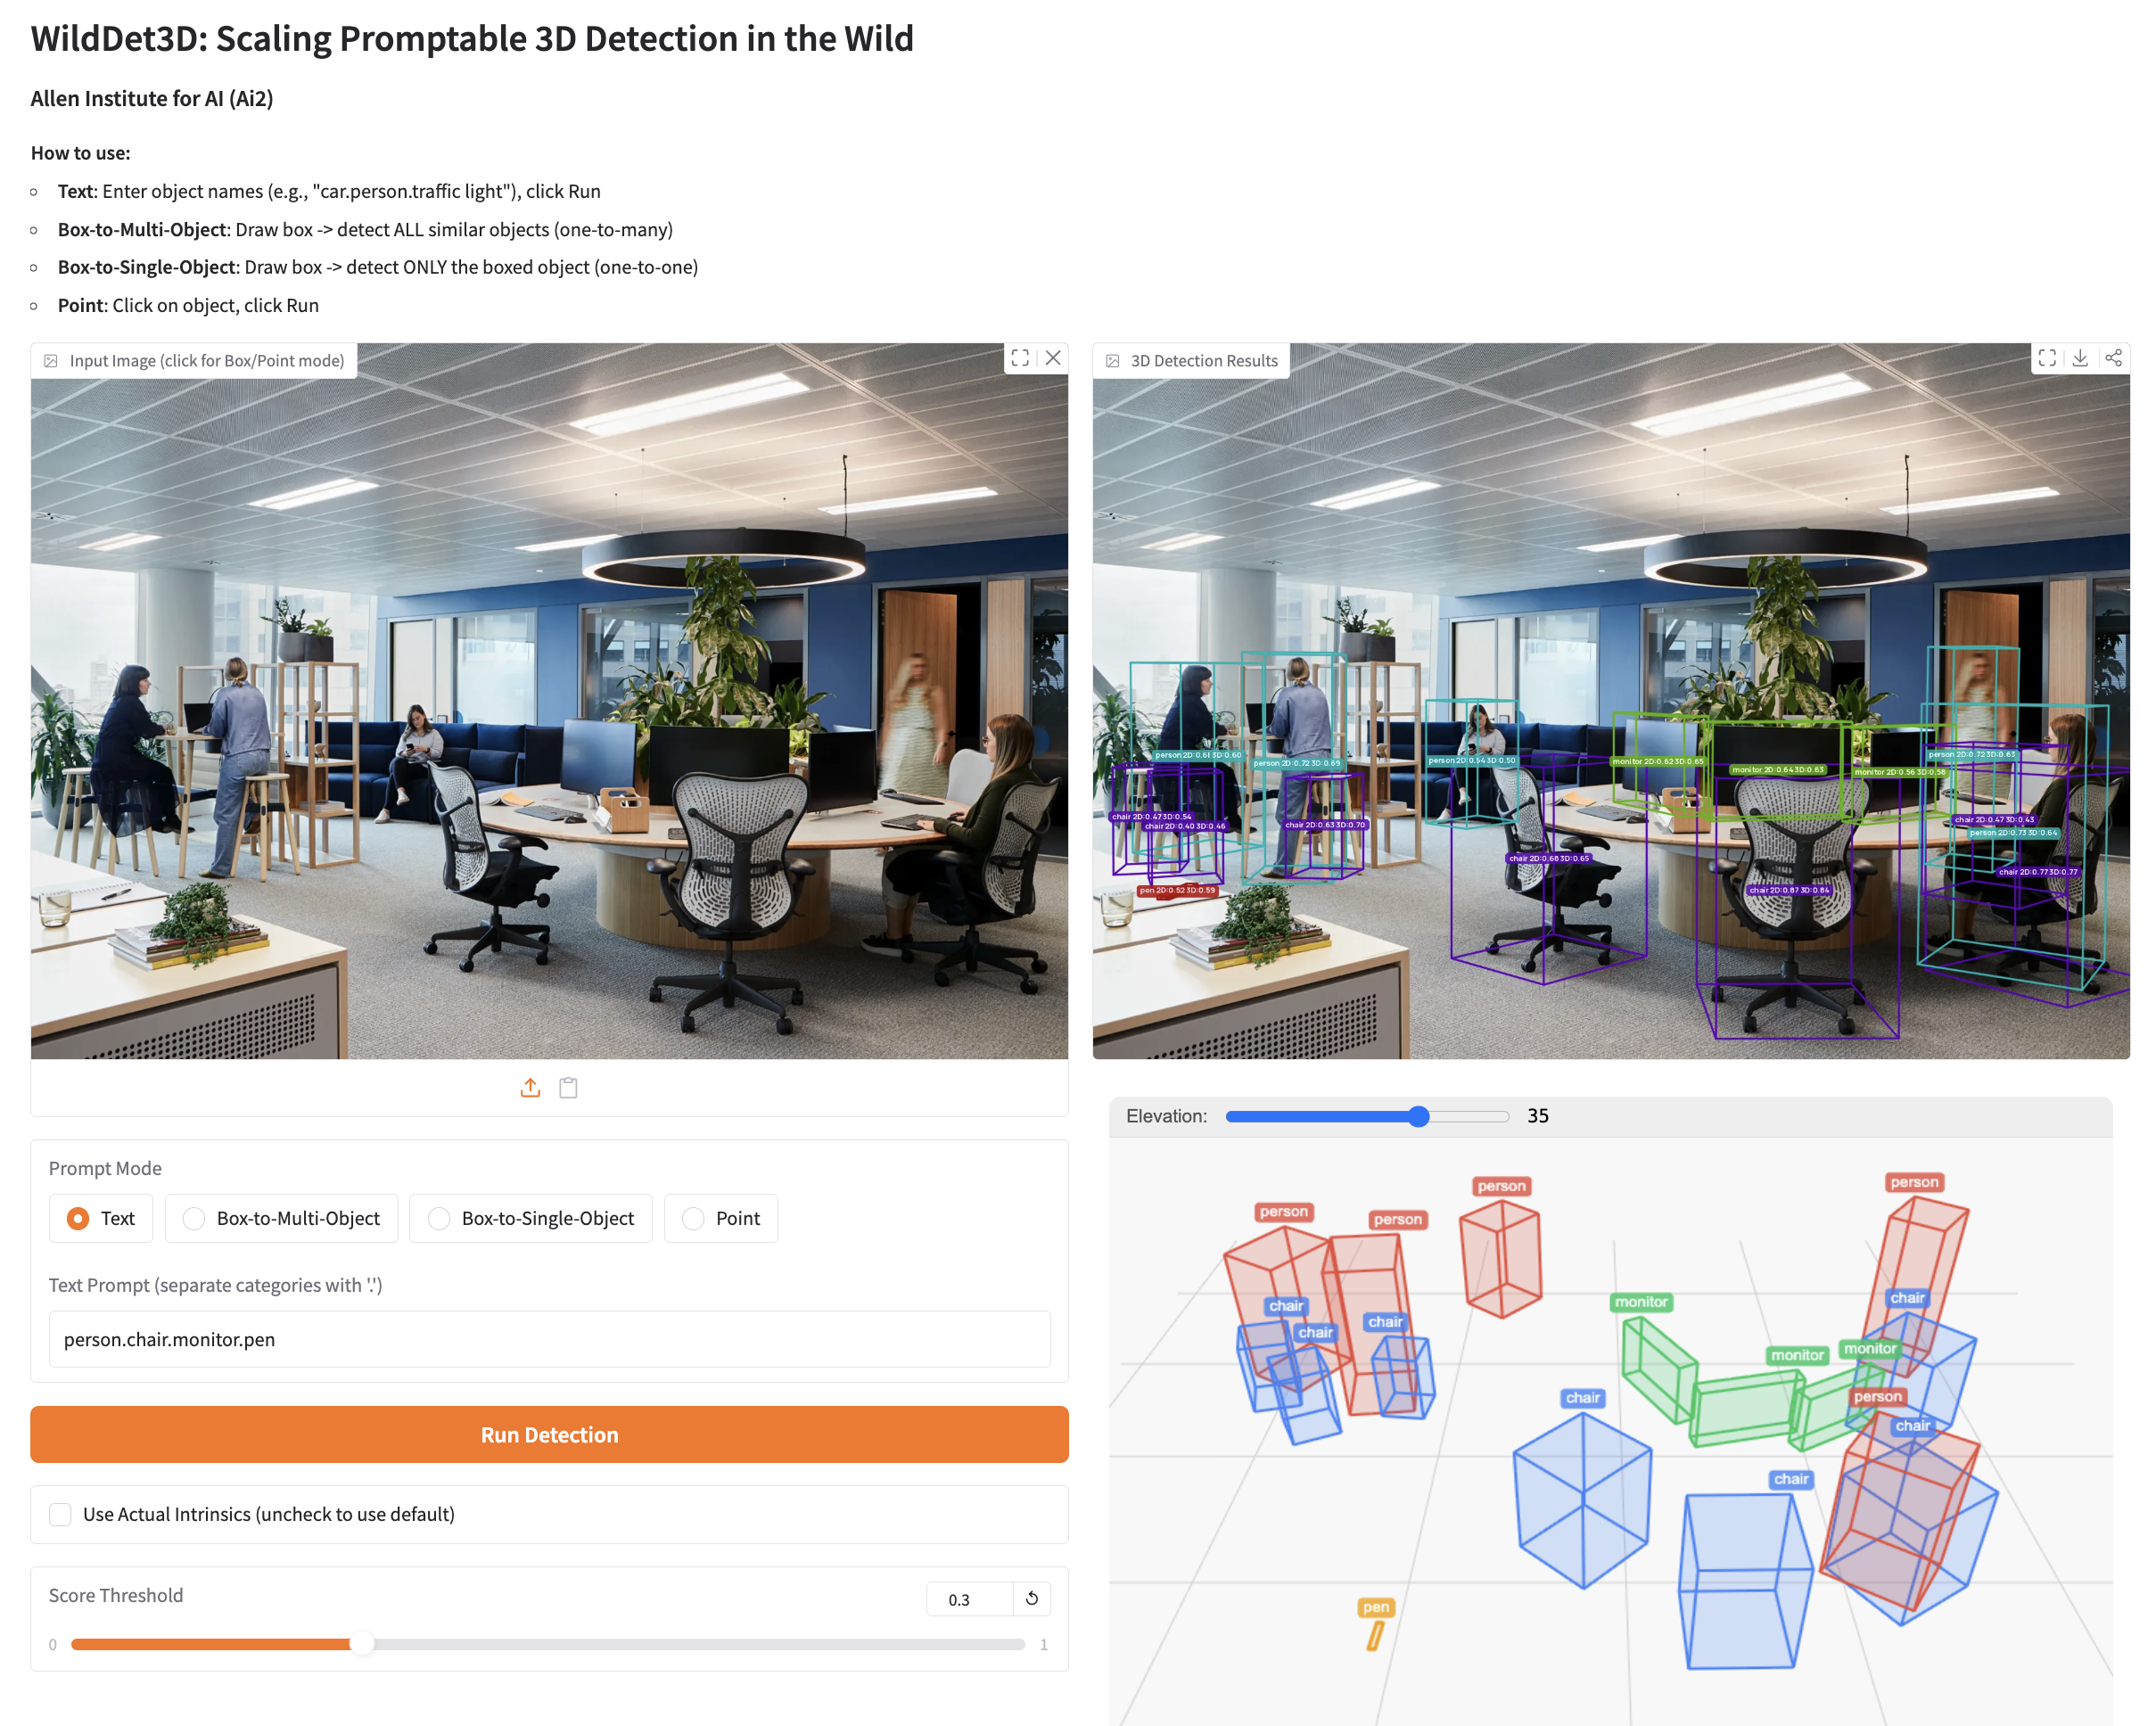
HuggingFace Interactive Demo
Interactive web demo with text, point, and box prompts
Live Demo | Run Locally
|
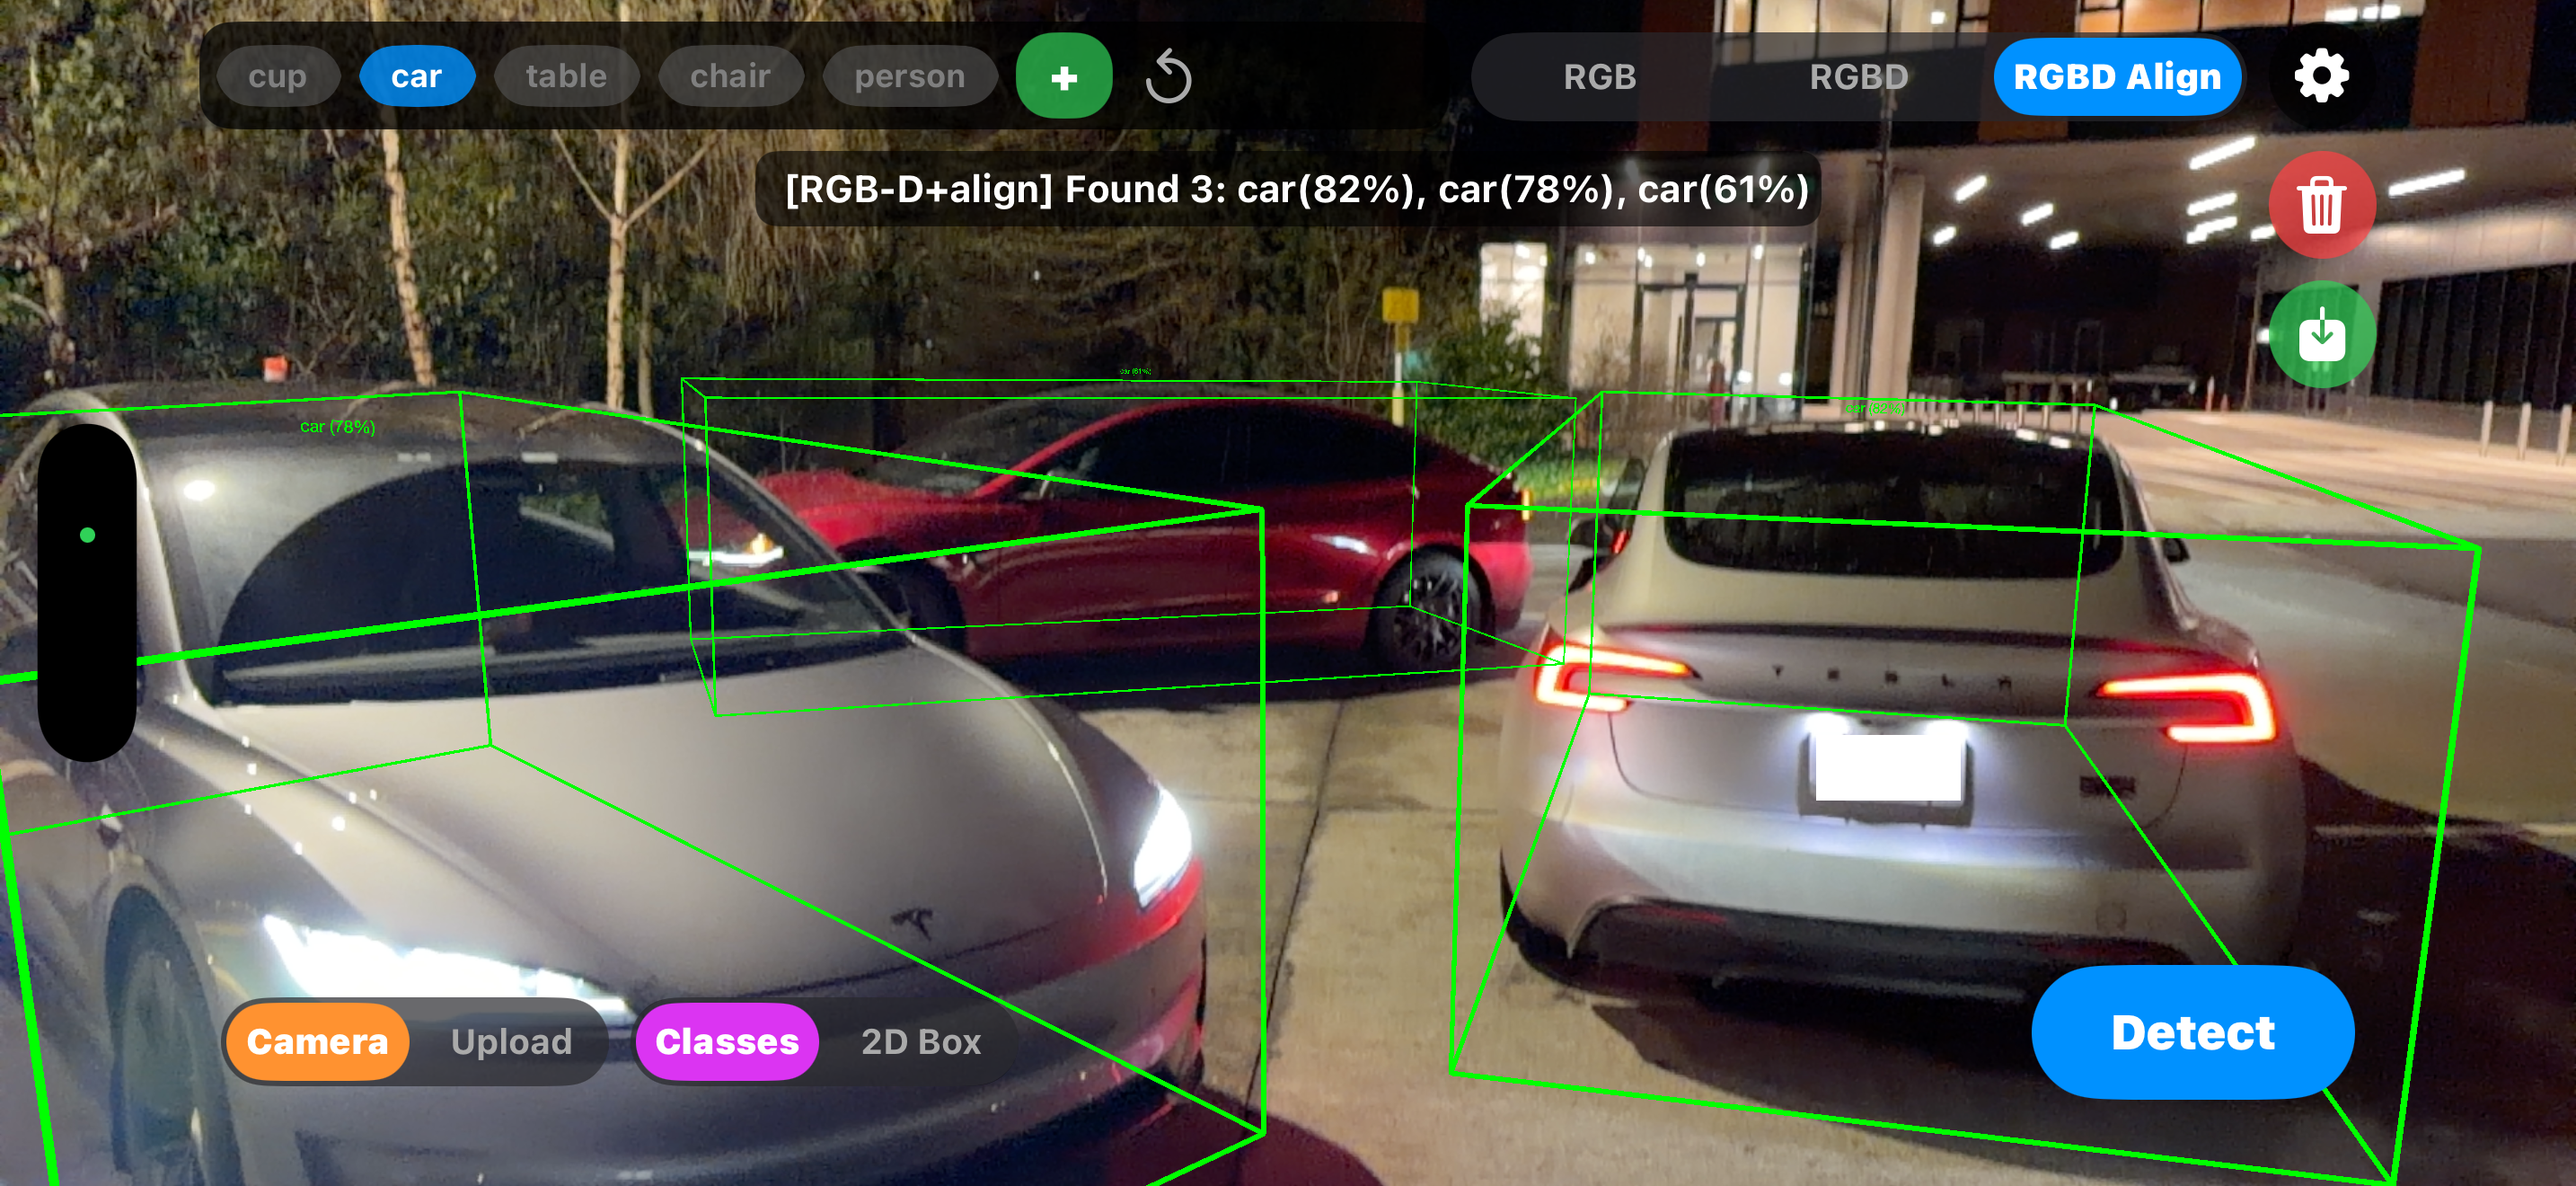
iPhone App
Real-time on-device 3D detection
App Store | Video | README
|
|
|
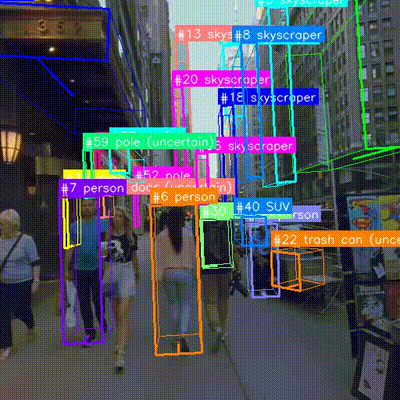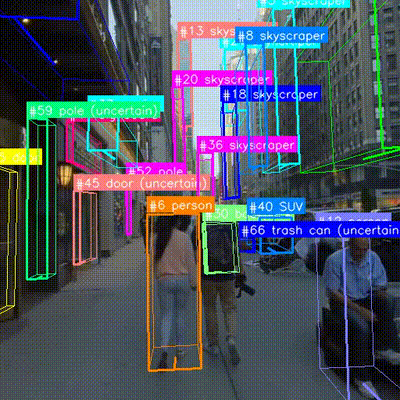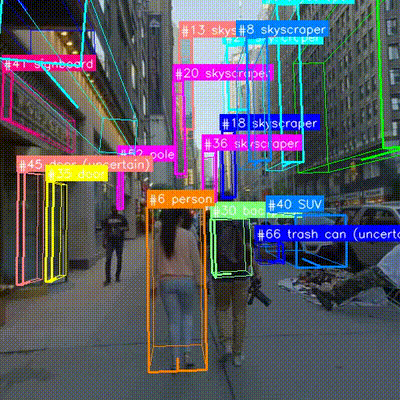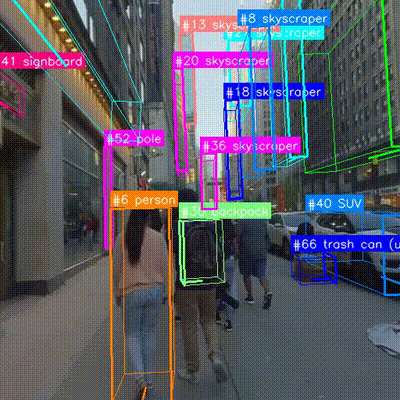
|
Integrate with VLM
Combine with vision-language models
README
|
Zero-Shot Tracking
3D object tracking without training
README
|
|
|
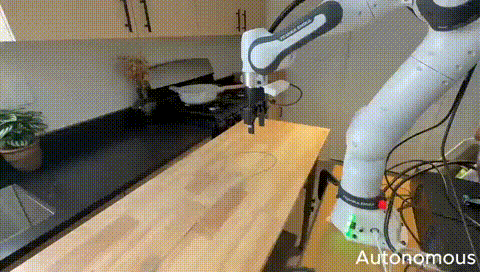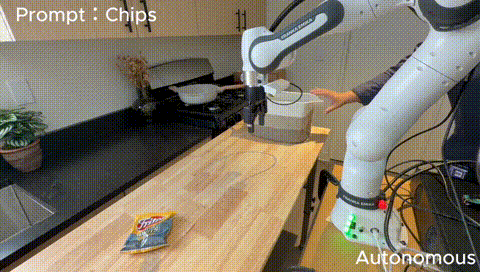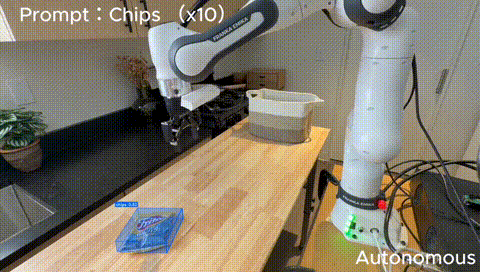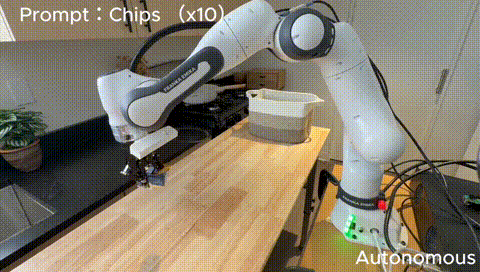
|
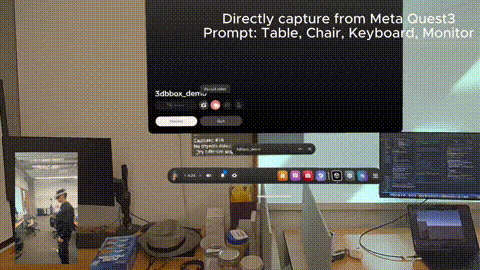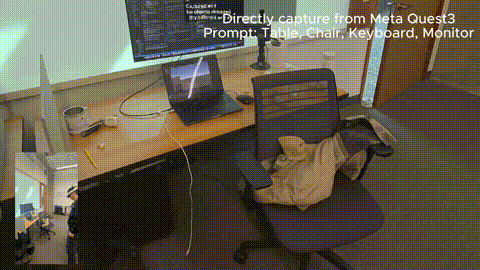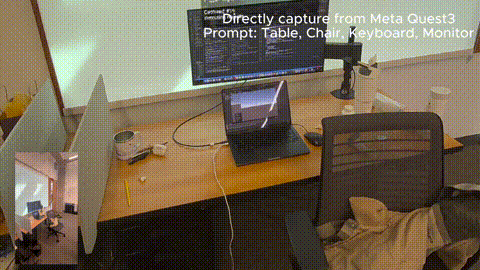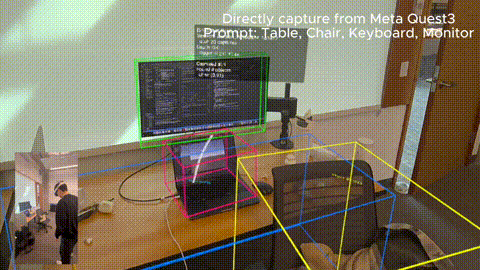
Meta Quest
3D detection in AR/VR
Video
|
Robotics
3D perception for robotic manipulation
Video
|
|
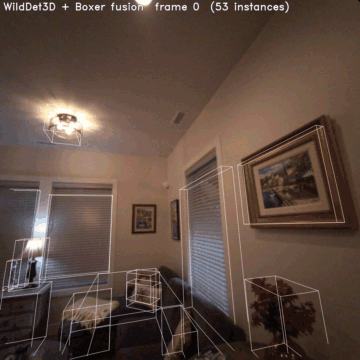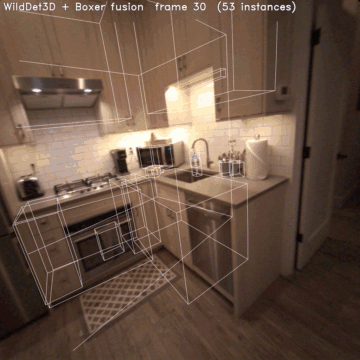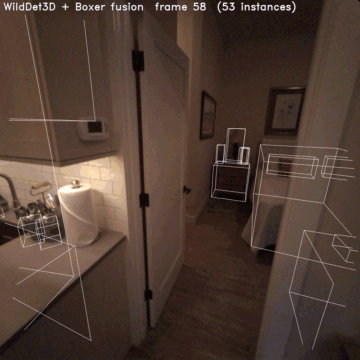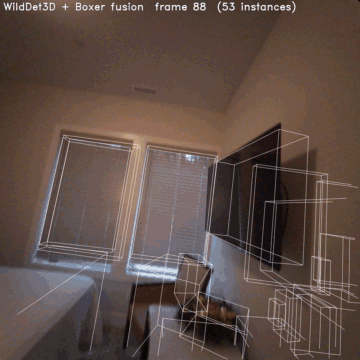
|
Integrating with Meta FAIR's Boxer demo for indoor labelling
WildDet3D replaces OWL + BoxerNet inside Meta FAIR's Boxer indoor labelling pipeline on Project Aria. Boxer's AriaLoader, offline fusion, online tracker, and 3D viewers all run on our outputs unchanged.
README
|
## News
- **2026-05-20** — Released Omni3D, ScanNet, Argoverse 2 evaluation configs (text / box-prompt × mono / GT-depth, 4 modes each). ([#15](https://github.com/allenai/WildDet3D/pull/15))
- **2026-05-18** — Added a Boxer demo: WildDet3D as a drop-in detector for [Meta FAIR's Boxer](https://github.com/facebookresearch/boxer) indoor-labelling pipeline on Project Aria. ([#13](https://github.com/allenai/WildDet3D/pull/13))
- **2026-05-17** — Released FoundationPose data preparation scripts (extract, 3D bbox, Qwen-VLM classifications). ([#12](https://github.com/allenai/WildDet3D/pull/12))
- **2026-04-27** — Coordinate-transform fixes for tracking and the HuggingFace / VLM demos. ([#8](https://github.com/allenai/WildDet3D/pull/8), [#9](https://github.com/allenai/WildDet3D/pull/9))
- **2026-04-19** — Released training code, WildDet3D-Data preparation scripts, and inference / visualization fixes. ([#6](https://github.com/allenai/WildDet3D/pull/6))
- **2026-04-07** — Initial release: inference code, WildDet3D-Bench evaluation, HuggingFace Space, iPhone app, and project page.
## TODO
- [x] Release inference code
- [x] Release WildDet3D-Bench evaluation
- [x] Release training code
- [x] Release evaluation on other benchmarks (Omni3D, Argoverse2, ScanNet)
- [ ] Release WildDet3D-Embodied, WildDet3D finetuning on robotics data like Droid, better for robotics applications or serving as a backbone for robotics models.
## Contents
- [Demo & Applications](#demo--applications)
- [News](#news)
- [Model Weights](#model-weights)
- [Installation](#installation)
- [Inference](#inference)
- [Evaluation](#evaluation)
- [WildDet3D-Bench](#wilddet3d-bench)
- [WildDet3D-Stereo4D-Bench](#wilddet3d-stereo4d-bench)
- [Training](#training)
- [Training Data Preparation](#training-data-preparation) → see [docs/TRAINING_DATA.md](docs/TRAINING_DATA.md)
- [Results](#results)
- [WildDet3D-Bench (In-the-Wild)](#wilddet3d-bench-in-the-wild)
- [Omni3D](#omni3d)
- [Zero-shot Transfer (Argoverse 2 + ScanNet)](#zero-shot-transfer-argoverse-2--scannet)
- [WildDet3D Data](#wilddet3d-data)
- [Citation](#citation)
## Model Weights
| Checkpoint | Stage | Training Recipe | Size | Download |
|---|---|---|---|---|
| `wilddet3d_alldata_all_prompt_v1.0.pt` | Stage 3 (paper) | Stage 2 ckpt → Omni3D + ITW-human mix-prompt finetune, 3 ep | ~4.7 GB | [allenai/WildDet3D](https://huggingface.co/allenai/WildDet3D/resolve/main/wilddet3d_alldata_all_prompt_v1.0.pt) |
| `wilddet3d_stage2_alldata_12e_v1.0.pt` | Stage 2 (intermediate) | Stage 1 ckpt → 8-dataset all-data finetune, 12 ep | ~4.7 GB | [allenai/WildDet3D](https://huggingface.co/allenai/WildDet3D/resolve/main/wilddet3d_stage2_alldata_12e_v1.0.pt) |
| `wilddet3d_stage1_omni3d_12e_v1.0.pt` | Stage 1 (intermediate) | Omni3D-only canonical rotation, 12 ep from scratch | ~4.7 GB | [allenai/WildDet3D](https://huggingface.co/allenai/WildDet3D/resolve/main/wilddet3d_stage1_omni3d_12e_v1.0.pt) |
All three share the same architecture (SAM3 ViT backbone + LingBot-Depth DINOv2 ViT-L/14 geometry backend, ~1.2B params) and the same stripped format (`state_dict` + `epoch`/`step` + `hparams`, optimizer state stripped). Pick the latest stage you need; for the paper numbers, use `wilddet3d_alldata_all_prompt_v1.0.pt`.
```bash
# Download the released paper checkpoint (~4.7 GB)
pip install huggingface_hub
huggingface-cli download allenai/WildDet3D wilddet3d_alldata_all_prompt_v1.0.pt --local-dir ckpt/
```
**Intermediate checkpoints (for partial reproduction of the 3-stage training):**
```bash
# Stage 1 -- Omni3D-only canonical, 12 epochs (~4.7 GB)
huggingface-cli download allenai/WildDet3D wilddet3d_stage1_omni3d_12e_v1.0.pt --local-dir ckpt/
# Stage 2 -- 8-dataset all-data finetune from Stage 1, 12 epochs (~4.7 GB)
huggingface-cli download allenai/WildDet3D wilddet3d_stage2_alldata_12e_v1.0.pt --local-dir ckpt/
```
See [`docs/TRAINING.md`](docs/TRAINING.md) for how to load these as the starting point of the next stage.
## Installation
```bash
git clone --recurse-submodules https://github.com/allenai/WildDet3D.git
cd WildDet3D
# If you forgot --recurse-submodules when cloning:
# git submodule update --init --recursive
# Training also needs MoGe (loss helpers used by the depth backend); clone it under third_party/:
# git clone https://github.com/microsoft/moge.git third_party/moge
conda create -n wilddet3d python=3.11 -y
conda activate wilddet3d
# 1. PyTorch (locked to the tested CUDA / version combination)
pip install torch==2.5.1 torchvision==0.20.1 --index-url https://download.pytorch.org/whl/cu121
# 2. vis4d (pinned to a known-good version; reuses the torch above)
pip install vis4d==1.0.0
# 3. vis4d CUDA ops (built from source, required by wilddet3d/ops)
pip install git+https://github.com/SysCV/vis4d_cuda_ops.git --no-build-isolation --no-cache-dir
# 4. Remaining dependencies (includes sam3's transitive deps;
# sam3 itself is loaded from third_party/sam3 via sys.path injection
# in wilddet3d/__init__.py, no separate install needed)
pip install -r requirements.txt
```
## Inference
```python
from wilddet3d import build_model, preprocess
from wilddet3d.vis.visualize import draw_3d_boxes
import numpy as np
from PIL import Image
# Build model
model = build_model(
checkpoint="ckpt/wilddet3d_alldata_all_prompt_v1.0.pt",
score_threshold=0.3,
skip_pretrained=True,
# Enable this ONLY if you will pass `depth_gt=...` to `model(...)`
# (i.e. you preprocessed the image with `depth=`). Monocular callers
# leave it off.
# use_depth_input_test=True,
)
# Load and preprocess image
image = np.array(Image.open("image.jpg")).astype(np.float32)
# With known camera intrinsics
intrinsics = np.load("intrinsics.npy") # (3, 3)
data = preprocess(image, intrinsics)
# Without intrinsics (uses default: focal=max(H,W), principal point at center)
# data = preprocess(image)
# With a known depth map (e.g., from LiDAR or stereo), pass it through
# the same preprocess. Depth must be (H, W) float32 in meters at the
# original image resolution; preprocess resizes + center-pads it to
# match the model's input_hw (same transforms eval uses).
# depth = np.load("depth.npy") # (H, W) float32, meters
# data = preprocess(image, intrinsics, depth=depth)
# Omit `depth` (or pass None) to let the model use its monocular
# LingBot-Depth prediction instead. When depth is provided, also pass
# `depth_gt=data["depth_gt"].cuda()` to each model(...) call below.
# Text prompt: detect all instances of given categories
results = model(
images=data["images"].cuda(),
intrinsics=data["intrinsics"].cuda()[None],
input_hw=[data["input_hw"]],
original_hw=[data["original_hw"]],
padding=[data["padding"]],
input_texts=["car", "person", "bicycle"],
# depth_gt=data["depth_gt"].cuda(), # include only if preprocess was called with depth=...
)
boxes, boxes3d, scores, scores_2d, scores_3d, class_ids, depth_maps = results
# Box prompt (geometric): lift a 2D box to 3D (one-to-one)
results = model(
images=data["images"].cuda(),
intrinsics=data["intrinsics"].cuda()[None],
input_hw=[data["input_hw"]],
original_hw=[data["original_hw"]],
padding=[data["padding"]],
input_boxes=[[100, 200, 300, 400]], # pixel xyxy
prompt_text="geometric",
# depth_gt=data["depth_gt"].cuda(), # include only if preprocess was called with depth=...
)
# Exemplar prompt: use a 2D box as visual exemplar, find all similar objects (one-to-many)
results = model(
images=data["images"].cuda(),
intrinsics=data["intrinsics"].cuda()[None],
input_hw=[data["input_hw"]],
original_hw=[data["original_hw"]],
padding=[data["padding"]],
input_boxes=[[100, 200, 300, 400]],
prompt_text="visual",
# depth_gt=data["depth_gt"].cuda(), # include only if preprocess was called with depth=...
)
# Point prompt
results = model(
images=data["images"].cuda(),
intrinsics=data["intrinsics"].cuda()[None],
input_hw=[data["input_hw"]],
original_hw=[data["original_hw"]],
padding=[data["padding"]],
input_points=[[(150, 250, 1), (200, 300, 0)]], # (x, y, label): 1=positive, 0=negative
prompt_text="geometric",
# depth_gt=data["depth_gt"].cuda(), # include only if preprocess was called with depth=...
)
# Visualize results
boxes, boxes3d, scores, scores_2d, scores_3d, class_ids, depth_maps = results
draw_3d_boxes(
image=image.astype(np.uint8),
boxes3d=boxes3d[0],
intrinsics=intrinsics,
scores_2d=scores_2d[0],
scores_3d=scores_3d[0],
class_ids=class_ids[0],
class_names=["car", "person", "bicycle"],
save_path="output.png",
# Optional debug overlays (both default off):
# predicted 2D boxes (green):
# boxes_2d=boxes[0],
# draw_predicted_2d_boxes=True,
# user prompt boxes (red) / points (red pos, gray neg):
# input_boxes=[[100, 200, 300, 400]],
# input_points=[[(150, 250, 1)]],
# draw_prompt=True,
)
```
**Notes:**
- If `intrinsics` is not provided, a default intrinsic matrix is used (`focal=max(H,W)`, principal point at image center).
- Optional depth input: pass `depth_gt=depth_tensor` (shape `(B, 1, H, W)`, meters) for improved 3D localization with sparse/dense depth (e.g., LiDAR).
See **[docs/INFERENCE.md](docs/INFERENCE.md)** for the full API reference.
### Faster Inference (BF16 autocast + `torch.compile`)
`optimize_for_inference()` wraps the predictor with `torch.autocast` and (optionally) `torch.compile`. On an H100 80GB this delivers a **3.0x speedup** over FP32 eager with the same detections (cosine similarity to FP32 = 1.000 to 4 decimals).
```python
from wilddet3d import build_model, optimize_for_inference, preprocess
model = build_model(
checkpoint="ckpt/wilddet3d_alldata_all_prompt_v1.0.pt",
skip_pretrained=True,
)
# BF16 autocast + torch.compile (default: max-autotune-no-cudagraphs, ~3.0x speedup)
model = optimize_for_inference(model)
# Equivalent to:
# model = optimize_for_inference(model, dtype="bf16", compile_mode="max-autotune-no-cudagraphs")
# First call triggers compile (~17 min for max-autotune, ~2 min for "default").
# Subsequent calls use the inductor cache.
results = model(images=..., intrinsics=..., input_texts=["chair", "table"], ...)
```
**Latency** (1008x1008 input, text prompt, H100 80GB):
| Config | Median latency | Speedup | vs FP32 (cos sim / rel L2) |
|---|---|---|---|
| FP32 eager (baseline) | 219 ms | 1.00x | — |
| BF16 autocast | 132 ms | **1.66x** | 1.0000 / 5e-4 |
| BF16 autocast + `torch.compile("default")` | 83 ms | **2.64x** | 1.0000 / 7e-4 |
| BF16 autocast + `torch.compile("max-autotune-no-cudagraphs")` **(default)** | 73 ms | **3.01x** | 1.0000 / 7e-4 |
**Notes:**
- `dtype="bf16"` is recommended on Ampere or newer (A100 / H100 / RTX 30xx+). PyTorch autocast keeps numerically sensitive ops (LayerNorm / softmax / log / exp) in FP32 automatically, so detection outputs are bit-equivalent to FP32 in practice.
- `compile_mode="max-autotune-no-cudagraphs"` (the default) is the fastest end-to-end. First-time compile takes ~17 min; the inductor cache speeds up subsequent runs.
- `compile_mode="default"` gives 2.6x with a much shorter (~2 min) compile — use this if you iterate often.
- `compile_mode="reduce-overhead"` / `"max-autotune"` (CUDA-graph modes) are **not** supported — the detection head has dynamic shapes from NMS / canonical-rotation masking.
- Reproduce the numbers above with `python scripts/benchmark_inference.py`.
## Evaluation
### WildDet3D-Bench
Download the evaluation data from [allenai/WildDet3D-Data](https://huggingface.co/datasets/allenai/WildDet3D-Data) (including `InTheWild_v3_val.json` which the eval configs expect at `data/in_the_wild/annotations/`). Evaluate using the [vis4d](https://github.com/SysCV/vis4d) framework:
Third-party image data for WildDet3D, only for personal/academic use, do not redistribute! [download here](https://huggingface.co/collections/weikaih/wilddet3d-images).
```bash
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH
# Text prompt
vis4d test --config configs/eval/in_the_wild/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Text prompt + GT depth
vis4d test --config configs/eval/in_the_wild/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Box prompt (oracle)
vis4d test --config configs/eval/in_the_wild/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Box prompt + GT depth
vis4d test --config configs/eval/in_the_wild/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
```
| Mode | Config |
|---|---|
| Text | `configs/eval/in_the_wild/text.py` |
| Text + Depth | `configs/eval/in_the_wild/text_with_depth.py` |
| Box Prompt | `configs/eval/in_the_wild/box_prompt.py` |
| Box Prompt + Depth | `configs/eval/in_the_wild/box_prompt_with_depth.py` |
### WildDet3D-Stereo4D-Bench
Download the evaluation data from [allenai/WildDet3D-Stereo4D-Bench-Images](https://huggingface.co/datasets/allenai/WildDet3D-Stereo4D-Bench-Images) (including `Stereo4D_val.json` / `Stereo4D_test.json` -> `data/in_the_wild/annotations/`). Evaluate (383 images with real stereo depth):
```bash
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH
# Text prompt
vis4d test --config configs/eval/stereo4d/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Text prompt + GT depth
vis4d test --config configs/eval/stereo4d/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Box prompt (oracle)
vis4d test --config configs/eval/stereo4d/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Box prompt + GT depth
vis4d test --config configs/eval/stereo4d/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
```
| Mode | Config |
|---|---|
| Text | `configs/eval/stereo4d/text.py` |
| Text + Depth | `configs/eval/stereo4d/text_with_depth.py` |
| Box Prompt | `configs/eval/stereo4d/box_prompt.py` |
| Box Prompt + Depth | `configs/eval/stereo4d/box_prompt_with_depth.py` |
### Omni3D (in-domain) + zero-shot Argoverse 2 / ScanNet
Omni3D is the primary training distribution; Argoverse 2 and ScanNet
are held out and used for zero-shot evaluation. The evaluation protocol
(datasets, splits, ODS metric, Base/Novel splits) follows the prior
work **3D-MOOD** ([cvg/3D-MOOD](https://github.com/cvg/3D-MOOD)) so
numbers are directly comparable to their reported results. Each
benchmark has four mode configs (`text`, `text_with_depth`,
`box_prompt`, `box_prompt_with_depth`):
```bash
export PYTHONPATH=$(pwd):$PYTHONPATH
# Omni3D — reports AP per Omni3D sub-dataset (KITTI / nuScenes / SUNRGBD /
# Hypersim / ARKitScenes / Objectron) plus the macro AP_3D.
vis4d test --config configs/eval/omni3d/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/omni3d/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/omni3d/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/omni3d/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# ScanNet (zero-shot) — reports AP / mATE / mASE / mAOE / ODS with a
# Base / Novel split on 18 indoor categories (15 frequent indoors are
# treated as Base).
vis4d test --config configs/eval/scannet/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/scannet/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/scannet/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/scannet/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
# Argoverse 2 (zero-shot) — reports the same metric family, with
# Base = the 11 common AV2 driving categories.
vis4d test --config configs/eval/argoverse/text.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/argoverse/text_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/argoverse/box_prompt.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
vis4d test --config configs/eval/argoverse/box_prompt_with_depth.py --gpus 1 --ckpt ckpt/wilddet3d_alldata_all_prompt_v1.0.pt
```
See **[docs/EVALUATION.md](docs/EVALUATION.md)** for the metric
definitions, data setup, and the per-benchmark config table.
## Training
WildDet3D is trained in 3 stages. Each stage uses `vis4d fit`:
```bash
# Set PYTHONPATH so `configs/` is importable
export PYTHONPATH=$(pwd):$PYTHONPATH
# Stage 1 (12 ep): Omni3D canonical pretraining
vis4d fit --config configs/training/stage1_omni3d.py --gpus 8
# Stage 2 (12 ep): all-data dense fine-tuning (Omni3D + CA1M + Waymo + 3EED + FoundationPose + ITW-human + V3Det-human), 5-mode collator (no mask)
vis4d fit --config configs/training/stage2_alldata.py --gpus 8
# Stage 3 (3 ep): high-quality human-reviewed fine-tuning on a mix of box / point / text prompts
vis4d fit --config configs/training/stage3_mix_box_point_text_ft.py --gpus 8
```
Multi-node: add `--num_nodes N`. Batch size defaults to 4 samples/GPU (global batch 128 at 8 GPUs × 4 nodes).
### Training Data Preparation
See **[docs/TRAINING_DATA.md](docs/TRAINING_DATA.md)** for per-dataset download + convert + HDF5-pack instructions (Omni3D, CA1M, Waymo v2, 3EED, FoundationPose, ITW, Stereo4D, mask annotations, pretrained checkpoints). All frame-extraction scripts under `scripts/data_prep/` are deterministic, so following the doc reproduces our exact train/val splits.
Third-party image data for WildDet3D, only for personal/academic use, do not redistribute! [download here](https://huggingface.co/collections/weikaih/wilddet3d-images).
## Results
### WildDet3D-Bench (In-the-Wild)
AP is computed using center-distance matching. AP_r, AP_c, AP_f denote rare (<5), common (5-20), and frequent (>20) category splits.
| Method | Data | AP_r | AP_c | AP_f | AP |
|---|---|---|---|---|---|
| **Text Prompt** | | | | | |
| 3D-MOOD | Omni3D | 2.4 | 2.1 | 2.6 | 2.3 |
| WildDet3D | Omni3D | 9.0 | 6.5 | 5.2 | 6.8 |
| WildDet3D w/ depth | Omni3D | 23.0 | 21.5 | 16.1 | 20.7 |
| WildDet3D | Omni3D, Others, WildDet3D-Data | 28.3 | 21.6 | 18.7 | 22.6 |
| WildDet3D w/ depth | Omni3D, Others, WildDet3D-Data | **47.4** | **40.7** | **37.2** | **41.6** |
| **Box Prompt** | | | | | |
| OVMono3D-LIFT | Omni3D | 7.4 | 8.8 | 5.1 | 7.7 |
| DetAny3D | Omni3D, Others | 9.9 | 7.4 | 6.3 | 7.8 |
| WildDet3D | Omni3D | 12.0 | 7.9 | 5.3 | 8.4 |
| WildDet3D w/ depth | Omni3D | 26.4 | 24.4 | 19.6 | 23.9 |
| WildDet3D | Omni3D, Others, WildDet3D-Data | 30.0 | 24.2 | 20.3 | 24.8 |
| WildDet3D w/ depth | Omni3D, Others, WildDet3D-Data | **53.7** | **46.1** | **42.5** | **47.2** |
### Omni3D
AP is computed at 3D IoU [0.5:0.95].
| Method | KITTI | nuScenes | SUNRGBD | Hypersim | ARKitScenes | Objectron | AP |
|---|---|---|---|---|---|---|---|
| **Text Prompt** | | | | | | | |
| Cube R-CNN | 32.6 | 30.1 | 15.3 | 7.5 | 41.7 | 50.8 | 23.3 |
| 3D-MOOD Swin-T | 32.8 | 31.5 | 21.9 | 10.5 | 51.0 | 64.3 | 28.4 |
| 3D-MOOD Swin-B | 31.4 | 35.8 | 23.8 | 9.1 | 53.9 | 67.9 | 30.0 |
| WildDet3D | **37.0** | 31.7 | 38.9 | 16.5 | 64.6 | 60.5 | 34.2 |
| WildDet3D w/ depth | 36.1 | 32.0 | **51.1** | **26.6** | **73.3** | **68.3** | **41.6** |
| **Box Prompt** | | | | | | | |
| OVMono3D-LIFT | 31.4 | 32.5 | 23.2 | 11.9 | 54.2 | 63.5 | 29.6 |
| DetAny3D | 38.7 | **37.6** | 46.1 | 16.0 | 50.6 | 56.8 | 34.4 |
| WildDet3D | **44.3** | 35.3 | 43.1 | 17.3 | 66.6 | 60.8 | 36.4 |
| WildDet3D w/ depth | 42.8 | 35.9 | **58.7** | **30.4** | **76.6** | **68.5** | **45.8** |
### Zero-shot Transfer (Argoverse 2 + ScanNet)
Trained on Omni3D + In-the-Wild only; evaluated zero-shot on
Argoverse 2 (outdoor driving, 26 classes) and ScanNet (indoor,
18 classes). The dataset splits, ODS metric, and Base/Novel category
groupings are taken from
[3D-MOOD](https://github.com/cvg/3D-MOOD) so the numbers below are
directly comparable to their reported baselines.
ODS = (3·AP + (1 - mATE) + (1 - mASE) + (1 - mAOE)) / 6 using the
canonical-rotation AOE convention. Higher is better for AP and ODS;
lower is better for mATE, mASE, mAOE.
| Method | Argoverse2 AP | mATE | mASE | mAOE | ODS | ScanNet AP | mATE | mASE | mAOE | ODS |
|---|---|---|---|---|---|---|---|---|---|---|
| Cube R-CNN | 8.6 | 0.903 | 0.867 | 0.953 | 8.9 | 20.0 | 0.733 | 0.774 | 0.921 | 19.5 |
| 3D-MOOD Swin-T | 14.8 | 0.782 | 0.697 | 0.612 | 22.5 | 27.3 | 0.630 | 0.726 | 0.650 | 30.2 |
| 3D-MOOD Swin-B | 14.7 | 0.755 | 0.680 | 0.580 | 23.8 | 28.8 | 0.612 | **0.706** | 0.655 | 31.5 |
| WildDet3D | 43.4 | 0.714 | 0.645 | 0.526 | 40.3 | 56.5 | 0.601 | 0.720 | 0.437 | 48.9 |
| WildDet3D w/ depth | **43.4** | **0.701** | **0.645** | **0.526** | **40.4** | **57.6** | **0.589** | 0.707 | **0.422** | **50.2** |
GT depth helps on ScanNet (+1.3 ODS) where indoor scenes benefit from
metric depth; the gain on Argoverse 2 is marginal, suggesting the
monocular depth head is already well-calibrated for outdoor driving.
### Qualitative Results
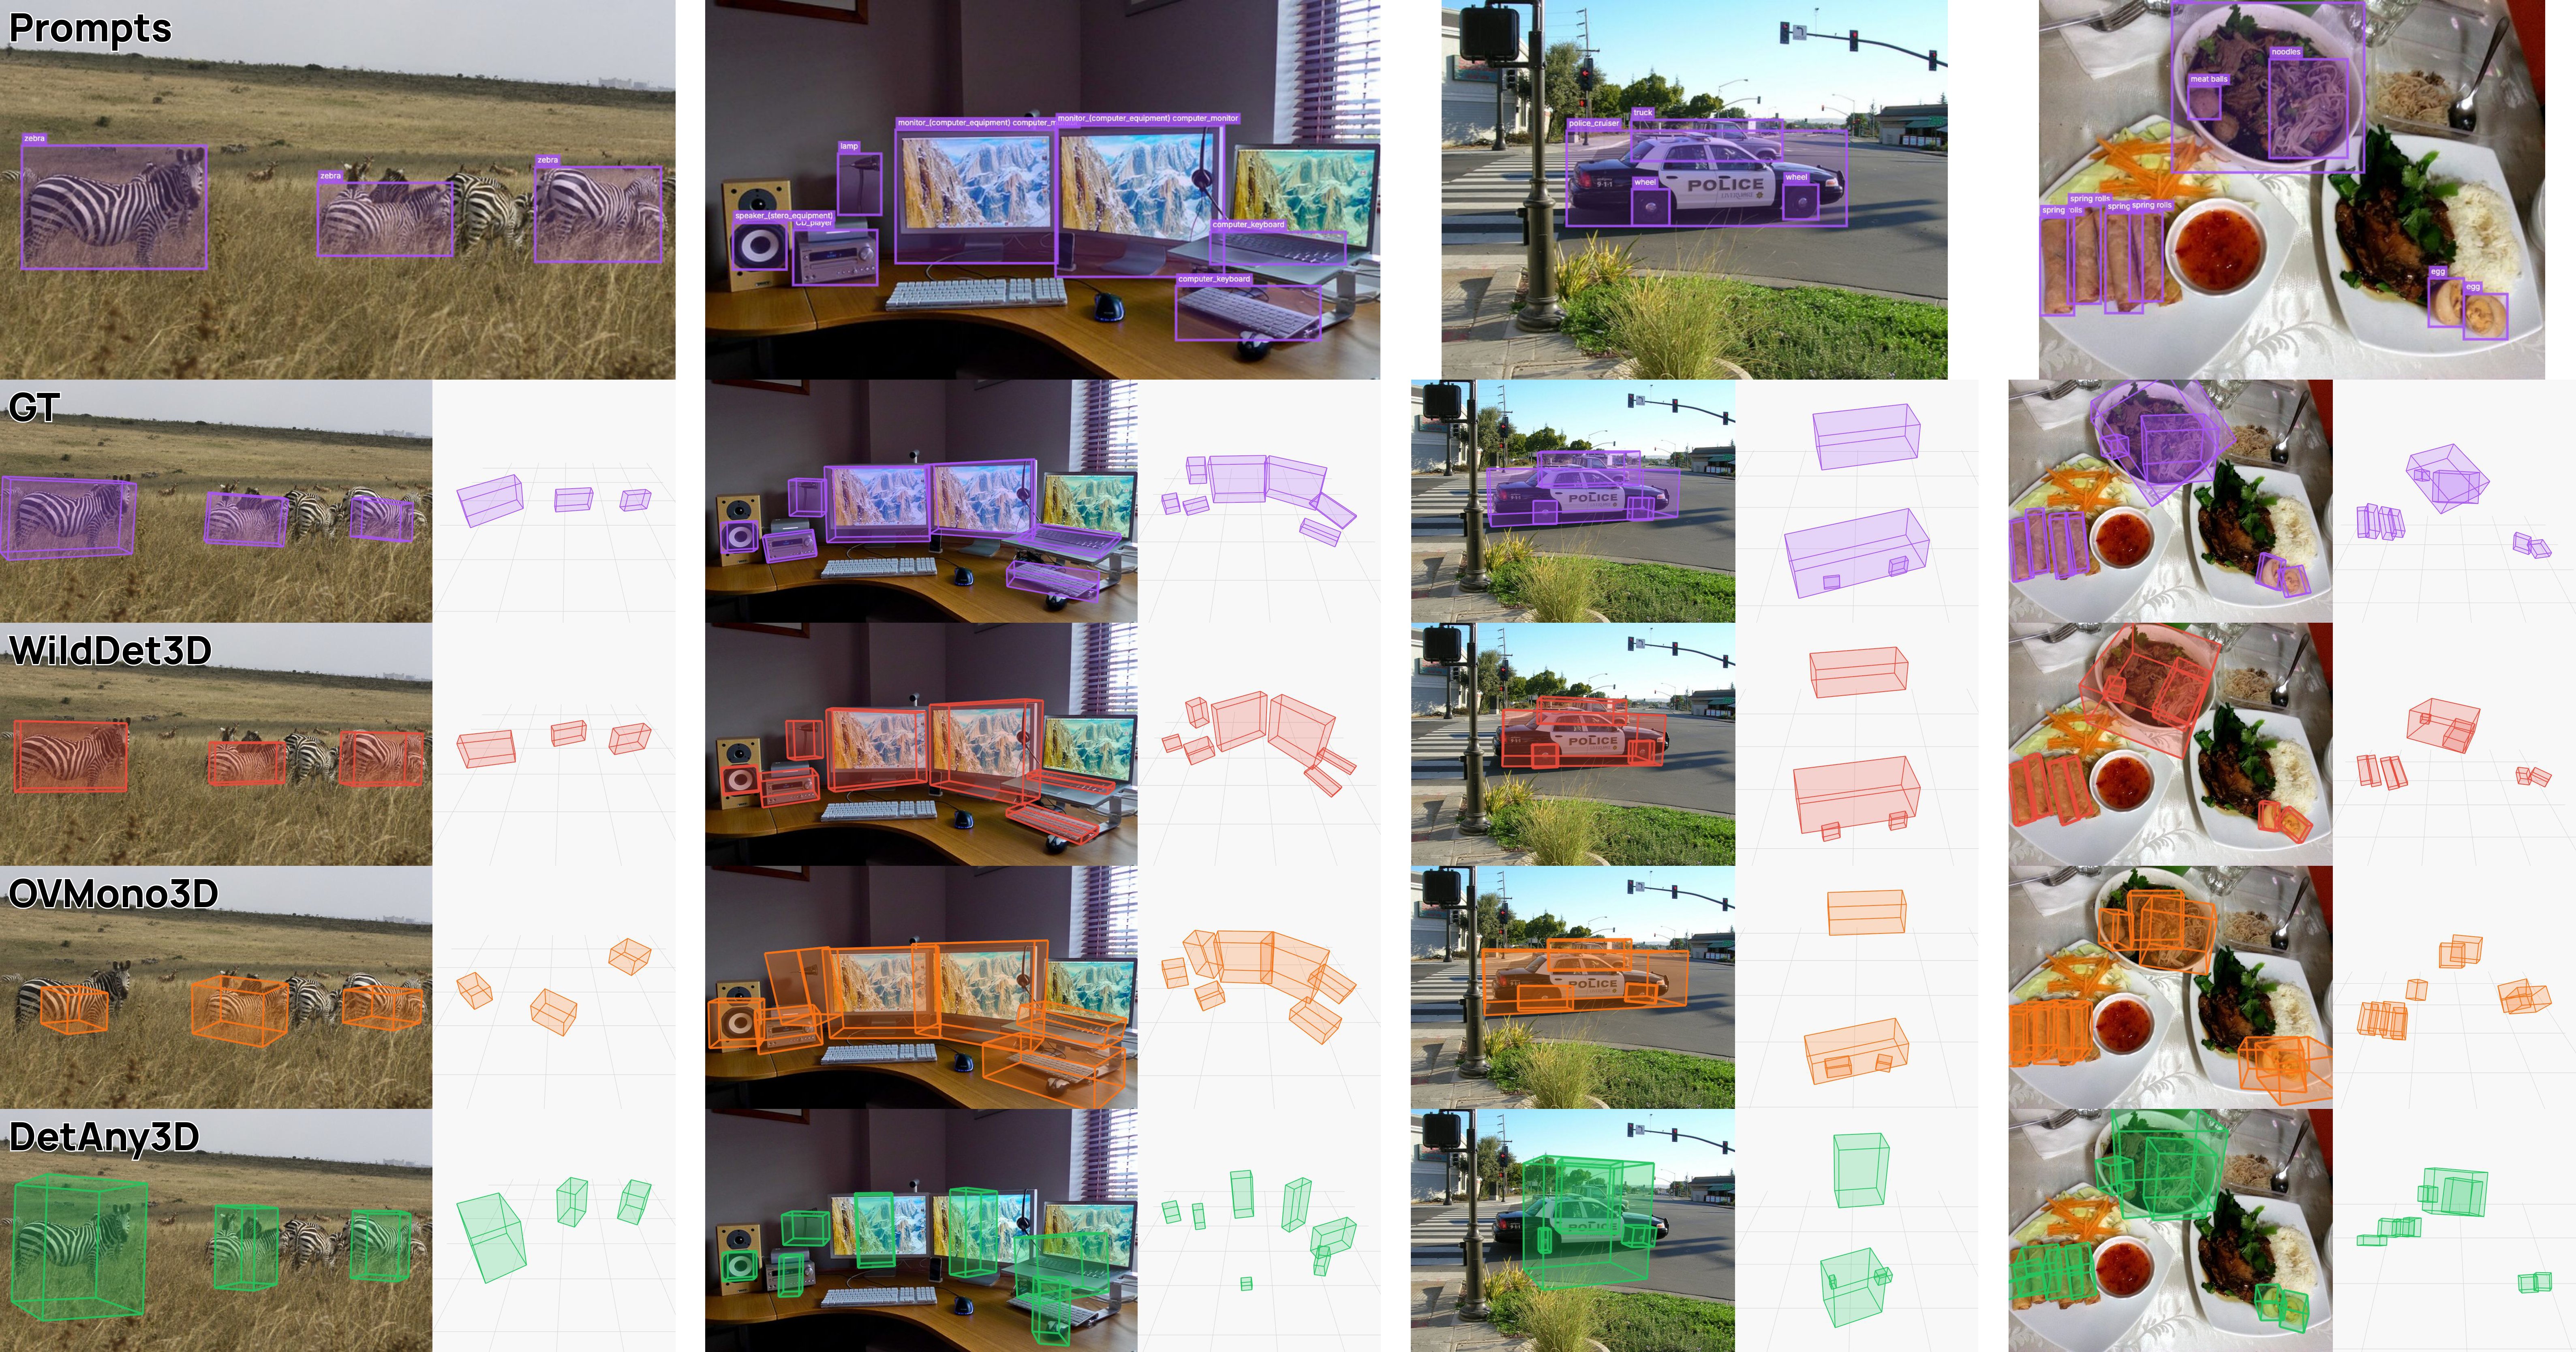
**Box prompt comparison** (WildDet3D vs OVMono3D vs DetAny3D):
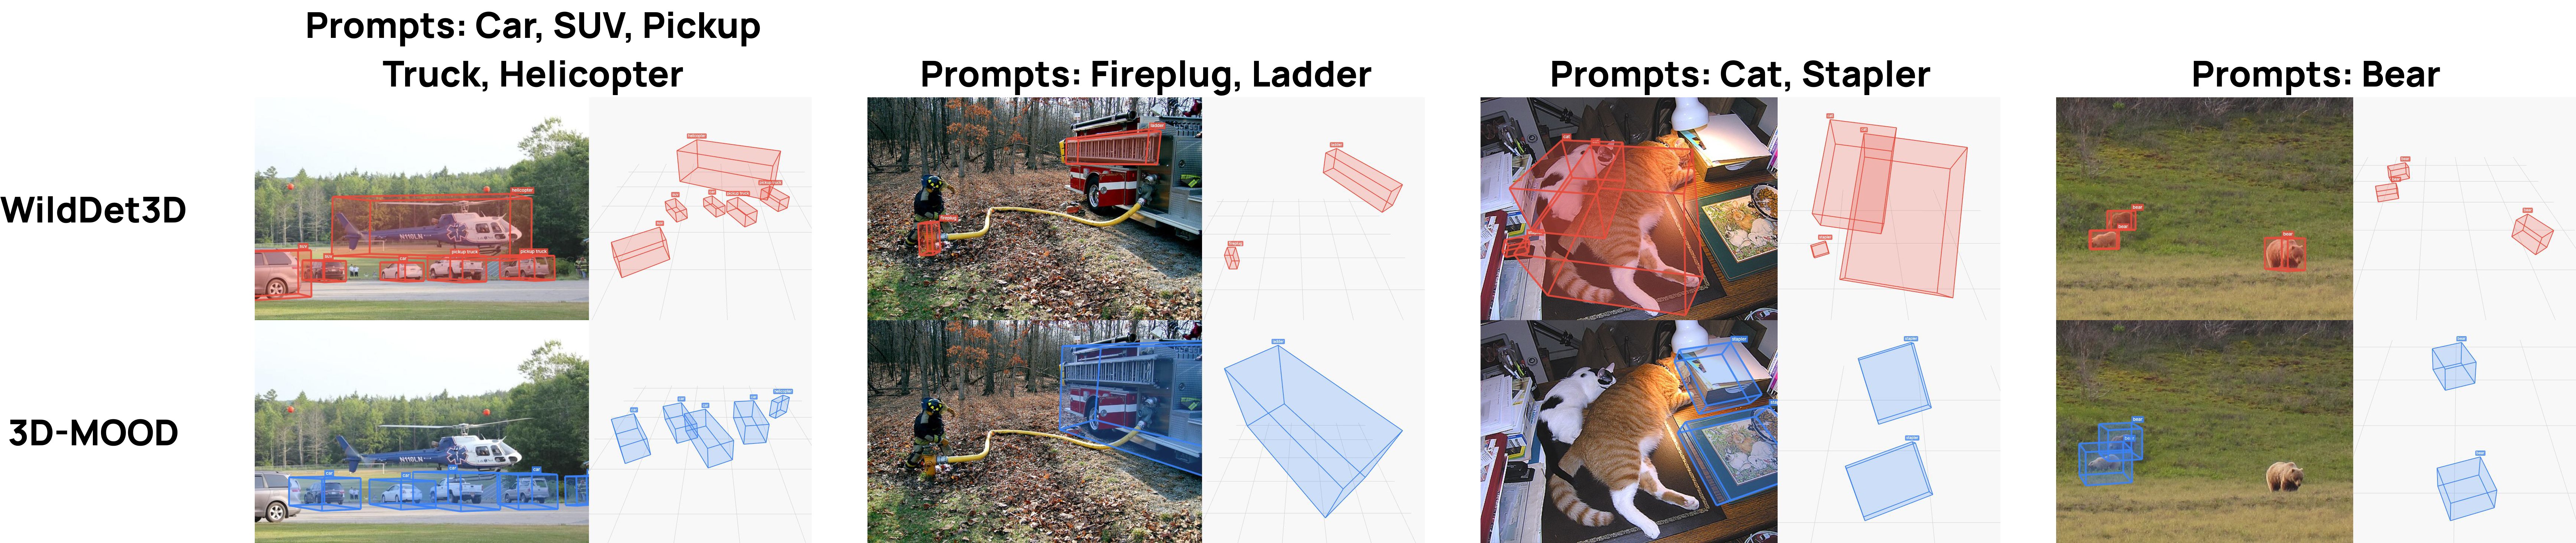
**Text prompt comparison**:
## WildDet3D Data
We introduce **WildDet3D-Data**, a large-scale in-the-wild dataset for monocular 3D detection with human-verified 3D bounding box annotations. The dataset covers images from COCO, LVIS, Objects365, and V3Det.
| Split | Description | Images | Annotations | Categories |
|---|---|---|---|---|
| Val | Validation set (human) | 2,470 | 9,256 | 785 |
| Test | Test set (human) | 2,433 | 5,596 | 633 |
| Train (Human) | Human-reviewed only | 102,979 | 229,934 | 11,879 |
| Train (Essential) | Human + VLM-qualified small objects | 102,979 | 412,711 | 12,064 |
| Train (Synthetic) | VLM auto-selected | 896,004 | 3,483,292 | 11,896 |
| **Total** | | **1,003,886** | **3,910,855** | **13,499** |
The dataset is hosted on HuggingFace: [allenai/WildDet3D-Data](https://huggingface.co/datasets/allenai/WildDet3D-Data). See the [dataset README](https://huggingface.co/datasets/allenai/WildDet3D-Data) for download instructions and data format.
## Citation
If you find this work useful, please cite:
```bibtex
@misc{huang2026wilddet3dscalingpromptable3d,
title={WildDet3D: Scaling Promptable 3D Detection in the Wild},
author={Weikai Huang and Jieyu Zhang and Sijun Li and Taoyang Jia and Jiafei Duan and Yunqian Cheng and Jaemin Cho and Matthew Wallingford and Rustin Soraki and Chris Dongjoo Kim and Shuo Liu and Donovan Clay and Taira Anderson and Winson Han and Ali Farhadi and Bharath Hariharan and Zhongzheng Ren and Ranjay Krishna},
year={2026},
eprint={2604.08626},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2604.08626},
}
```
## Acknowledgements
- [Omni3D](https://github.com/facebookresearch/omni3d) -- 3D detection benchmarks and baselines
- [vis4d](https://github.com/SysCV/vis4d) -- Training and evaluation framework
- [SAM 3](https://github.com/facebookresearch/sam3) -- Segment Anything Model 3
- [LingBot-Depth](https://github.com/Robbyant/lingbot-depth) -- Monocular depth estimation
- [3D-MOOD](https://github.com/cvg/3D-MOOD) -- Open-vocabulary monocular 3D detection
- [DetAny3D](https://github.com/OpenDriveLab/DetAny3D) -- Detect anything in 3D
- [OVMono3D](https://github.com/UVA-Computer-Vision-Lab/ovmono3d) -- Open-vocabulary monocular 3D detection
- [LabelAny3D](https://github.com/UVA-Computer-Vision-Lab/LabelAny3D) -- 3D bounding box annotation tool
## License
**Codebase:** This codebase incorporates code from [SAM 3](https://github.com/facebookresearch/sam3), and is licensed under the [SAM License](https://github.com/facebookresearch/sam3/blob/main/LICENSE). It is intended for research and educational use in accordance with [Ai2's Responsible Use Guidelines](https://allenai.org/responsible-use).
**Model:** This model is based on [SAM 3](https://github.com/facebookresearch/sam3) and [LingBot-Depth](https://github.com/Robbyant/lingbot-depth), and is licensed under the [SAM License](https://github.com/facebookresearch/sam3/blob/main/LICENSE). This model is intended for research and educational use in accordance with [Ai2's Responsible Use Guidelines](https://allenai.org/responsible-use).