 # **Q**uestion and **A**nswer based on **Anything**


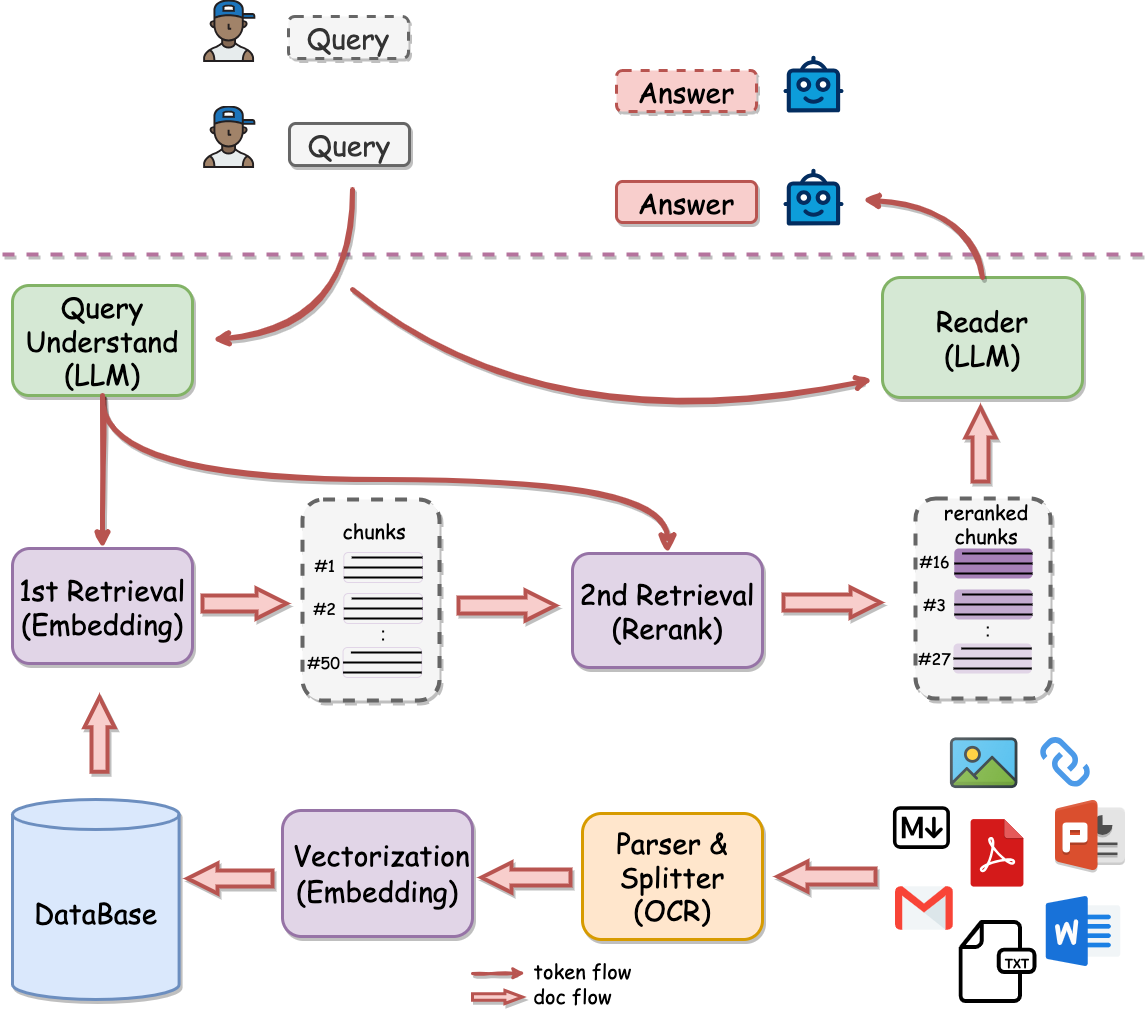
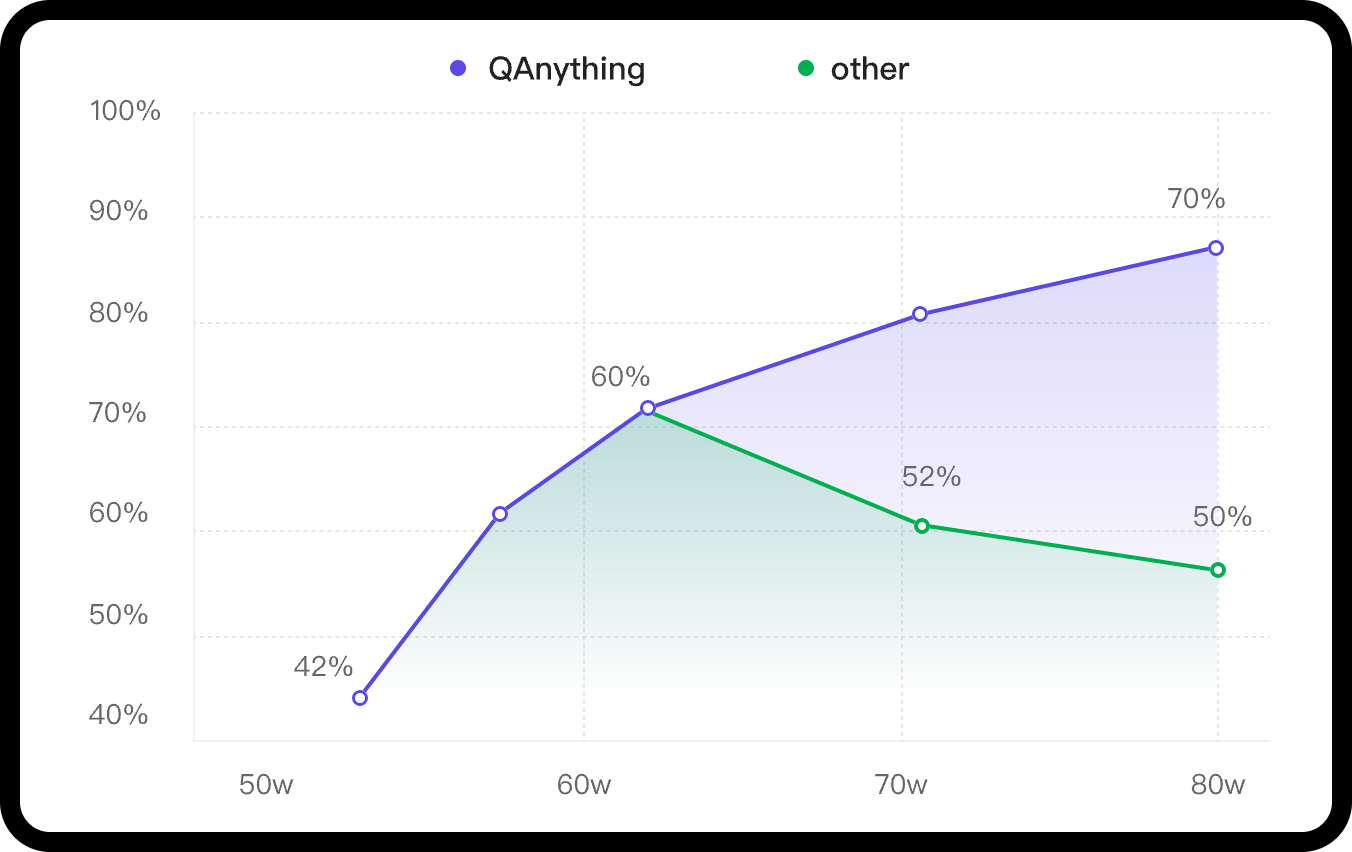
 ***NOTE:***
- In `WithoutReranker` setting, our `bce-embedding-base_v1` outperforms all the other embedding models.
- With fixing the embedding model, our `bce-reranker-base_v1` achieves the best performance.
- **The combination of `bce-embedding-base_v1` and `bce-reranker-base_v1` is SOTA**.
- If you want to use embedding and rerank separately, please refer to [BCEmbedding](https://github.com/netease-youdao/BCEmbedding)
### LLM
The open source version of QAnything is based on QwenLM and has been fine-tuned on a large number of professional question-answering datasets. It greatly enhances the ability of question-answering.
If you need to use it for commercial purposes, please follow the license of QwenLM. For more details, please refer to: [QwenLM](https://github.com/QwenLM/Qwen)
# 🚀 Latest Updates
- ***2024-08-23***: **Support quick start, front-end configuration parameters, online preview and editing of chunk blocks, greatly optimize project architecture and startup mode, greatly optimize parsing and retrieval effects.** - See More👉 [v2.0.0](https://github.com/netease-youdao/QAnything/releases/tag/v2.0.0)
- ***2024-05-20***: **Support other large model services compatible with OpenAI API, and provide an optimized powerful PDF parser.** - See More👉 [v1.4.1](https://github.com/netease-youdao/QAnything/releases/tag/v1.4.1)
- ***2024-04-26***: **Support web search, FAQ, custom bot, file traceability preview etc.** - See More👉 [v1.4.0](https://github.com/netease-youdao/QAnything/releases/tag/v1.4.0-python)
- ***2024-04-03***: **Support installation in a pure Python environment.Support hybrid search.** - See More👉 [v1.3.0](https://github.com/netease-youdao/QAnything/releases/tag/v1.3.0)
- ***2024-01-29***: **Support for custom large models, including OpenAI API and other open-source large models, with a minimum GPU requirement of GTX 1050Ti, greatly improving deployment, debugging, and user experience.** - See More👉 [v1.2.0](https://github.com/netease-youdao/QAnything/releases/tag/v1.2.0)
- ***2024-01-23***: **Enable rerank by default and fix various issues when starting on Windows.** - See More👉 [v1.1.1](https://github.com/netease-youdao/QAnything/releases/tag/v1.1.1)
- ***2024-01-18***: **Support one-click startup, support Windows deployment, improve PDF, XLSX, HTML parsing efficiency.** - See More👉 [v1.1.0](https://github.com/netease-youdao/QAnything/releases/tag/v1.1.0)
# Before You Start
**Star us on GitHub, and be instantly notified for new release!**
* [🏄 Try QAnything Online](https://qanything.ai)
* [📚 Try read.youdao.com | 有道速读](https://read.youdao.com)
* [🛠️ Only use our BCEmbedding(embedding & rerank)](https://github.com/netease-youdao/BCEmbedding)
* [📖 FAQ](FAQ_zh.md)
* [👂️Let me hear your voice](https://qanything.canny.io/feature-requests)
# Getting Started
## Latest Features Table
| features | python (v1.4.2) | docker (v1.2.2) | QAnything v2.0.0 | Explanation |
|----------------------------------------------------------------------|-----------------|-----------------|------------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| Detailed installation document | ✅ | ✅ | ✅ | |
| Support API | ✅ | ✅ | ✅ | |
| Support production environment | ❌ | ✅ | ✅ | |
| Support offline use | ❌ | ✅ | ✅ | |
| Support multiple concurrency | ❌ | ✅ | ✅ | |
| Support multi-card inference | ❌ | ✅ | ❌ | Version 2.0.0 no longer provides default local LLM. All access is through the openai interface, and users can deploy local LLM through tools such as ollama. |
| Support Mac (M series chips) | ✅ | ❌ | ✅ | |
| Support Linux | ✅ | ✅ | ✅ | The old version of Python defaults to using onnxruntime-gpu for cuda12 on Linux, and automatically switches to onnxruntime when glibc<2.28. |
| Support windows | ❌ | ❌ | ✅ | Both old versions of Python and Docker require WSL environment. Version 2.0.0 can be started directly in a non-WSL environment. |
| Support CPU only | ✅ | ❌ | ✅ | Version 2.0.0 Mac, Linux, Win unified no longer use GPU, completely migrated to CPU. |
| Support hybrid search (BM25+embedding) | ❌ | ✅ | ✅ | |
| Support web search (need VPN) | ✅ | ❌ | ✅ | |
| Support FAQ | ✅ | ❌ | ✅ | |
| Support BOT | ✅ | ❌ | ✅ | |
| Support Traceability | ✅ | ❌ | ✅ | |
| Support Log retrieval | ✅ | ❌ | ✅ | |
| Support audio file | ✅ | ❌ | ❌ | Relying on whisper, slow speed and high resource consumption, temporarily removed. |
| Support OpenCloudOS | ✅ | ❌ | ✅ | |
| Support interfaces compatible with Openaiapi (including ollama) | ✅ | ✅ | ✅ | Old versions of Python and Docker require manual modification of parameters such as api_key, base_url, model, etc. In version 2.0.0, these are all changed to be automatically saved in the front end settings. |
| PDF parsing performance improvement (including tables) | ✅ | ❌ | ✅ | Version 1.4.2 requires manual settings, version 2.0.0 does not require manual settings, and both the PDF parsing effect and performance have been improved. |
| User-defined configuration (Experimental: Improve speed) | ✅ | ❌ | ✅ | v1.4.2 needs to be set manually, v2.0.0 uses the best configuration by default. |
| Improvement in parsing performance of other file types | ❌ | ❌ | ✅ | Version 2.0.0 improves the parsing effect of URLs, Markdown, XLSX, DOCX, etc. |
| Support independent service invocation | ❌ | ❌ | ✅ | Version 2.0.0 independent dependent services, including embed, rerank, ocr, pdf parsing services, can be called independently (http) |
| Support quick start mode | ❌ | ❌ | ✅ | Quick Start: No need to create a knowledge base, support for file upload and instant questioning, support for fileless Q&A. |
| Support only retrieval mode | ❌ | ❌ | ✅ | Only return search results, do not call the large model for question answering. |
| Support parsing result chunks content visualization, manual editing. | ❌ | ❌ | ✅ | Version 2.0.0 supports manually editing the contents of chunks, which take effect in real time. |
| PDF parsing supports images, supports answering with images. | ❌ | ❌ | ✅ | |
## Version 2.0.0 adds detailed optimizations:
* Support front-end configuration API_BASE, API_KEY, text chunk size, output token quantity, context message quantity, etc.
* Optimize the instruction compliance of Bot role settings, each Bot can configure model parameters separately.
* Support creating multiple dialogue windows and saving multiple sets of historical Q&A records at the same time.
* Support saving question and answer records as images
* Optimize the logic of uploading files, parse files and question-and-answer requests independently, uploading files will no longer affect question-and-answer.
* Optimize image size, the compressed size of the old version image is 18.94GB -> the compressed size of the new version image is 4.88GB, reduced to 1/4 of the original size, providing a complete Dockerfile.
* Search optimization, chunks add fragment fusion and sorting, aggregate single document or double document.
* Both the retrieval stage and the question-answering stage embed metadata information to improve the retrieval and question-answering effectiveness.
### Display of data at each stage:
* Display the upload progress of all files in the knowledge base.
* Display the progress of uploading a single file in the knowledge base, and the time consumed in each stage of the upload.
* Question and answer information statistics, including time consumption at each stage of question and answer, token consumption, model information, etc.
* User information statistics, including total number of uploaded files, total time consumed, question and answer history records, etc.
### Problem fixed
* The xlsx file format supports parsing multiple sheets.
* Optimize the problem of missing recognition of PDF tables.
* Fix some parsing errors in DOCX files.
* Optimize FAQ matching logic.
* Support for non-UTF-8 encoded txt files.
## Comparison of New and Old Parsing Effects
* First, with regard to the parsing of large tables in documents, especially tables that span multiple pages, version 2.0 has made significant improvements. The new version's parsing logic can analyze the structure of the table, including the layout of rows and columns, and can automatically identify the table headers, placing them at the top of each table segment that is split. This improvement prevents interruptions in meaning caused by logical segmentation when parsing long tables.
| Original image | Old version parsing effect | New version parsing effect |
|:----:|:--------------------------------------------:|:---------------------------------------------------------------------------------------------:|
|  |  |  |
* In addition, version 2.0 has also been optimized for handling text columnation and cross-page layout. It can recognize double-column or multi-column layouts of text and correctly divide text blocks in accordance with human reading habits. At the same time, this version can also save images in documents to ensure the integrity of content is not lost during file parsing. As shown in the figure below, the correct arrangement should be to group the text arranged in sequence as 1, 2, 3 into a large paragraph and then segment it, rather than segmenting 1, 2, 3 separately.
* In version 1.4 parsing results, the cross-page text "higher" was chunked into the next text block, which is detrimental to large model semantic understanding. In version 2.0 parsing results, it is correctly divided, and images interspersed in text paragraphs are also parsed into corresponding chunk statements. Non-main text such as "Figure 1 Identification and Authorization and Their Support Relationship 37" and "Cover Story Cover Feature" were successfully filtered out.
| Original image | Old version parsing effect | New version parsing effect |
|:----:|:--------------------------------------------:|:---------------------------------------------------------------------------------------------:|
|  | 
Welcome to the QAnything [Discord](https://discord.gg/5uNpPsEJz8) community
## WeChat
Welcome to follow QAnything WeChat Official Account to get the latest information.
 Welcome to scan the code to join the QAnything discussion group.
 ## Email
If you need to contact our team privately, please reach out to us via the following email:
AIcloud_Business@corp.youdao.com
## GitHub issues & discussions
Reach out to the maintainer at one of the following places:
- [Github issues](https://github.com/netease-youdao/QAnything/issues)
- [Github discussions](https://github.com/netease-youdao/QAnything/discussions)
- Contact options listed on [this GitHub profile](https://github.com/netease-youdao)