Spotter: Let the Embodied Model Lead, and the VLM Reflect for It
If our project helps you, please give us a star ⭐ on GitHub to support us.


| 📄 Paper | 🏠 Project page | 🤖 Model checkpoints | 🌐 Simulator | 🚀 Get started |
|---|---|---|---|---|
| [arXiv](https://arxiv.org/abs/2609.36808) | [zqc3117.github.io/Spotter](https://zqc3117.github.io/Spotter/) | [pi0.5](https://huggingface.co/DAVIAN-Robotics/pi05-robocasa-H50) · [Cosmos Policy](https://huggingface.co/nvidia/Cosmos-Policy-RoboCasa-Predict2-2B) (RoboCasa) · [pi0.5](https://huggingface.co/motus-robotics/pi0.5_robotwin2) (RoboTwin 2.0) | [RoboCasa](https://robocasa.ai) · [RoboTwin 2.0](https://github.com/RoboTwin-Platform/RoboTwin) | [Installation](#-environment-setup) · [Quick start](#-evaluation-with-released-checkpoints) |
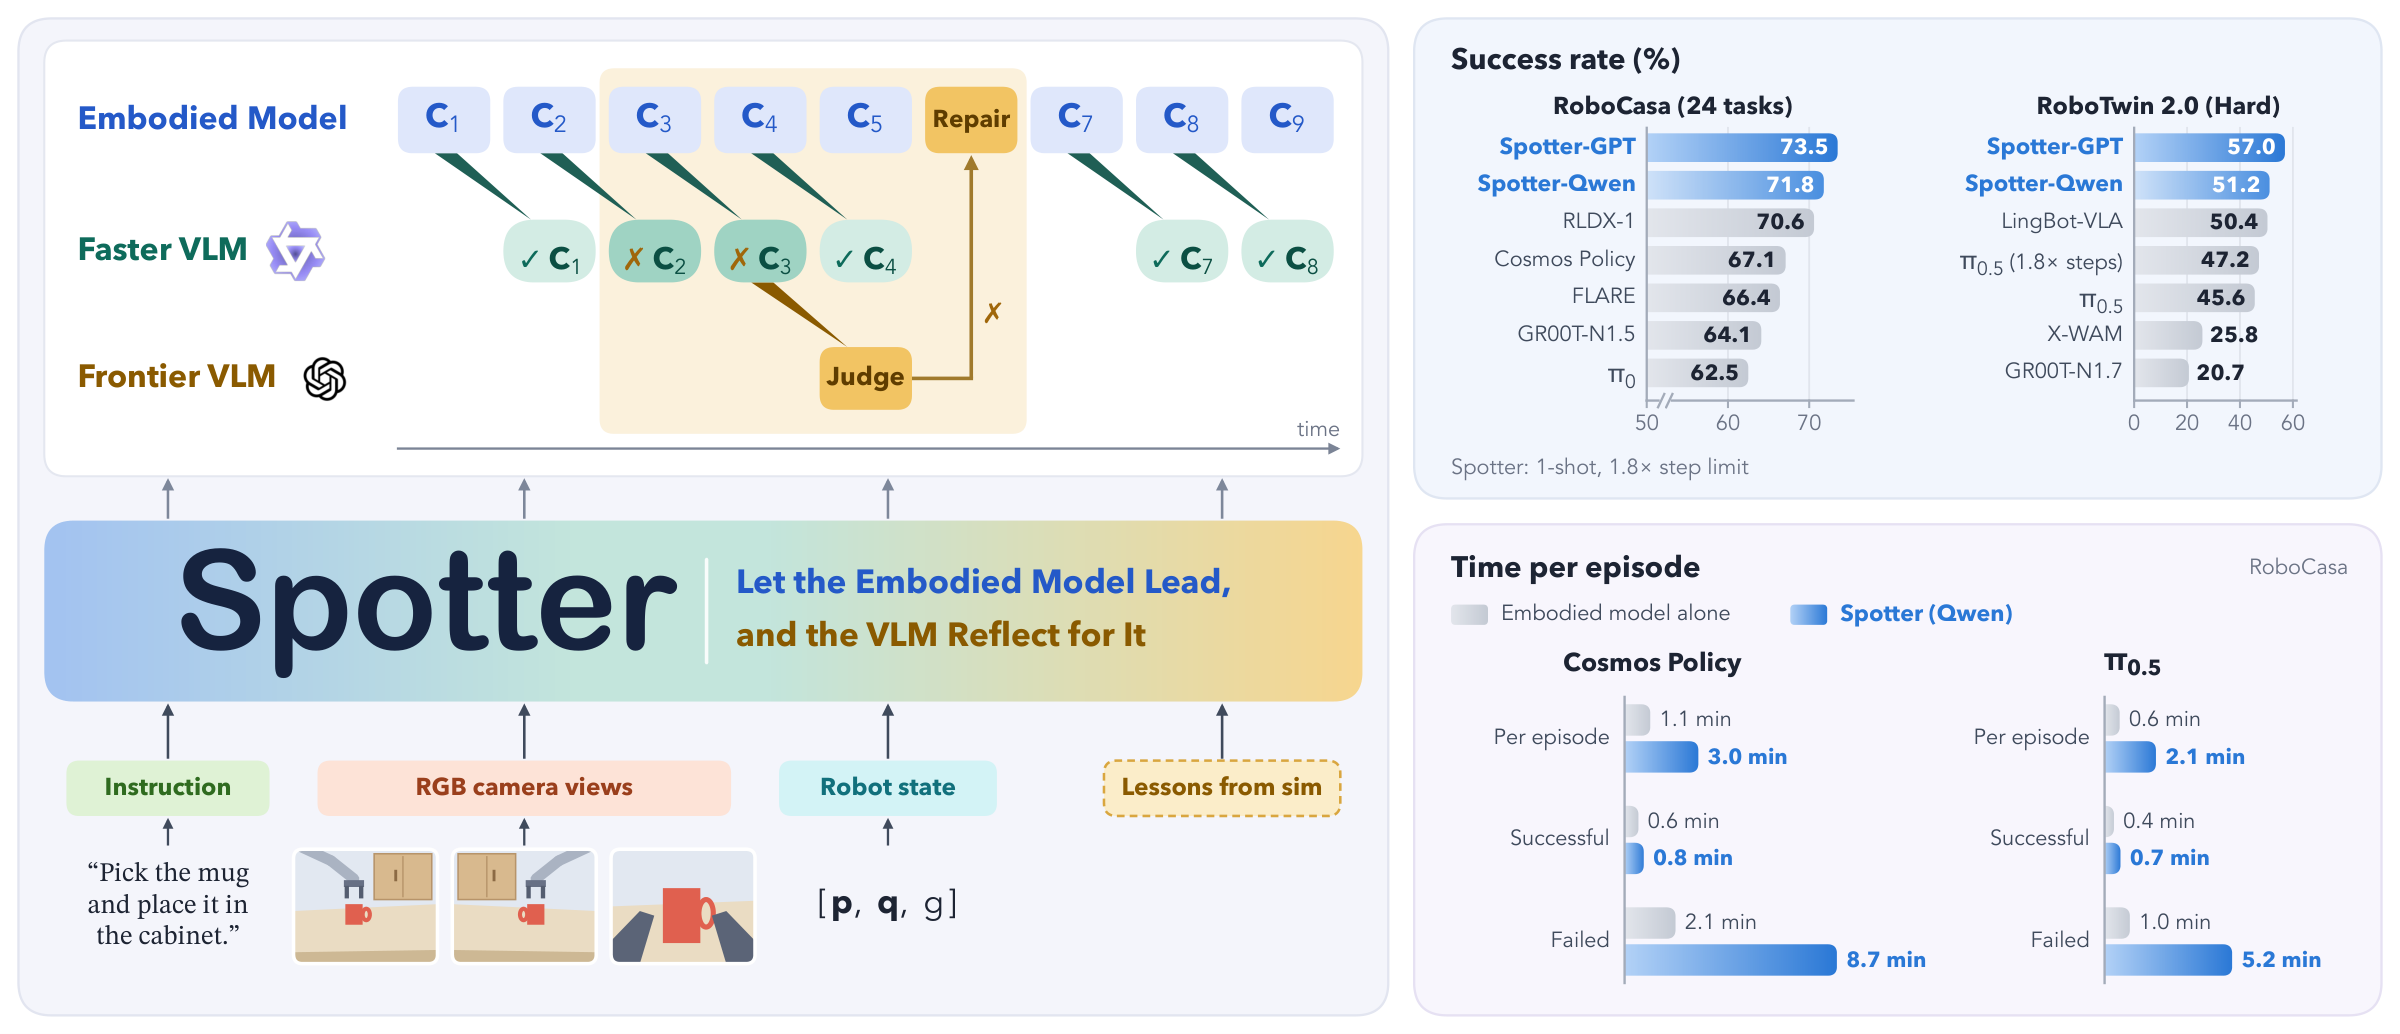
**Spotter** adds a lightweight intervention layer between a frozen embodied model (System 1) and a VLM (System 2).
Instead of having the VLM plan every step, the embodied model leads and keeps executing, while a local screener
watches in parallel and the VLM steps in only to confirm and repair an error. The VLM's job becomes much simpler,
so the whole framework works with a **locally served, open-source Qwen and no privileged information**.
## 📰 What's New
- [2026/10] 🔥 RoboCasa: we release the code version that was evaluated on the 1,200-episode test set, with a render guard for black / noisy frames and a wrist-depth `aim` step for grasping. See [RoboCasa](#robocasa).
- [2026/10] 🔥 Spotter supports **RoboTwin 2.0** with π0.5: one-command evaluation (`bash robotwin_eval.sh`), a 1-shot example bank ([fewshot_bank_robotwin.tar.gz](https://github.com/zqc3117/Spotter/releases/download/v1.0/fewshot_bank_robotwin.tar.gz)), and full logs on ModelScope with every episode's frames, judge prompts and replies ([150 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-150): policy alone, Spotter and a VLM-led agent, each with Qwen and GPT; [50 tasks × 10 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-50x10)). The real-robot demo (Franka Research 3) and the [project page](https://zqc3117.github.io/Spotter/) are online. See [RoboTwin 2.0](#robotwin-20).
- [2026/09] 🎉 The paper is on [arXiv](https://arxiv.org/abs/2609.36808), and the code is released with the RoboCasa example bank ([fewshot_bank.tar.gz](https://github.com/zqc3117/Spotter/releases/download/v1.0/fewshot_bank.tar.gz)).
## 🎬 Demos
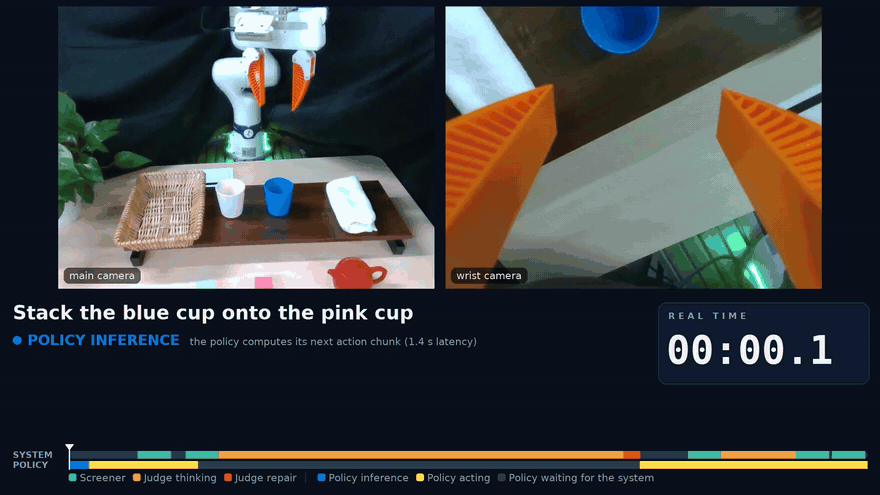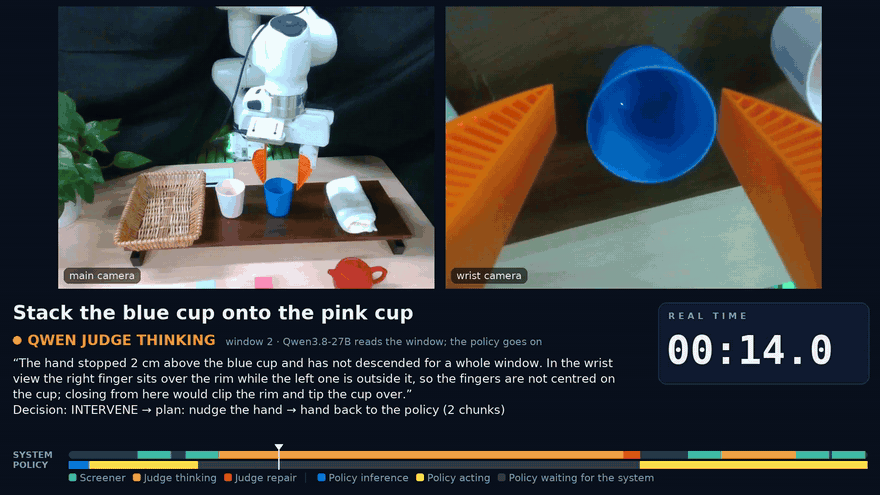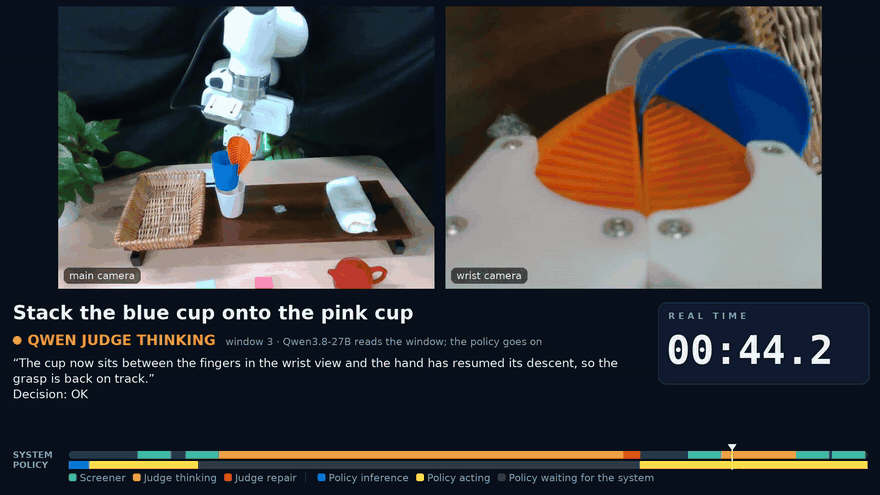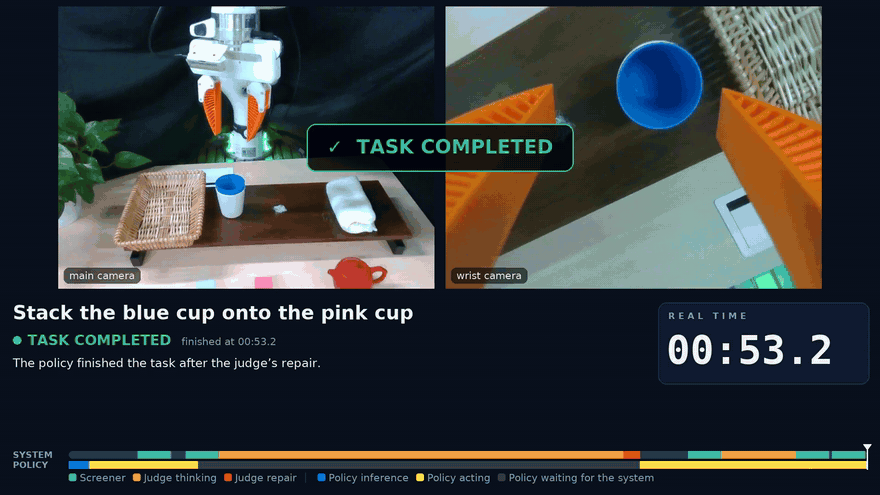
Real robot (Franka Research 3), stacking the blue cup onto the pink cup. Shown at 2×, with the judge's thinking time shortened; the on-screen clock is real time.
Watch the full video on the project page.
## 🔥 Highlights
- **A lightweight intervention layer.** Like a person who keeps a little attention on a task and focuses only when
something looks wrong, Spotter lets execution flow continuously and brings in the VLM only on a confirmed error.
- **A simpler job for the VLM.** The VLM no longer drives the robot. It only has to notice a failure, repair it with
a short primitive plan, and check the fix. A local Qwen with no access to the task's success signal is enough.
- **Continuous execution, low overhead.** The embodied model never waits for the VLM on the routine path:
a successful episode takes only **13–16 s** longer than the policy alone.
## 💡 Why Spotter
Existing VLM-led robot agents are serial: the VLM plans a segment, the embodied model executes it, and the VLM
decides what comes next. This forces a dilemma:
- **Short segments** mean frequent VLM calls and high latency, even on easy tasks.
- **Long segments** mean a deviation during execution cannot be caught in time, and later actions keep going wrong.
Spotter removes this trade-off by supervising in parallel rather than in series.
| | VLM-led agents | Spotter |
|---|---|---|
| Who drives execution | VLM plans every step | Embodied model leads |
| When the VLM is called | Before every step | Only on a confirmed error |
| Embodied model waits for the VLM | Every step | Only during a repair |
| Needs privileged information | Usually (e.g. the success signal) | No |
| Works with a local Qwen | Only with privileged information | Yes |
### 🎯 Works with a weaker model, without privileged information
With the same local Qwen and no privileged information on RoboCasa (1,200 episodes), a representative VLM-led agent
falls **below the policy alone** (Cosmos Policy 67.9 → 65.2, π0.5 64.3 → 60.5), while Spotter still improves it
(→ 71.7 and 68.4).
### ⚡ Almost no overhead when nothing goes wrong
With Qwen, the judge is called **less than once** per successful episode on average, which adds only **13–16 s**
over the policy alone and takes about **70% less time** than a VLM-led agent using the same Qwen.
> **Simulators.** Spotter runs on both [RoboCasa](#robocasa) and [RoboTwin 2.0](#robotwin-20). RoboTwin 2.0 has a
> one-command evaluation, `bash robotwin_eval.sh` (see [Evaluation](#-evaluation-with-released-checkpoints)).
>
> **RoboTwin 2.0 results and full logs** (every episode's frames, prompts and replies):
> [50 tasks × 10 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-50x10) (policy alone vs. Spotter-Qwen)
> and [150 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-150) (policy alone, Spotter and a
> VLM-led agent, each with Qwen and GPT).
## 📑 Index
- [File Structure](#-file-structure)
- [Environment Setup](#-environment-setup)
- [Model Preparation](#-model-preparation)
- [Simulator Assets and Episode Sets](#-simulator-assets-and-episode-sets)
- [Evaluation with Released Checkpoints](#-evaluation-with-released-checkpoints): [RoboCasa](#robocasa) · [RoboTwin 2.0](#robotwin-20)
- [Reproducing the Paper](#-reproducing-the-paper)
- [Building the Lesson Library and Example Bank](#-building-the-lesson-library-and-example-bank)
- [Plugging In Your Own Embodied Model](#-plugging-in-your-own-embodied-model)
- [Outputs](#-outputs) · [Configuration Reference](#-configuration-reference)
- [Acknowledgements](#-acknowledgements) · [License](#-license) · [Contact](#-contact) · [Citation](#-citation)
## 📂 File Structure
```text
Spotter/
├── spotter.sh # one entry point: serve Qwen / the policy, run episodes, summarize
├── robotwin_eval.sh # one-command RoboTwin 2.0 evaluation (servers + Spotter arm + control + summary)
├── recovery_explore/ # Spotter itself
│ ├── judge_driver_v7.sh # supervision loop for one lane: screen -> judge -> repair -> verify
│ ├── env_service.py # RoboCasa simulation service (RPC), started by launch_svc.sh
│ ├── env_service_robotwin.py # RoboTwin 2.0 simulation service (same RPC surface, SAPIEN)
│ ├── robotwin_intervention.py # RoboTwin repair primitives (dual arm); robodojo_intervention.py is its base
│ ├── robotwin_policy_server.py # RoboTwin pi0.5 policy server (openpi websocket protocol)
│ ├── primitives.py # motion primitives the judge composes repairs from
│ ├── grasp_aim.py # RoboCasa `aim` step: finds the object in the wrist depth image and plans the grasp
│ ├── render_guard.py # RoboCasa: re-renders black / noise frames from a leaked EGL context
│ ├── JUDGE_BRIEF_V7.md # judge prompt; BRIEF_PNP.md / BRIEF_MECH.md / BRIEF_RT.md add task-family notes
│ ├── cli/ # screener, judge channels (Qwen / GPT), harness, few-shot tools
│ ├── memory_bank/ # frozen library of 77 general lessons (RoboCasa)
│ ├── memory_bank_robotwin_noreset/ # the RoboTwin 2.0 lessons
│ ├── episode_sets/ # sall500.txt (paper, 1,200) · s500q96.txt (96, debugging) · rt500.txt / rt150.txt (RoboTwin 2.0)
│ ├── fewshot_bank/ # (downloaded) worked examples for the 1-shot setting; robotwin/ for RoboTwin 2.0
│ └── runs__/ # (generated) results.jsonl, per-lane logs, frames shown to the judge
├── rpc/ # π0.5 policy server, RPC protocol, RoboCasa rollout and collection scripts
├── cf_bench/ # snapshot and replay tools for the error-correction study
├── env/ # env.sh.example, requirements-robocasa.txt, requirements-pi05.txt
├── assets/ # logo
└── LICENSE · THIRD_PARTY_NOTICES.md · LICENSES/
```
## 🔧 Environment Setup
**Qwen screener and judge.** vLLM in its own environment, and a local `env/env.sh`:
```bash
python3 -m venv .venvs/vllm && .venvs/vllm/bin/pip install vllm
cp env/env.sh.example env/env.sh && $EDITOR env/env.sh
```
**RoboCasa.** Spotter uses three Python environments for RoboCasa:
| Environment | Python | Runs | Install |
|---|---|---|---|
| `robocasa` | 3.10 | simulation service, judge driver, Cosmos policy server | [Cosmos Policy](https://github.com/NVlabs/cosmos-policy) RoboCasa setup, then `env/requirements-robocasa.txt` |
| `pi05` | 3.12 | π0.5 policy server (LeRobot) | `env/requirements-pi05.txt` |
| `vllm` | 3.10+ | Qwen screener and judge | the Qwen step above |
```bash
# 1) RoboCasa + Cosmos Policy: follow the RoboCasa setup of https://github.com/NVlabs/cosmos-policy, then
pip install -r env/requirements-robocasa.txt
# 2) π0.5
python3.12 -m venv .venvs/pi05 && .venvs/pi05/bin/pip install -r env/requirements-pi05.txt
```
> **Note.** Headless MuJoCo rendering needs an EGL-capable NVIDIA GPU (`MUJOCO_GL=egl`, set in `env/env.sh`).
**RoboTwin 2.0.** Spotter runs on [RoboTwin 2.0](https://github.com/RoboTwin-Platform/RoboTwin)
(aloha-agilex dual arm, SAPIEN 3, 50 tasks, `demo_randomized` scenes); the family is `robotwin`.
RoboTwin's simulator and planner (SAPIEN 3, mplib, cuRobo) live in their own Python 3.10 environment,
laid out as a *portable runtime* that `env/env.sh` points at:
```text
/
├── .venv/ # python 3.10: sapien 3.0.0b1, mplib 0.2.1, toppra, torch (CUDA build matching your GPU)
└── worktree/third_party/RoboTwin/ # the RoboTwin 2.0 tree
├── envs/curobo/src/ # cuRobo sources (its CUDA kernels must match your torch)
├── assets/{objects,background_texture,embodiments}/ # RoboTwin 2.0 assets (TianxingChen/RoboTwin2.0 on the Hub)
└── policy/pi0/checkpoints/pi05_robotwin2_clean_randomized/robotwin2/40000/ # the pi0.5 checkpoint
```
Install RoboTwin 2.0 and its assets as its README says, then set in `env/env.sh`:
```bash
export ROBOTWIN_RUNTIME=/path/to/robotwin-runtime # or ROBOTWIN_ROOT + ROBOTWIN_PY
export ROBOTWIN_POLICY_PYTHON=/path/to/robotwin-policy-venv/bin/python # a venv satisfying policy/pi05/requirements.txt (openpi, lerobot < 0.3)
```
The simulation renders with SAPIEN's ray tracer (Vulkan, RTX-class GPU); on RTX 5090 the `optix` denoiser is used
because the default `oidn` fails there.
## 📦 Model Preparation
**1) Qwen judge and screener.**
```bash
huggingface-cli download Qwen/Qwen3.8-27B-FP8 --local-dir checkpoints/Qwen3.8-27B-FP8
```
Then set in `env/env.sh`:
```bash
export QWEN_MODEL=$PWD/checkpoints/Qwen3.8-27B-FP8
export VLLM_VENV=$PWD/.venvs/vllm
```
**2) RoboCasa.** Download π0.5 and Cosmos Policy:
```bash
huggingface-cli download DAVIAN-Robotics/pi05-robocasa-H50 --local-dir checkpoints/pi05-robocasa-H50
huggingface-cli download nvidia/Cosmos-Policy-RoboCasa-Predict2-2B --local-dir checkpoints/Cosmos-Policy-RoboCasa-Predict2-2B
```
Expected layout:
```text
checkpoints/
├── pi05-robocasa-H50/ # model.safetensors, config.json, policy_*processor*, tokenizer/
├── Cosmos-Policy-RoboCasa-Predict2-2B/ # Cosmos-Policy-RoboCasa-Predict2-2B.pt, robocasa_t5_embeddings.pkl, ...
└── Qwen3.8-27B-FP8/
```
Then set in `env/env.sh`:
```bash
export PI05_CHECKPOINT=$PWD/checkpoints/pi05-robocasa-H50
export COSMOS_CHECKPOINT=$PWD/checkpoints/Cosmos-Policy-RoboCasa-Predict2-2B/Cosmos-Policy-RoboCasa-Predict2-2B.pt
```
For the 1-shot setting, download the RoboCasa example bank (151 MB):
```bash
curl -L https://github.com/zqc3117/Spotter/releases/download/v1.0/fewshot_bank.tar.gz | tar -xz -C recovery_explore
```
**3) RoboTwin 2.0.** The policy is the pi0.5 checkpoint
[motus-robotics/pi0.5_robotwin2](https://huggingface.co/motus-robotics/pi0.5_robotwin2), placed at
`policy/pi0/checkpoints/pi05_robotwin2_clean_randomized/robotwin2/40000/` inside the RoboTwin tree
(see [Environment Setup](#-environment-setup)). For the 1-shot setting, download the RoboTwin example bank (33 MB)
into `recovery_explore/fewshot_bank/robotwin/`:
```bash
curl -L https://github.com/zqc3117/Spotter/releases/download/v1.0/fewshot_bank_robotwin.tar.gz | tar -xz -C recovery_explore
```
> **GPT judge (optional).** Set `ENGINE=api` together with `OPENAI_RESPONSES_URL` and `OPENAI_API_TOKEN_FILE`;
> the judge becomes GPT-6 Astra while the screener stays the local Qwen.
## 🧭 Simulator Assets and Episode Sets
**RoboCasa assets** are installed by the Cosmos Policy RoboCasa setup above.
**RoboTwin 2.0 assets** are installed with RoboTwin itself ([Environment Setup](#-environment-setup)).
**Episode sets** ship with the repository, one `TASK:SEED:EPISODE` per line:
| File | Episodes | Use |
|---|---:|---|
| `episode_sets/sall500.txt` | 1,200 | RoboCasa paper evaluation: 24 tasks × episodes 0–49, seed 500 |
| `episode_sets/s500q96.txt` | 96 | RoboCasa debugging subset, 4 episodes per task |
| `episode_sets/rt50x10n.txt` | 500 | RoboTwin 2.0: 50 tasks × 10 episodes |
| `episode_sets/rt500.txt` | 500 | RoboTwin 2.0 evaluation used for the released results: `rt50x10n` with the episodes that cannot be built in the current simulator replaced by the next buildable episode of the same task |
| `episode_sets/rt150.txt` | 150 | RoboTwin 2.0 comparison with a VLM-led agent: 50 tasks × 3 episodes, a subset of `rt500` |
RoboCasa lessons and worked examples were learned on seed 195, disjoint from the test seed.
## 🚀 Evaluation with Released Checkpoints
Each server runs in its own terminal after `source env/env.sh`.
**1) Serve the Qwen screener and judge** (one replica per GPU, ports 8301, 8302, ...).
```bash
bash spotter.sh judge --gpus 0,1,2,3
curl -s http://127.0.0.1:8301/v1/models # check
```
With fewer GPUs, pass fewer ids (e.g. `--gpus 0`) and `export QWEN_PORTS=8301` before running.
### RoboCasa
**2) Serve the embodied model**: π0.5 on port 8900 or Cosmos Policy on port 8800.
```bash
bash spotter.sh policy pi05 --gpu 4 # or: bash spotter.sh policy cosmos --gpu 4
curl -s http://127.0.0.1:8900/health # check
```
**3) Smoke test: one episode.** The driver starts the simulation service by itself.
```bash
bash spotter.sh run pi05 # one episode, control and Spotter on the same scene
```
**4) Full evaluation on `sall500`.**
```bash
bash spotter.sh run pi05 sall500 --lanes 8
bash spotter.sh summary
```
Running the driver directly
`spotter.sh run` launches one driver per lane. The single-episode pi0.5 run above is equivalent to:
```bash
mkdir -p recovery_explore/runs_smoke
printf 'PnPCabToCounter:195:0\n' > recovery_explore/runs_smoke/episodes_pi05.txt
ON_POD=1 RUN=smoke TARGET=1 NGPU=1 FAMILY_OVERRIDE=pi05 \
SIM_HOST=127.0.0.1 SIM_MANAGED=0 POLICY_URL=http://127.0.0.1:8900 \
ENGINE=qwen MODEL=qwen38 SCREEN=1 QWEN_KEEP_TURNS=20 \
STEP_BUDGET_SCALE=1.8 WINDOW=1 TEL_CHUNKS=10 COMPACT_AT=110000 MAX_INTERVENTIONS=8 \
ALLOW_RESET=0 MAX_RESETS=0 FEWSHOT=0 LEARN=0 CTRL_ONLY=0 SKIP_CONTROL=0 \
bash recovery_explore/judge_driver_v7.sh 0
```
The driver starts and restarts the simulation service on port `8450+lane` by itself. All lanes of a run
claim episodes from the same queue, and each lane stops once the run has `TARGET` results.
### RoboTwin 2.0
**One command.** `robotwin_eval.sh` starts Qwen and the pi0.5 policy if they are not already up, runs the Spotter arm
and then the policy-only control on the same 500 episodes (`rt500`), and prints the summary. It uses the settings of
the released results: 1.8× step budget, 1-shot, Qwen thinking in the repair turns with `QWEN_THINK_BUDGET=5000`.
```bash
bash robotwin_eval.sh --judge-gpus 0,1,2,3 --policy-gpu 4 --lanes 12
```
Add `--dry-run` to print the commands without running them. Each RoboTwin simulator takes about 8 GB of GPU memory,
so plan about three lanes per 32 GB GPU. The judge's thinking dominates the time of the Spotter arm; more Qwen replicas
(`--judge-gpus`) make it faster.
Step by step
With the Qwen servers from step 1 running:
```bash
bash spotter.sh policy robotwin --gpu 4 # pi0.5 for RoboTwin, port 9100 (check: curl http://127.0.0.1:9100/healthz)
bash spotter.sh run robotwin # smoke: adjust_bottle, episode 35
bash spotter.sh run robotwin rt500 --lanes 12 --one-shot # Spotter arm on the 500 evaluation episodes (1-shot)
bash spotter.sh run robotwin rt500 --lanes 12 --arm ctrl # the policy-only baseline on the same episodes
bash spotter.sh summary
```
**Results with this code.** We re-ran the Spotter arms on RoboTwin 2.0 with this version of the code, on the 500
episodes of `rt500` (1.8× step budget, 1-shot); the control is the policy alone on the same 500 episodes:
| Arm | Success |
|---|---:|
| Policy alone (pi0.5) | 240 / 500 (48.0%) |
| Spotter-Qwen, `QWEN_THINK_BUDGET=2000` | 252 / 500 (50.4%) |
| Spotter-Qwen, `QWEN_THINK_BUDGET=5000` (default) | 267 / 500 (53.4%) |
Because every run involves randomness, these numbers differ somewhat from the paper. We have uploaded the
per-episode results, with every episode's frames, judge prompts and replies, to ModelScope:
[50 tasks × 10 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-50x10).
**Comparison with a VLM-led agent (150 episodes).** On `rt150` (50 tasks × 3 episodes, a subset of `rt500`), with the
same settings (1.8× step budget, 1-shot, Qwen thinking in the repair turns up to 5000 tokens), we also ran Spotter with
GPT and a VLM-led agent with both LLMs; every arm runs on the same episodes. The VLM-led agent drives the episode turn by
turn and calls the policy as a tool; its code is not part of this release.
| Arm | LLM | Success |
|---|---|---:|
| Policy alone (pi0.5) | – | 72 / 150 (48.0%) |
| Spotter | Qwen3.8-27B-FP8 | 79 / 150 (52.7%) |
| Spotter | GPT-6-astra | 84 / 150 (56.0%) |
| VLM-led agent | Qwen3.8-27B-FP8 | 63 / 150 (42.0%) |
| VLM-led agent | GPT-6-astra | 84 / 150 (56.0%) |
The complete records of all five arms, with every episode's frames, prompts and replies, are on ModelScope:
[150 episodes](https://www.modelscope.ai/datasets/seamoke/spotter-robotwin-150).
### Run options
`bash spotter.sh run [SET] [options]`, for both simulators:
| Option | Meaning |
|---|---|
| `SET` | `smoke` (1 episode, default); RoboCasa: `s500q96`, `sall500`; RoboTwin 2.0: `rt500`, `rt150`, `rt50x10n`; or a file with one `TASK:SEED:EPISODE` per line |
| `--lanes N` | episodes run in parallel; lane `N` runs its own simulation service on port `8450+N` |
| `--sim-gpus N` | GPUs the simulation services share, GPU `0..N-1` (default: all) |
| `--arm` | `both` (control and Spotter on each episode, default), `treat` (Spotter only), `ctrl` (policy only) |
| `--one-shot` | add one worked example to the judge (needs the example bank) |
| `--run NAME` | run name (default `_`); rerunning the same name resumes it |
| `--dry-run` | print the commands without running them |
Both arms of an episode share the same scene, instruction and step budget:
| Arm | Description |
|---|---|
| **Control** | Policy only; no judge calls. |
| **Treatment** | Policy plus judge and optional interventions. |
`spotter.sh run ` applies that family's column of the [Configuration Reference](#-configuration-reference); every setting can still be overridden through the environment.
## 📊 Reproducing the Paper
The Spotter rows of Table 1 (RoboCasa, 1,200 episodes) are the full evaluation above with these settings;
variables are exported before `spotter.sh run`.
| Table 1 row | Settings |
|---|---|
| Embodied model, 1.0× / 1.8× step limit | `--arm ctrl` with `STEP_BUDGET_SCALE=1.0` / `1.8` |
| Spotter (Qwen), full context | `spotter.sh` defaults |
| Spotter (Qwen), short context | `TEL_CHUNKS=3 QWEN_KEEP_TURNS=3 COMPACT_AT=22000 MAX_INTERVENTIONS=3 SCREEN_CONFIRM2=0` (π0.5 also `WINDOW=2`) |
| Spotter (Qwen), 1-shot | `--one-shot` |
| Spotter (GPT), with / no screener | `ENGINE=api` with `SCREEN=1` / `SCREEN=0` |
| Spotter (GPT), 1-shot | `ENGINE=api` and `--one-shot` |
| Harness VLA | run with its own code: [RLinf/RPent](https://github.com/RLinf/RPent) |
The fixed-retry rows of Table 1 are not included in this release.
**Supervision mode.** `spotter.sh` runs the synchronous supervision loop (`ASYNC_SCREEN=0`). For the bounded
asynchronous mode of Section 3.2, set `ASYNC_SCREEN=2 ASYNC_K=2`: the policy runs at most two supervision windows
ahead of the last check (4 chunks on Cosmos Policy, 2 on π0.5).
**Time.** `results.jsonl` logs the wall-clock time of each arm and of the judge and screener calls (see
[Outputs](#-outputs)); token counts are not logged by this release.
**Section 3.1.** `rpc/run_remote_robocasa_cf_branch_collect.py` collects the post-failure and normal candidates, and
`cf_bench/` replays them and runs the language-feedback protocol. The test-time scorers (Consistency-Consensus,
GeoBoN, RCS) are not included.
## 🧠 Building the Lesson Library and Example Bank
The released library (77 general lessons in `recovery_explore/memory_bank/global/`) and the example bank are frozen
and used as-is for every paper result; this section is only needed to rebuild them or to cover new tasks.
**1) Run learning episodes** on seed 195, never on the test seed. Only here may the judge reset and retry; each
episode writes its lessons as drafts to `memory_bank/inbox//`.
```bash
ENGINE=api LEARN=1 ALLOW_RESET=1 MAX_RESETS=5 bash spotter.sh run cosmos --run learn_cosmos
```
**2) Review the drafts** and move the general ones into `memory_bank/global/`, following the lesson format in
`recovery_explore/memory_bank/README.md`. Remove anything privileged or task-specific.
**3) Build the example bank** for the 1-shot setting from the learning runs:
```bash
python3 recovery_explore/cli/fewshot_build.py --family cosmos --seed 195 --out recovery_explore/fewshot_bank
```
## 🔌 Plugging In Your Own Embodied Model
Spotter never trains the policy, so a new embodied model only needs to be served and registered:
1. **Serve it over the same RPC interface** as `rpc/policy_server_pi05.py`: `GET /health`, and `POST /v1/infer`
taking an `InferenceRequest` (task description, seed, observation images and state) and returning an
`InferenceResponse` with an action chunk (see `rpc/protocol.py`).
2. **Register the family** next to `cosmos` and `pi05`: action dimension and steps per chunk in
`recovery_explore/cosmos_call.py` and `env_service.py`, service launch in `launch_svc.sh`, port and defaults in `spotter.sh`.
3. **Choose the supervision granularity**: `WINDOW` (chunks per screening check) and `TEL_CHUNKS` (telemetry rows
shown to the judge).
4. **Run** `bash spotter.sh run ...`.
## 📈 Outputs
```text
recovery_explore/runs__/
├── results.jsonl # one line per episode
├── lane/driver.log # per-lane progress
└── lane/jd-.../w/ # frames shown to the judge in window k
```
| Field | Meaning |
|---|---|
| `task`, `seed`, `episode` | the episode |
| `control_success` / `treatment_success` | success of the policy alone / with Spotter |
| `interventions`, `judge_calls`, `screened_windows` | repairs executed, judge calls, windows the screener passed |
| `ctrl_s`, `treat_s` | wall-clock seconds of the control and Spotter arms (`-1` if the arm was skipped) |
| `model_s`, `screen_s` | seconds spent in judge calls and in screener calls |
| `stale_steps`, `stale_ivs` | asynchronous mode only: steps and repairs made on an out-of-date window |
```bash
bash spotter.sh summary # all runs
bash spotter.sh summary pi05_sall500
bash spotter.sh summary robotwin_rt500
```
## 🧩 Configuration Reference
| Setting | RoboCasa · Cosmos | RoboCasa · pi0.5 | RoboTwin 2.0 · pi0.5 |
|---|---:|---:|---:|
| `FAMILY_OVERRIDE` | `cosmos` | `pi05` | `robotwin` |
| Steps per chunk | 16 | 25 | 16 |
| `WINDOW` (judge window, in chunks) | 2 | 1 | 2 |
| `TEL_CHUNKS` / `RT_TEL_CHUNKS` | 40 | 10 | 10 |
| `MAX_INTERVENTIONS` | 8 | 8 | 5 |
| `QWEN_KEEP_TURNS` / `COMPACT_AT` | 20 / 110000 | 20 / 110000 | 10 / 40000 |
| Policy port | 8800 | 8900 | 9100 |
| Policy server | `python -m rpc.server` (upstream Cosmos Policy) | `python -m rpc.policy_server_pi05` | `recovery_explore/robotwin_policy_server.py` |
`spotter.sh run ` applies the matching column, and `robotwin_eval.sh` the RoboTwin 2.0 one with `--one-shot`, as in the released results; every value can be overridden through the environment. The parameters below are shared; their paper values refer to RoboCasa, and the per-family values above take precedence.
| Parameter | Paper value | Purpose |
|---|---:|---|
| `STEP_BUDGET_SCALE` | `1.8` | Step budget multiplier; same value for control and treatment. |
| `SCREEN` | `1` | Screener on; `0` calls the judge every window. |
| `SCREEN_CONFIRM2` | `1` | Call the judge after two consecutive flags; `0` after one. |
| `MAX_INTERVENTIONS` | `8` | Maximum interventions per episode. |
| `ALLOW_RESET` / `MAX_RESETS` | `0` / `0` | Disable rollbacks so episodes stay comparable. |
| `ENGINE` / `MODEL` | `qwen` / `qwen38` | Local Qwen judge; `ENGINE=api` for GPT-6 Astra. |
| `COMPACT_AT` | `110000` | Qwen conversation compaction threshold (tokens). |
| `QWEN_KEEP_TURNS` | `20` | Recent judge turns kept in full. |
| `FEWSHOT` | `0` | `1` adds one worked example (`--one-shot`); needs the example bank. |
Qwen thinks only in the repair turns of an intervention, up to `QWEN_THINK_BUDGET` (default `5000`) tokens per call; the screener and the window verdict never think, and `QWEN_REPAIR_THINK=0` turns thinking off everywhere, as in the paper.
**Choosing the thinking budget.** Set `QWEN_THINK_BUDGET` to what your Qwen servers can afford. A larger budget gives
the repair plan more room but makes every repair turn slower; a smaller one is faster but cuts the thinking off before
it finishes. Use the largest budget that keeps repair turns within `ACT_DEADLINE` (raise that too on slow GPUs or with
many lanes per replica), and check after a run that most repair turns were **not** cut off. Each repair reply is saved
as `act_w*_a*_r*.json` in the episode folder, with `think_budget_hit: true` when the thinking ran into the budget:
```bash
python3 - <<'EOF'
import glob, json
files = glob.glob("recovery_explore/runs__/lane*/jd-*/act_w*.json")
hit = sum(bool(json.load(open(f)).get("think_budget_hit")) for f in files)
print(f"{hit}/{len(files)} repair turns hit the thinking budget")
EOF
```
If more than about half are cut, raise the budget (or add Qwen replicas so the larger budget stays fast). On RoboTwin 2.0,
a budget of 2000 cut off the thinking in about 65% of the repair turns, and 5000 in about 44%.
How the judge is paced has its own switches, all off or conservative by default:
| Variable | Default | Effect |
|---|---:|---|
| `ASYNC_SCREEN` | `0` | `1` lets the policy keep stepping while the judge works; the loop then resumes at the newest finished window. Faster, but the judge is looking at a window the episode has already moved past — `results.jsonl` records that cost as `stale_steps` and `stale_ivs`. `2` also holds the policy within `ASYNC_K` windows of the last check. |
| `MISS_GRACE` | `2` | Windows the policy gets to retry on its own after closing on nothing, before the judge may take over. |
| `FIRST_IV_FRAC` | `35` | The first intervention waits until the policy has closed on nothing at least once, or the episode is this far (%) into its step budget. `0` disables the gate. |
| `MONITOR_AFTER_BUDGET` | `1` | Keep calling the judge once the intervention budget is spent, for the record. `0` stops calling it. |
| `LATE_IV_FRAC` | `45` (RoboCasa), `0` (RoboTwin 2.0) | No *first* intervention once the episode is this far (%) into its step budget; later interventions are unaffected. `0` disables it. |
| `PLAN_ROUNDS` | `5` (RoboCasa), `3` (RoboTwin 2.0) | Plan segments the judge may send within one intervention. |
**RoboCasa repair steps.** Besides the motion primitives, the RoboCasa judge has an `aim` step: the robot looks down with
its wrist depth camera, finds the object near the last missed grasp (or near a point the judge names), grasps it across
its short side, lifts slightly to check the hold, and reports `held`, `closed_empty`, `slipped`, `no_object`, `too_wide`,
`blocked` or `step_cap`. A hand-back right after a held grasp keeps the gripper closed (`{"op": "policy", "hold": true}`
does the same explicitly). Pixel targets are `[row, col]` normalized to 0–1000 within one camera image (`PIXEL_FRAME=1000`;
`512` takes raw pixels), and Qwen gets each camera as its own image for pointing (`QWEN_POINT_TILES=1`). Everything the
judge uses comes from the cameras and the robot's own joint and gripper readings.
Changing `STEP_BUDGET_SCALE`, `WINDOW` or the policy family changes the experiment. Compare runs only on the same
episode set; because the policies' rollouts are not bit-reproducible, compare aggregate success rates rather than
single episodes.
## 🙏 Acknowledgements
- [RoboCasa](https://robocasa.ai): the simulation benchmark and assets we evaluate on.
- [Cosmos Policy](https://github.com/NVlabs/cosmos-policy): the released RoboCasa checkpoint and its policy server.
- [π0.5](https://huggingface.co/DAVIAN-Robotics/pi05-robocasa-H50) and [LeRobot](https://github.com/huggingface/lerobot): the RoboCasa π0.5 checkpoint and the library that loads it.
- [RoboTwin 2.0](https://github.com/RoboTwin-Platform/RoboTwin) and [pi0.5 for RoboTwin 2.0](https://huggingface.co/motus-robotics/pi0.5_robotwin2): the dual-arm benchmark and the policy checkpoint we evaluate with.
- [Qwen](https://huggingface.co/Qwen) and [vLLM](https://github.com/vllm-project/vllm): the local screener and judge.
- [RPent](https://github.com/RLinf/RPent): parts of `recovery_explore/` are adapted from it (Apache-2.0, see `THIRD_PARTY_NOTICES.md`).
## 📜 License
This project is released under the [MIT License](LICENSE). Some files in
`recovery_explore/` are adapted from RPent and remain under the Apache License 2.0; see
[THIRD_PARTY_NOTICES.md](THIRD_PARTY_NOTICES.md).
## 📬 Contact
Have a question, want to share results, or just follow development? Join us:
You can also ask questions and share ideas in [GitHub Discussions](https://github.com/zqc3117/Spotter/discussions), report bugs in [Issues](https://github.com/zqc3117/Spotter/issues), or email Qichao Zhao at [zhaoqc25@mails.tsinghua.edu.cn](mailto:zhaoqc25@mails.tsinghua.edu.cn).
## 📖 Citation
```bibtex
@article{li2026spotter,
title = {Spotter: Let the Embodied Model Lead, and the VLM Reflect for It},
author = {Li, Long and Zhao, Qichao and Yang, Yue and Xu, Fan and Wang, Zhe and Liew, Alan Wee-Chung and Qu, Chao and Shen, Heng Tao and Pan, Shirui},
journal = {arXiv preprint arXiv:2609.36808},
year = {2026}
}
```
|