-windows-x86_64-cuda.zip` has
`coli_cuda.dll` (cards of compute capability 8.0 and newer) and the colibri,
qwen36 and kimi_k3 engines that load it, with DeepSeek V4's own CUDA DLLs. Unpack it
over the main archive and the setup picks CUDA.
- **Every layer on the card** for Qwen3.6, Qwen3.8 and OLMoE: the dense layers,
the attention and the routed experts the card holds run as one chain, and the
experts it does not hold run on the CPU. On an RTX PRO 4000,
Qwen3.6-35B-A3B UD-Q4_K_M decodes at 104.8 tok/s and reads a prompt at 3,491,
OLMoE at 354.6 and 10,418 ([the table](#three-backends-on-one-machine)).
- **A routed-expert tier on the card for every engine** (`cu_tier.h`), and the
dense matrices on it for DeepSeek V4, V4.1, Kimi K3, GLM-5.3 and MiMo
(`cu_dense.h`).
- **A GGUF's blocks on the card** (`cuda_bd.cuh`): every ggml block type of 32
weights or more, each row as the file has it; a prompt goes through the
tensor cores ([gguf.md](docs/gguf.md)).
- **The VRAM expert tier** keeps the hottest experts on the card, chosen from
measured routing; misses compute on the CPU at the same time. Qwen3.6 on two
8 GB cards (RTX 3070 and Quadro RTX 4000) decoded 11.3 tok/s with a warm
history ([qwen36-cuda-tier.md](docs/qwen36-cuda-tier.md)); GLM-5.2 on six
RTX 5090 with every expert resident, 9.0-9.2 tok/s
([benchmarks.md](docs/benchmarks.md)); DeepSeek V4 Flash on an RTX 5080,
1.5-1.6 tok/s and a 3,324-token prompt in 90 s
([deepseek-v4.md](docs/deepseek-v4.md)).
- **Qwen3.6's DeltaNet layers on the card** (`Q36_DN_GPU=1`,
opt-in). Each of Qwen3.6's 30 DeltaNet layers used to copy its data between
the card and the CPU four times per token; now a decode token runs the whole layer
on the card, with its recurrent state kept in VRAM. On an RTX 3070 with the
dense layers in VRAM: 25.4 to 30.0 tok/s
([qwen36-cuda-tier.md](docs/qwen36-cuda-tier.md#the-deltanet-layer-on-the-card-q36_dn_gpu1)).
- **Older cards.** If the CUDA toolkit no longer compiles for your card (CUDA
13 and a V100, in [#1852](https://github.com/JustVugg/colibri/issues/1852)),
the setup sees it before building and uses the card through Vulkan, saying
why; a CUDA 12.x toolkit brings the CUDA path back.
DeepSeek V4's CUDA tier also builds for Pascal and Turing
(`CUDA_ARCH=portable-pre-ampere NO_TC=1`).
All of it: [docs/cuda.md](docs/cuda.md).
### Apple Silicon
A Metal backend does the expert math on the unified-memory GPU for several
engines ([docs/metal.md](docs/metal.md)). The release's macOS archive has
`colibri`, `inkling` and `kimi_k3` built with it: `COLI_METAL=1` (`K3_METAL=1`
for Kimi K3) turns it on, and without it they run on the CPU. From source,
build with `METAL=1`; the one-step setup builds for the CPU.
## System One: a decision with a probability
Most of what people ask a model for is a choice, not a paragraph: which queue,
which verdict, yes or no. `POST /v1/systemone` takes a state (text or JSON) and
typed questions, and answers each one with the probability of every allowed
option and a confidence. Nothing is generated, so no answer can fall outside
your list, and "the model is not sure" is a number you can put a threshold on.
```bash
curl -s http://127.0.0.1:8000/v1/systemone -H 'Content-Type: application/json' -d '{
"state": "340 lines, 8 files, no tests. CI is green but nothing covers that path.",
"questions": {
"review": {"type": "choice", "instructions": "What should the reviewer do?",
"criteria": {"merge": null, "request changes": null, "close": null}},
"risky": {"type": "noul", "instructions": "Is this change risky?"}}}'
```
A `choice` comes back with the chosen label, a probability for every label and a
`confidence` from 0 (flat) to 1 (certain); a `noul` with the probability of yes;
a `score` with the expected level.
Who answers:
- **Any chat model colibri runs**, by scoring: it reads the probability of each
option instead of writing an answer. Many questions about one document read
the document once: on Qwen3.6, four questions about one document came back
5.7x faster than generating the same answers on the same CPU box.
- **Three decision models**, natively, in one forward pass with the calibration
their authors fitted: [Laya](docs/laya.md) (Convai Innovations),
[GLiNER2.5-Decide](docs/gliner_decide.md) (fastino) and [Clef](docs/clef.md)
(Cloudflare; it also chats). Their sizes and speeds are in
[the decision models table](#which-model-for-my-machine).
**Switching from Jev.** The request and the reply are those of TypeSafe's Jev
API, so a Jev client switches to colibri by changing its base URL and nothing
else: `TYPESAFE_BASE_URL=http://127.0.0.1:8000` (the key it already sends is
accepted by a server started without `COLI_API_KEY`). The two official SDKs,
unmodified, are tested against `coli serve`.
The same mode is in the terminal (`/decide merge | request changes | close` in
`coli chat`) and on the dashboard's System One page. The request and reply in
full, the scoring rules and where it does not help:
[docs/systemone.md](docs/systemone.md).
## The dashboard
`coli web` opens it, and so does the one-step setup: the chat, the System One
page, the Brain and the Profiling page, in a light or a dark theme.
### The chat UI
`coli ui` opens the new chat next to a running `coli serve`: reasoning in its own block,
pictures for models with a vision tower, web search, the expert map, a live monitor, and
coding agents opened already pointed at colibri. Seven languages. See [ui/README.md](ui/README.md).
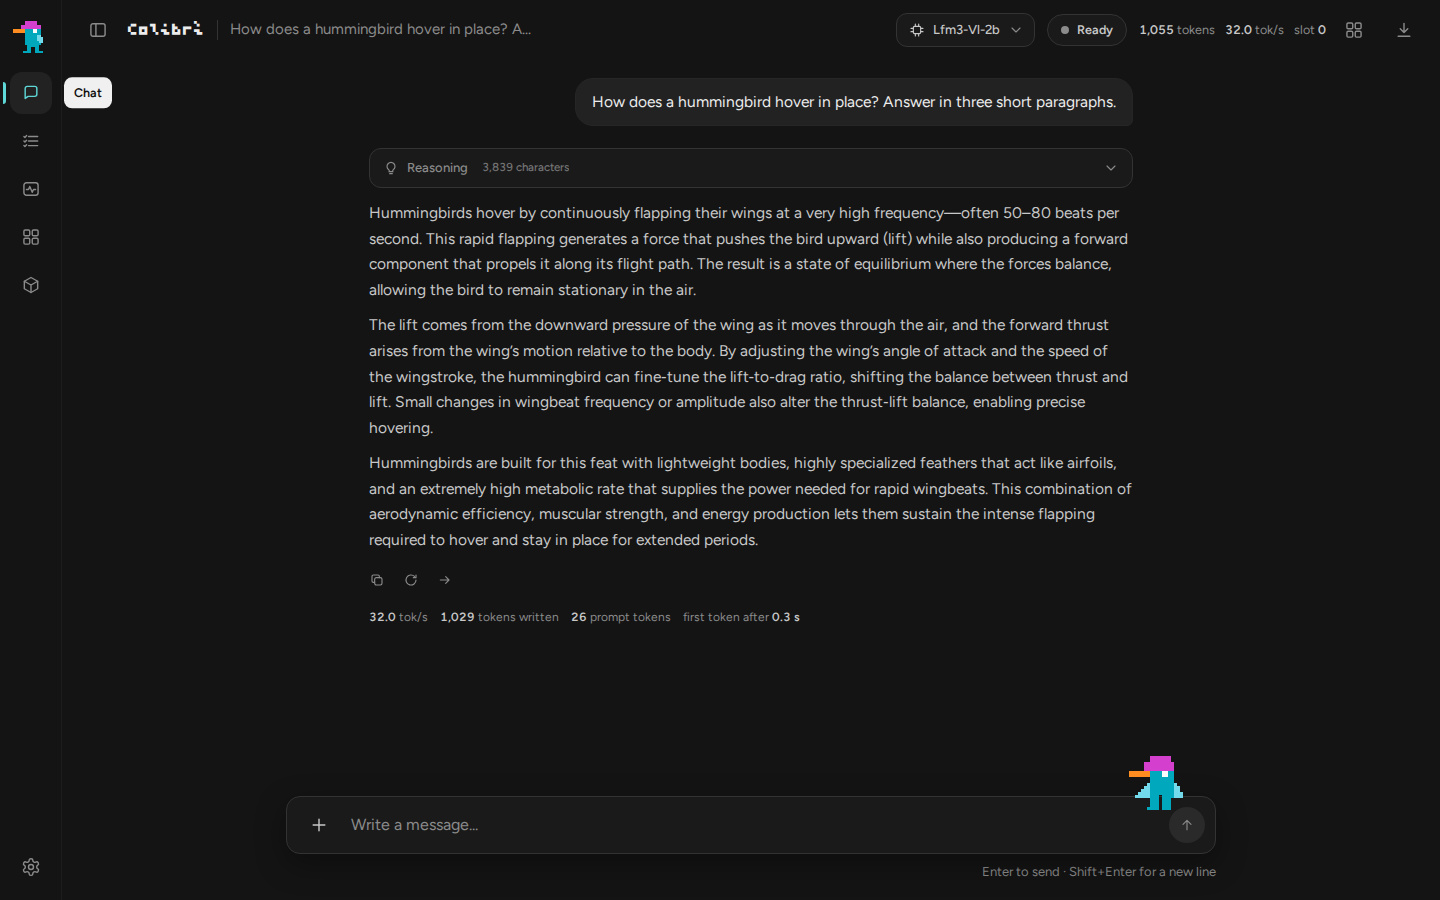
LFM3-VL-2B on an i5-13500's CPU, 32 tok/s.
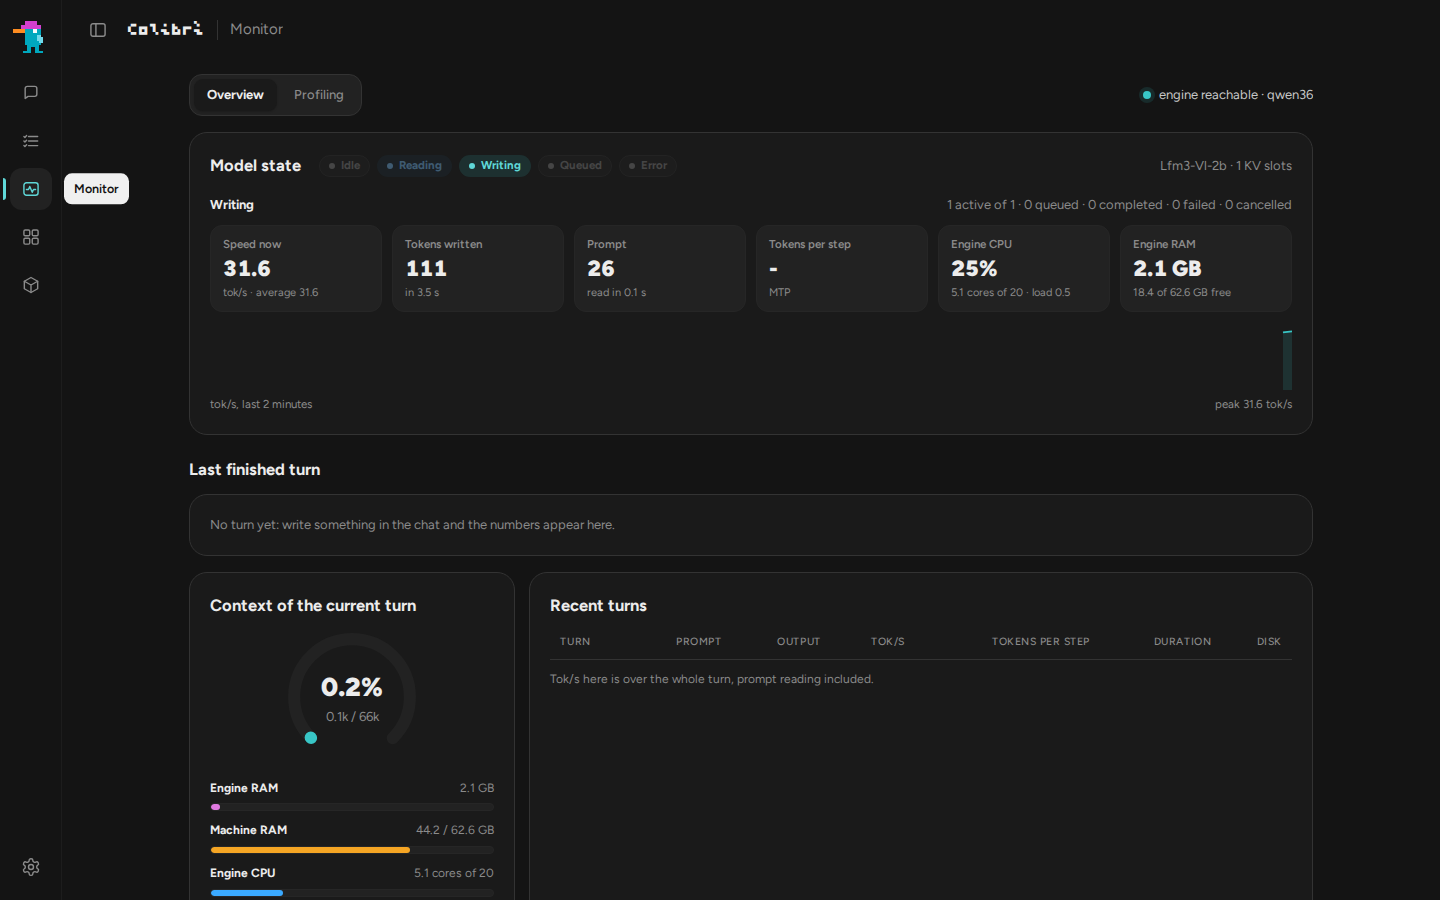
The monitor while LFM3-VL-2B writes: 31.6 tok/s, the prompt read in 0.1 s, 2.1 GB of RAM.
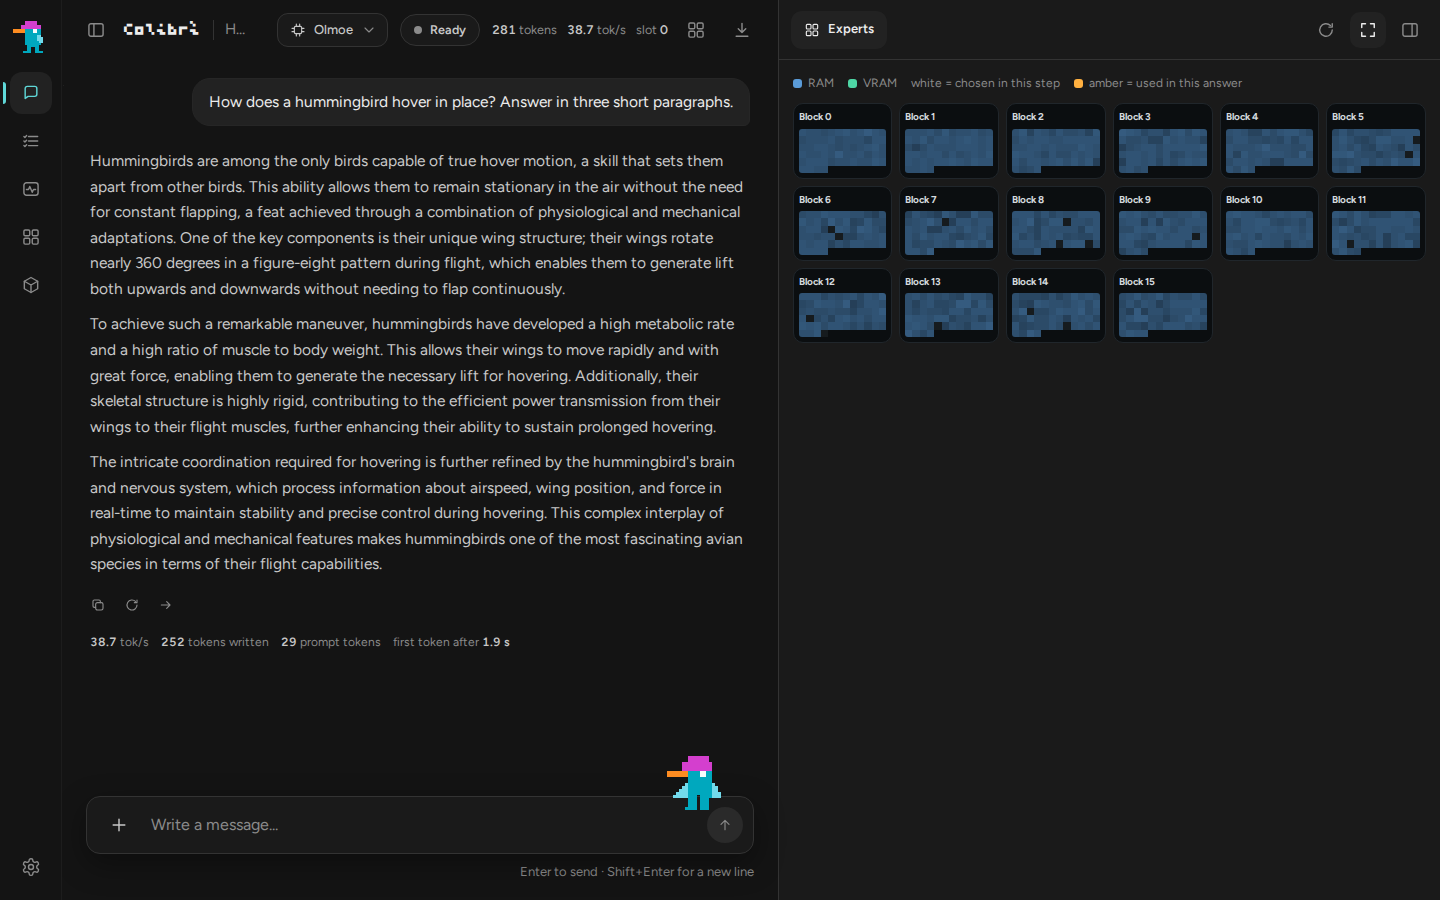
OLMoE with the expert map open beside the chat: a cell per expert in each block, white when chosen in this step,
amber when used in this answer.
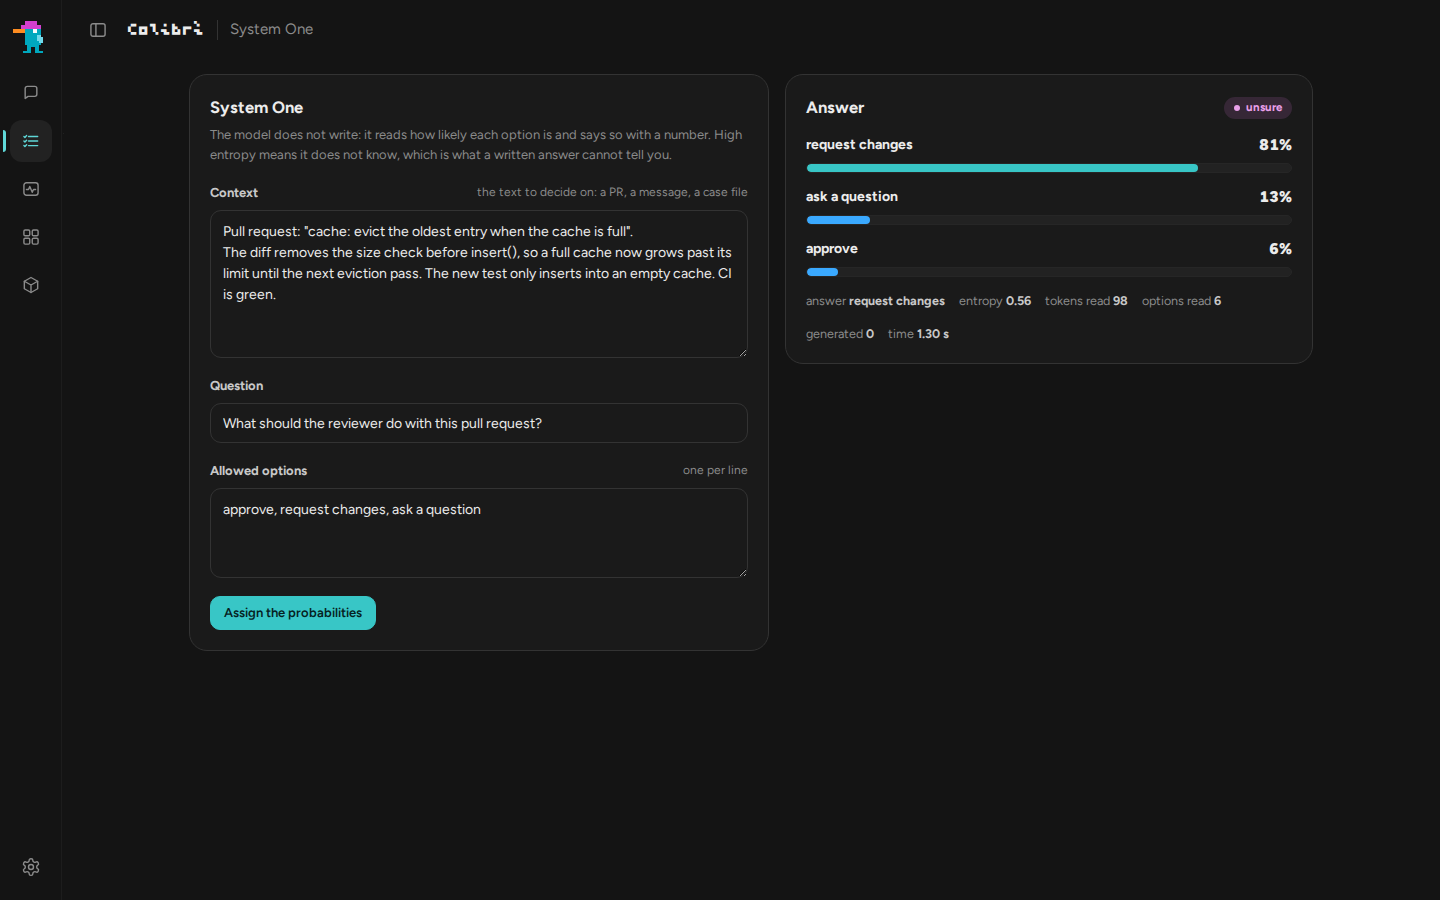
System One: give the model a document and the only answers it may pick. Here Qwen3.6-35B on an RTX PRO 4000
reads a pull request that breaks a cache's size limit: request changes at 81%, entropy 0.56 (unsure), 98 tokens read, 0 generated.
The **Profiling** page shows where each turn spends its time, phase by phase,
with the last 30 turns as a trend.
## Use it from other apps
`coli serve` (which the setup starts for you) is one server with several APIs:
- **OpenAI-compatible**: `/v1/chat/completions`, `/v1/completions` and
`/v1/models`, with streaming, JSON replies, stop sequences and logprobs;
- **Anthropic-compatible**: `/v1/messages`, so Claude Code and the Anthropic
SDKs work against it;
- **tool calling** on every chat engine except Inkling and OLMoE, each in its
model's native format ([the per-engine table](docs/api.md#tool-calling-support));
- **images in** on GLM-5.3-Flash, DeepSeek V4.1 Flash, MiMo-V2.6,
Qwen3.8-Flash-Next, Qwen3.8-27B, LFM3-VL and Mistral-Large-4 (from a GGUF, with
the `mmproj` file next to it): a path in a `coli chat` message, an
attachment in `coli web` or `coli ui`, or an `image_url` part;
- **documents in** on every chat engine: `/file PATH` in `coli chat` (or
`coli chat --file PATH`) sends a text file's or a PDF's text with the next
message. Only a file named that way is read, never a path inside a message;
it must be a regular file with a text suffix or `.pdf`, within 64 MiB and
2 million characters. A PDF is parsed in a separate process with a time and
memory limit, by `pdftotext` (poppler) or `pypdf`;
- **pictures out** with Qwen-Image-2.1 on `POST /v1/images/generations`,
and drawn inside the terminal by `coli chat`
([qwen-image.md](docs/qwen-image.md));
- **decisions** on `POST /v1/systemone` ([above](#system-one-a-decision-with-a-probability));
- **several conversations at once** on every text engine: `coli serve
--kv-slots N` keeps up to 16, each with its own cache, and decodes their next
tokens together ([api.md](docs/api.md#isolated-kv-contexts)).
Coding CLIs and editors connect as to any OpenAI-compatible provider: base URL
`http://127.0.0.1:8000/v1`, the model id `coli status` prints, any non-empty key
([docs/api.md](docs/api.md#connect-a-coding-cli-or-editor)).
## How it works
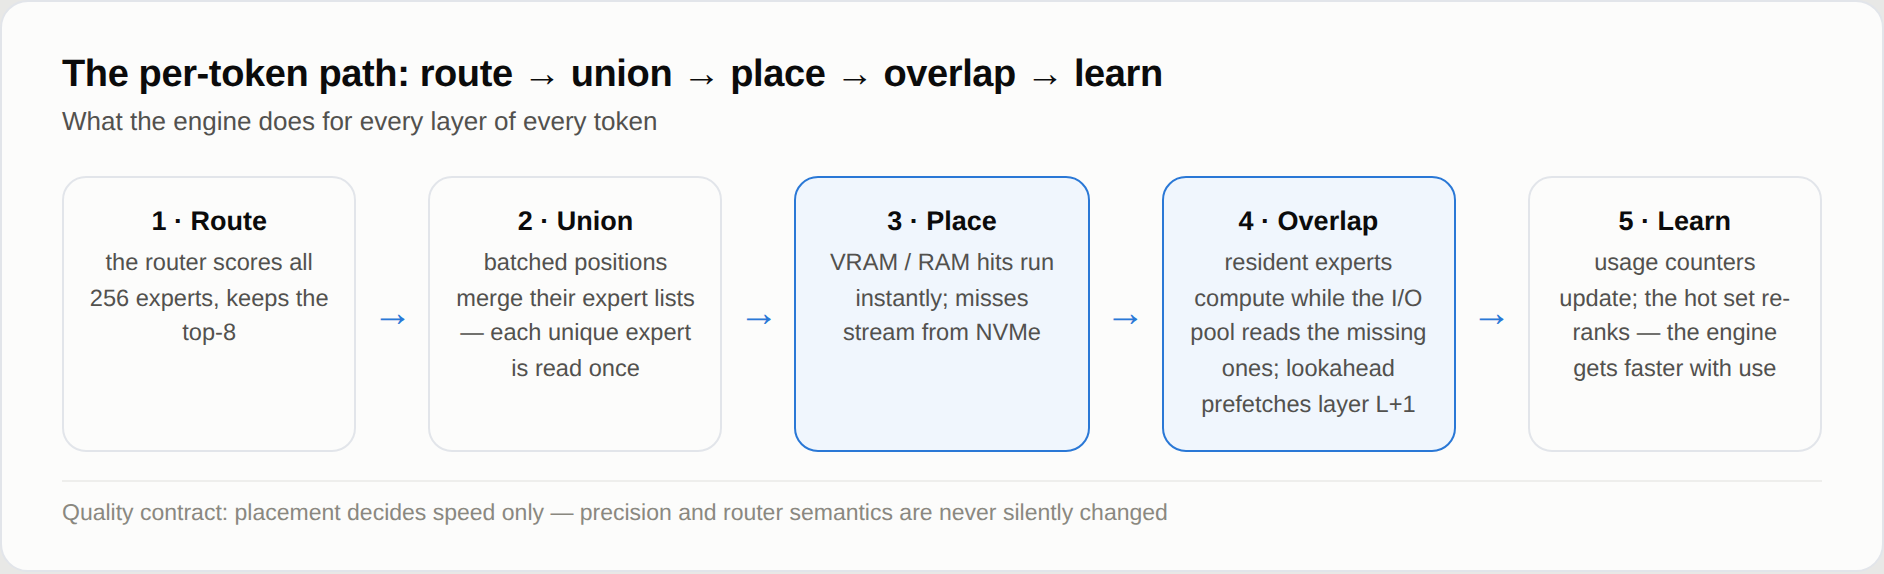
Every layer of every token walks the same five steps: route, union, place,
overlap, learn. The design goal is that **placement only ever decides speed**:
the router's decisions and the weights' precision are the same whether an
expert answered from VRAM, from RAM or from disk.
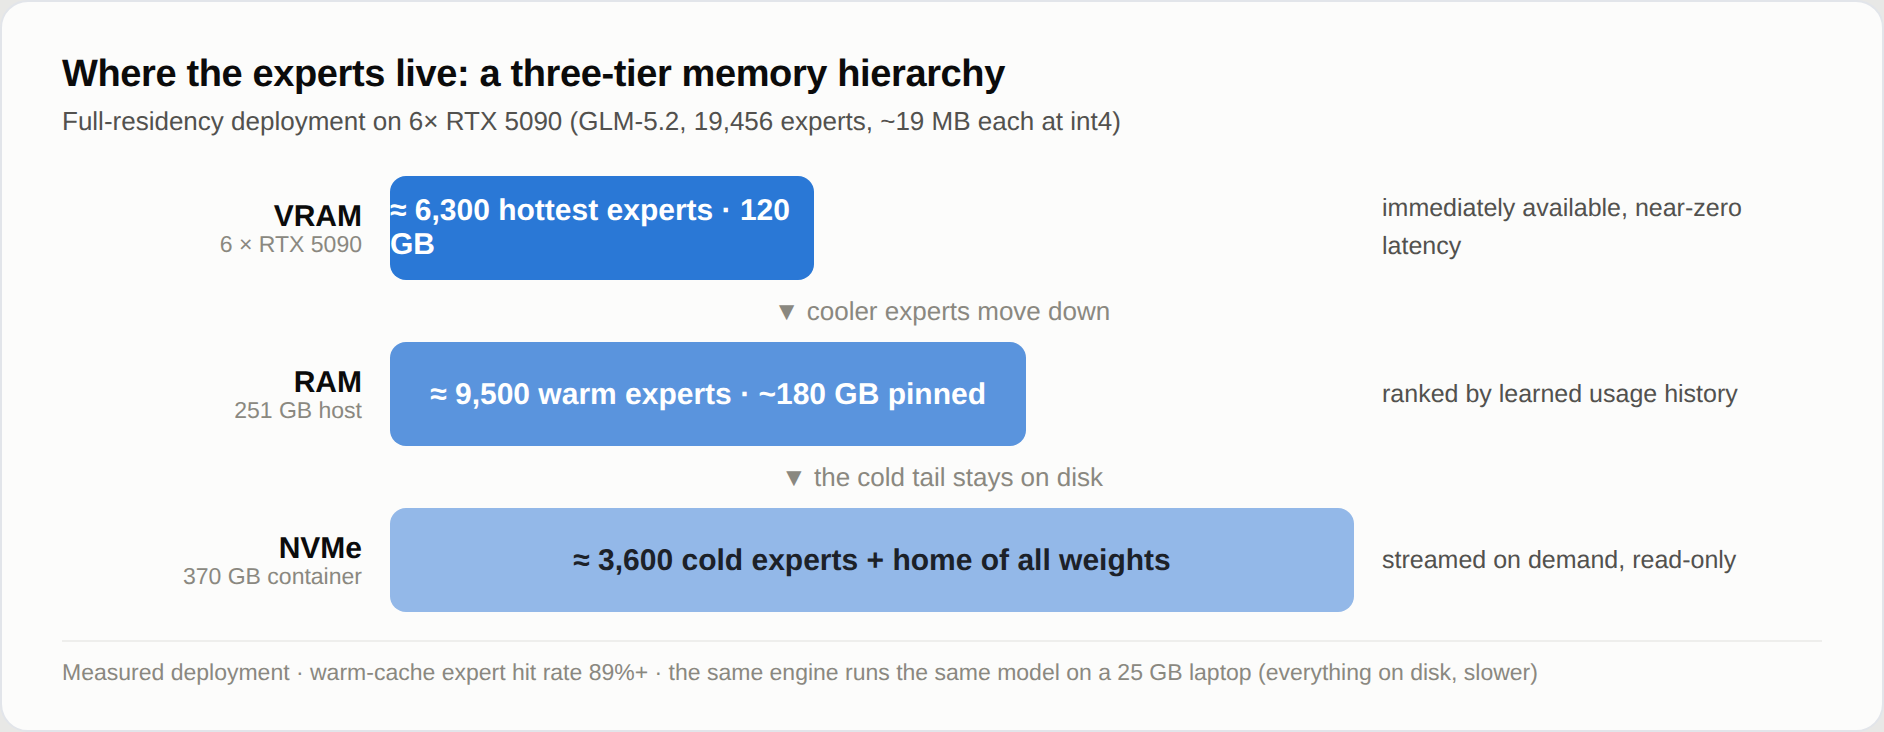
- **A JIT for weights.** A compiler JIT never compiles the whole program: it
watches what runs and compiles the hot paths. colibri makes the same bet
about weights. Measured routing heat decides which experts earn VRAM, RAM or
disk: a per-layer LRU cache, plus a pinned hot set learned from your own
conversations (`.coli_usage`, updated every turn). colibri gets faster the
more you use it. It works because routing has measurable structure (the
[expert atlas](https://github.com/JustVugg/colibri/issues/175)).
- **Never wait for the disk twice.** An expert's three matrices are read in one
`pread`; a pool of loaders reads the missing experts while the resident ones
compute; a batch of positions reads each expert once; a router-lookahead
thread can prefetch the next layer (GLM-5.2's routing is 71.6% predictable
one layer ahead). `DIRECT=1` (O_DIRECT) is often a large win on fast NVMe drives and
neutral or worse on others: measure it on yours ([tuning.md](docs/tuning.md)).
- **More than one SSD.** `COLI_MODEL_MIRROR=/second/glm52_i4 ./coli chat --model /fast/glm52_i4`
reads from a copy on a second drive. Two NVMe drives on independent
controllers measured +37.5% decode; a partial mirror on a smaller drive works
too ([multidisk.md](docs/multidisk.md)).
- **From a laptop to a rack.** On a 25 GB laptop every expert streams from
disk, slowly and correctly; on a large host every expert is resident
(`CUDA_EXPERT_GB=auto PIN_GB=all`) and the disk drops out of decoding.
`COLI_NUMA=1` spreads the resident weights over the memory controllers of a
multi-socket host, and a local cluster mode runs routed experts on other
machines ([cluster.md](docs/cluster.md)).
- **A faithful model.** Every engine is checked in CI against its model's
reference implementation on a tiny fixture. GLM-5.2's MLA attention keeps a
compressed KV state (576 floats per token instead of 32,768, 57x smaller)
that survives restarts, so a conversation reopens with no prompt to read
again.
- **Speculation that earns its keep.** GLM-5.2's int8 MTP head drafts 2.2-2.8
tokens per forward when it pays; Qwen3.8-Flash-Next's MTP head, on by default, adds
16-20% with the same output, and prompt lookup 6-7% on code edits. Qwen3.6's
head (`Q36_MTP=1`) takes its decode from 99.7-104.5 to 115.8-120.1 tok/s on
CUDA and from 83.2-83.8 to 99.9-109.3 on Vulkan (an RTX PRO 4000). DeepSeek
V4.1's DSpark head drafts as deep as its confidence says, and a gate skips the
drafts that cannot pay. Where drafting costs more than it saves (DeepSeek V4)
it stays off ([speculative.md](docs/speculative.md),
[tuning.md](docs/tuning.md#speculation-and-reproducibility)).
The engine is one C file per model family (`c/colibri.c` for GLM-5.2) over
shared headers, with no BLAS and no Python at runtime: Python runs only the
setup, the launcher, the converters and the API gateway.
## Benchmarks
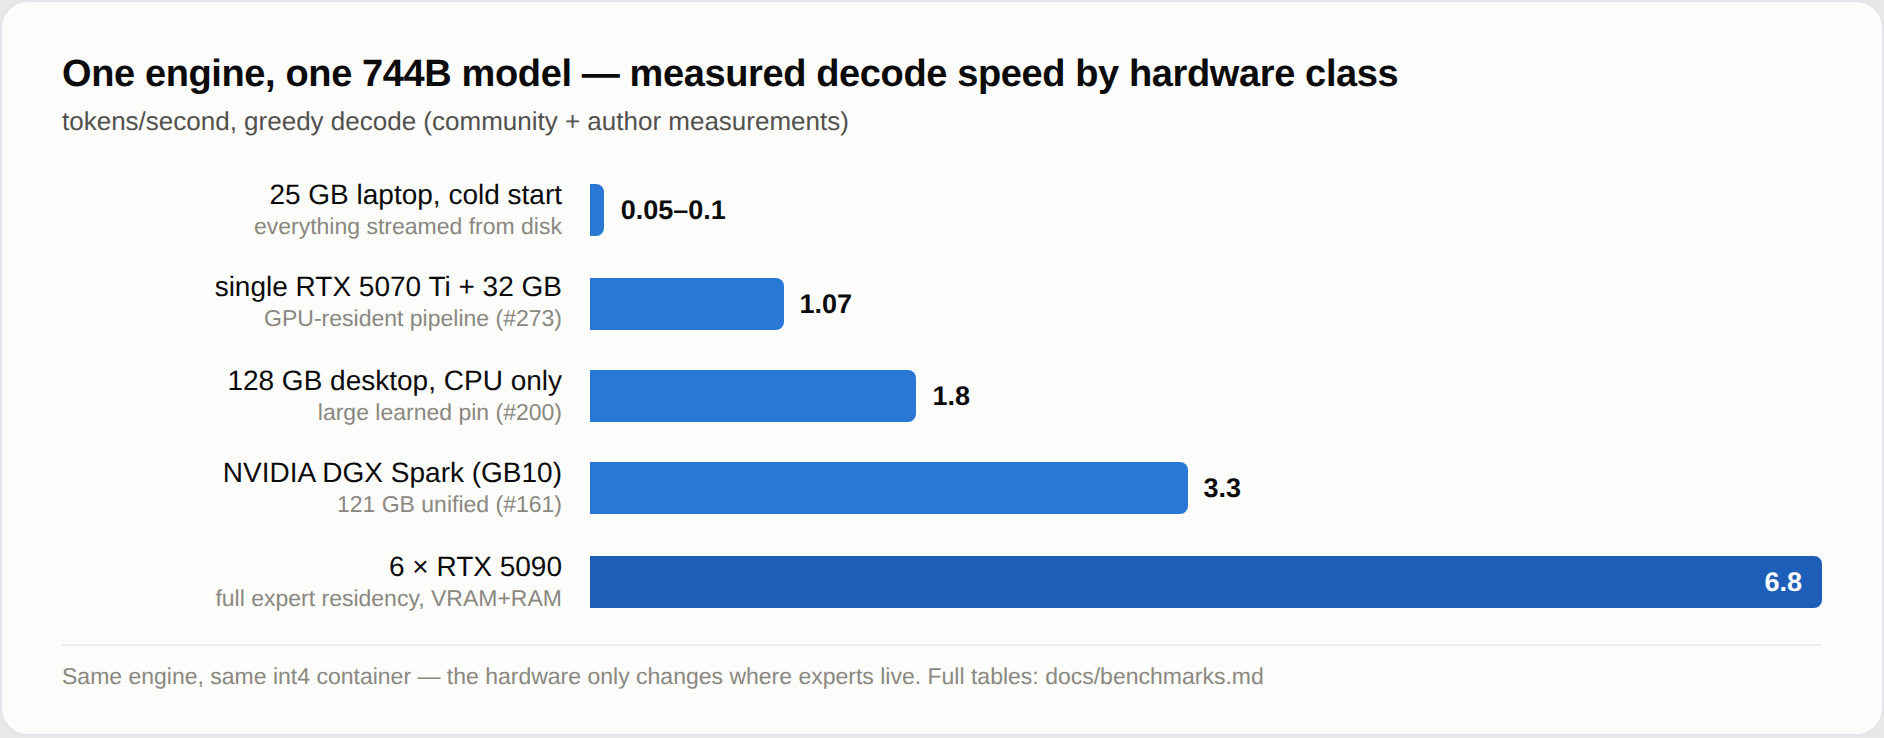
The same engine and the same int4 container: the hardware only changes where
the experts live. GLM-5.2 decode, from [the full tables](docs/benchmarks.md):
- **6x RTX 5090, every expert resident:** 5.8-6.8 tok/s, 9.0-9.2 with selective
NUMA interleave ([experiment log](docs/experiments/glm52-6x5090-2026-07-12.md));
- **128 GB, CPU only** (Ryzen AI Max+ 395): 1.83 tok/s warm
([#200](https://github.com/JustVugg/colibri/issues/200));
- **a single RTX 5070 Ti laptop-class box:** 1.07 tok/s
([#273](https://github.com/JustVugg/colibri/issues/273));
- **the 25 GB laptop where this started:** 0.05-0.1 tok/s cold, the honest
floor.
### Three backends on one machine
An i5-13500 with 62 GB of RAM and an RTX PRO 4000 Blackwell SFF (24 GB, 70 W),
each model served by `coli serve`: a fresh 450-token prompt, then a 128-token
streamed answer, the request's HTTP included; the better of two runs, tok/s.
| GGUF | CUDA prompt | CUDA decode | Vulkan prompt | Vulkan decode | CPU prompt | CPU decode |
|---|---:|---:|---:|---:|---:|---:|
| Qwen3.6-35B-A3B UD-Q4_K_M | 3,491 | 104.8 | 2,076 | 92.9 | 122.6 | 13.9 |
| LFM3-VL-2B Q4_K_M | 12,317 | 235.1 | 8,174 | 214.1 | 286.5 | 34.5 |
| OLMoE-1B-7B-0125-Instruct Q4_K_M | 10,418 | 354.6 | 6,867 | 299.4 | 279.9 | 47.4 |
| LFM3-VL-2B F16 | 11,524 | 103.4 | 7,767 | 99.3 | 49.7 | 6.4 |
| Qwen3.8-Flash-Next IQ2_XS (68 GB: the experts the card cannot hold stay in RAM) | 217.1 | 51.4 | 214.3 | 50.6 | 38.3 | 9.3 |
### Large models on the same machine
Machine D again, each model from its published GGUF through `coli serve`: what
neither the card nor the RAM holds comes from the two NVMe drives. Tokens per
second, from each model's page:
| GGUF | size | backend | prompt | decode |
|---|---:|---|---:|---:|
| Inkling-Small UD-IQ2_XXS | 77 GB | Vulkan | 15.1-33.1 | 10.92-11.53 ([vulkan.md](docs/vulkan.md)) |
| MiMo-V2.6-Flash Q2_K_S | 106 GB | Vulkan | 8.2 | 7.8 ([gguf.md](docs/gguf.md)) |
| DeepSeek V4 Flash 0731 UD-IQ2_XXS | 85 GB | Vulkan | 19.7-20.4 | 6.18-6.25 ([vulkan.md](docs/vulkan.md)) |
| DeepSeek V4.1 Flash UD-IQ1_S | | Vulkan | 31.8 over 3,403 tokens | 5.01-5.29 ([deepseek-v41.md](docs/deepseek-v41.md)) |
| GLM-5.3-Flash UD-IQ2_XXS | 95 GB | Vulkan | 9.3 | 2.92-3.40 ([vulkan.md](docs/vulkan.md)) |
| Muse Spark Open UD-IQ1_S | 176 GB | Vulkan | 5.0-5.3 | 1.55-1.58 ([qwen36.md](docs/qwen36.md#muse-spark-open)) |
| Mistral-Large-4 UD-IQ1_S | 233 GB | CUDA | 240 tokens in 66-82 s | 1.34-1.36 ([mistral-large4.md](docs/mistral-large4.md)) |
| GLM-5.2 UD-IQ1_S | 202 GB | Vulkan | | 0.633-0.658 ([gguf.md](docs/gguf.md)) |
| Kimi K3 UD-IQ1_S | 594 GB | Vulkan | 31 tokens in 46.5 s | 0.349 ([gguf.md](docs/gguf.md)) |
### Long contexts and agents
- **A 256k context at the speed of 64k.** Qwen3.8-Flash-Next IQ2_XS on the CUDA
chain of machine D, at a context of 262,144 tokens: prompt 15.6 -> 149 tok/s,
decode 9.6 -> 45.7 (the RAM plan at one prompt segment, K/V in float16 on the
card; at 65,536 it reads 188 and decodes 48.4) ([qwen38.md](docs/qwen38.md)).
- **An agent's turns read only what is new.** A short request between two turns
(an agent asking for the conversation's title) parks the conversation instead
of taking its state, on every engine (`COLI_PARK`). Hermes Agent's second turn
on Qwen3.8-Flash-Next, 14,810 tokens: 86 s -> 4.9 s
([qwen38.md](docs/qwen38.md#an-agents-turns)).
- **KV caches in float16**: GLM-5.3 at 131,072 tokens holds 11.9 GB instead of
23.9 ([CHANGELOG](CHANGELOG.md)).
Quality is measured, not assumed: the int4 container's cost and the
quantization ablations are in
[benchmarks.md](docs/benchmarks.md#quality-benchmark). To add your machine,
follow [the benchmark protocol](docs/benchmarking.md) and open an issue with
the numbers.
## Install by hand
**1. The program.** Take the archive for your platform from
[Releases](https://github.com/JustVugg/colibri/releases) (Linux x86_64, macOS,
Windows; no compiler needed, only [Python 3](https://www.python.org/downloads/)
for the launcher and the API) and unpack it, then `python3 coli info`. The Linux
and Windows engines have Vulkan built in, with their `shaders/` beside them, and
the macOS ones Metal; for an NVIDIA card on Windows add the CUDA archive. Or build
from source with `gcc` (or clang) and OpenMP:
```bash
git clone https://github.com/JustVugg/colibri && cd colibri/c
./setup.sh # checks gcc/OpenMP, builds, self-tests
make qwen36 VK=1 # one engine, here with Vulkan (CUDA=1 for CUDA)
```
**2. A model.** Any download in [the tables above](#which-model-for-my-machine):
the setup's ids map to Hugging Face repositories, and each model's page has the
download and conversion command. For GLM-5.2 use the group-scaled (gs64)
container with the int8 MTP head,
[`mastouri/GLM-5.2-colibri-int4-g64-with-int8-mtp`](https://huggingface.co/mastouri/GLM-5.2-colibri-int4-g64-with-int8-mtp)
(429 GB), or [`Justvugg/GLM-5.3-colibri-int4-g64`](https://huggingface.co/Justvugg/GLM-5.3-colibri-int4-g64)
for GLM-5.3 (419 GB, no MTP head). Not the older per-row int4 mirrors: they
measure about 9 points worse on quality and caused the looping answers of
[#455](https://github.com/JustVugg/colibri/issues/455). `./coli convert --model
/nvme/glm52_i4` builds the same container from the FP8 release, shard by shard,
without ever needing its 756 GB on disk at once. How to check the MTP head and
the rest: [quickstart.md](docs/quickstart.md#3-get-the-model). A GGUF you
already have needs no conversion: `./coli import` its first file
([above](#from-a-gguf)).
**3. Run it.** From `c/` in a source checkout, or from the unpacked release.
The launcher reads the model's `config.json` and picks the engine and its chat
template, so the commands are the same for every model:
```bash
./coli chat --model /nvme/qwen36 # chat in the terminal
./coli web --model /nvme/qwen36 # API + dashboard, opens a browser
./coli serve --model /nvme/qwen36 # API + dashboard, no browser
./coli plan --model /nvme/qwen36 # where the model will live: VRAM, RAM, disk
./coli doctor --model /nvme/qwen36 # read-only check: is everything ready?
./coli tune --model /nvme/qwen36 # measure and save this machine's fastest safe settings
./coli import /nvme/Flint-UD-Q4_K_XL.gguf # a GGUF: writes Flint-UD-Q4_K_XL.colibri next to it
./coli ui # the chat UI, next to a running coli serve
```
On Windows a release archive ships `coli.cmd` (`coli.cmd chat --model
D:\qwen36`); from a source checkout use `py -3 c\coli`. The `.exe` files are
the engines, not the launcher. Every option and variable:
[SETTINGS.md](docs/SETTINGS.md), [ENVIRONMENT.md](docs/ENVIRONMENT.md).
## Research, and how to help
colibri wants frontier models to depend less on scarce hardware and to cost
less to run. That means changing how weights are stored and moved, deciding
what lives in VRAM, RAM or storage, overlapping CPU and GPU work, and testing
new ways to decode. Nothing is kept because it is conventional, and nothing is
adopted because a microbenchmark looks fast: the deciding result is end-to-end
inference on real machines, with quality measured alongside speed. The open
questions:
| hypothesis | evidence so far | experiment still needed |
|---|---|---|
| Routing history can place experts better than plain LRU | learned pins improve repeated workloads, but can overfit a prompt | held-out, cross-session A/Bs across coding, chat, multilingual, and long-context workloads |
| Multiple SSDs can turn independent bandwidth into decode speed | two independent NVMe drives measured +37.5% decode; a slower third drive was neutral after weighted striping ([measurements](docs/multidisk.md#what-has-been-measured)) | reproduce across drive speeds, controller layouts, and cache states |
| A hardware-aware planner can approach each machine's best configuration automatically | RAM/VRAM budgets and several backends are detected today, and the setup picks the build | compare the generated plan with a controlled parameter sweep across laptops, workstations, NUMA hosts, and multi-GPU systems |
| Lossless or quality-bounded representations can reduce weight movement enough to matter | format and quantization ablations exist, with correctness/quality gates | reproduce quality, bytes moved, latency, and cost per useful token together, not compression ratio alone |
| Routing-aware speculation can pay before near-full residency | MTP and grammar drafts work, but MTP has also measured a 32% loss around 85% expert hit | map the break-even surface across acceptance, expert hit rate, batch union, and draft depth |
| CPU/GPU overlap can hide transfer and synchronization rather than merely move the bottleneck | CUDA, Metal and Vulkan wins exist, but fast CPUs, integrated GPUs and low residency can erase them | per-stage profiles and one-variable A/Bs across PCIe, unified-memory, and full-resident machines, and more discrete cards for the Vulkan tier and chain than the one measured (an RTX PRO 4000) |
Want to help? Pick a row and publish the negative results too. Record the
hardware, commit, model, exact command, prompt, cache state, throughput, time
to first token, expert hit rate, bytes read and a quality check; change one
variable, repeat, and attach the raw logs. Start with
[CONTRIBUTING.md](CONTRIBUTING.md) and [the benchmark protocol](docs/benchmarking.md),
then [open an issue](https://github.com/JustVugg/colibri/issues/new). A
well-controlled failure is worth more here than an unexplained fast number.
## Documentation
| topic | doc |
|---|---|
| The one-step setup and the manual install, every platform | [quickstart.md](docs/quickstart.md) |
| Setting up through an AI assistant, and the MCP server | [AI_SETUP.md](docs/AI_SETUP.md), [MCP_SERVER.md](docs/MCP_SERVER.md) |
| The API: OpenAI, Anthropic, tools, KV slots, dashboard | [api.md](docs/api.md) |
| System One and the decision models | [systemone.md](docs/systemone.md), [laya.md](docs/laya.md), [gliner_decide.md](docs/gliner_decide.md), [clef.md](docs/clef.md) |
| GGUF files: the architectures, the two modes, what each engine does with the blocks | [gguf.md](docs/gguf.md) |
| The models on the Qwen3.6 engine (Flint, Muse Spark Open, LFM3-VL) and Mistral-Large-4 | [qwen36.md](docs/qwen36.md), [mistral-large4.md](docs/mistral-large4.md) |
| The chat UI (`coli ui`) | [ui/README.md](ui/README.md) |
| Vulkan: the expert tier, the dense chain, cards without Resizable BAR | [vulkan.md](docs/vulkan.md) |
| CUDA, and Qwen3.6's CUDA tier | [cuda.md](docs/cuda.md), [qwen36-cuda-tier.md](docs/qwen36-cuda-tier.md) |
| Apple Silicon, Windows | [metal.md](docs/metal.md), [windows.md](docs/windows.md) |
| Tuning, the learning cache, prefetch | [tuning.md](docs/tuning.md) |
| Speculative decoding: the MTP heads, prompt lookup, the gate | [speculative.md](docs/speculative.md) |
| Several SSDs, several machines | [multidisk.md](docs/multidisk.md), [cluster.md](docs/cluster.md) |
| Benchmarks and how to measure | [benchmarks.md](docs/benchmarks.md), [benchmarking.md](docs/benchmarking.md) |
| Every option and environment variable | [SETTINGS.md](docs/SETTINGS.md), [ENVIRONMENT.md](docs/ENVIRONMENT.md) |
| Grammar-forced drafts, and the experimental embedding ABIs | [grammar-draft.md](docs/grammar-draft.md), [segment-runtime.md](docs/segment-runtime.md), [edge-runtime.md](docs/edge-runtime.md) |
## Repo layout
```
start-here.sh, START-HERE.bat the one-step setup (Linux and macOS, Windows)
Makefile root build/check entry point
c/
├── colibri.c GLM-5.2/5.3, Mistral-Large-4 (make glm)
├── glm53.c GLM-5.3-Flash (make glm53)
├── inkling.c Inkling (make inkling)
├── kimi_k3.c Kimi K3 (make kimi_k3)
├── deepseek_v4.c DeepSeek V4 Flash (make deepseek-v4)
├── deepseek_v41.c DeepSeek V4.1 Flash (make deepseek_v41)
├── mimo.c MiMo-V2.6 Flash and Pro (make mimo)
├── qwen38.c Qwen3.8-Flash-Next (make qwen38)
├── qwen36.c Qwen3.6, Qwen3-Coder, Qwen3.8-27B, Flint, Muse Spark,
│ LFM3-VL, Clef (make qwen36)
├── olmoe.c OLMoE (make olmoe)
├── qwenimage.c Qwen-Image-2.1 (make qwenimage)
├── laya.c Laya (make laya)
├── gliner_decide.c GLiNER2.5-Decide (make gliner_decide)
│
├── st.h, quant.h, idot.h safetensors reads, container decoders, integer kernels
├── expert_ffn.h, expert_store.h routed-expert kernel and streaming expert cache
├── tok.h, json.h, compat.h tokenizer, JSON, Windows/macOS shims
├── route_trace.h, kv_prefix.h routing telemetry (.coli_usage), KV prefix reuse
├── gguf.h, park.h GGUF reader, a conversation parked between an agent's turns
├── decide_serve.h the decision engines' side of System One
│
├── backend_cuda.*, cu_tier.h, cuda_chain.cu optional CUDA tier and chains (CUDA=1)
├── backend_metal.* optional Metal tier (METAL=1)
├── backend_vulkan.*, vk_tier.c, vk_chain.c optional Vulkan tier and dense chain (VK=1)
│
├── coli user-facing CLI
├── setup_*.py the one-step setup: hardware, catalog, downloads, flow
├── mcp_server.py the MCP server (coli mcp)
├── openai_server.py OpenAI- and Anthropic-compatible HTTP gateway
├── resource_plan.py RAM/VRAM planner behind coli plan and coli doctor
├── tools/ conversion, fixtures and benchmarks
└── tests/ dependency-free C and Python tests
ui/ the chat UI (coli ui)
web/ the dashboard (a pure API client)
desktop/ Tauri desktop shell around the dashboard
docker/ container images
docs/ reference docs, experiments, media
site/ the website
```
**One `.c` per model family, over shared single headers.** An engine owns its
architecture and nothing else; anything two engines both need lives in a header
they both include, so a fix reaches all of them at once. From the repository
root, `make`, `make check` and `make clean` delegate to the engine Makefile.
## Supporting the project
colibri started as a one-person project on a 12-core laptop with 25 GB of RAM;
today its numbers come from a community of real machines. If it is useful to
you:
- star the repository and share it;
- open issues with benchmark numbers from your hardware: datapoints move this
project more than anything else;
- join the [Discord community](https://discord.gg/RXV83nSZdk) to discuss
experiments, hardware results and research directions;
- reach out through GitHub issues to sponsor development or donate hardware.
## Why "colibrì"
The hummingbird weighs a few grams, hovers in place, and visits a thousand
flowers a day. This engine keeps a 744-billion-parameter giant alive on
hummingbird rations: 25 GB of RAM, twelve CPU cores, and a lot of disk patience.
## Acknowledgements
colibri is an engine; the minds it runs are a gift. Thank you to the teams who
release their weights in the open: **Z.ai** (GLM), **Moonshot AI** (Kimi),
**Alibaba Qwen**, **DeepSeek**, **Xiaomi** (MiMo), **Thinking Machines**
(Inkling), **Allen AI** (OLMoE), **Convai Innovations** (Laya), **fastino**
(GLiNER2.5-Decide) and **Cloudflare** (Clef); to the people who publish
converted containers; and to every contributor who benchmarked, bisected,
replicated an atlas run or sent a patch. Third-party code in this repository
and its licences: [THIRD_PARTY_NOTICES.md](THIRD_PARTY_NOTICES.md).
The project's expert placement, compression, and routing experiments also build
on ideas and evidence from the following open research and systems work:
- [REAP](https://github.com/CerebrasResearch/reap) and
[EASY-EP](https://github.com/RUCAIBox/EASYEP) for output-aware and
domain-specific expert importance.
- [SERE](https://github.com/JL-Cheng/SERE) for similarity-based expert
re-routing, and [ReMoE](https://github.com/BUAA-OSCAR/ReMoE) for
cache-locality-aware router fine-tuning.
- [MC-SMoE](https://github.com/UNITES-Lab/MC-SMoE) for routing-guided expert
merging and compression.
- [MoBE](https://github.com/inclusionAI/MoBE) and
[D²-MoE](https://github.com/lliai/D2MoE) for shared expert bases and
low-rank expert deltas.
- [HybriMoE](https://github.com/PKU-SEC-Lab/HybriMoE) for hybrid CPU/GPU expert
scheduling, [ScMoE](https://arxiv.org/abs/2404.05019) for overlapping expert
communication with computation, and
[OD-MoE](https://arxiv.org/abs/2512.03927) for distributed on-demand expert
loading.
- [vLLM](https://github.com/vllm-project/vllm),
[llama.cpp](https://github.com/ggml-org/llama.cpp), and
[kTransformers](https://github.com/kvcache-ai/ktransformers) for the open
inference systems and expert-offload work that make comparisons reproducible.
The engine also stands on concrete engineering work, not only ideas. Each of
these is used or reimplemented in the tree today:
- [safetensors](https://github.com/huggingface/safetensors): the container
every engine reads (`c/st.h`), including its fp8 and I64 dtypes.
- [tiktoken](https://github.com/openai/tiktoken): `c/tok.h` reimplements its
`byte_pair_encode` exactly, merging the adjacent pair whose concatenation has
the lowest vocab id, so a tiktoken-derived vocabulary needs no merges list.
- [llama.cpp](https://github.com/ggml-org/llama.cpp): the GBNF grammar subset
in `c/grammar.h` follows its syntax and its set-of-stacks PDA, and the Metal
path borrows its `newBufferWithBytesNoCopy` residency trick.
- [vLLM](https://github.com/vllm-project/vllm): the reference for output
semantics the engine matches position by position (e.g. where the final norm
lands relative to the LM head).
- [transformers](https://github.com/huggingface/transformers): the oracle:
CI reproduces a random-init model token for token against it.
- [DietGPU](https://github.com/facebookresearch/dietgpu): the GPU ANS codec
behind the experimental compressed expert tier (`COLI_ANS`).
- [rocWMMA](https://github.com/ROCm/rocWMMA): the HIP backend maps CUDA's
`nvcuda::wmma` fragment/mma_sync API onto it (`c/backend_gpu_compat.h`), which
is what lets one .cu source compile for both vendors.
## License
Apache 2.0, Copyright 2026 Vincenzo Fornaro. See [LICENSE](LICENSE) and [NOTICE](NOTICE). Each model keeps the licence its authors gave it (GLM-5.2 weights are released by Z.ai under MIT; Qwen-Image-2.1 is for non-commercial use only).